CRISPDM the CRossIndustry Standard Process for Data Mining
- Slides: 81
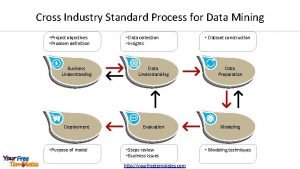
CRISP-DM, the CRoss-Industry Standard Process for Data Mining. 2
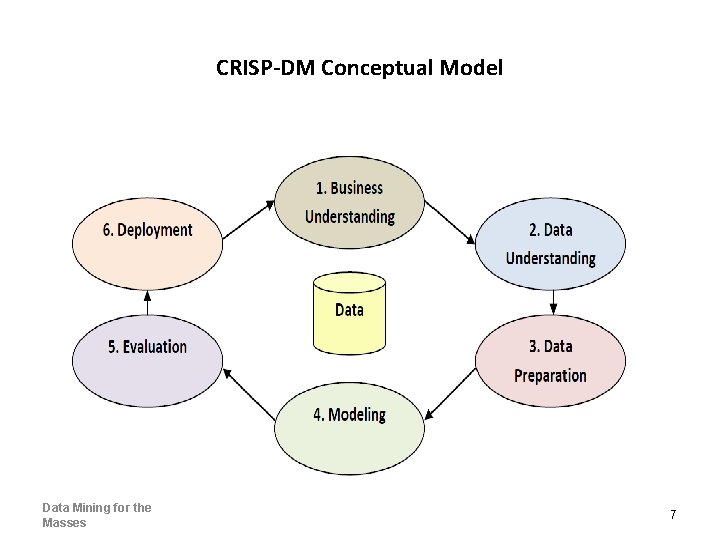
CRISP-DM Conceptual Model Data Mining for the Masses 7
A new data mining project in Rapid. Miner The Rapid. Miner start screen 9
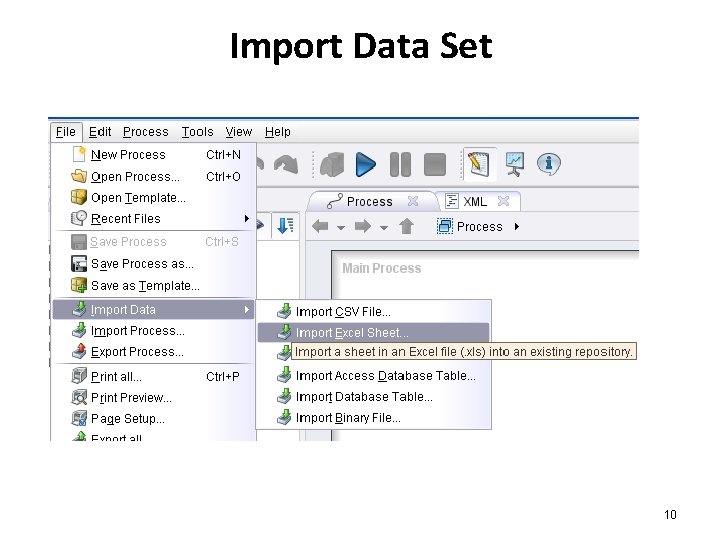
Import Data Set 10
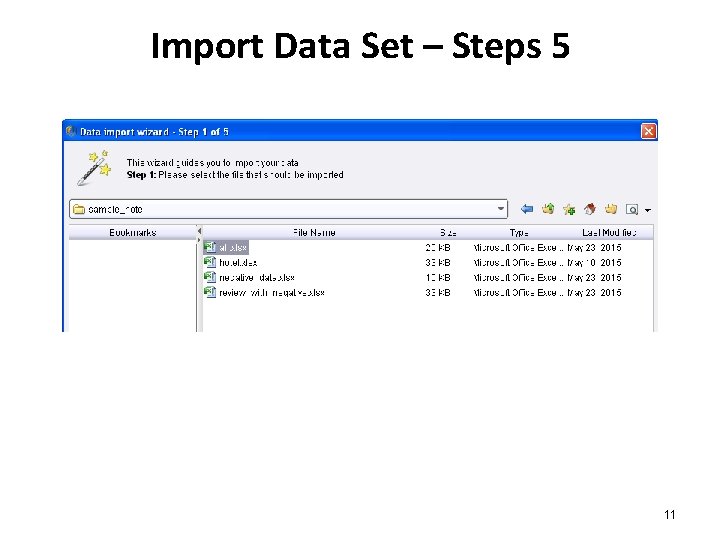
Import Data Set – Steps 5 11
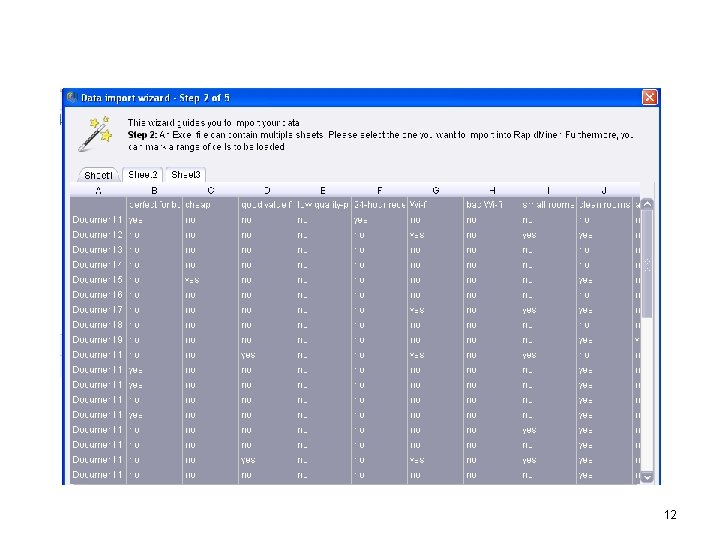
12
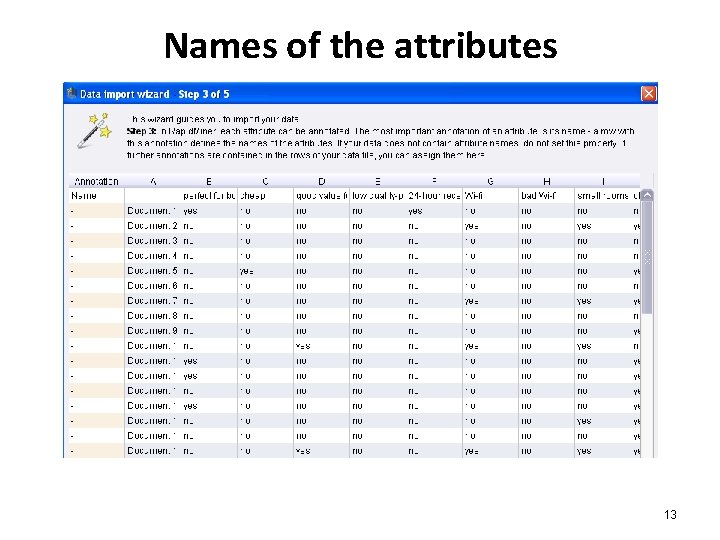
Names of the attributes 13
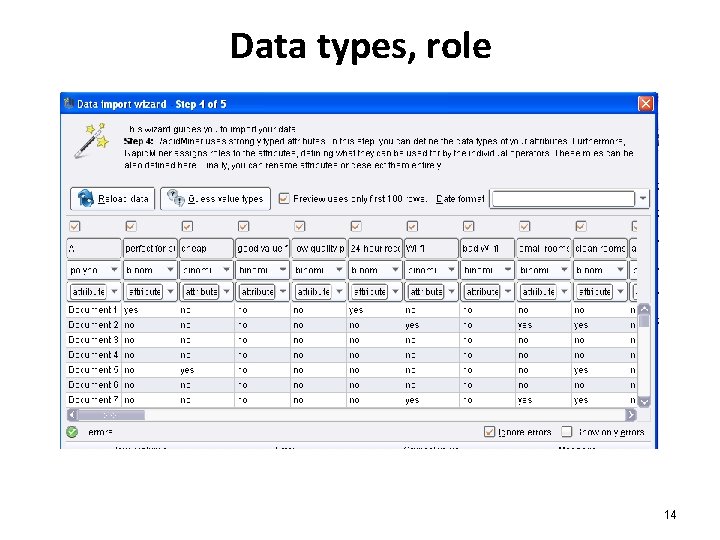
Data types, role 14
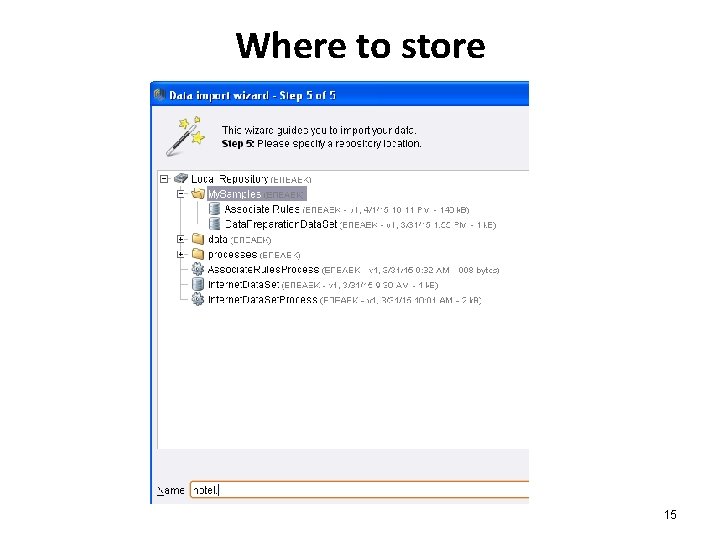
Where to store 15
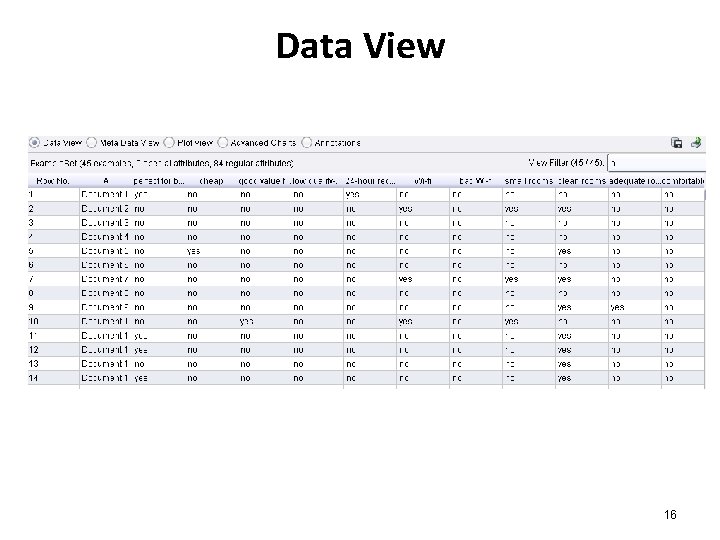
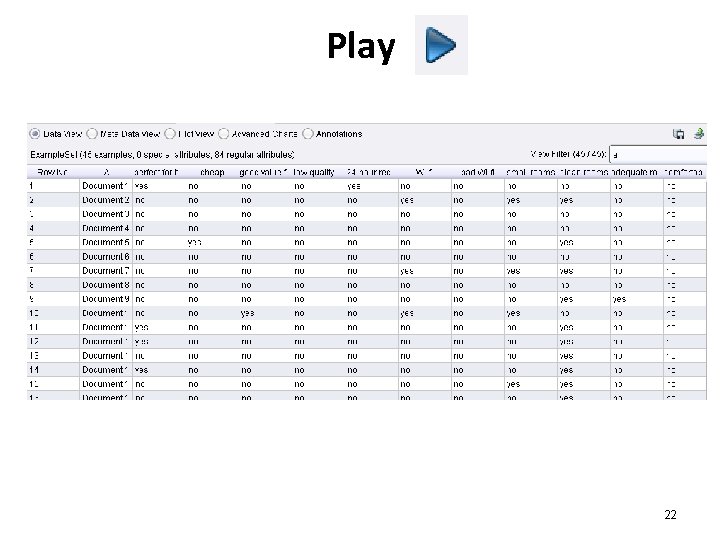
Data View 16
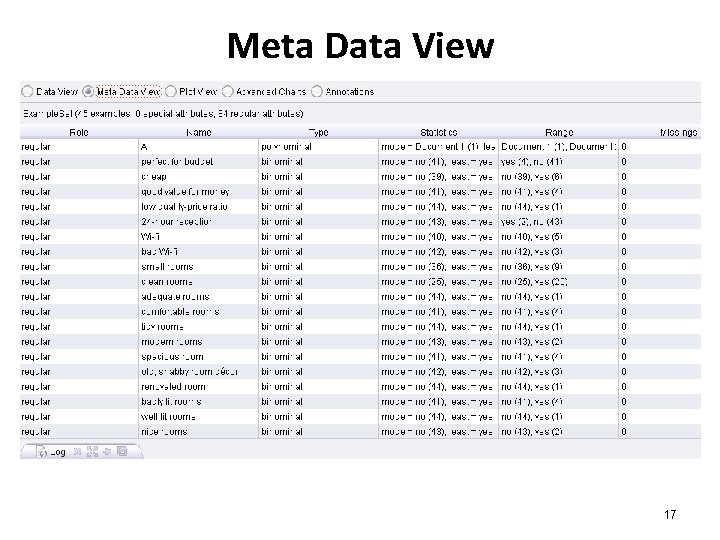
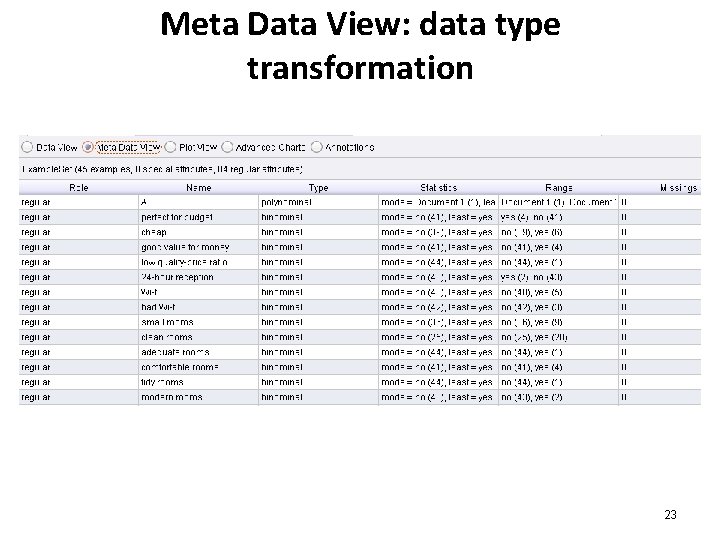
Meta Data View 17
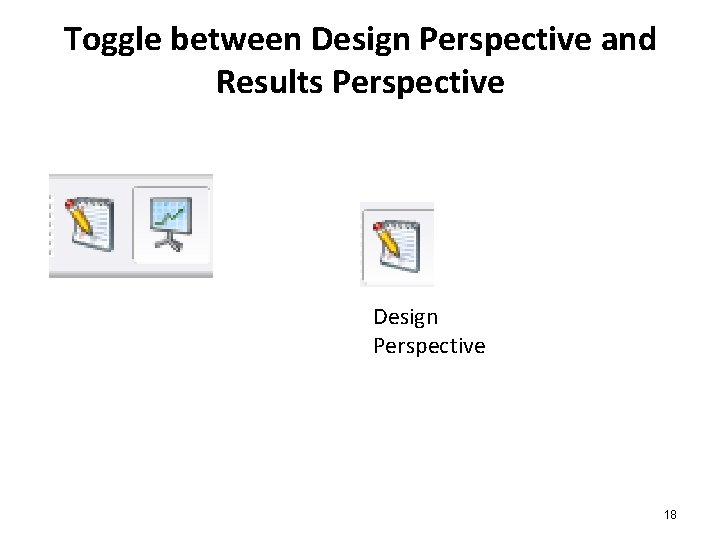
Toggle between Design Perspective and Results Perspective Design Perspective 18
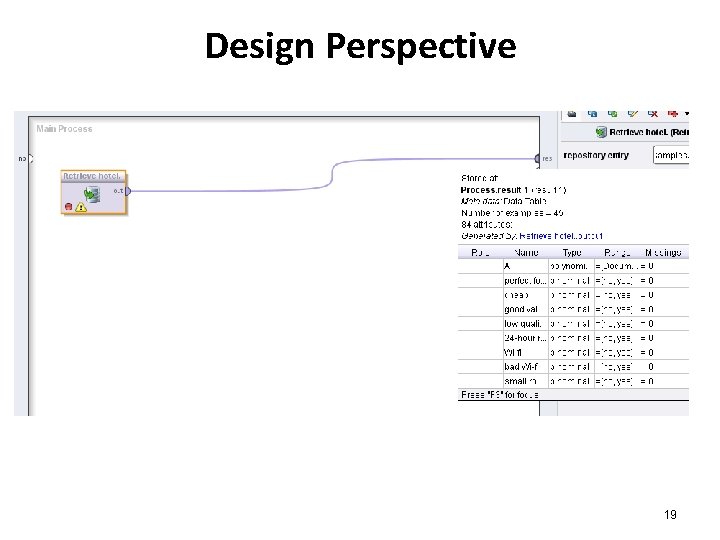
Design Perspective 19
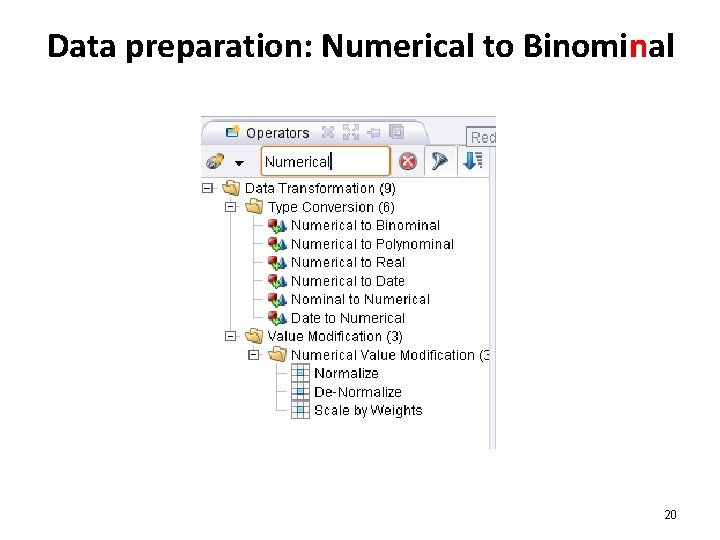
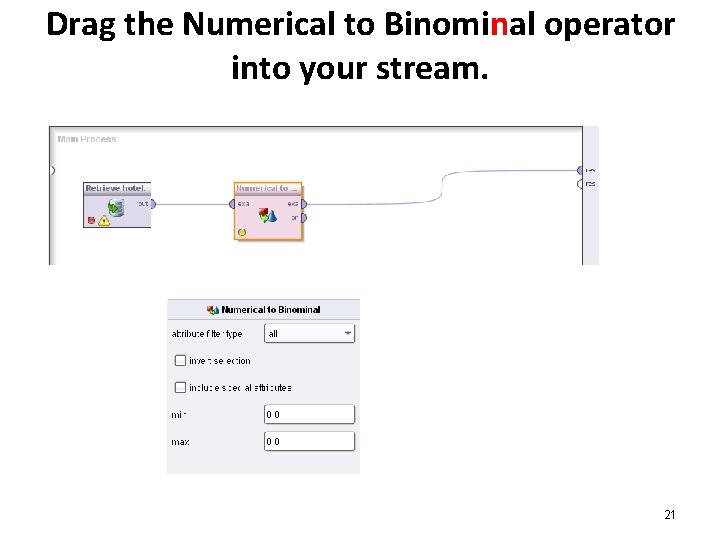
Data preparation: Numerical to Binominal 20
Drag the Numerical to Binominal operator into your stream. 21
Play 22
Meta Data View: data type transformation 23
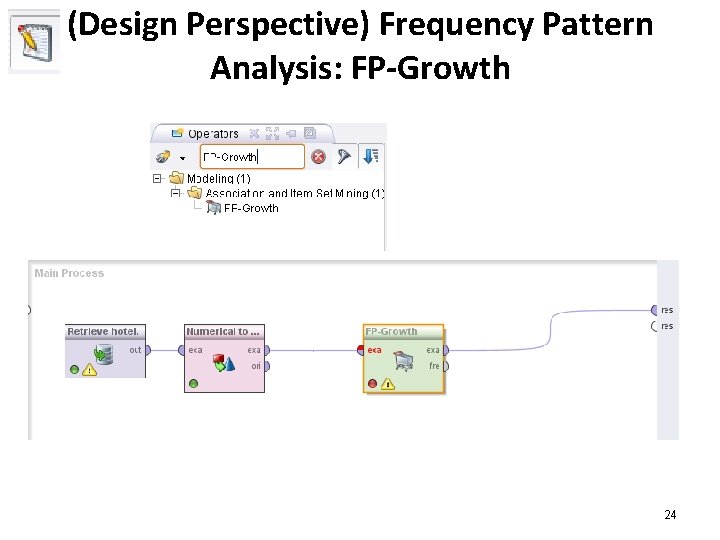
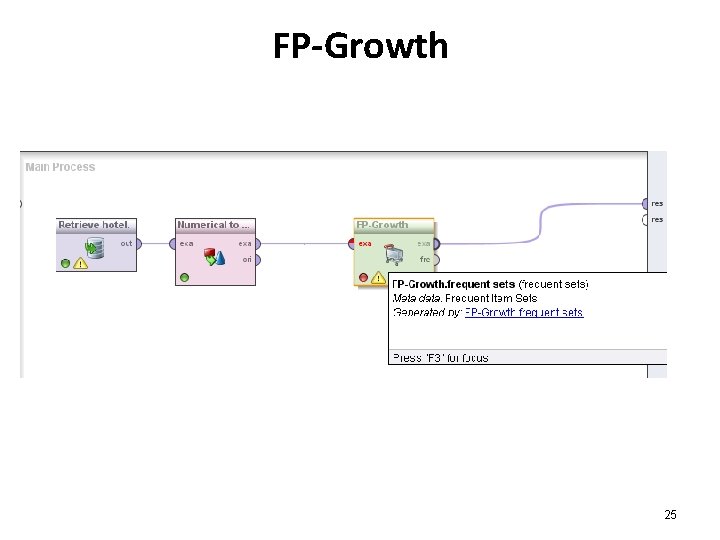
(Design Perspective) Frequency Pattern Analysis: FP-Growth 24
FP-Growth 25
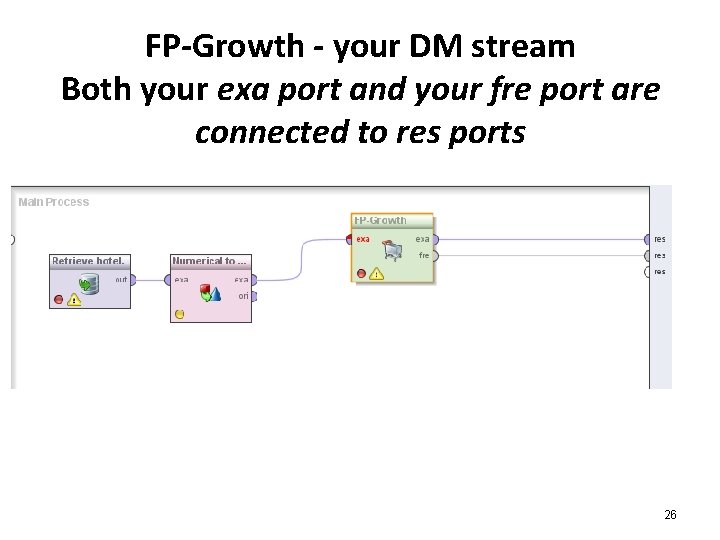
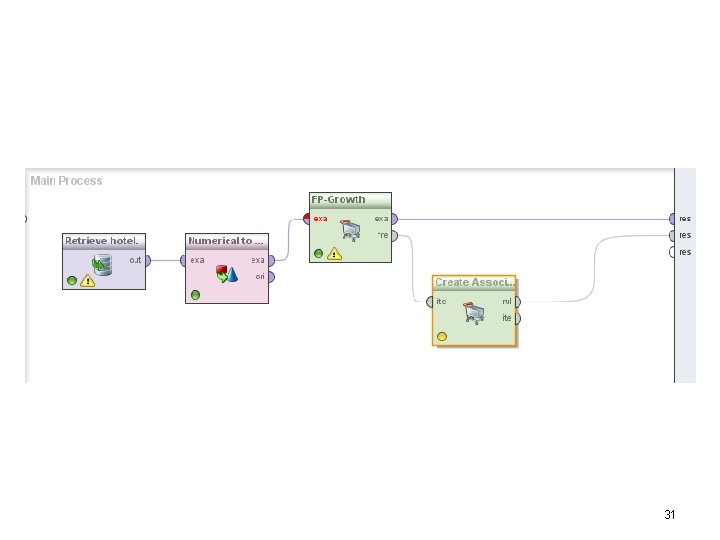
FP-Growth - your DM stream Both your exa port and your fre port are connected to res ports 26
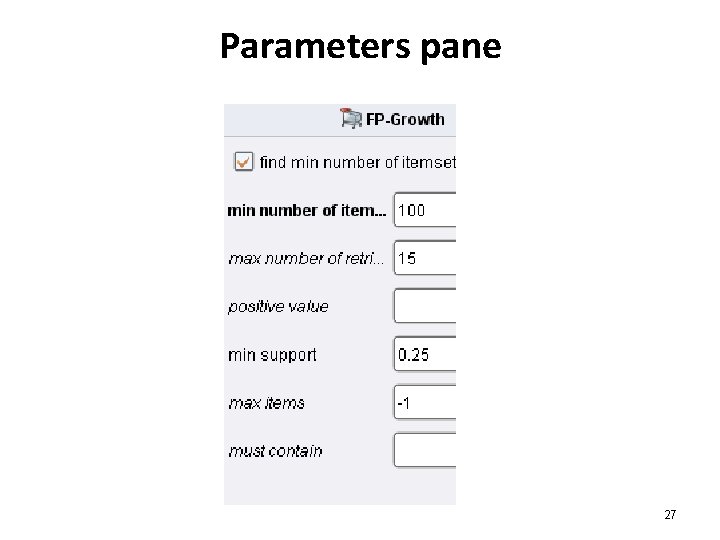
Parameters pane 27
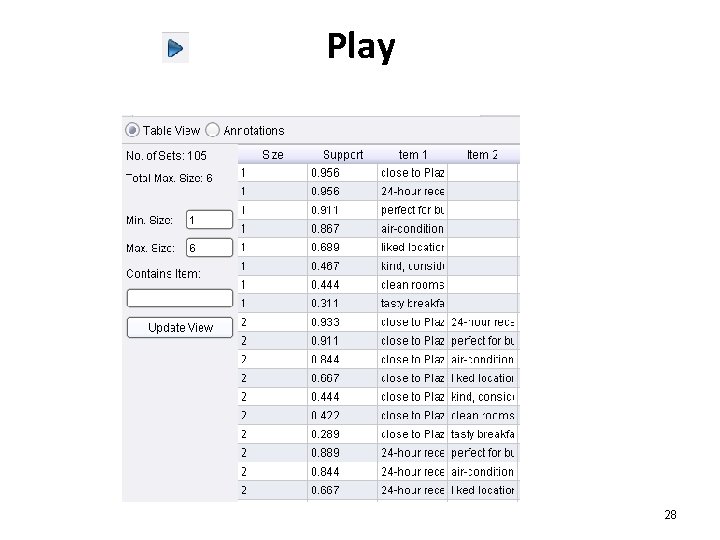
Play 28
Further investigation
Create Association Rules operator 30
31
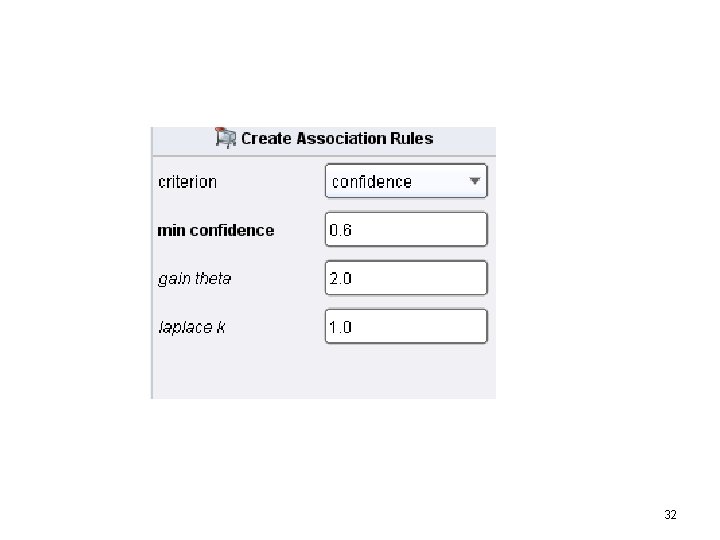
32
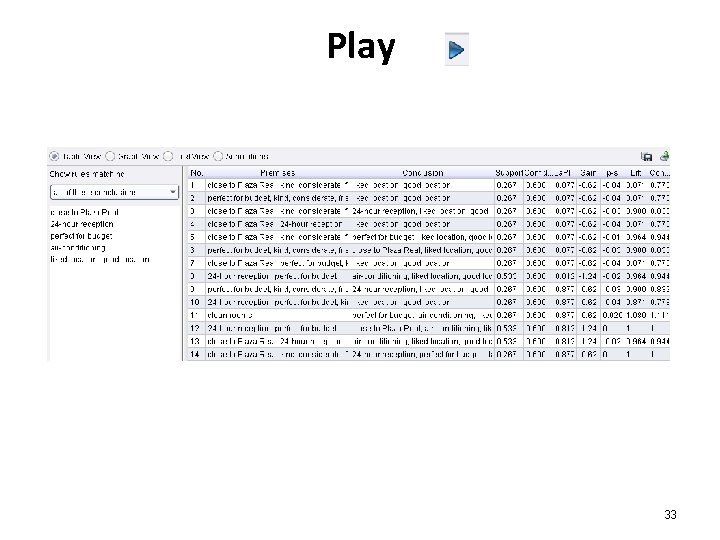
Play 33
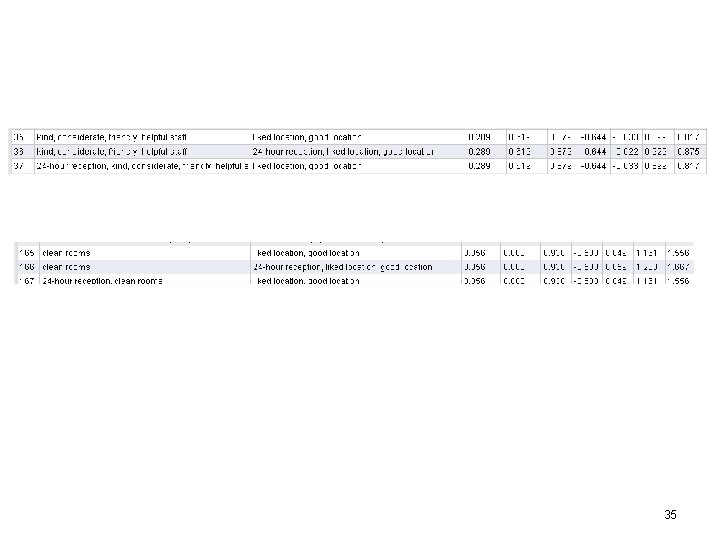
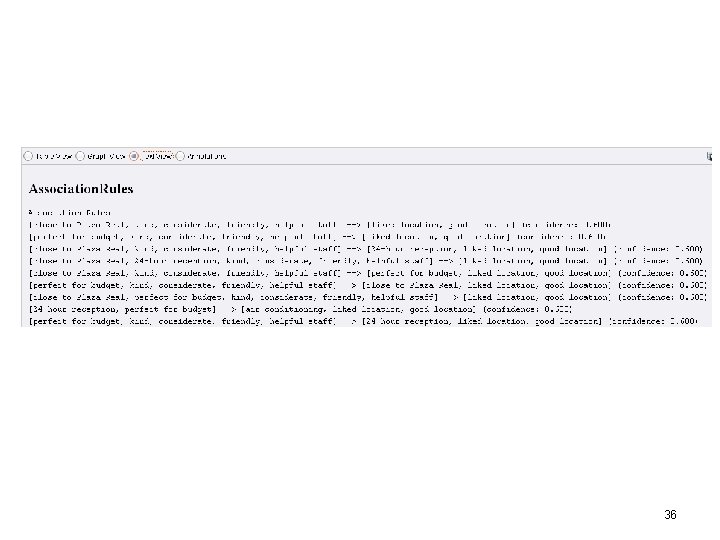
rules found with the 60% confidence threshold 34
35
36
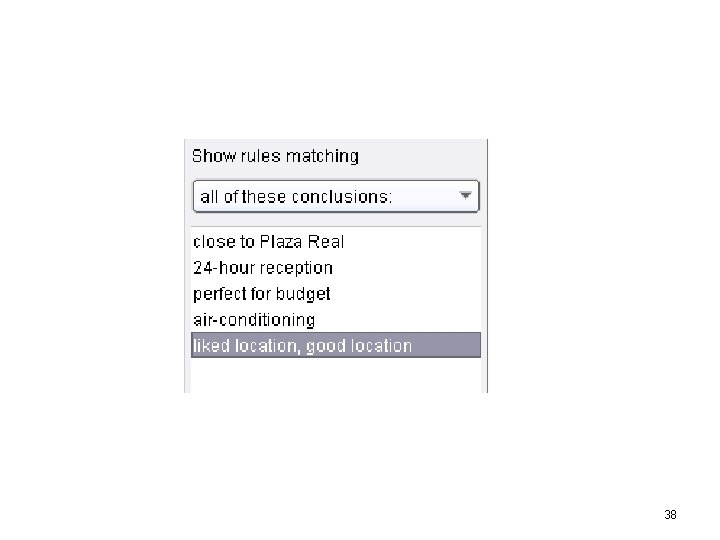
37
38
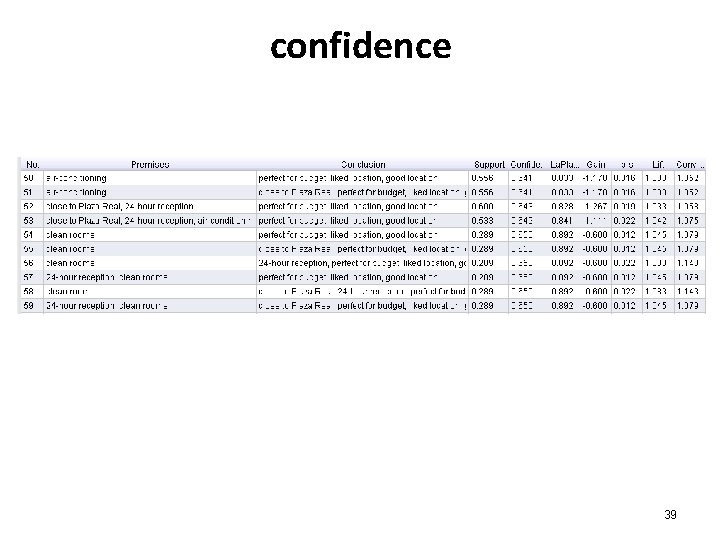
confidence 39
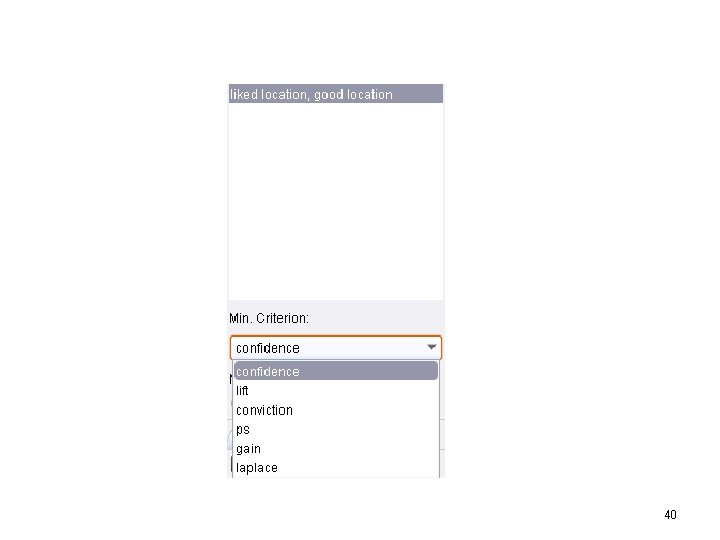
40
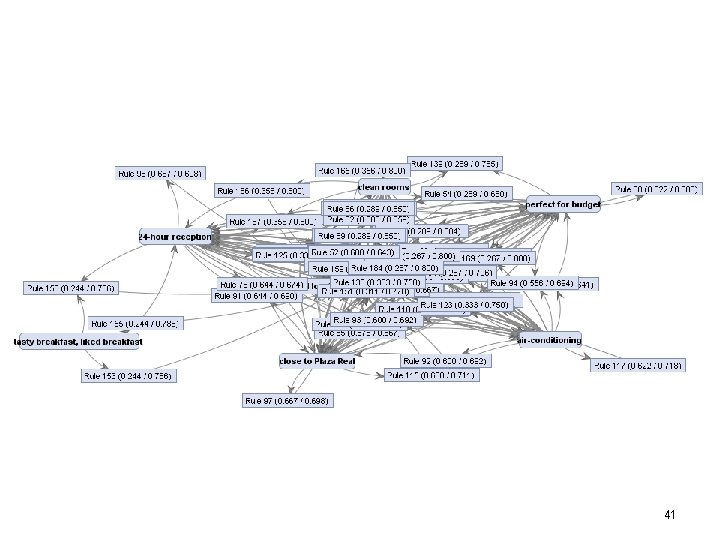
41
Do linkages between attributes exist? Yes, they do.
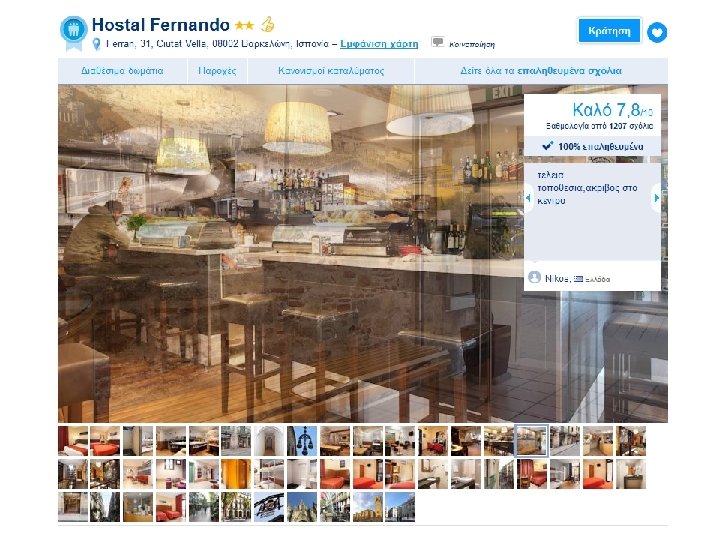
Hostal Fernando, Barcelona 44
45
46
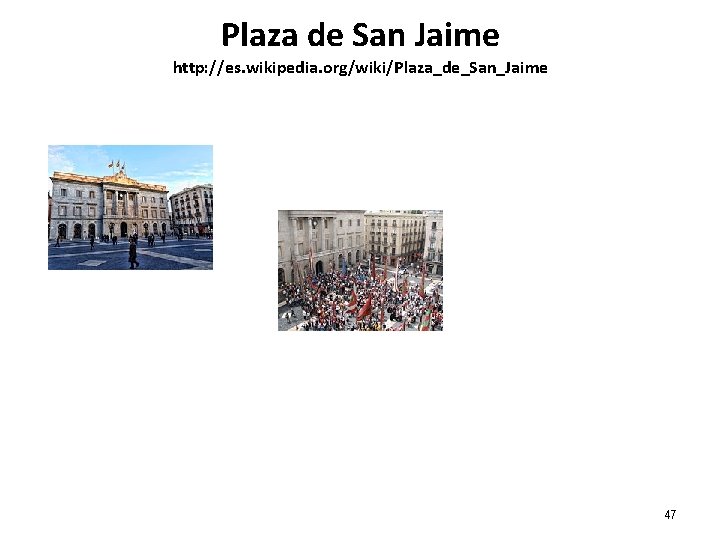
Plaza de San Jaime http: //es. wikipedia. org/wiki/Plaza_de_San_Jaime 47
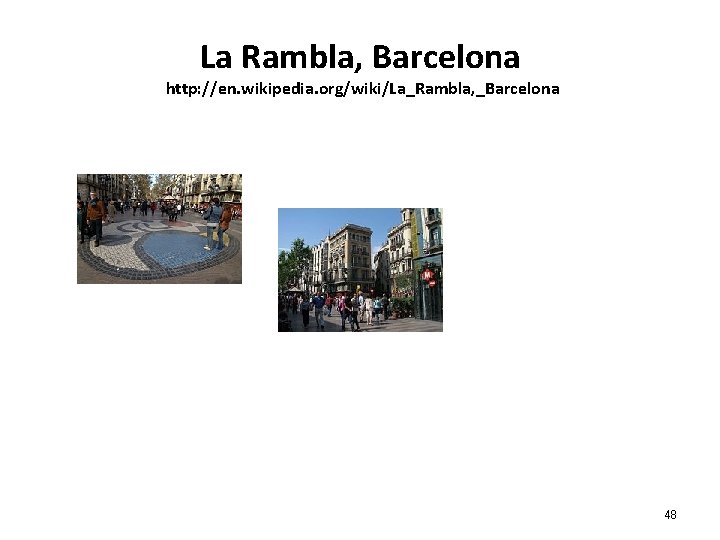
La Rambla, Barcelona http: //en. wikipedia. org/wiki/La_Rambla, _Barcelona 48
Text Mining Procedure 49
Step 1: Establishing the corpus (2014) - booking. com (949 total reviews) - Trip. Advisor (333 total reviews) - Twitter (1 review). The booking. com list was pruned to contain only reviews that contained text (i. e. reviews that just had a numeric grade and a headline were excluded). We also decided to use reviews from the past four years (2010 -2014), as older reviews may not be relevant to the state of the hotel in the present day. This left 90 reviews from booking. com, 89 from Trip. Advisor and 1 from Twitter. From these a sample of 45 reviews was obtained as follows: 1) 22 reviews from booking. com, by starting from the first review and selecting every fifth review 2) 22 reviews from Trip. Advisor divides reviews into the categories Excellent, Very good, Average, Poor, and Terrible, so a stratified sample was obtained containing 5 Excellent reviews (out of 21), 13 Very good (out of 51), 3 Average (out of 11), 1 Poor (out of 4), and 0 Terrible (out of 2). Within each stratum the reviews were selected as in the booking. com sample (every n-th review) 3) 1 review from Twitter 50
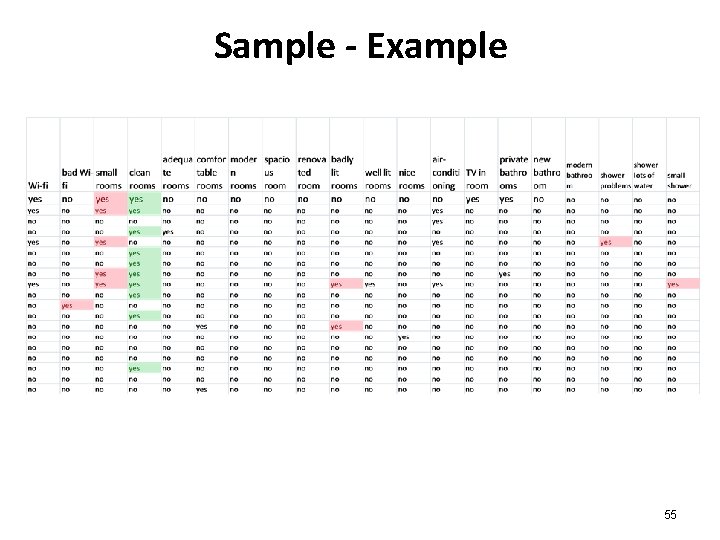
Step 2: Creating the Term-Document Matrix An Excel spreadsheet was created, with columns representing terms and rows representing each document (review). In places where a phrase was more important than a plain word, the phrase was used as a term (for example "good value for money" instead of "good", "value", and "money"). Synonymous phrases were stored as one term (for example "good location", "great location" and "liked location" became "liked location, good location"). 91 terms-phrases were recorded. Afterwards we did a further reduction of the data, by further replacing synonyms 51
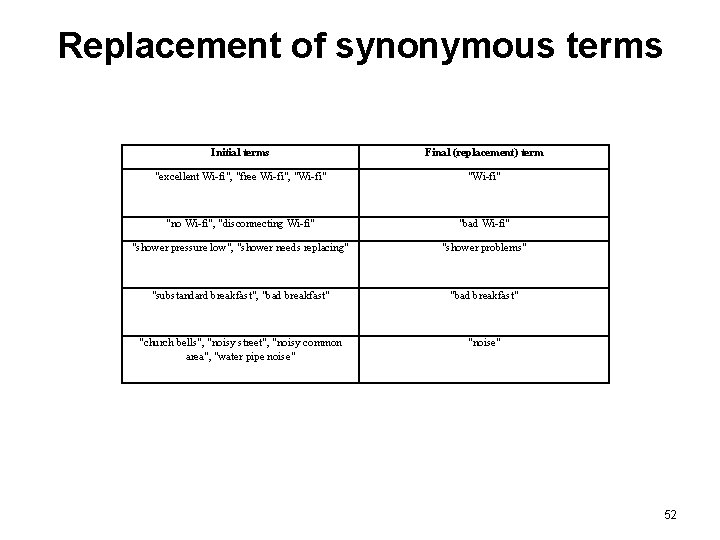
Replacement of synonymous terms Initial terms Final (replacement) term "excellent Wi-fi", "free Wi-fi", "Wi-fi" "no Wi-fi", "disconnecting Wi-fi" "bad Wi-fi" "shower pressure low", "shower needs replacing" "shower problems" "substandard breakfast", "bad breakfast" "church bells", "noisy street", "noisy common area", "water pipe noise" "noise" 52
Replacement of synonymous terms This was done in order to not only reduce the number of terms, but also to increase the frequency of some rare terms in the total amount of documents so that they would be more meaningful (for example "shower pressure low" and "shower needs replacing" appeared in only 1 document each, but when replaced with the same synonym it appears in 2 documents). This left a final 83 terms. 53
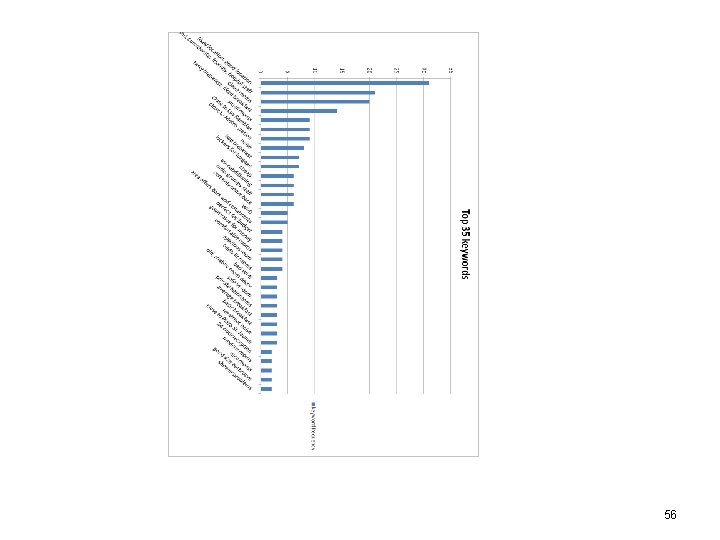
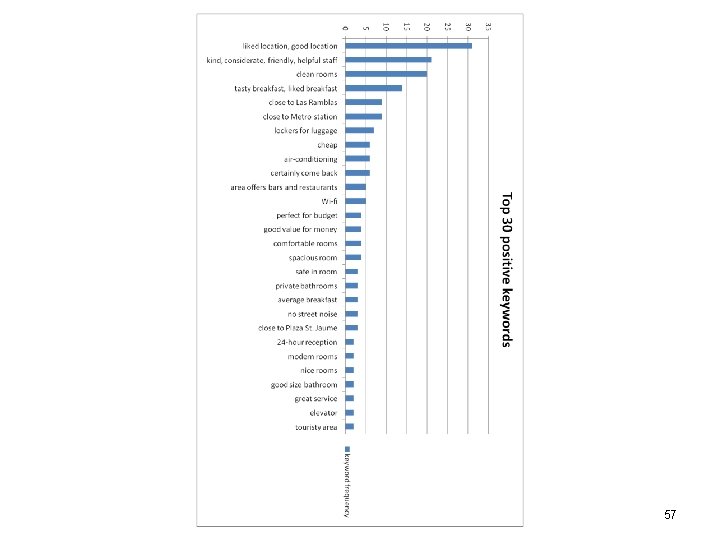
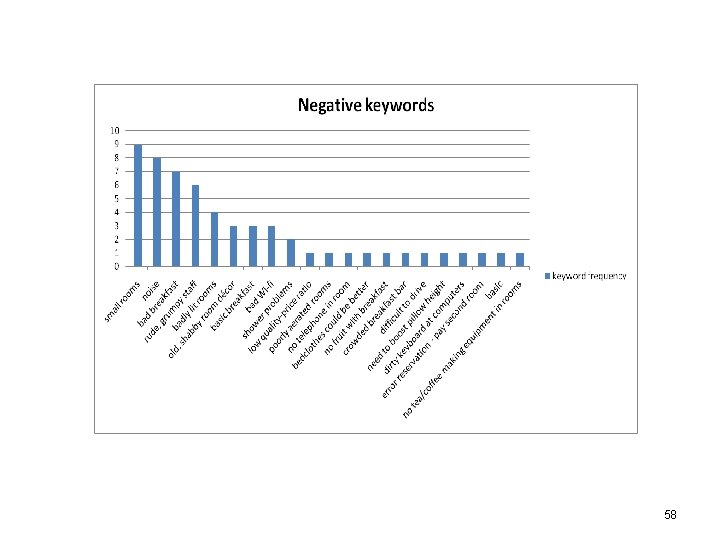
Step 3: Extracting the knowledge -The terms were sorted by frequency, i. e. how many documents they appeared in. - A histogram was created with the 35 most common terms. -Afterwards, the terms were divided into positive and negative terms and again sorted by frequency. - Histograms were created for the top 30 positive and all (21) negative terms. - Rapid. Miner can be used to find potential associations among the data. - Various algorithms could be used for this. - Examples of data sets for experimentation: 1) one containing all the data (documents and terms) 2) one containing all the documents but only the negative terms 3) one containing all the terms but only the documents that contained negative terms. 54
Sample - Example 55
56
57
58
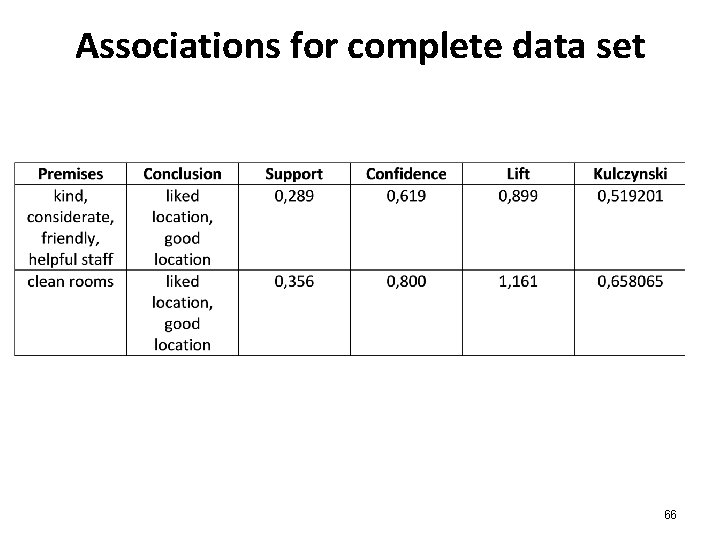
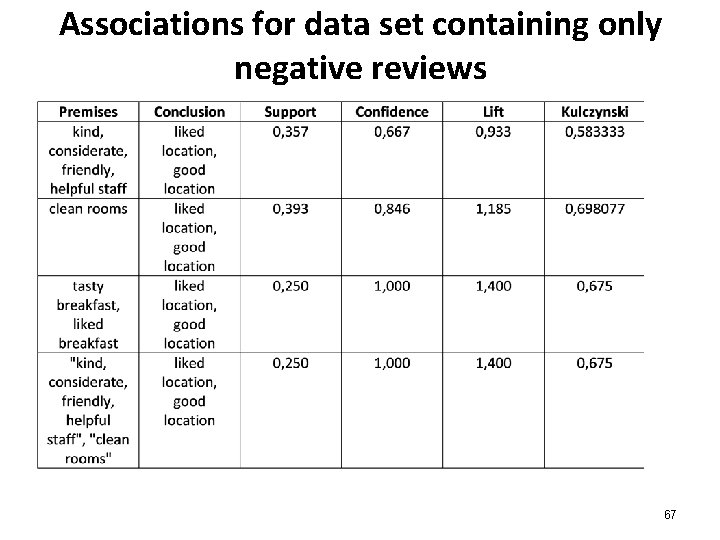
How to use the tool Rapid. Miner to find potential associations among the data The algorithm FP-Growth was used. Three data sets were used: 1) one containing all the data (documents and terms), 2) one containing all the documents but only the negative terms 3) one containing all the terms but only the documents that contained negative terms. The support threshold was 25% and the confidence threshold 60%. For each association the relationship proposed was evaluated with both the lift and the Kulczynski measure The Kulczynski measure is used to counter the effect of many nulltransactions (Han, Camber & Pei, 2011, p. 270). 59
Method In general, the associations found were not very strong. The results for the first set show a small positive association between "clean rooms" and "like location". For the second set no associations were found. For the third set we see again the small positive association between "clean rooms" and "like location". There also seems to be a slight positive association between "liked breakfast" and "liked location", and between "kind staff" and "clean rooms" and "liked location". 60
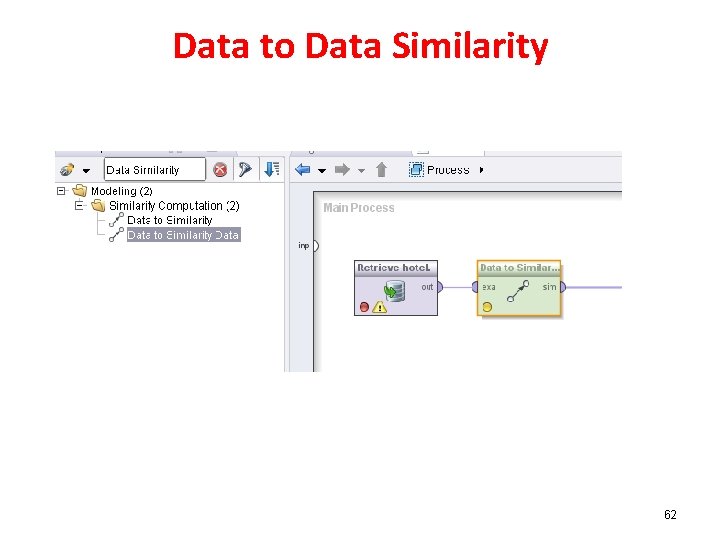
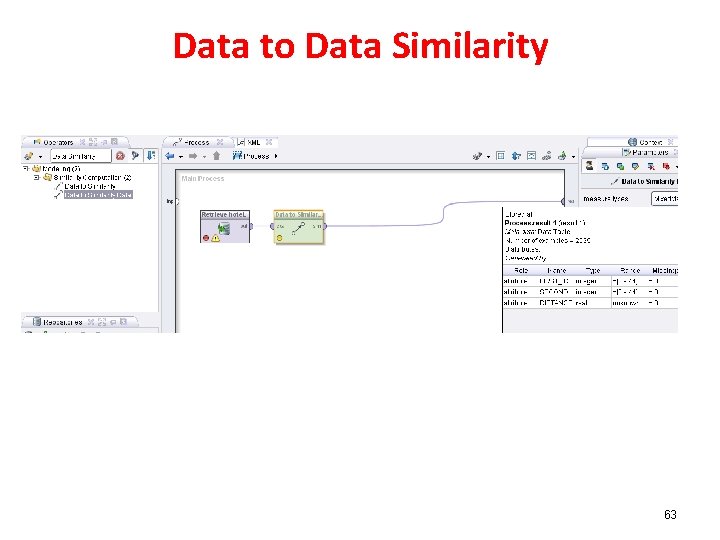
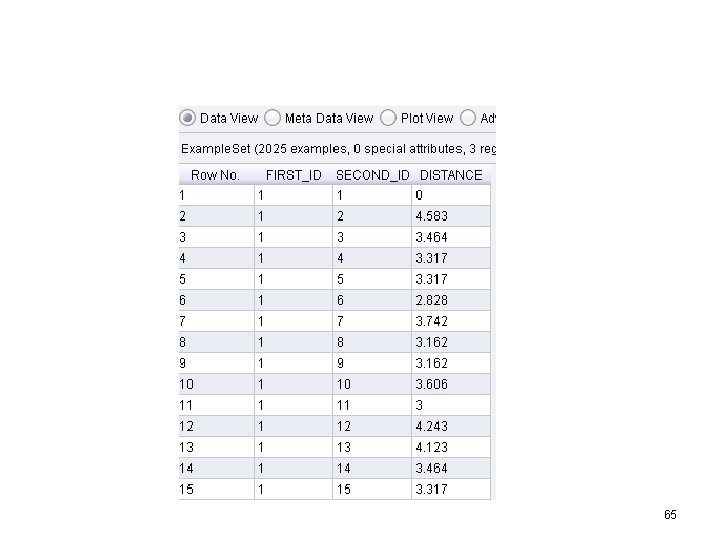
clustering • The Hopkins statistic was used to assess the clustering tendency of the data (Han, Camber & Pei, 2011, pp. 484 -486). • The distance between the documents was calculated with Rapid. Miner's Data to Data Similarity Model • Excel used to find the minimum distance. • The value found for the Hopkins statistic was H = 70/(68+70) ≈ 0. 5073, • It means that the data set is unlikely to have statistically significant clusters. • Therefore we did not proceed further with clustering. 61
Data to Data Similarity 62
Data to Data Similarity 63
Write Excel operator 64
65
Associations for complete data set 66
Associations for data set containing only negative reviews 67
Analysis The most popular website for leaving reviews was booking. com. This is not unexpected, as many hotel customers will have booked through this website and naturally turn to it to leave feedback (feedback leaving is also encouraged via email from booking. com to customers). Trip. Advisor was also very popular. Twitter, on the contrary, seemed to not be popular at all; most of the mentions of the hotel were simply someone stating that they were staying there, and only one was a review 68
Most of the reviews were generally positive, something that was reflected in the term frequency. The hotel location was cited as the most positive thing, and this probably accounts for its presence in all the association patterns. The most common problems cited were the size and state of the rooms (badly lit, shabby decor), noise, quality of the breakfast, rude or grumpy staff, and bad Wi-fi. Regarding the last three, however, more people had the opposite experience (good breakfast, kind, helpful staff, and good Wi-fi). A possible explanation is that most members of the staff are helpful, but there are some who are not and the people claiming rude or grumpy staff had experiences with the latter. 69
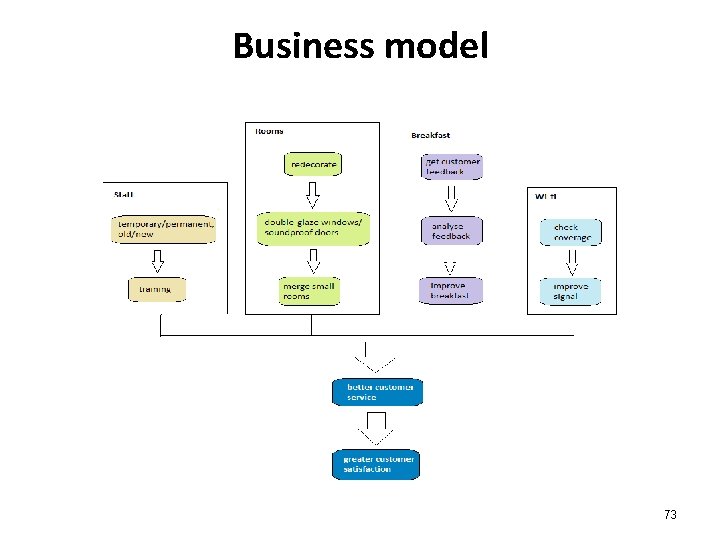
I would recommend that the hotel offer the staff some training, to ensure that they all realise the importance of being friendly and helpful. This should also be offered to every newly hired staff member and anyone hired temporarily (e. g. only for the high season), and would minimize the chance of customers having a negative experience with a staff member. 70
Regarding the rooms, redecorating should be done to those rooms that have not yet been renovated to fix the shabby decor. Windows should be double-glazed and the doors should be soundproofed, to reduce the noise in the rooms. About the lighting and the size there is probably not much that can be done, as it depends on the hotel's location, however the owners might want to look into knocking down some walls between some of the smaller rooms to create one bigger room (for example two small twin rooms could be merged to create one triple room). 71
As far as breakfast is concerned, We recommend that the management ask for customer feedback and recommendations to pinpoint more precisely what some people think is wrong with the breakfast. Is it not varied enough? Is the quality of the food offered bad? They should leave feedback forms in the breakfast area and/or the rooms asking customers to rate different aspects of the breakfast and offer suggestions for its improvement. Then they must act on the feedback they get. The Wi-fi coverage should be checked to ensure all rooms have a good quality signal. If, as seems likely, some rooms are found to have poor signal, steps should be taken to correct this. 72
Business model 73
Conclusions 74
Text mining has offered an interesting insight into customers’ opinions about Hostal Fernando. Although for the most part the feedback has been positive, there have been some rather common complaints, the most popular of which were the size of the rooms and noise, which show there is room for improvement. My recommendations are that the hotel owners redecorate, refurbish, offer training to their staff, ensure Wi-fi signal quality in all rooms and solicit customer feedback in order to gain a better understanding of certain complaints. In this way customer satisfaction will improve and the hotel will remain antagonistic as a business in the future. 75
References 1. Han, J. , Kamber, M. and Pei, J. , 2011. Data Mining: Concepts and Techniques. 3 rd ed. Saint Lous: Morgan Kaufmann. 2. Turban, E. , Sharda, R. , Delen, D. , King, D. and Aronson, J. E. , 2011. Business Intelligence: a managerial approach. 2 nd ed. Upper Saddle River: Pearson Prentice Hall. 3. M. North, Data Mining for the Masses, 2012, ISBN: 978 -0615684376 76