0319 review MIPS Use general purpose registers with
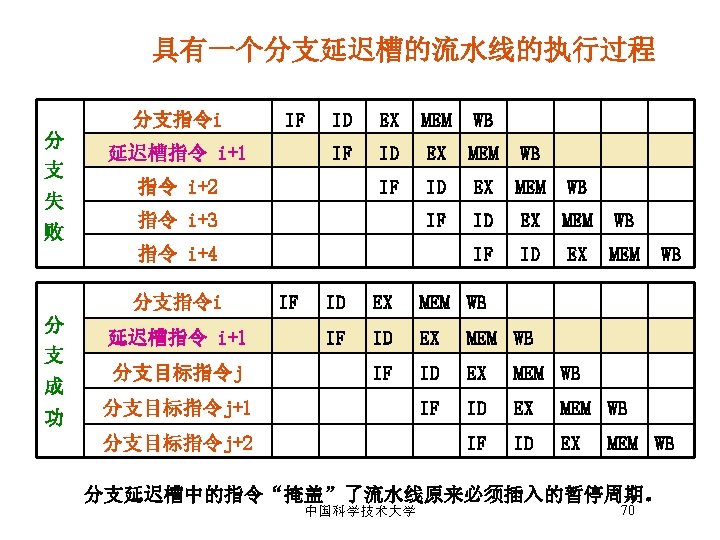
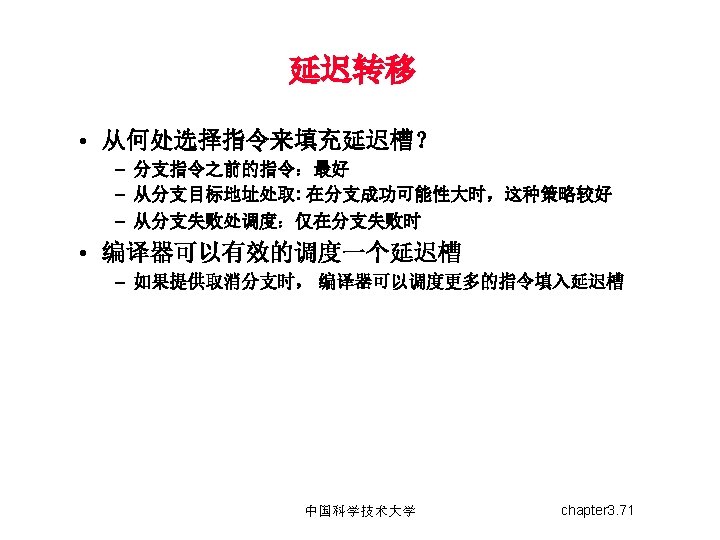
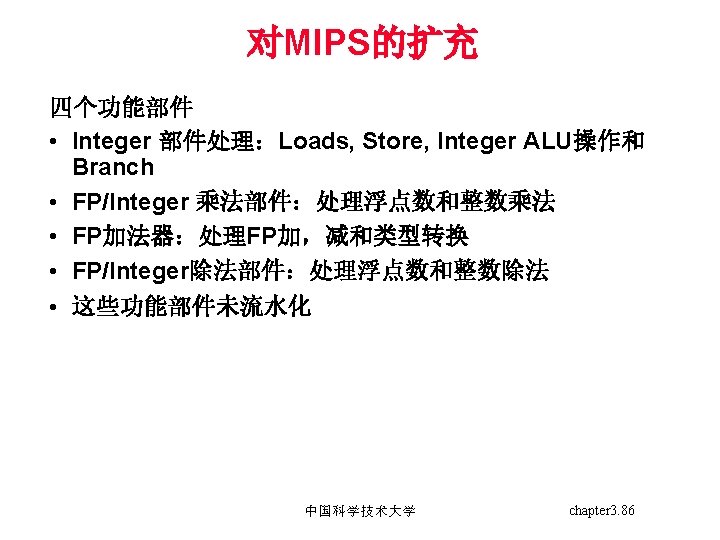
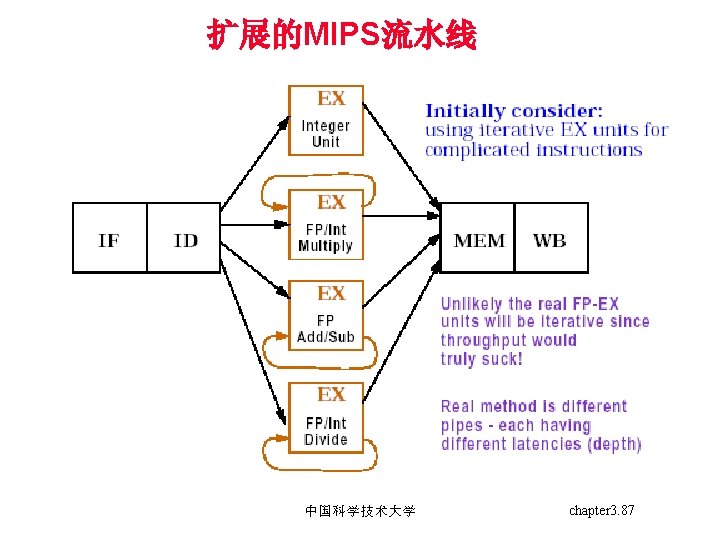
- Slides: 124
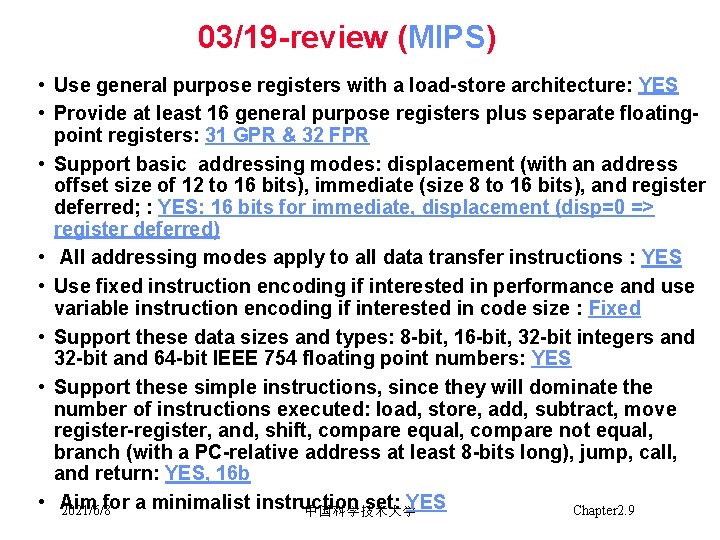
03/19 -review (MIPS) • Use general purpose registers with a load-store architecture: YES • Provide at least 16 general purpose registers plus separate floatingpoint registers: 31 GPR & 32 FPR • Support basic addressing modes: displacement (with an address offset size of 12 to 16 bits), immediate (size 8 to 16 bits), and register deferred; : YES: 16 bits for immediate, displacement (disp=0 => register deferred) • All addressing modes apply to all data transfer instructions : YES • Use fixed instruction encoding if interested in performance and use variable instruction encoding if interested in code size : Fixed • Support these data sizes and types: 8 -bit, 16 -bit, 32 -bit integers and 32 -bit and 64 -bit IEEE 754 floating point numbers: YES • Support these simple instructions, since they will dominate the number of instructions executed: load, store, add, subtract, move register-register, and, shift, compare equal, compare not equal, branch (with a PC-relative address at least 8 -bits long), jump, call, and return: YES, 16 b • Aim for a minimalist instruction set: YES 2021/6/8 Chapter 2. 9 中国科学技术大学
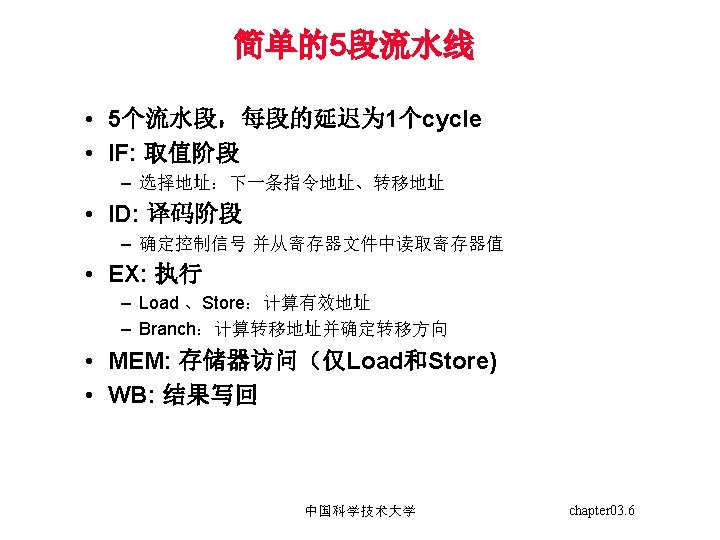
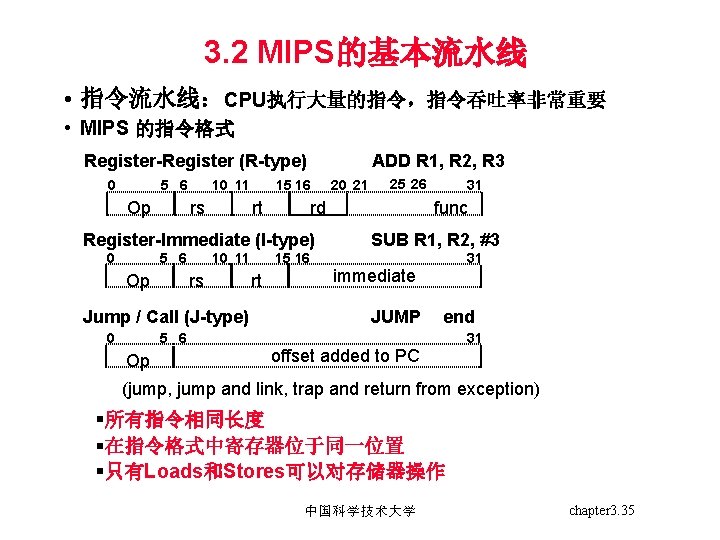
3. 2 MIPS的基本流水线 • 指令流水线:CPU执行大量的指令,指令吞吐率非常重要 • MIPS 的指令格式 Register-Register (R-type) 0 5 6 Op 10 11 rs ADD R 1, R 2, R 3 15 16 rt 10 11 5 6 Op rs Jump / Call (J-type) 5 6 0 Op 25 26 rd Register-Immediate (I-type) 0 20 21 31 func SUB R 1, R 2, #3 15 16 rt 31 immediate JUMP end offset added to PC 31 (jump, jump and link, trap and return from exception) §所有指令相同长度 §在指令格式中寄存器位于同一位置 §只有Loads和Stores可以对存储器操作 中国科学技术大学 chapter 3. 35
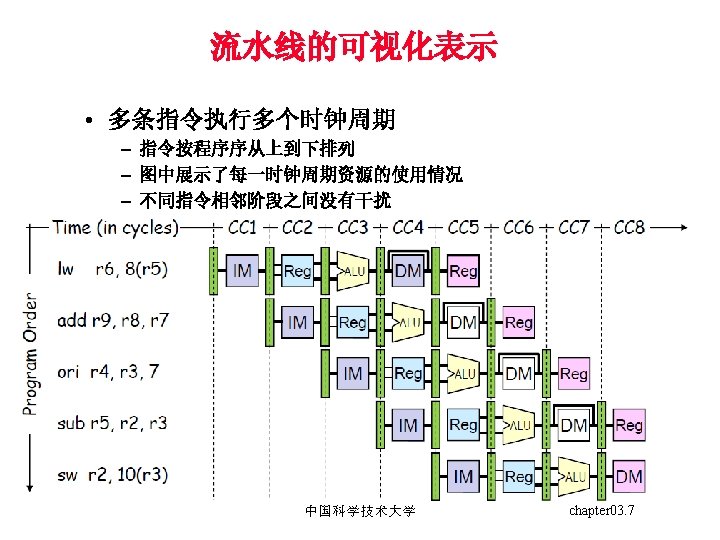
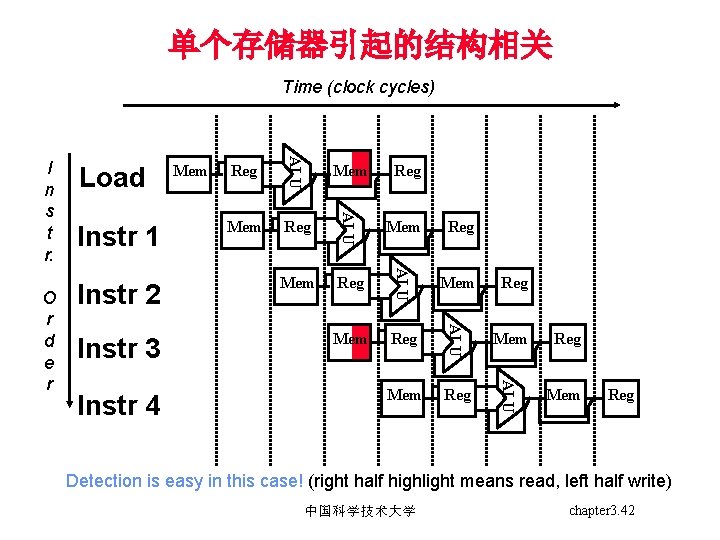
单个存储器引起的结构相关 Time (clock cycles) Instr 4 Reg Mem Reg Mem Reg ALU Instr 3 Mem ALU Instr 2 Reg ALU Instr 1 Mem ALU O r d e r Load ALU I n s t r. Mem Reg Detection is easy in this case! (right half highlight means read, left half write) 中国科学技术大学 chapter 3. 42
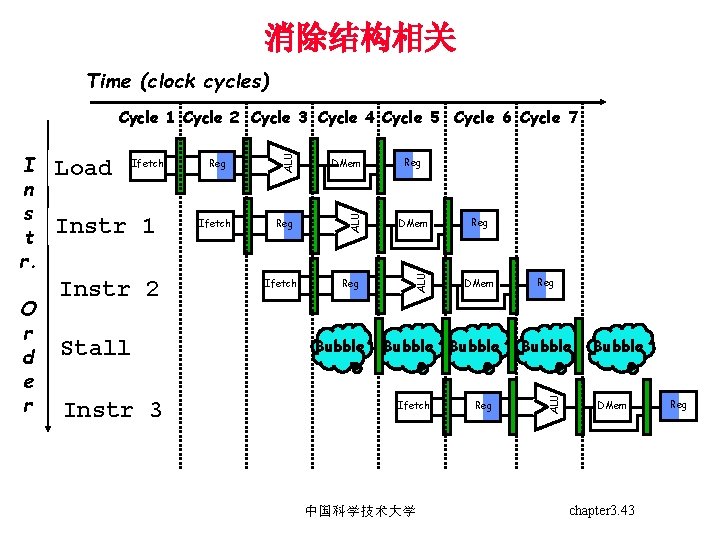
消除结构相关 Time (clock cycles) Instr 1 Instr 2 Stall Instr 3 Reg Ifetch DMem Reg ALU Ifetch Bubble Reg DMem Bubble Ifetch 中国科学技术大学 Reg Bubble ALU O r d e r Load ALU I n s t r. ALU Cycle 1 Cycle 2 Cycle 3 Cycle 4 Cycle 5 Cycle 6 Cycle 7 Bubble DMem chapter 3. 43 Reg
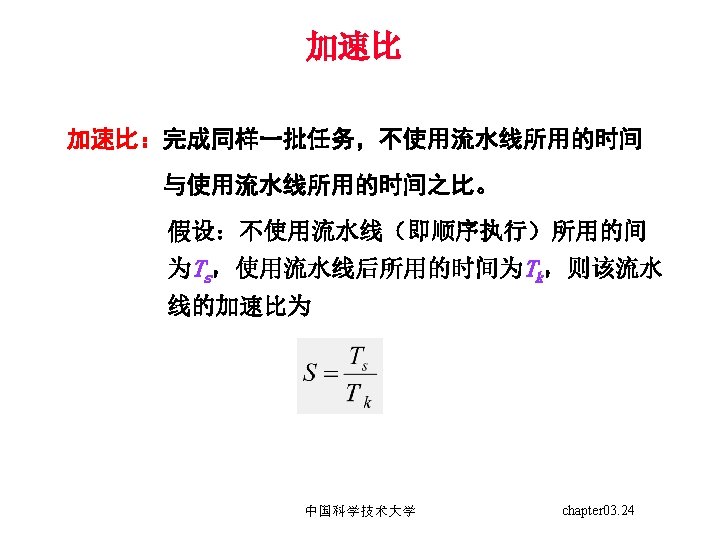
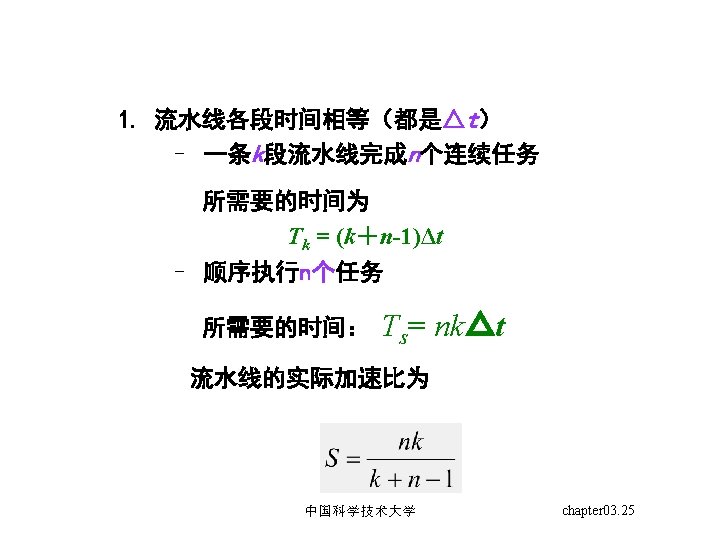
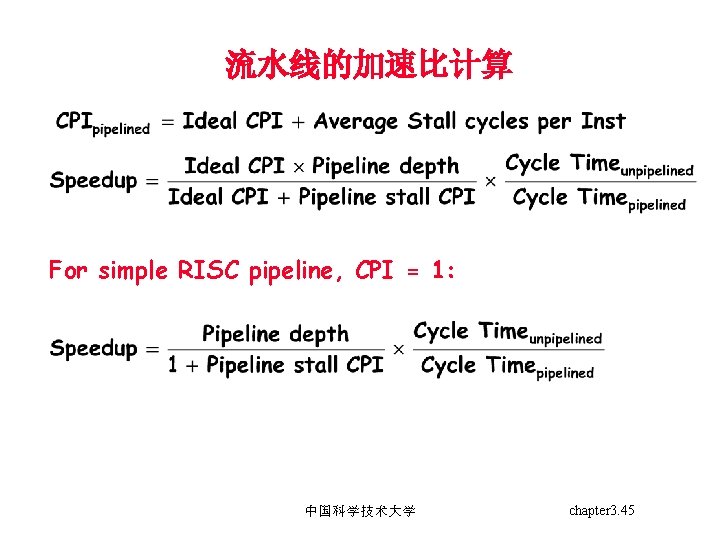
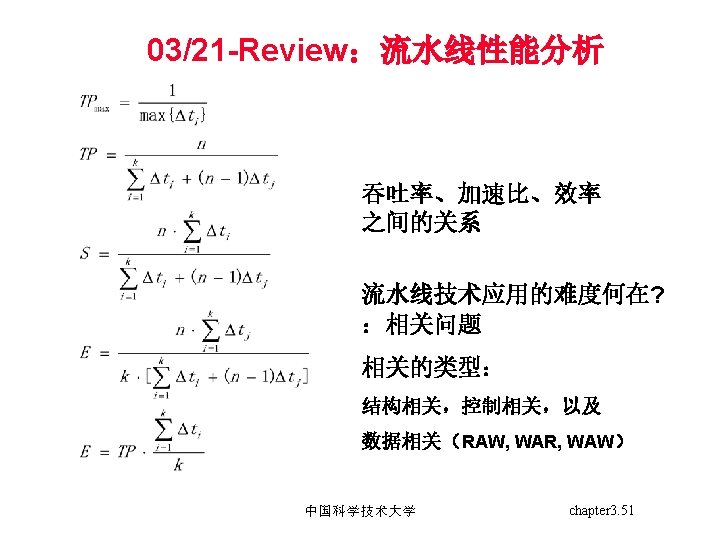
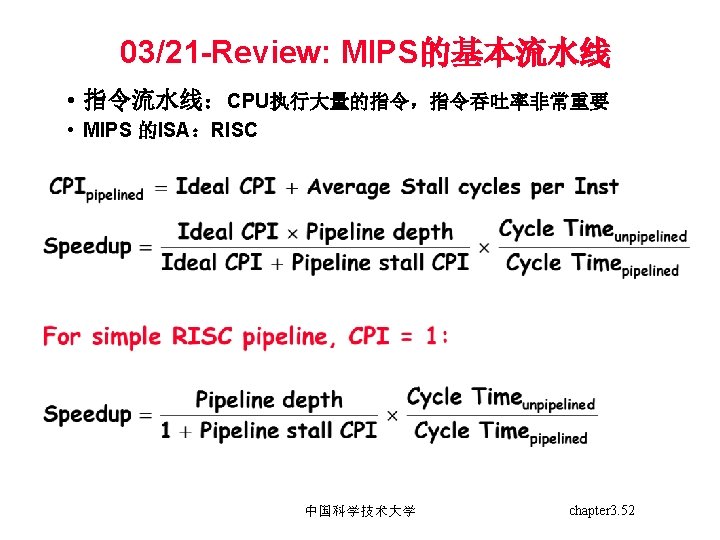
流水线的加速比计算 For simple RISC pipeline, CPI = 1: 中国科学技术大学 chapter 3. 45
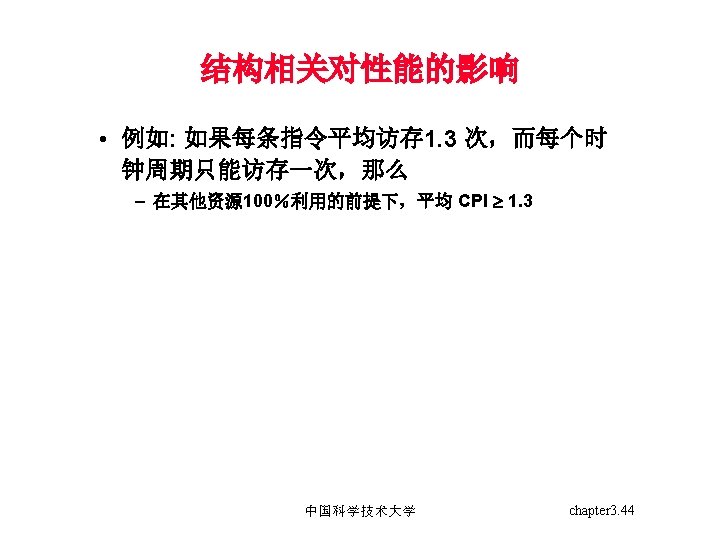
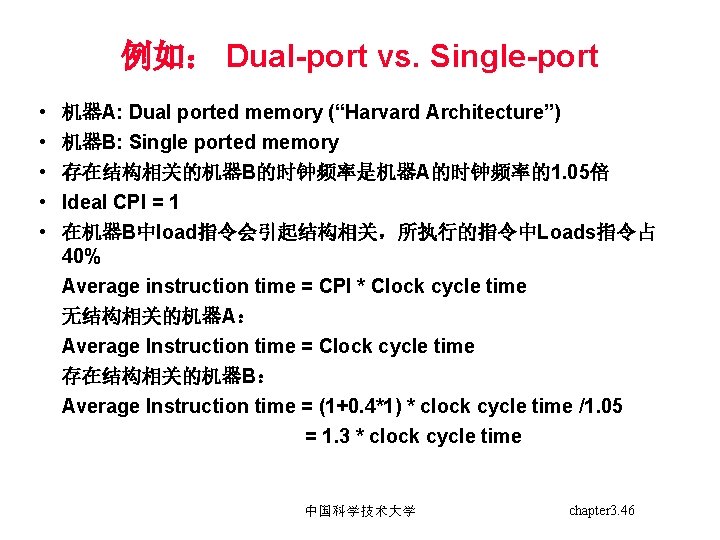
例如: Dual-port vs. Single-port • • • 机器A: Dual ported memory (“Harvard Architecture”) 机器B: Single ported memory 存在结构相关的机器B的时钟频率是机器A的时钟频率的1. 05倍 Ideal CPI = 1 在机器B中load指令会引起结构相关,所执行的指令中Loads指令占 40% Average instruction time = CPI * Clock cycle time 无结构相关的机器A: Average Instruction time = Clock cycle time 存在结构相关的机器B: Average Instruction time = (1+0. 4*1) * clock cycle time /1. 05 = 1. 3 * clock cycle time 中国科学技术大学 chapter 3. 46
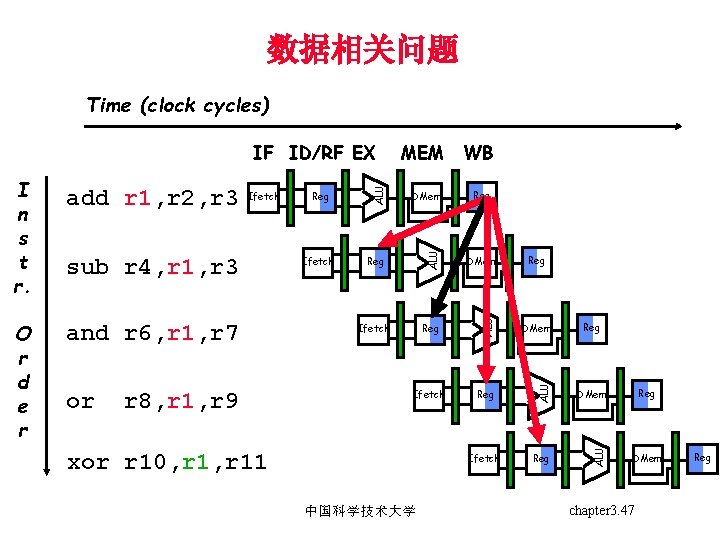
数据相关问题 Time (clock cycles) and r 6, r 1, r 7 or r 8, r 1, r 9 Ifetch DMem Reg DMem Ifetch Reg ALU sub r 4, r 1, r 3 Reg ALU Ifetch ALU O r d e r add r 1, r 2, r 3 WB ALU I n s t r. MEM ALU IF ID/RF EX xor r 10, r 11 中国科学技术大学 Reg Reg DMem chapter 3. 47 Reg
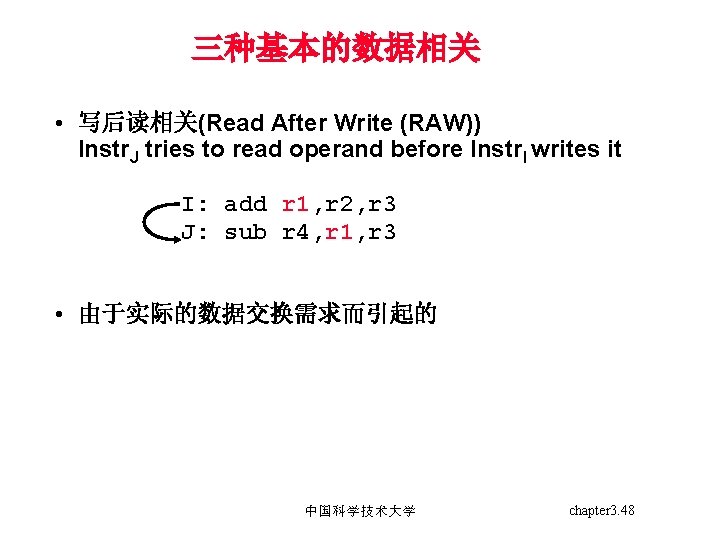
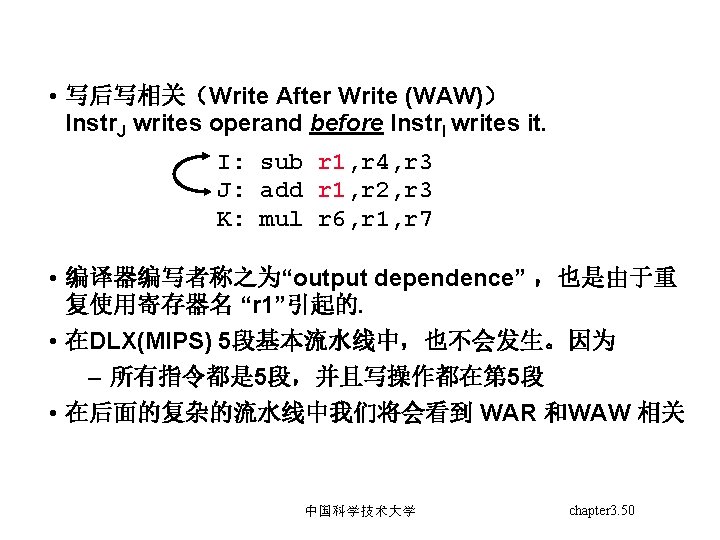
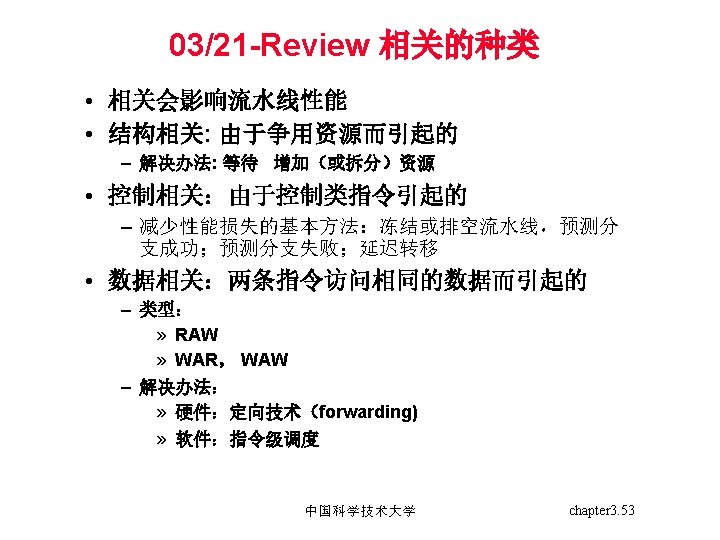
三种基本的数据相关 • 写后读相关(Read After Write (RAW)) Instr. J tries to read operand before Instr. I writes it I: add r 1, r 2, r 3 J: sub r 4, r 1, r 3 • 由于实际的数据交换需求而引起的 中国科学技术大学 chapter 3. 48
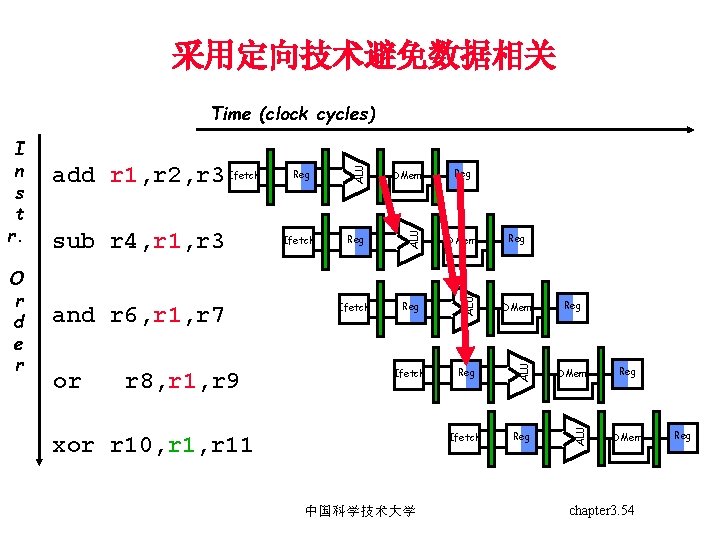
采用定向技术避免数据相关 or r 8, r 1, r 9 Reg DMem Ifetch Reg ALU and r 6, r 1, r 7 Ifetch DMem ALU sub r 4, r 1, r 3 Reg ALU O r d e r add r 1, r 2, r 3 Ifetch ALU I n s t r. ALU Time (clock cycles) xor r 10, r 11 中国科学技术大学 Reg Reg DMem chapter 3. 54 Reg
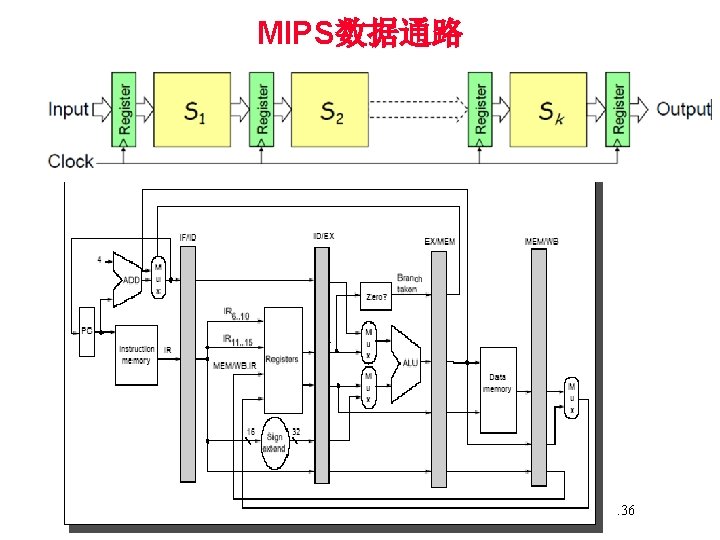
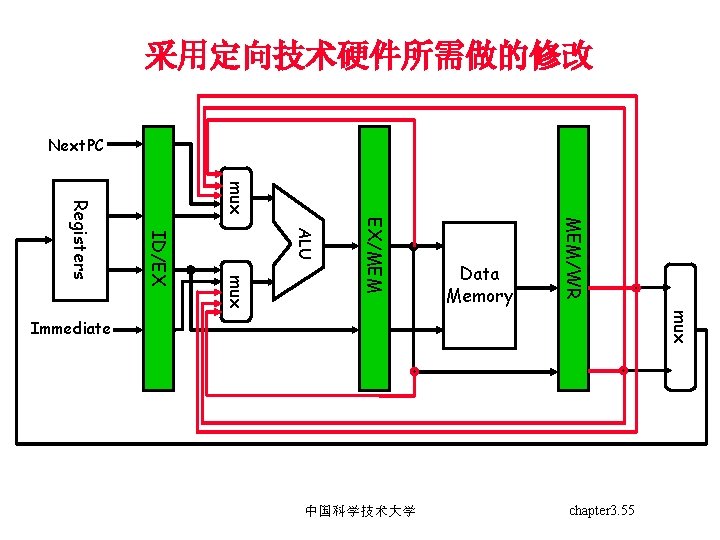
采用定向技术硬件所需做的修改 Next. PC mux MEM/WR EX/MEM ALU mux ID/EX Registers Data Memory mux Immediate 中国科学技术大学 chapter 3. 55
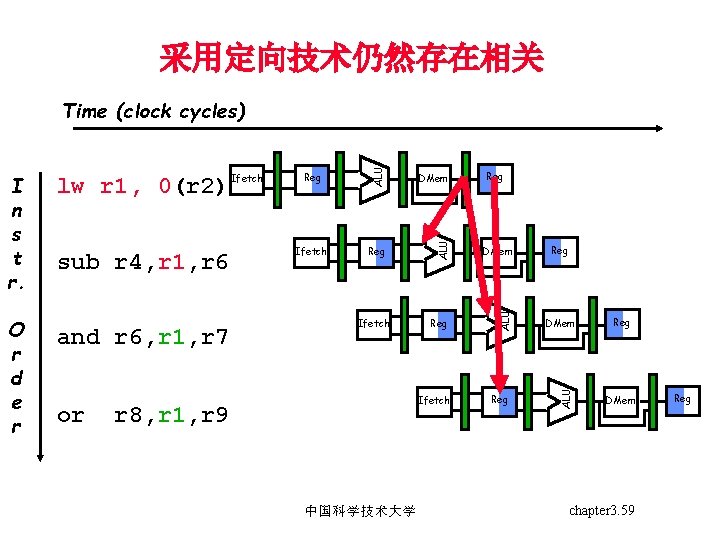
采用定向技术仍然存在相关 and r 6, r 1, r 7 or DMem Ifetch Reg DMem Reg Ifetch r 8, r 1, r 9 中国科学技术大学 Reg Reg DMem ALU sub r 4, r 1, r 6 Reg ALU O r d e r lw r 1, 0(r 2) Ifetch ALU I n s t r. ALU Time (clock cycles) Reg DMem chapter 3. 59 Reg
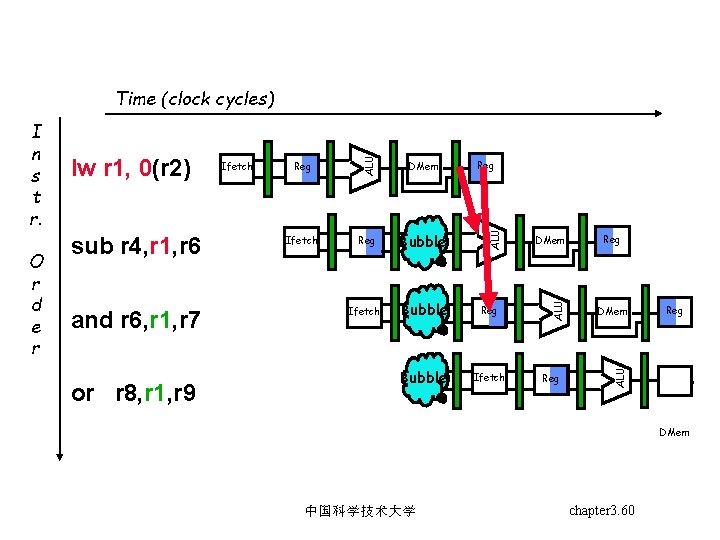
and r 6, r 1, r 7 or r 8, r 1, r 9 Reg DMem Ifetch Reg Bubble Ifetch Bubble Reg Bubble Ifetch Reg DMem Reg ALU sub r 4, r 1, r 6 Ifetch ALU O r d e r lw r 1, 0(r 2) ALU I n s t r. ALU Time (clock cycles) DMem 中国科学技术大学 chapter 3. 60
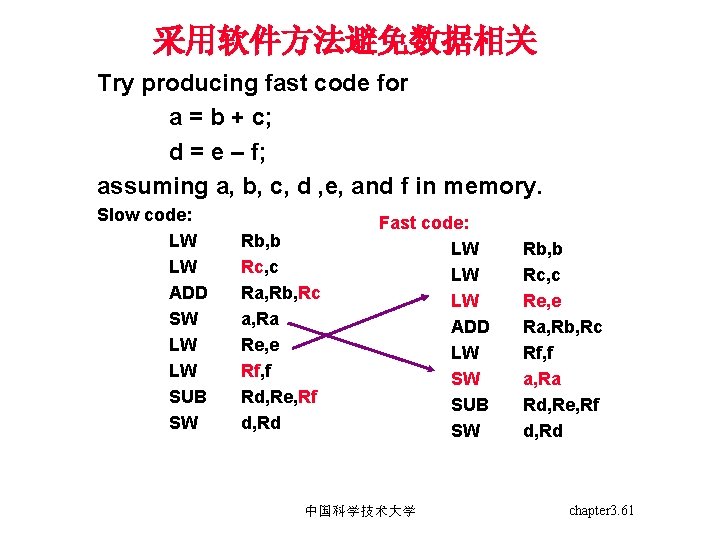
采用软件方法避免数据相关 Try producing fast code for a = b + c; d = e – f; assuming a, b, c, d , e, and f in memory. Slow code: LW LW ADD SW LW LW SUB SW Rb, b Rc, c Ra, Rb, Rc a, Ra Re, e Rf, f Rd, Re, Rf d, Rd Fast code: LW LW LW ADD LW SW SUB SW 中国科学技术大学 Rb, b Rc, c Re, e Ra, Rb, Rc Rf, f a, Ra Rd, Re, Rf d, Rd chapter 3. 61
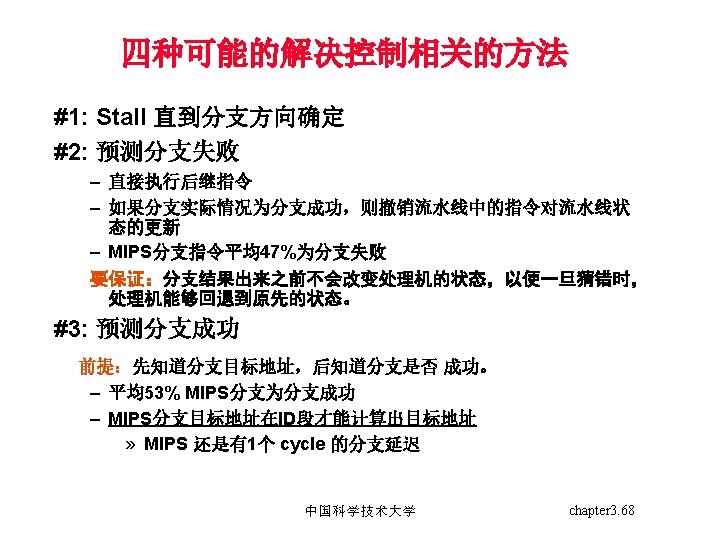
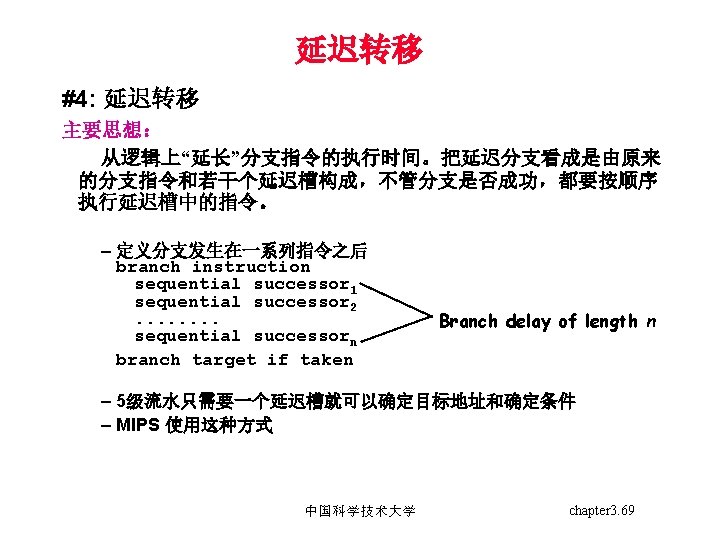
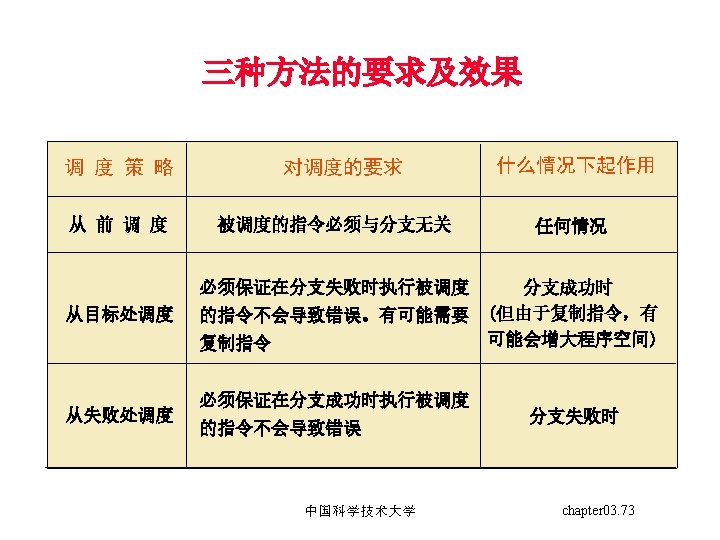
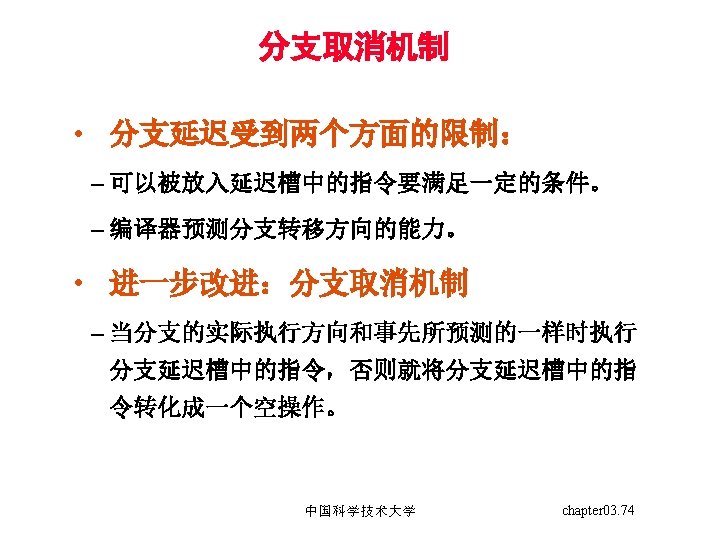
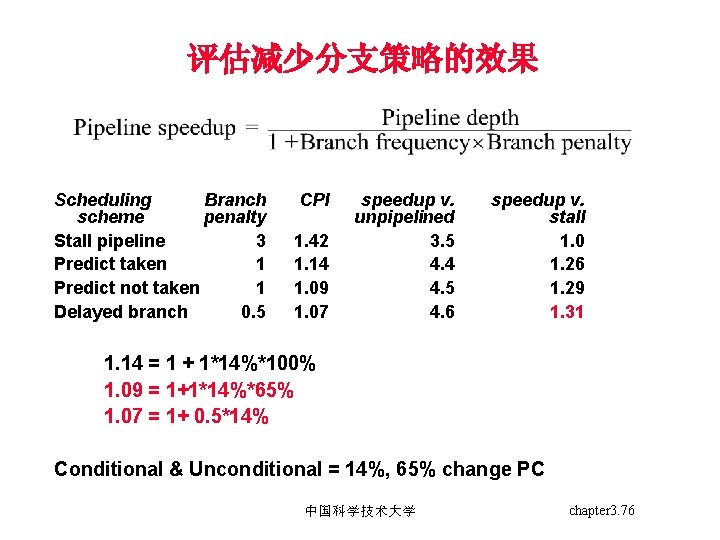
评估减少分支策略的效果 Scheduling Branch scheme penalty Stall pipeline 3 Predict taken 1 Predict not taken 1 Delayed branch 0. 5 CPI 1. 42 1. 14 1. 09 1. 07 speedup v. unpipelined 3. 5 4. 4 4. 5 4. 6 speedup v. stall 1. 0 1. 26 1. 29 1. 31 1. 14 = 1 + 1*14%*100% 1. 09 = 1+1*14%*65% 1. 07 = 1+ 0. 5*14% Conditional & Unconditional = 14%, 65% change PC 中国科学技术大学 chapter 3. 76
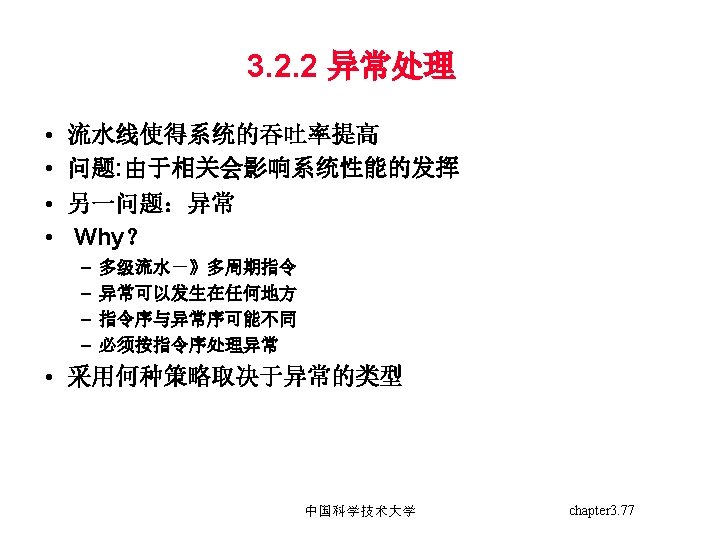
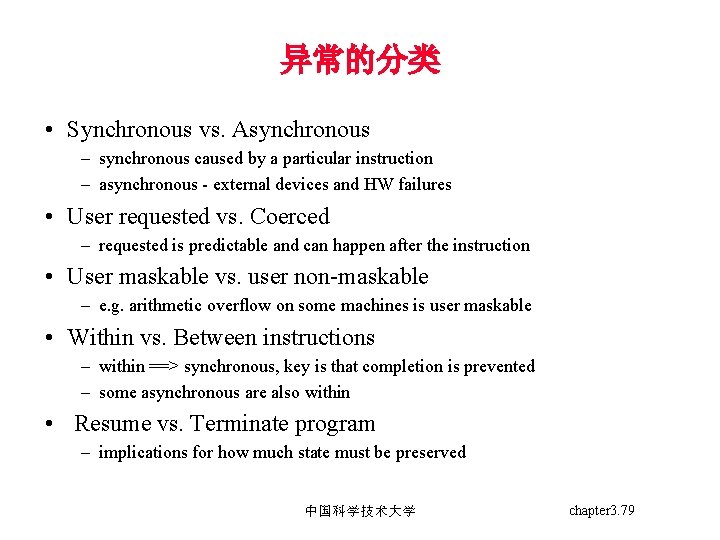
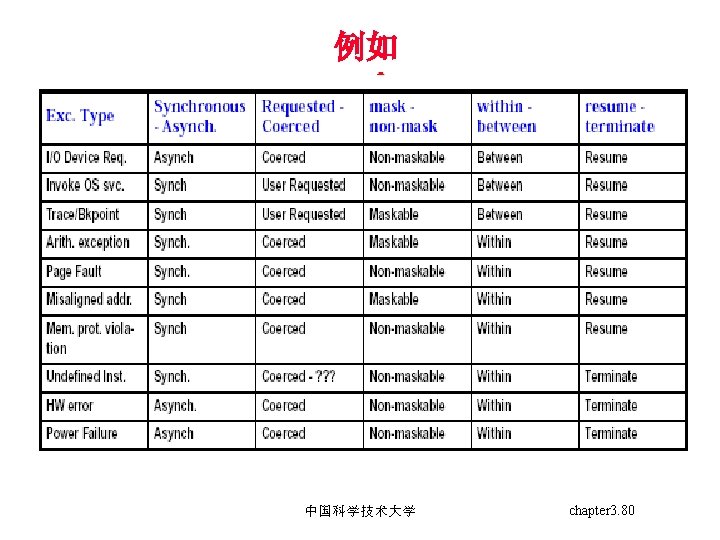
异常的分类 • Synchronous vs. Asynchronous – synchronous caused by a particular instruction – asynchronous - external devices and HW failures • User requested vs. Coerced – requested is predictable and can happen after the instruction • User maskable vs. user non-maskable – e. g. arithmetic overflow on some machines is user maskable • Within vs. Between instructions – within ==> synchronous, key is that completion is prevented – some asynchronous are also within • Resume vs. Terminate program – implications for how much state must be preserved 中国科学技术大学 chapter 3. 79
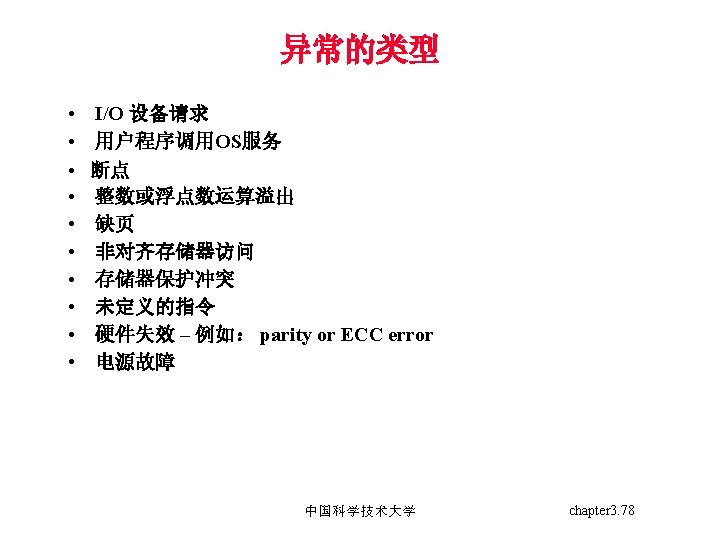
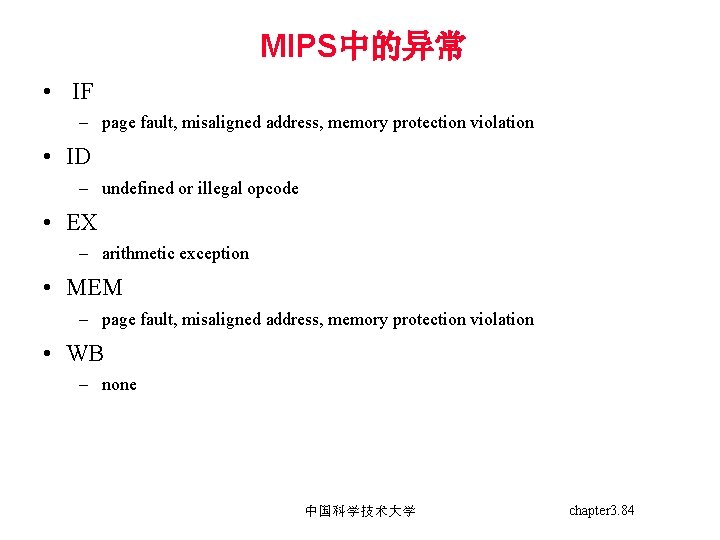
MIPS中的异常 • IF – page fault, misaligned address, memory protection violation • ID – undefined or illegal opcode • EX – arithmetic exception • MEM – page fault, misaligned address, memory protection violation • WB – none 中国科学技术大学 chapter 3. 84
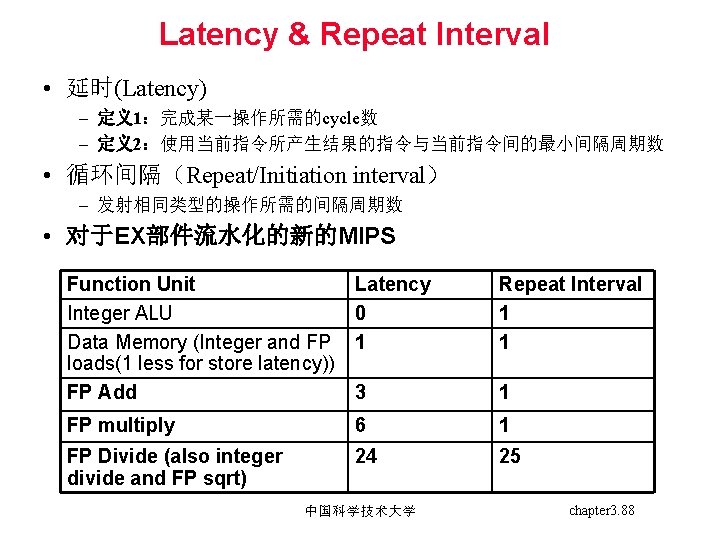
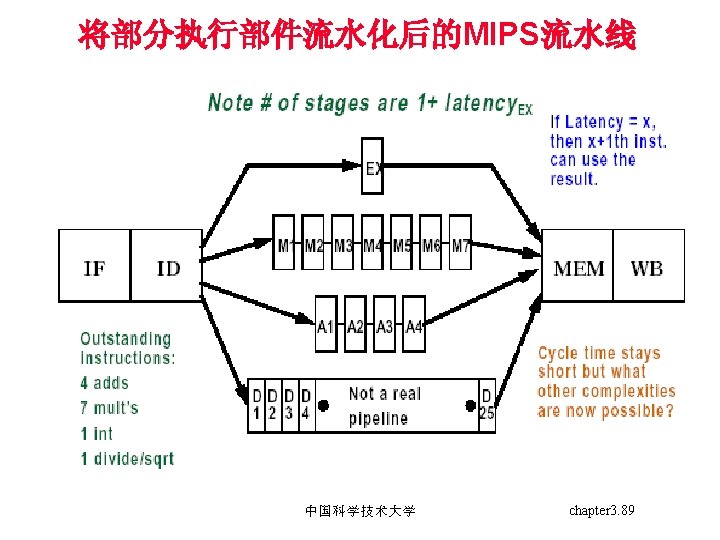
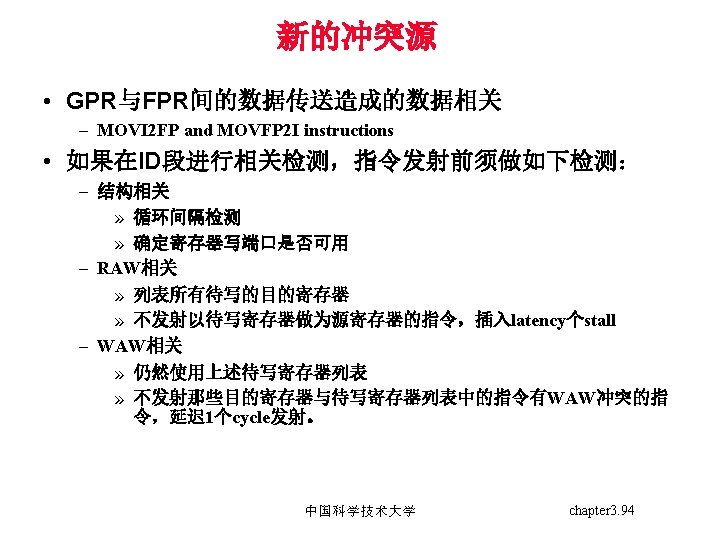
Latency & Repeat Interval • 延时(Latency) – 定义1:完成某一操作所需的cycle数 – 定义2:使用当前指令所产生结果的指令与当前指令间的最小间隔周期数 • 循环间隔(Repeat/Initiation interval) – 发射相同类型的操作所需的间隔周期数 • 对于EX部件流水化的新的MIPS Function Unit Integer ALU Data Memory (Integer and FP loads(1 less for store latency)) FP Add Latency 0 1 Repeat Interval 1 1 3 1 FP multiply 6 1 FP Divide (also integer divide and FP sqrt) 24 25 中国科学技术大学 chapter 3. 88
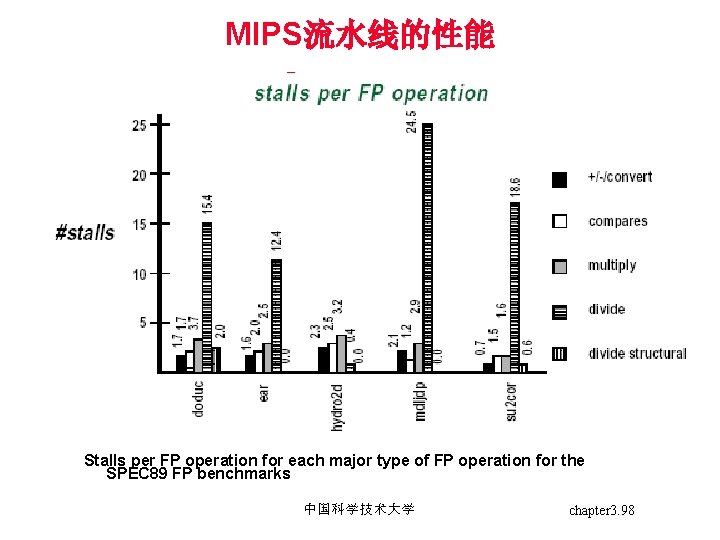
MIPS流水线的性能 Stalls per FP operation for each major type of FP operation for the SPEC 89 FP benchmarks 中国科学技术大学 chapter 3. 98
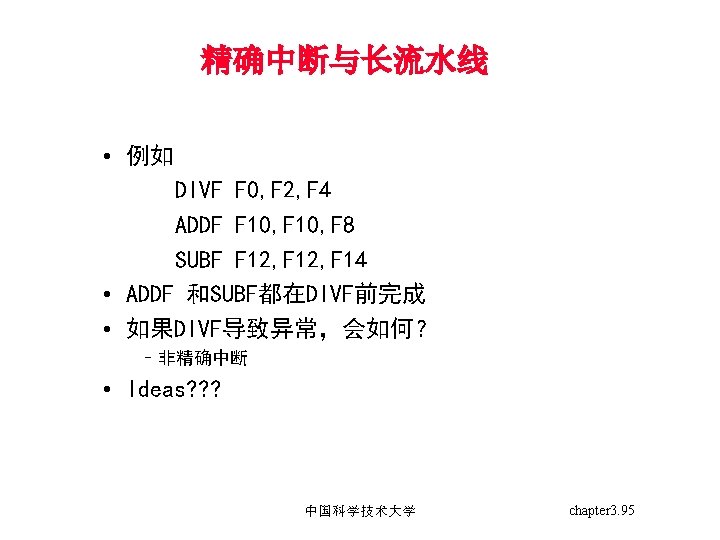
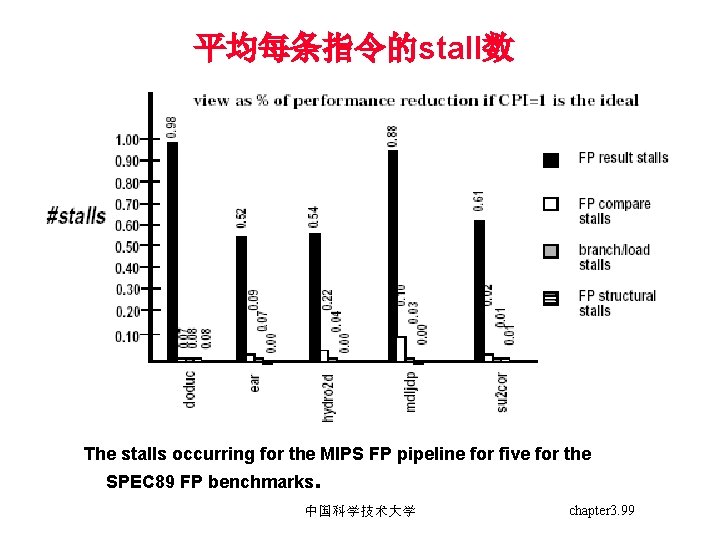
平均每条指令的stall数 The stalls occurring for the MIPS FP pipeline for five for the SPEC 89 FP benchmarks. 中国科学技术大学 chapter 3. 99
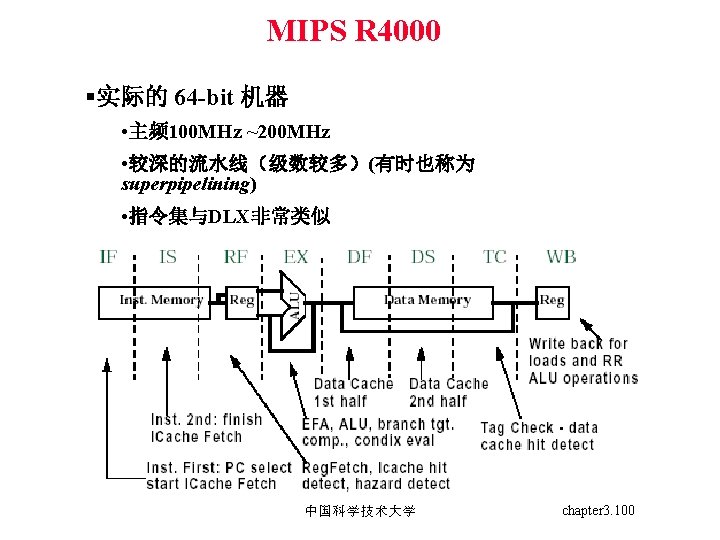
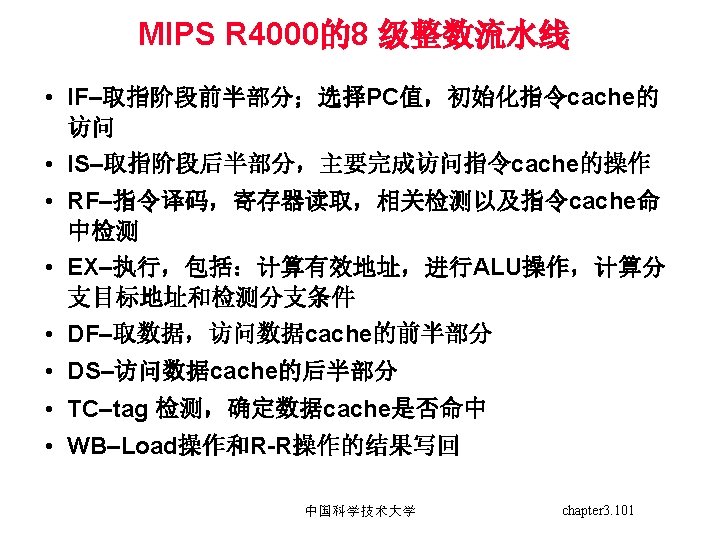
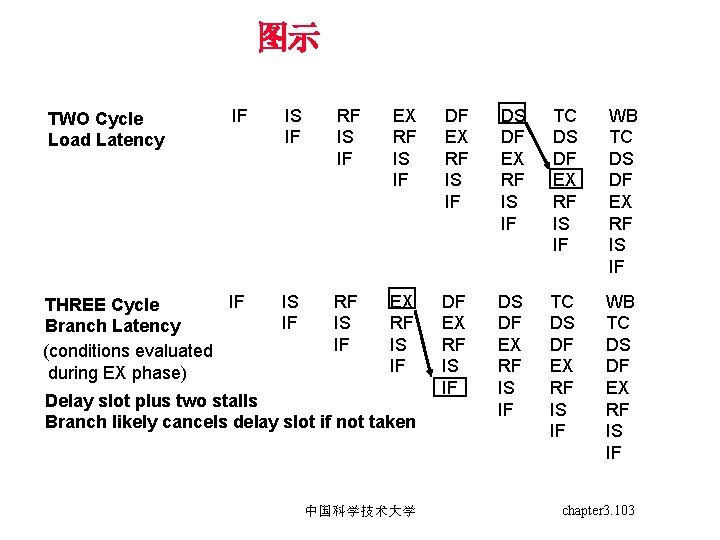
图示 IF IS IF RF IS IF EX RF IS IF DS DF EX RF IS IF TC DS DF EX RF IS IF WB TC DS DF EX RF IS IF IF THREE Cycle Branch Latency (conditions evaluated during EX phase) IS IF RF IS IF EX RF IS IF DS DF EX RF IS IF TC DS DF EX RF IS IF WB TC DS DF EX RF IS IF TWO Cycle Load Latency Delay slot plus two stalls Branch likely cancels delay slot if not taken 中国科学技术大学 chapter 3. 103
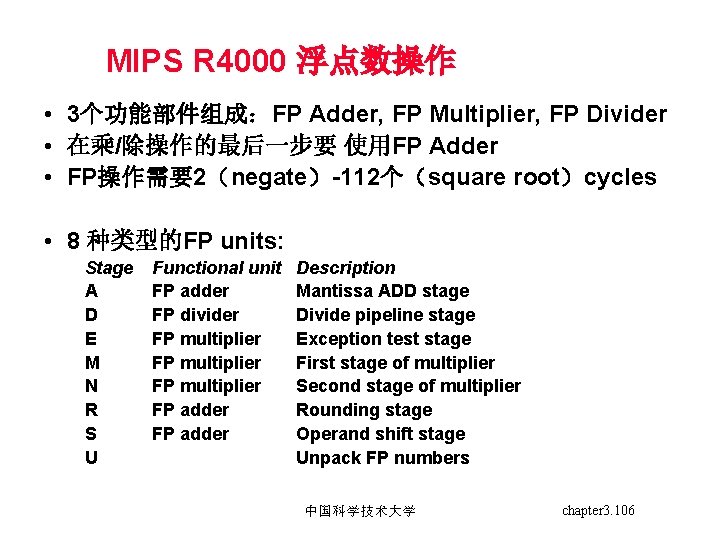
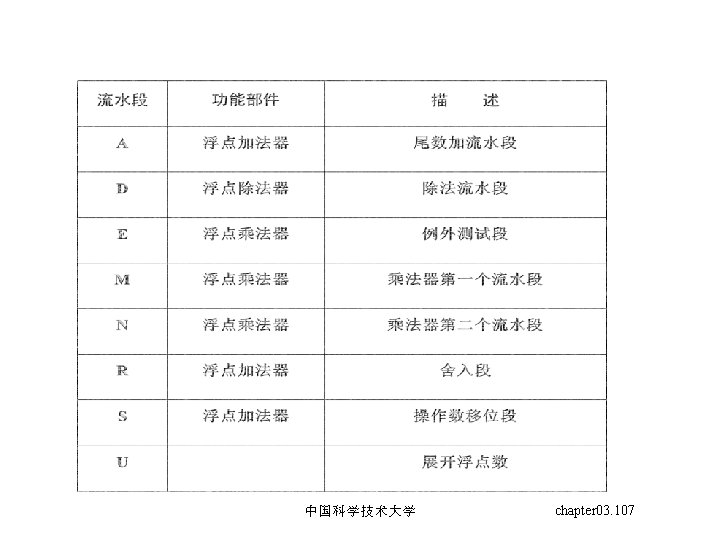
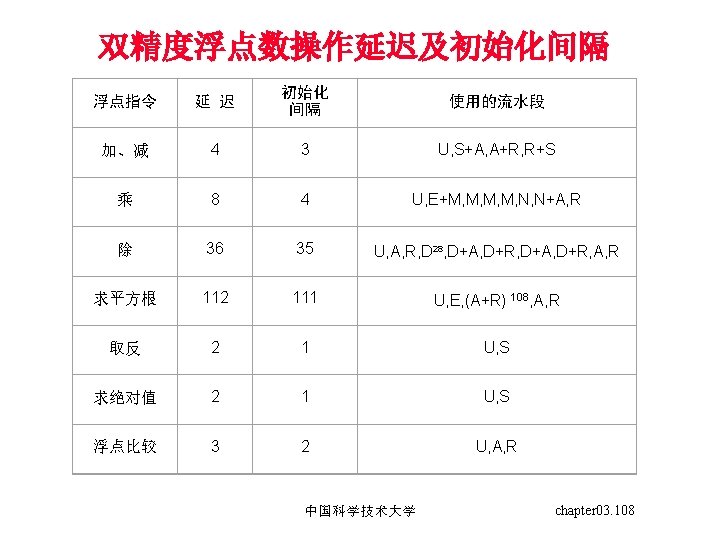
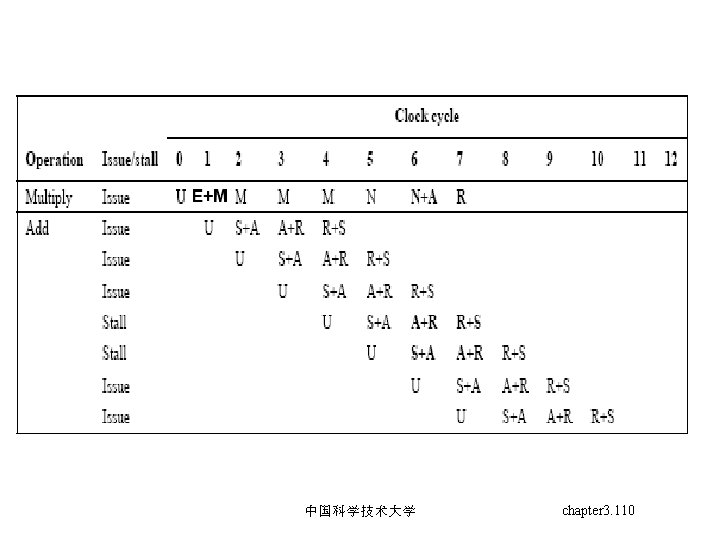
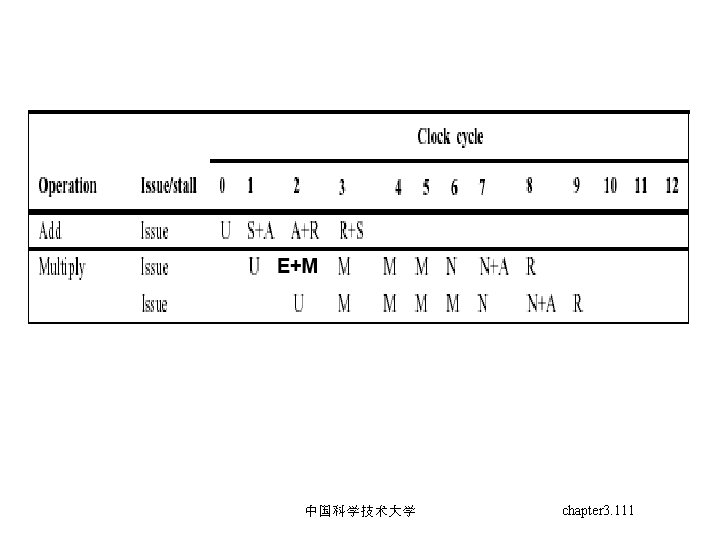
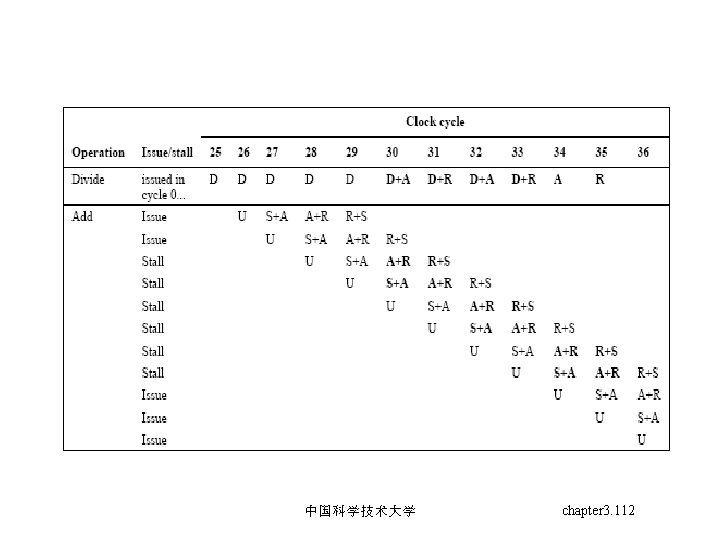
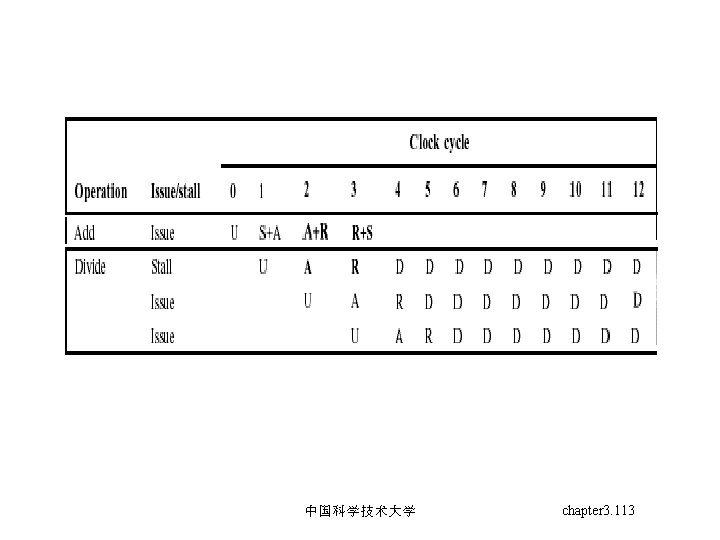
MIPS R 4000 浮点数操作 • 3个功能部件组成:FP Adder, FP Multiplier, FP Divider • 在乘/除操作的最后一步要 使用FP Adder • FP操作需要2(negate)-112个(square root)cycles • 8 种类型的FP units: Stage A D E M N R S U Functional unit FP adder FP divider FP multiplier FP adder Description Mantissa ADD stage Divide pipeline stage Exception test stage First stage of multiplier Second stage of multiplier Rounding stage Operand shift stage Unpack FP numbers 中国科学技术大学 chapter 3. 106
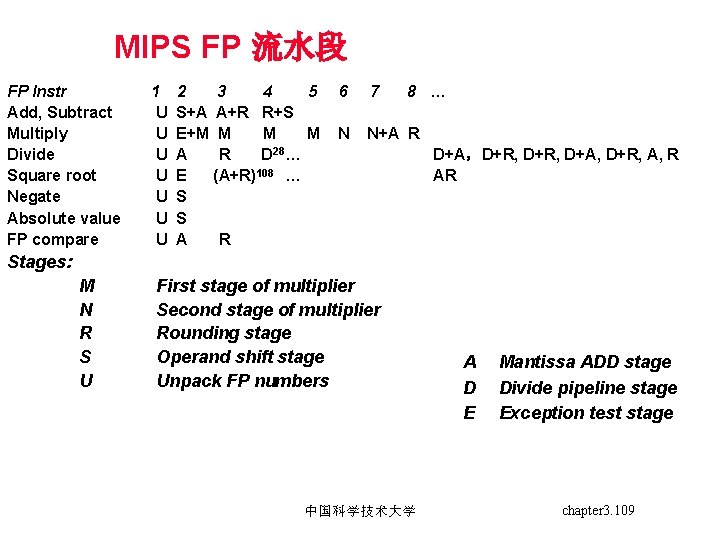
MIPS FP 流水段 FP Instr Add, Subtract Multiply Divide Square root Negate Absolute value FP compare 1 U U U U 2 3 4 5 S+A A+R R+S E+M M A R D 28 … E (A+R)108 … S S A R 6 7 8 … N N+A R D+A,D+R, D+A, D+R, A, R AR Stages: M N R S U First stage of multiplier Second stage of multiplier Rounding stage Operand shift stage Unpack FP numbers 中国科学技术大学 A D E Mantissa ADD stage Divide pipeline stage Exception test stage chapter 3. 109
Acknowledgements • These slides contain material developed and copyright by: – – John Kubiatowicz (UCB) Krste Asanovic (UCB) David Patterson (UCB) Chenxi Zhang (Tongji) • UCB material derived from course CS 152、 CS 252、CS 61 C • KFUPM material derived from course COE 501、 COE 502 中国科学技术大学 117
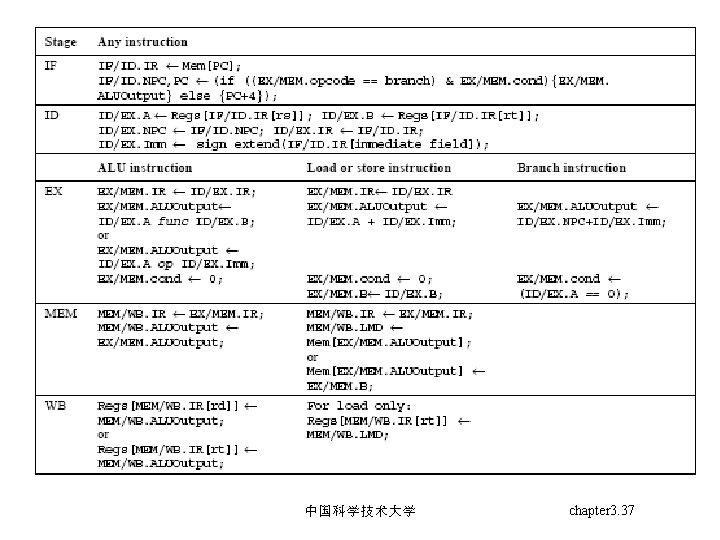
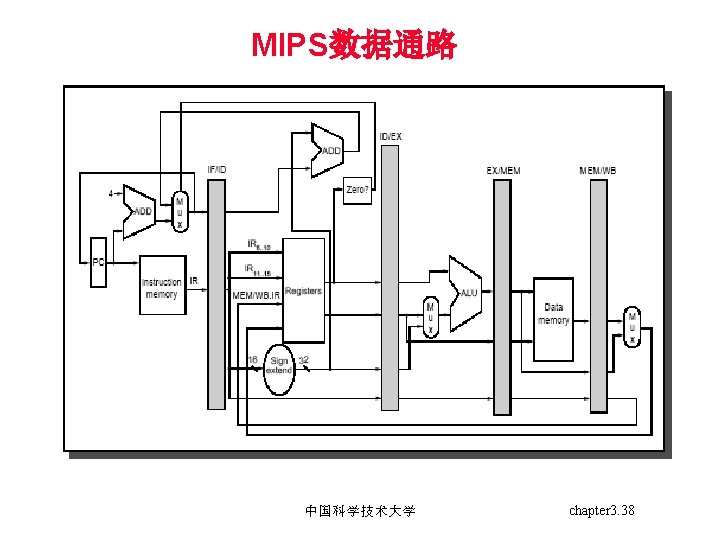
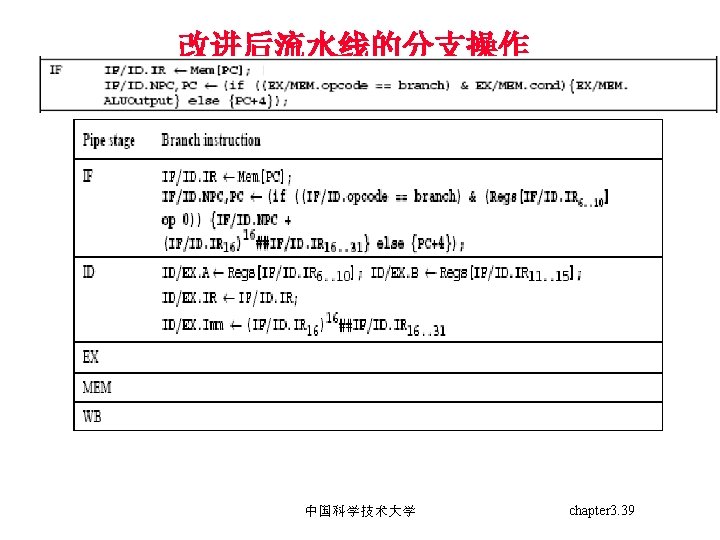
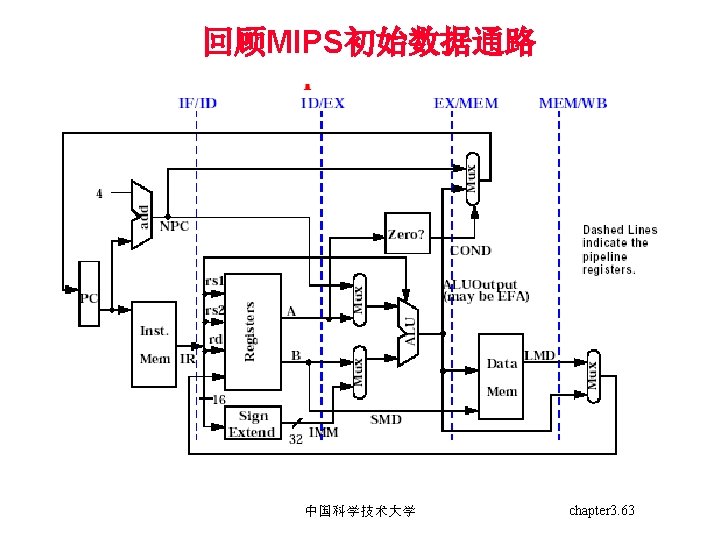
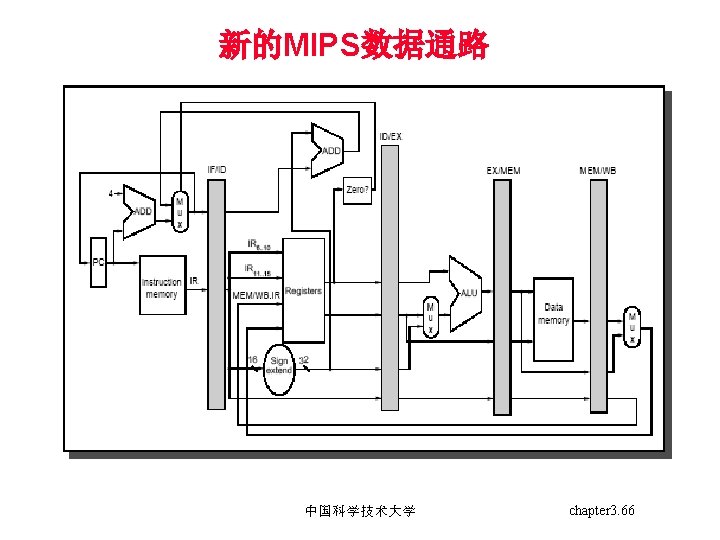
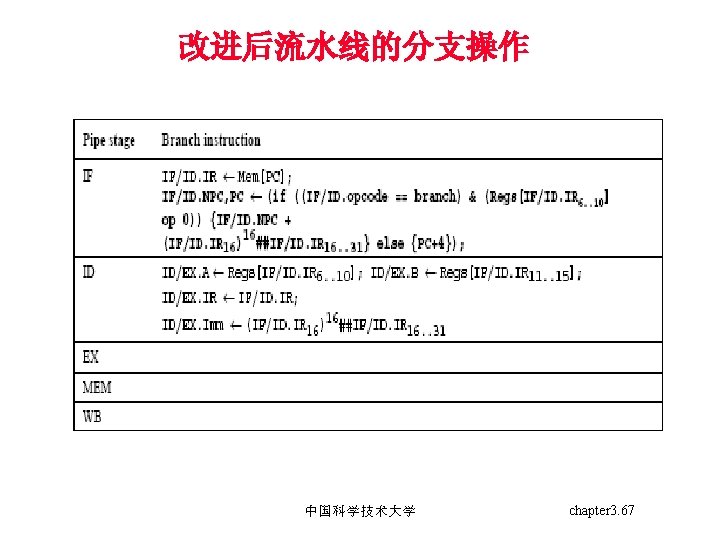
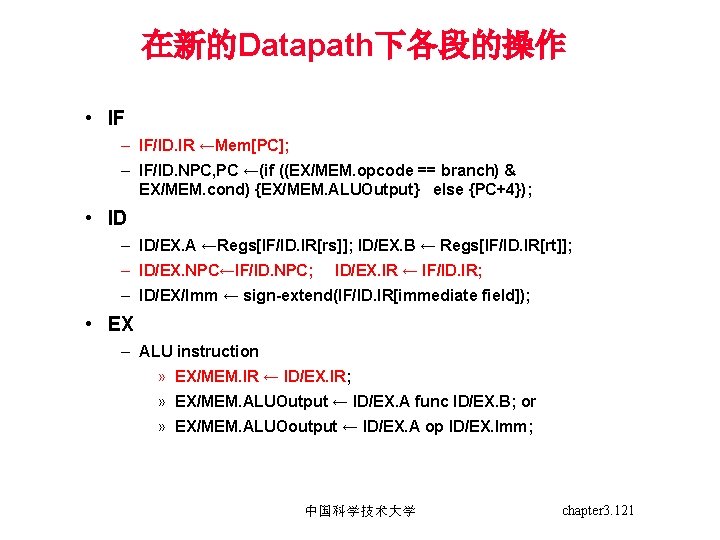
在新的Datapath下各段的操作 • IF – IF/ID. IR ←Mem[PC]; – IF/ID. NPC, PC ←(if ((EX/MEM. opcode == branch) & EX/MEM. cond) {EX/MEM. ALUOutput} else {PC+4}); • ID – ID/EX. A ←Regs[IF/ID. IR[rs]]; ID/EX. B ← Regs[IF/ID. IR[rt]]; – ID/EX. NPC←IF/ID. NPC; ID/EX. IR ← IF/ID. IR; – ID/EX/Imm ← sign-extend(IF/ID. IR[immediate field]); • EX – ALU instruction » EX/MEM. IR ← ID/EX. IR; » EX/MEM. ALUOutput ← ID/EX. A func ID/EX. B; or » EX/MEM. ALUOoutput ← ID/EX. A op ID/EX. Imm; 中国科学技术大学 chapter 3. 121
– Load or store instruction » EX/MEM. IR ← ID/EX. IR » EX/MEM. ALUOutput ← ID/EX. A + ID/EX. Imm » EX/MEM. B ← ID/EX. B – Branch instruction » EX/MEM. ALUOutput ← ID/EX. NPC + (ID/EX. Imm << 2) » EX/MEM. cond ← (ID/EX. A == 0); • MEM – ALU Instruction » MEM/WB. IR ←EX/MEM. IR » MEM/WB. ALUOutput ←EX/MEM. ALUOutput; – Load or store instruction » MEM/WB. IR ←EX/MEM. IR; » MEM/WB. LMD ← Mem[EX/MEM. ALUOutput]; or Mem[EX/MEM. ALUOutput] ← EX/MEM. B; (store) 中国科学技术大学 chapter 3. 122
• WB – ALU instruction » Regs[MEM/WB. IR[rd]] ← MEM/WB. ALUOutput; or » Regs[MEM/WB. IR[rt]] ← MEM/WB. ALUOutput; – For load only » Regs[MEM/WB. IR[rt]] ← MEM/WB. LMD 中国科学技术大学 chapter 3. 123
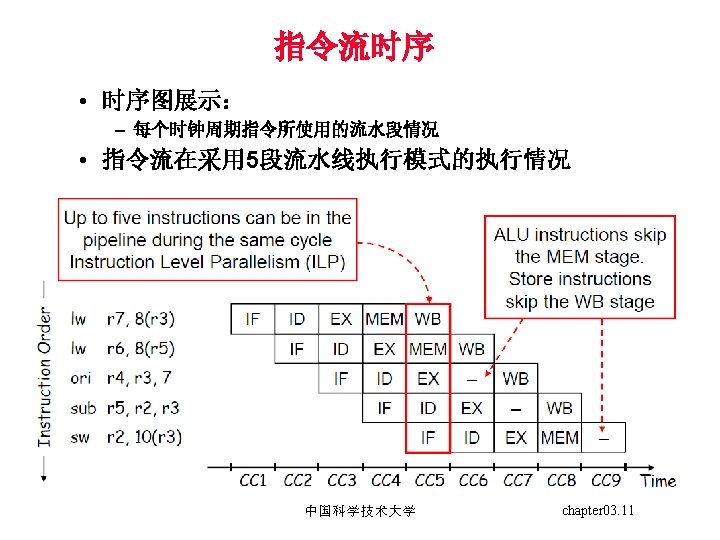
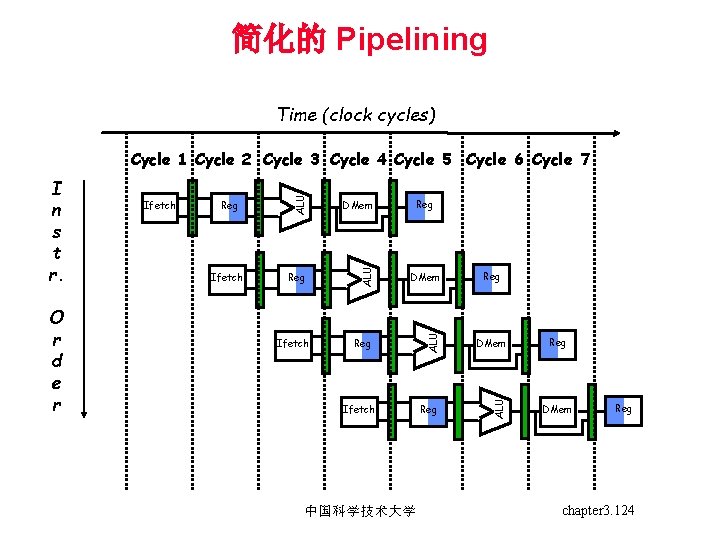
简化的 Pipelining Time (clock cycles) Ifetch DMem Reg ALU O r d e r Ifetch ALU I n s t r. ALU Cycle 1 Cycle 2 Cycle 3 Cycle 4 Cycle 5 Cycle 6 Cycle 7 Ifetch Reg Ifetch 中国科学技术大学 Reg DMem Reg chapter 3. 124