Chapter 5 Large and Fast Exploiting Memory Hierarchy
- Slides: 92
Chapter 5 Large and Fast: Exploiting Memory Hierarchy
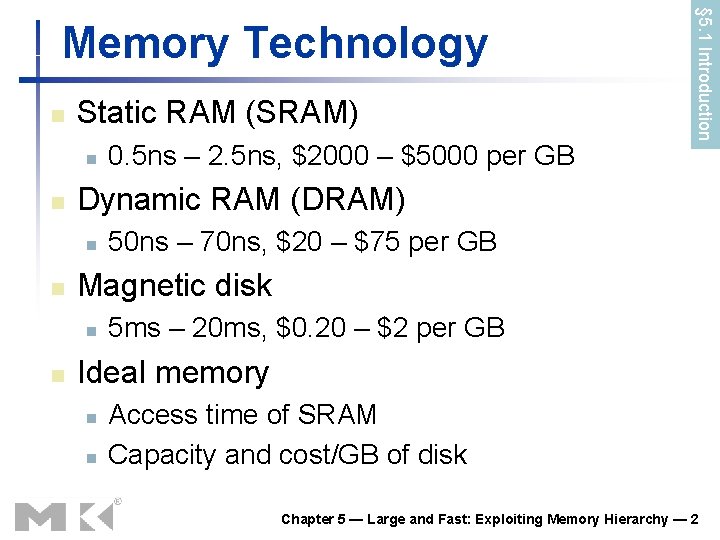
n Static RAM (SRAM) n n Dynamic RAM (DRAM) n n 50 ns – 70 ns, $20 – $75 per GB Magnetic disk n n 0. 5 ns – 2. 5 ns, $2000 – $5000 per GB § 5. 1 Introduction Memory Technology 5 ms – 20 ms, $0. 20 – $2 per GB Ideal memory n n Access time of SRAM Capacity and cost/GB of disk Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 2
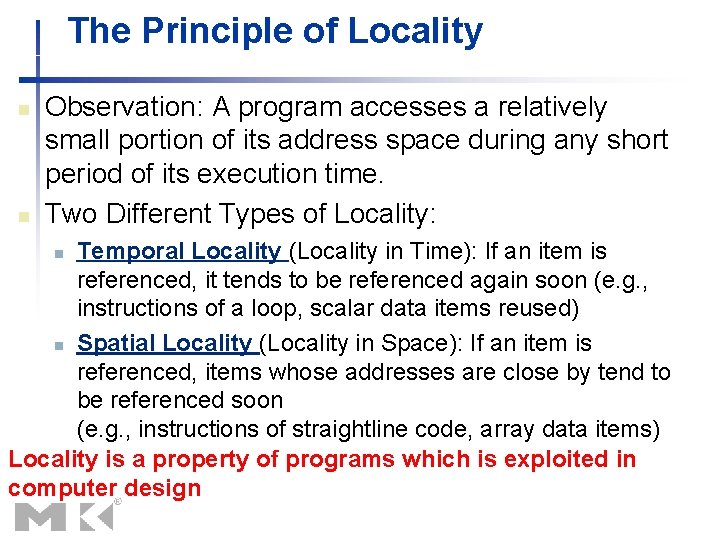
The Principle of Locality n n Observation: A program accesses a relatively small portion of its address space during any short period of its execution time. Two Different Types of Locality: Temporal Locality (Locality in Time): If an item is referenced, it tends to be referenced again soon (e. g. , instructions of a loop, scalar data items reused) n Spatial Locality (Locality in Space): If an item is referenced, items whose addresses are close by tend to be referenced soon (e. g. , instructions of straightline code, array data items) Locality is a property of programs which is exploited in computer design n
Taking Advantage of Locality n Memory of a computer could be organized in a hierarchy Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 4
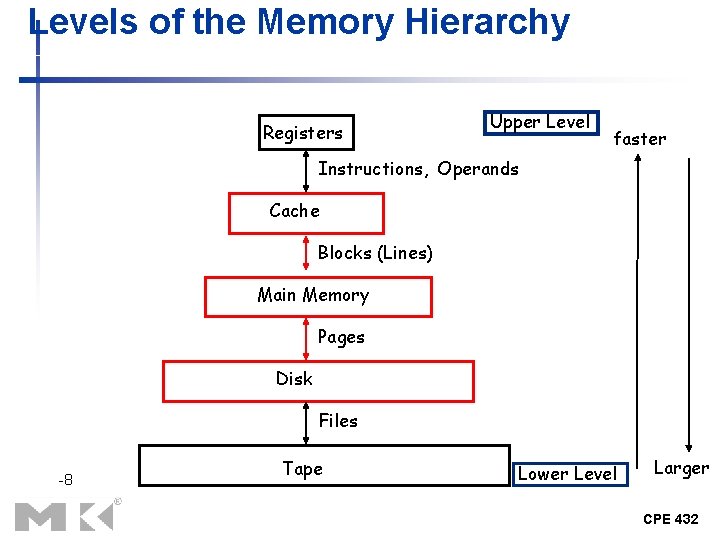
Levels of the Memory Hierarchy Registers Upper Level faster Instructions, Operands Cache Blocks (Lines) Main Memory Pages Disk Files -8 Tape Lower Level Larger CPE 432
Taking Advantage of Locality n n n Organize the computer memory system in a hierarchy Store everything on disk Copy recently accessed (and nearby) items from disk to smaller DRAM memory n n Main memory Copy more recently accessed (and nearby) items from DRAM to smaller SRAM memory n Cache memory attached to CPU Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 6
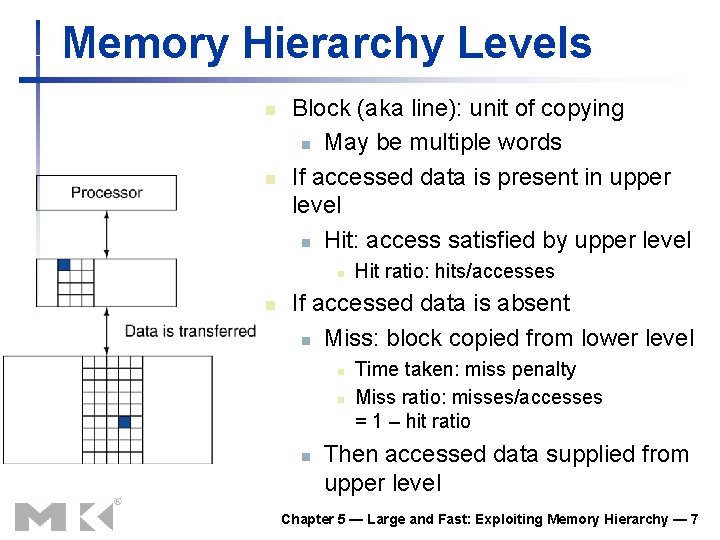
Memory Hierarchy Levels n n Block (aka line): unit of copying n May be multiple words If accessed data is present in upper level n Hit: access satisfied by upper level n n Hit ratio: hits/accesses If accessed data is absent n Miss: block copied from lower level n n n Time taken: miss penalty Miss ratio: misses/accesses = 1 – hit ratio Then accessed data supplied from upper level Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 7
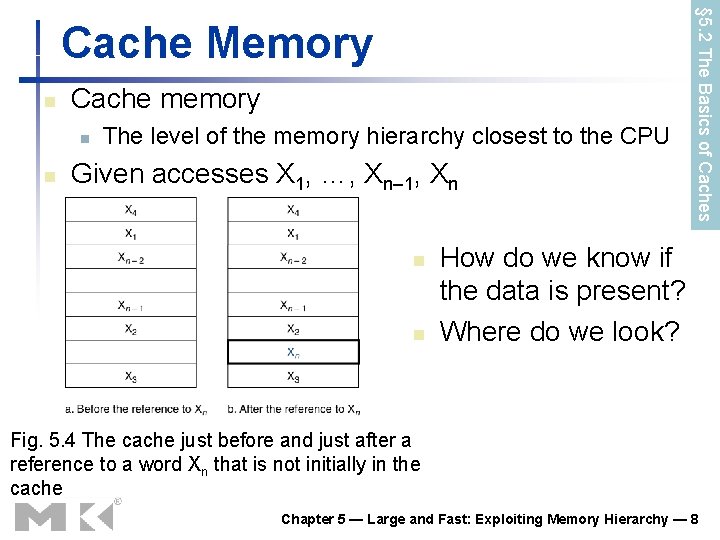
n Cache memory n n The level of the memory hierarchy closest to the CPU Given accesses X 1, …, Xn– 1, Xn n n § 5. 2 The Basics of Caches Cache Memory How do we know if the data is present? Where do we look? Fig. 5. 4 The cache just before and just after a reference to a word Xn that is not initially in the cache Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 8
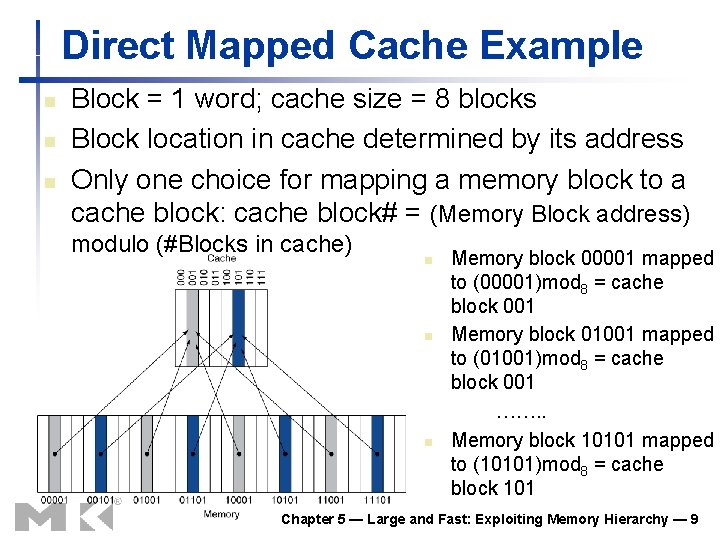
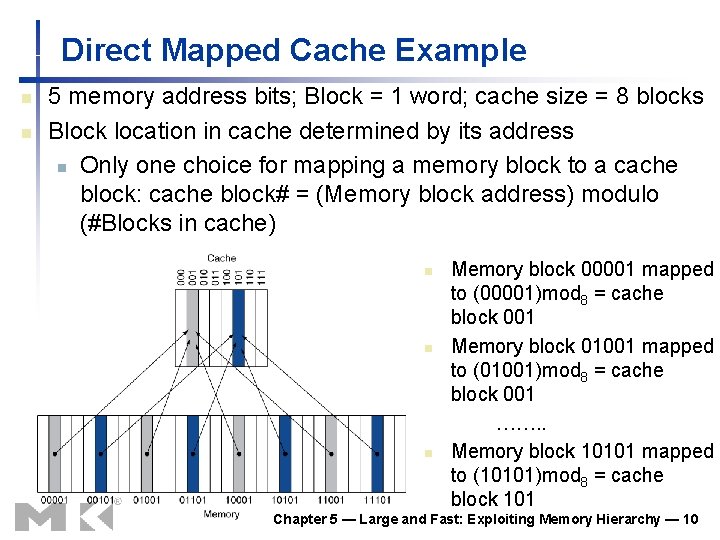
Direct Mapped Cache Example n n n Block = 1 word; cache size = 8 blocks Block location in cache determined by its address Only one choice for mapping a memory block to a cache block: cache block# = (Memory Block address) modulo (#Blocks in cache) n n n Memory block 00001 mapped to (00001)mod 8 = cache block 001 Memory block 01001 mapped to (01001)mod 8 = cache block 001 ……. . Memory block 10101 mapped to (10101)mod 8 = cache block 101 Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 9
Direct Mapped Cache Example n n 5 memory address bits; Block = 1 word; cache size = 8 blocks Block location in cache determined by its address n Only one choice for mapping a memory block to a cache block: cache block# = (Memory block address) modulo (#Blocks in cache) n n n Memory block 00001 mapped to (00001)mod 8 = cache block 001 Memory block 01001 mapped to (01001)mod 8 = cache block 001 ……. . Memory block 10101 mapped to (10101)mod 8 = cache block 101 Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 10
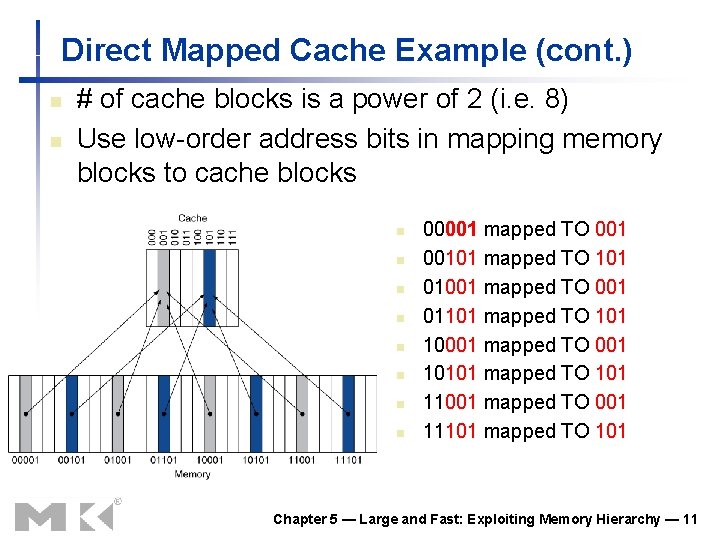
Direct Mapped Cache Example (cont. ) n n # of cache blocks is a power of 2 (i. e. 8) Use low-order address bits in mapping memory blocks to cache blocks n n n n 00001 mapped TO 00101 mapped TO 101 01001 mapped TO 001 01101 mapped TO 101 10001 mapped TO 001 10101 mapped TO 101 11001 mapped TO 001 11101 mapped TO 101 Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 11
Tags and Valid Bits n How do we know which particular memory block is stored in a cache block? n n Store in the cache block the block memory address as well as its data Actually, only need to store the high-order bits of the address (in the example 2 bits) Called the tag What if there is no data in a cache block? n n Valid bit: 1 = data present, 0 = data not present Initially 0 Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 12
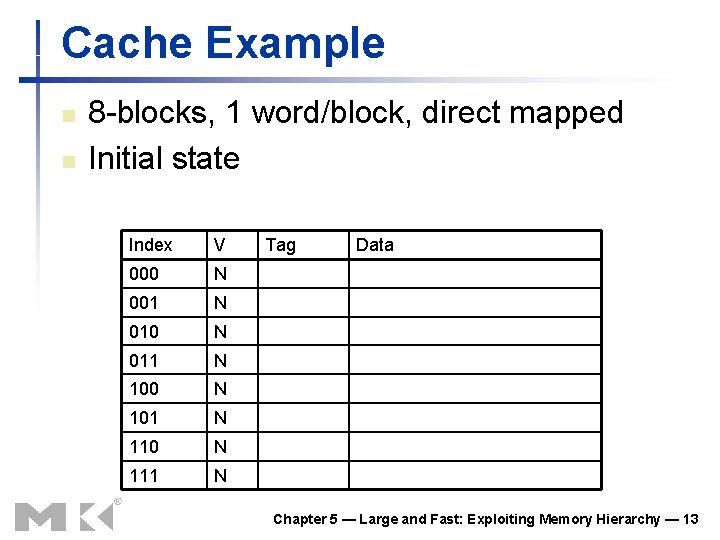
Cache Example n n 8 -blocks, 1 word/block, direct mapped Initial state Index V 000 N 001 N 010 N 011 N 100 N 101 N 110 N 111 N Tag Data Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 13
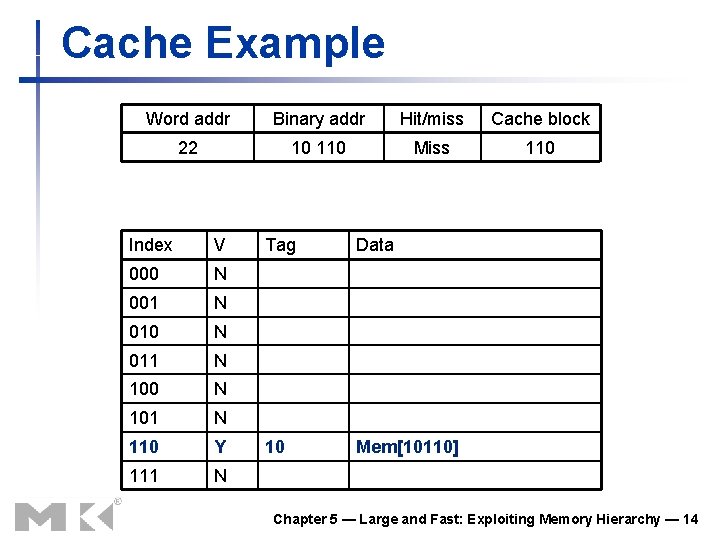
Cache Example Word addr Binary addr Hit/miss Cache block 22 10 110 Miss 110 Index V 000 N 001 N 010 N 011 N 100 N 101 N 110 Y 111 N Tag Data 10 Mem[10110] Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 14
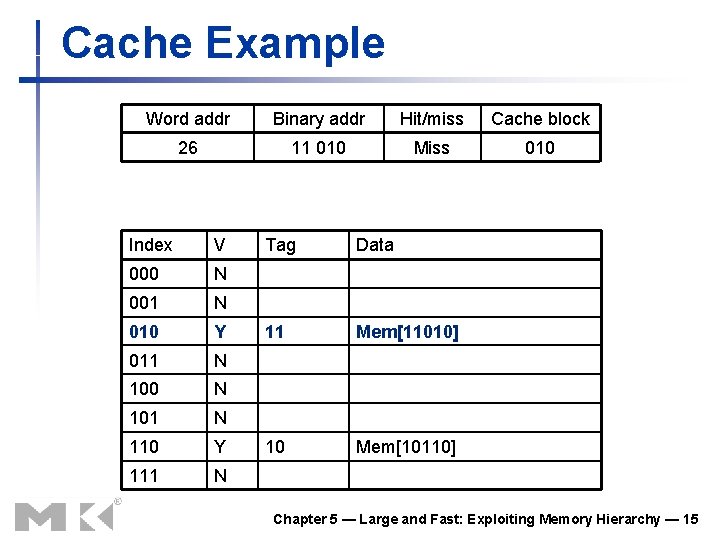
Cache Example Word addr Binary addr Hit/miss Cache block 26 11 010 Miss 010 Index V 000 N 001 N 010 Y 011 N 100 N 101 N 110 Y 111 N Tag Data 11 Mem[11010] 10 Mem[10110] Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 15
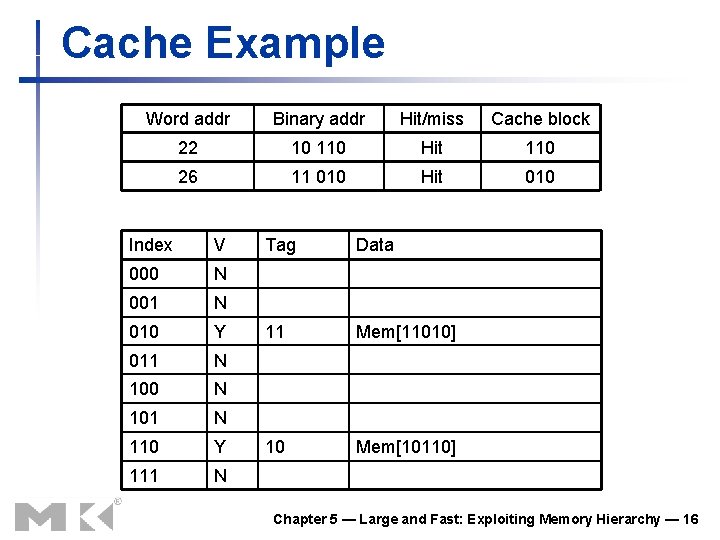
Cache Example Word addr Binary addr Hit/miss Cache block 22 10 110 Hit 110 26 11 010 Hit 010 Index V 000 N 001 N 010 Y 011 N 100 N 101 N 110 Y 111 N Tag Data 11 Mem[11010] 10 Mem[10110] Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 16
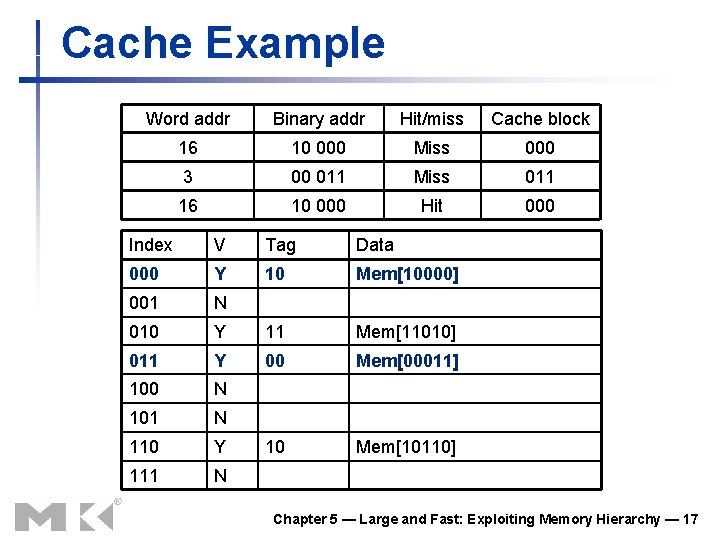
Cache Example Word addr Binary addr Hit/miss Cache block 16 10 000 Miss 000 3 00 011 Miss 011 16 10 000 Hit 000 Index V Tag Data 000 Y 10 Mem[10000] 001 N 010 Y 11 Mem[11010] 011 Y 00 Mem[00011] 100 N 101 N 110 Y 10 Mem[10110] 111 N Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 17
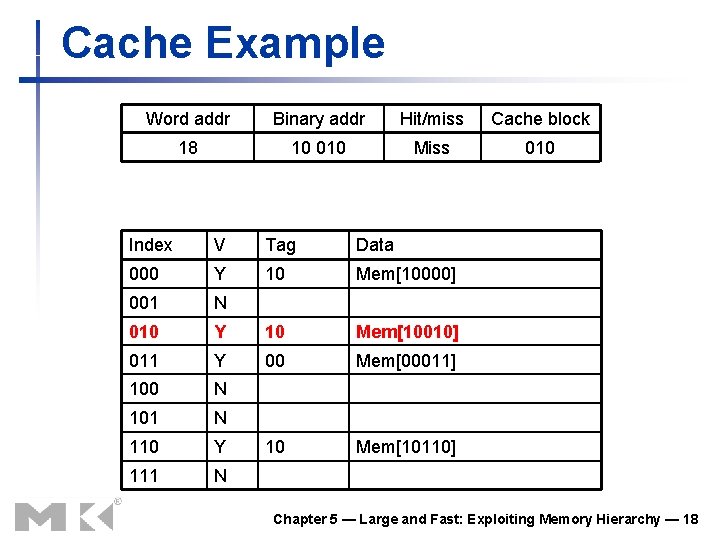
Cache Example Word addr Binary addr Hit/miss Cache block 18 10 010 Miss 010 Index V Tag Data 000 Y 10 Mem[10000] 001 N 010 Y 10 Mem[10010] 011 Y 00 Mem[00011] 100 N 101 N 110 Y 10 Mem[10110] 111 N Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 18
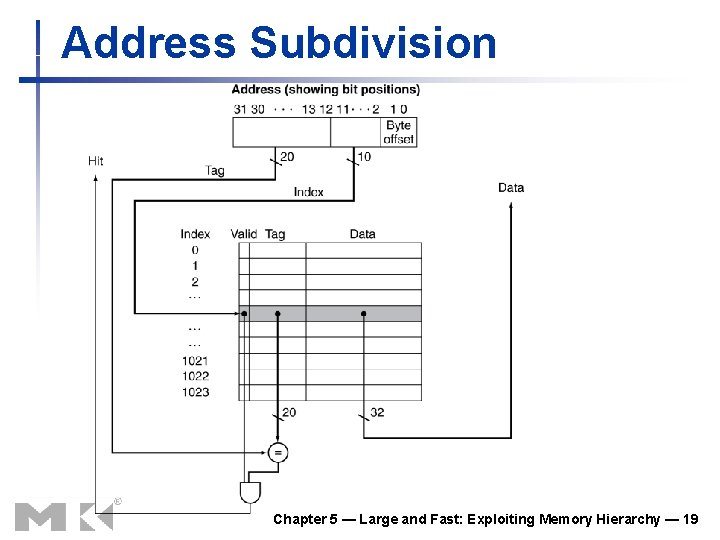
Address Subdivision Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 19
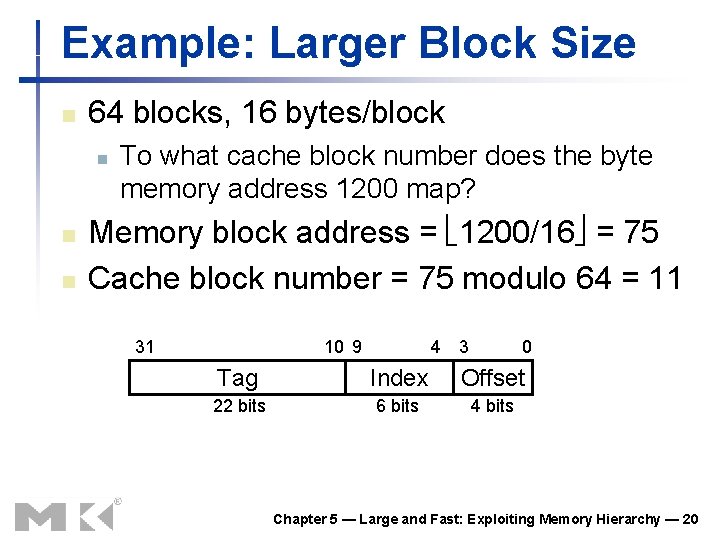
Example: Larger Block Size n 64 blocks, 16 bytes/block n n n To what cache block number does the byte memory address 1200 map? Memory block address = 1200/16 = 75 Cache block number = 75 modulo 64 = 11 31 10 9 4 3 0 Tag Index Offset 22 bits 6 bits 4 bits Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 20
Block Size Considerations n Larger blocks should reduce miss rate n n Due to spatial locality But in a fixed-sized cache n Larger blocks fewer of them n n More competition increased miss rate Larger miss penalty n n Can override benefit of reduced miss rate Early restart and critical-word-first can help Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 21
Cache Misses n n On cache hit, CPU proceeds normally On cache miss n n n Stall the CPU pipeline Fetch block from next level of hierarchy Instruction cache miss n n Restart instruction fetch Data cache miss n Complete data access Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 22
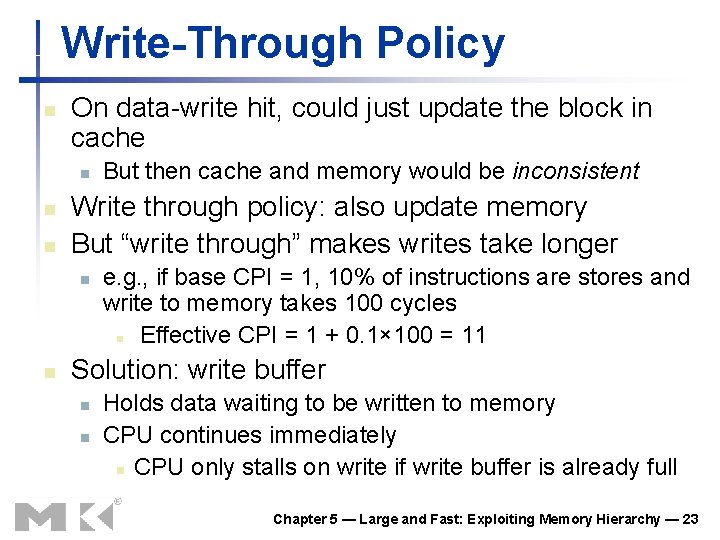
Write-Through Policy n On data-write hit, could just update the block in cache n n n Write through policy: also update memory But “write through” makes writes take longer n n But then cache and memory would be inconsistent e. g. , if base CPI = 1, 10% of instructions are stores and write to memory takes 100 cycles n Effective CPI = 1 + 0. 1× 100 = 11 Solution: write buffer n n Holds data waiting to be written to memory CPU continues immediately n CPU only stalls on write if write buffer is already full Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 23
Write-Back Policy n Alternative: On data-write hit, just update the block in cache n n Keep track of whether each block is dirty When a dirty block is replaced n n Write it back to memory Can use a write buffer to allow replacing block to be read first Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 24
n n n Write Allocation What should happen on a write miss? For write-back caches n Allocate the cache block; fetch the block from memory For write-through caches: 2 alternatives 1. Allocate the cache block n fetch the block from memory 2. Write around: don’t fetch the block from memory n n Allocate block in cache and write to the cache and “write buffer” This often works well since programs often write a whole blo before reading it (e. g. , initialization)
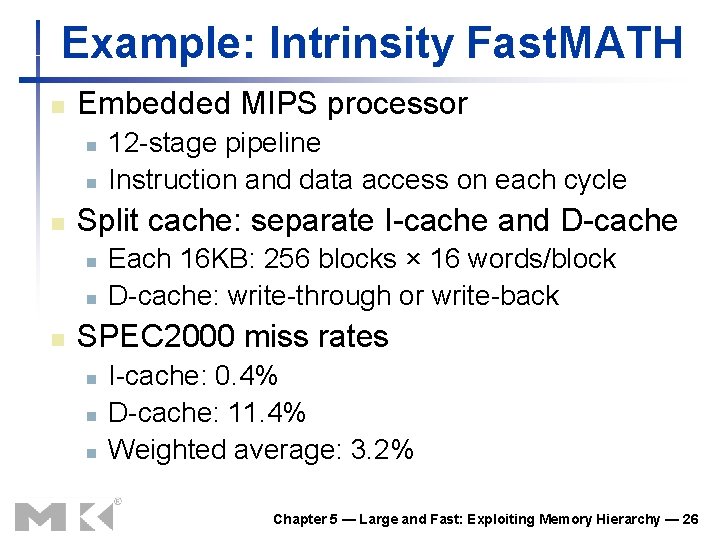
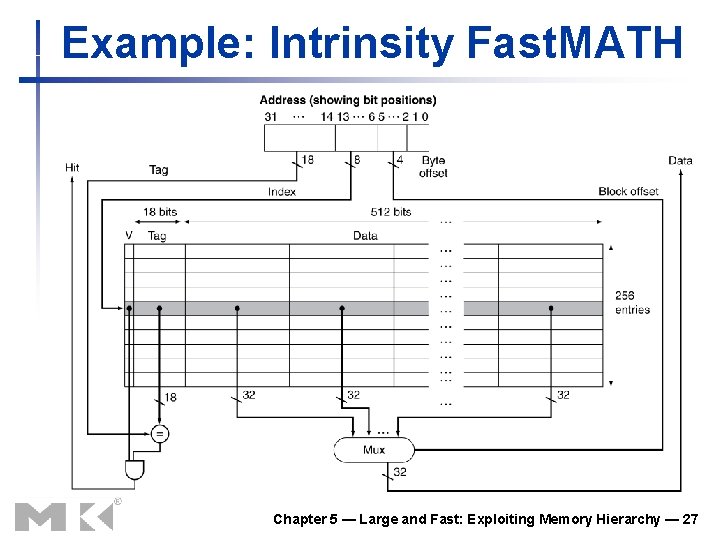
Example: Intrinsity Fast. MATH n Embedded MIPS processor n n n Split cache: separate I-cache and D-cache n n n 12 -stage pipeline Instruction and data access on each cycle Each 16 KB: 256 blocks × 16 words/block D-cache: write-through or write-back SPEC 2000 miss rates n n n I-cache: 0. 4% D-cache: 11. 4% Weighted average: 3. 2% Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 26
Example: Intrinsity Fast. MATH Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 27
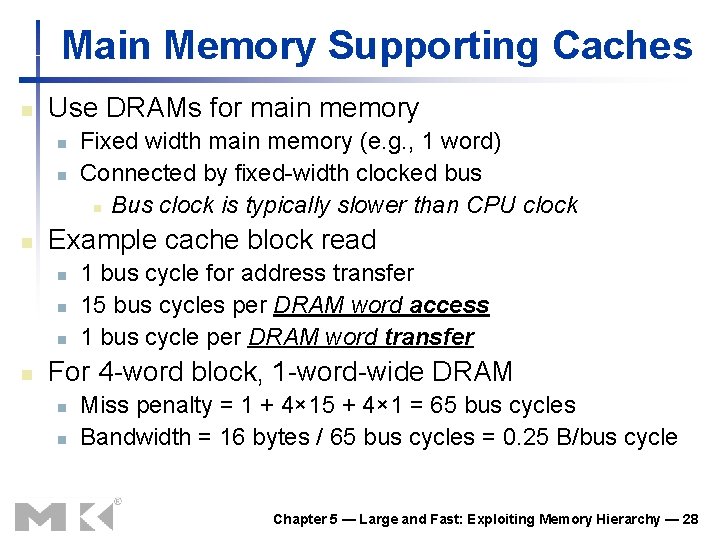
Main Memory Supporting Caches n Use DRAMs for main memory n n n Example cache block read n n Fixed width main memory (e. g. , 1 word) Connected by fixed-width clocked bus n Bus clock is typically slower than CPU clock 1 bus cycle for address transfer 15 bus cycles per DRAM word access 1 bus cycle per DRAM word transfer For 4 -word block, 1 -word-wide DRAM n n Miss penalty = 1 + 4× 15 + 4× 1 = 65 bus cycles Bandwidth = 16 bytes / 65 bus cycles = 0. 25 B/bus cycle Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 28
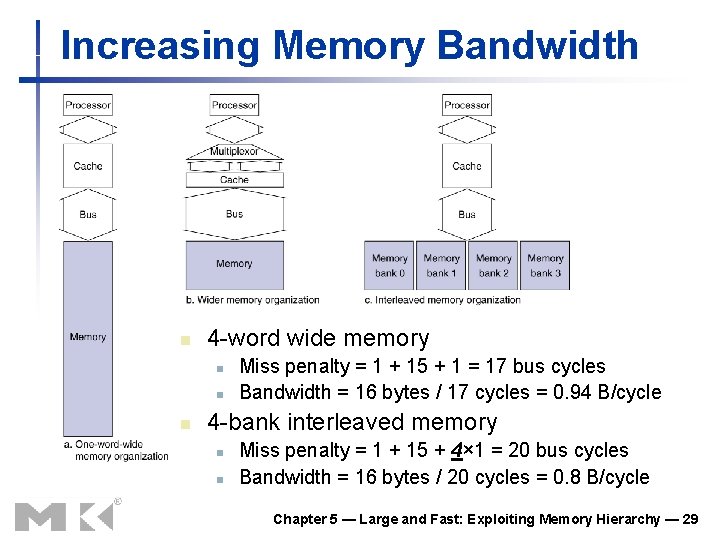
Increasing Memory Bandwidth n 4 -word wide memory n n n Miss penalty = 1 + 15 + 1 = 17 bus cycles Bandwidth = 16 bytes / 17 cycles = 0. 94 B/cycle 4 -bank interleaved memory n n Miss penalty = 1 + 15 + 4× 1 = 20 bus cycles Bandwidth = 16 bytes / 20 cycles = 0. 8 B/cycle Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 29
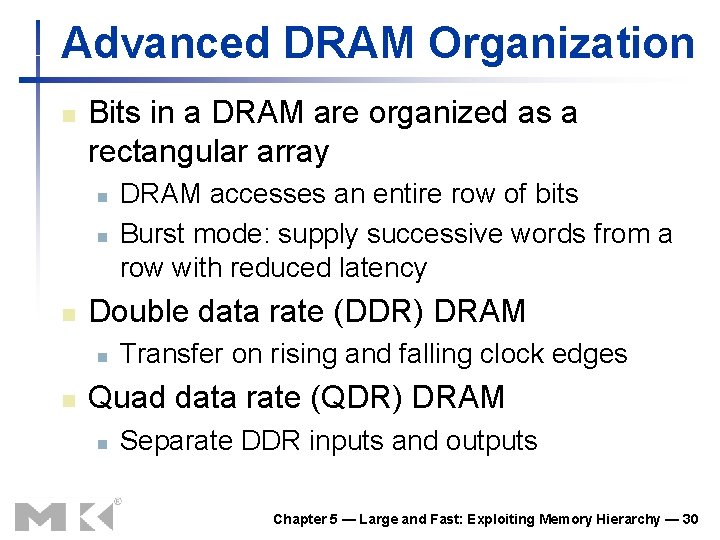
Advanced DRAM Organization n Bits in a DRAM are organized as a rectangular array n n n Double data rate (DDR) DRAM n n DRAM accesses an entire row of bits Burst mode: supply successive words from a row with reduced latency Transfer on rising and falling clock edges Quad data rate (QDR) DRAM n Separate DDR inputs and outputs Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 30
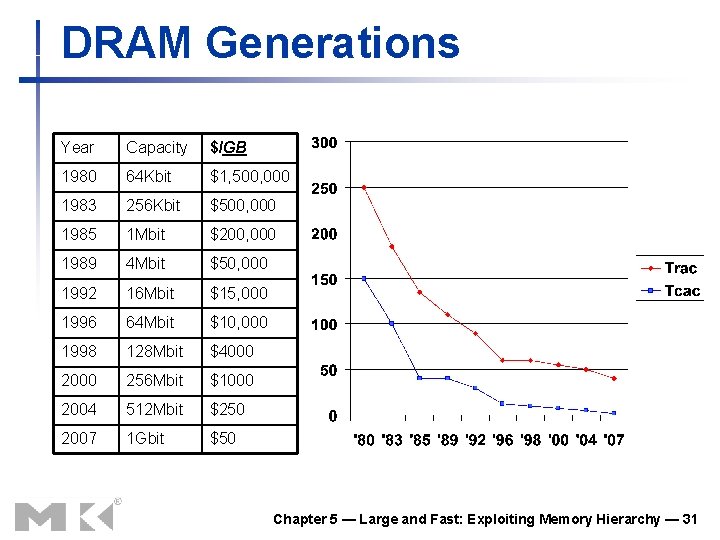
DRAM Generations Year Capacity $/GB 1980 64 Kbit $1, 500, 000 1983 256 Kbit $500, 000 1985 1 Mbit $200, 000 1989 4 Mbit $50, 000 1992 16 Mbit $15, 000 1996 64 Mbit $10, 000 1998 128 Mbit $4000 256 Mbit $1000 2004 512 Mbit $250 2007 1 Gbit $50 Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 31
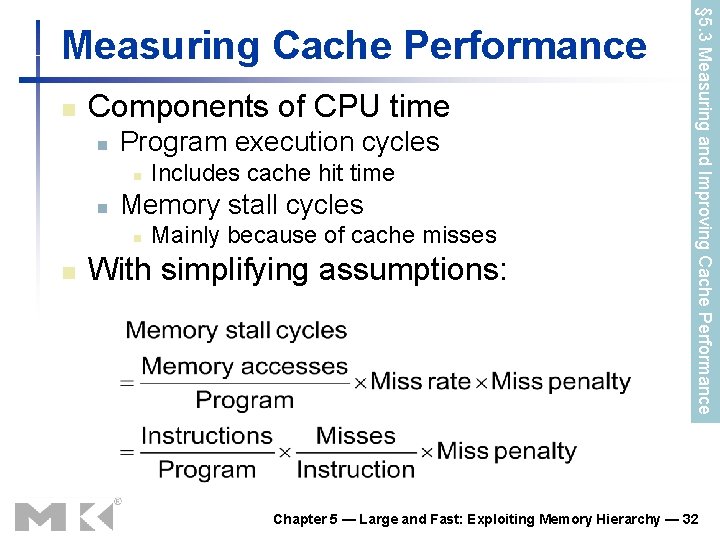
n Components of CPU time n Program execution cycles n n Memory stall cycles n n Includes cache hit time Mainly because of cache misses With simplifying assumptions: § 5. 3 Measuring and Improving Cache Performance Measuring Cache Performance Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 32
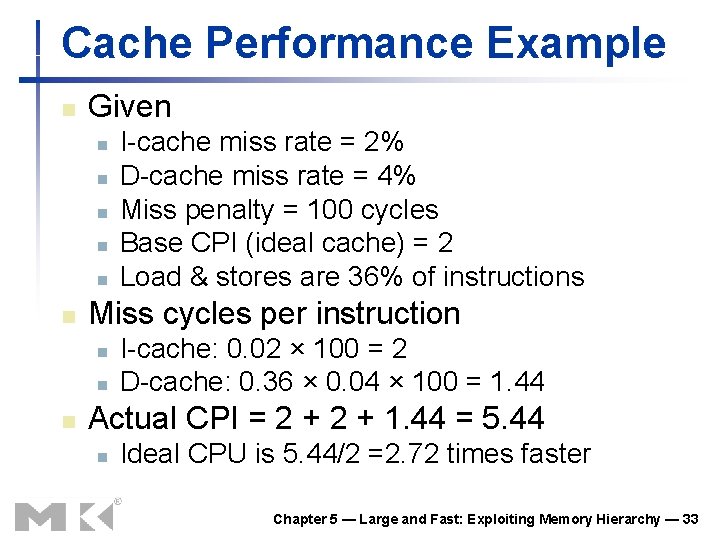
Cache Performance Example n Given n n n Miss cycles per instruction n I-cache miss rate = 2% D-cache miss rate = 4% Miss penalty = 100 cycles Base CPI (ideal cache) = 2 Load & stores are 36% of instructions I-cache: 0. 02 × 100 = 2 D-cache: 0. 36 × 0. 04 × 100 = 1. 44 Actual CPI = 2 + 1. 44 = 5. 44 n Ideal CPU is 5. 44/2 =2. 72 times faster Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 33
Average Access Time n n Hit time is also important for performance Average memory access time (AMAT) n n AMAT = Hit time + Miss rate × Miss penalty Example n n CPU with 1 ns clock, hit time = 1 cycle, miss penalty = 20 cycles, I-cache miss rate = 5% AMAT = 1 + 0. 05 × 20 = 2 ns n 2 cycles per instruction Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 34
Performance Summary n When CPU performance increased n n Decreasing base CPI n n Greater proportion of time spent on memory stalls Increasing clock rate n n Miss penalty becomes more significant Memory stalls account for more CPU cycles Can’t neglect cache behavior when evaluating system performance Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 35
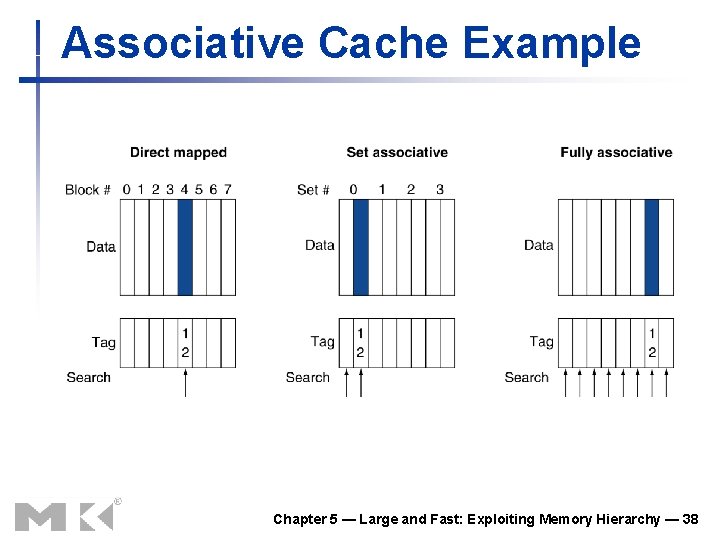
Fully Associative Caches n n n Allow a memory block to go in any cache block Requires all cache blocks to be searched simultaneously Comparator per cache block is needed (expensive) 36
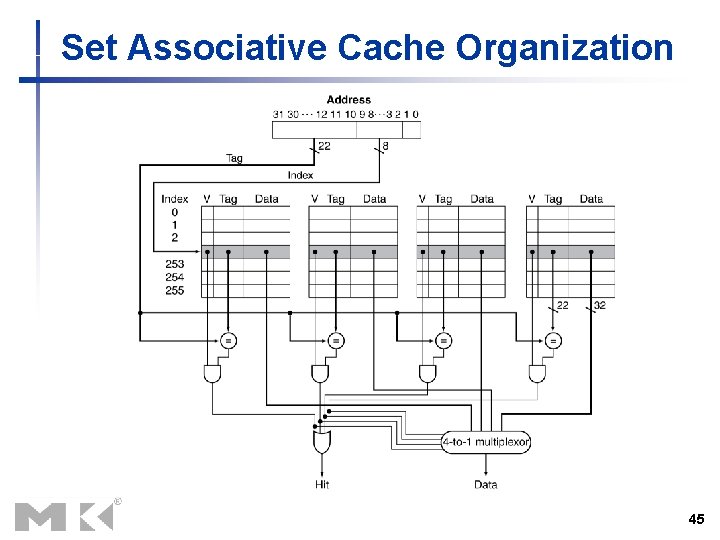
n-way Set Associative Caches n n n Organize the cache into sets (groups) of blocks Each set contains n cache blocks Main memory block number is used to determine which set in the cache will store the memory block n n n (Memory block number) modulo (#Sets in cache) Search all cache blocks in a given set simultaneously n comparators are needed (less expensive than a fully associative cache organization) 37
Associative Cache Example Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 38
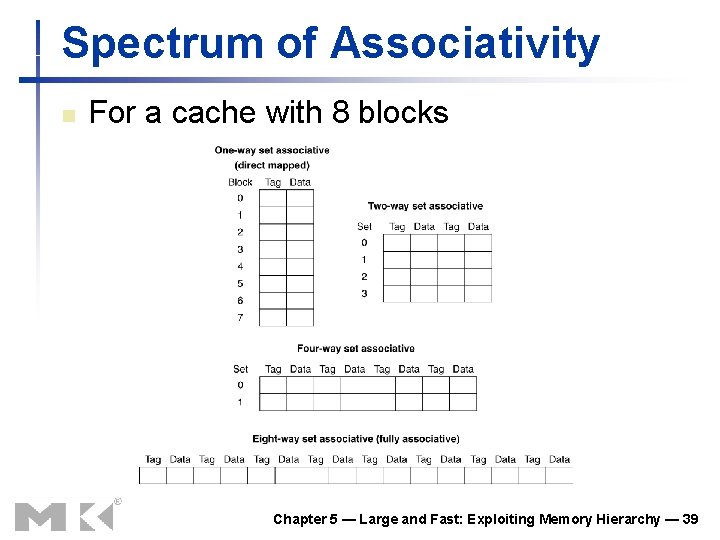
Spectrum of Associativity n For a cache with 8 blocks Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 39
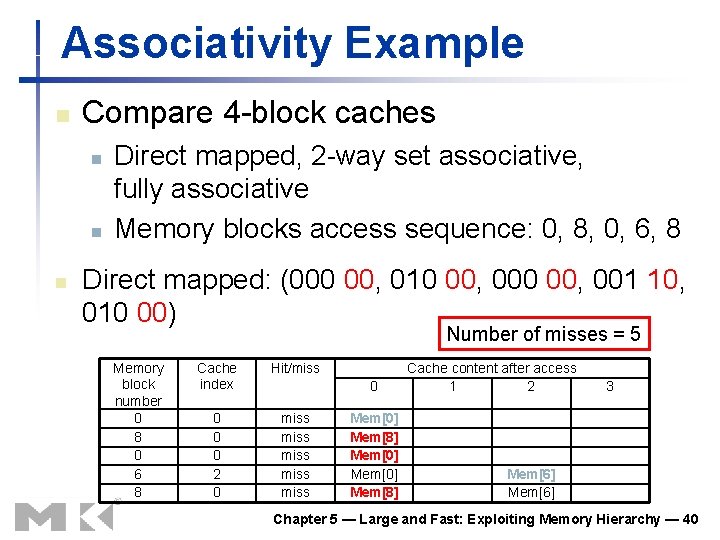
Associativity Example n Compare 4 -block caches n n n Direct mapped, 2 -way set associative, fully associative Memory blocks access sequence: 0, 8, 0, 6, 8 Direct mapped: (000 00, 010 00, 001 10, 010 00) Number of misses = 5 Memory block number 0 8 0 6 8 Cache index Hit/miss 0 0 0 2 0 miss miss 0 Mem[0] Mem[8] Cache content after access 1 2 3 Mem[6] Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 40
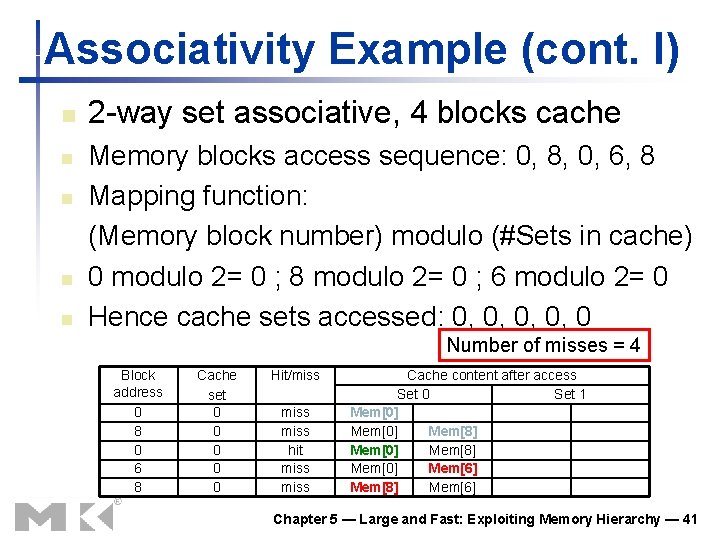
Associativity Example (cont. I) n n n 2 -way set associative, 4 blocks cache Memory blocks access sequence: 0, 8, 0, 6, 8 Mapping function: (Memory block number) modulo (#Sets in cache) 0 modulo 2= 0 ; 8 modulo 2= 0 ; 6 modulo 2= 0 Hence cache sets accessed: 0, 0, 0 Number of misses = 4 Block address 0 8 0 6 8 Cache set 0 0 0 Hit/miss hit miss Cache content after access Set 0 Set 1 Mem[0] Mem[8] Mem[0] Mem[6] Mem[8] Mem[6] Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 41
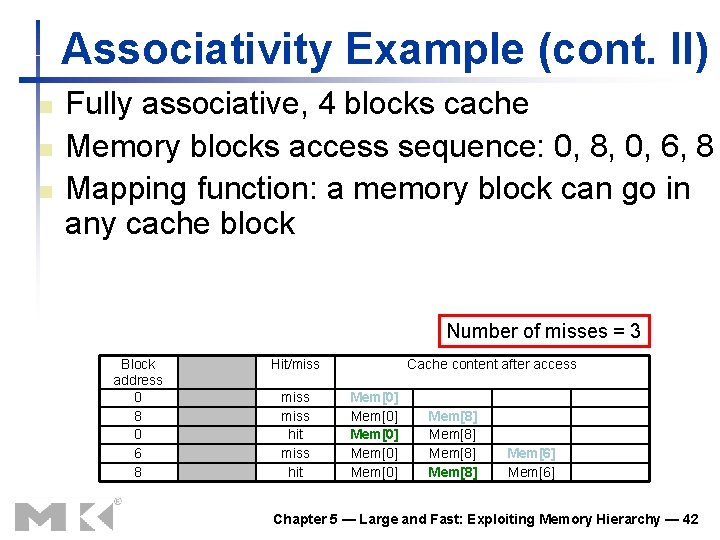
Associativity Example (cont. II) n n n Fully associative, 4 blocks cache Memory blocks access sequence: 0, 8, 0, 6, 8 Mapping function: a memory block can go in any cache block Number of misses = 3 Block address 0 8 0 6 8 Hit/miss hit Cache content after access Mem[0] Mem[0] Mem[8] Mem[6] Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 42
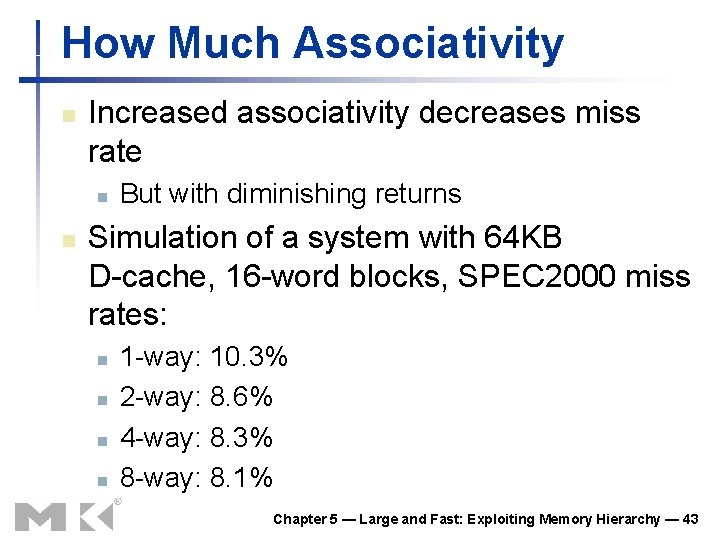
How Much Associativity n Increased associativity decreases miss rate n n But with diminishing returns Simulation of a system with 64 KB D-cache, 16 -word blocks, SPEC 2000 miss rates: n n 1 -way: 10. 3% 2 -way: 8. 6% 4 -way: 8. 3% 8 -way: 8. 1% Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 43
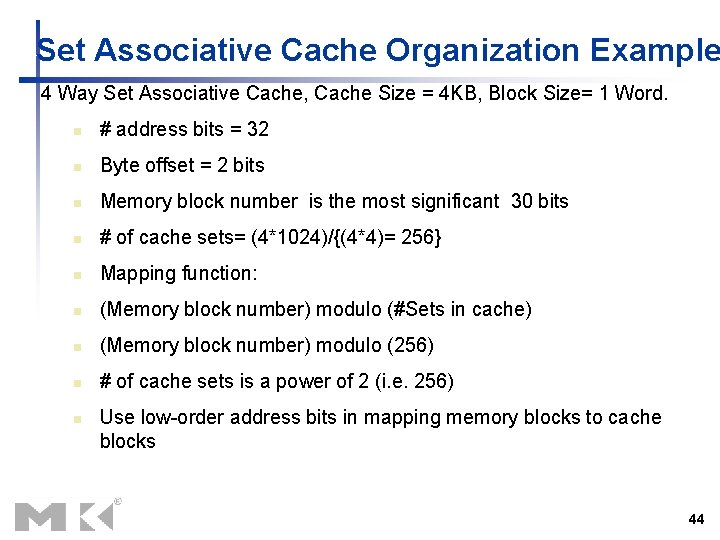
Set Associative Cache Organization Example 4 Way Set Associative Cache, Cache Size = 4 KB, Block Size= 1 Word. n # address bits = 32 n Byte offset = 2 bits n Memory block number is the most significant 30 bits n # of cache sets= (4*1024)/{(4*4)= 256} n Mapping function: n (Memory block number) modulo (#Sets in cache) n (Memory block number) modulo (256) n # of cache sets is a power of 2 (i. e. 256) n Use low-order address bits in mapping memory blocks to cache blocks 44
Set Associative Cache Organization 45
Block Replacement Policy n n Direct mapped: no choice Set associative n n n Prefer non-valid block, if there is one Otherwise, choose among blocks in the set Least-recently used (LRU) n Choose the block unused for the longest time n n Simple for 2 -way, manageable for 4 -way, too hard beyond that Random n Gives approximately the same performance as LRU for high associativity Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 46
Multilevel Caches n Primary cache attached to CPU n n Level-2 cache services misses from primary cache n n n Small, but fast Larger than primary cache Slower than primary cache Faster than main memory Main memory services L-2 cache misses Some high-end systems include L-3 cache Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 47
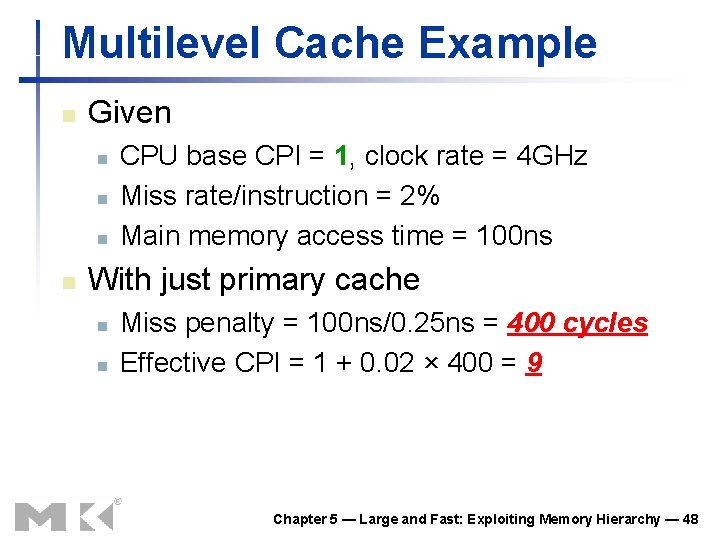
Multilevel Cache Example n Given n n CPU base CPI = 1, clock rate = 4 GHz Miss rate/instruction = 2% Main memory access time = 100 ns With just primary cache n n Miss penalty = 100 ns/0. 25 ns = 400 cycles Effective CPI = 1 + 0. 02 × 400 = 9 Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 48
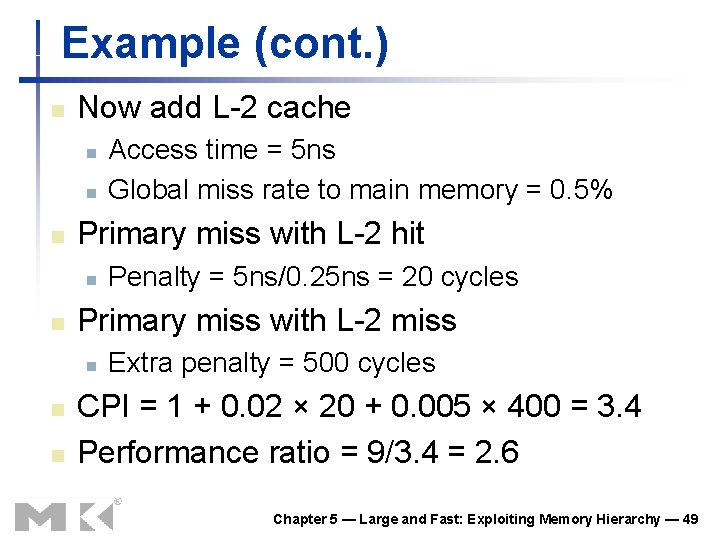
Example (cont. ) n Now add L-2 cache n n n Primary miss with L-2 hit n n n Penalty = 5 ns/0. 25 ns = 20 cycles Primary miss with L-2 miss n n Access time = 5 ns Global miss rate to main memory = 0. 5% Extra penalty = 500 cycles CPI = 1 + 0. 02 × 20 + 0. 005 × 400 = 3. 4 Performance ratio = 9/3. 4 = 2. 6 Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 49
Multilevel Cache Considerations n Primary cache n n L-2 cache n n n Focus on minimal hit time Focus on low miss rate to avoid main memory access Hit time has less overall impact Results n n L-1 cache usually smaller than a single cache L-1 block size smaller than L-2 block size Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 50
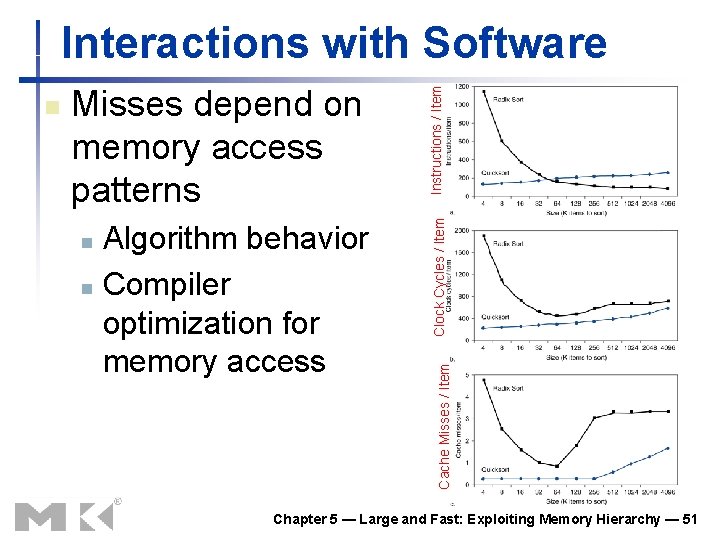
Algorithm behavior n Compiler optimization for memory access n Clock Cycles / Item Misses depend on memory access patterns Cache Misses / Item n Instructions / Item Interactions with Software Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 51
n Use main memory as a “cache” for secondary (disk) storage n n Programs share main memory n n n Managed jointly by CPU hardware and the operating system (OS) § 5. 4 Virtual Memory Each gets a private virtual address space holding its frequently used code and data Protected from other programs CPU and OS translate virtual addresses to physical addresses n n VM “block” is called a page VM “miss” is called a page fault Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 52
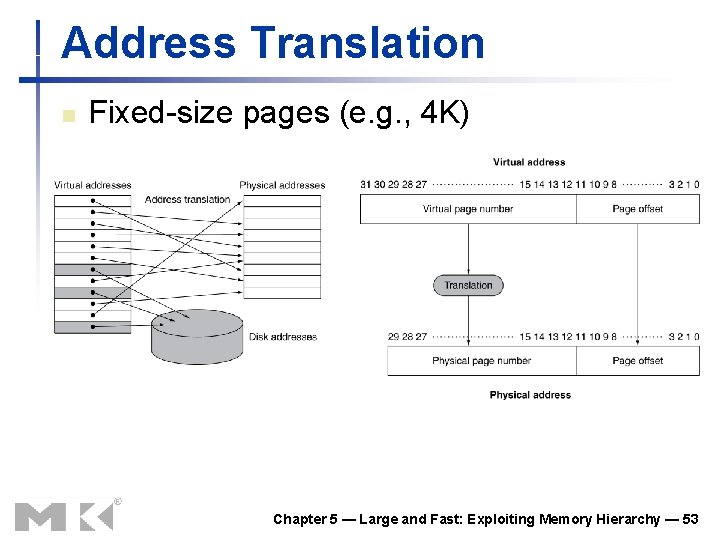
Address Translation n Fixed-size pages (e. g. , 4 K) Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 53
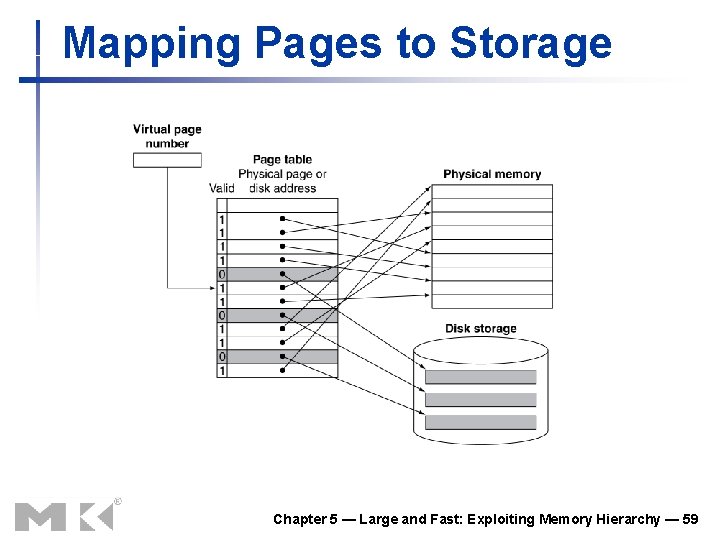
Page Fault Penalty n On page fault, the page must be fetched from disk n n n Takes millions of clock cycles Handled by OS code Try to minimize page fault rate n n Fully associative placement Smart replacement algorithms Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 54
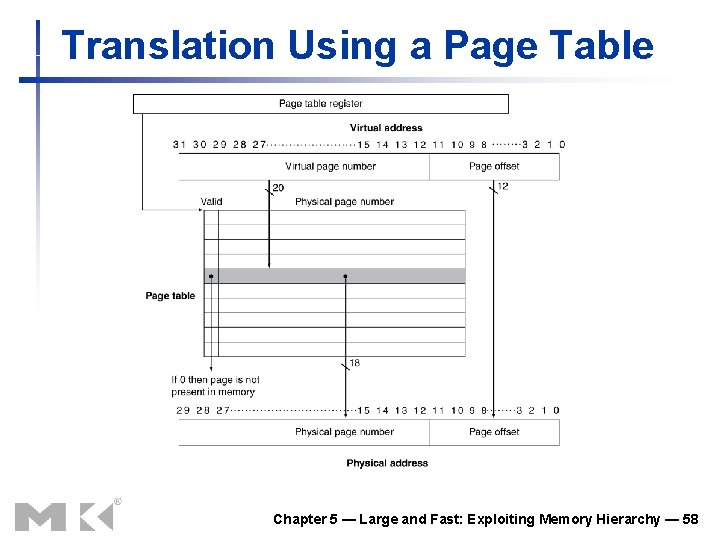
Virtual to Physical Address Translation n n How to translate a virtual address into a physical address? Use a page table stored in memory and a base register pointing to the address of the first entry of the page table Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 55
Page Tables n Stores virtual address translation information n If page is present in memory n n n Array of page table entries, indexed by virtual page number Page table register in CPU points to page table in physical memory Page Table Entry (PTE) stores the physical page number Plus other status bits (referenced, dirty, …) If page is not present n PTE can refer to location in swap space on disk Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 56
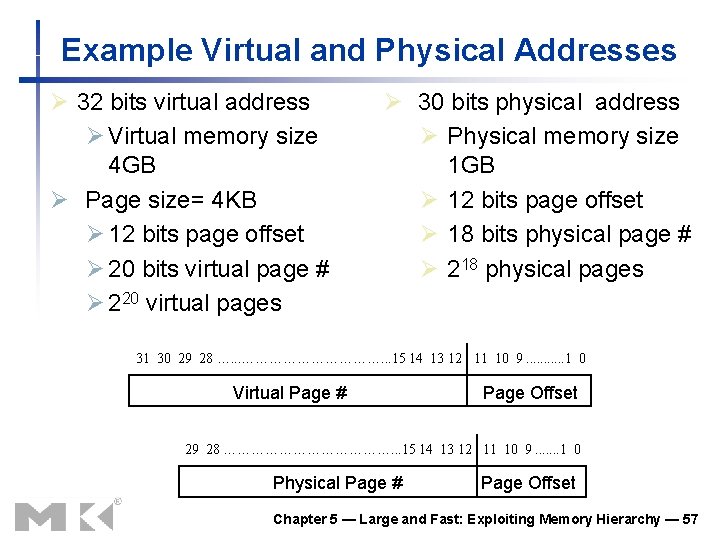
Example Virtual and Physical Addresses Ø 32 bits virtual address Ø Virtual memory size 4 GB Ø Page size= 4 KB Ø 12 bits page offset Ø 20 bits virtual page # Ø 220 virtual pages Ø 30 bits physical address Ø Physical memory size 1 GB Ø 12 bits page offset Ø 18 bits physical page # Ø 218 physical pages 31 30 29 28 …. . . ……………. . . 15 14 13 12 11 10 9. . . 1 0 Virtual Page # Page Offset 29 28 ………………. . . 15 14 13 12 11 10 9. . . . 1 0 Physical Page # Page Offset Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 57
Translation Using a Page Table Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 58
Mapping Pages to Storage Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 59
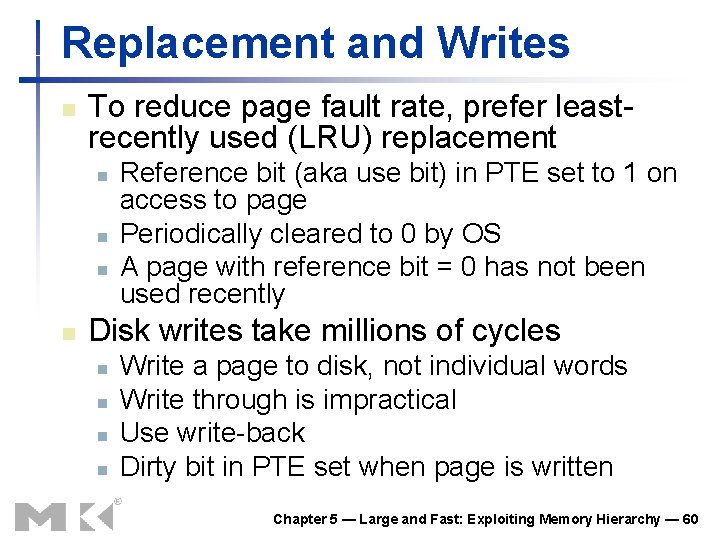
Replacement and Writes n To reduce page fault rate, prefer leastrecently used (LRU) replacement n n Reference bit (aka use bit) in PTE set to 1 on access to page Periodically cleared to 0 by OS A page with reference bit = 0 has not been used recently Disk writes take millions of cycles n n Write a page to disk, not individual words Write through is impractical Use write-back Dirty bit in PTE set when page is written Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 60
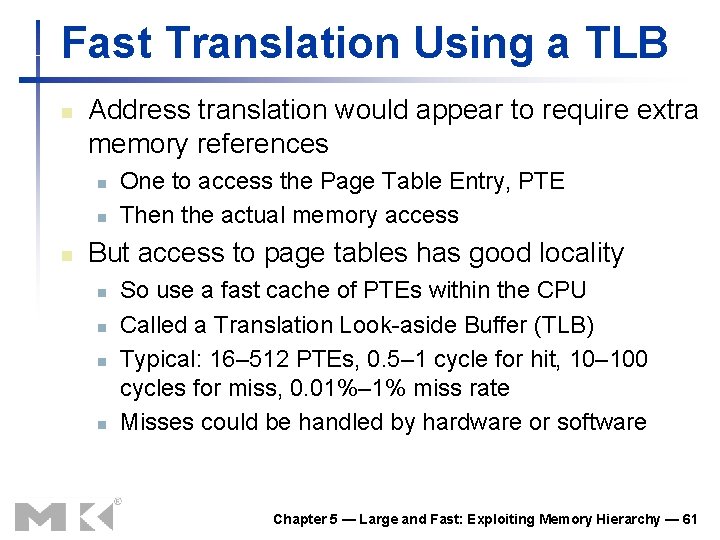
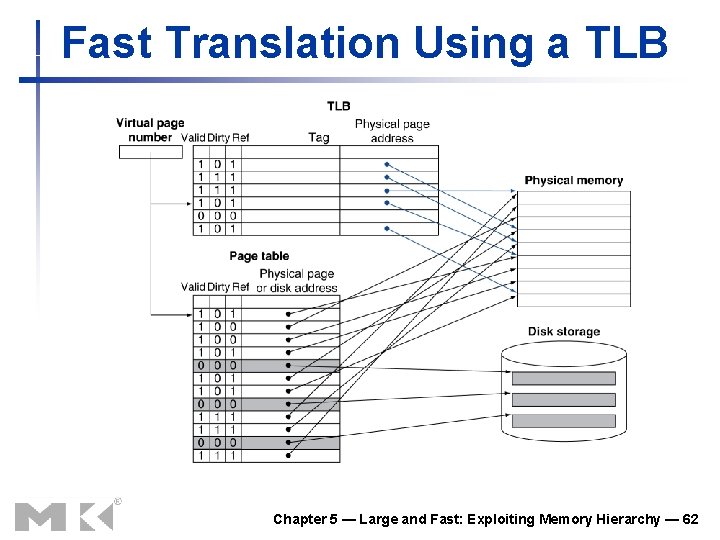
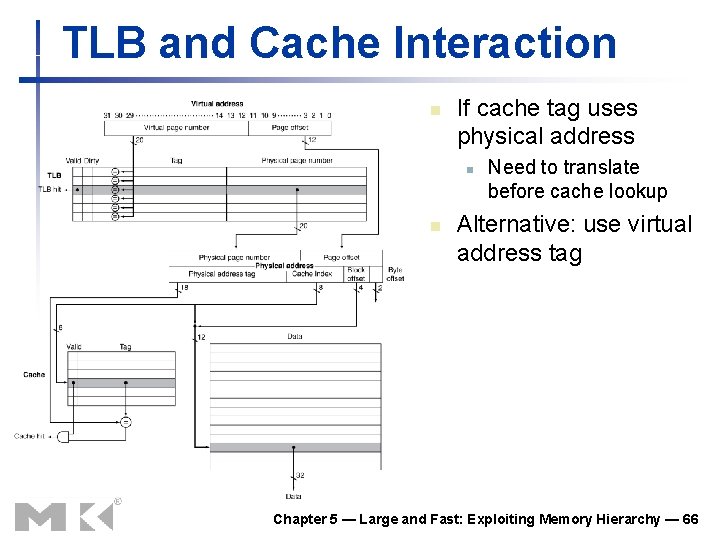
Fast Translation Using a TLB n Address translation would appear to require extra memory references n n n One to access the Page Table Entry, PTE Then the actual memory access But access to page tables has good locality n n So use a fast cache of PTEs within the CPU Called a Translation Look-aside Buffer (TLB) Typical: 16– 512 PTEs, 0. 5– 1 cycle for hit, 10– 100 cycles for miss, 0. 01%– 1% miss rate Misses could be handled by hardware or software Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 61
Fast Translation Using a TLB Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 62
TLB Misses n If page is in memory n n Load the PTE from memory and retry Could be handled in hardware n n Or in software n n Can get complex for more complicated page table structures Raise a special exception, with optimized handler If page is not in memory (page fault) n n OS handles fetching the page and updating the page table Then restart the faulting instruction Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 63
TLB Miss Handler n TLB miss indicates either n n n Must recognize TLB miss before destination register overwritten n n Page is present in main memory, but the associated PTE is not in TLB Page not preset (TLB is a cache for PTEs of pages residing in memory) Raise exception Handler copies PTE from memory to TLB n n Then restarts instruction If page not present, page fault will occur
Page Fault Handler n n n Use faulting virtual address to find PTE Locate page on disk Choose physical page to replace n n n If dirty, write to disk first Read page from disk into memory and update page table Make the process that caused the page fault runnable again n Restart from faulting instruction Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 65
TLB and Cache Interaction n If cache tag uses physical address n n Need to translate before cache lookup Alternative: use virtual address tag Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 66
The BIG Picture n Common principles apply at all levels of the memory hierarchy n n Based on notions of caching At each level in the hierarchy n n Block placement Finding a block Replacement on a miss Write policy § 5. 5 A Common Framework for Memory Hierarchies The Memory Hierarchy Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 67
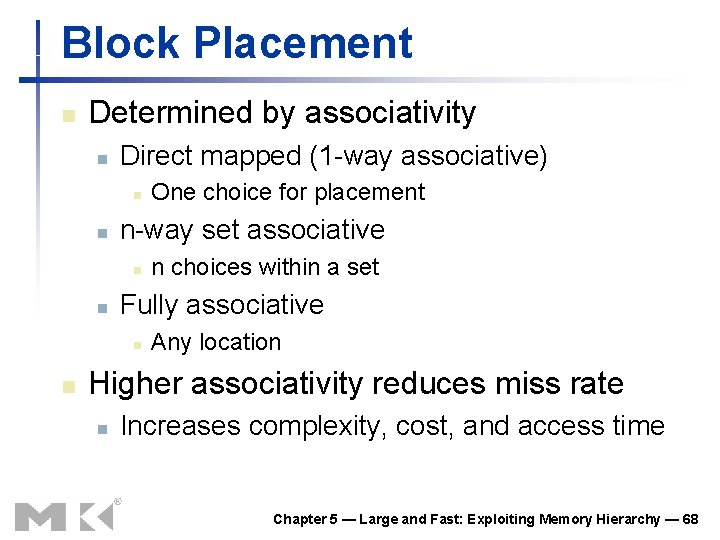
Block Placement n Determined by associativity n Direct mapped (1 -way associative) n n n-way set associative n n n choices within a set Fully associative n n One choice for placement Any location Higher associativity reduces miss rate n Increases complexity, cost, and access time Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 68
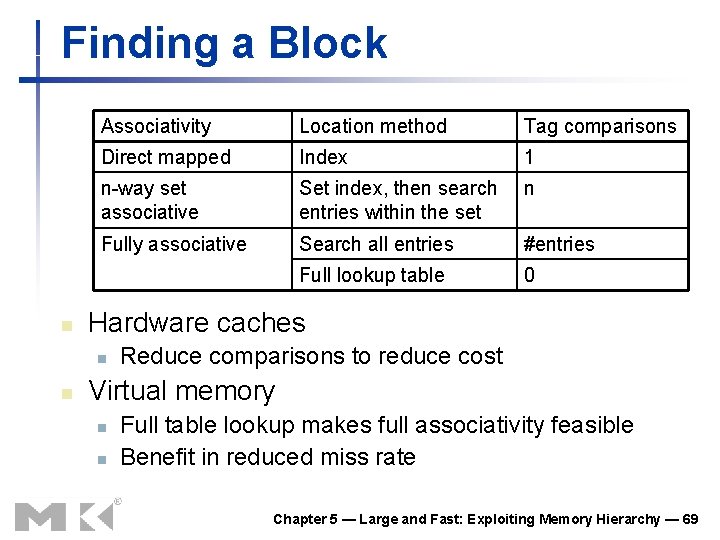
Finding a Block n Associativity Location method Tag comparisons Direct mapped Index 1 n-way set associative Set index, then search entries within the set n Fully associative Search all entries #entries Full lookup table 0 Hardware caches n n Reduce comparisons to reduce cost Virtual memory n n Full table lookup makes full associativity feasible Benefit in reduced miss rate Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 69
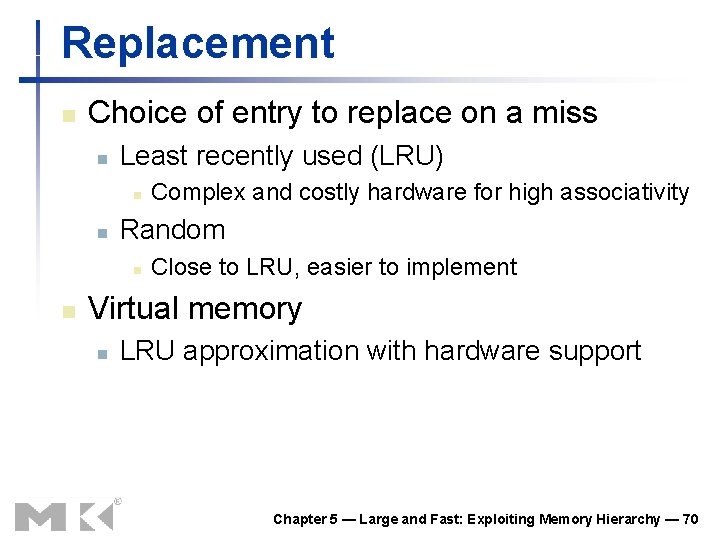
Replacement n Choice of entry to replace on a miss n Least recently used (LRU) n n Random n n Complex and costly hardware for high associativity Close to LRU, easier to implement Virtual memory n LRU approximation with hardware support Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 70
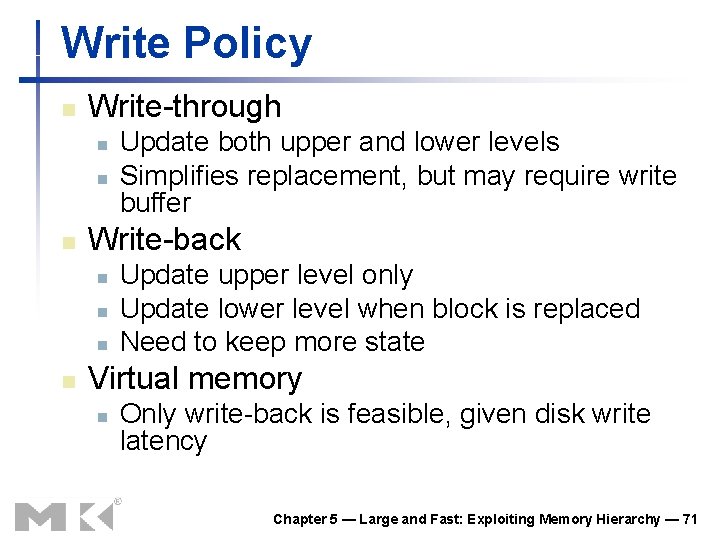
Write Policy n Write-through n n n Write-back n n Update both upper and lower levels Simplifies replacement, but may require write buffer Update upper level only Update lower level when block is replaced Need to keep more state Virtual memory n Only write-back is feasible, given disk write latency Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 71
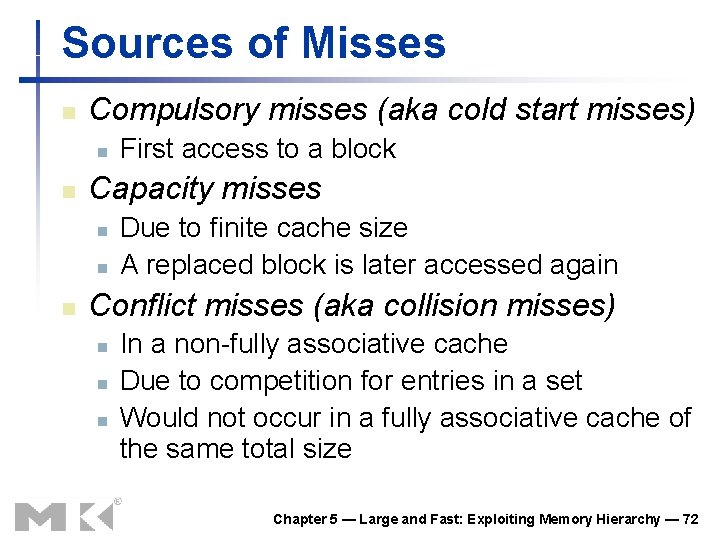
Sources of Misses n Compulsory misses (aka cold start misses) n n Capacity misses n n n First access to a block Due to finite cache size A replaced block is later accessed again Conflict misses (aka collision misses) n n n In a non-fully associative cache Due to competition for entries in a set Would not occur in a fully associative cache of the same total size Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 72
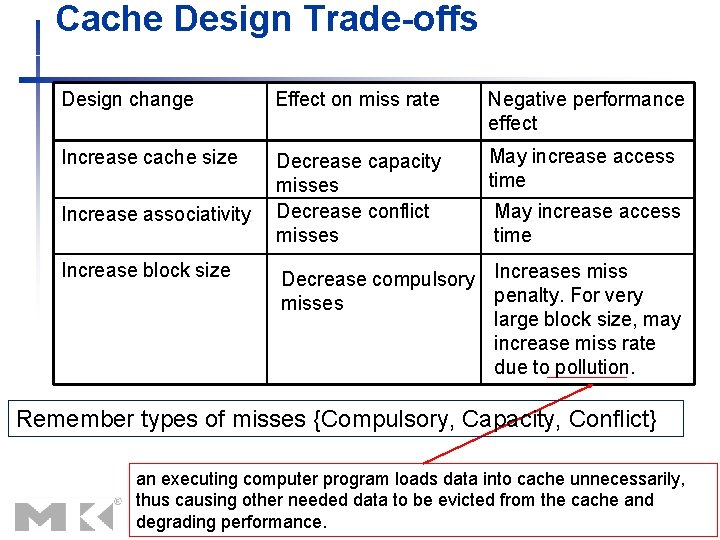
Cache Design Trade-offs Design change Effect on miss rate Negative performance effect Increase cache size Decrease capacity misses Decrease conflict misses May increase access time Increase associativity Increase block size May increase access time Decrease compulsory Increases miss penalty. For very misses large block size, may increase miss rate due to pollution. Remember types of misses {Compulsory, Capacity, Conflict} an executing computer program loads data into cache unnecessarily, thus causing other needed data to be evicted from the cache and degrading performance.
Skip section 5. 6 “Virtual Machines” Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 74
Next: Section 5. 7 Using a Finite State Machine to Control A Simple Cache Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 75
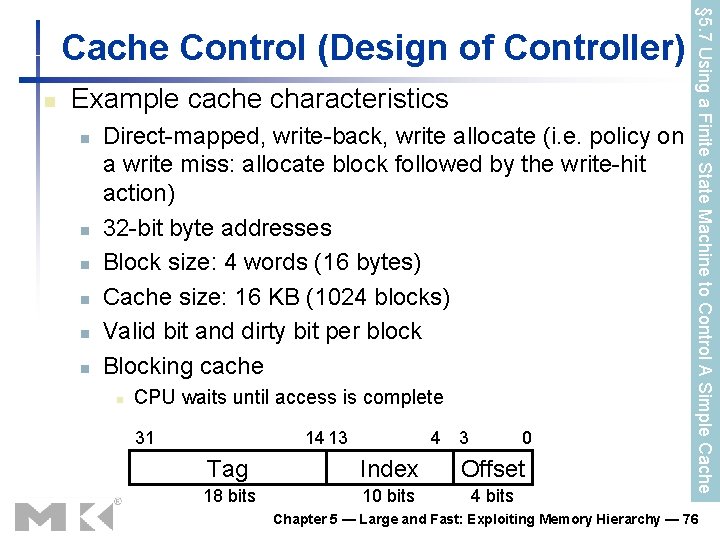
n Example cache characteristics n n n Direct-mapped, write-back, write allocate (i. e. policy on a write miss: allocate block followed by the write-hit action) 32 -bit byte addresses Block size: 4 words (16 bytes) Cache size: 16 KB (1024 blocks) Valid bit and dirty bit per block Blocking cache n CPU waits until access is complete 31 14 13 4 3 0 Tag Index Offset 18 bits 10 bits 4 bits § 5. 7 Using a Finite State Machine to Control A Simple Cache Control (Design of Controller) Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 76
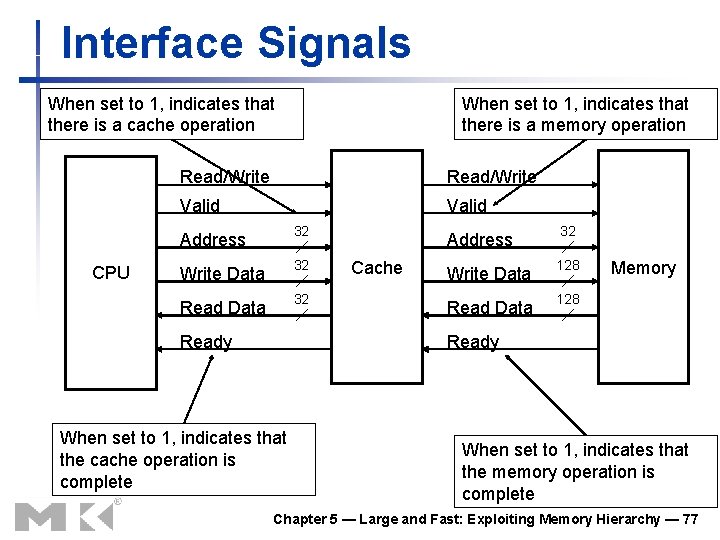
Interface Signals When set to 1, indicates that there is a cache operation CPU When set to 1, indicates that there is a memory operation Read/Write Valid Address 32 Write Data 32 Ready Cache Address 32 Write Data 128 Read Data 128 Memory Ready When set to 1, indicates that the cache operation is complete When set to 1, indicates that the memory operation is complete Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 77
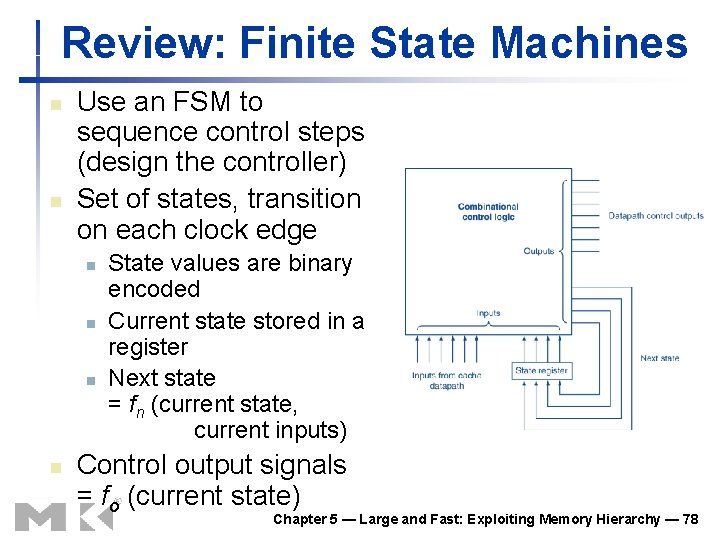
Review: Finite State Machines n n Use an FSM to sequence control steps (design the controller) Set of states, transition on each clock edge n n State values are binary encoded Current state stored in a register Next state = fn (current state, current inputs) Control output signals = fo (current state) Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 78
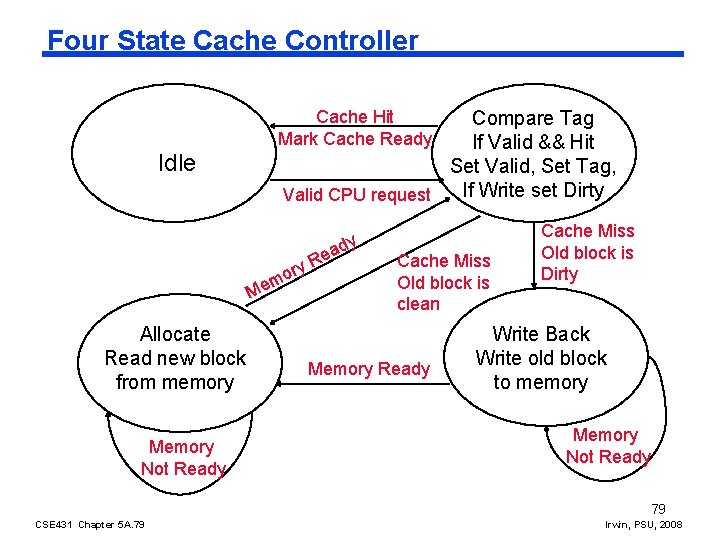
Four State Cache Controller Cache Hit Mark Cache Ready Compare Tag If Valid && Hit Set Valid, Set Tag, If Write set Dirty Valid CPU request Idle ory m e M Allocate Read new block from memory Memory Not Ready dy a e R Cache Miss Old block is clean Memory Ready Cache Miss Old block is Dirty Write Back Write old block to memory Memory Not Ready 79 CSE 431 Chapter 5 A. 79 Irwin, PSU, 2008
§ 5. 8 Parallelism and Memory Hierarchies: Cache Coherence 80 Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 80
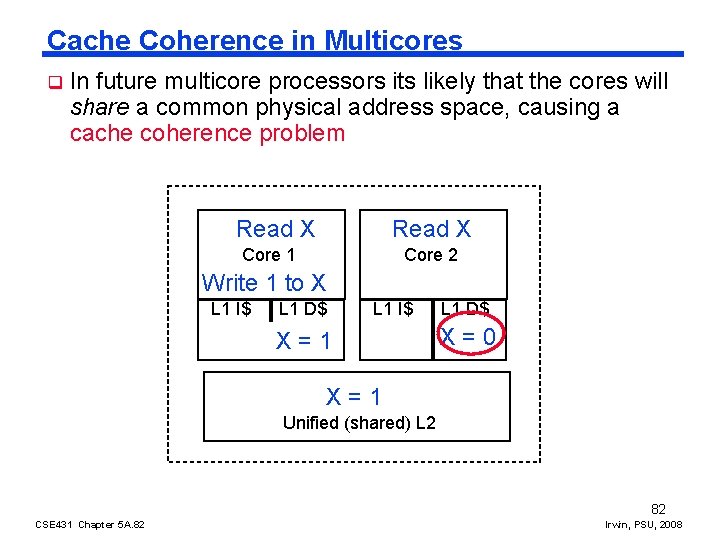
Cache Coherence in Multicores q In future multicore processors its likely that the cores will share a common physical address space, causing a cache coherence problem Read X Core 1 Core 2 Write 1 to X L 1 I$ L 1 D$ L 1 I$ XX == 01 L 1 D$ X=0 = 01 XX = Unified (shared) L 2 82 CSE 431 Chapter 5 A. 82 Irwin, PSU, 2008
Coherence Defined n n Informally: If caches are coherent, then reads return most recently written value Formally: n n n If core 1 writes X and then core 1 reads X (with no intervening writes) the read operation returns the written value Core 1 writes X then core 2 reads X (sufficiently later) the read operation returns the written value core 1 writes X then core 2 writes X cores 1 & 2 see writes in the same order n End up with the same final value for X Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 83
A Coherent Memory System q Any read of a data item should return the most recently written value of the data item Coherence – defines what values can be returned by a read - Writes to the same location are serialized (two writes to the same location must be seen in the same order by all cores) l Consistency – determines when a written value will be returned by a read l 84 CSE 431 Chapter 5 A. 84 Irwin, PSU, 2008
A Coherent Memory System (cont. ) q To enforce coherence, caches must provide Replication of shared data items in multiple cores’ caches (e. g. without accessing L 2 cache in our example) l Replication reduces both latency and contention for a read shared data item l Migration of shared data items to a core’s local cache l Migration reduced the latency of the access the data and the bandwidth demand on the shared memory (L 2 in our example) l 85 CSE 431 Chapter 5 A. 85 Irwin, PSU, 2008
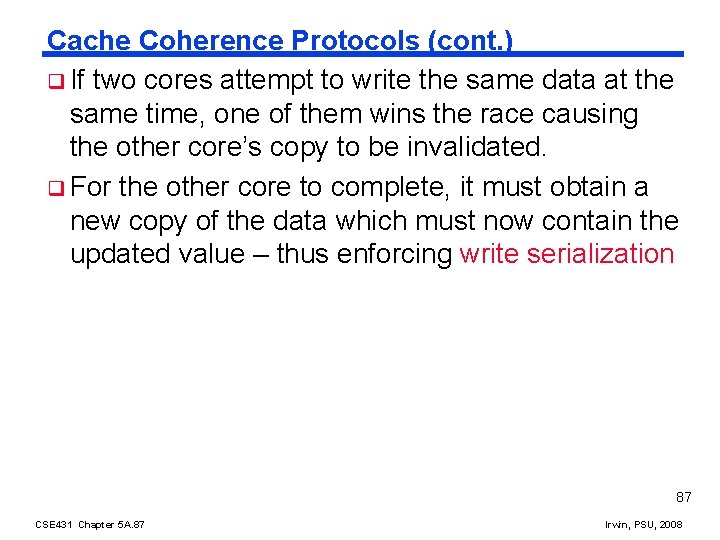
Cache Coherence Protocols q Need a hardware protocol to ensure cache coherence q the most popular of cache coherence protocols is snooping l The cache controllers monitor (snoop) on the broadcast medium (e. g. , bus) to determine if their cache has a copy of a block that is requested q Write invalidate protocol – writes require exclusive access and invalidate all other copies l Exclusive access ensure that no other readable or writable copies of an item exists 86 CSE 431 Chapter 5 A. 86 Irwin, PSU, 2008
Cache Coherence Protocols (cont. ) q If two cores attempt to write the same data at the same time, one of them wins the race causing the other core’s copy to be invalidated. q For the other core to complete, it must obtain a new copy of the data which must now contain the updated value – thus enforcing write serialization 87 CSE 431 Chapter 5 A. 87 Irwin, PSU, 2008
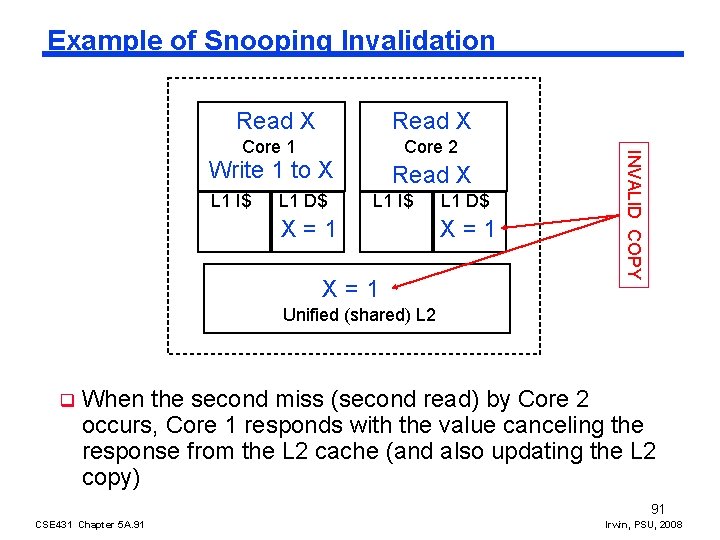
Example of Snooping Invalidation Read X Core 2 Write 1 to X L 1 I$ L 1 D$ Read X L 1 I$ X X == 01 XX==1 I 0 L 1 D$ X == 1 X 0 I INVALID COPY Core 1 Unified (shared) L 2 q When the second miss (second read) by Core 2 occurs, Core 1 responds with the value canceling the response from the L 2 cache (and also updating the L 2 copy) 91 CSE 431 Chapter 5 A. 91 Irwin, PSU, 2008
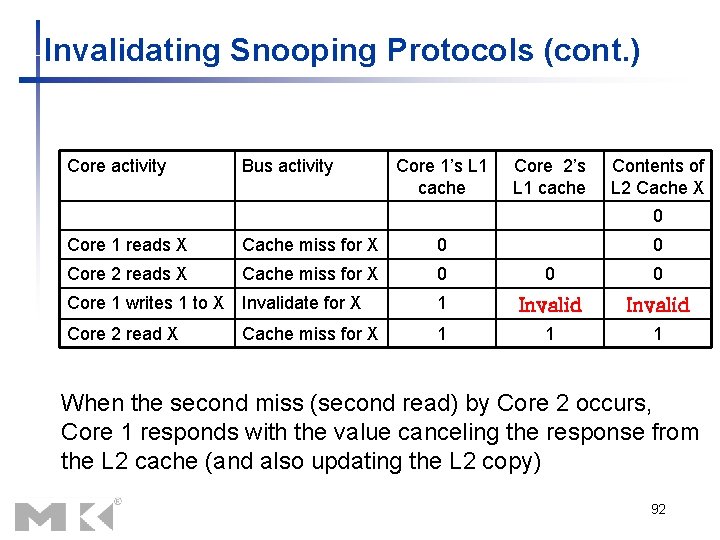
Invalidating Snooping Protocols (cont. ) Core activity Bus activity Core 1’s L 1 cache Core 2’s L 1 cache Contents of L 2 Cache X 0 Core 1 reads X Cache miss for X 0 Core 2 reads X Cache miss for X 0 0 0 Core 1 writes 1 to X Invalidate for X 1 Invalid Core 2 read X 1 1 1 Cache miss for X 0 When the second miss (second read) by Core 2 occurs, Core 1 responds with the value canceling the response from the L 2 cache (and also updating the L 2 copy) 92
Invalidating Snooping Protocols n A processor’s cache gets exclusive access to a block when this processor writes in this block n n n The exclusive access is achieved by broadcasting an “invalidate” message on the bus which will make copies of the block in caches of other processors invalid. A subsequent read by a another processor produces a cache miss Owning cache supplies updated value 93
Skip sections 5. 9, 5. 10, 5. 11 Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 94
§ 5. 12 Concluding Remarks Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 95
Concluding Remarks n Fast memories are small, large memories are slow n n n Principle of locality n n Programs use a small part of their memory space frequently Memory hierarchy n n We really want fast, large memories Caching gives this illusion L 1 cache L 2 cache … DRAM memory disk Memory system design is critical for multiprocessors (e. g. multicore microprocessors) Chapter 5 — Large and Fast: Exploiting Memory Hierarchy — 96