CS 4803 7643 Deep Learning Topics Convolutional Neural
- Slides: 57
CS 4803 / 7643: Deep Learning Topics: – Convolutional Neural Networks – (Finish) Backprop in conv layers – Toeplitz matrices and convolutions = matrix-mult – Dilated/a-trous convolutions – Transposed convolutions Dhruv Batra Georgia Tech
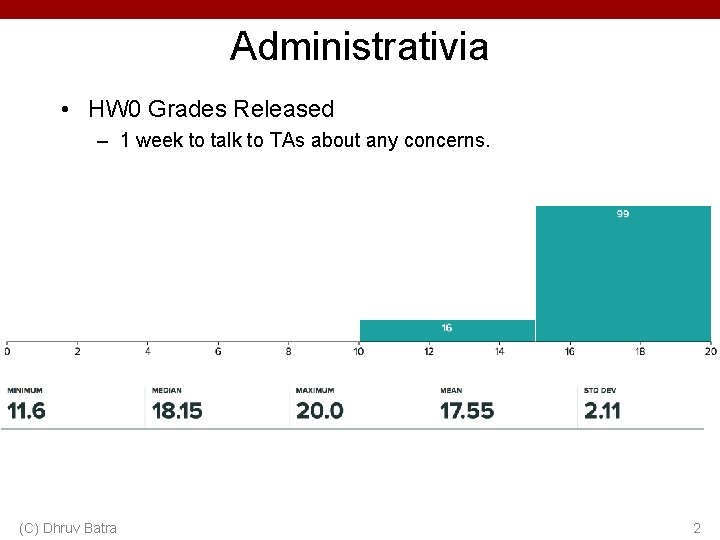
Administrativia • HW 0 Grades Released – 1 week to talk to TAs about any concerns. (C) Dhruv Batra 2
Administrativia • HW 1 Analysis – https: //evalai. cloudcv. org/web/challenges/challengepage/132/leaderboard/377 – https: //docs. google. com/spreadsheets/d/1 ke. PFv 77 CUMhnz. LFv. Vm. R 2 k 9 JP 0 MYLX 3 ea. LQS 84 vs. Vt. I/edit# gid=1412360458 – Overfitting plots (C) Dhruv Batra 3
Administrativia • HW 2 Released – Due: 10/18, 11: 55 pm – https: //www. cc. gatech. edu/classes/AY 2019/cs 7643_fall/asse ts/hw 2. pdf • Project Sign-up – Due: 10/05 – https: //reproducibility-challenge. github. io/iclr_2019/ – https: //docs. google. com/spreadsheets/d/1 Bip. WLvv. Wb 7 Fu 6 OSDd-u. OCF 1 Lr_4 dr. KOCRVdhxm_e. SHc/edit#gid=0 (C) Dhruv Batra 4
Recap from last time (C) Dhruv Batra 5
Can we have 1 x 1 filters? (C) Dhruv Batra 6
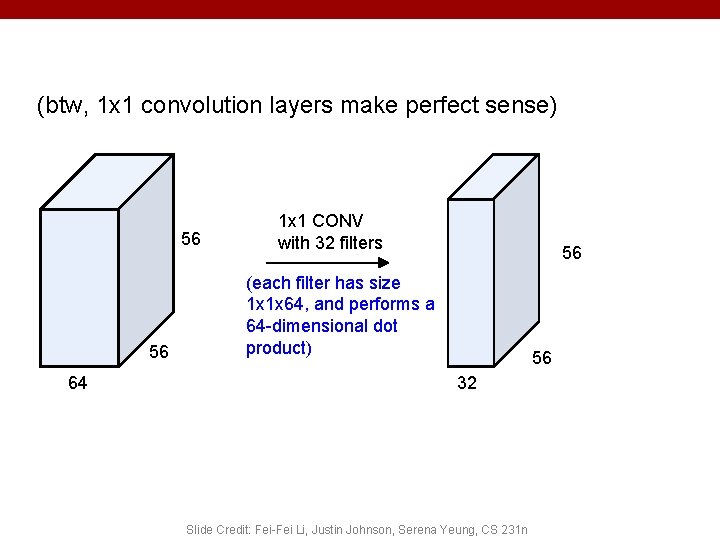
(btw, 1 x 1 convolution layers make perfect sense) 56 56 64 1 x 1 CONV with 32 filters 56 (each filter has size 1 x 1 x 64, and performs a 64 -dimensional dot product) 56 32 Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n
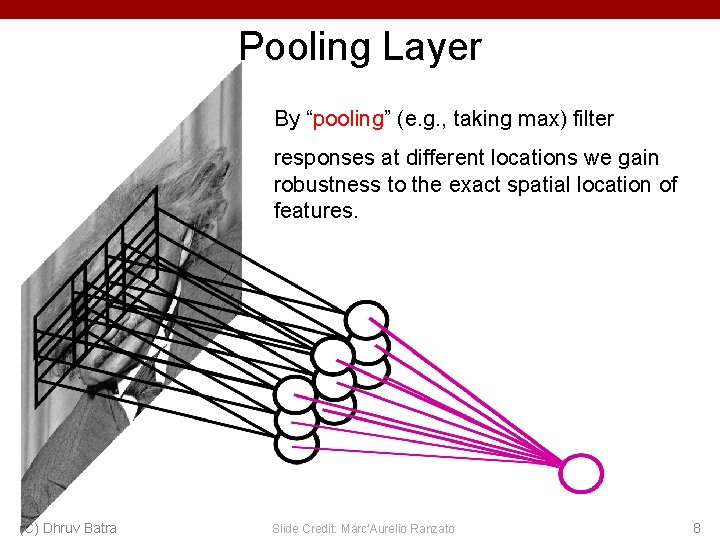
Pooling Layer By “pooling” (e. g. , taking max) filter responses at different locations we gain robustness to the exact spatial location of features. (C) Dhruv Batra Slide Credit: Marc'Aurelio Ranzato 8
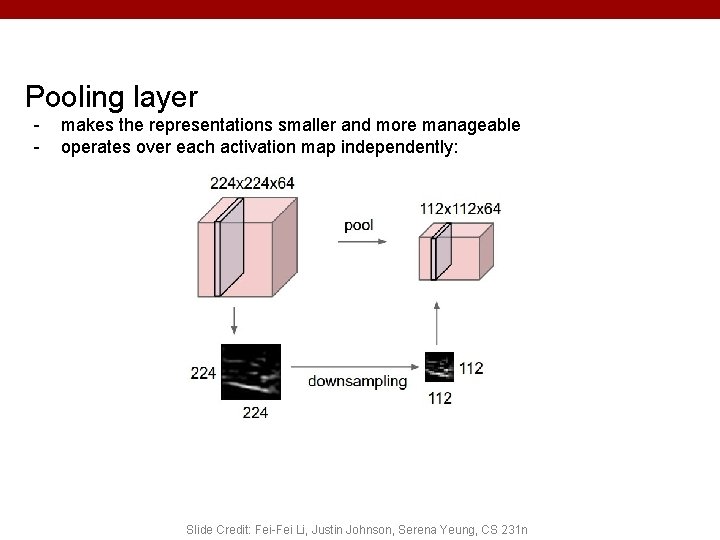
Pooling layer - makes the representations smaller and more manageable operates over each activation map independently: Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n
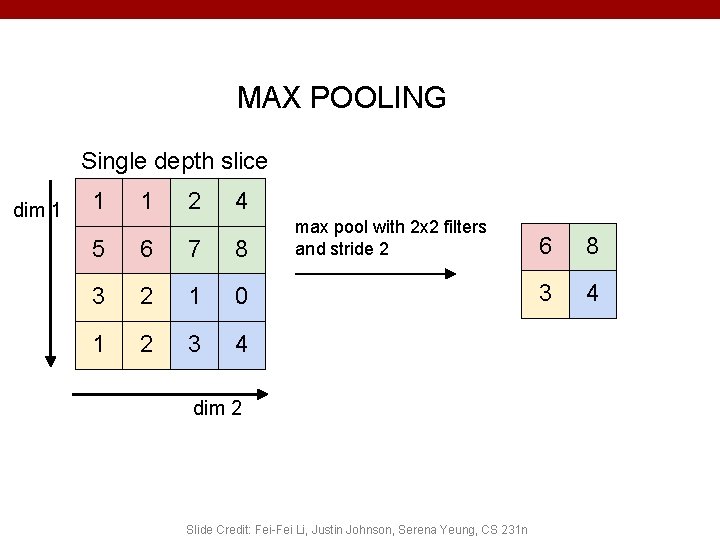
MAX POOLING Single depth slice dim 1 1 1 2 4 5 6 7 8 3 2 1 0 1 2 3 4 max pool with 2 x 2 filters and stride 2 dim 2 Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n 6 8 3 4
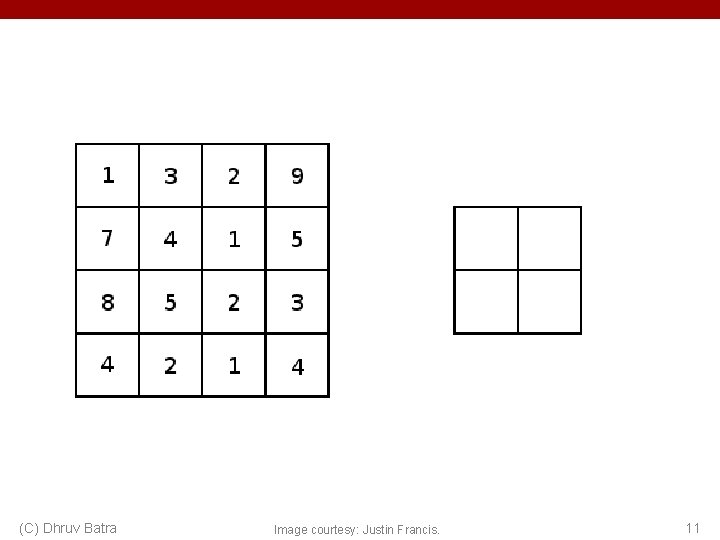
(C) Dhruv Batra Image courtesy: Justin Francis. 11
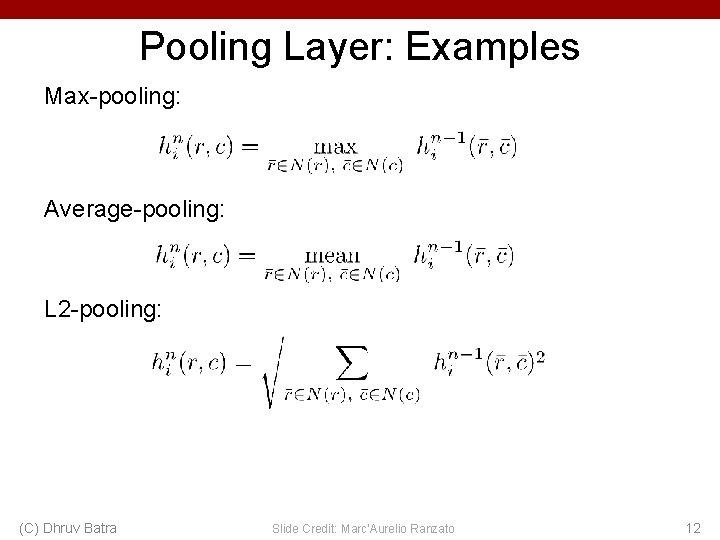
Pooling Layer: Examples Max-pooling: Average-pooling: L 2 -pooling: (C) Dhruv Batra Slide Credit: Marc'Aurelio Ranzato 12
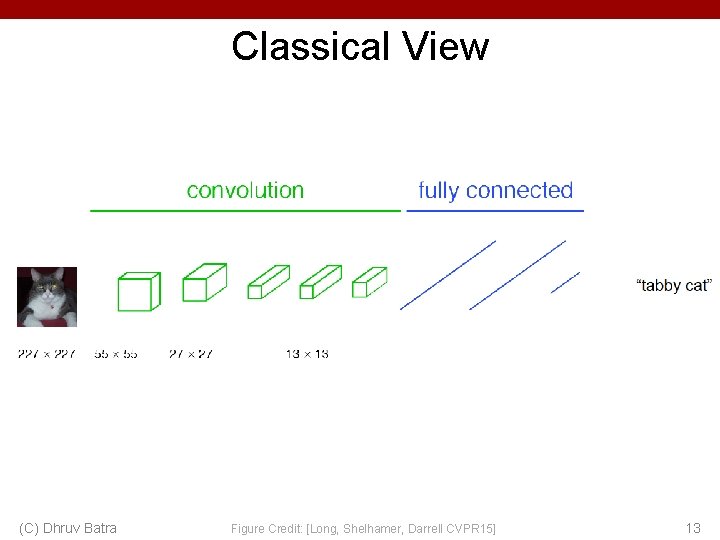
Classical View (C) Dhruv Batra Figure Credit: [Long, Shelhamer, Darrell CVPR 15] 13
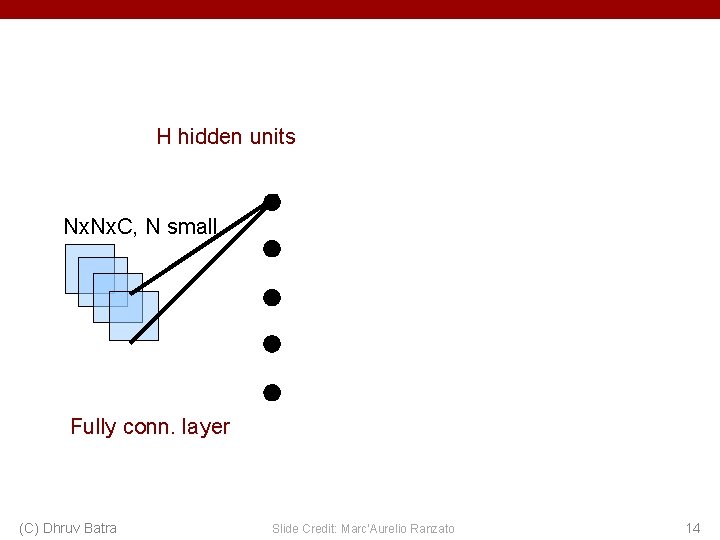
H hidden units Nx. C, N small Fully conn. layer (C) Dhruv Batra Slide Credit: Marc'Aurelio Ranzato 14
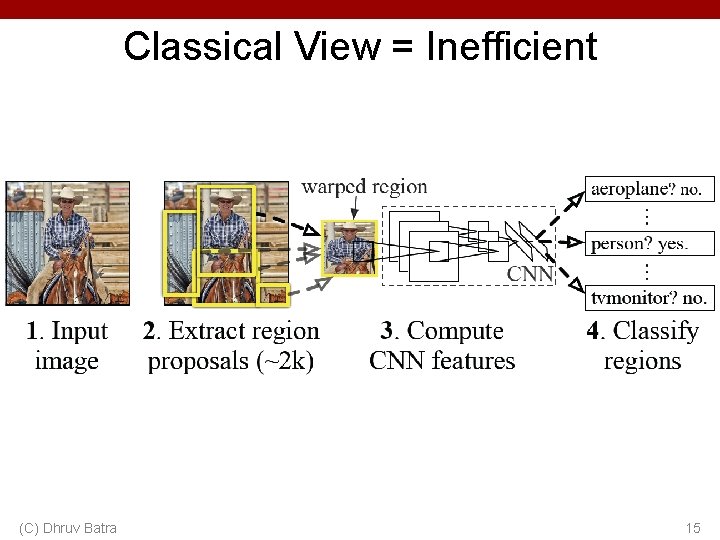
Classical View = Inefficient (C) Dhruv Batra 15
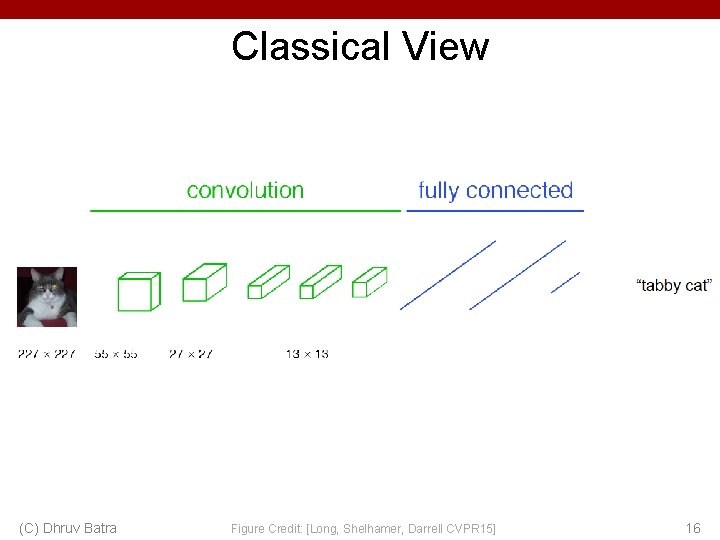
Classical View (C) Dhruv Batra Figure Credit: [Long, Shelhamer, Darrell CVPR 15] 16
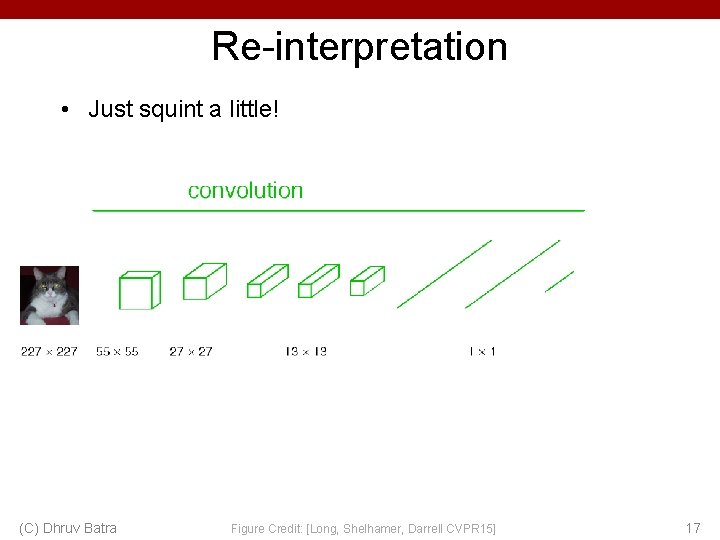
Re-interpretation • Just squint a little! (C) Dhruv Batra Figure Credit: [Long, Shelhamer, Darrell CVPR 15] 17
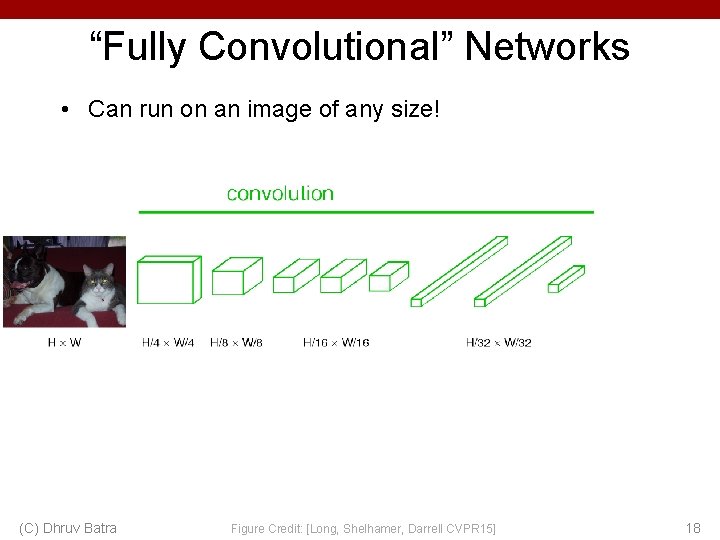
“Fully Convolutional” Networks • Can run on an image of any size! (C) Dhruv Batra Figure Credit: [Long, Shelhamer, Darrell CVPR 15] 18
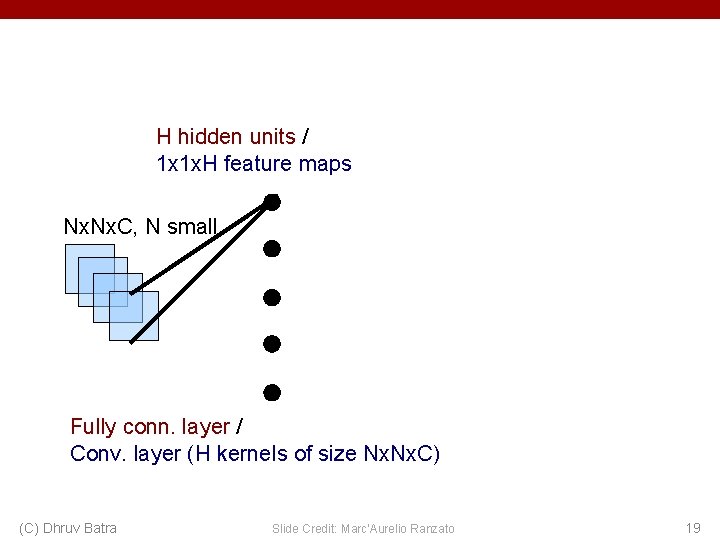
H hidden units / 1 x 1 x. H feature maps Nx. C, N small Fully conn. layer / Conv. layer (H kernels of size Nx. C) (C) Dhruv Batra Slide Credit: Marc'Aurelio Ranzato 19
Benefit of this thinking • Mathematically elegant • Efficiency – Can run network on arbitrary image – Without multiple crops (C) Dhruv Batra 20
Plan for Today • Convolutional Neural Networks – – (C) Dhruv Batra (Finish) Backprop in conv layers Dilated/a-trous convolutions Toeplitz matrices and convolutions = matrix-mult Transposed convolutions 21
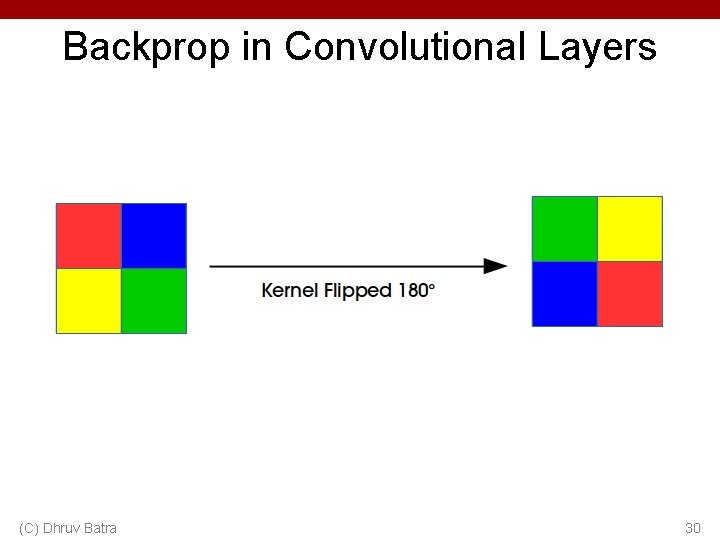
Backprop in Convolutional Layers • Notes – https: //www. cc. gatech. edu/classes/AY 2018/cs 7643_fall/slide s/L 6_cnns_backprop_notes. pdf (C) Dhruv Batra 22
Backprop in Convolutional Layers (C) Dhruv Batra 23
Backprop in Convolutional Layers (C) Dhruv Batra 24
Backprop in Convolutional Layers (C) Dhruv Batra 25
Backprop in Convolutional Layers (C) Dhruv Batra 26
Backprop in Convolutional Layers (C) Dhruv Batra 27
Backprop in Convolutional Layers (C) Dhruv Batra 28
Backprop in Convolutional Layers (C) Dhruv Batra 29
Backprop in Convolutional Layers (C) Dhruv Batra 30
Plan for Today • Convolutional Neural Networks – – (C) Dhruv Batra (Finish) Backprop in conv layers Dilated/a-trous convolutions Toeplitz matrices and convolutions = matrix-mult Transposed convolutions 31
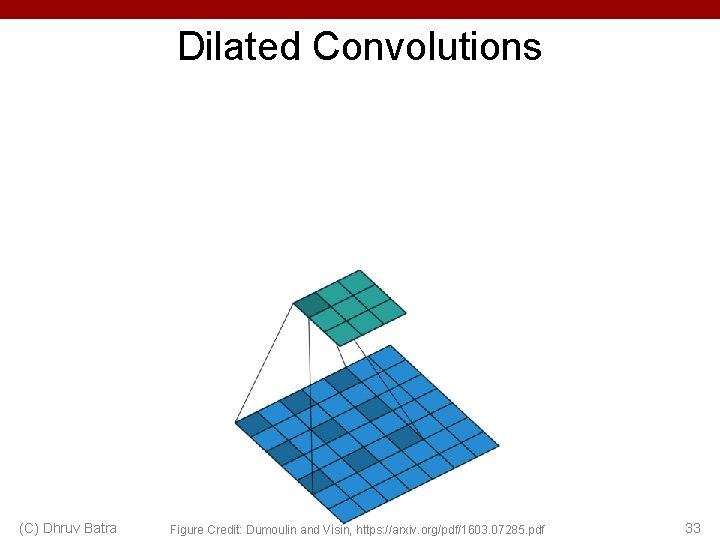
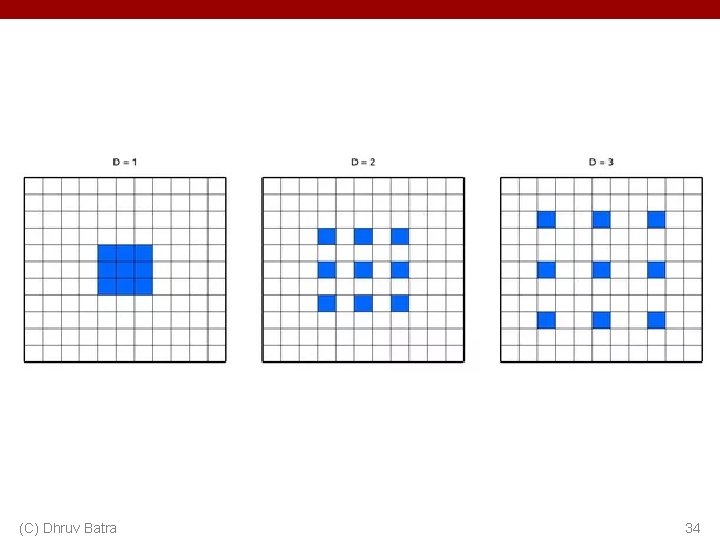
Dilated Convolutions (C) Dhruv Batra 32
Dilated Convolutions (C) Dhruv Batra Figure Credit: Dumoulin and Visin, https: //arxiv. org/pdf/1603. 07285. pdf 33
(C) Dhruv Batra 34
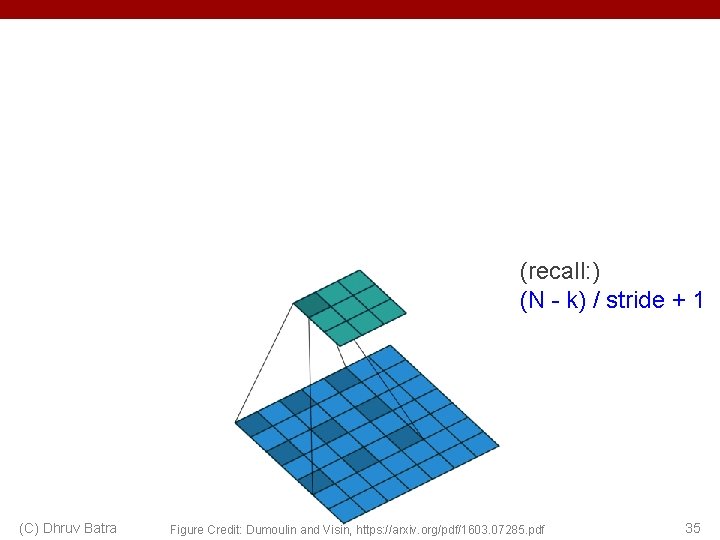
(recall: ) (N - k) / stride + 1 (C) Dhruv Batra Figure Credit: Dumoulin and Visin, https: //arxiv. org/pdf/1603. 07285. pdf 35
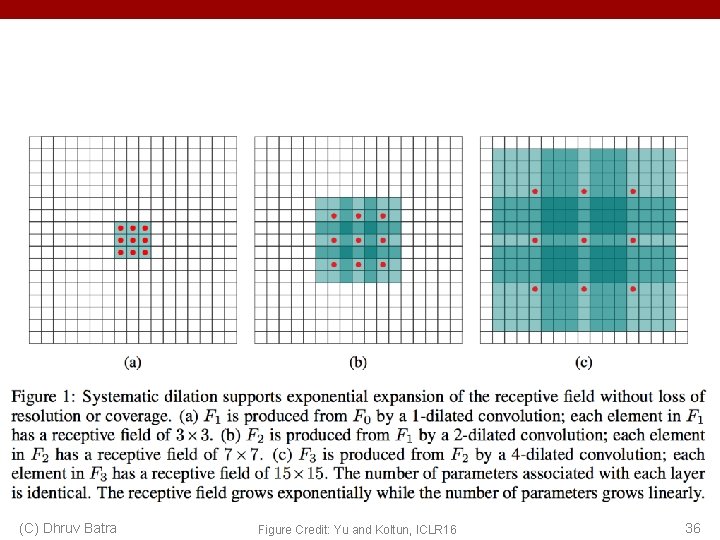
(C) Dhruv Batra Figure Credit: Yu and Koltun, ICLR 16 36
Plan for Today • Convolutional Neural Networks – – (C) Dhruv Batra (Finish) Backprop in conv layers Dilated/a-trous convolutions Toeplitz matrices and convolutions = matrix-mult Transposed convolutions 37
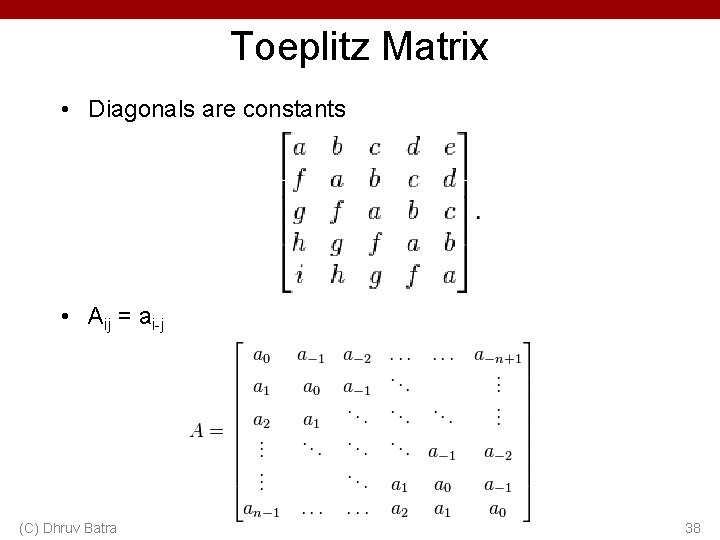
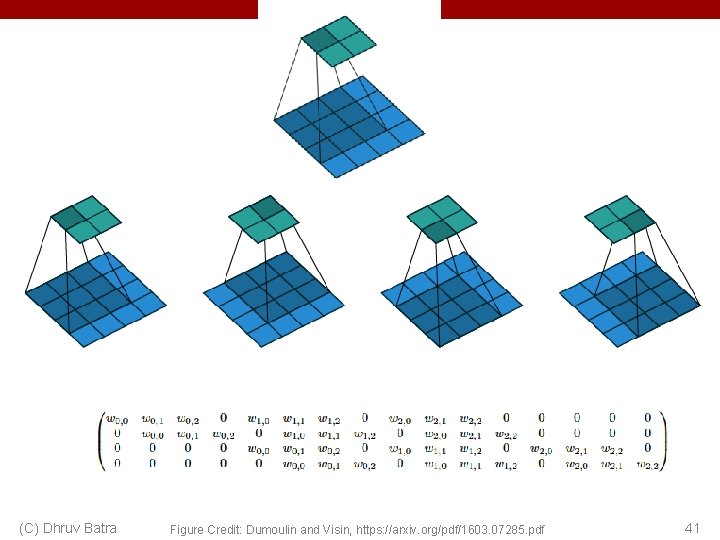
Toeplitz Matrix • Diagonals are constants • Aij = ai-j (C) Dhruv Batra 38
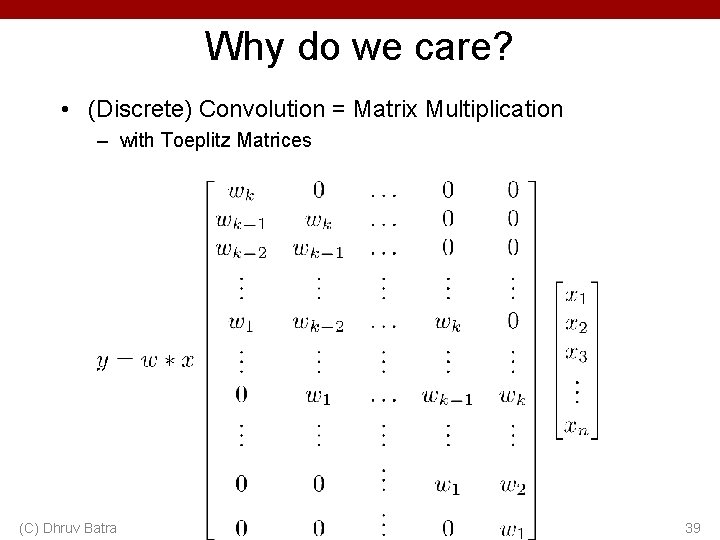
Why do we care? • (Discrete) Convolution = Matrix Multiplication – with Toeplitz Matrices (C) Dhruv Batra 39
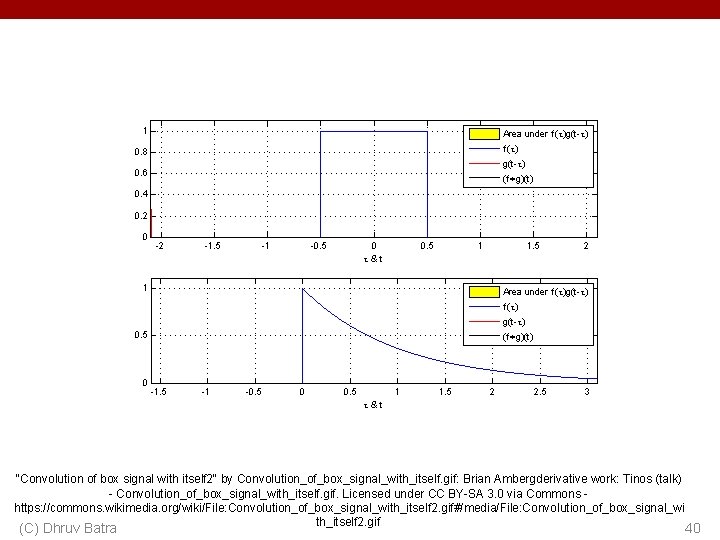
"Convolution of box signal with itself 2" by Convolution_of_box_signal_with_itself. gif: Brian Ambergderivative work: Tinos (talk) - Convolution_of_box_signal_with_itself. gif. Licensed under CC BY-SA 3. 0 via Commons https: //commons. wikimedia. org/wiki/File: Convolution_of_box_signal_with_itself 2. gif#/media/File: Convolution_of_box_signal_wi th_itself 2. gif (C) Dhruv Batra 40
(C) Dhruv Batra Figure Credit: Dumoulin and Visin, https: //arxiv. org/pdf/1603. 07285. pdf 41
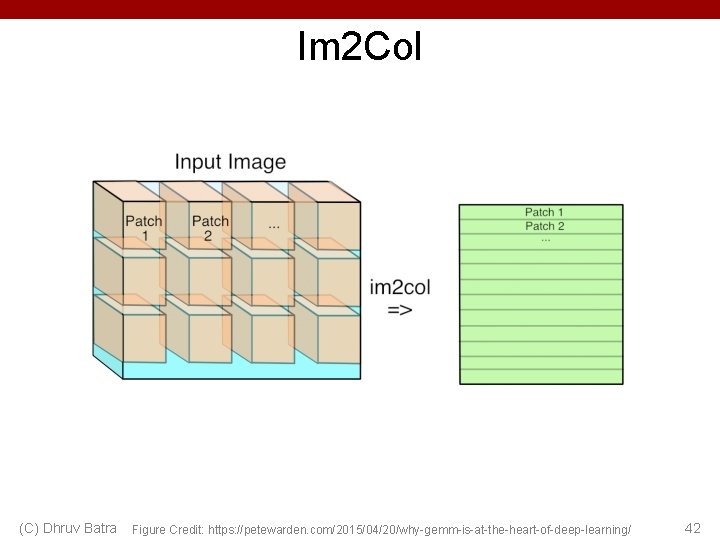
Im 2 Col (C) Dhruv Batra Figure Credit: https: //petewarden. com/2015/04/20/why-gemm-is-at-the-heart-of-deep-learning/ 42
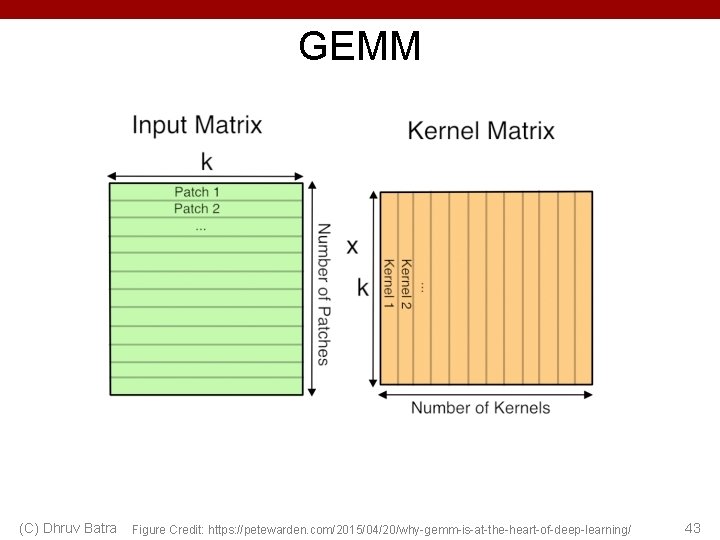
GEMM (C) Dhruv Batra Figure Credit: https: //petewarden. com/2015/04/20/why-gemm-is-at-the-heart-of-deep-learning/ 43
Plan for Today • Convolutional Neural Networks – – (C) Dhruv Batra (Finish) Backprop in conv layers Dilated/a-trous convolutions Toeplitz matrices and convolutions = matrix-mult Transposed convolutions 44
Transposed Convolutions • • Deconvolution (bad) Upconvolution Fractionally strided convolution Backward strided convolution (C) Dhruv Batra 45
So far: Image Classification Fully-Connected: 4096 to 1000 This image is CC 0 public domain Figure copyright Alex Krizhevsky, Ilya Sutskever, and Geoffrey Hinton, 2012. Reproduced with permission. Vector: 4096 Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n Class Scores Cat: 0. 9 Dog: 0. 05 Car: 0. 01. . .
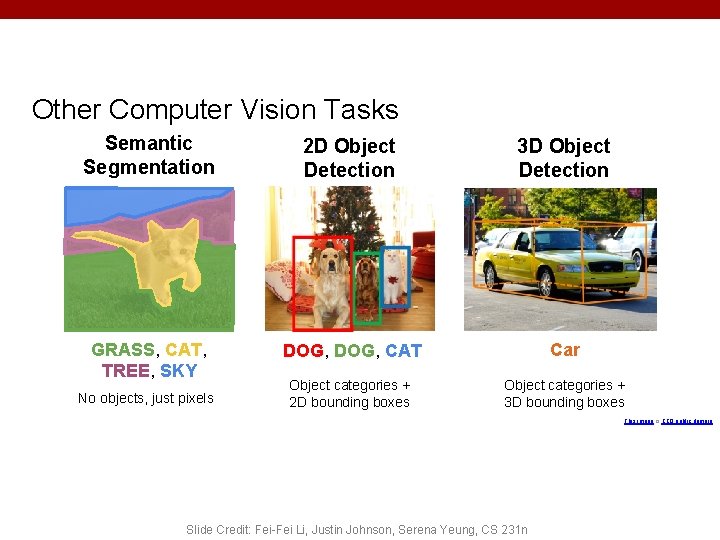
Other Computer Vision Tasks Semantic Segmentation 2 D Object Detection 3 D Object Detection GRASS, CAT, TREE, SKY DOG, CAT Car Object categories + 2 D bounding boxes Object categories + 3 D bounding boxes No objects, just pixels This image is CC 0 public domain Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n
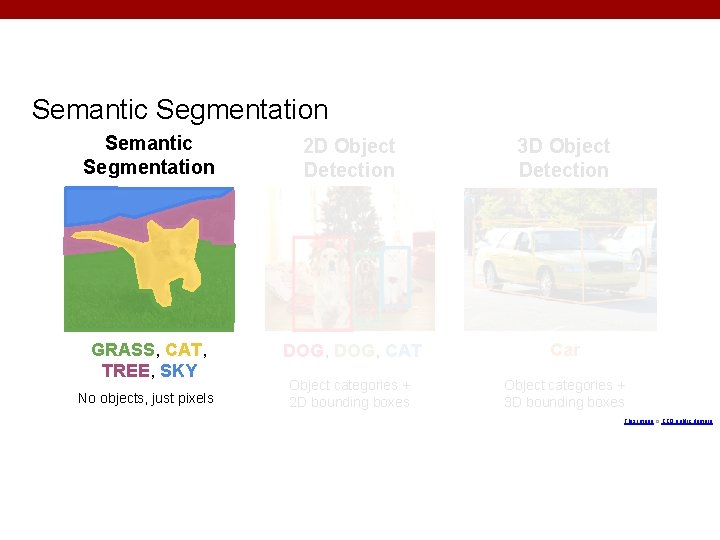
Semantic Segmentation 2 D Object Detection 3 D Object Detection GRASS, CAT, TREE, SKY DOG, CAT Car Object categories + 2 D bounding boxes Object categories + 3 D bounding boxes No objects, just pixels This image is CC 0 public domain
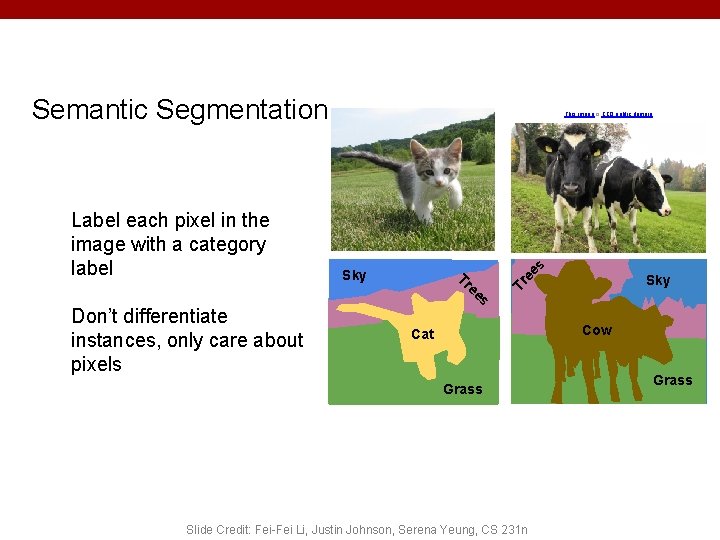
Semantic Segmentation s s ee Tr Don’t differentiate instances, only care about pixels Sky Tr ee Label each pixel in the image with a category label This image is CC 0 public domain Sky Cow Cat Grass Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n Grass
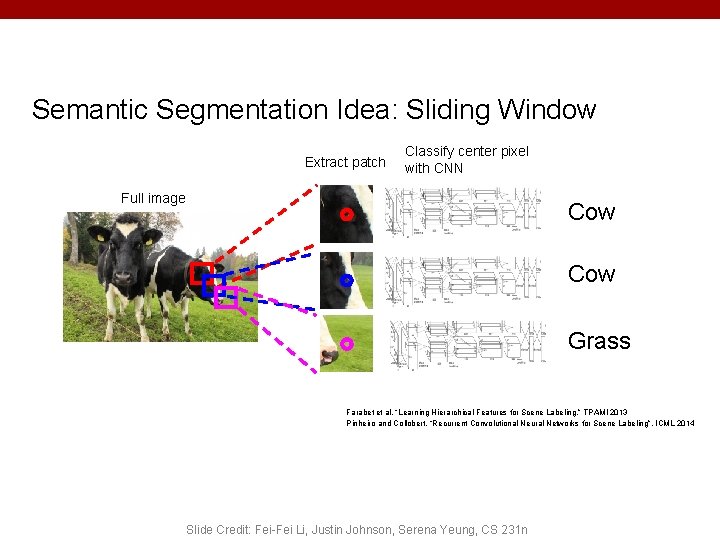
Semantic Segmentation Idea: Sliding Window Extract patch Classify center pixel with CNN Full image Cow Grass Farabet et al, “Learning Hierarchical Features for Scene Labeling, ” TPAMI 2013 Pinheiro and Collobert, “Recurrent Convolutional Neural Networks for Scene Labeling”, ICML 2014 Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n
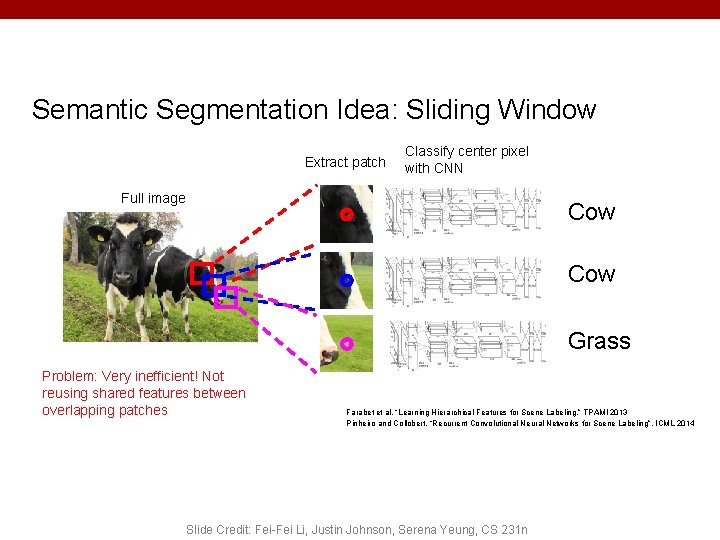
Semantic Segmentation Idea: Sliding Window Extract patch Classify center pixel with CNN Full image Cow Grass Problem: Very inefficient! Not reusing shared features between overlapping patches Farabet et al, “Learning Hierarchical Features for Scene Labeling, ” TPAMI 2013 Pinheiro and Collobert, “Recurrent Convolutional Neural Networks for Scene Labeling”, ICML 2014 Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n
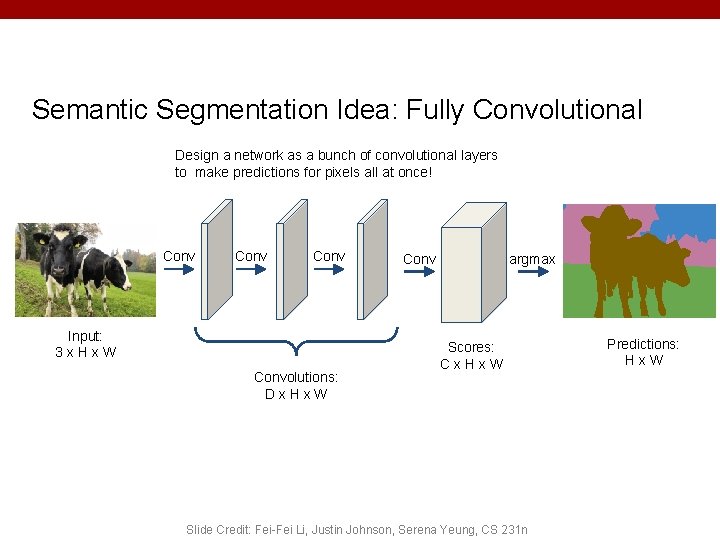
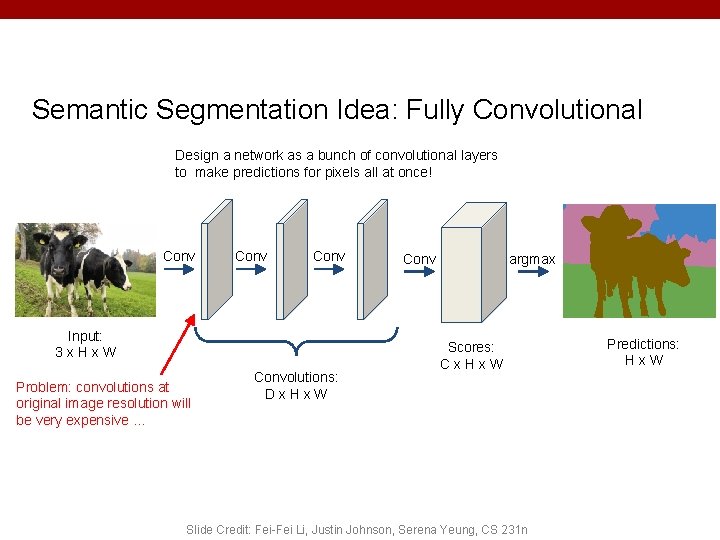
Semantic Segmentation Idea: Fully Convolutional Design a network as a bunch of convolutional layers to make predictions for pixels all at once! Conv Input: 3 x. Hx. W Convolutions: Dx. Hx. W Conv argmax Scores: Cx. Hx. W Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n Predictions: Hx. W
Semantic Segmentation Idea: Fully Convolutional Design a network as a bunch of convolutional layers to make predictions for pixels all at once! Conv Input: 3 x. Hx. W Problem: convolutions at original image resolution will be very expensive. . . Convolutions: Dx. Hx. W Conv argmax Scores: Cx. Hx. W Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n Predictions: Hx. W
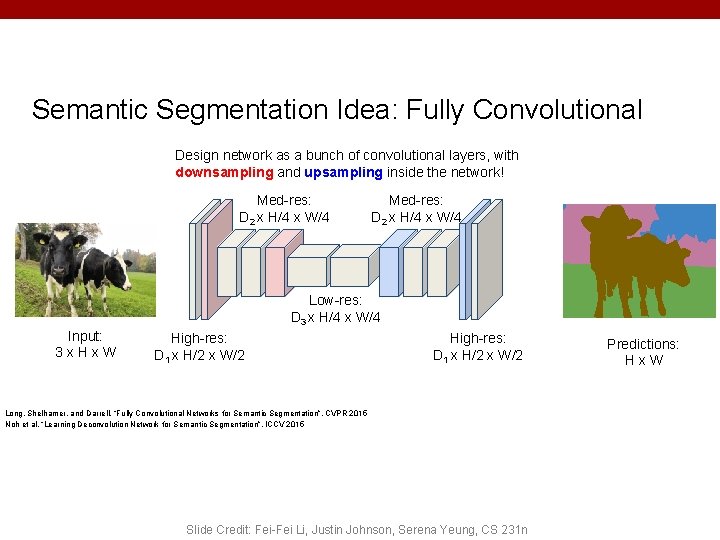
Semantic Segmentation Idea: Fully Convolutional Design network as a bunch of convolutional layers, with downsampling and upsampling inside the network! Med-res: D 2 x H/4 x W/4 Low-res: D 3 x H/4 x W/4 Input: 3 x. Hx. W High-res: D 1 x H/2 x W/2 Long, Shelhamer, and Darrell, “Fully Convolutional Networks for Semantic Segmentation”, CVPR 2015 Noh et al, “Learning Deconvolution Network for Semantic Segmentation”, ICCV 2015 Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n Predictions: Hx. W
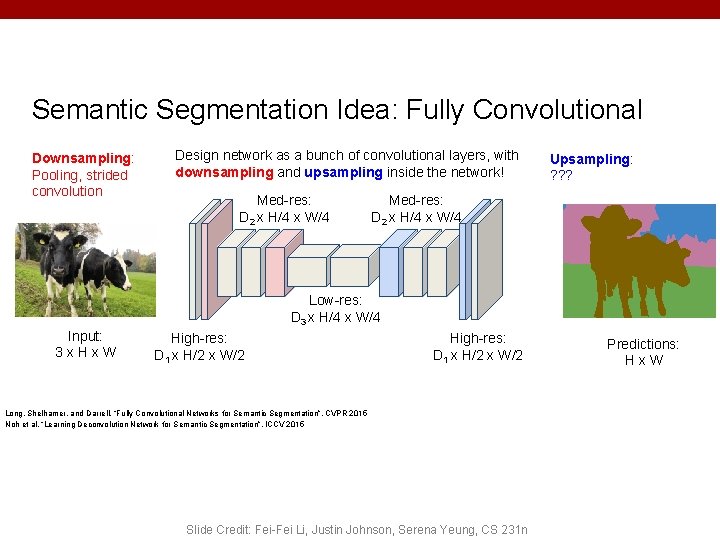
Semantic Segmentation Idea: Fully Convolutional Downsampling: Pooling, strided convolution Design network as a bunch of convolutional layers, with downsampling and upsampling inside the network! Med-res: D 2 x H/4 x W/4 Upsampling: ? ? ? Med-res: D 2 x H/4 x W/4 Low-res: D 3 x H/4 x W/4 Input: 3 x. Hx. W High-res: D 1 x H/2 x W/2 Long, Shelhamer, and Darrell, “Fully Convolutional Networks for Semantic Segmentation”, CVPR 2015 Noh et al, “Learning Deconvolution Network for Semantic Segmentation”, ICCV 2015 Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n Predictions: Hx. W
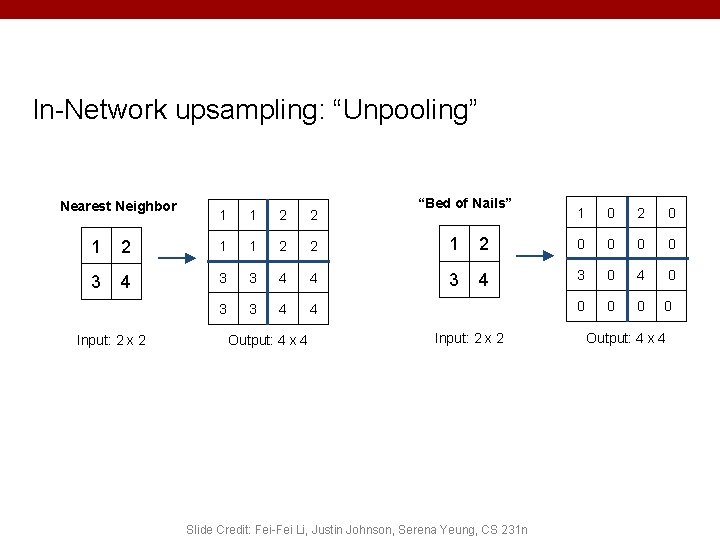
In-Network upsampling: “Unpooling” Nearest Neighbor 1 1 2 2 “Bed of Nails” 1 0 2 0 1 2 1 1 2 2 1 2 0 0 3 4 3 3 4 4 3 0 4 0 3 3 4 4 0 0 Input: 2 x 2 Output: 4 x 4 Input: 2 x 2 Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n Output: 4 x 4
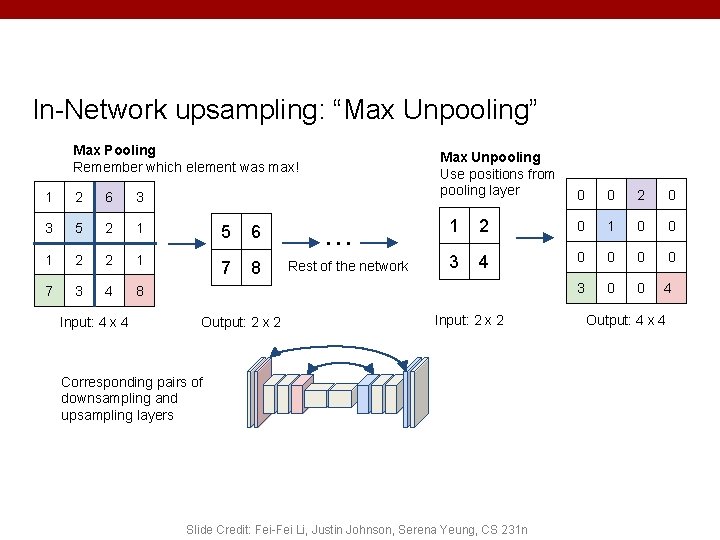
In-Network upsampling: “Max Unpooling” Max Pooling Remember which element was max! 1 2 6 3 3 5 2 1 5 6 1 2 2 1 7 8 7 3 4 8 Input: 4 x 4 Output: 2 x 2 Max Unpooling Use positions from pooling layer … Rest of the network 0 0 2 0 1 0 0 3 4 0 0 3 0 0 4 Input: 2 x 2 Corresponding pairs of downsampling and upsampling layers Slide Credit: Fei-Fei Li, Justin Johnson, Serena Yeung, CS 231 n Output: 4 x 4