Adding Search to the Hadoop Ecosystem Gregory Chanan
- Slides: 34
Adding Search to the Hadoop Ecosystem Gregory Chanan (gchanan AT cloudera. com) LA HUG Sept 2013 1
Agenda • • • Big Data and Search – setting the stage Cloudera Search Architecture Component deep dive Security Conclusion
Why Search? Hadoop for everyone • Typical case: • Ingest data to storage engine (HDFS, HBase, etc) • Process data (Map. Reduce, Hive, Impala) • Experts know Map. Reduce • Savvy people know SQL • Everyone knows Search! •
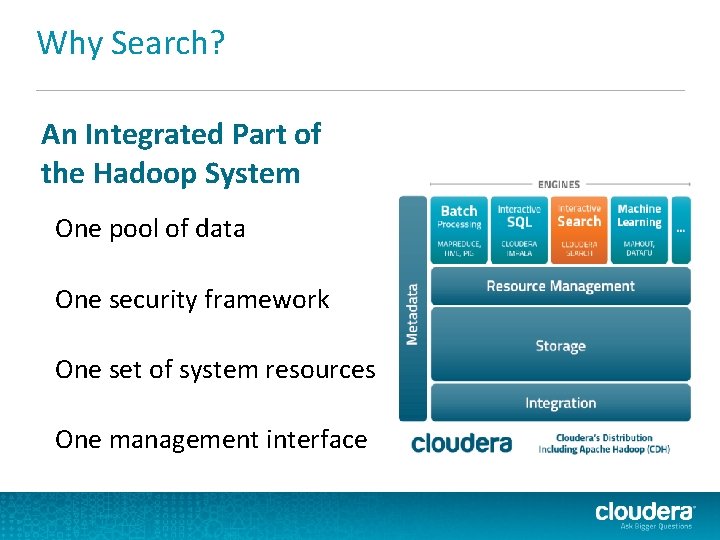
Why Search? An Integrated Part of the Hadoop System One pool of data One security framework One set of system resources One management interface
Benefits of Search • Improved Big Data ROI An interactive experience without technical knowledge • Single data set for multiple computing frameworks • • Faster time to insight Exploratory analysis, esp. unstructured data • Broad range of indexing options to accommodate needs • • Cost efficiency Single scalable platform; no incremental investment • No need for separate systems, storage •
What is Cloudera Search? Full-text, interactive search with faceted navigation • Apache Solr integrated with CDH • Established, mature search with vibrant community • In production environments for years • • Open Source 100% Apache, 100% Solr • Standard Solr APIs • Batch, near real-time, and on-demand indexing • Released 1. 0 (GA) last week! •
Cloudera Search Components HDFS/MR/Lucene/Solr. Cloud • Indexing • Near Real Time (NRT) indexing • Batch • ETL – Cloudera Morphlines • Querying •
Apache Hadoop • Apache HDFS Distributed file system • High reliability • High throughput • • Apache Map. Reduce Parallel, distributed programming model • Allows processing of large datasets • Fault tolerant •
Apache Lucene • Full text search Indexing • Query • Traditional inverted index • Batch and Incremental indexing • We are using version 4. 4 in current release •
Apache Solr • Search service built using Lucene • • Ships with Lucene (same TLP at Apache) Provides XML/HTTP/JSON/Python/Ruby/… APIs Indexing • Query • Administrative interface • Also rich web admin GUI via HTTP •
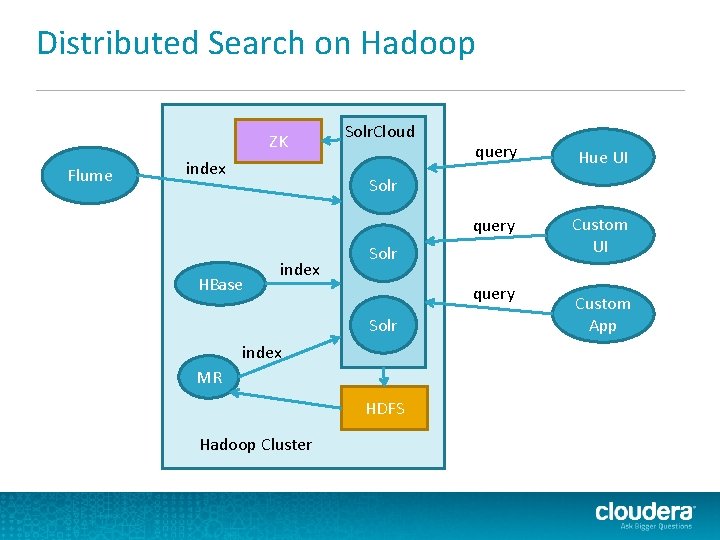
Apache Solr. Cloud Provides distributed Search capability • Part of Solr (not a separate library/codebase) • Shards – provide scalability • partition index for size • replicate for query performance • • Uses Zoo. Keeper for coordination No split-brain issues • Simplifies operations •
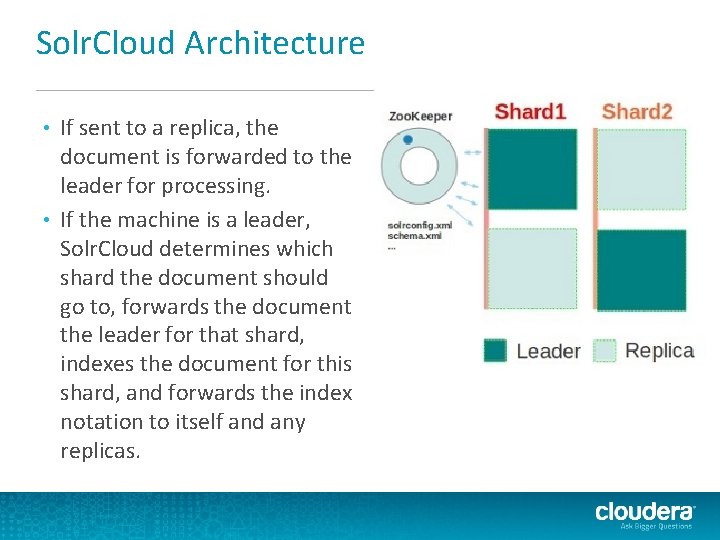
Solr. Cloud Architecture If sent to a replica, the document is forwarded to the leader for processing. • If the machine is a leader, Solr. Cloud determines which shard the document should go to, forwards the document the leader for that shard, indexes the document for this shard, and forwards the index notation to itself and any replicas. •
Distributed Search on Hadoop ZK Flume index Solr. Cloud query Hue UI query Custom UI Solr HBase index Solr query Solr index MR HDFS Hadoop Cluster Custom App
Indexing • Near Real Time (NRT) Flume • HBase Indexer • • Batch (MR)
Indexing • Near Real Time (NRT) Flume • HBase Indexer • • Batch (MR)
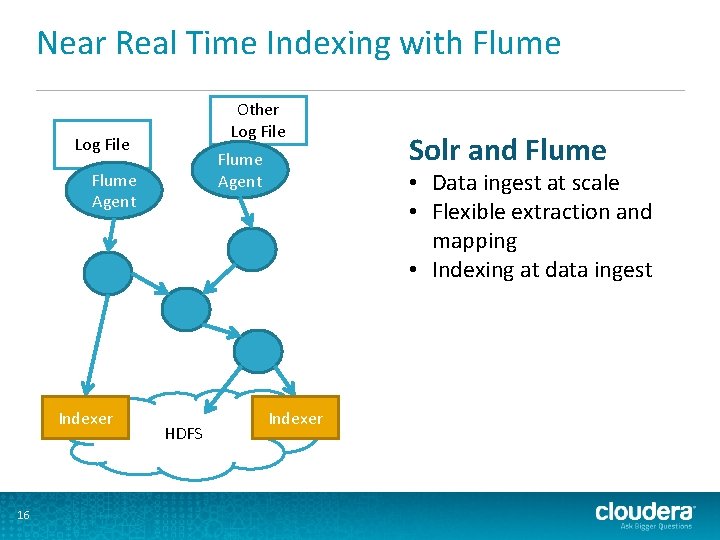
Near Real Time Indexing with Flume Other Log File Flume Agent Indexer 16 HDFS Solr and Flume • Data ingest at scale • Flexible extraction and mapping • Indexing at data ingest Indexer
Apache Flume - Morphline. Solr. Sink • A Flume Source… • • A Flume Channel… • • Carries the event – Memory. Channel or reliable File. Channel A Flume Sink… • • Receives/gathers events Sends the events on to the next location Flume Morphline. Solr. Sink • Integrates Cloudera Morphlines library • ETL, more on that in a bit Does batching • Results sent to Solr for indexing •
Indexing • Near Real Time (NRT) Flume • HBase Indexer • • Batch (MR)
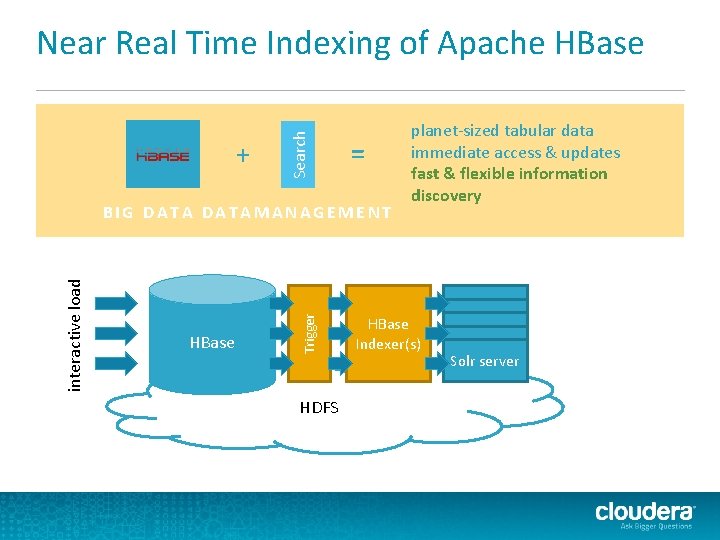
+ Search Near Real Time Indexing of Apache HBase = HBase Trigger interactive load BIG DATAMANAGEMENT HDFS planet-sized tabular data immediate access & updates fast & flexible information discovery HBase Indexer(s) Solr server Solr server
Lily HBase Indexer • Collaboration between NGData & Cloudera • • NGData are creators of the Lily data management platform Lily HBase Indexer • Service which acts as a HBase replication listener • HBase replication features, such as filtering, supported Replication updates trigger indexing of updates (rows) • Integrates Cloudera Morphlines library for ETL of rows • AL 2 licensed on github https: //github. com/ngdata •
Indexing • Near Real Time (NRT) Flume • HBase Indexer • • Batch (MR)
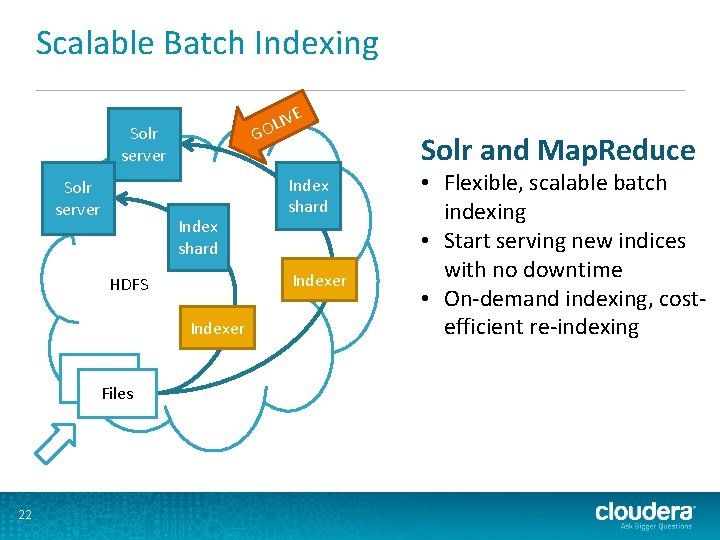
Scalable Batch Indexing E LIV O G Solr server Index shard Indexer HDFS Indexer Files 22 Index shard Solr and Map. Reduce • Flexible, scalable batch indexing • Start serving new indices with no downtime • On-demand indexing, costefficient re-indexing
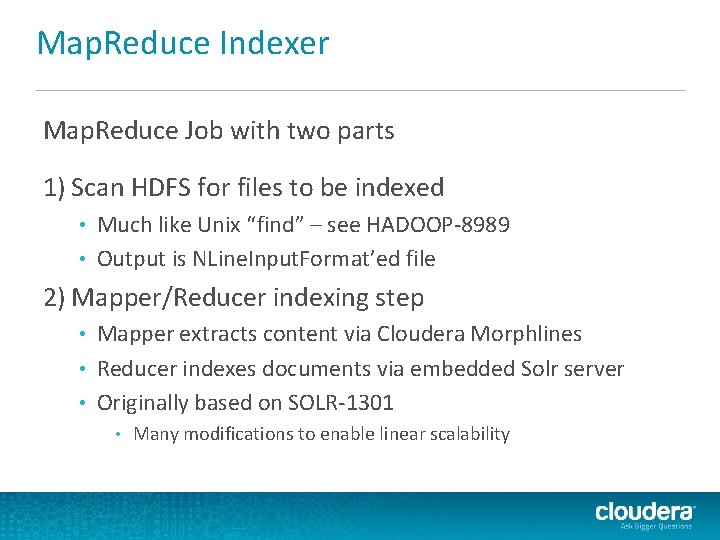
Map. Reduce Indexer Map. Reduce Job with two parts 1) Scan HDFS for files to be indexed Much like Unix “find” – see HADOOP-8989 • Output is NLine. Input. Format’ed file • 2) Mapper/Reducer indexing step Mapper extracts content via Cloudera Morphlines • Reducer indexes documents via embedded Solr server • Originally based on SOLR-1301 • • Many modifications to enable linear scalability
Map. Reduce Indexer “golive” Cloudera created this to bridge the gap between NRT (low latency, expensive) and Batch (high latency, cheap at scale) indexing • Results of MR indexing operation are immediately merged into a live Solr. Cloud serving cluster • No downtime for users • No NRT expense • Linear scale out to the size of your MR cluster •
Cloudera Morphlines Open Source framework for simple ETL • Simplify ETL • Built-in commands and library support (Avro format, Hadoop Sequence. Files, grok for syslog messages) • Configuration over coding • Standardize ETL • Ships as part Cloudera Developer Kit (CDK) • It’s a Java library • AL 2 licensed on github https: //github. com/cloudera/cdk •
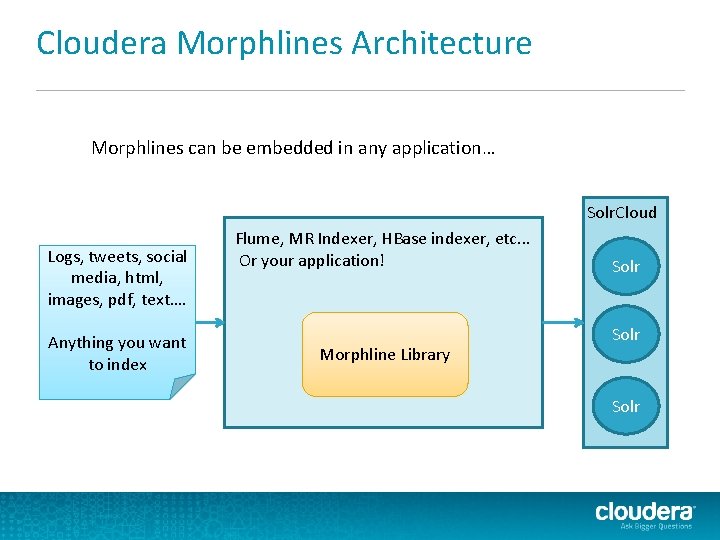
Cloudera Morphlines Architecture Morphlines can be embedded in any application… Solr. Cloud Logs, tweets, social media, html, images, pdf, text…. Anything you want to index Flume, MR Indexer, HBase indexer, etc. . . Or your application! Morphline Library Solr
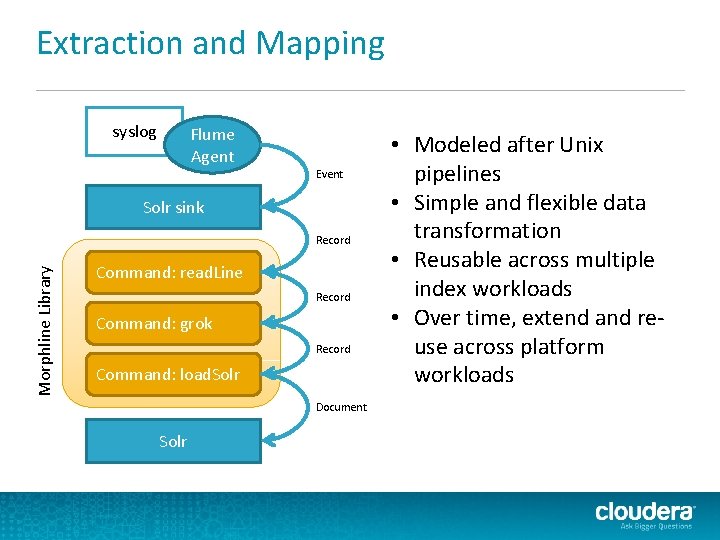
Extraction and Mapping syslog Flume Agent Event Solr sink Morphline Library Record Command: read. Line Record Command: grok Record Command: load. Solr Document Solr • Modeled after Unix pipelines • Simple and flexible data transformation • Reusable across multiple index workloads • Over time, extend and reuse across platform workloads
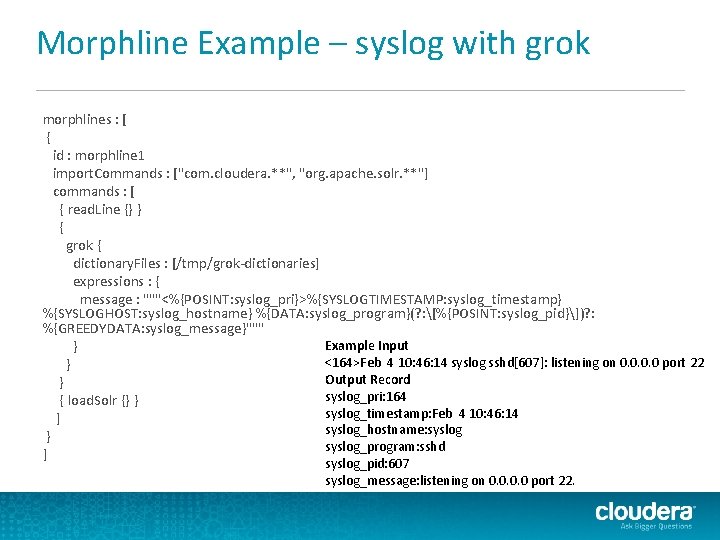
Morphline Example – syslog with grok morphlines : [ { id : morphline 1 import. Commands : ["com. cloudera. **", "org. apache. solr. **"] commands : [ { read. Line {} } { grok { dictionary. Files : [/tmp/grok-dictionaries] expressions : { message : """<%{POSINT: syslog_pri}>%{SYSLOGTIMESTAMP: syslog_timestamp} %{SYSLOGHOST: syslog_hostname} %{DATA: syslog_program}(? : [%{POSINT: syslog_pid}])? : %{GREEDYDATA: syslog_message}""" Example Input } <164>Feb 4 10: 46: 14 syslog sshd[607]: listening on 0. 0 port 22 } Output Record } syslog_pri: 164 { load. Solr {} } syslog_timestamp: Feb 4 10: 46: 14 ] syslog_hostname: syslog } syslog_program: sshd ] syslog_pid: 607 syslog_message: listening on 0. 0 port 22.
Current Command Library • • Integrate with and load into Apache Solr Flexible log file analysis Single-line record, multi-line records, CSV files Regex based pattern matching and extraction Integration with Avro Integration with Apache Hadoop Sequence Files Integration with Solr. Cell and all Apache Tika parsers Auto-detection of MIME types from binary data using Apache Tika
Current Command Library (cont) • • • Scripting support for dynamic java code Operations on fields for assignment and comparison Operations on fields with list and set semantics if-then-else conditionals A small rules engine (try. Rules) String and timestamp conversions slf 4 j logging Yammer metrics and counters Decompression and unpacking of arbitrarily nested container file formats Etc…
Querying Built-in solr web UI • Write your own • Hue •
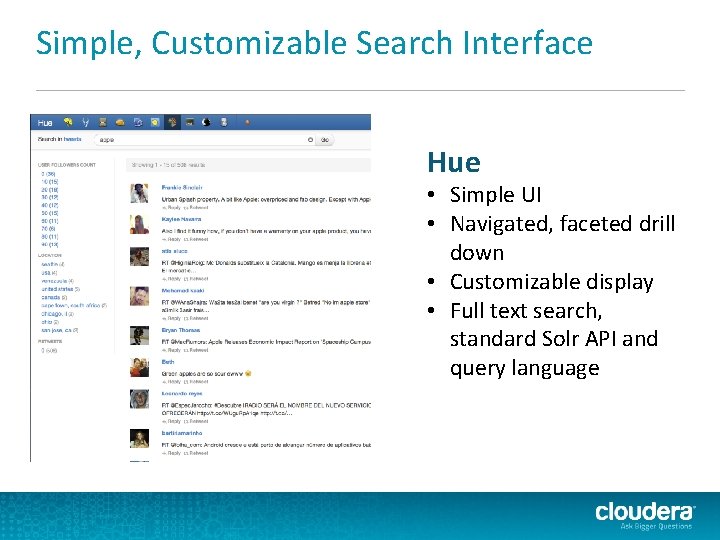
Simple, Customizable Search Interface Hue • Simple UI • Navigated, faceted drill down • Customizable display • Full text search, standard Solr API and query language
Security Upstream Solr doesn’t really deal with security • Search 1. 0 supports kerberos authentication • • Similar to Oozie / Web. HDFS Actively working on Index-level authorization using Apache Sentry • Future: more granular authorization •
Conclusion • Cloudera Search now Generally Available (1. 0) Free Download • Extensive documentation • Send your questions and feedback to searchuser@cloudera. org • Take the Search online training • • Cloudera Manager Standard (i. e. the free version) Simple management of Search • Free Download • • Quick. Start VM also available!