Chemoinformatics 2017 David Chalmers Section 1 Chemical data
- Slides: 53
Chemoinformatics 2017 David Chalmers
Section 1: Chemical data
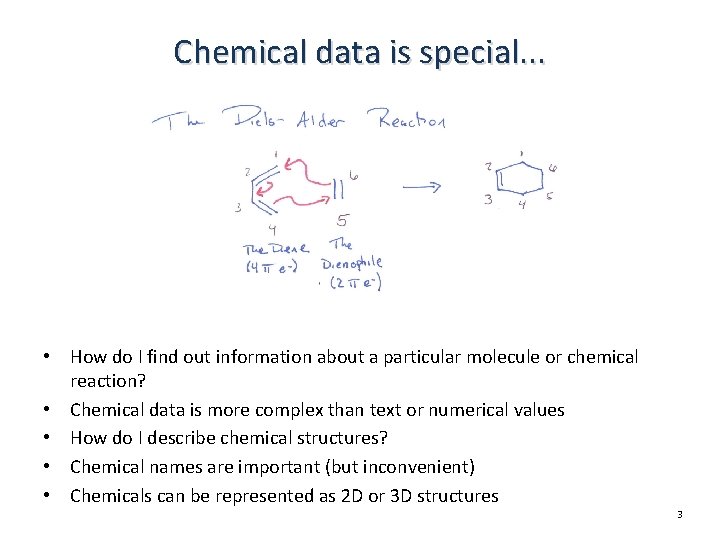
Chemical data is special. . . • How do I find out information about a particular molecule or chemical reaction? • Chemical data is more complex than text or numerical values • How do I describe chemical structures? • Chemical names are important (but inconvenient) • Chemicals can be represented as 2 D or 3 D structures 3
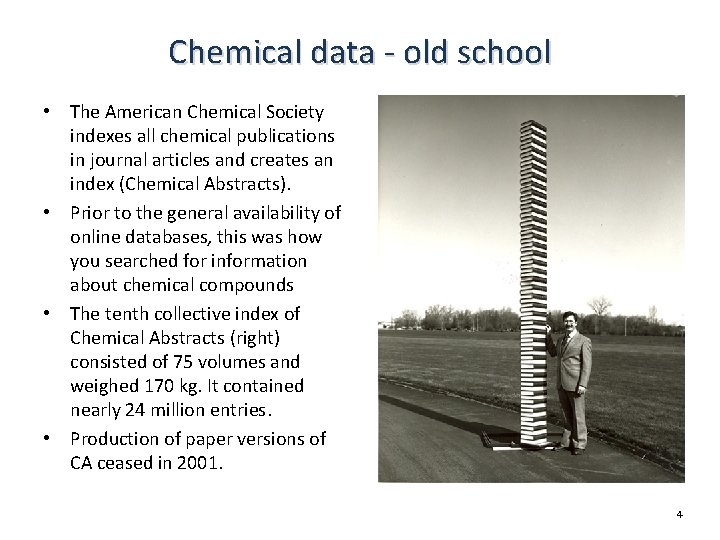
Chemical data - old school • The American Chemical Society indexes all chemical publications in journal articles and creates an index (Chemical Abstracts). • Prior to the general availability of online databases, this was how you searched for information about chemical compounds • The tenth collective index of Chemical Abstracts (right) consisted of 75 volumes and weighed 170 kg. It contained nearly 24 million entries. • Production of paper versions of CA ceased in 2001. 4
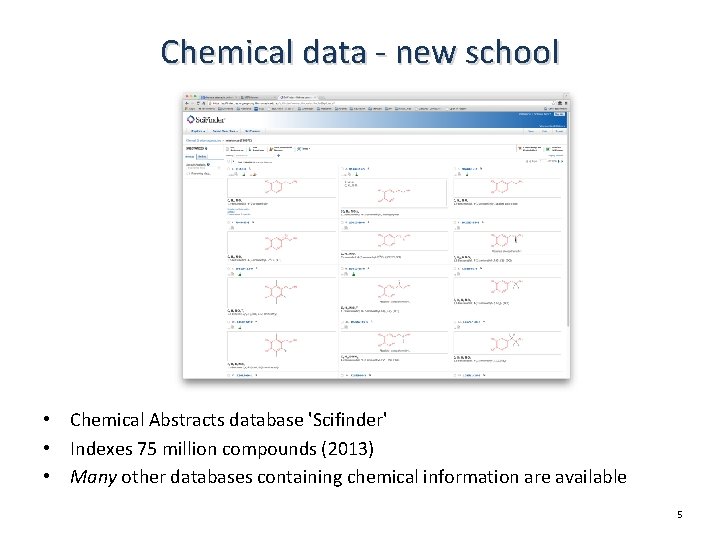
Chemical data - new school • Chemical Abstracts database 'Scifinder' • Indexes 75 million compounds (2013) • Many other databases containing chemical information are available 5
How do we represent molecules in a computer? We can store a wide range of information about each molecule Information about the whole molecule: • molecule name • journal article (for crystal structures) • creator or author(s) Information about each atom: • atomic element (H, He, C, N, O, F, etc. ) • atom name (E. g. in an amino acid N, CA, CB, CO O, etc. ) • Coordinates in Cartesian format 2 D (X, Y) or 3 D (X, Y, Z) or Z-matrix format • Atom charge (formal and/or partial) • residue name (E. g. for a protein: Ala, Pro, etc. ) • temperature factor and occupancy for crystal structures Bonding information: • usually stored as a connection table which describes which atoms are bonded together. • information about bond-orders (single, double, aromatic, etc. ) is important, but it is not always stored in some file formats (E. g. pdb) 6
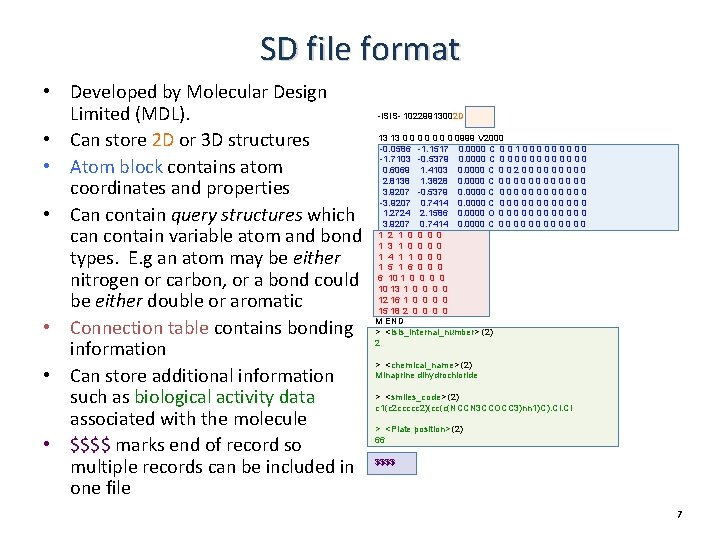
SD file format • Developed by Molecular Design Limited (MDL). • Can store 2 D or 3 D structures • Atom block contains atom coordinates and properties • Can contain query structures which can contain variable atom and bond types. E. g an atom may be either nitrogen or carbon, or a bond could be either double or aromatic • Connection table contains bonding information • Can store additional information such as biological activity data associated with the molecule • $$$$ marks end of record so multiple records can be included in one file -ISIS- 10229913002 D 13 13 0 0 0 0999 V 2000 -0. 0586 -1. 1517 0. 0000 C 0 0 1 0 0 0 0 0 -1. 7103 -0. 5379 0. 0000 C 0 0 0 0. 6069 1. 4103 0. 0000 C 0 0 2 0 0 0 0 0 2. 8138 1. 3828 0. 0000 C 0 0 0 3. 9207 -0. 5379 0. 0000 C 0 0 0 -3. 9207 0. 7414 0. 0000 C 0 0 0 1. 2724 2. 1586 0. 0000 O 0 0 0 3. 9207 0. 7414 0. 0000 C 0 0 0 1 2 1 0 0 1 3 1 0 0 1 4 1 1 0 0 0 1 5 1 6 0 0 0 6 10 1 0 0 10 13 1 0 0 12 16 1 0 0 15 18 2 0 0 M END > <Isis_internal_number> (2) 2 > <chemical_name> (2) Minaprine dihydrochloride > <smiles_code> (2) c 1(c 2 ccccc 2)(cc(c(NCCN 3 CCOCC 3)nn 1)C). Cl > <Plate position> (2) 66 $$$$ 7
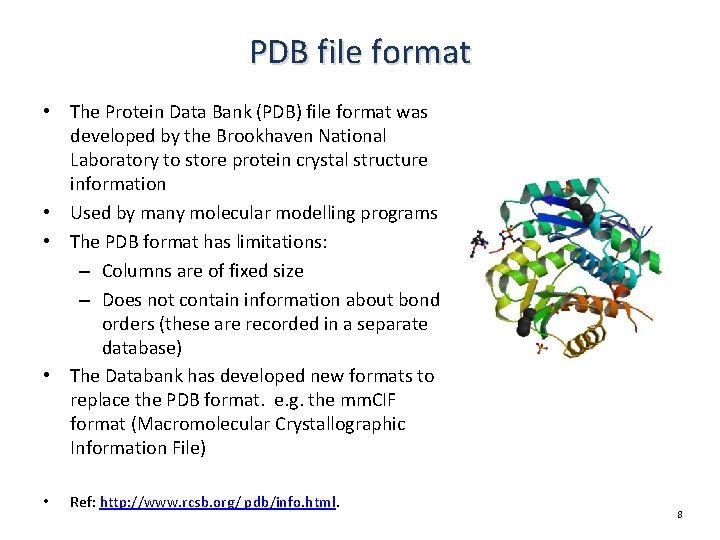
PDB file format • The Protein Data Bank (PDB) file format was developed by the Brookhaven National Laboratory to store protein crystal structure information • Used by many molecular modelling programs • The PDB format has limitations: – Columns are of fixed size – Does not contain information about bond orders (these are recorded in a separate database) • The Databank has developed new formats to replace the PDB format. e. g. the mm. CIF format (Macromolecular Crystallographic Information File) • Ref: http: //www. rcsb. org/ pdb/info. html. 8
Section 2: Line notations
Chemical Line Notations • Representations of molecules that fit on a single line. E. g. standard structural formulas. These work well for linear compounds, but less well for rings… CH 3 CH 2 COOH Line notations are: • Compact • Generally human readable/understandable • Use little computer storage 10
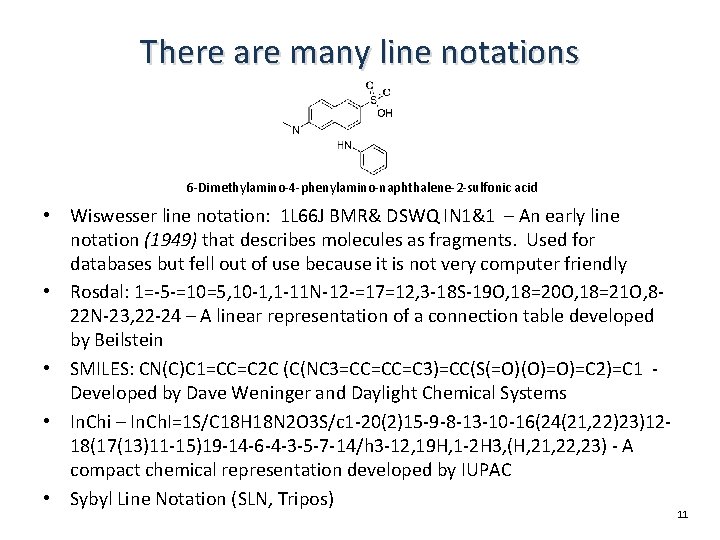
There are many line notations 6 -Dimethylamino-4 -phenylamino-naphthalene-2 -sulfonic acid • Wiswesser line notation: 1 L 66 J BMR& DSWQ IN 1&1 – An early line notation (1949) that describes molecules as fragments. Used for databases but fell out of use because it is not very computer friendly • Rosdal: 1=-5 -=10=5, 10 -1, 1 -11 N-12 -=17=12, 3 -18 S-19 O, 18=20 O, 18=21 O, 822 N-23, 22 -24 – A linear representation of a connection table developed by Beilstein • SMILES: CN(C)C 1=CC=C 2 C (C(NC 3=CC=CC=C 3)=CC(S(=O)(O)=O)=C 2)=C 1 Developed by Dave Weninger and Daylight Chemical Systems • In. Chi – In. Ch. I=1 S/C 18 H 18 N 2 O 3 S/c 1 -20(2)15 -9 -8 -13 -10 -16(24(21, 22)23)1218(17(13)11 -15)19 -14 -6 -4 -3 -5 -7 -14/h 3 -12, 19 H, 1 -2 H 3, (H, 21, 22, 23) - A compact chemical representation developed by IUPAC • Sybyl Line Notation (SLN, Tripos) 11
SMILES • SMILES is the most widely used and most useful chemical line notation • Can be used as input/output in many programs • Simple SMILES strings resemble standard chemical nomenclature. The atoms commonly found in organic molecules (B, C, N, O, P, S, F, Cl, Br, I) are represented by the atomic element symbol. • Single bonds are implied between each atom. • Hydrogen atoms are not usually shown (but can be included if necessary) 12
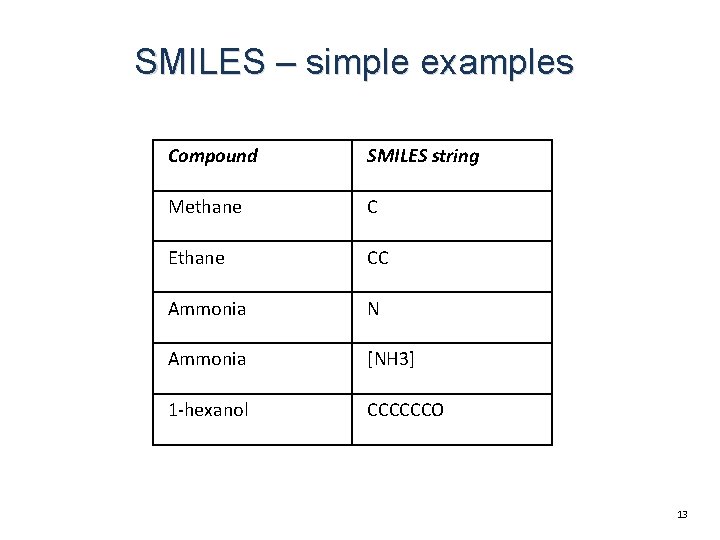
SMILES – simple examples Compound SMILES string Methane C Ethane CC Ammonia N Ammonia [NH 3] 1 -hexanol CCCCCCO 13
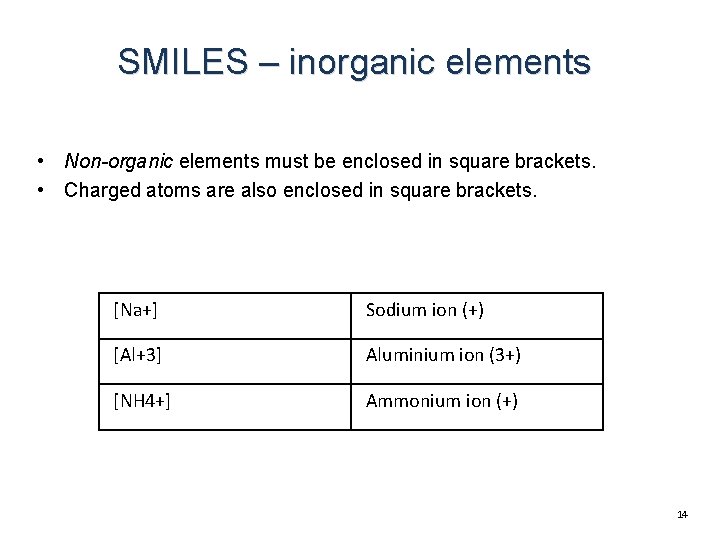
SMILES – inorganic elements • Non-organic elements must be enclosed in square brackets. • Charged atoms are also enclosed in square brackets. [Na+] Sodium ion (+) [Al+3] Aluminium ion (3+) [NH 4+] Ammonium ion (+) 14
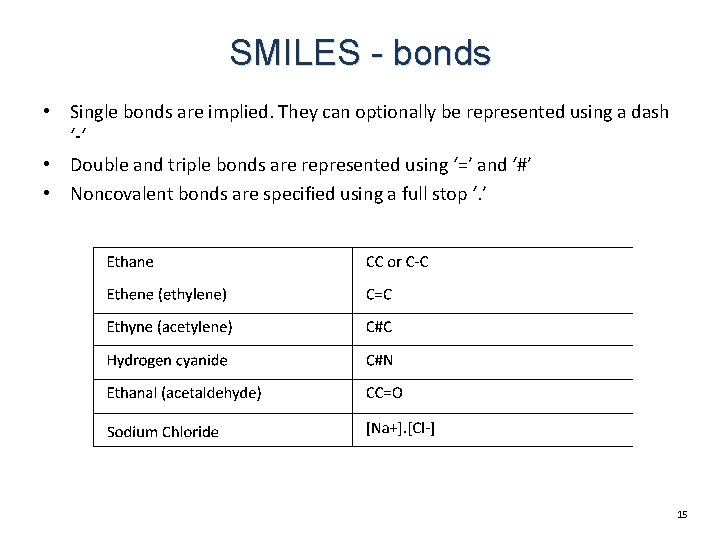
SMILES - bonds • Single bonds are implied. They can optionally be represented using a dash ‘-‘ • Double and triple bonds are represented using ‘=’ and ‘#’ • Noncovalent bonds are specified using a full stop ‘. ’ 15
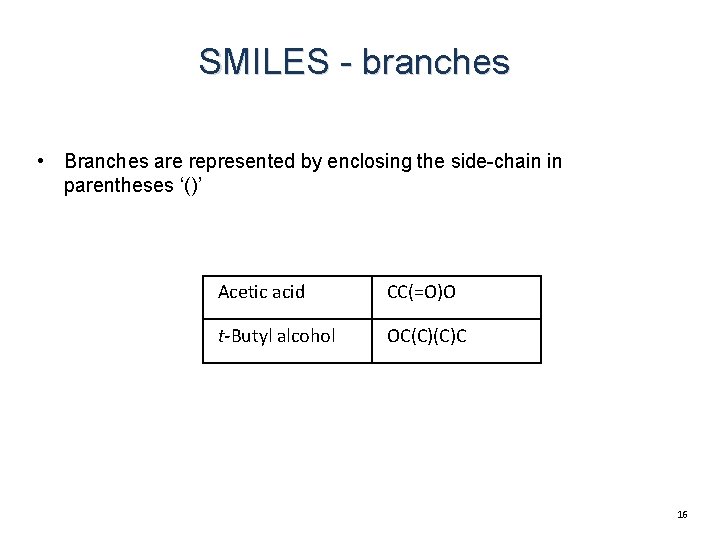
SMILES - branches • Branches are represented by enclosing the side-chain in parentheses ‘()’ Acetic acid CC(=O)O t-Butyl alcohol OC(C)(C)C 16
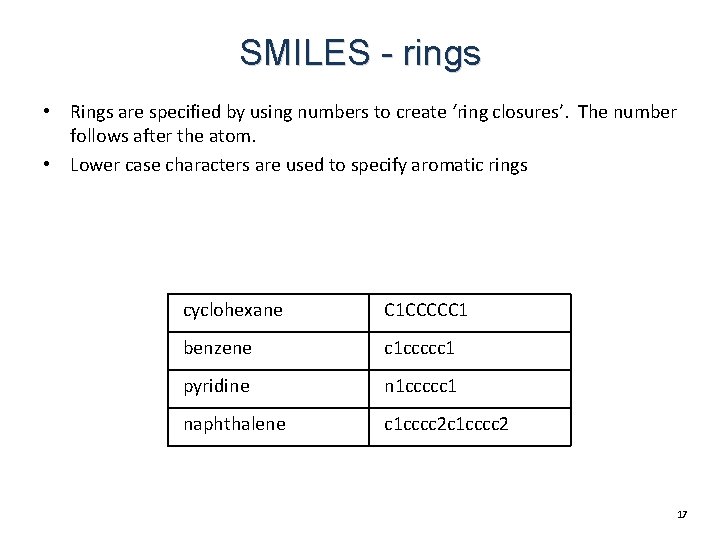
SMILES - rings • Rings are specified by using numbers to create ‘ring closures’. The number follows after the atom. • Lower case characters are used to specify aromatic rings cyclohexane C 1 CCCCC 1 benzene c 1 ccccc 1 pyridine n 1 ccccc 1 naphthalene c 1 cccc 2 17
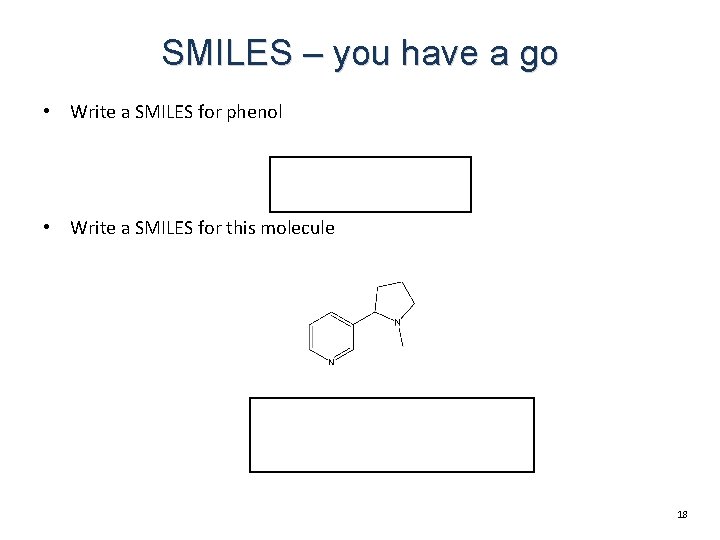
SMILES – you have a go • Write a SMILES for phenol Oc 1 ccccc 1 • Write a SMILES for this molecule CN 1 CCCC 1 c 2 cnccc 2 18
SMILES - Additional notations • SMILES contains additional features which can be used to describe chirality, double bond isomers (E, Z) and metal complexes. • More information about the SMILES notation is available at: http: //www. daylight. com/dayhtml_tutorials/languages/smiles/index. ht ml http: //www. daylight. com/dayhtml/doc/theory. smiles. html#RTFT o. CX 1 19
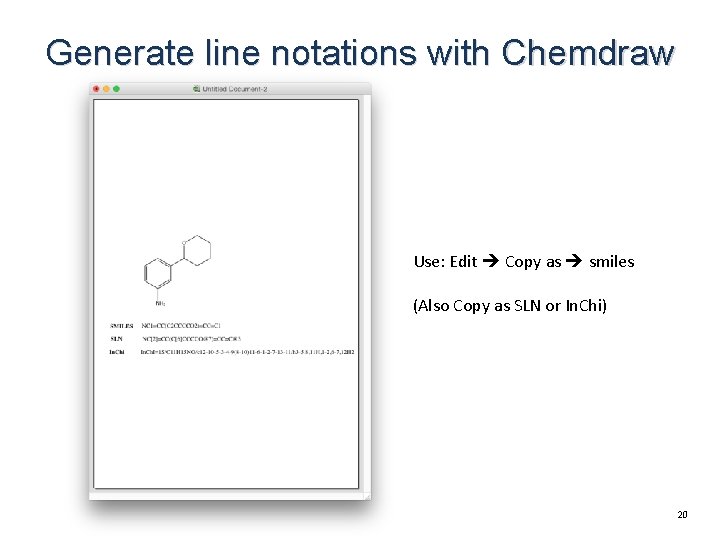
Generate line notations with Chemdraw Use: Edit Copy as smiles (Also Copy as SLN or In. Chi) 20
Section 3: Chemical databases
Chemical Databases • Chemical databases are important in all stages of medicinal chemistry • Databases may contain: – Chemical structure, reaction and synthetic data (e. g. Chemical Abstracts, Reaxxys, the Merck Index) – Compound structure and synthesis information (e. g. An inhouse compound registry) – Biological activity data such as inhouse testing data or MDL Drug Data Report (MDDR) CAS registers 89 million compounds and 39 million patent and journal articles 22
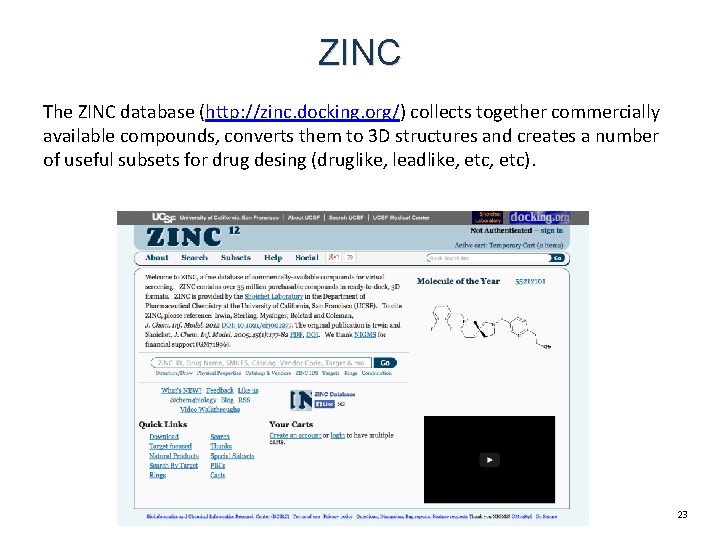
ZINC The ZINC database (http: //zinc. docking. org/) collects together commercially available compounds, converts them to 3 D structures and creates a number of useful subsets for drug desing (druglike, leadlike, etc). 23
Searching chemical databases • The important distinction between chemical database software and other database programs used for holding text or images is that a chemical database must be able to interpret chemical structures • In a chemical database it is desirable to be able to search for: – Exact compound structures – Compounds containing a particular substructure – Compounds similar to a given structure • In some cases we wish to search for chemical features in 3 D (pharmacophores) 24
Section 4: Similarity and similarity comparisons
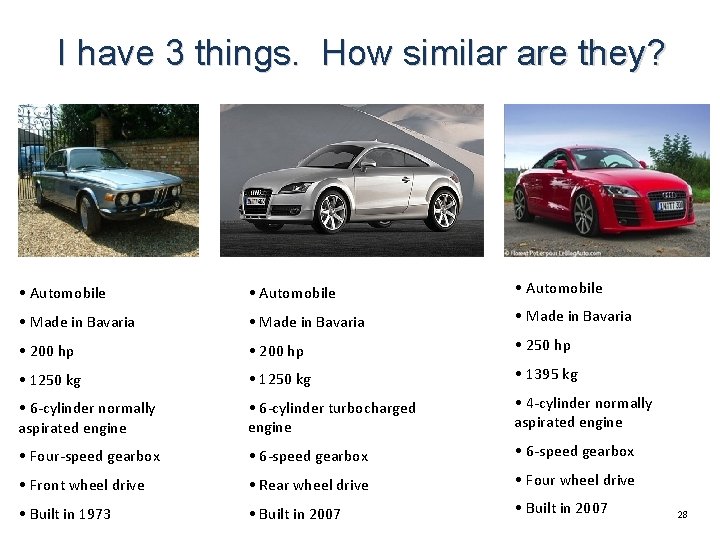
I have 3 things. How similar are they? • Automobile • Made in Bavaria • 200 hp • 250 hp • 1250 kg • 1395 kg • 6 -cylinder normally aspirated engine • 6 -cylinder turbocharged engine • 4 -cylinder normally aspirated engine • Four-speed gearbox • 6 -speed gearbox • Front wheel drive • Rear wheel drive • Four wheel drive • Built in 1973 • Built in 2007 28
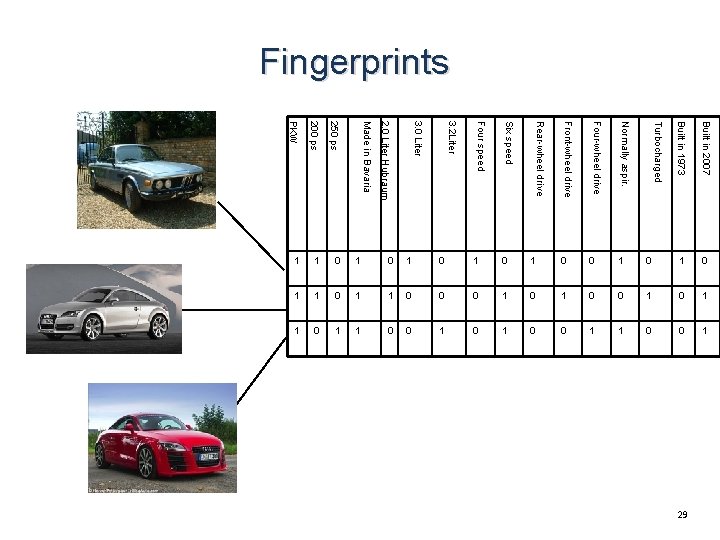
Fingerprints 200 ps 250 ps Four speed Six speed Front-wheel drive Four-wheel drive Normally aspir. Built in 1973 Built in 2007 1 0 1 0 1 0 1 1 0 0 0 1 0 1 1 0 0 1 1 0 0 1 Made in Bavaria 2, 0 Liter Hubraum 3. 0 Liter 3. 2 Liter Rear-wheel drive Turbocharged PKW 1 29
Molecular comparison using molecular features or fragments • Comparison of molecular structures is straightforward for a chemist but is more difficult for a computer • The simplest approach is to compare every atom in one molecule to every atom in a second molecule. This is slow (particularly if we wish to search a database containing thousands or even millions of entries) • We therefore need a quick way (even approximate) way to compare two molecules • Solution: Break each molecule down into smaller pieces (features) and which allow a quick comparison between molecules 30
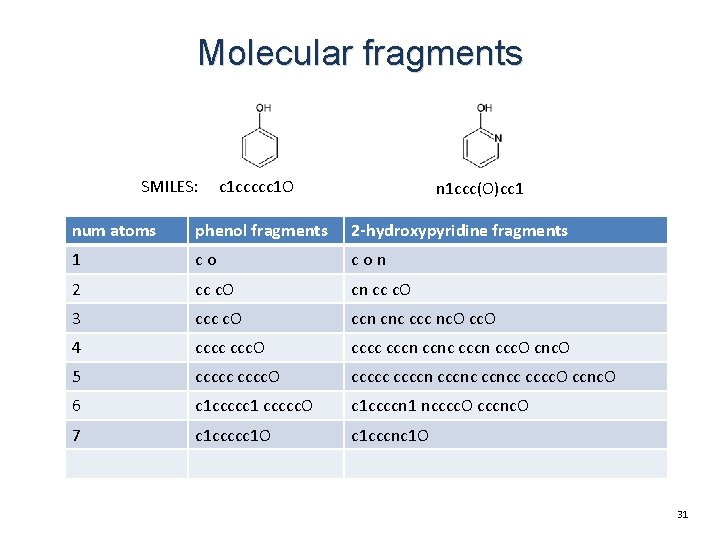
Molecular fragments SMILES: c 1 ccccc 1 O n 1 ccc(O)cc 1 num atoms phenol fragments 2 -hydroxypyridine fragments 1 co con 2 cc c. O cn cc c. O 3 ccc c. O ccn cnc ccc nc. O cc. O 4 cccc ccc. O cccc cccn ccnc cccn ccc. O cnc. O 5 ccccc. O cccccn cccncc cccc. O ccnc. O 6 c 1 ccccc 1 ccccc. O c 1 ccccn 1 ncccc. O cccnc. O 7 c 1 ccccc 1 O c 1 cccnc 1 O 31
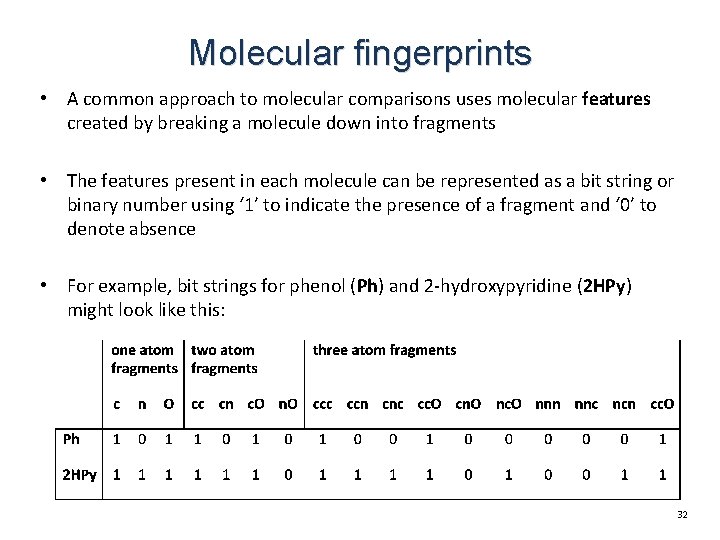
Molecular fingerprints • A common approach to molecular comparisons uses molecular features created by breaking a molecule down into fragments • The features present in each molecule can be represented as a bit string or binary number using ‘ 1’ to indicate the presence of a fragment and ‘ 0’ to denote absence • For example, bit strings for phenol (Ph) and 2 -hydroxypyridine (2 HPy) might look like this: 32
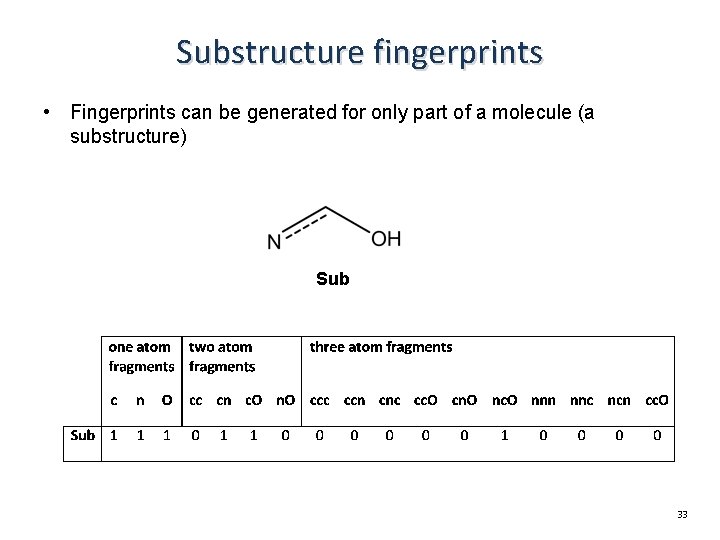
Substructure fingerprints • Fingerprints can be generated for only part of a molecule (a substructure) Sub 33
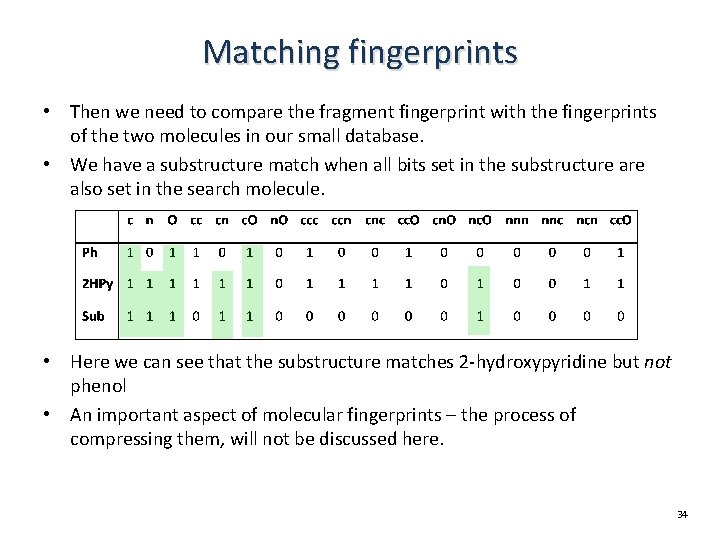
Matching fingerprints • Then we need to compare the fragment fingerprint with the fingerprints of the two molecules in our small database. • We have a substructure match when all bits set in the substructure also set in the search molecule. • Here we can see that the substructure matches 2 -hydroxypyridine but not phenol • An important aspect of molecular fingerprints – the process of compressing them, will not be discussed here. 34
Molecular fingerprints • These bit strings only contain fragments up to three atoms in size. In principal you can include any size fragments • A typical case is keys used by the organisation MDL. – For structure searching they have a set of 166 keys – For similarity searching a set of 960 keys is used • Advantages: – Fingerprints comparison uses Boolean arithmetic (AND, OR, NOT) which is very fast – Two identical molecules will have the same fingerprint regardless of orientation 35
Chemical Diversity and Similarity • Molecular similarity (or dissimilarity) means different things in different contexts. What molecular properties do we wish to compare? • Common structures – Common scaffolds – Common functional groups • Common physicochemical properties • Etc. 36
Chemical Diversity and Similarity • It is often useful to be able to find molecules that are similar or dissimilar in some respects. • Two important applications are: – Lead hopping – the idea of finding lead molecules with similar biological activity to a known compound, but with a fundamentally different chemical structure – Generating structurally diverse screening libraries – we usually wish to make efficient use of HTS screening and make sure that we are not testing large numbers of very similar compounds (e. g. compounds substituted with different halogens: F, Cl, Br, etc) 37
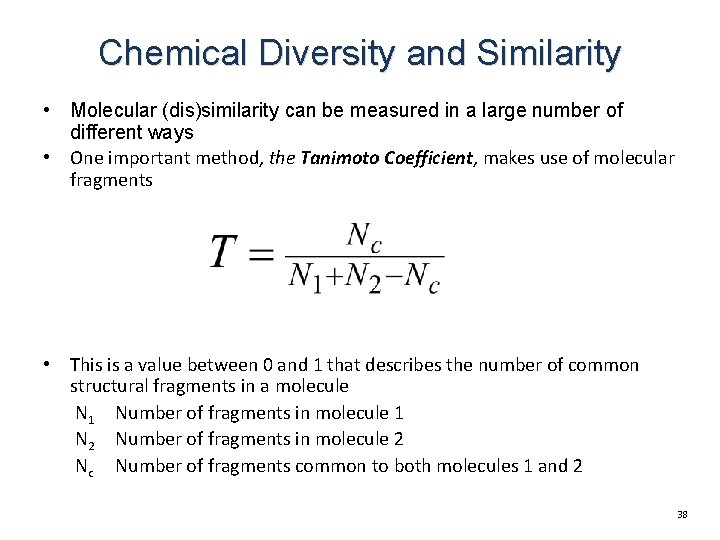
Chemical Diversity and Similarity • Molecular (dis)similarity can be measured in a large number of different ways • One important method, the Tanimoto Coefficient, makes use of molecular fragments • This is a value between 0 and 1 that describes the number of common structural fragments in a molecule N 1 Number of fragments in molecule 1 N 2 Number of fragments in molecule 2 Nc Number of fragments common to both molecules 1 and 2 38
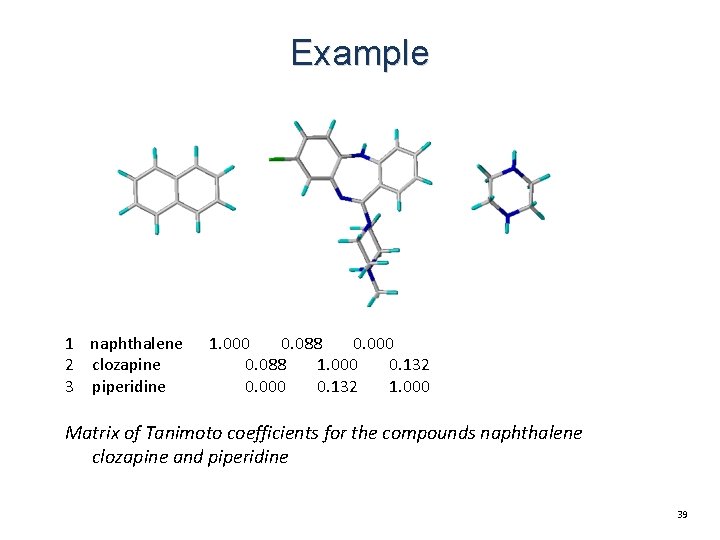
Example 1 naphthalene 2 clozapine 3 piperidine 1. 000 0. 088 0. 000 0. 088 1. 000 0. 132 0. 000 0. 132 1. 000 Matrix of Tanimoto coefficients for the compounds naphthalene clozapine and piperidine 39
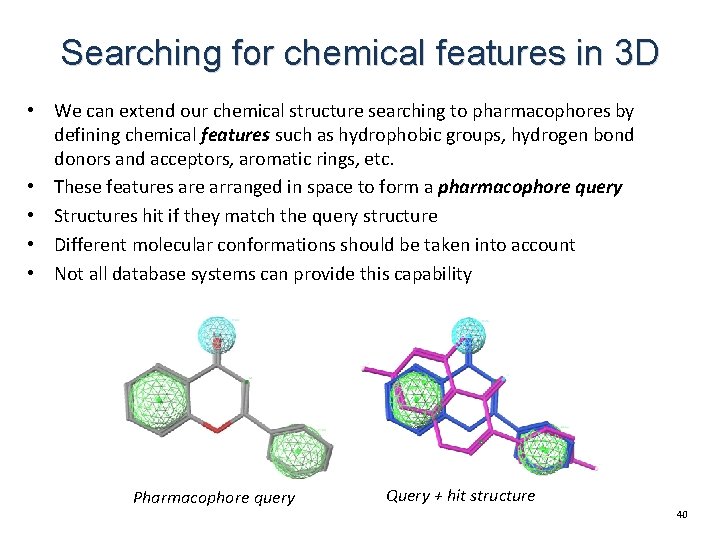
Searching for chemical features in 3 D • We can extend our chemical structure searching to pharmacophores by defining chemical features such as hydrophobic groups, hydrogen bond donors and acceptors, aromatic rings, etc. • These features are arranged in space to form a pharmacophore query • Structures hit if they match the query structure • Different molecular conformations should be taken into account • Not all database systems can provide this capability Pharmacophore query Query + hit structure 40
Section 5: Application of similarity searching
Lead or Scaffold Hopping • Ideas of molecular similarity are interesting to drug designers, because it provides a way to find molecules that are functionally similar to an active compound but might avoid other problems such as low activity, poor ADME properties or competitive patents ($$$$) • The idea of generating new biologically active molecules that contain an active pharmacophore but are built on a different molecular scaffold is known as lead hopping. This can be thought of jumping from one region of chemical space to another 42
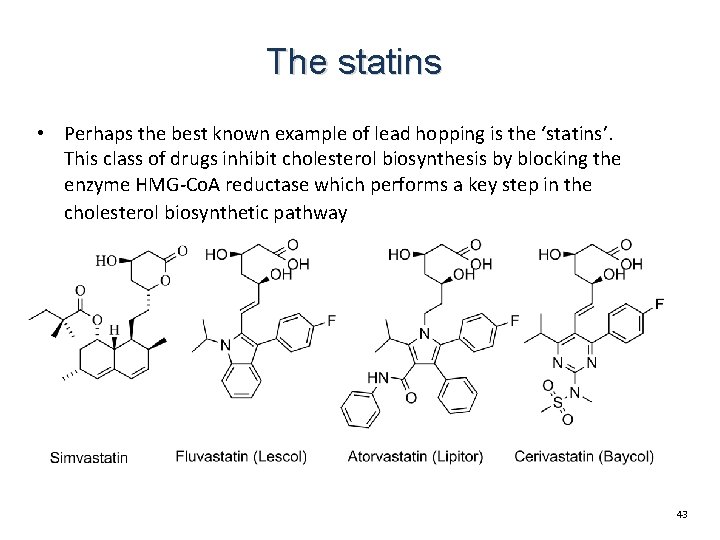
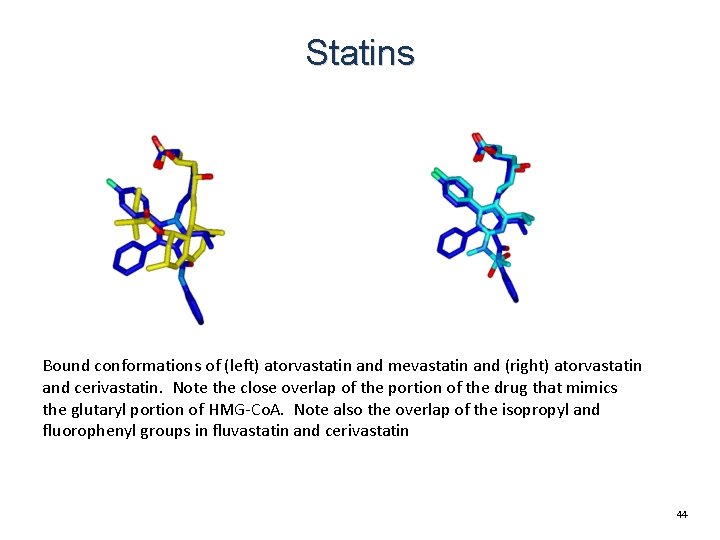
The statins • Perhaps the best known example of lead hopping is the ‘statins’. This class of drugs inhibit cholesterol biosynthesis by blocking the enzyme HMG-Co. A reductase which performs a key step in the cholesterol biosynthetic pathway 43
Statins Bound conformations of (left) atorvastatin and mevastatin and (right) atorvastatin and cerivastatin. Note the close overlap of the portion of the drug that mimics the glutaryl portion of HMG-Co. A. Note also the overlap of the isopropyl and fluorophenyl groups in fluvastatin and cerivastatin 44
Shape-based lead hopping • In another example, Rush et al. (J. Med. Chem. 2005, 48, 1489 -1495) describe using a shape based similarity method to identify a new class of antibacterial compounds • In this case, the target is the Zip. A-Fts. Z protein-protein interaction which has an essential role in the formation of the septal ring - a membraneassociated organelle that drives constriction and formation of new cell walls during cell division 45
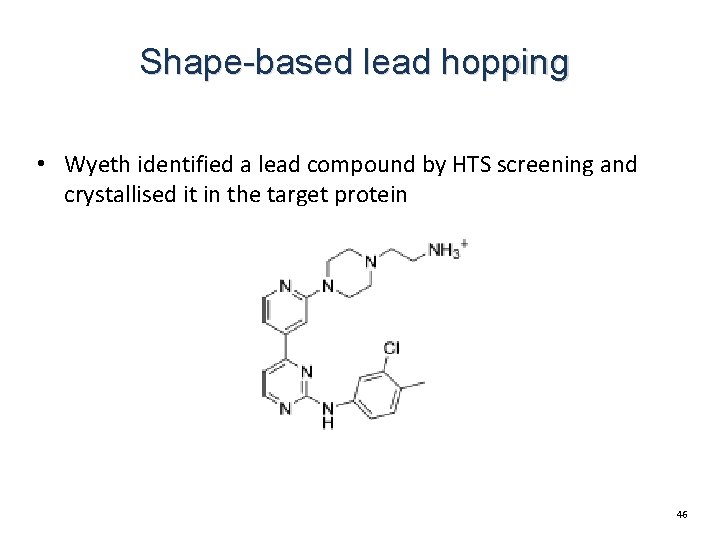
Shape-based lead hopping • Wyeth identified a lead compound by HTS screening and crystallised it in the target protein 46
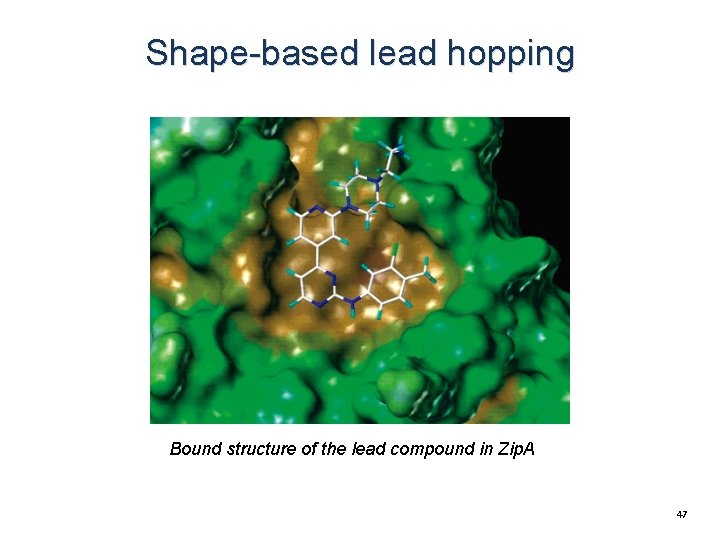
Shape-based lead hopping Bound structure of the lead compound in Zip. A 47
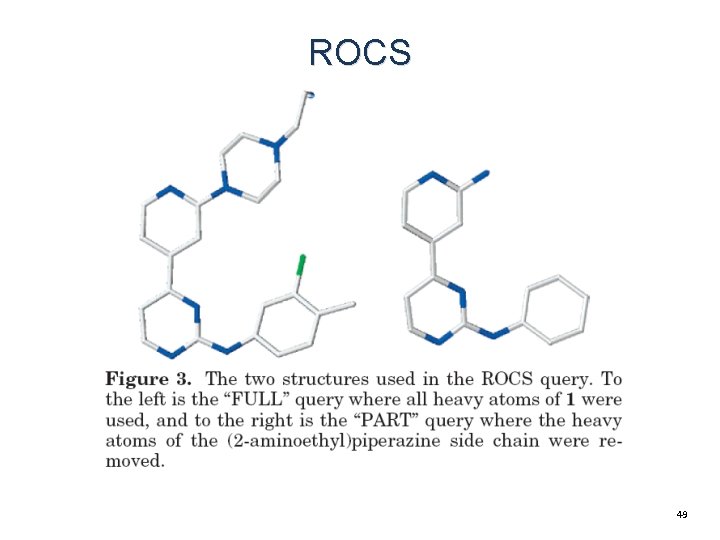
Shape-based lead hopping • The researchers then used a shape-based comparison (Rapid Overlay of Chemical Structures or ROCS) to find related compounds that were available for testing. • The comparison between the search structures and the query molecules used a Tanimoto comparison. 48
ROCS 49
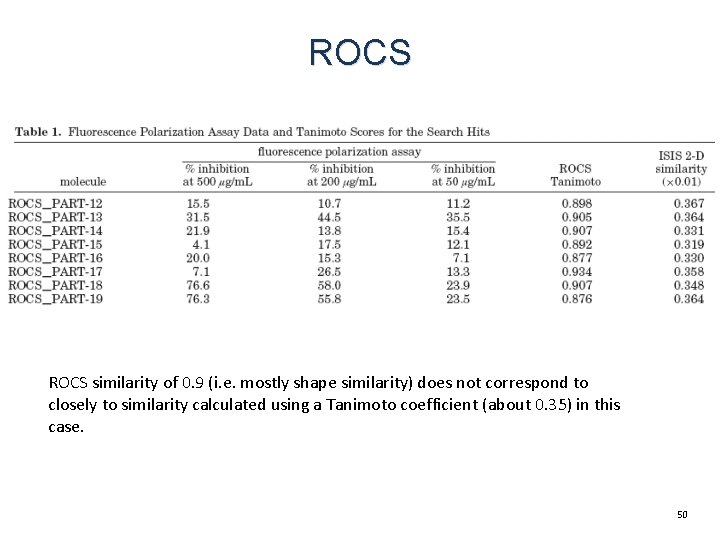
ROCS similarity of 0. 9 (i. e. mostly shape similarity) does not correspond to closely to similarity calculated using a Tanimoto coefficient (about 0. 35) in this case. 50
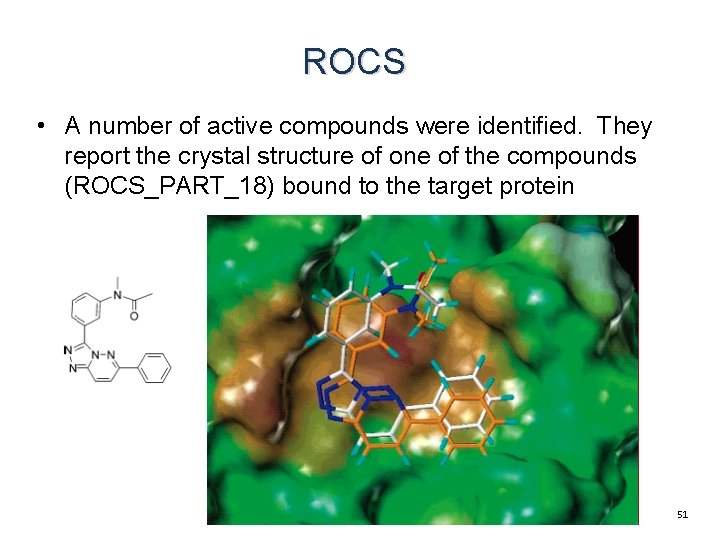
ROCS • A number of active compounds were identified. They report the crystal structure of one of the compounds (ROCS_PART_18) bound to the target protein 51
Key learning questions Chemical data • How does it differ from other types of data (e. g. text)? • How does this complicate finding information (searching)? • How do we store chemical data? Line notations • What is a line notation? Why might this be useful? • How does the SMILES line notation work? Chemical databases • Why might these be useful? Similarity • What is a fingerprint? • How can fingerprints or features be used to find similar things? • How can you use fingerprints to find substructures? • What is a Tanimoto coefficient? How would you use one? Lead hopping • Why do chemists care about this? • How can it help in a drug development program? 52
Good resources • SMILES: Daylight SMILES tutorial and theory http: //www. daylight. com/dayhtml_tutorials/languages/smiles/index. ht ml http: //www. daylight. com/dayhtml/doc/theory. smiles. html#RTFT o. CX 1