Lecture Slides for INTRODUCTION TO Machine Learning ETHEM
- Slides: 37
Lecture Slides for INTRODUCTION TO Machine Learning ETHEM ALPAYDIN © The MIT Press, 2004 alpaydin@boun. edu. tr http: //www. cmpe. boun. edu. tr/~ethem/i 2 ml Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
CHAPTER 11: Multilayer Perceptrons Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
Neural Networks n n n Networks of processing units (neurons) with connections (synapses) between them Large number of neurons: 1010 Large connectitivity: 105 Parallel processing Distributed computation/memory Robust to noise, failures 3 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
Understanding the Brain n Levels of analysis (Marr, 1982) Computational theory 2. Representation and algorithm 3. Hardware implementation 1. n n Reverse engineering: From hardware to theory Parallel processing: SIMD vs MIMD Neural net: SIMD with modifiable local memory Learning: Update by training/experience 4 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
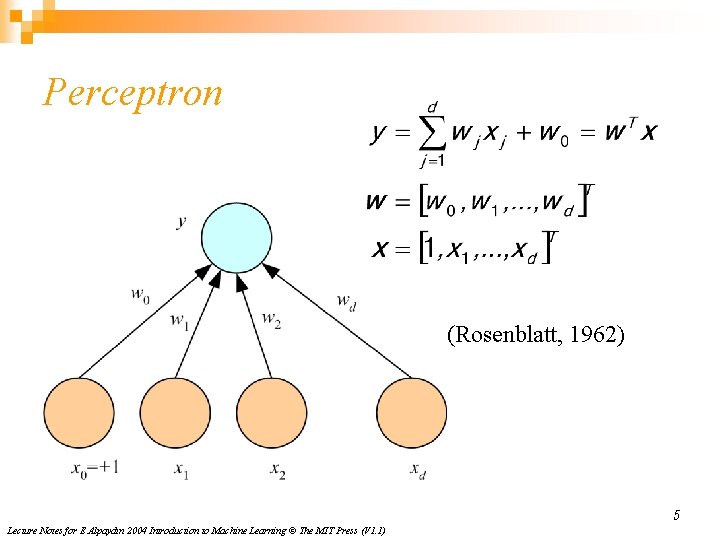
Perceptron (Rosenblatt, 1962) 5 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
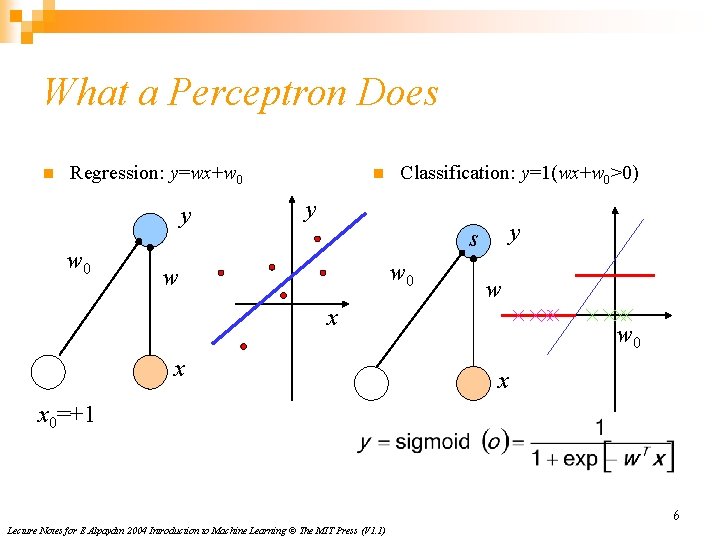
What a Perceptron Does n Regression: y=wx+w 0 y w 0 n Classification: y=1(wx+w 0>0) y y s w 0 w w x x w 0 x x 0=+1 6 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
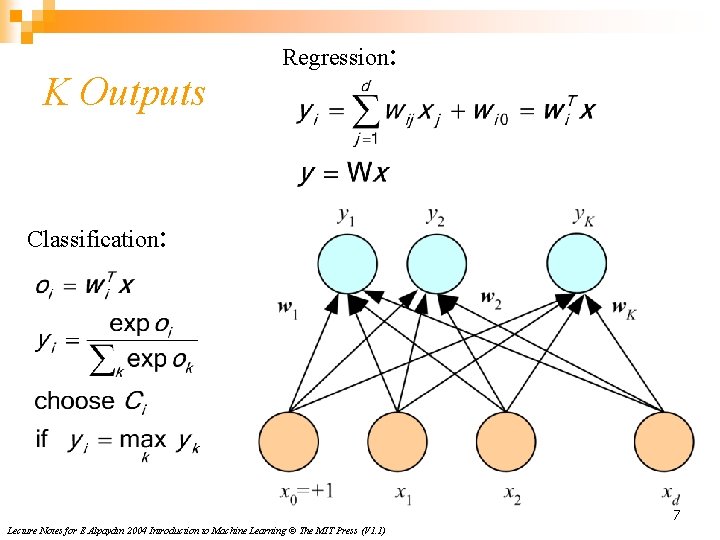
K Outputs Regression: Classification: 7 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
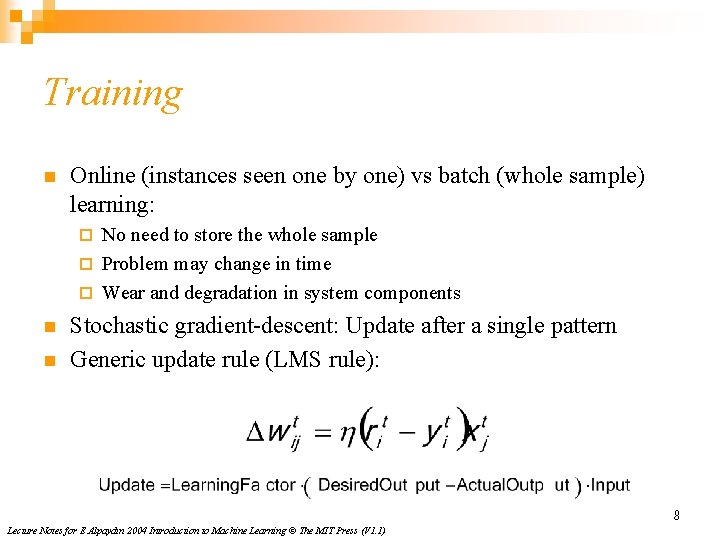
Training n Online (instances seen one by one) vs batch (whole sample) learning: No need to store the whole sample ¨ Problem may change in time ¨ Wear and degradation in system components ¨ n n Stochastic gradient-descent: Update after a single pattern Generic update rule (LMS rule): 8 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
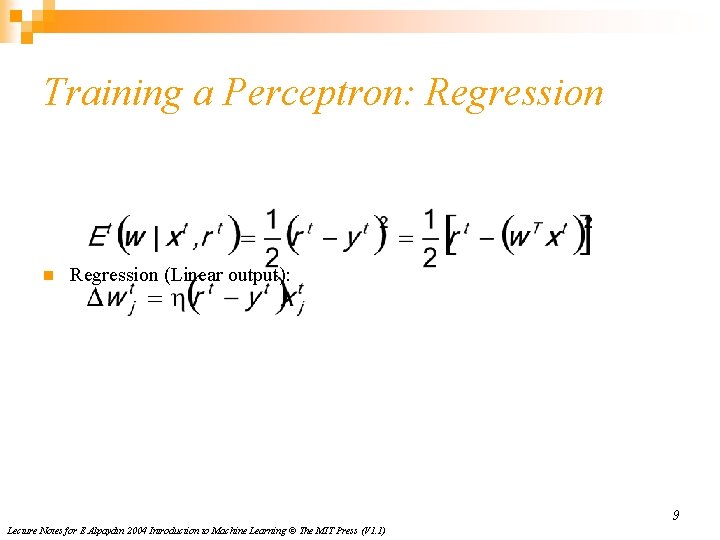
Training a Perceptron: Regression n Regression (Linear output): 9 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
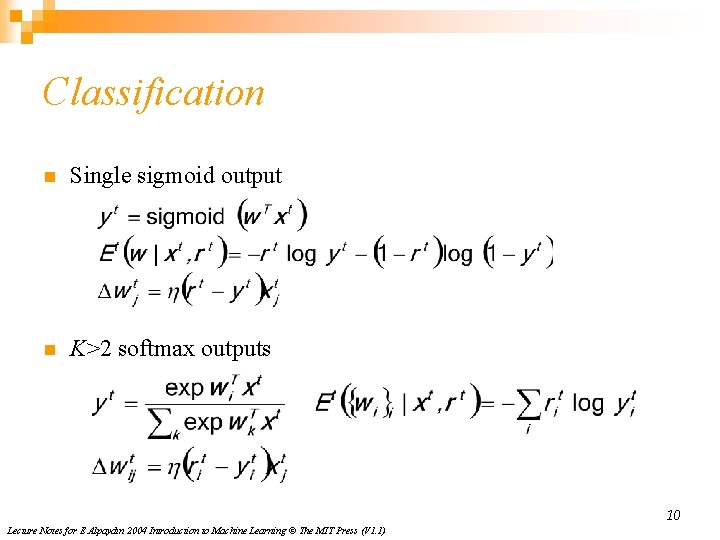
Classification n Single sigmoid output n K>2 softmax outputs 10 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
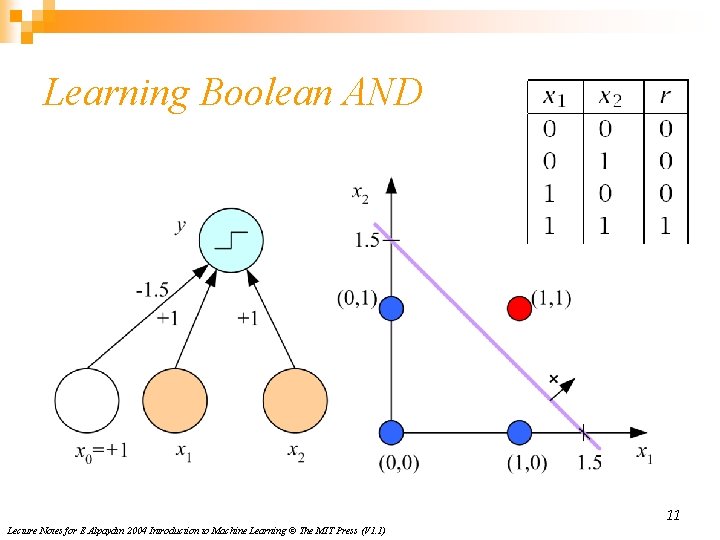
Learning Boolean AND 11 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
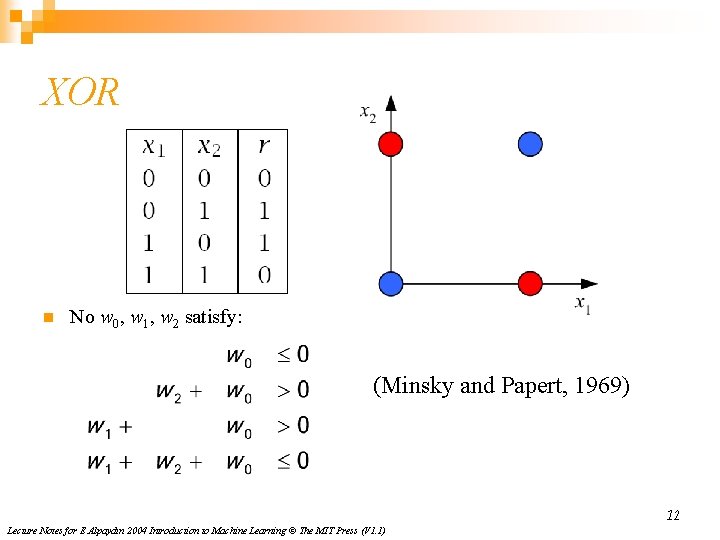
XOR n No w 0, w 1, w 2 satisfy: (Minsky and Papert, 1969) 12 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
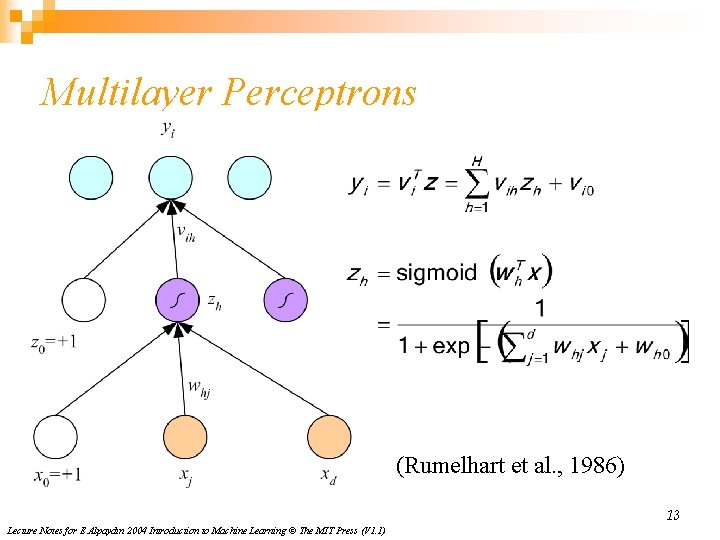
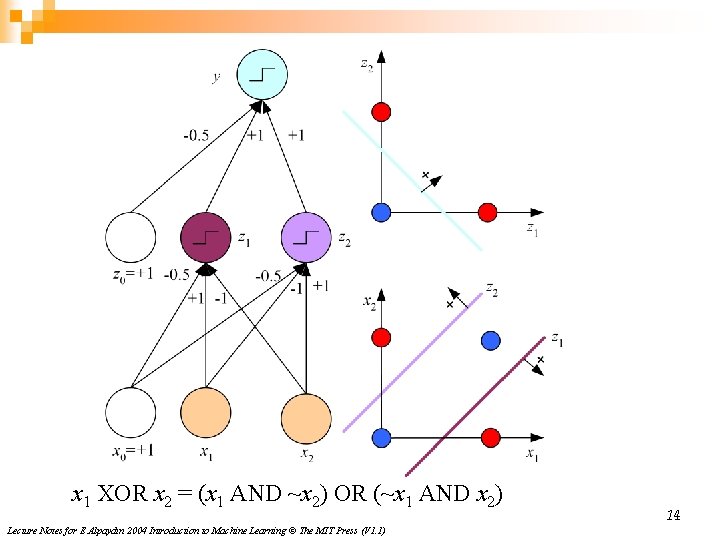
Multilayer Perceptrons (Rumelhart et al. , 1986) 13 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
x 1 XOR x 2 = (x 1 AND ~x 2) OR (~x 1 AND x 2) Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1) 14
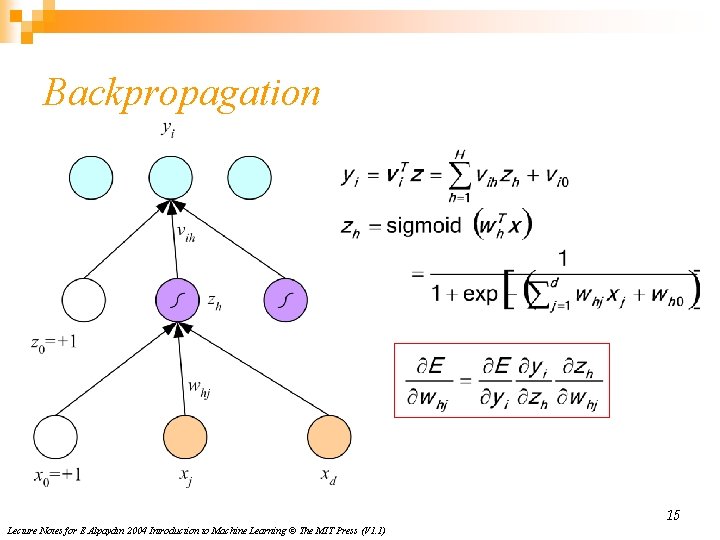
Backpropagation 15 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
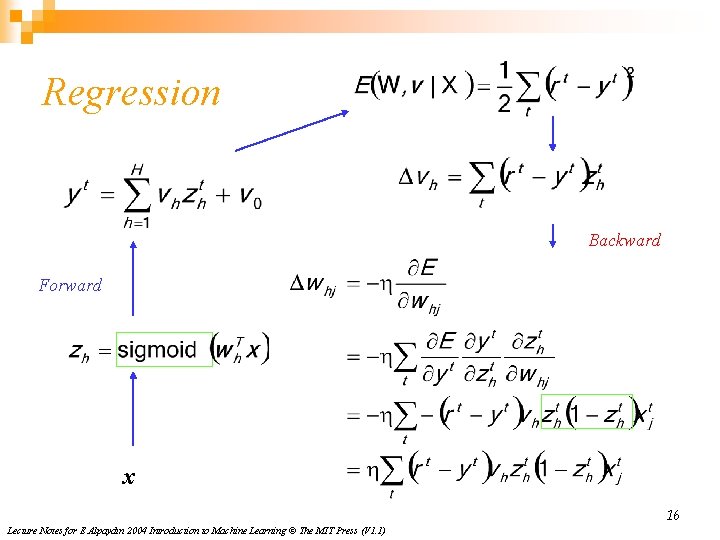
Regression Backward Forward x 16 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
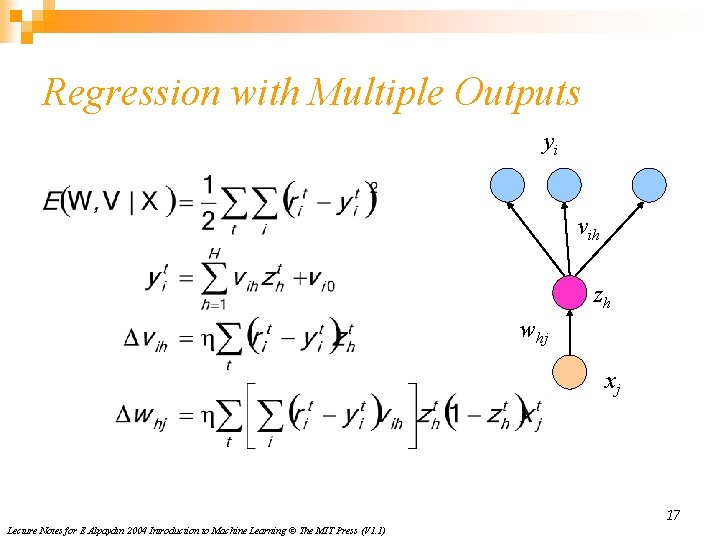
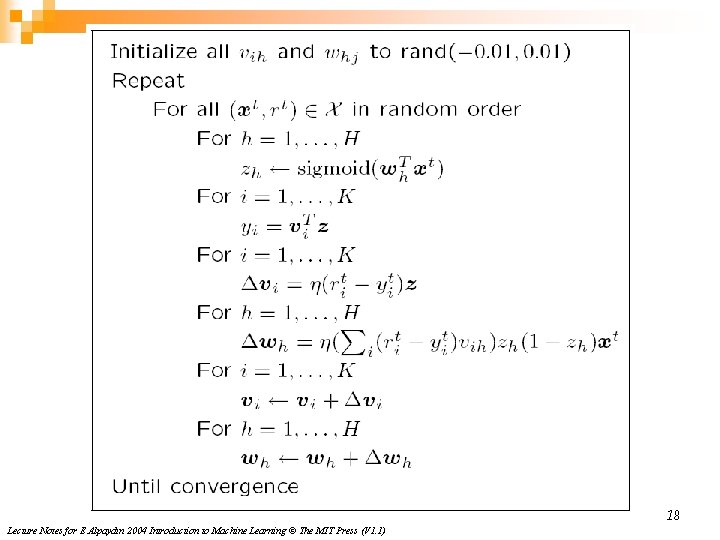
Regression with Multiple Outputs yi vih zh whj xj 17 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
18 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
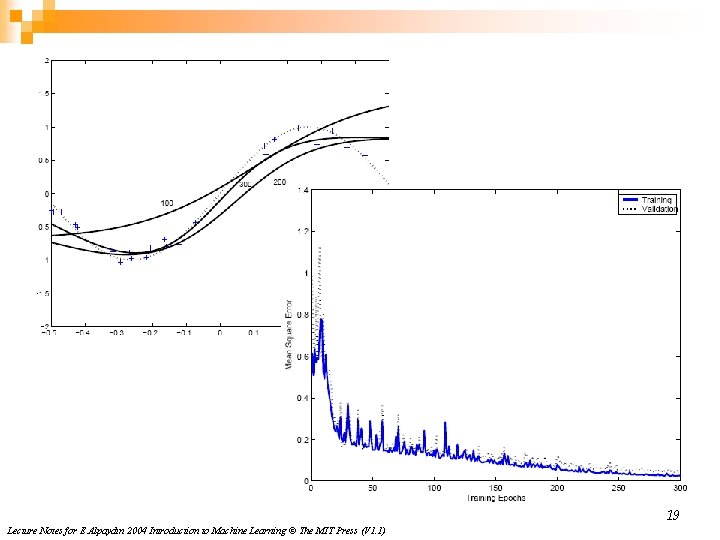
19 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
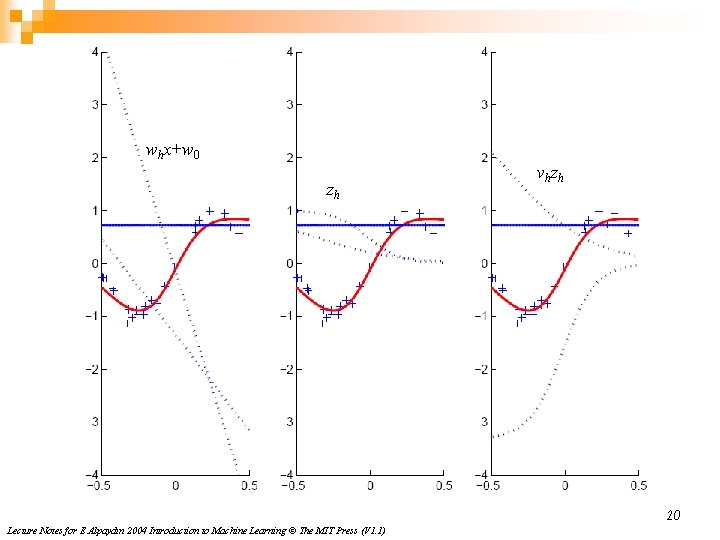
whx+w 0 zh v h zh 20 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
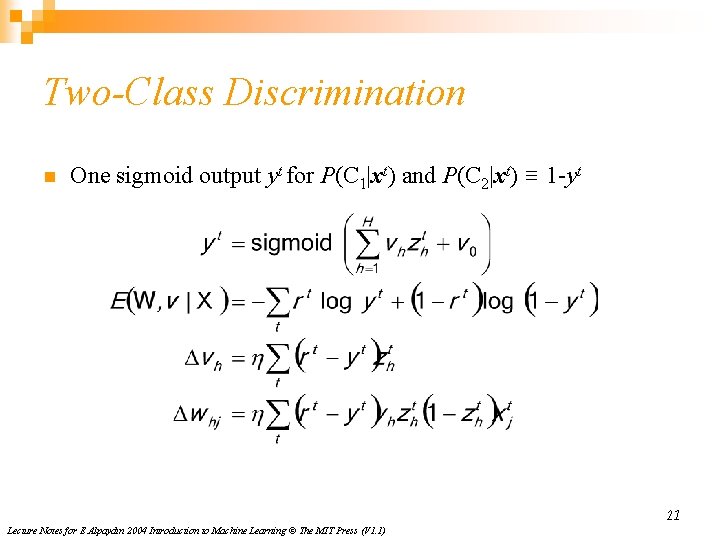
Two-Class Discrimination n One sigmoid output yt for P(C 1|xt) and P(C 2|xt) ≡ 1 -yt 21 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
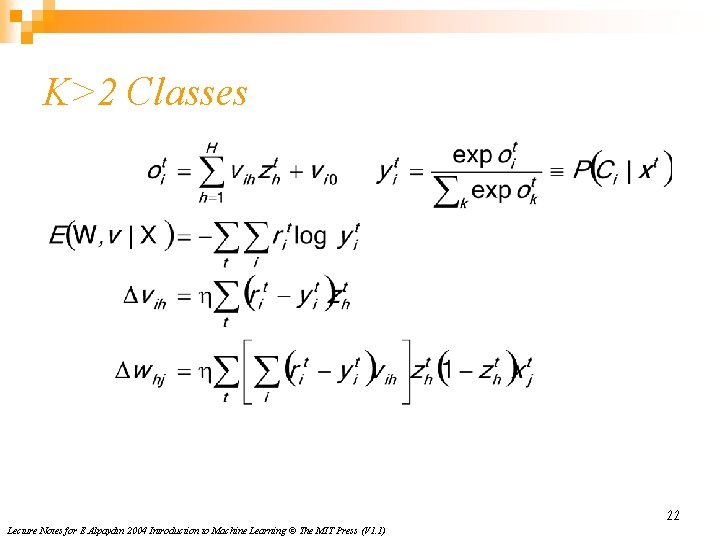
K>2 Classes 22 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
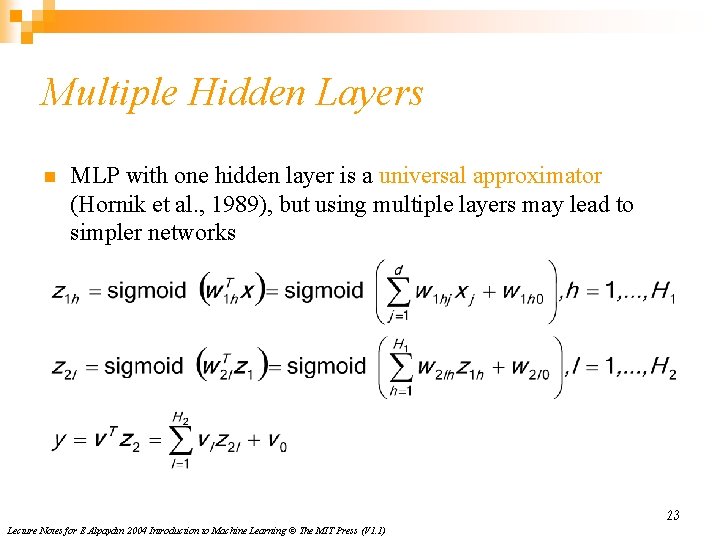
Multiple Hidden Layers n MLP with one hidden layer is a universal approximator (Hornik et al. , 1989), but using multiple layers may lead to simpler networks 23 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
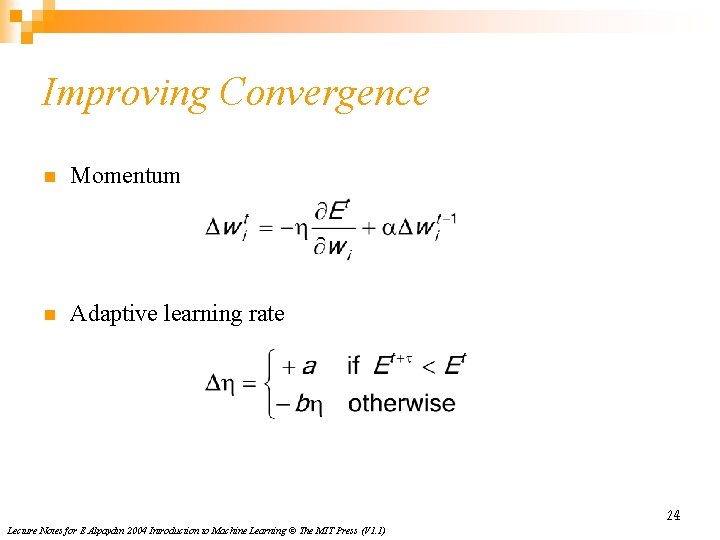
Improving Convergence n Momentum n Adaptive learning rate 24 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
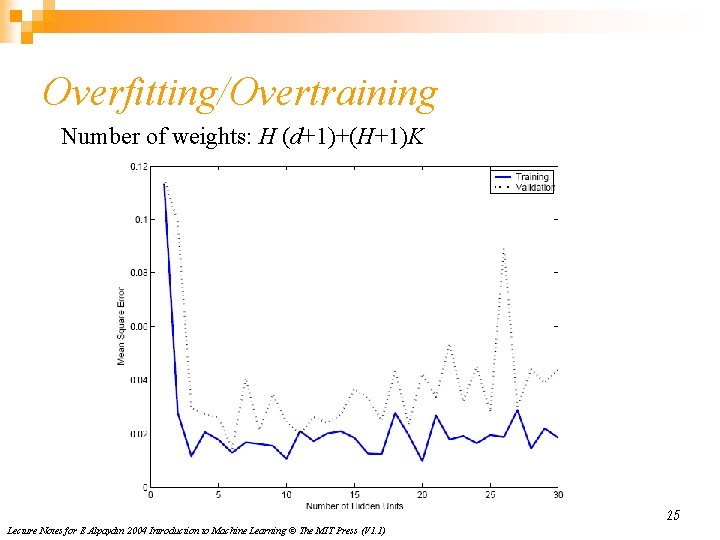
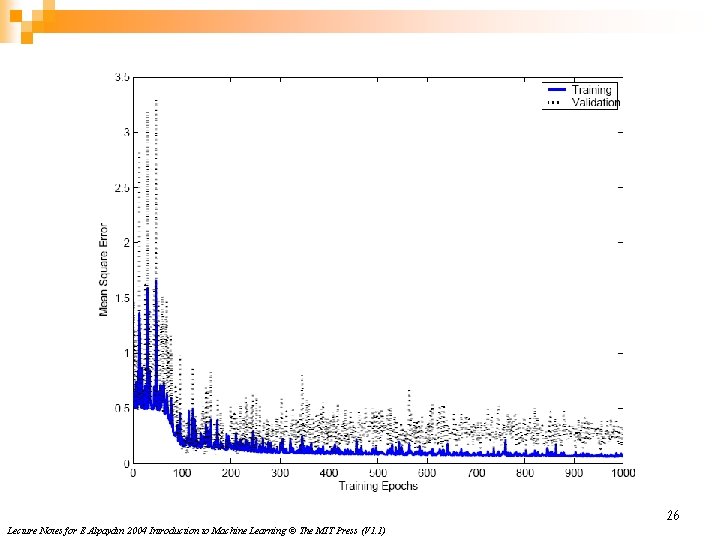
Overfitting/Overtraining Number of weights: H (d+1)+(H+1)K 25 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
26 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
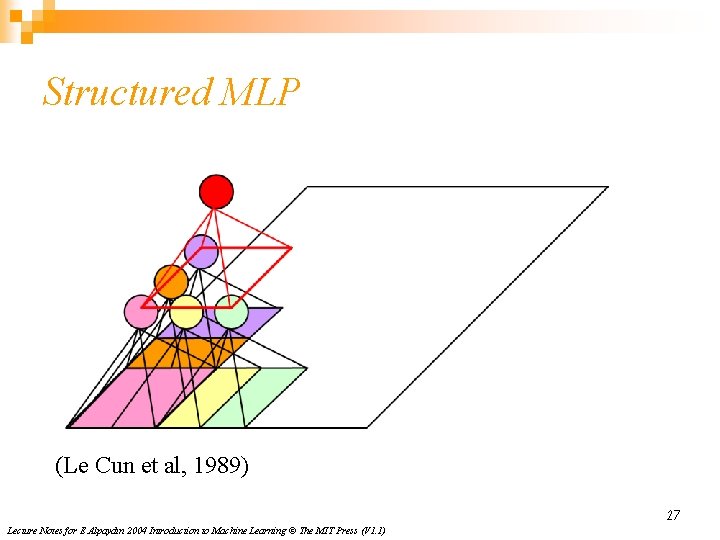
Structured MLP (Le Cun et al, 1989) 27 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
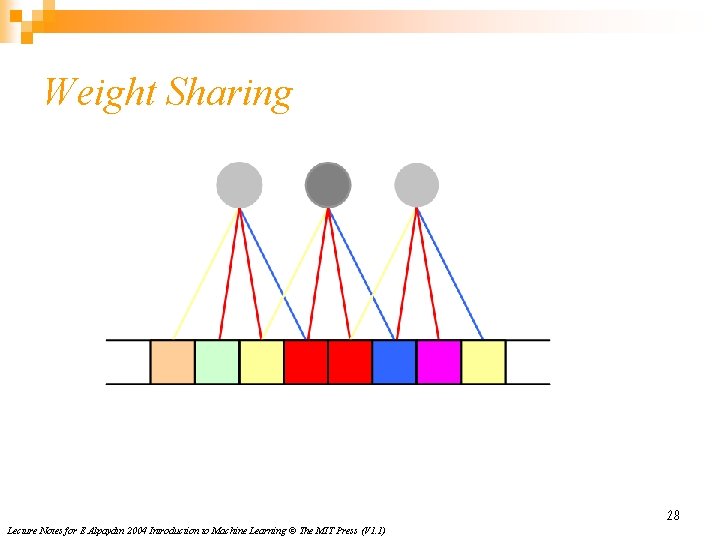
Weight Sharing 28 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
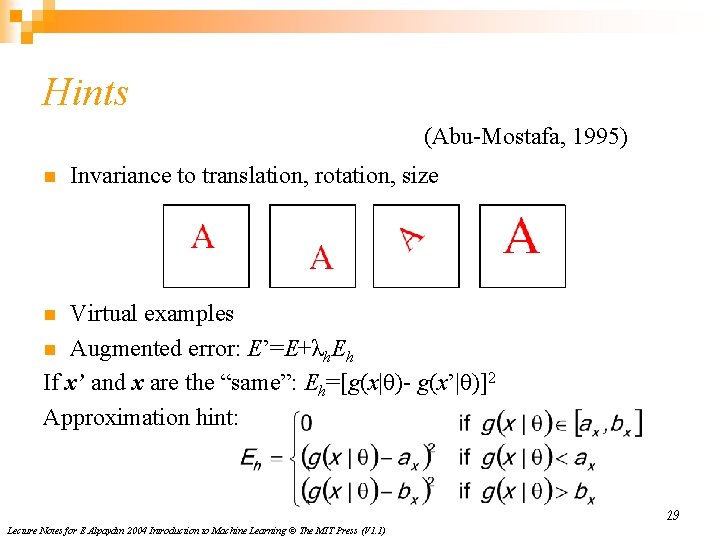
Hints (Abu-Mostafa, 1995) n Invariance to translation, rotation, size Virtual examples n Augmented error: E’=E+λh. Eh If x’ and x are the “same”: Eh=[g(x|θ)- g(x’|θ)]2 Approximation hint: n 29 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
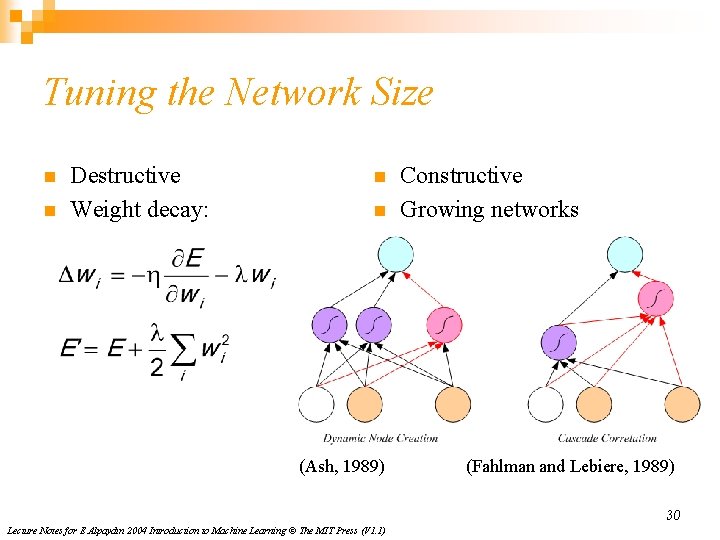
Tuning the Network Size n n Destructive Weight decay: n n (Ash, 1989) Constructive Growing networks (Fahlman and Lebiere, 1989) 30 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
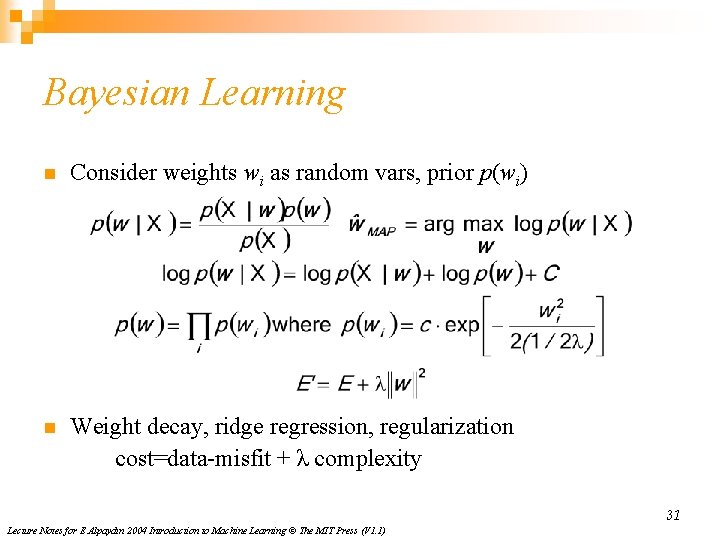
Bayesian Learning n Consider weights wi as random vars, prior p(wi) n Weight decay, ridge regression, regularization cost=data-misfit + λ complexity 31 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
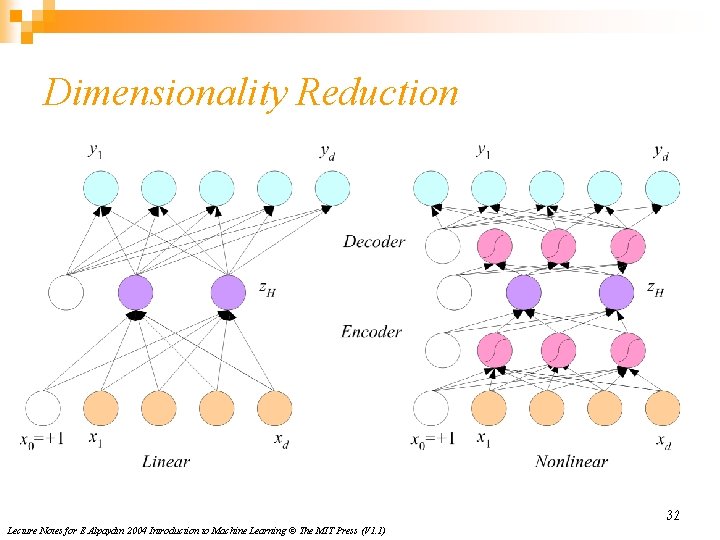
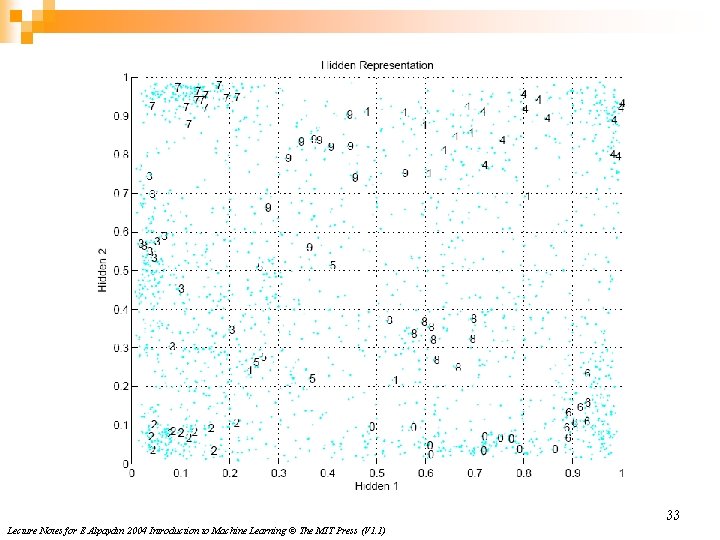
Dimensionality Reduction 32 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
33 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
Learning Time n Applications: Sequence recognition: Speech recognition ¨ Sequence reproduction: Time-series prediction ¨ Sequence association ¨ n Network architectures Time-delay networks (Waibel et al. , 1989) ¨ Recurrent networks (Rumelhart et al. , 1986) ¨ 34 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
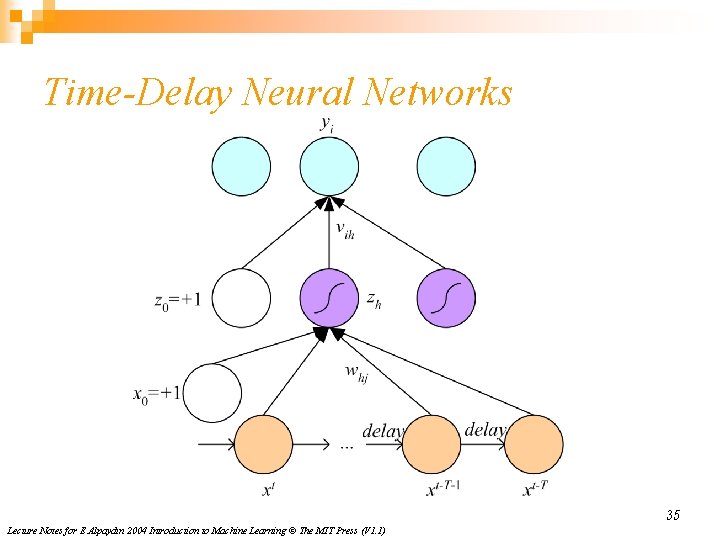
Time-Delay Neural Networks 35 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
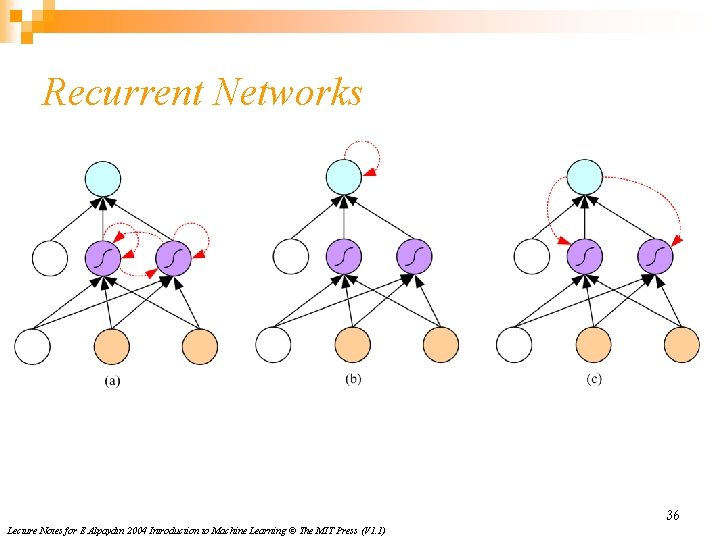
Recurrent Networks 36 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)
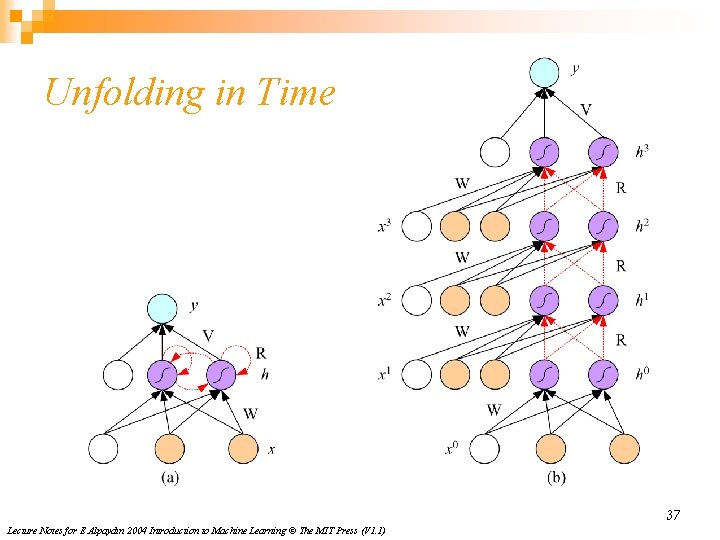
Unfolding in Time 37 Lecture Notes for E Alpaydın 2004 Introduction to Machine Learning © The MIT Press (V 1. 1)