Computer Architecture A Quantitative Approach Fifth Edition Chapter
- Slides: 82
Computer Architecture A Quantitative Approach, Fifth Edition Chapter 2 Memory Hierarchy Design Copyright © 2012, Elsevier Inc. All rights reserved. 1
n n n Programmers want unlimited amounts of memory with low latency Fast memory technology is more expensive per bit than slower memory Solution: organize memory system into a hierarchy n n n Introduction Entire addressable memory space available in largest, slowest memory Incrementally smaller and faster memories, each containing a subset of the memory below it, proceed in steps up toward the processor Temporal and spatial locality insures that nearly all references can be found in smaller memories n Gives the allusion of a large, fast memory being presented to the processor Copyright © 2012, Elsevier Inc. All rights reserved. 2
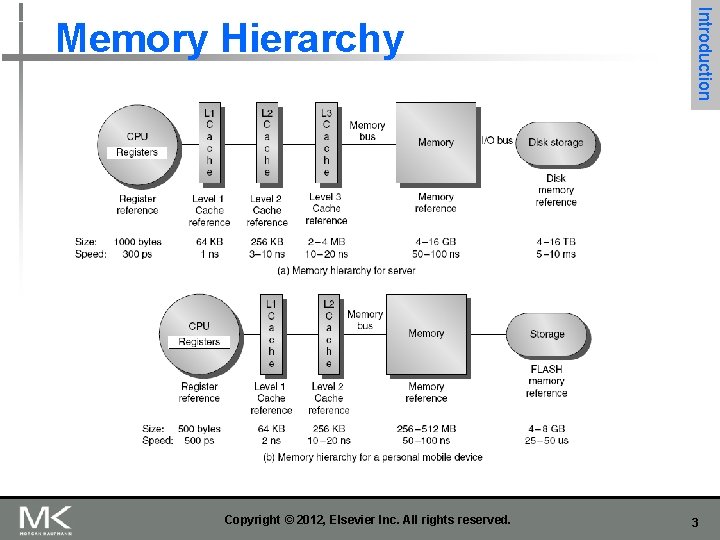
Copyright © 2012, Elsevier Inc. All rights reserved. Introduction Memory Hierarchy 3
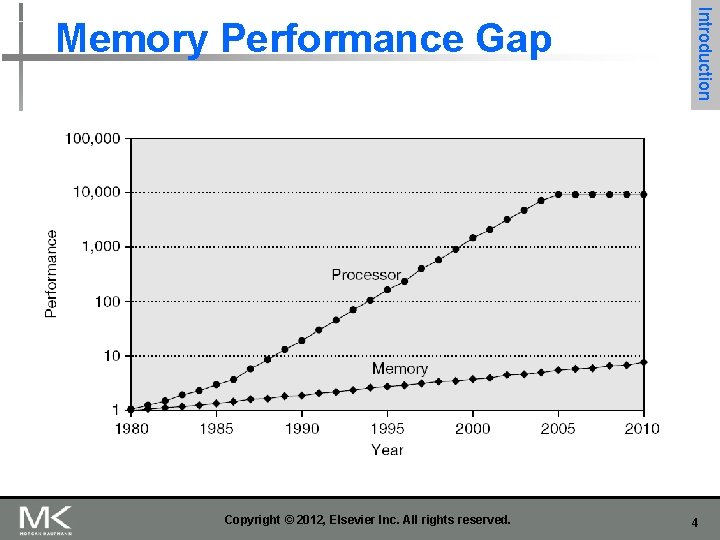
Copyright © 2012, Elsevier Inc. All rights reserved. Introduction Memory Performance Gap 4
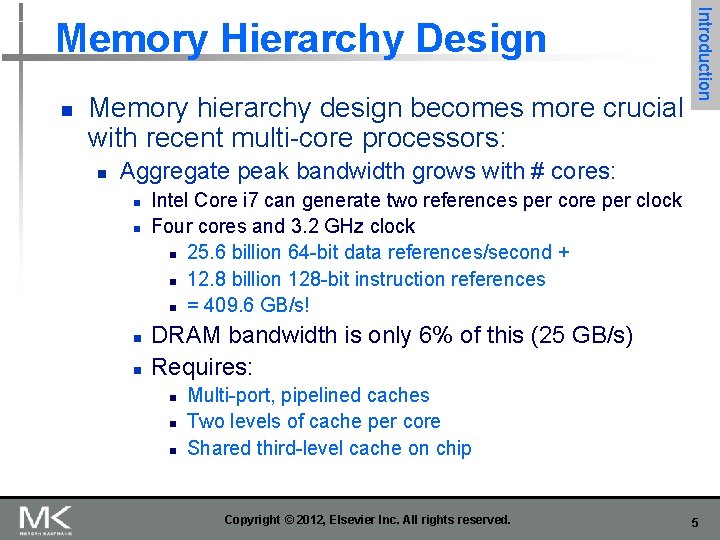
n Memory hierarchy design becomes more crucial with recent multi-core processors: n Introduction Memory Hierarchy Design Aggregate peak bandwidth grows with # cores: n n Intel Core i 7 can generate two references per core per clock Four cores and 3. 2 GHz clock n 25. 6 billion 64 -bit data references/second + n 12. 8 billion 128 -bit instruction references n = 409. 6 GB/s! DRAM bandwidth is only 6% of this (25 GB/s) Requires: n n n Multi-port, pipelined caches Two levels of cache per core Shared third-level cache on chip Copyright © 2012, Elsevier Inc. All rights reserved. 5
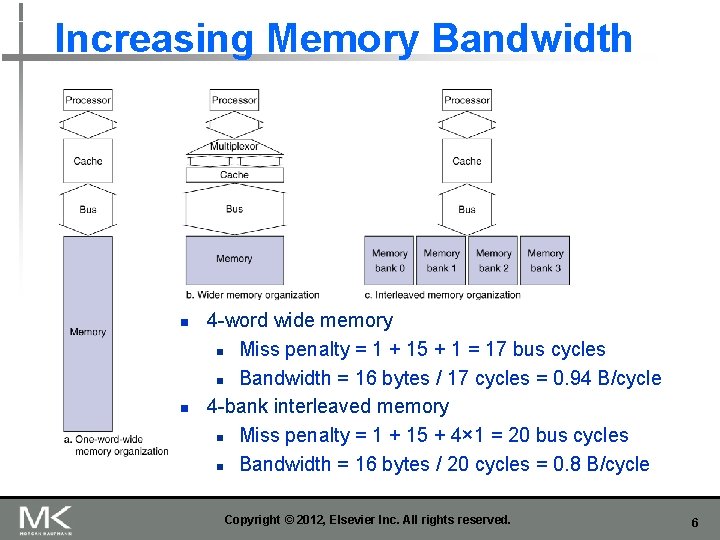
Increasing Memory Bandwidth n n 4 -word wide memory n Miss penalty = 1 + 15 + 1 = 17 bus cycles n Bandwidth = 16 bytes / 17 cycles = 0. 94 B/cycle 4 -bank interleaved memory n Miss penalty = 1 + 15 + 4× 1 = 20 bus cycles n Bandwidth = 16 bytes / 20 cycles = 0. 8 B/cycle Copyright © 2012, Elsevier Inc. All rights reserved. 6
n High-end microprocessors have >10 MB on-chip cache n Introduction Performance and Power Consumes large amount of area and power budget Copyright © 2012, Elsevier Inc. All rights reserved. 7
n When a word is not found in the cache, a miss occurs: n n n Fetch word from lower level in hierarchy, requiring a higher latency reference Lower level may be another cache or the main memory Also fetch the other words contained within the block n n Introduction Memory Hierarchy Basics Takes advantage of spatial locality Place block into cache in any location within its set, determined by address n block address MOD number of sets Copyright © 2012, Elsevier Inc. All rights reserved. 8
n n blocks per set => n-way set associative n n n Introduction Memory Hierarchy Basics Direct-mapped cache => one block per set Fully associative => one set Writing to cache: two strategies n Write-through n n Write-back n n Immediately update lower levels of hierarchy Only update lower levels of hierarchy when an updated block is replaced Both strategies use write buffer to make writes asynchronous Copyright © 2012, Elsevier Inc. All rights reserved. 9
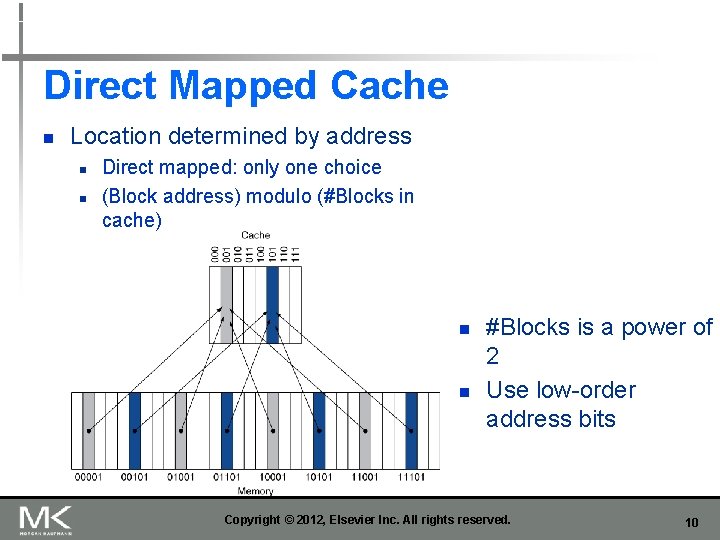
Direct Mapped Cache n Location determined by address n n Direct mapped: only one choice (Block address) modulo (#Blocks in cache) n n #Blocks is a power of 2 Use low-order address bits Copyright © 2012, Elsevier Inc. All rights reserved. 10
Tags and Valid Bits n How do we know which particular block is stored in a cache location? n n Store block address as well as the data Actually, only need the high-order bits Called the tag What if there is no data in a location? n n Valid bit: 1 = present, 0 = not present Initially 0 Copyright © 2012, Elsevier Inc. All rights reserved. 11
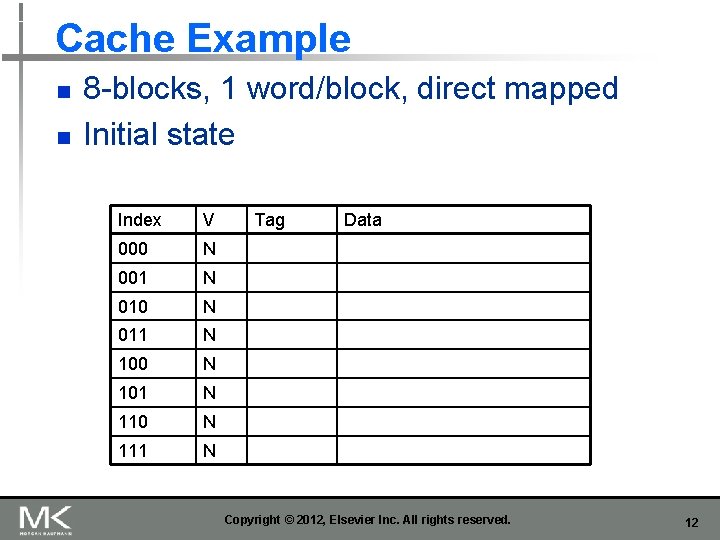
Cache Example n n 8 -blocks, 1 word/block, direct mapped Initial state Index V 000 N 001 N 010 N 011 N 100 N 101 N 110 N 111 N Tag Data Copyright © 2012, Elsevier Inc. All rights reserved. 12
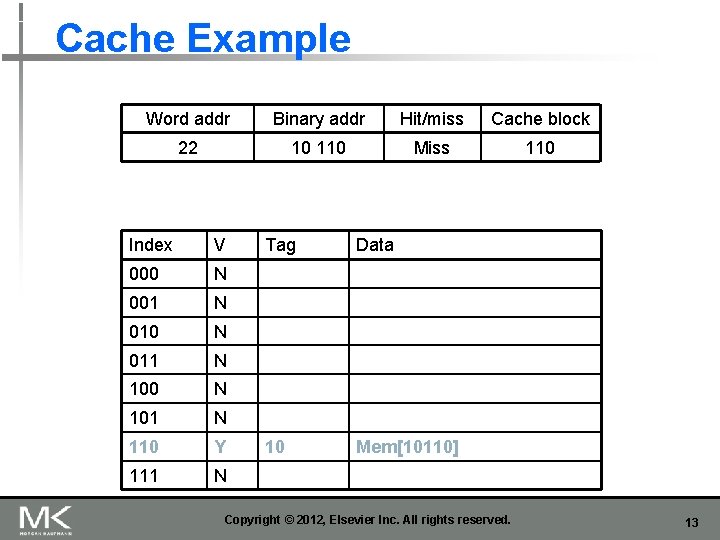
Cache Example Word addr Binary addr Hit/miss Cache block 22 10 110 Miss 110 Index V 000 N 001 N 010 N 011 N 100 N 101 N 110 Y 111 N Tag Data 10 Mem[10110] Copyright © 2012, Elsevier Inc. All rights reserved. 13
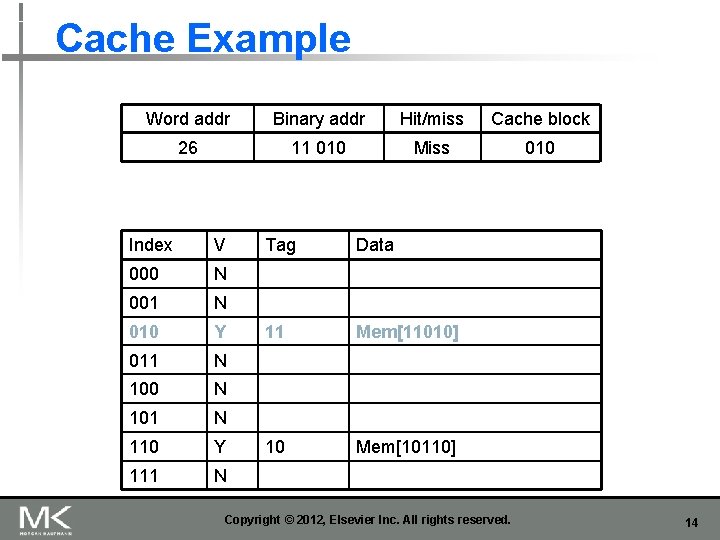
Cache Example Word addr Binary addr Hit/miss Cache block 26 11 010 Miss 010 Index V 000 N 001 N 010 Y 011 N 100 N 101 N 110 Y 111 N Tag Data 11 Mem[11010] 10 Mem[10110] Copyright © 2012, Elsevier Inc. All rights reserved. 14
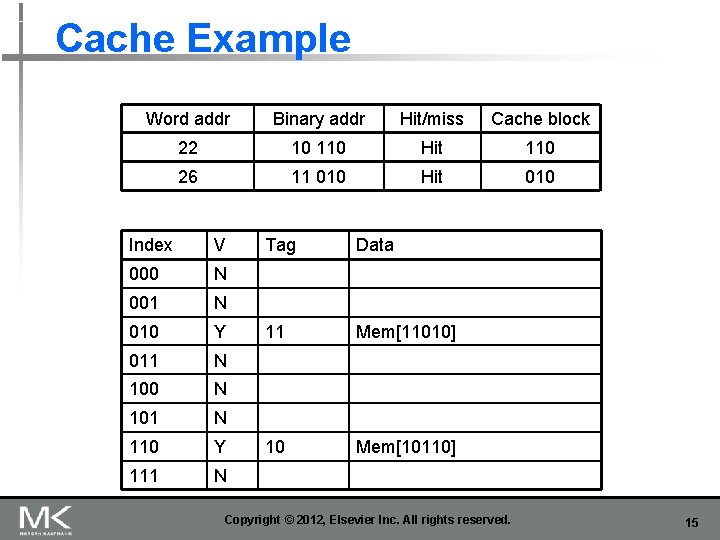
Cache Example Word addr Binary addr Hit/miss Cache block 22 10 110 Hit 110 26 11 010 Hit 010 Index V 000 N 001 N 010 Y 011 N 100 N 101 N 110 Y 111 N Tag Data 11 Mem[11010] 10 Mem[10110] Copyright © 2012, Elsevier Inc. All rights reserved. 15
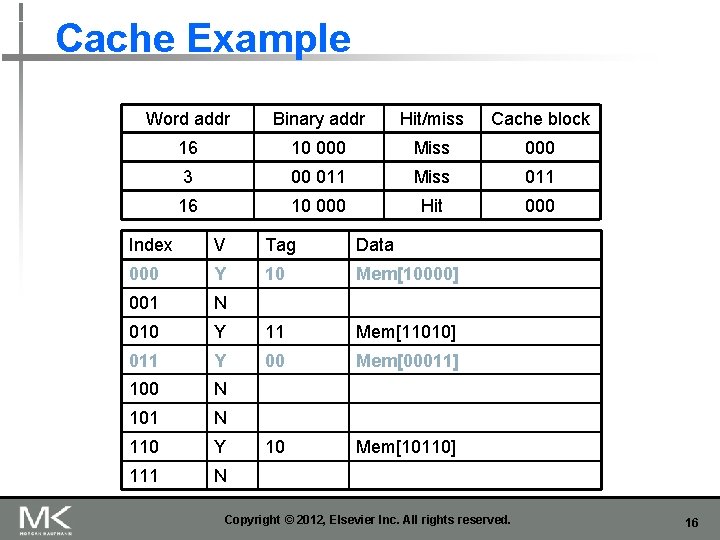
Cache Example Word addr Binary addr Hit/miss Cache block 16 10 000 Miss 000 3 00 011 Miss 011 16 10 000 Hit 000 Index V Tag Data 000 Y 10 Mem[10000] 001 N 010 Y 11 Mem[11010] 011 Y 00 Mem[00011] 100 N 101 N 110 Y 10 Mem[10110] 111 N Copyright © 2012, Elsevier Inc. All rights reserved. 16
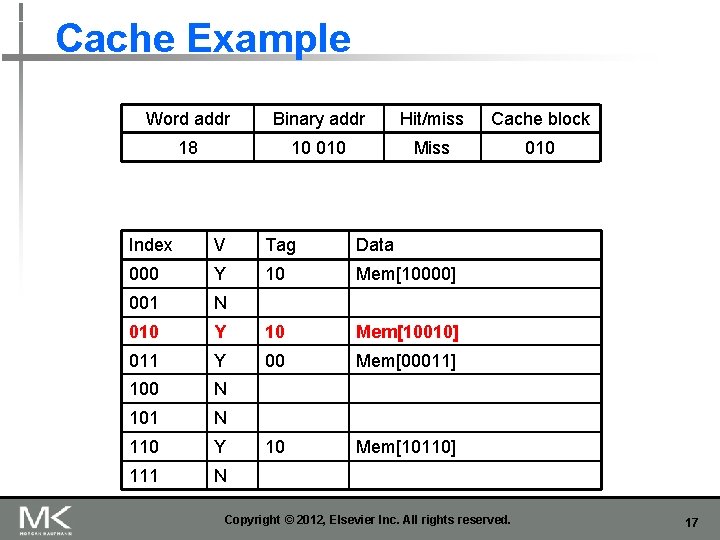
Cache Example Word addr Binary addr Hit/miss Cache block 18 10 010 Miss 010 Index V Tag Data 000 Y 10 Mem[10000] 001 N 010 Y 10 Mem[10010] 011 Y 00 Mem[00011] 100 N 101 N 110 Y 10 Mem[10110] 111 N Copyright © 2012, Elsevier Inc. All rights reserved. 17
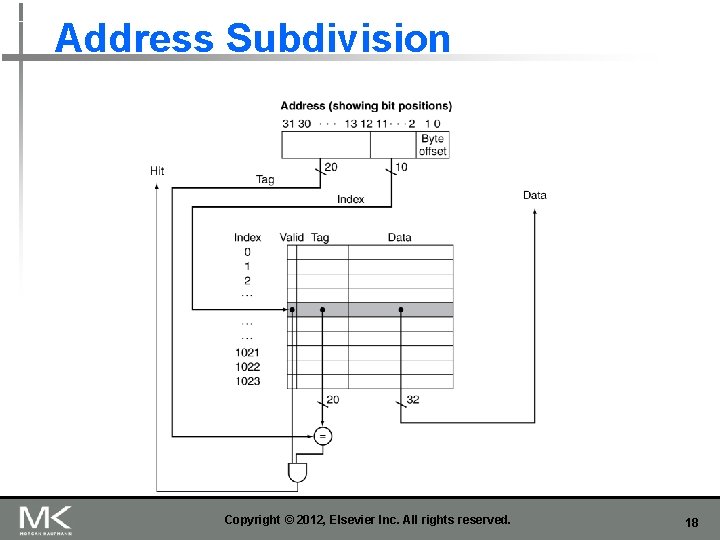
Address Subdivision Copyright © 2012, Elsevier Inc. All rights reserved. 18
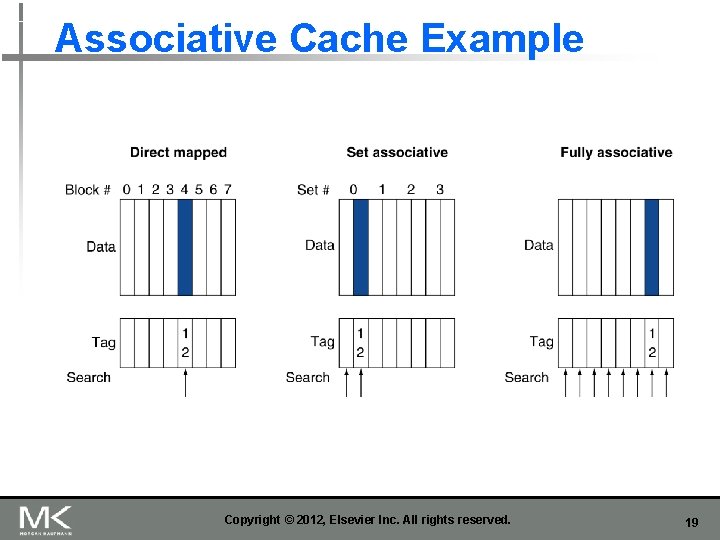
Associative Cache Example Copyright © 2012, Elsevier Inc. All rights reserved. 19
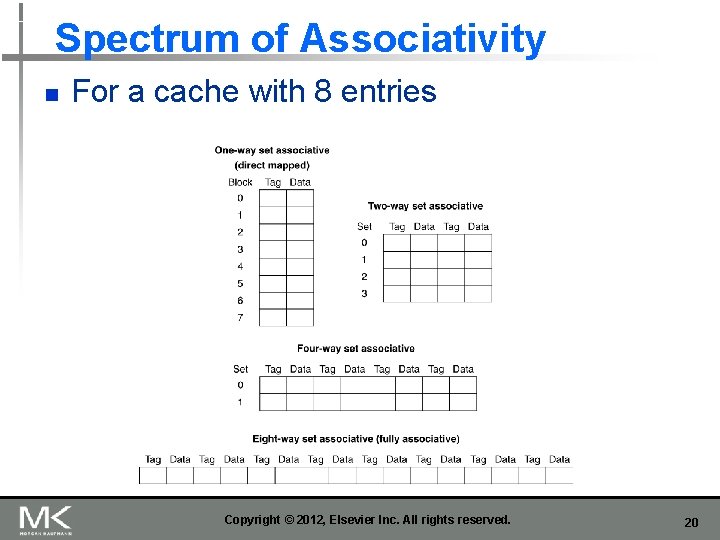
Spectrum of Associativity n For a cache with 8 entries Copyright © 2012, Elsevier Inc. All rights reserved. 20
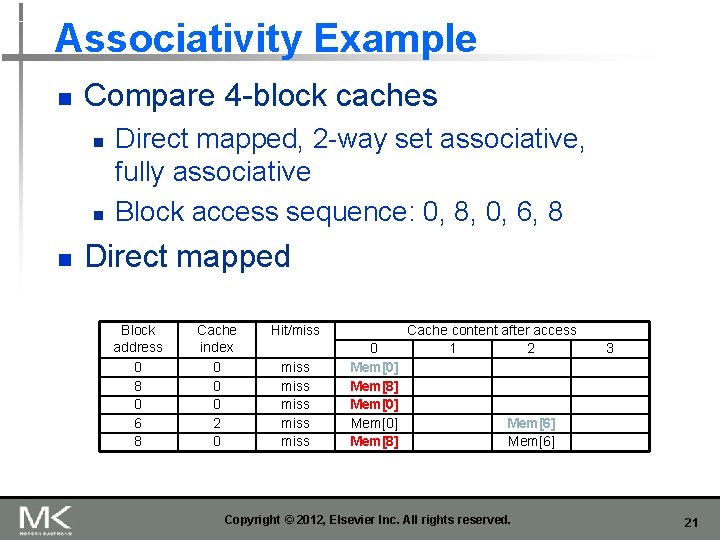
Associativity Example n Compare 4 -block caches n n n Direct mapped, 2 -way set associative, fully associative Block access sequence: 0, 8, 0, 6, 8 Direct mapped Block address 0 8 0 6 8 Cache index 0 0 0 2 0 Hit/miss miss 0 Mem[0] Mem[8] Cache content after access 1 2 3 Mem[6] Copyright © 2012, Elsevier Inc. All rights reserved. 21
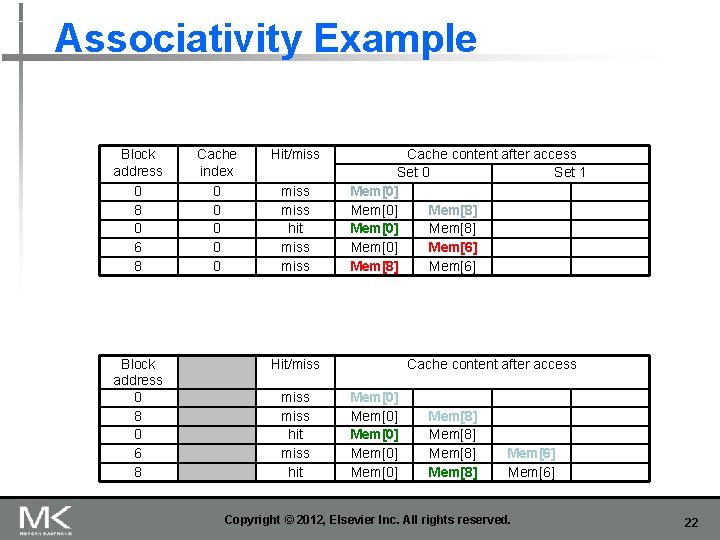
Associativity Example Block address 0 8 0 6 8 Cache index 0 0 0 Hit/miss hit miss Cache content after access Set 0 Set 1 Mem[0] Mem[8] Mem[0] Mem[6] Mem[8] Mem[6] Hit/miss hit Cache content after access Mem[0] Mem[0] Mem[8] Mem[6] Copyright © 2012, Elsevier Inc. All rights reserved. 22
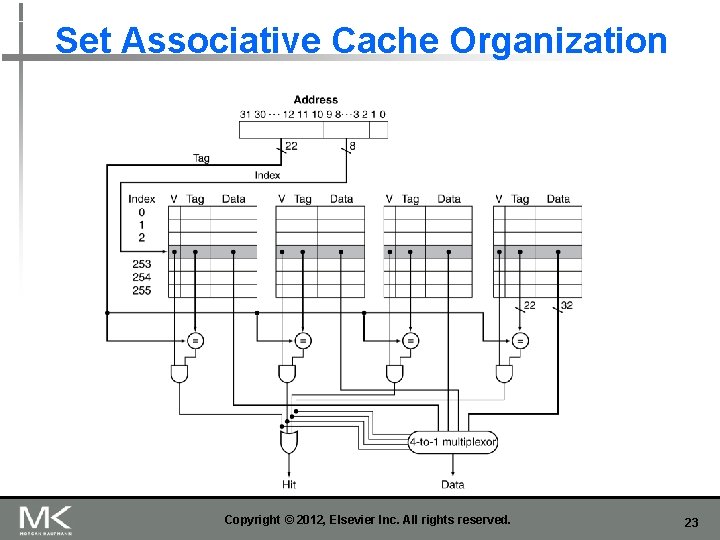
Set Associative Cache Organization Copyright © 2012, Elsevier Inc. All rights reserved. 23
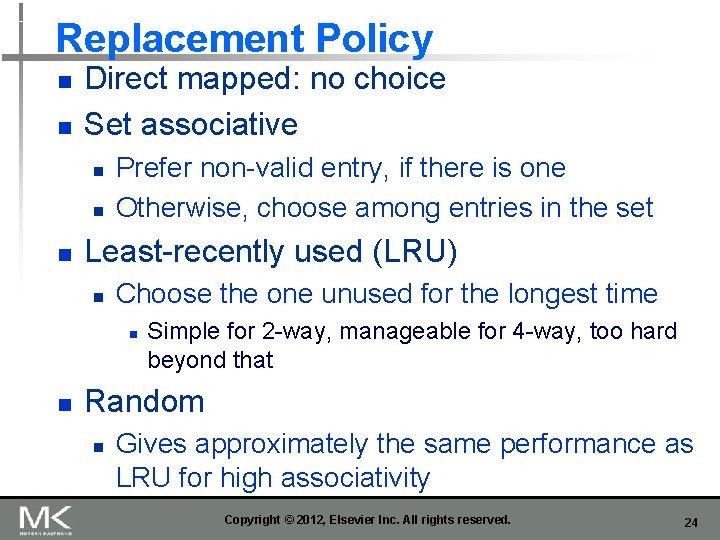
Replacement Policy n n Direct mapped: no choice Set associative n n n Prefer non-valid entry, if there is one Otherwise, choose among entries in the set Least-recently used (LRU) n Choose the one unused for the longest time n n Simple for 2 -way, manageable for 4 -way, too hard beyond that Random n Gives approximately the same performance as LRU for high associativity Copyright © 2012, Elsevier Inc. All rights reserved. 24
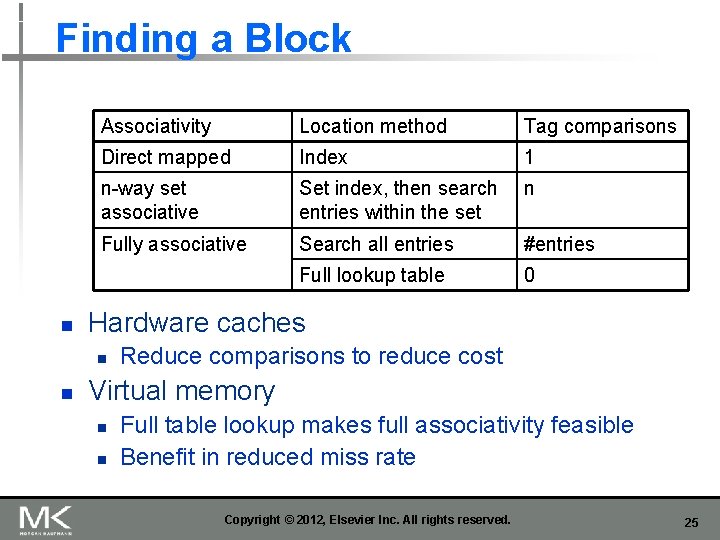
Finding a Block n Associativity Location method Tag comparisons Direct mapped Index 1 n-way set associative Set index, then search entries within the set n Fully associative Search all entries #entries Full lookup table 0 Hardware caches n n Reduce comparisons to reduce cost Virtual memory n n Full table lookup makes full associativity feasible Benefit in reduced miss rate Copyright © 2012, Elsevier Inc. All rights reserved. 25
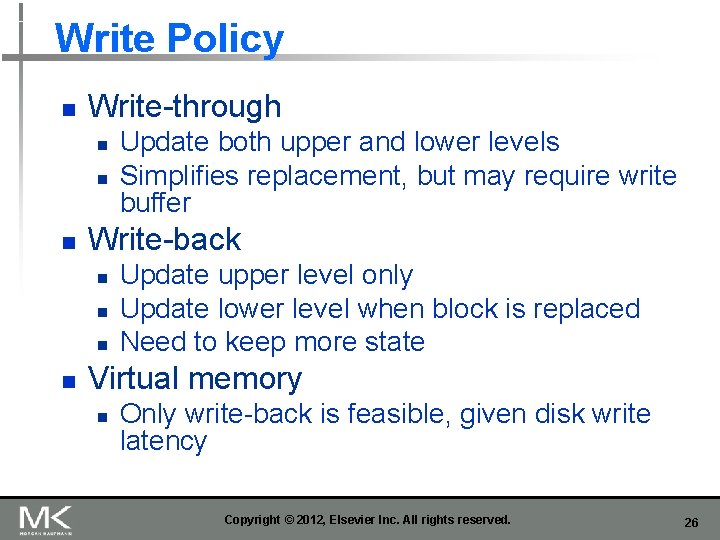
Write Policy n Write-through n n n Write-back n n Update both upper and lower levels Simplifies replacement, but may require write buffer Update upper level only Update lower level when block is replaced Need to keep more state Virtual memory n Only write-back is feasible, given disk write latency Copyright © 2012, Elsevier Inc. All rights reserved. 26
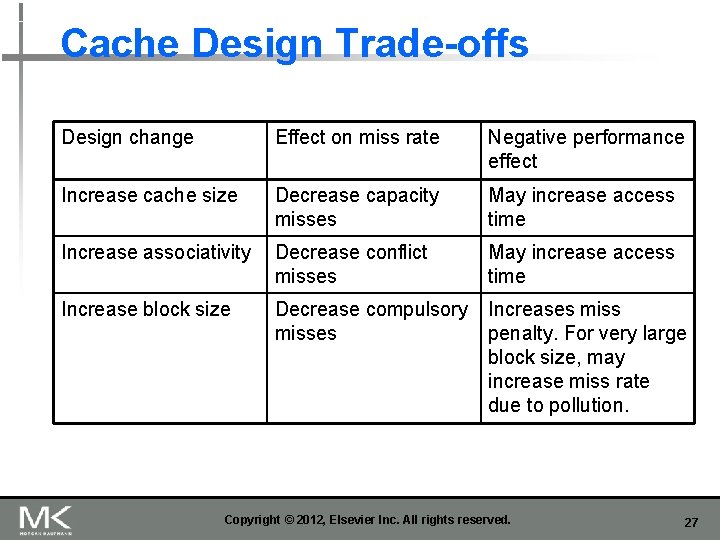
Cache Design Trade-offs Design change Effect on miss rate Negative performance effect Increase cache size Decrease capacity misses May increase access time Increase associativity Decrease conflict misses May increase access time Increase block size Decrease compulsory misses Increases miss penalty. For very large block size, may increase miss rate due to pollution. Copyright © 2012, Elsevier Inc. All rights reserved. 27
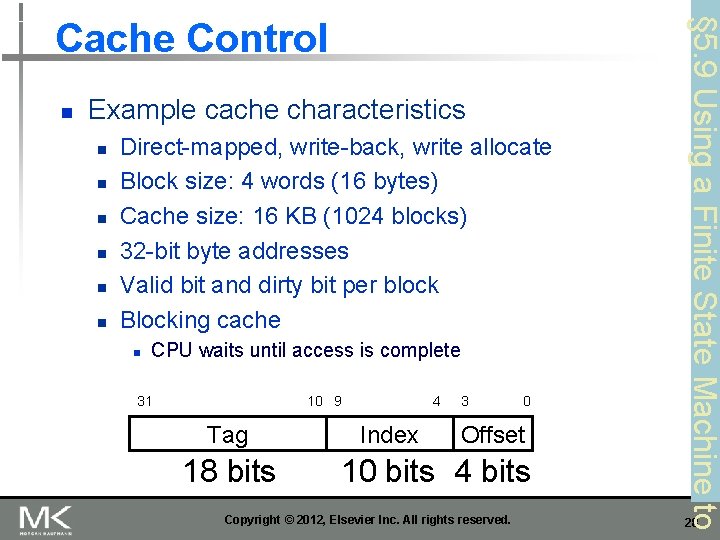
n Example cache characteristics n n n Direct-mapped, write-back, write allocate Block size: 4 words (16 bytes) Cache size: 16 KB (1024 blocks) 32 -bit byte addresses Valid bit and dirty bit per block Blocking cache n CPU waits until access is complete 31 10 9 Tag 18 bits 4 Index 3 0 Offset 10 bits 4 bits Copyright © 2012, Elsevier Inc. All rights reserved. § 5. 9 Using a Finite State Machine to C Cache Control 28
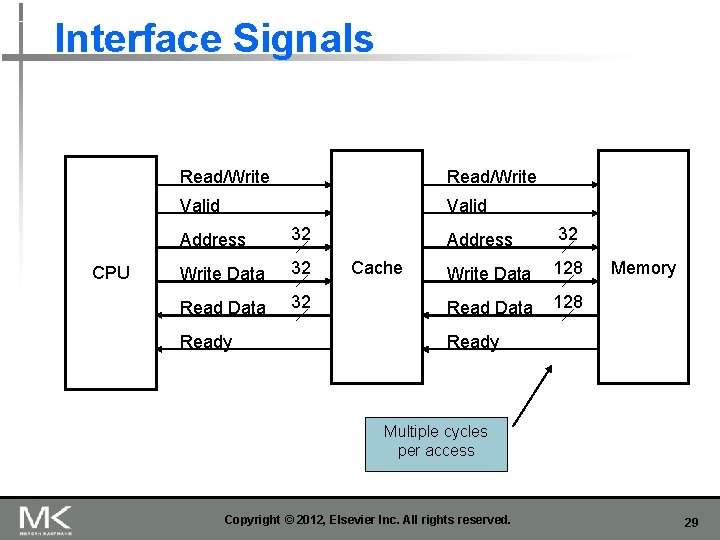
Interface Signals CPU Read/Write Valid Address 32 Write Data 32 Ready Cache Address 32 Write Data 128 Read Data 128 Memory Ready Multiple cycles per access Copyright © 2012, Elsevier Inc. All rights reserved. 29
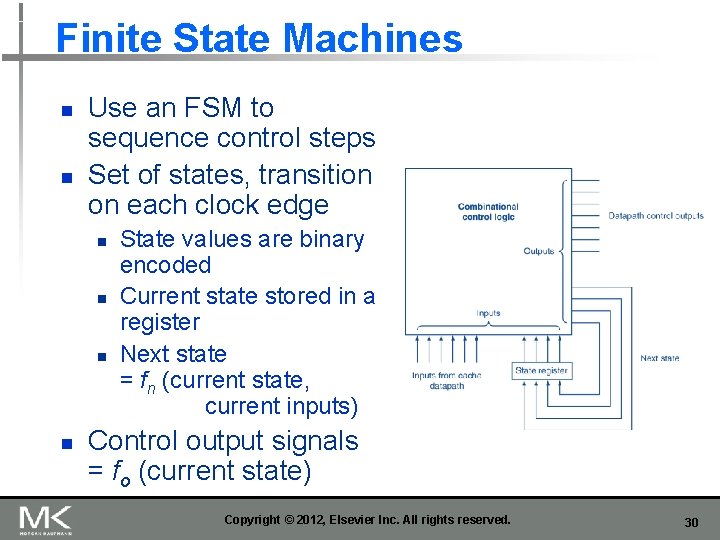
Finite State Machines n n Use an FSM to sequence control steps Set of states, transition on each clock edge n n State values are binary encoded Current state stored in a register Next state = fn (current state, current inputs) Control output signals = fo (current state) Copyright © 2012, Elsevier Inc. All rights reserved. 30
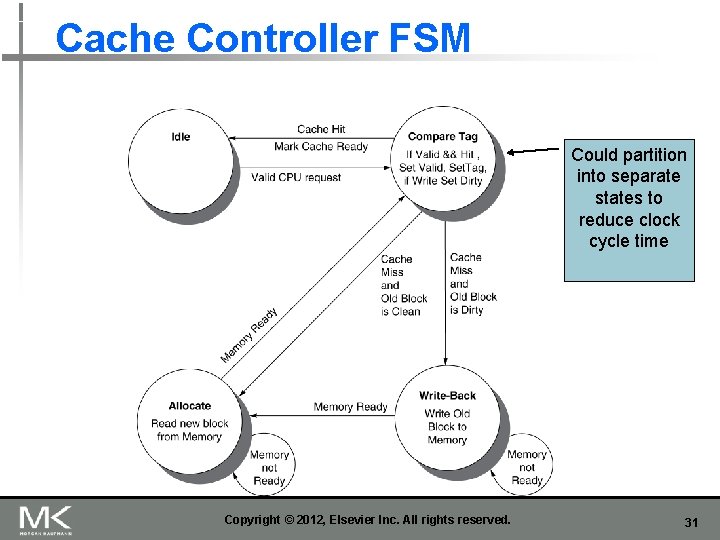
Cache Controller FSM Could partition into separate states to reduce clock cycle time Copyright © 2012, Elsevier Inc. All rights reserved. 31
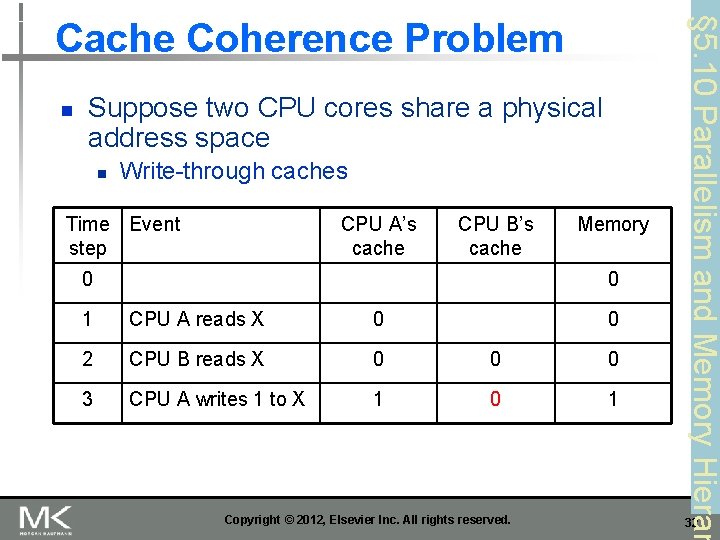
n Suppose two CPU cores share a physical address space n Write-through caches Time Event step CPU A’s cache CPU B’s cache 0 Memory 0 1 CPU A reads X 0 0 2 CPU B reads X 0 0 0 3 CPU A writes 1 to X 1 0 1 Copyright © 2012, Elsevier Inc. All rights reserved. § 5. 10 Parallelism and Memory Hierar Cache Coherence Problem 32
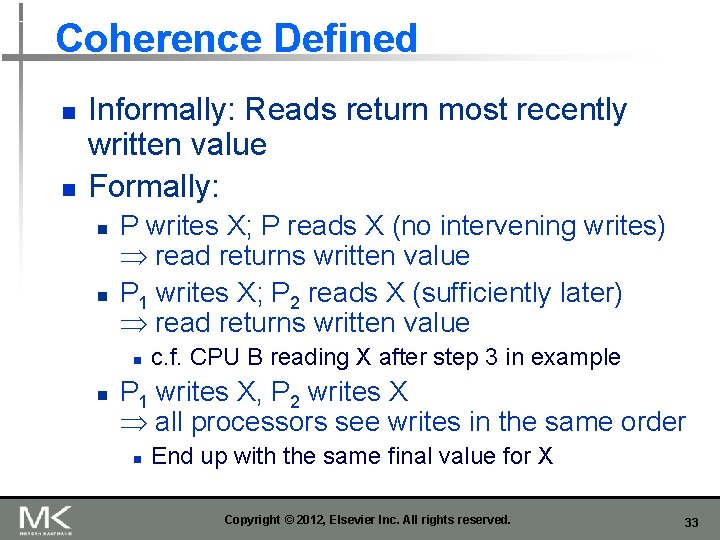
Coherence Defined n n Informally: Reads return most recently written value Formally: n n P writes X; P reads X (no intervening writes) read returns written value P 1 writes X; P 2 reads X (sufficiently later) read returns written value n n c. f. CPU B reading X after step 3 in example P 1 writes X, P 2 writes X all processors see writes in the same order n End up with the same final value for X Copyright © 2012, Elsevier Inc. All rights reserved. 33
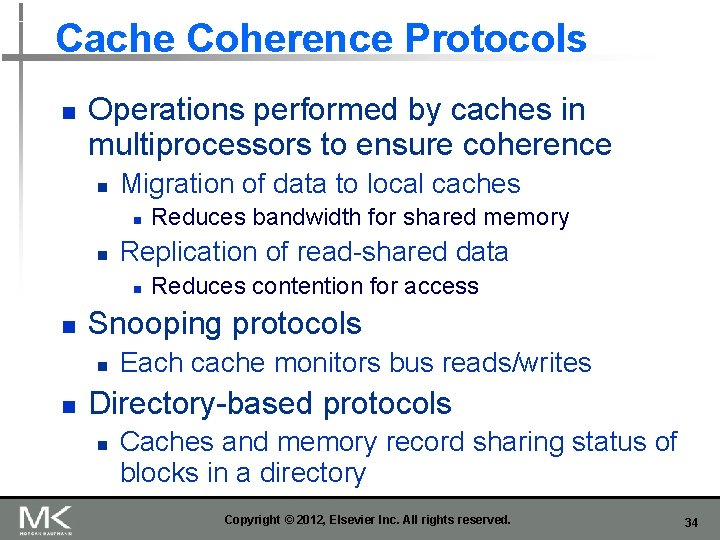
Cache Coherence Protocols n Operations performed by caches in multiprocessors to ensure coherence n Migration of data to local caches n n Replication of read-shared data n n Reduces contention for access Snooping protocols n n Reduces bandwidth for shared memory Each cache monitors bus reads/writes Directory-based protocols n Caches and memory record sharing status of blocks in a directory Copyright © 2012, Elsevier Inc. All rights reserved. 34
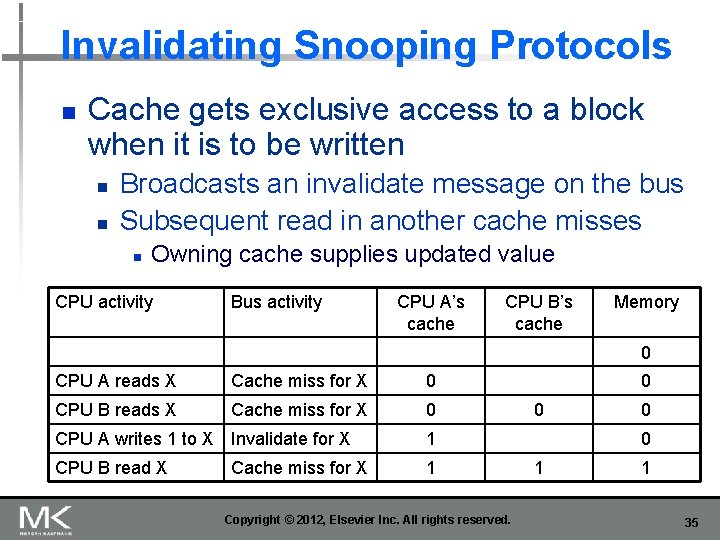
Invalidating Snooping Protocols n Cache gets exclusive access to a block when it is to be written n n Broadcasts an invalidate message on the bus Subsequent read in another cache misses n Owning cache supplies updated value CPU activity Bus activity CPU A’s cache CPU B’s cache Memory 0 CPU A reads X Cache miss for X 0 CPU B reads X Cache miss for X 0 CPU A writes 1 to X Invalidate for X 1 CPU B read X 1 Cache miss for X Copyright © 2012, Elsevier Inc. All rights reserved. 0 0 1 1 35
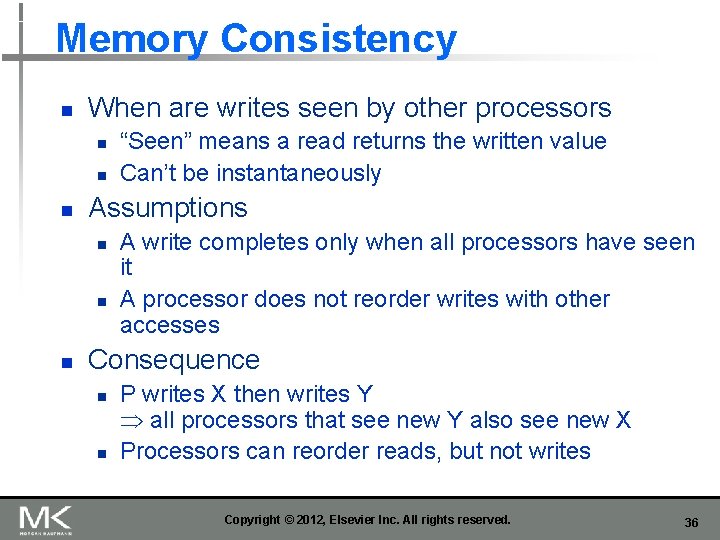
Memory Consistency n When are writes seen by other processors n n n Assumptions n n n “Seen” means a read returns the written value Can’t be instantaneously A write completes only when all processors have seen it A processor does not reorder writes with other accesses Consequence n n P writes X then writes Y all processors that see new Y also see new X Processors can reorder reads, but not writes Copyright © 2012, Elsevier Inc. All rights reserved. 36
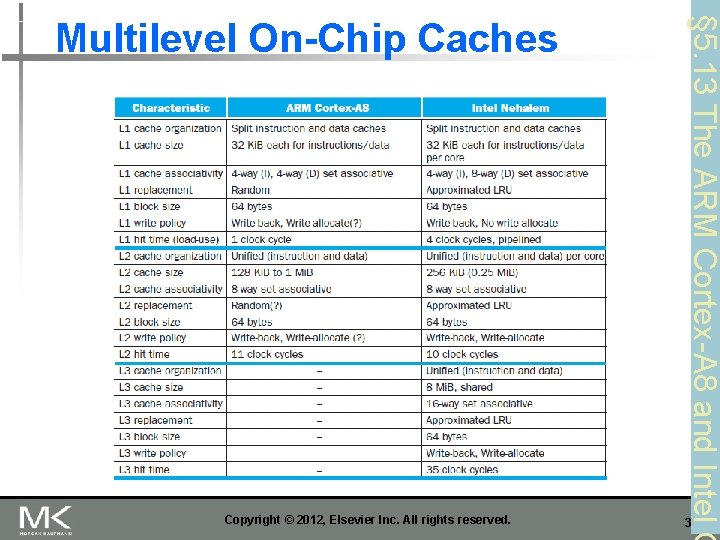
Copyright © 2012, Elsevier Inc. All rights reserved. § 5. 13 The ARM Cortex-A 8 and Intel C Multilevel On-Chip Caches 37
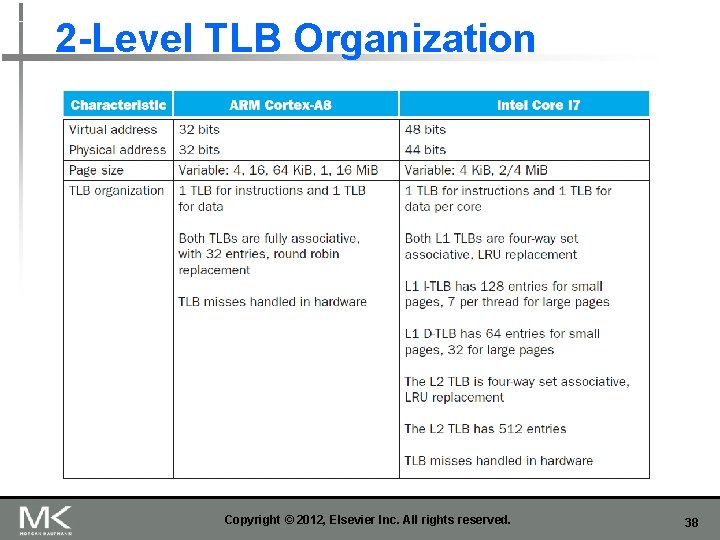
2 -Level TLB Organization Copyright © 2012, Elsevier Inc. All rights reserved. 38
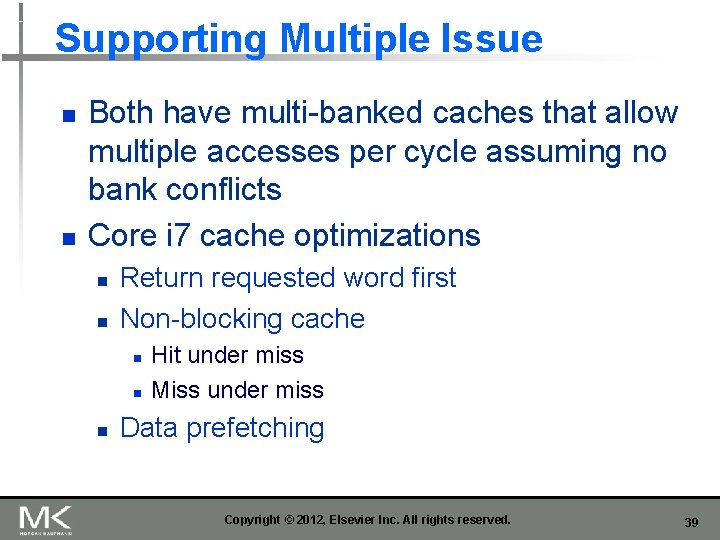
Supporting Multiple Issue n n Both have multi-banked caches that allow multiple accesses per cycle assuming no bank conflicts Core i 7 cache optimizations n n Return requested word first Non-blocking cache n n n Hit under miss Miss under miss Data prefetching Copyright © 2012, Elsevier Inc. All rights reserved. 39
n Miss rate n n Introduction Memory Hierarchy Basics Fraction of cache access that result in a miss Causes of misses n Compulsory n n Capacity n n First reference to a block Blocks discarded and later retrieved Conflict n Program makes repeated references to multiple addresses from different blocks that map to the same location in the cache Copyright © 2012, Elsevier Inc. All rights reserved. 40
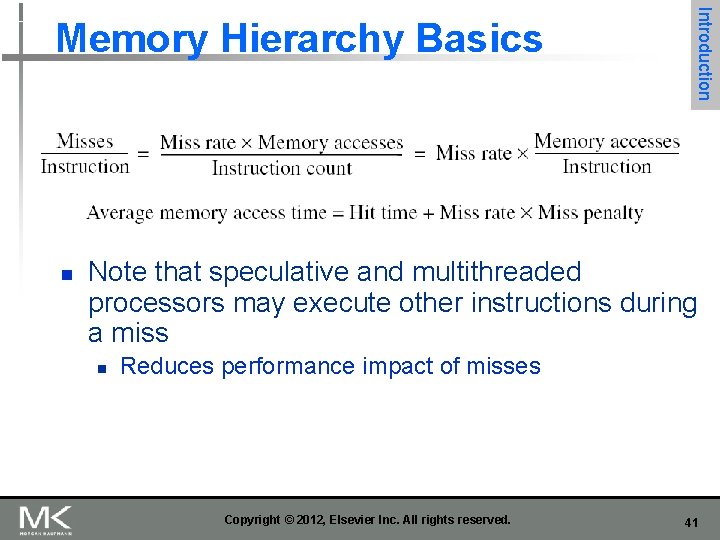
n Introduction Memory Hierarchy Basics Note that speculative and multithreaded processors may execute other instructions during a miss n Reduces performance impact of misses Copyright © 2012, Elsevier Inc. All rights reserved. 41
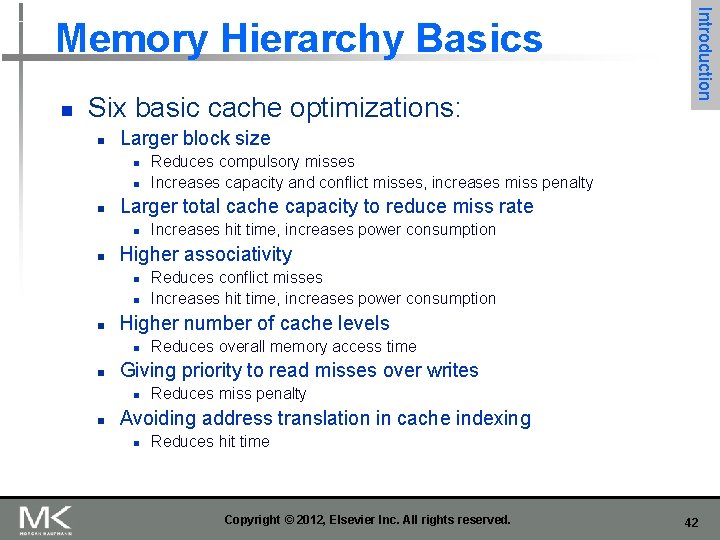
n Six basic cache optimizations: n Larger block size n n Reduces overall memory access time Giving priority to read misses over writes n n Reduces conflict misses Increases hit time, increases power consumption Higher number of cache levels n n Increases hit time, increases power consumption Higher associativity n n Reduces compulsory misses Increases capacity and conflict misses, increases miss penalty Larger total cache capacity to reduce miss rate n n Introduction Memory Hierarchy Basics Reduces miss penalty Avoiding address translation in cache indexing n Reduces hit time Copyright © 2012, Elsevier Inc. All rights reserved. 42
n Small and simple first level caches n Critical timing path: n n n addressing tag memory, then comparing tags, then selecting correct set Advanced Optimizations Ten Advanced Optimizations Direct-mapped caches can overlap tag compare and transmission of data Lower associativity reduces power because fewer cache lines are accessed Copyright © 2012, Elsevier Inc. All rights reserved. 43
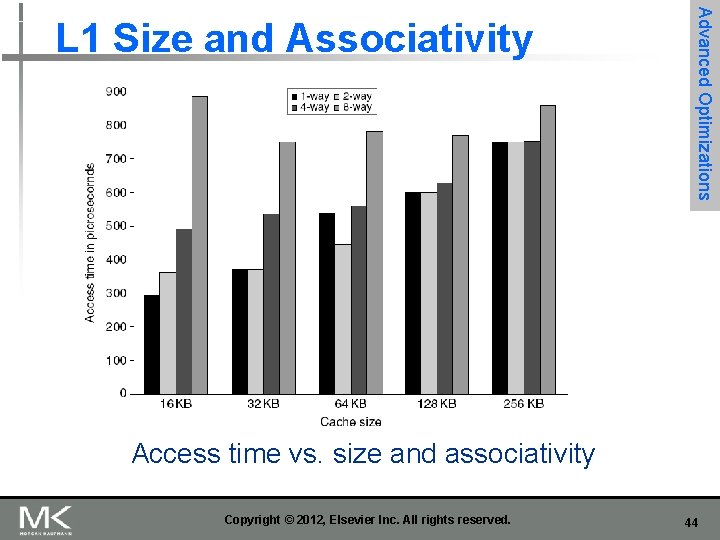
Advanced Optimizations L 1 Size and Associativity Access time vs. size and associativity Copyright © 2012, Elsevier Inc. All rights reserved. 44
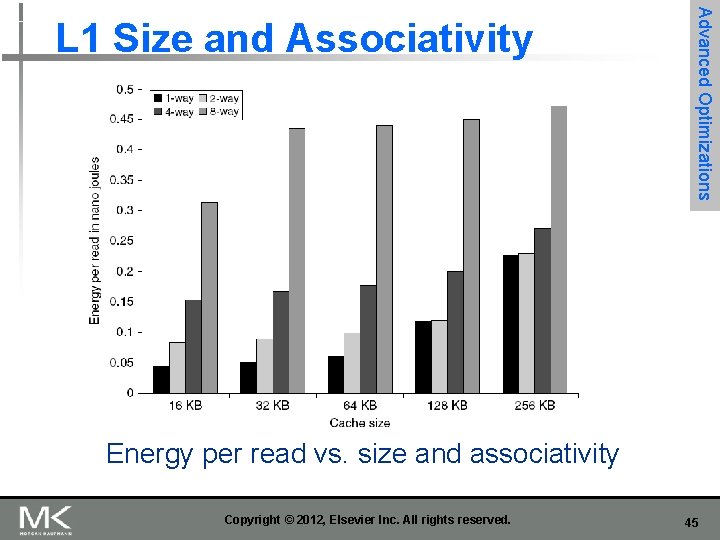
Advanced Optimizations L 1 Size and Associativity Energy per read vs. size and associativity Copyright © 2012, Elsevier Inc. All rights reserved. 45
n To improve hit time, predict the way to pre-set mux n n Mis-prediction gives longer hit time Prediction accuracy n n n Advanced Optimizations Way Prediction > 90% for two-way > 80% for four-way I-cache has better accuracy than D-cache First used on MIPS R 10000 in mid-90 s Used on ARM Cortex-A 8 Extend to predict block as well n n “Way selection” Increases mis-prediction penalty Copyright © 2012, Elsevier Inc. All rights reserved. 46
n Pipeline cache access to improve bandwidth n Examples: n n n Pentium: 1 cycle Pentium Pro – Pentium III: 2 cycles Pentium 4 – Core i 7: 4 cycles Advanced Optimizations Pipelining Cache Increases branch mis-prediction penalty Makes it easier to increase associativity Copyright © 2012, Elsevier Inc. All rights reserved. 47
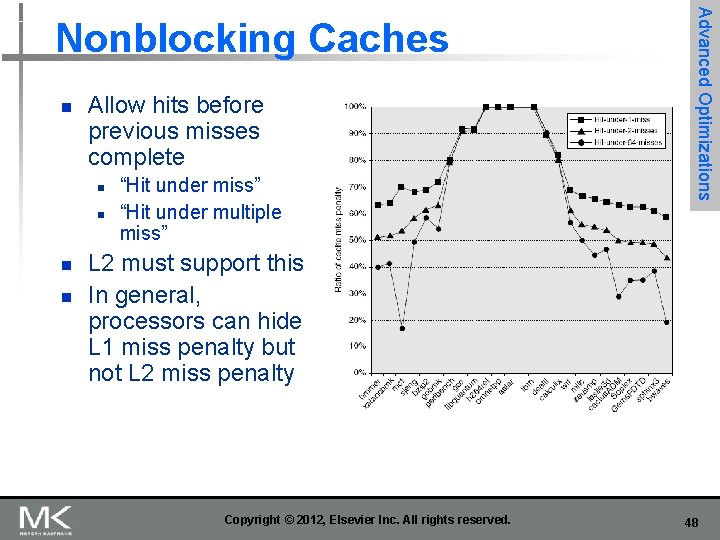
n Allow hits before previous misses complete n n “Hit under miss” “Hit under multiple miss” Advanced Optimizations Nonblocking Caches L 2 must support this In general, processors can hide L 1 miss penalty but not L 2 miss penalty Copyright © 2012, Elsevier Inc. All rights reserved. 48
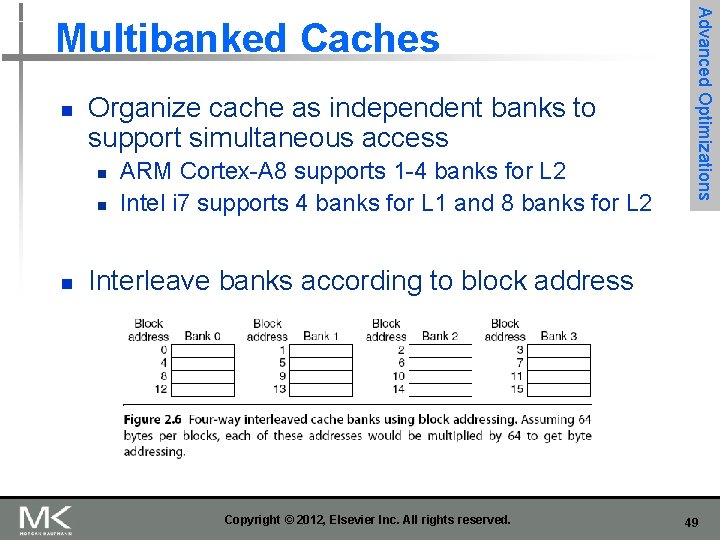
n Organize cache as independent banks to support simultaneous access n n n ARM Cortex-A 8 supports 1 -4 banks for L 2 Intel i 7 supports 4 banks for L 1 and 8 banks for L 2 Advanced Optimizations Multibanked Caches Interleave banks according to block address Copyright © 2012, Elsevier Inc. All rights reserved. 49
n Critical word first n n n Early restart n n n Request missed word from memory first Send it to the processor as soon as it arrives Advanced Optimizations Critical Word First, Early Restart Request words in normal order Send missed work to the processor as soon as it arrives Effectiveness of these strategies depends on block size and likelihood of another access to the portion of the block that has not yet been fetched Copyright © 2012, Elsevier Inc. All rights reserved. 50
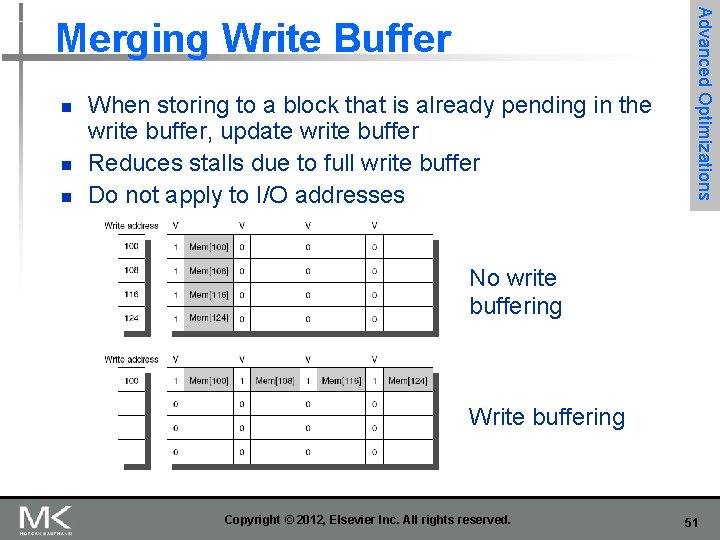
n n n When storing to a block that is already pending in the write buffer, update write buffer Reduces stalls due to full write buffer Do not apply to I/O addresses Advanced Optimizations Merging Write Buffer No write buffering Write buffering Copyright © 2012, Elsevier Inc. All rights reserved. 51
n Loop Interchange n n Swap nested loops to access memory in sequential order Advanced Optimizations Compiler Optimizations Blocking n n Instead of accessing entire rows or columns, subdivide matrices into blocks Requires more memory accesses but improves locality of accesses Copyright © 2012, Elsevier Inc. All rights reserved. 52
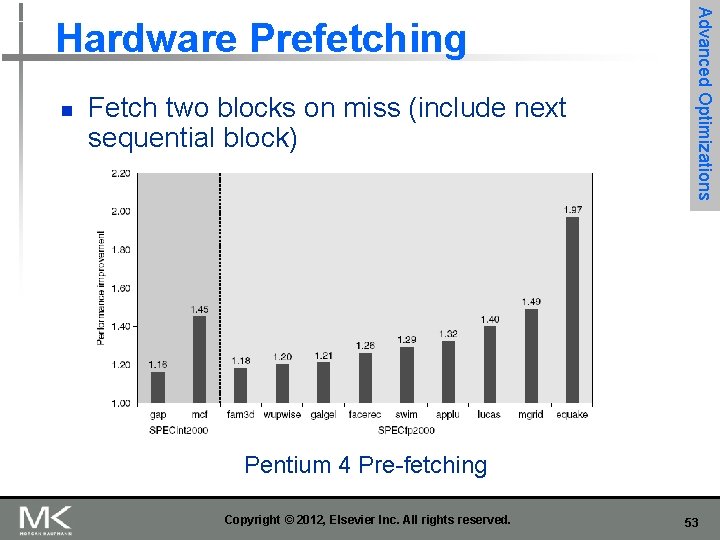
n Fetch two blocks on miss (include next sequential block) Advanced Optimizations Hardware Prefetching Pentium 4 Pre-fetching Copyright © 2012, Elsevier Inc. All rights reserved. 53
n n n Insert prefetch instructions before data is needed Non-faulting: prefetch doesn’t cause exceptions Register prefetch n n Loads data into register Cache prefetch n n Advanced Optimizations Compiler Prefetching Loads data into cache Combine with loop unrolling and software pipelining Copyright © 2012, Elsevier Inc. All rights reserved. 54
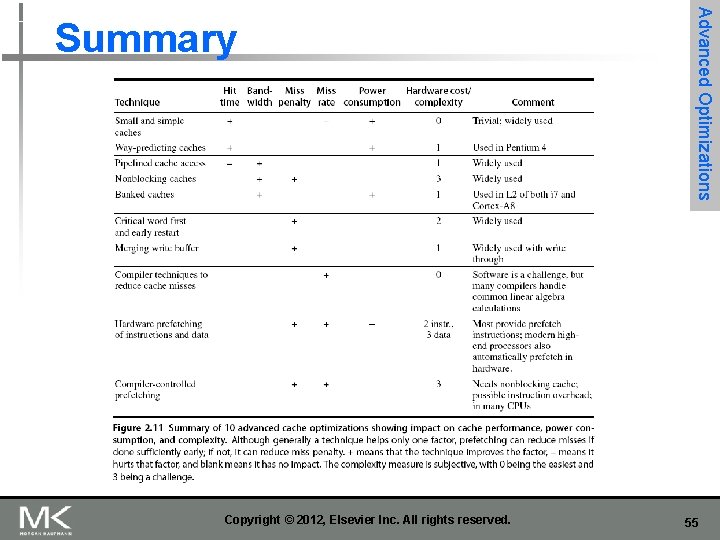
Copyright © 2012, Elsevier Inc. All rights reserved. Advanced Optimizations Summary 55
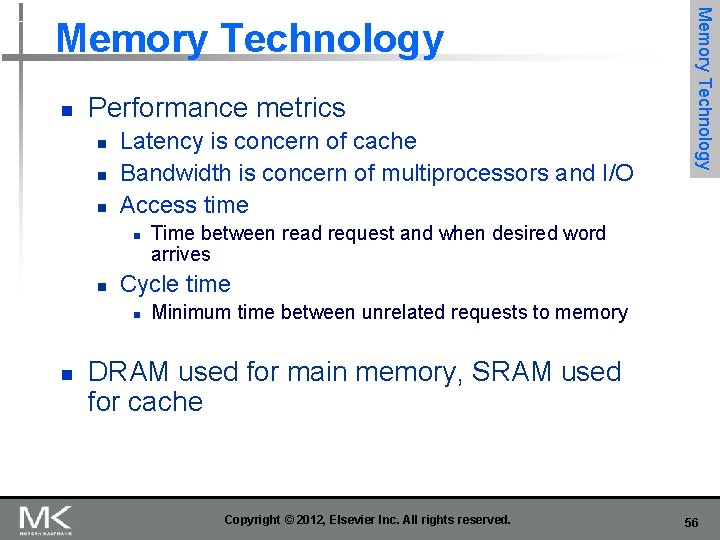
n Performance metrics n n n Latency is concern of cache Bandwidth is concern of multiprocessors and I/O Access time n n Time between read request and when desired word arrives Cycle time n n Memory Technology Minimum time between unrelated requests to memory DRAM used for main memory, SRAM used for cache Copyright © 2012, Elsevier Inc. All rights reserved. 56
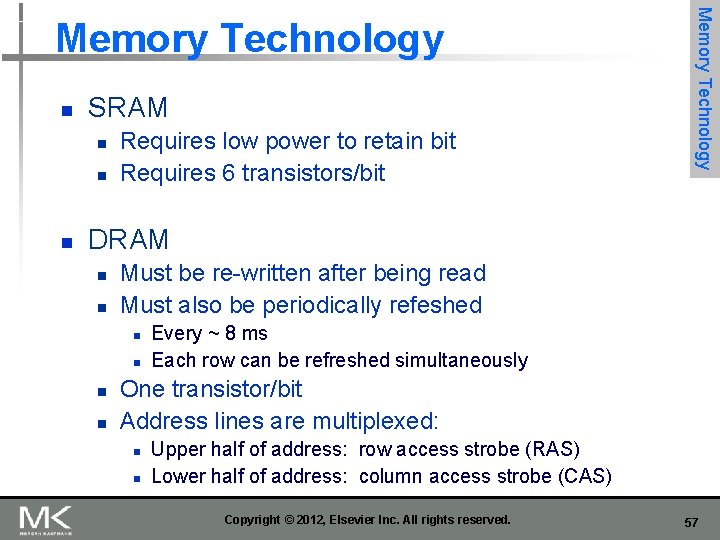
n SRAM n n n Requires low power to retain bit Requires 6 transistors/bit Memory Technology DRAM n n Must be re-written after being read Must also be periodically refeshed n n Every ~ 8 ms Each row can be refreshed simultaneously One transistor/bit Address lines are multiplexed: n n Upper half of address: row access strobe (RAS) Lower half of address: column access strobe (CAS) Copyright © 2012, Elsevier Inc. All rights reserved. 57
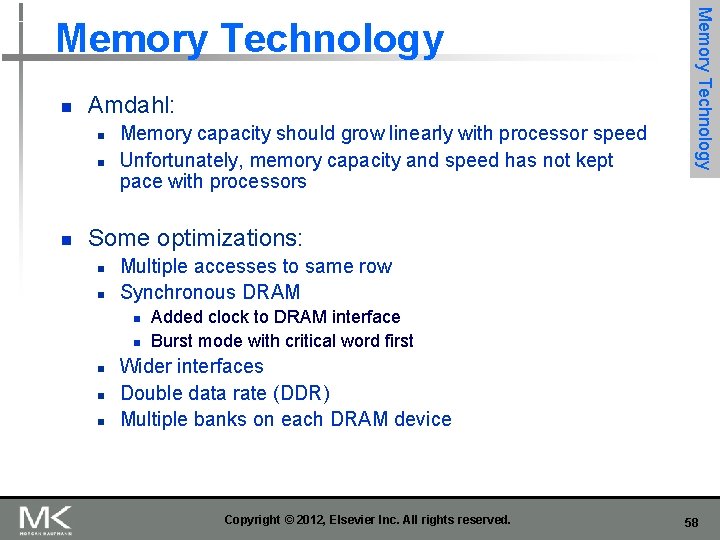
n Amdahl: n n n Memory capacity should grow linearly with processor speed Unfortunately, memory capacity and speed has not kept pace with processors Memory Technology Some optimizations: n n Multiple accesses to same row Synchronous DRAM n n n Added clock to DRAM interface Burst mode with critical word first Wider interfaces Double data rate (DDR) Multiple banks on each DRAM device Copyright © 2012, Elsevier Inc. All rights reserved. 58
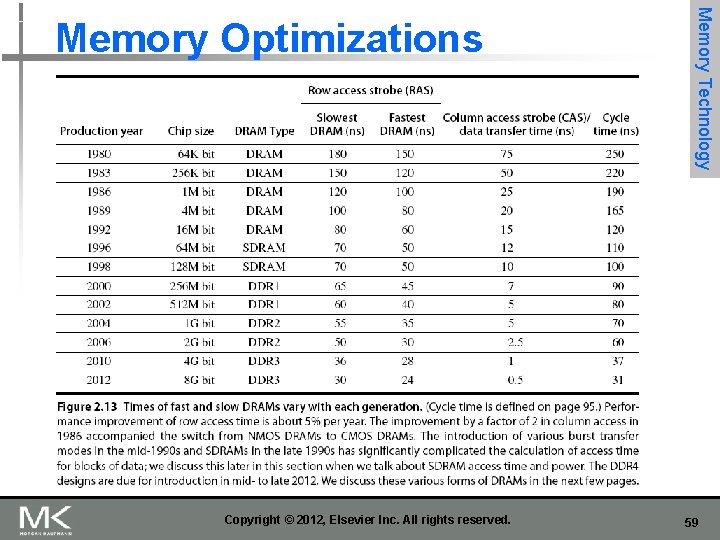
Copyright © 2012, Elsevier Inc. All rights reserved. Memory Technology Memory Optimizations 59
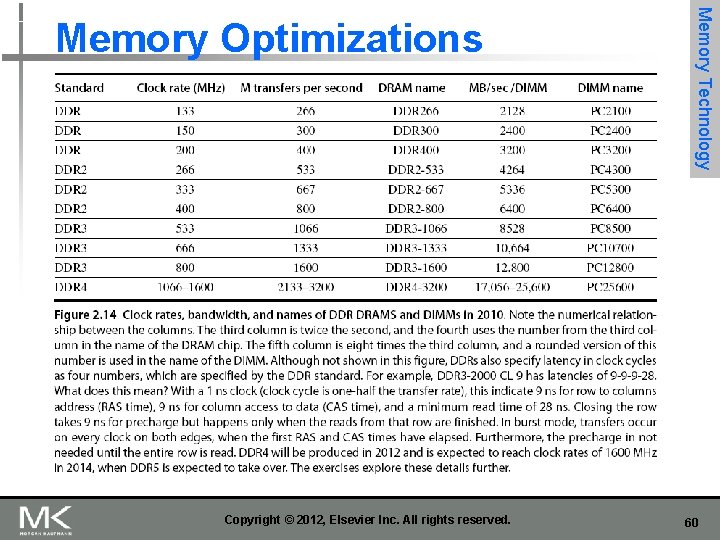
Copyright © 2012, Elsevier Inc. All rights reserved. Memory Technology Memory Optimizations 60
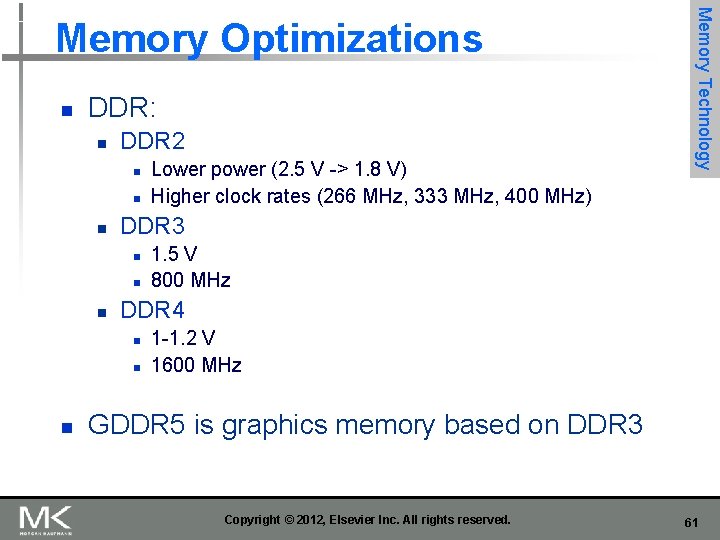
n DDR: n DDR 2 n n n DDR 3 n n n 1. 5 V 800 MHz DDR 4 n n n Lower power (2. 5 V -> 1. 8 V) Higher clock rates (266 MHz, 333 MHz, 400 MHz) Memory Technology Memory Optimizations 1 -1. 2 V 1600 MHz GDDR 5 is graphics memory based on DDR 3 Copyright © 2012, Elsevier Inc. All rights reserved. 61
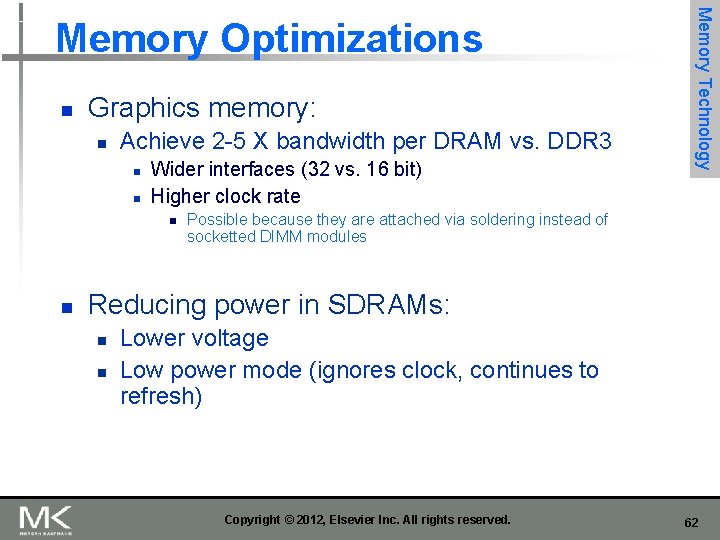
n Graphics memory: n Achieve 2 -5 X bandwidth per DRAM vs. DDR 3 n n Wider interfaces (32 vs. 16 bit) Higher clock rate n n Memory Technology Memory Optimizations Possible because they are attached via soldering instead of socketted DIMM modules Reducing power in SDRAMs: n n Lower voltage Low power mode (ignores clock, continues to refresh) Copyright © 2012, Elsevier Inc. All rights reserved. 62
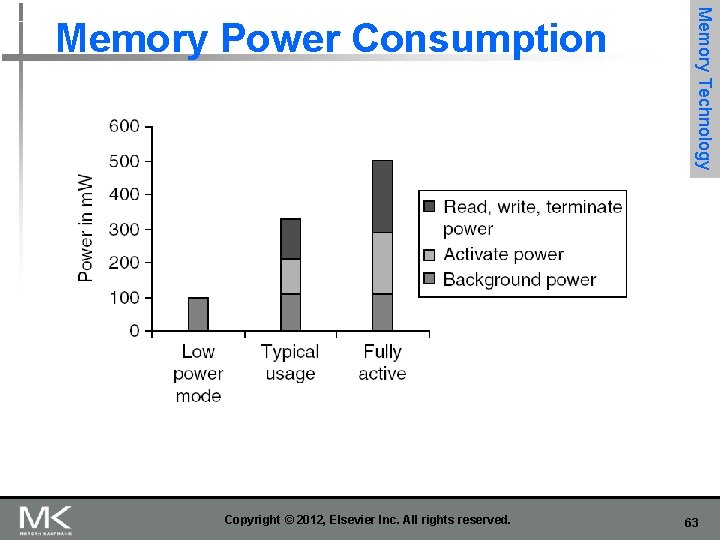
Copyright © 2012, Elsevier Inc. All rights reserved. Memory Technology Memory Power Consumption 63
n n n Type of EEPROM Must be erased (in blocks) before being overwritten Non volatile Limited number of write cycles Cheaper than SDRAM, more expensive than disk Slower than SRAM, faster than disk Copyright © 2012, Elsevier Inc. All rights reserved. Memory Technology Flash Memory 64
Flash Types n n n NOR flash: bit cell like a NOR gate n Random read/write access n Used for instruction memory in embedded systems NAND flash: bit cell like a NAND gate n Denser (bits/area), but block-at-a-time access n Cheaper GB n Used for USB keys, media storage, … Flash bits wears out after 1000’s of accesses n Not suitable for direct RAM or disk replacement n Wear leveling: remap data to less used blocks Copyright © 2012, Elsevier Inc. All rights reserved. 65
n n Memory is susceptible to cosmic rays Soft errors: dynamic errors n n Hard errors: permanent errors n n Detected and fixed by error correcting codes (ECC) Memory Technology Memory Dependability Use sparse rows to replace defective rows Chipkill: a RAID-like error recovery technique Copyright © 2012, Elsevier Inc. All rights reserved. 66
n Protection via virtual memory n n Keeps processes in their own memory space Role of architecture: n n n Provide user mode and supervisor mode Protect certain aspects of CPU state Provide mechanisms for switching between user mode and supervisor mode Provide mechanisms to limit memory accesses Provide TLB to translate addresses Copyright © 2012, Elsevier Inc. All rights reserved. Virtual Memory and Virtual Machines Virtual Memory 67
n n Supports isolation and security Sharing a computer among many unrelated users Enabled by raw speed of processors, making the overhead more acceptable Allows different ISAs and operating systems to be presented to user programs n n n “System Virtual Machines” SVM software is called “virtual machine monitor” or “hypervisor” Individual virtual machines run under the monitor are called “guest VMs” Copyright © 2012, Elsevier Inc. All rights reserved. Virtual Memory and Virtual Machines 68
n Each guest OS maintains its own set of page tables n n VMM adds a level of memory between physical and virtual memory called “real memory” VMM maintains shadow page table that maps guest virtual addresses to physical addresses n n Requires VMM to detect guest’s changes to its own page table Occurs naturally if accessing the page table pointer is a privileged operation Copyright © 2012, Elsevier Inc. All rights reserved. Virtual Memory and Virtual Machines Impact of VMs on Virtual Memory 69
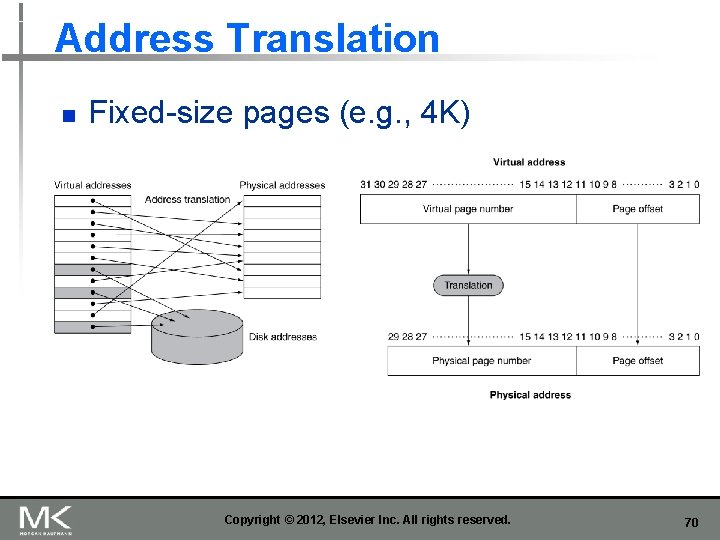
Address Translation n Fixed-size pages (e. g. , 4 K) Copyright © 2012, Elsevier Inc. All rights reserved. 70
Page Fault Penalty n On page fault, the page must be fetched from disk n n n Takes millions of clock cycles Handled by OS code Try to minimize page fault rate n n Fully associative placement Smart replacement algorithms Copyright © 2012, Elsevier Inc. All rights reserved. 71
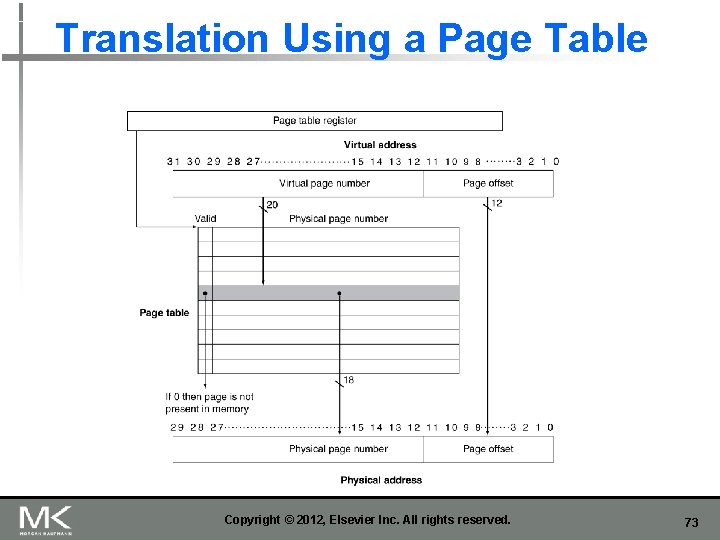
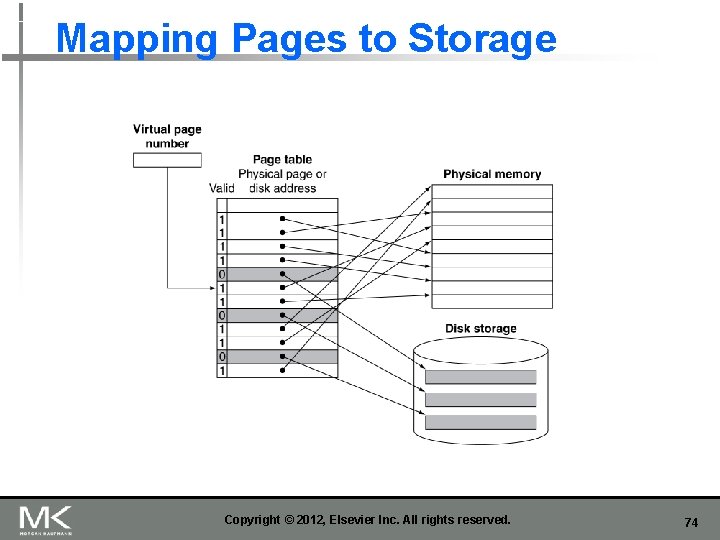
Page Tables n Stores placement information n If page is present in memory n n n Array of page table entries, indexed by virtual page number Page table register in CPU points to page table in physical memory PTE stores the physical page number Plus other status bits (referenced, dirty, …) If page is not present n PTE can refer to location in swap space on disk Copyright © 2012, Elsevier Inc. All rights reserved. 72
Translation Using a Page Table Copyright © 2012, Elsevier Inc. All rights reserved. 73
Mapping Pages to Storage Copyright © 2012, Elsevier Inc. All rights reserved. 74
Replacement and Writes n To reduce page fault rate, prefer leastrecently used (LRU) replacement n n Reference bit (aka use bit) in PTE set to 1 on access to page Periodically cleared to 0 by OS A page with reference bit = 0 has not been used recently Disk writes take millions of cycles n n Block at once, not individual locations Write through is impractical Use write-back Dirty bit in PTE set when page is written Copyright © 2012, Elsevier Inc. All rights reserved. 75
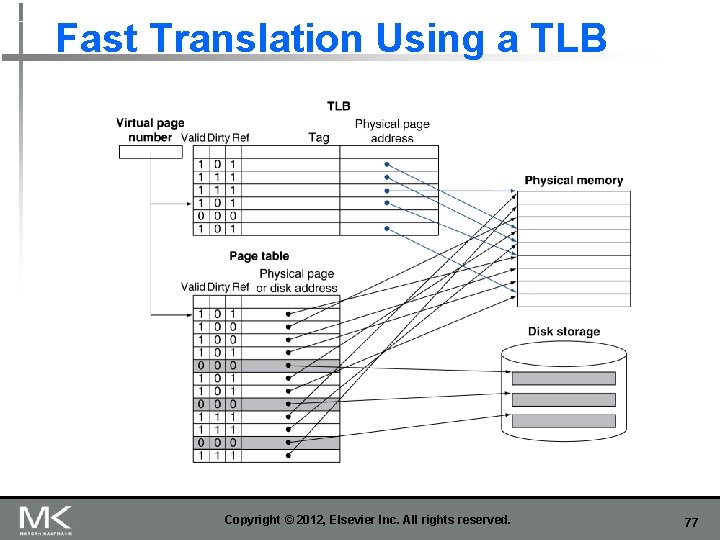
Fast Translation Using a TLB n n Address translation would appear to require extra memory references n One to access the PTE n Then the actual memory access But access to page tables has good locality n So use a fast cache of PTEs within the CPU n Called a Translation Look-aside Buffer (TLB) n Typical: 16– 512 PTEs, 0. 5– 1 cycle for hit, 10– 100 cycles for miss, 0. 01%– 1% miss rate n Misses could be handled by hardware or software Copyright © 2012, Elsevier Inc. All rights reserved. 76
Fast Translation Using a TLB Copyright © 2012, Elsevier Inc. All rights reserved. 77
TLB Misses n If page is in memory n n Load the PTE from memory and retry Could be handled in hardware n n Or in software n n Can get complex for more complicated page table structures Raise a special exception, with optimized handler If page is not in memory (page fault) n n OS handles fetching the page and updating the page table Then restart the faulting instruction Copyright © 2012, Elsevier Inc. All rights reserved. 78
TLB Miss Handler n TLB miss indicates n n n Must recognize TLB miss before destination register overwritten n n Page present, but PTE not in TLB Page not preset Raise exception Handler copies PTE from memory to TLB n n Then restarts instruction If page not present, page fault will occur Copyright © 2012, Elsevier Inc. All rights reserved. 79
Page Fault Handler n n n Use faulting virtual address to find PTE Locate page on disk Choose page to replace n n n If dirty, write to disk first Read page into memory and update page table Make process runnable again n Restart from faulting instruction Copyright © 2012, Elsevier Inc. All rights reserved. 80
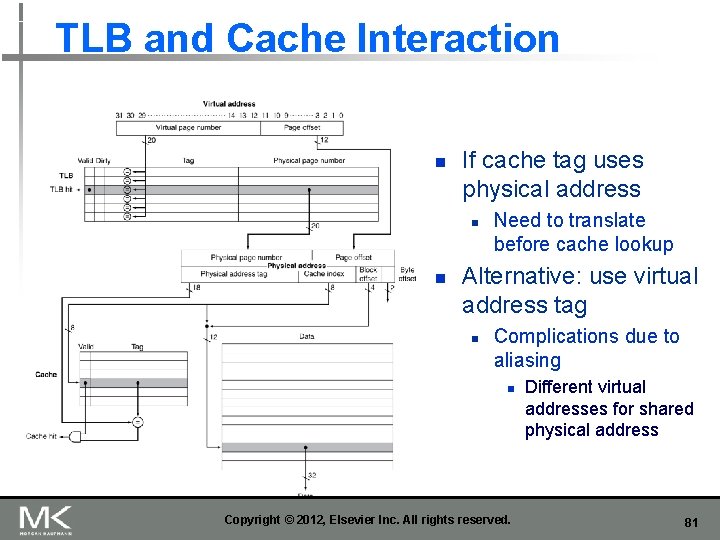
TLB and Cache Interaction n If cache tag uses physical address n n Need to translate before cache lookup Alternative: use virtual address tag n Complications due to aliasing n Copyright © 2012, Elsevier Inc. All rights reserved. Different virtual addresses for shared physical address 81
Memory Protection n Different tasks can share parts of their virtual address spaces n n n But need to protect against errant access Requires OS assistance Hardware support for OS protection n n Privileged supervisor mode (aka kernel mode) Privileged instructions Page tables and other state information only accessible in supervisor mode System call exception (e. g. , syscall in MIPS) Copyright © 2012, Elsevier Inc. All rights reserved. 82