Outline Parallel computing with GPU NVIDIA CUDA SVD


- Slides: 27
Outline • • Parallel computing with GPU NVIDIA CUDA SVD matrix computation Conclusion 6/9/2021 ICAL 2
Parallel computing with GPU • • • Parallel computing Flynn’s Taxonomy Algorithm decomposed Amdahl’s Law Correctness concepts 6/9/2021 ICAL 3
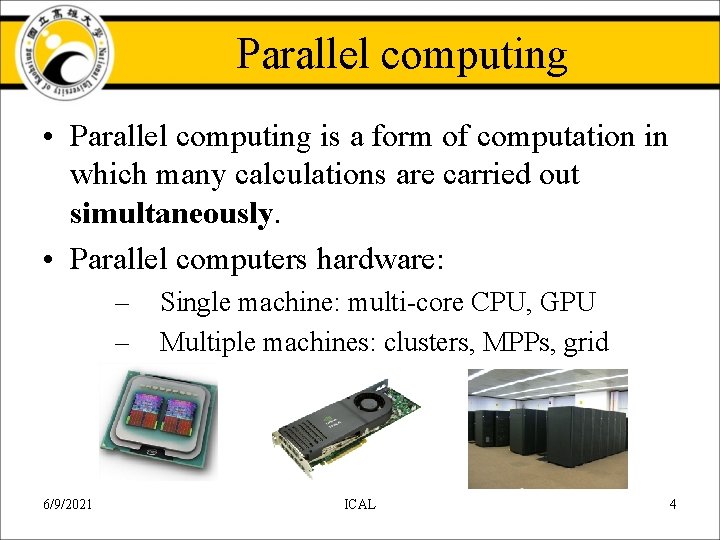
Parallel computing • Parallel computing is a form of computation in which many calculations are carried out simultaneously. • Parallel computers hardware: – – 6/9/2021 Single machine: multi-core CPU, GPU Multiple machines: clusters, MPPs, grid ICAL 4
Parallel computing (cont. ) • There are several kinds of parallel computing, such as: – Bit-level – Instruction level – Data decomposed – Task decomposed • The parallel computing has the speedup limit. 6/9/2021 ICAL 5
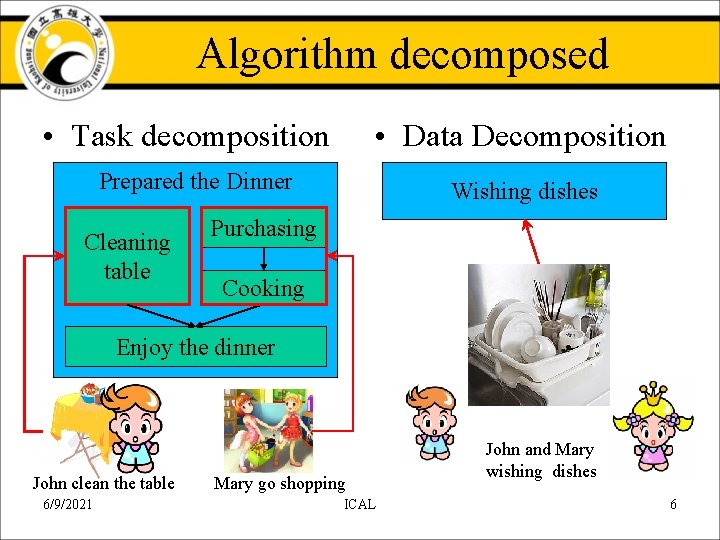
Algorithm decomposed • Task decomposition • Data Decomposition Prepared the Dinner Cleaning table Wishing dishes Purchasing Cooking Enjoy the dinner John clean the table 6/9/2021 Mary go shopping ICAL John and Mary wishing dishes 6
Flynn’s Taxonomy 6/9/2021 ICAL 7
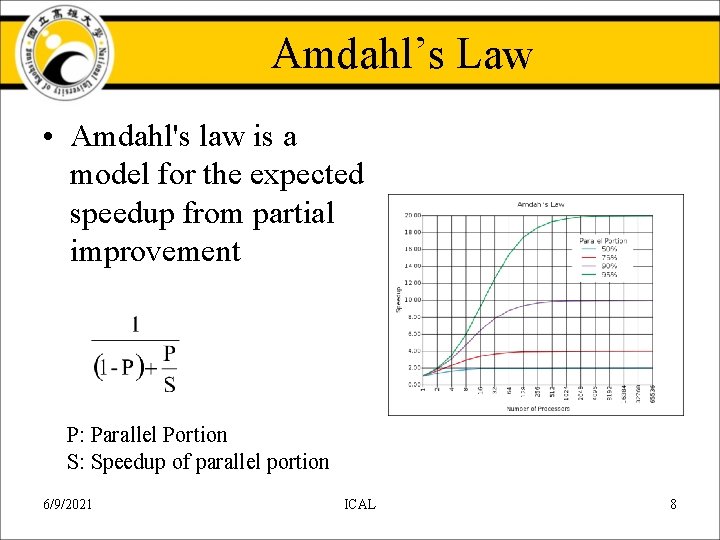
Amdahl’s Law • Amdahl's law is a model for the expected speedup from partial improvement P: Parallel Portion S: Speedup of parallel portion 6/9/2021 ICAL 8
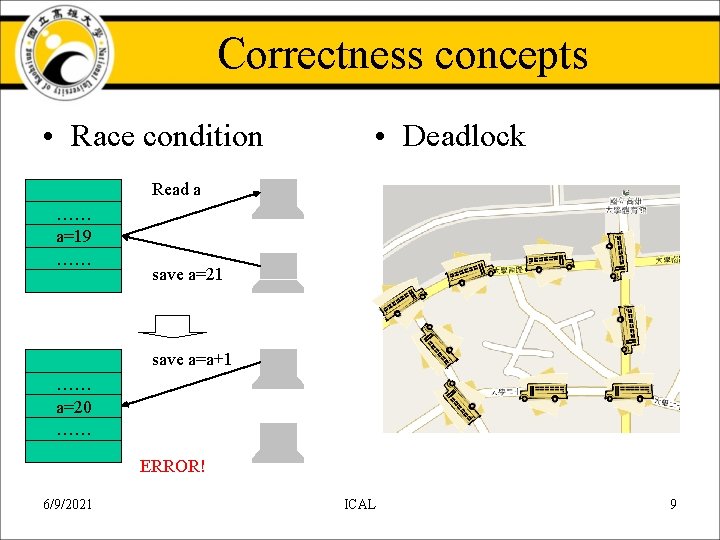
Correctness concepts • Race condition • Deadlock Read a …… a=19 …… save a=21 save a=a+1 …… a=20 …… ERROR! 6/9/2021 ICAL 9
NVIDIA CUDA • • Historical Trends CUDA Programming Languages Reported Speedup 6/9/2021 ICAL 10
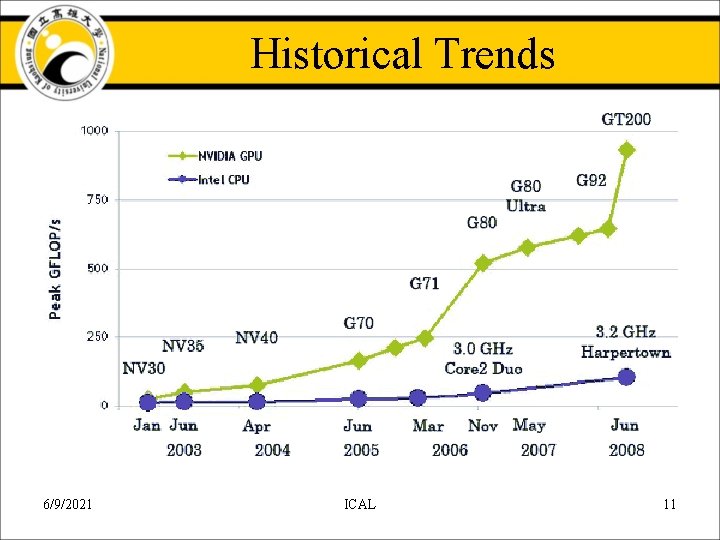
Historical Trends 6/9/2021 ICAL 11
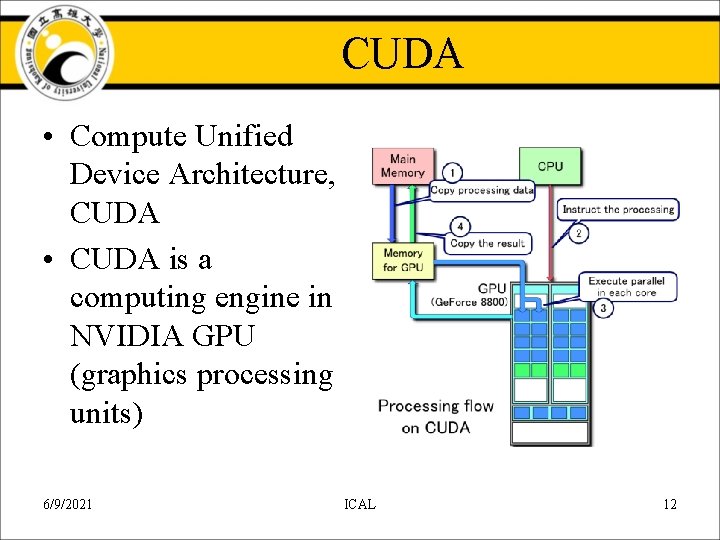
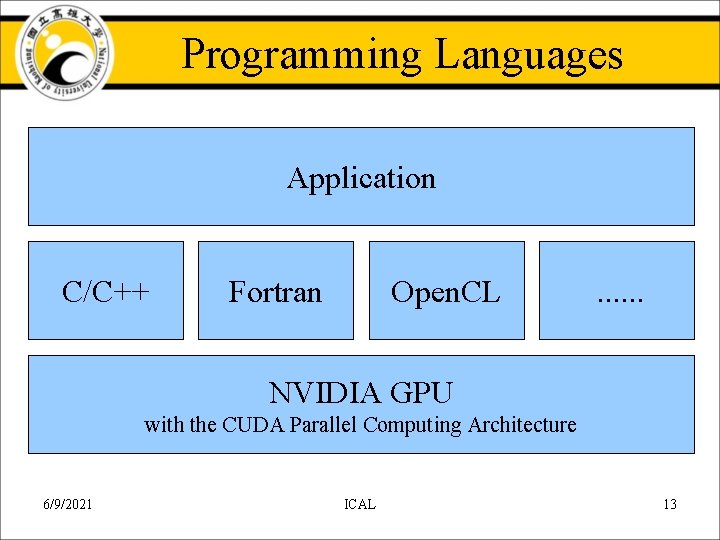
CUDA • Compute Unified Device Architecture, CUDA • CUDA is a computing engine in NVIDIA GPU (graphics processing units) 6/9/2021 ICAL 12
Programming Languages Application C/C++ Fortran Open. CL . . . NVIDIA GPU with the CUDA Parallel Computing Architecture 6/9/2021 ICAL 13
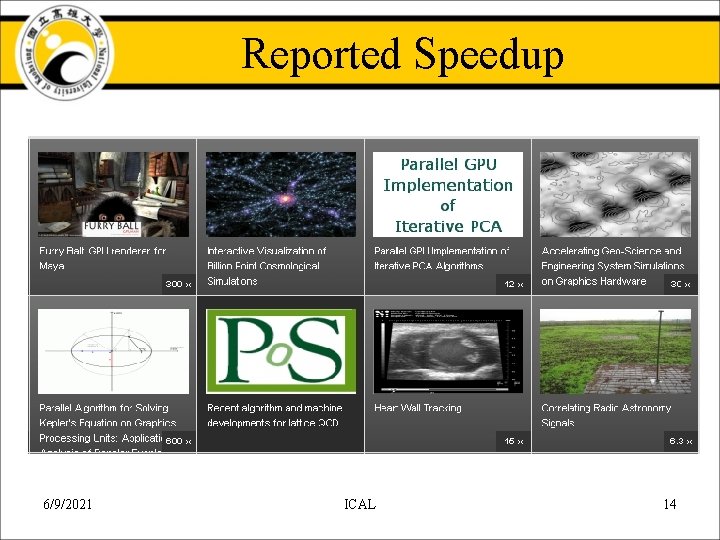
Reported Speedup 6/9/2021 ICAL 14
CUDA Architecture • • • Physical Reality behind CUDA Architectures Introducing the “Fermi” Architecture SM Architecture CUDA Core Architecture 6/9/2021 ICAL 15
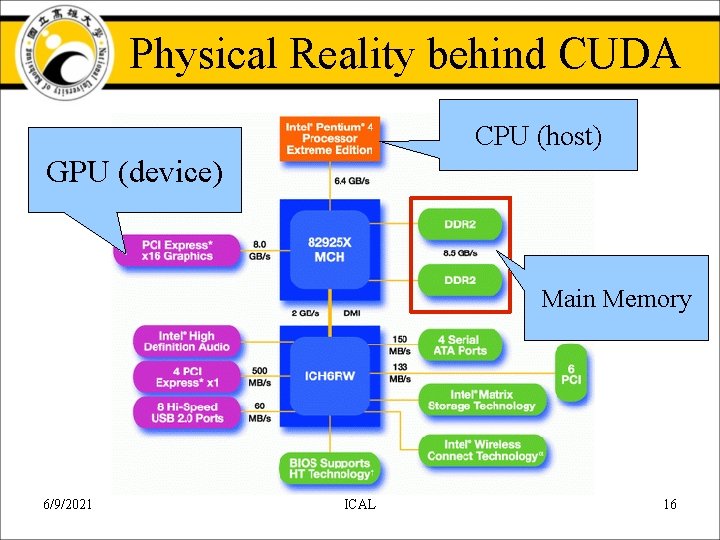
Physical Reality behind CUDA CPU (host) GPU (device) Main Memory 6/9/2021 ICAL 16
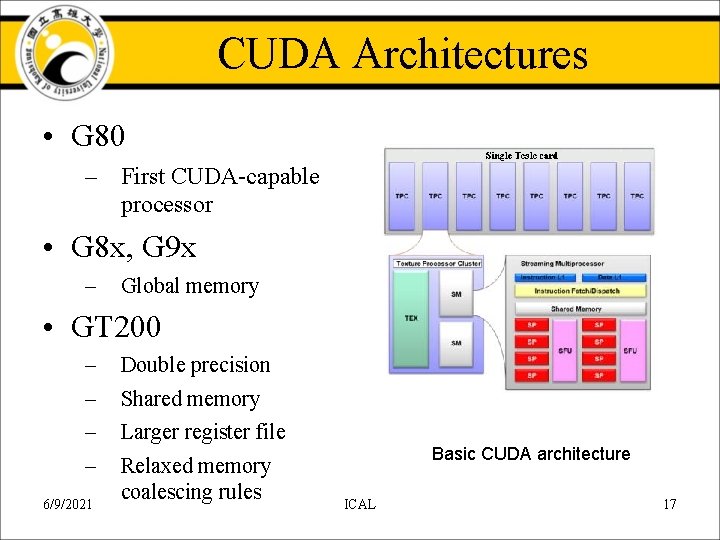
CUDA Architectures • G 80 – First CUDA-capable processor • G 8 x, G 9 x – Global memory • GT 200 – – 6/9/2021 Double precision Shared memory Larger register file Relaxed memory coalescing rules Basic CUDA architecture ICAL 17
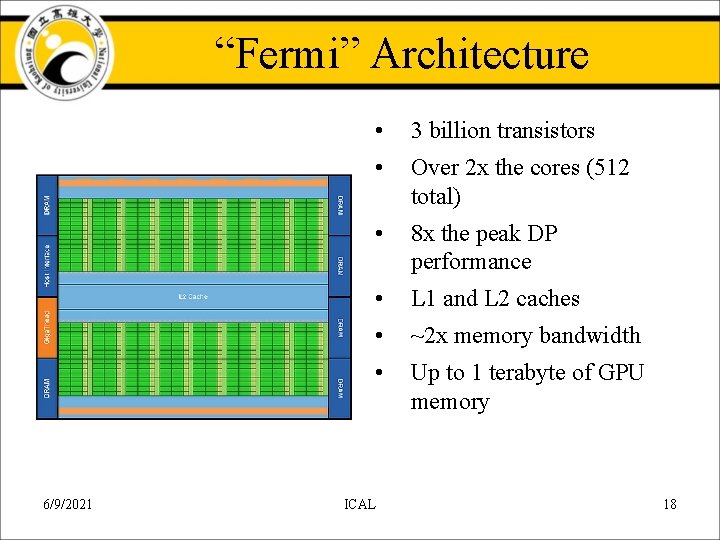
“Fermi” Architecture 6/9/2021 • 3 billion transistors • Over 2 x the cores (512 total) • 8 x the peak DP performance • L 1 and L 2 caches • ~2 x memory bandwidth • Up to 1 terabyte of GPU memory ICAL 18
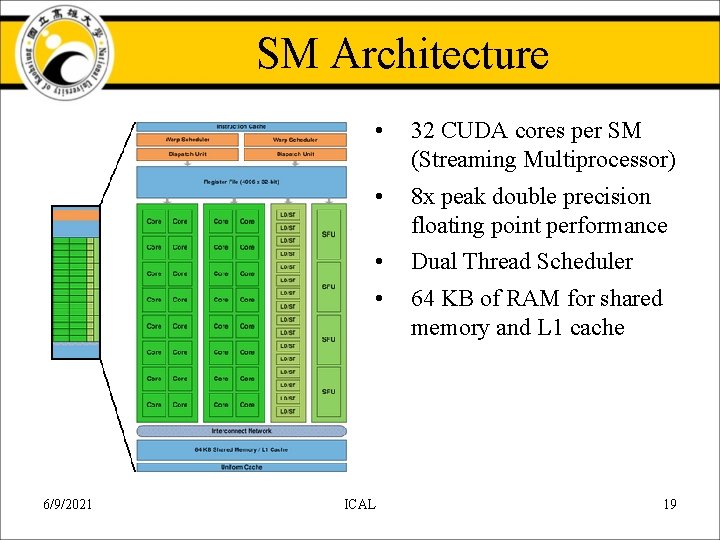
SM Architecture 6/9/2021 • 32 CUDA cores per SM (Streaming Multiprocessor) • 8 x peak double precision floating point performance • Dual Thread Scheduler • 64 KB of RAM for shared memory and L 1 cache ICAL 19
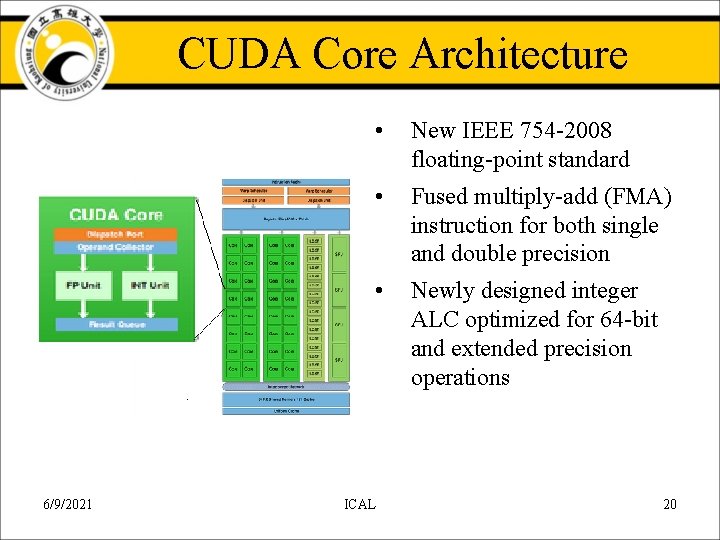
CUDA Core Architecture 6/9/2021 • New IEEE 754 -2008 floating-point standard • Fused multiply-add (FMA) instruction for both single and double precision • Newly designed integer ALC optimized for 64 -bit and extended precision operations ICAL 20
SVD matrix computation • • • SVD matrix computation Experiment Datasets Experiment Environment Experiment Results 6/9/2021 ICAL 21
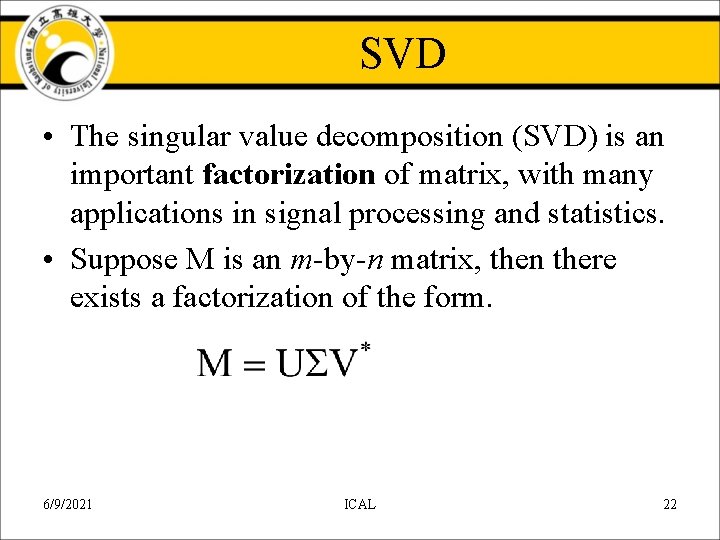
SVD • The singular value decomposition (SVD) is an important factorization of matrix, with many applications in signal processing and statistics. • Suppose M is an m-by-n matrix, then there exists a factorization of the form. 6/9/2021 ICAL 22
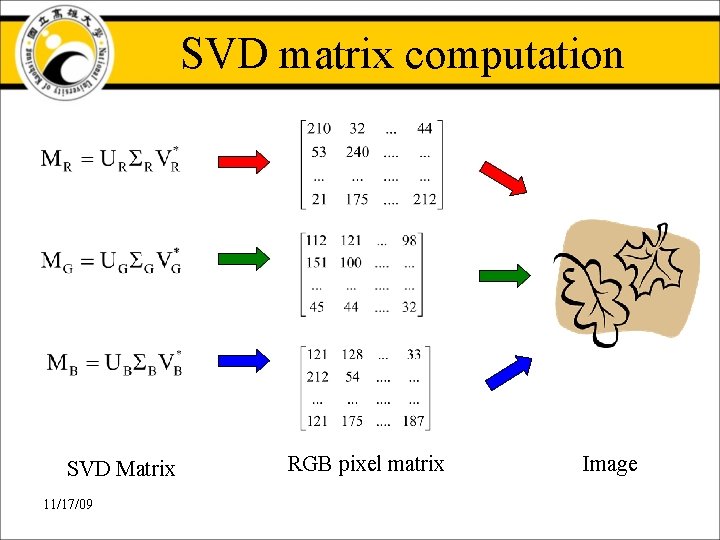
SVD matrix computation SVD Matrix 11/17/09 RGB pixel matrix Image
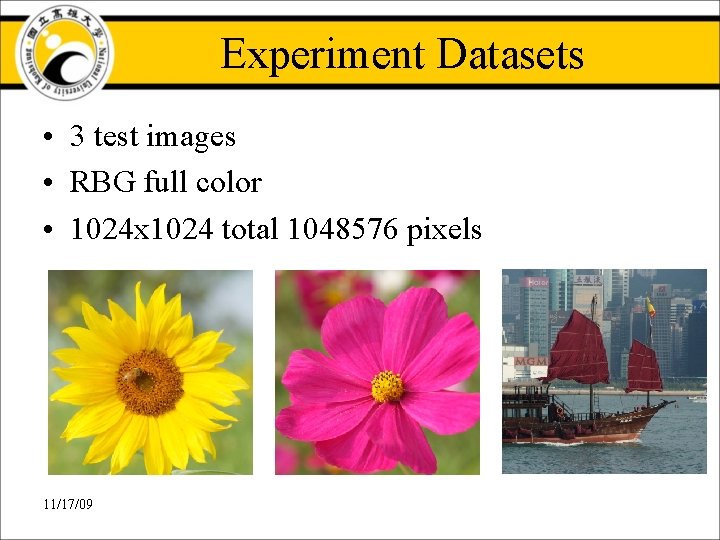
Experiment Datasets • 3 test images • RBG full color • 1024 x 1024 total 1048576 pixels 11/17/09
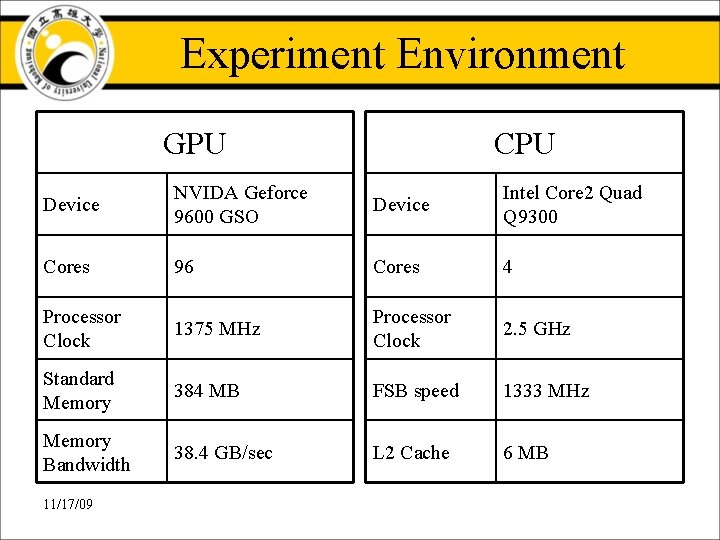
Experiment Environment GPU CPU Device NVIDA Geforce 9600 GSO Device Intel Core 2 Quad Q 9300 Cores 96 Cores 4 Processor Clock 1375 MHz Processor Clock 2. 5 GHz Standard Memory 384 MB FSB speed 1333 MHz Memory Bandwidth 38. 4 GB/sec L 2 Cache 6 MB 11/17/09
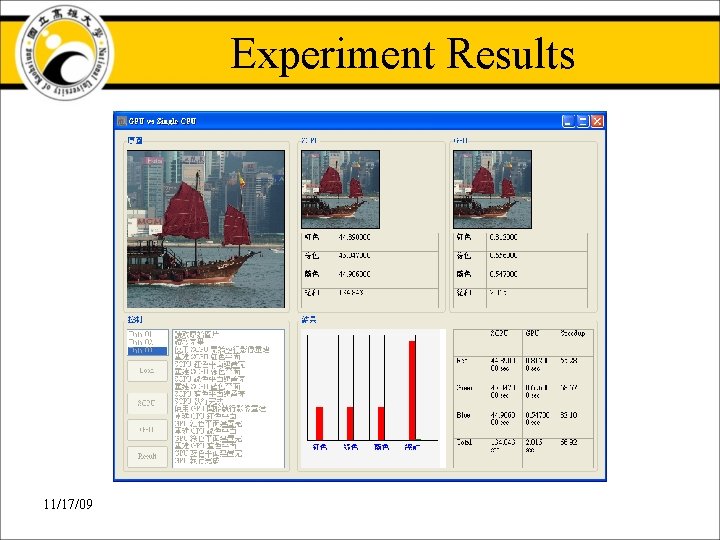
Experiment Results 11/17/09
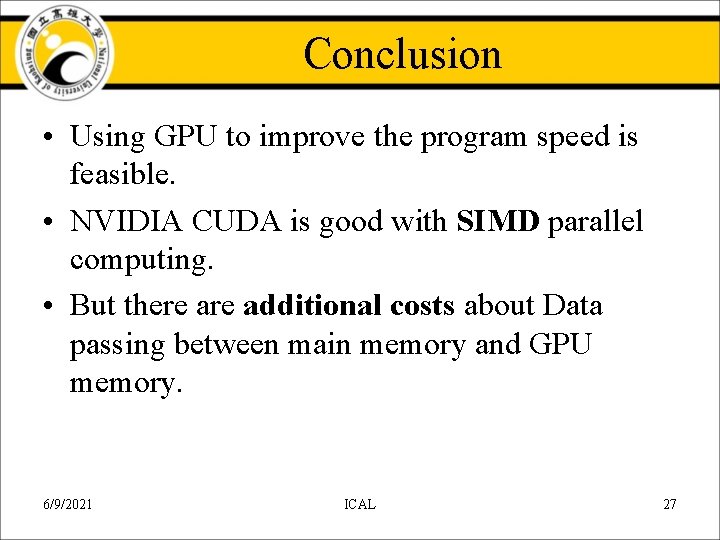
Conclusion • Using GPU to improve the program speed is feasible. • NVIDIA CUDA is good with SIMD parallel computing. • But there additional costs about Data passing between main memory and GPU memory. 6/9/2021 ICAL 27