Lecture 19 NN Regularization CS 109 A Introduction












- Slides: 29
Lecture 19: NN Regularization CS 109 A Introduction to Data Science Pavlos Protopapas and Kevin Rader
Outline Regularization of NN § § § Norm Penalties Early Stopping Data Augmentation Sparse Representation Bagging Dropout CS 109 A, PROTOPAPAS, RADER 2
Outline Regularization of NN § § § Norm Penalties Early Stopping Data Augmentation Sparse Representation Bagging Dropout CS 109 A, PROTOPAPAS, RADER 3
Regularization is any modification we make to a learning algorithm that is intended to reduce its generalization error but not its training error. CS 109 A, PROTOPAPAS, RADER 4
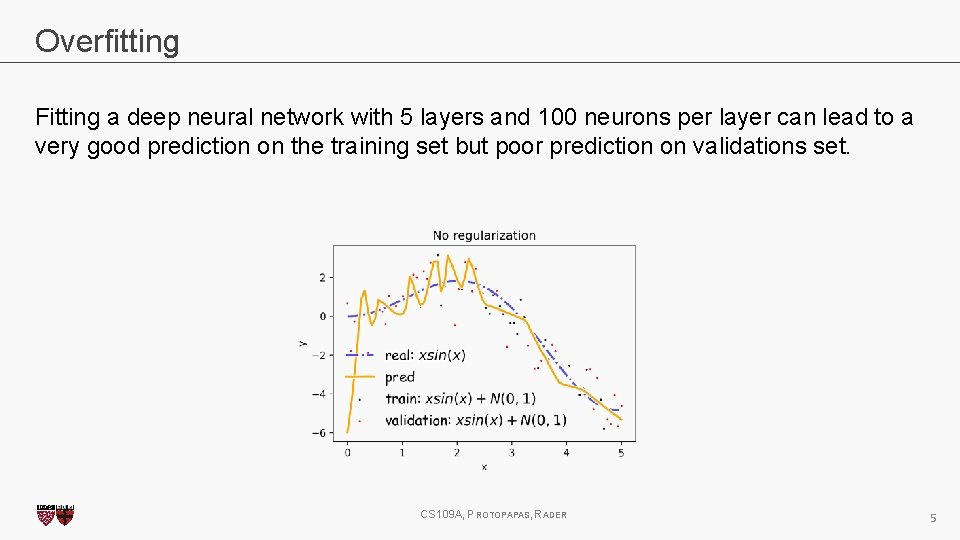
Overfitting Fitting a deep neural network with 5 layers and 100 neurons per layer can lead to a very good prediction on the training set but poor prediction on validations set. CS 109 A, PROTOPAPAS, RADER 5
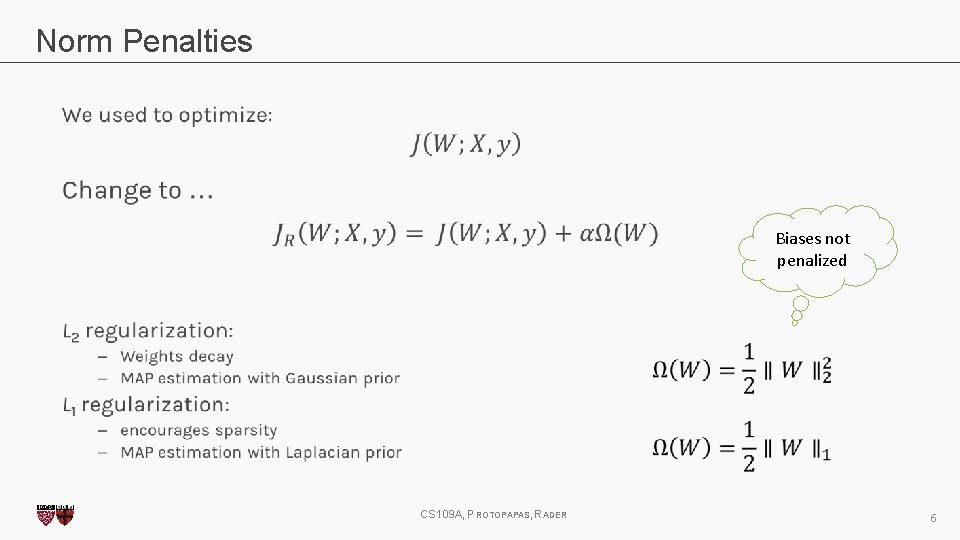
Norm Penalties Biases not penalized CS 109 A, PROTOPAPAS, RADER 6
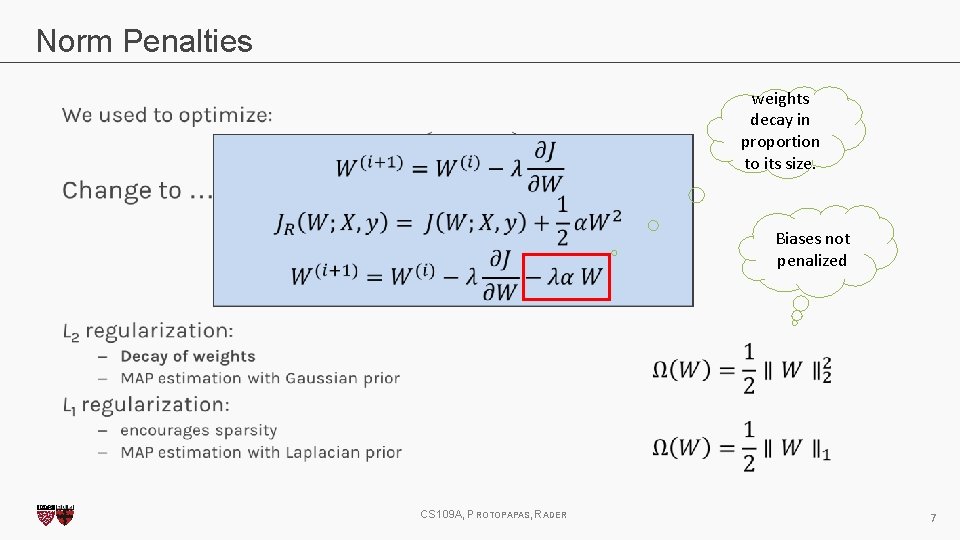
Norm Penalties weights decay in proportion to its size. Biases not penalized CS 109 A, PROTOPAPAS, RADER 7
Norm Penalties CS 109 A, PROTOPAPAS, RADER 8
Outline Regularization of NN § § § Norm Penalties Early Stopping Data Augmentation Sparse Representation Bagging Dropout CS 109 A, PROTOPAPAS, RADER 10
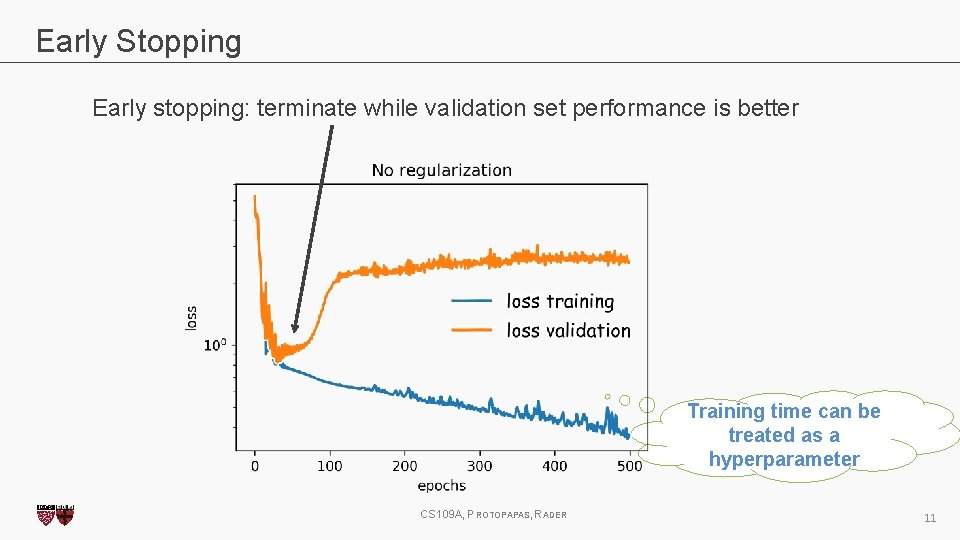
Early Stopping Early stopping: terminate while validation set performance is better Training time can be treated as a hyperparameter CS 109 A, PROTOPAPAS, RADER 11
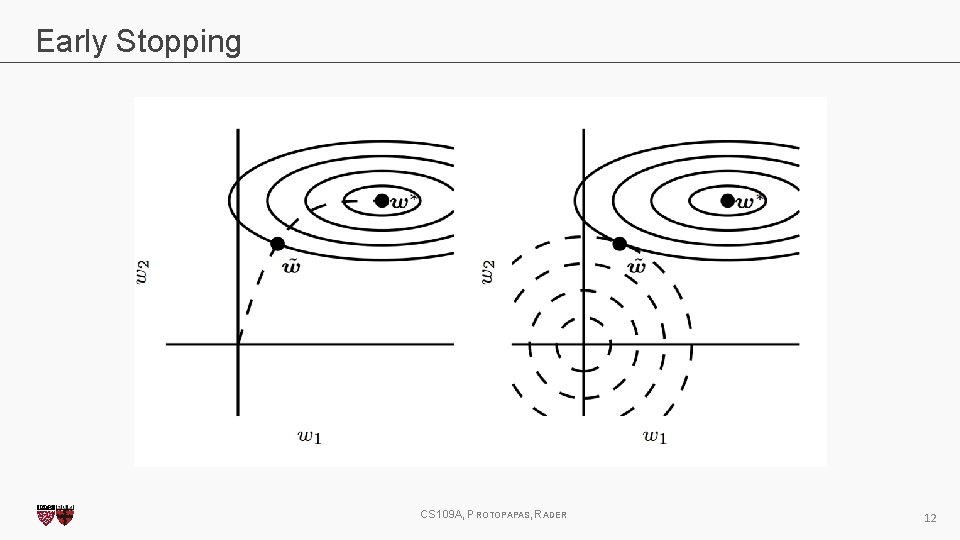
Early Stopping CS 109 A, PROTOPAPAS, RADER 12
Outline Regularization of NN § § § Norm Penalties Early Stopping Data Augmentation Sparse Representation Bagging Dropout CS 109 A, PROTOPAPAS, RADER 13
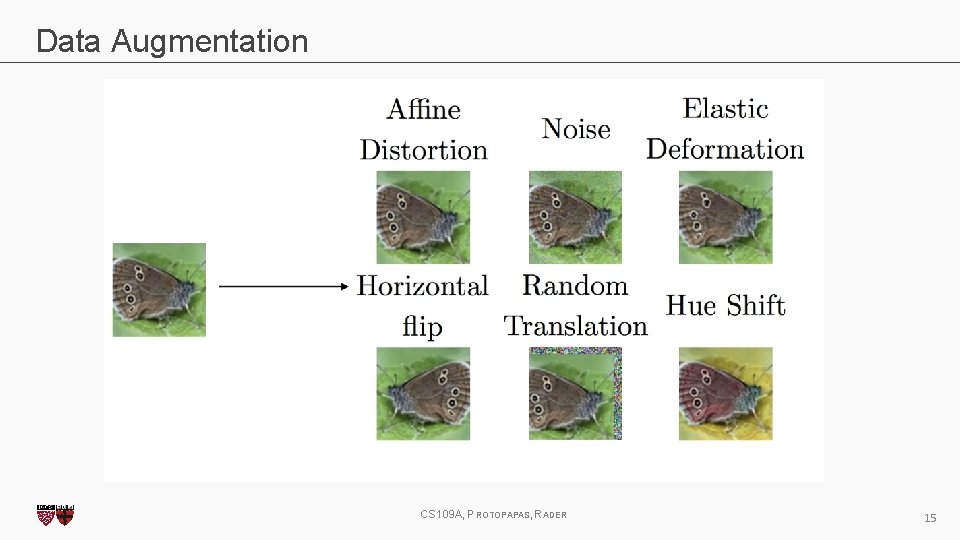
Data Augmentation CS 109 A, PROTOPAPAS, RADER 14
Data Augmentation CS 109 A, PROTOPAPAS, RADER 15
Outline Regularization of NN § § § Norm Penalties Early Stopping Data Augmentation Sparse Representation Bagging Dropout CS 109 A, PROTOPAPAS, RADER 16
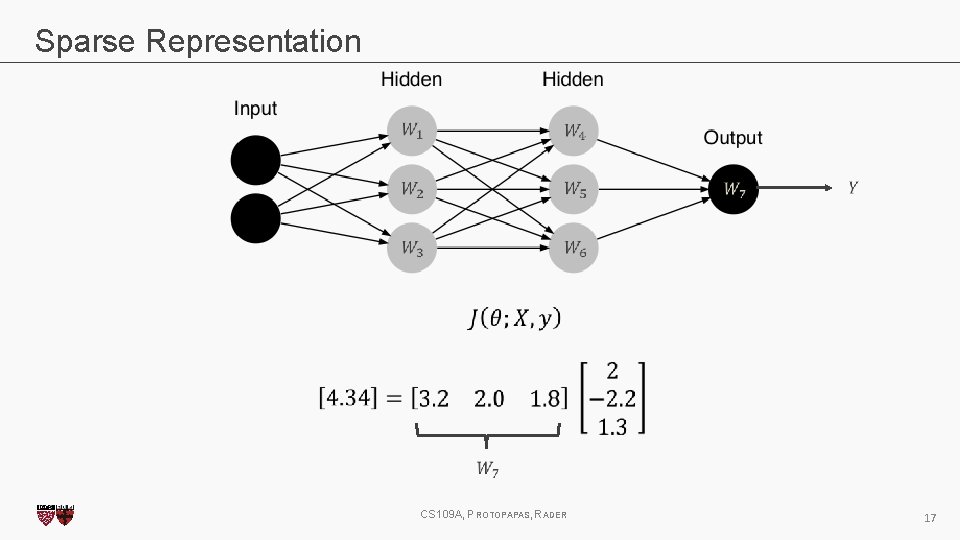
Sparse Representation CS 109 A, PROTOPAPAS, RADER 17
Sparse Representation Weights in output layer CS 109 A, PROTOPAPAS, RADER 18
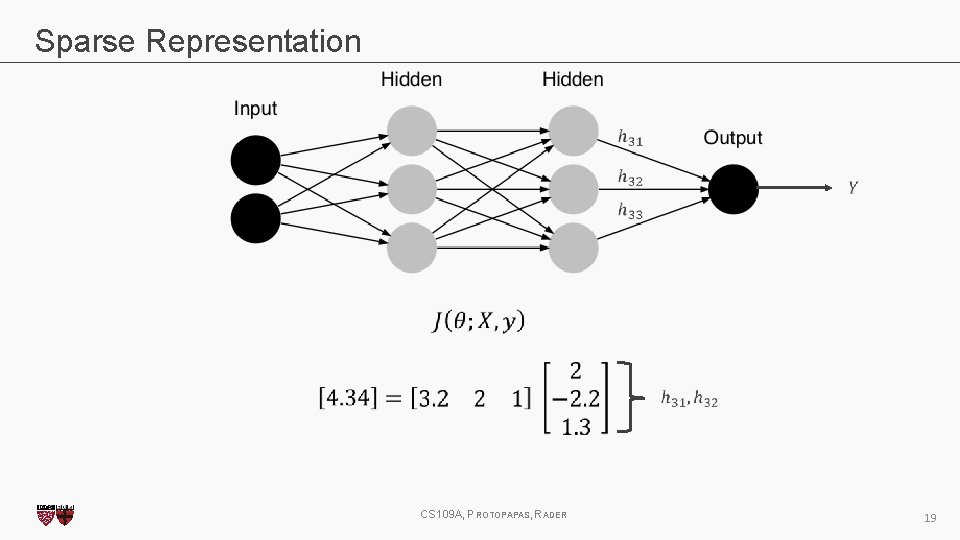
Sparse Representation CS 109 A, PROTOPAPAS, RADER 19
Sparse Representation Output of hidden layer CS 109 A, PROTOPAPAS, RADER 20
Outline Regularization of NN § § § Norm Penalties Early Stopping Data Augmentation Sparse Representation Bagging Dropout CS 109 A, PROTOPAPAS, RADER 21
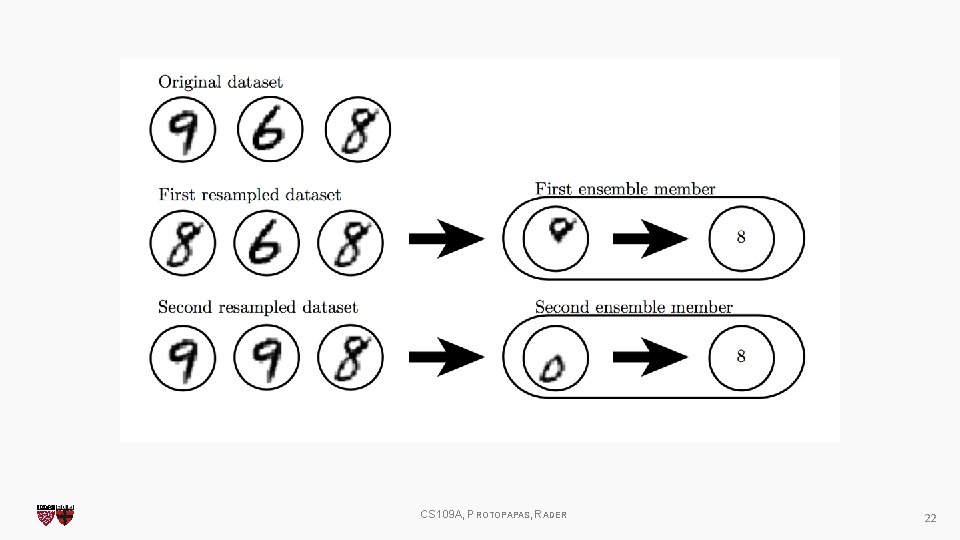
CS 109 A, PROTOPAPAS, RADER 22
Outline Regularization of NN § § § Norm Penalties Early Stopping Data Augmentation Sparse Representation Bagging Dropout CS 109 A, PROTOPAPAS, RADER 23
Noise Robustness Random perturbation of network weights • Gaussian noise: Equivalent to minimizing loss with regularization term • Encourages smooth function: small perturbation in weights leads to small changes in output Injecting noise in output labels • Better convergence: prevents pursuit of hard probabilities CS 109 A, PROTOPAPAS, RADER 24
Dropout Train all sub-networks obtained by removing nonoutput units from base network CS 109 A, PROTOPAPAS, RADER 25
Dropout: Stochastic GD For each new example/mini-batch: • Randomly sample a binary mask μ independently, where μi indicates if input/hidden node i is included • Multiply output of node i with μi, and perform gradient update Typically, an input node is included with prob=0. 8, hidden node with prob=0. 5. CS 109 A, PROTOPAPAS, RADER 26
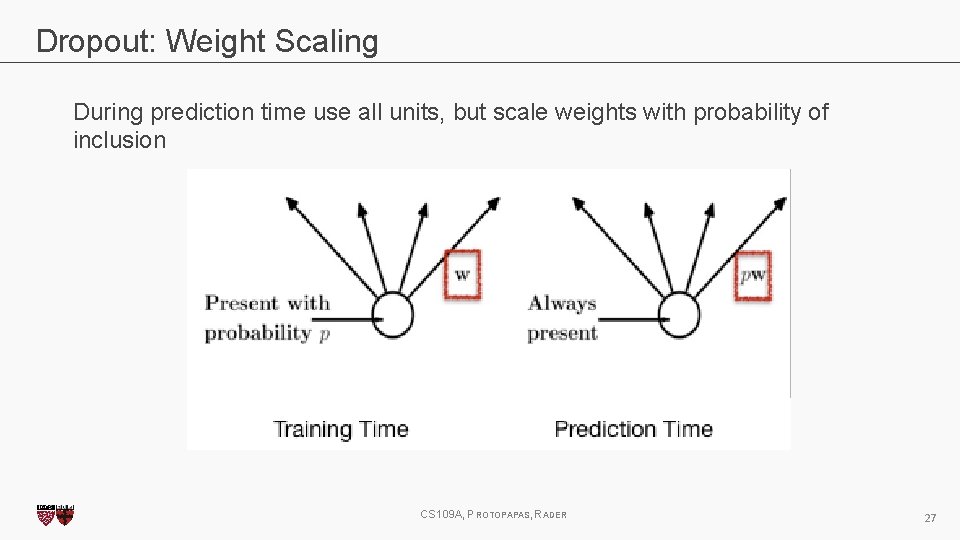
Dropout: Weight Scaling During prediction time use all units, but scale weights with probability of inclusion CS 109 A, PROTOPAPAS, RADER 27
Adversarial Examples CS 109 A, PROTOPAPAS, RADER 28
Adversarial Examples Panda 57% confidence noise Gibbon 99. 3% confidence Training on adversarial examples is mostly intended to improve security, but can sometimes provide generic regularization. CS 109 A, PROTOPAPAS, RADER 29
Recap Regularization of NN § § § Norm Penalties Early Stopping Data Augmentation Sparse Representation Bagging Dropout CS 109 A, PROTOPAPAS, RADER 30