CV 192 Spatial Transformer Networks Oren Freifeld Ron
- Slides: 33
CV 192: Spatial Transformer Networks Oren Freifeld Ron Shapira Weber Computer Science, Ben-Gurion University
Contents • A short review • Spatial Transformer Networks • Inverse-Compositional Spatial Transformer Networks Special thank to Asher Fredman who helped creating this presentation
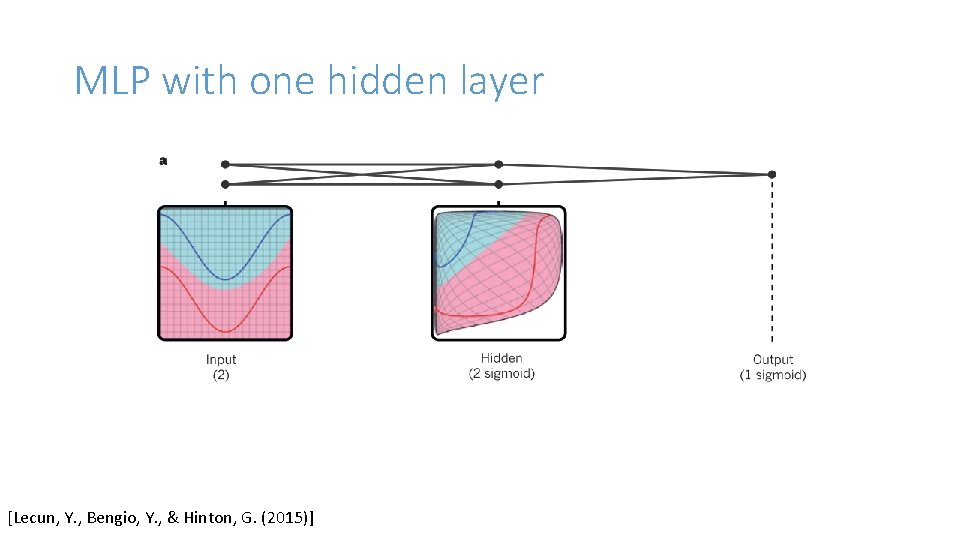
MLP with one hidden layer [Lecun, Y. , Bengio, Y. , & Hinton, G. (2015)]
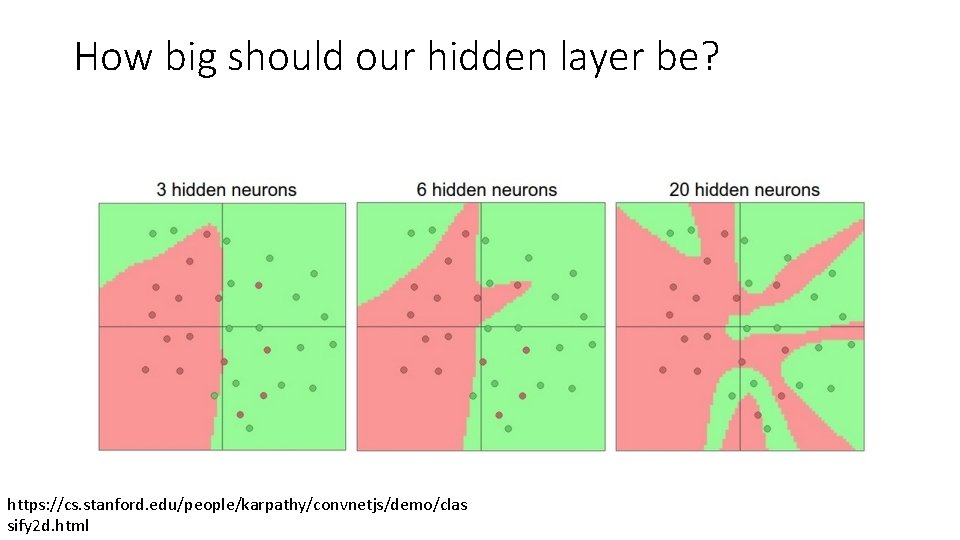
How big should our hidden layer be? https: //cs. stanford. edu/people/karpathy/convnetjs/demo/clas sify 2 d. html
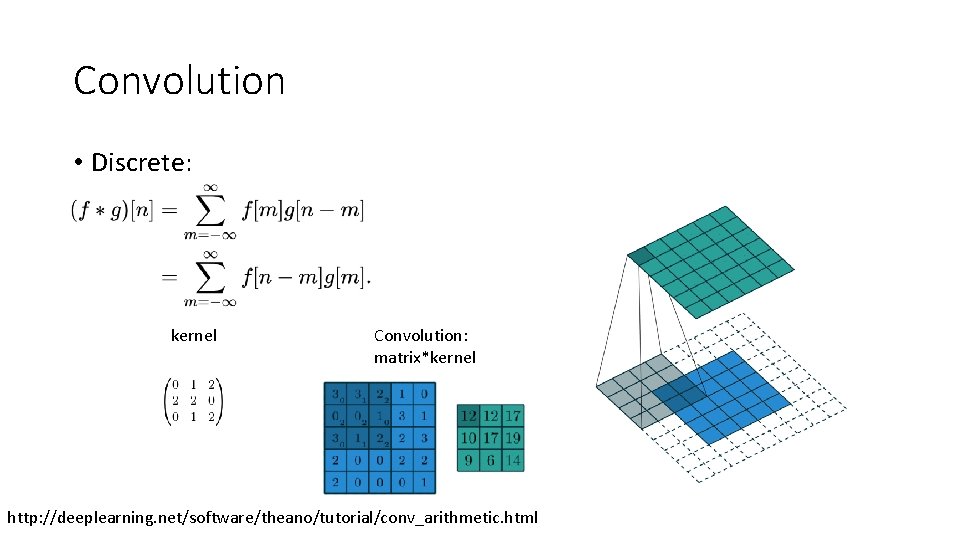
Convolution • Discrete: kernel Convolution: matrix*kernel http: //deeplearning. net/software/theano/tutorial/conv_arithmetic. html
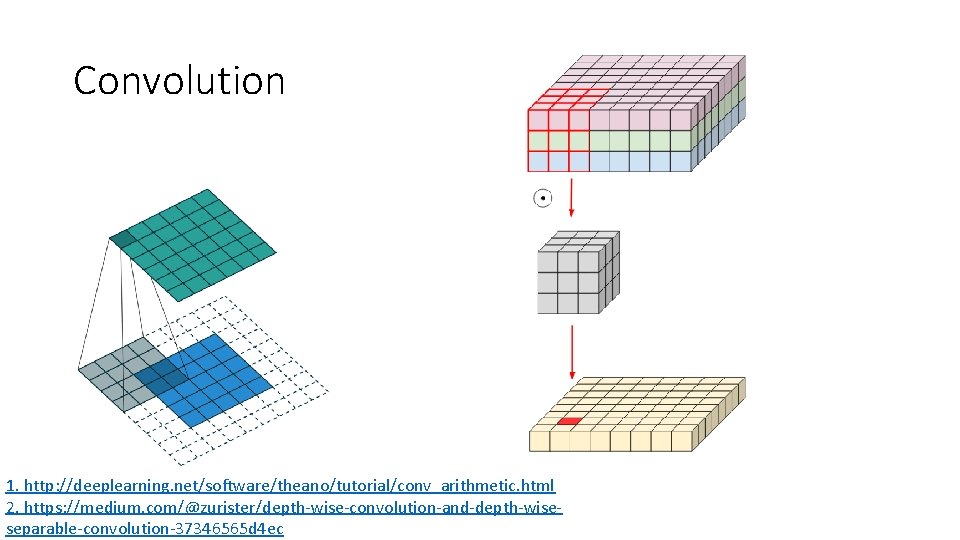
Convolution 1. http: //deeplearning. net/software/theano/tutorial/conv_arithmetic. html 2. https: //medium. com/@zurister/depth-wise-convolution-and-depth-wiseseparable-convolution-37346565 d 4 ec
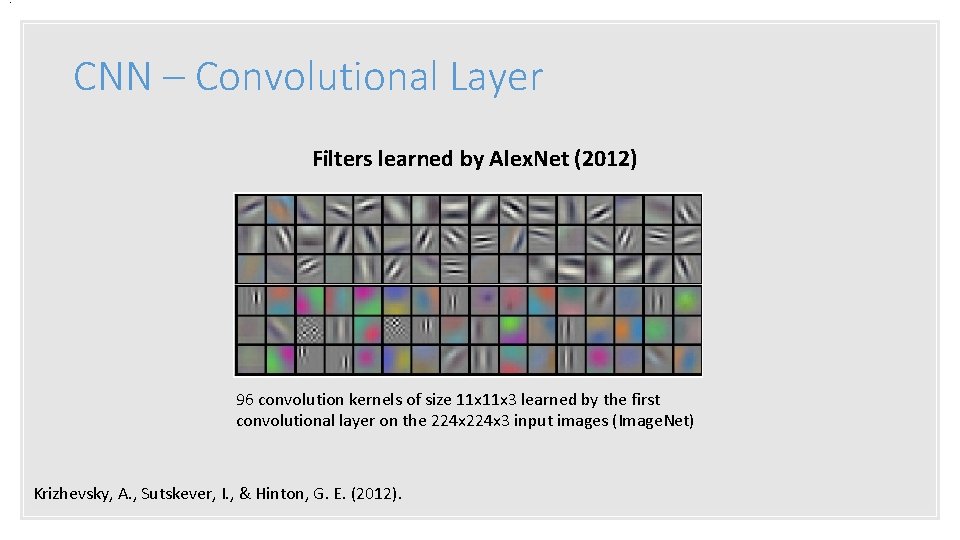
. CNN – Convolutional Layer Filters learned by Alex. Net (2012) 96 convolution kernels of size 11 x 3 learned by the first convolutional layer on the 224 x 3 input images (Image. Net) Krizhevsky, A. , Sutskever, I. , & Hinton, G. E. (2012).
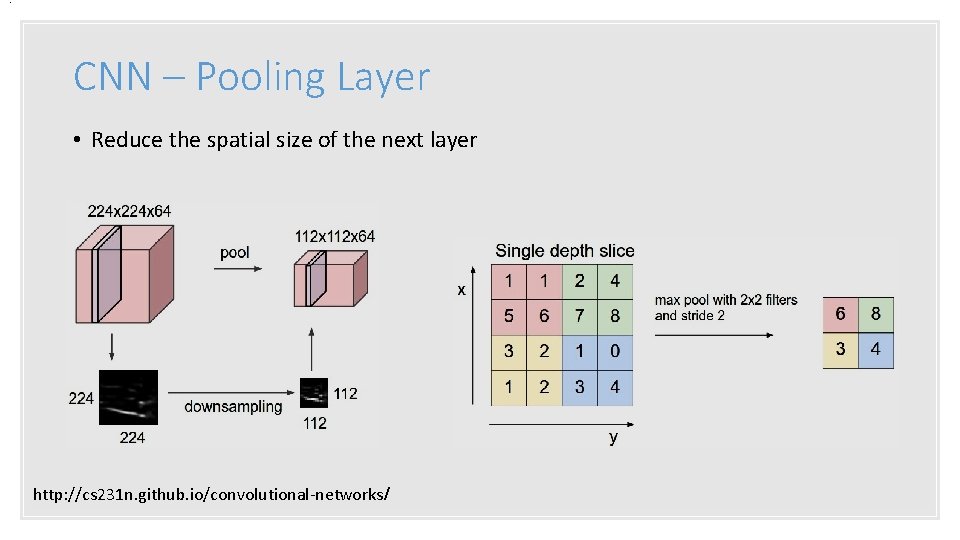
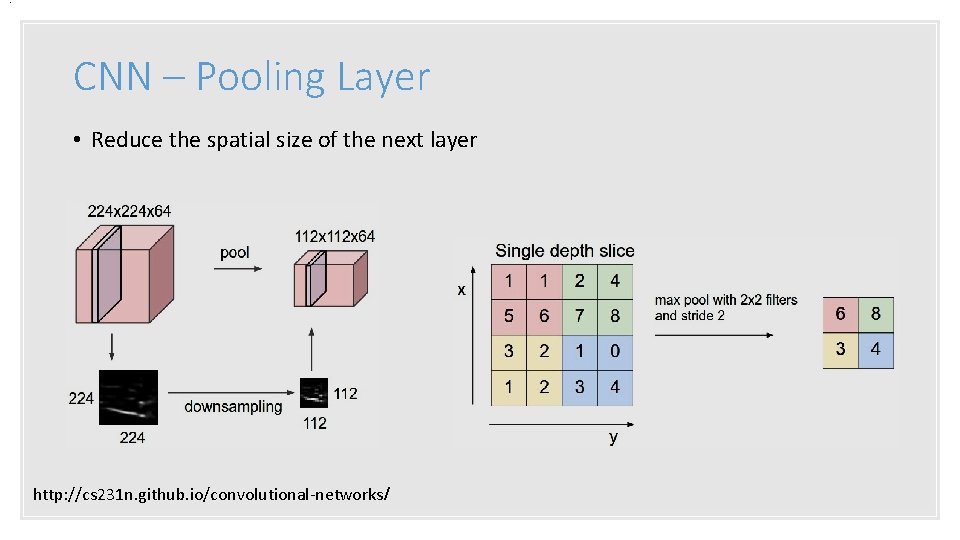
. CNN – Pooling Layer • Reduce the spatial size of the next layer http: //cs 231 n. github. io/convolutional-networks/
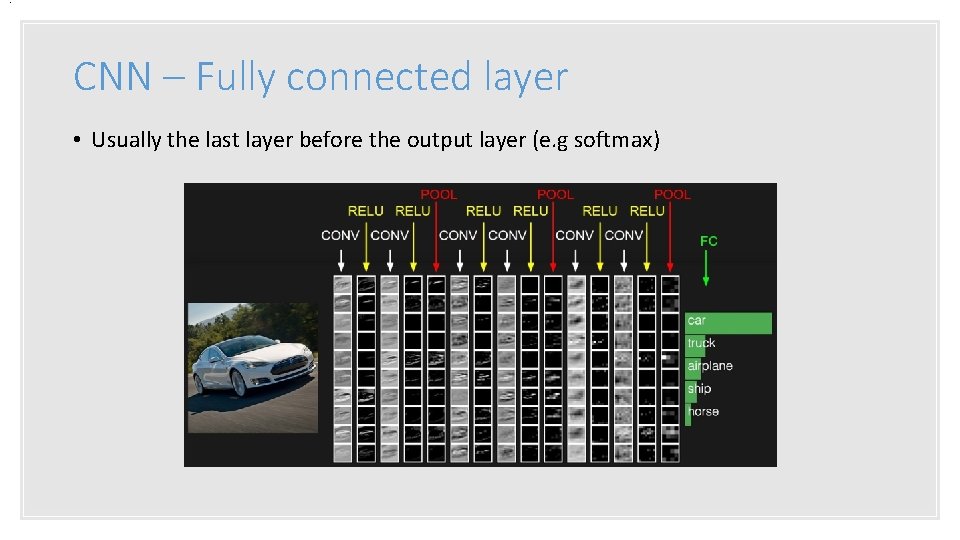
. CNN – Fully connected layer • Usually the last layer before the output layer (e. g softmax)
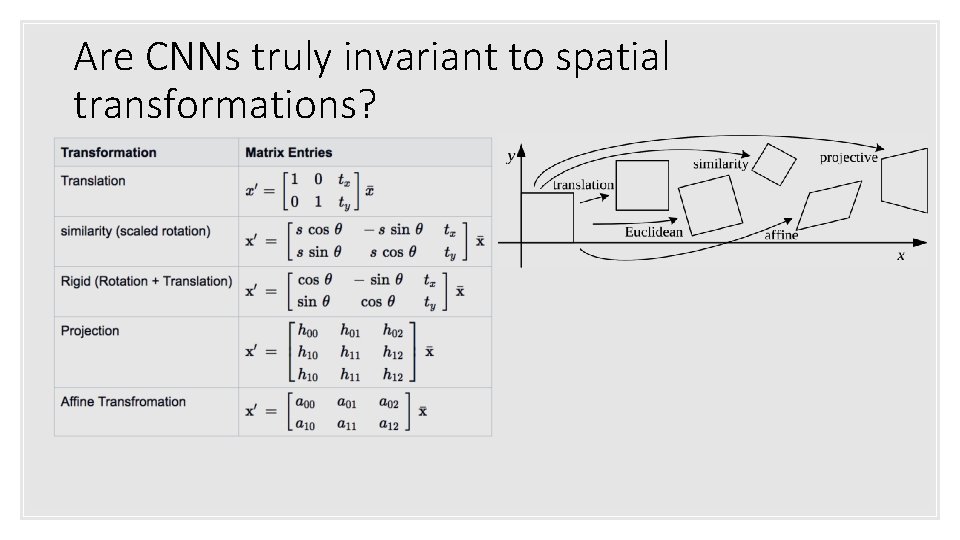
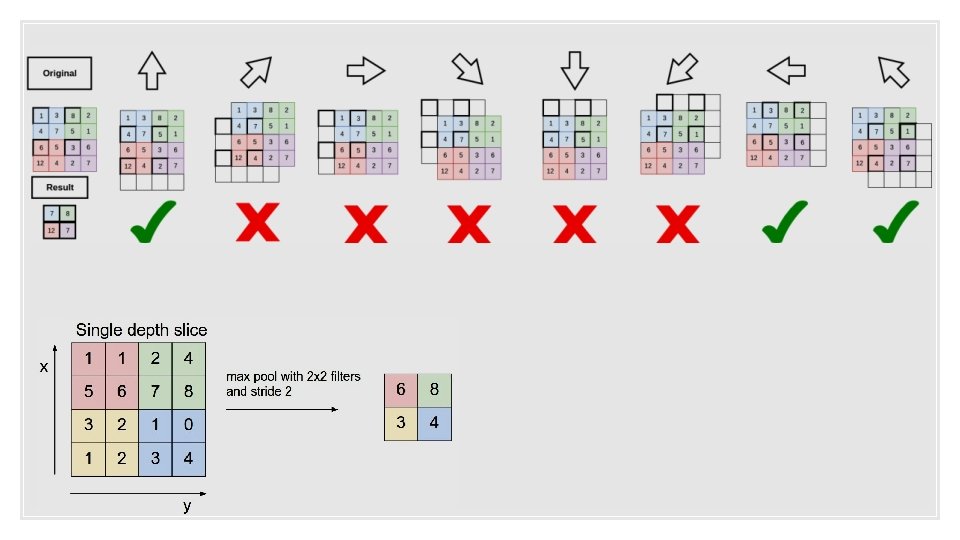
Are CNNs truly invariant to spatial transformations?
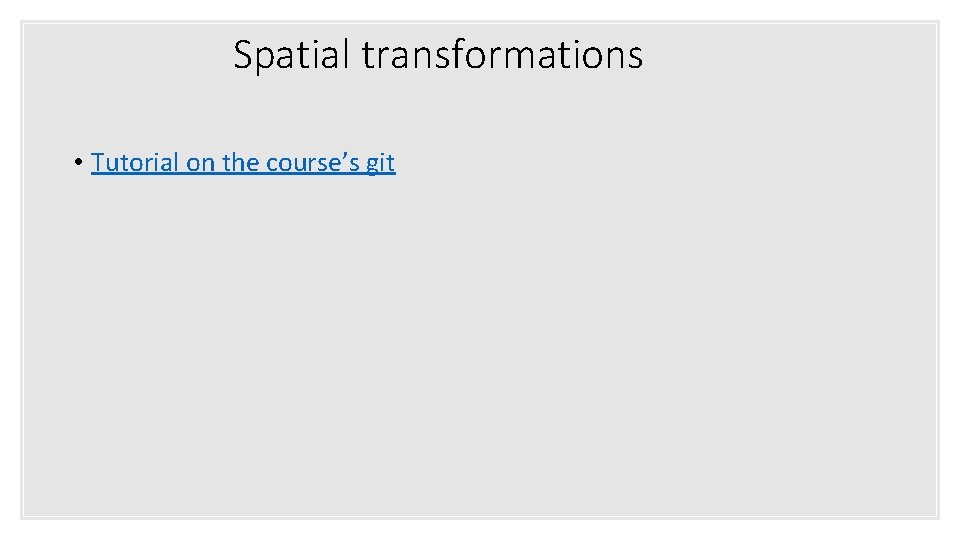
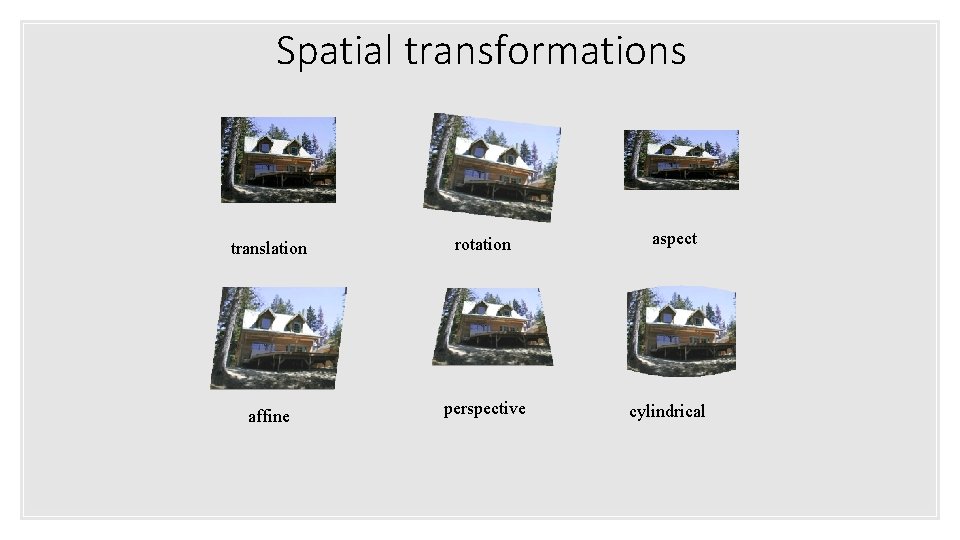
Spatial transformations • Tutorial on the course’s git
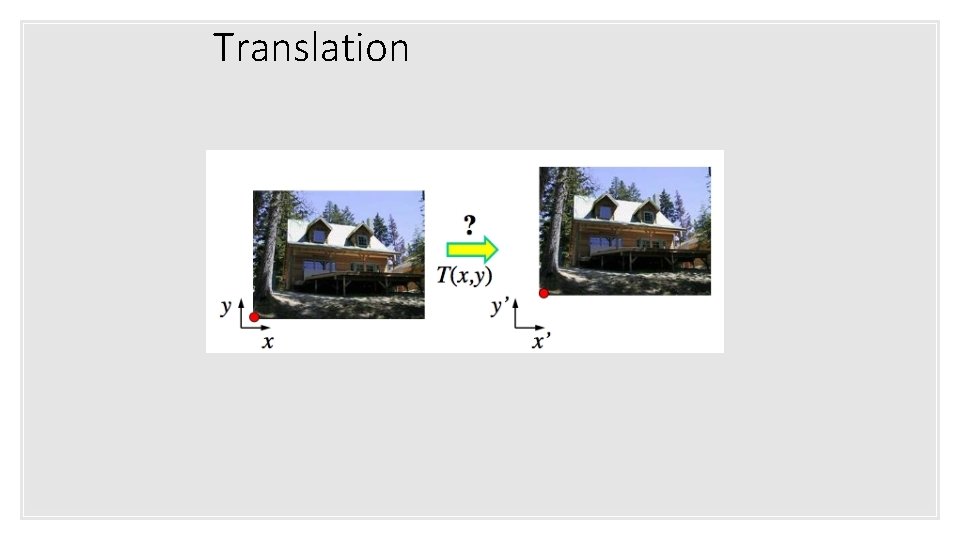
Translation
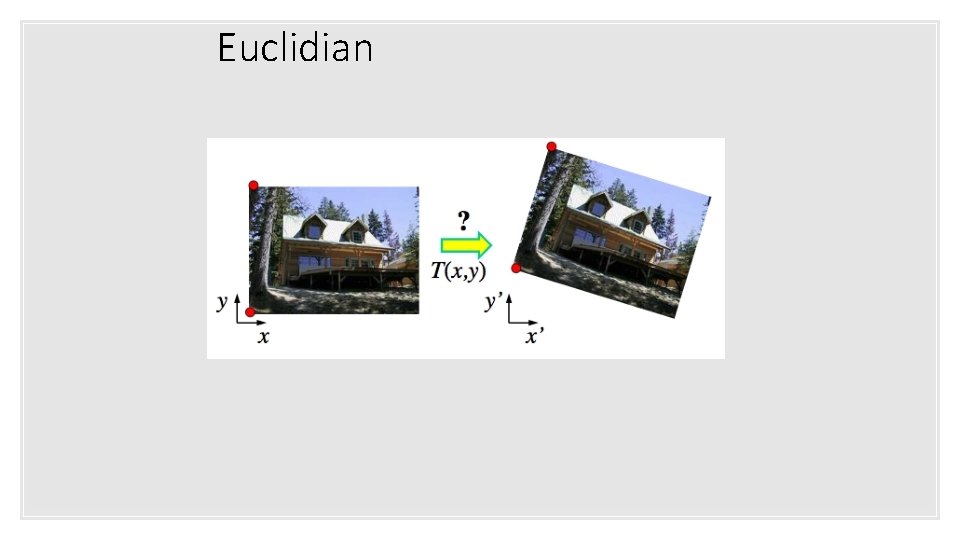
Euclidian
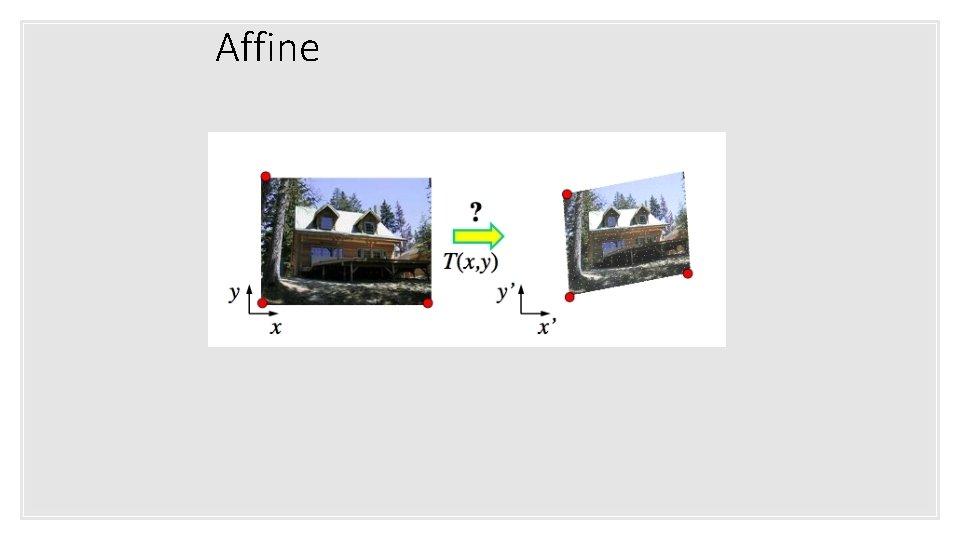
Affine
Spatial transformations translation rotation affine perspective aspect cylindrical
. CNN – Pooling Layer • Reduce the spatial size of the next layer http: //cs 231 n. github. io/convolutional-networks/
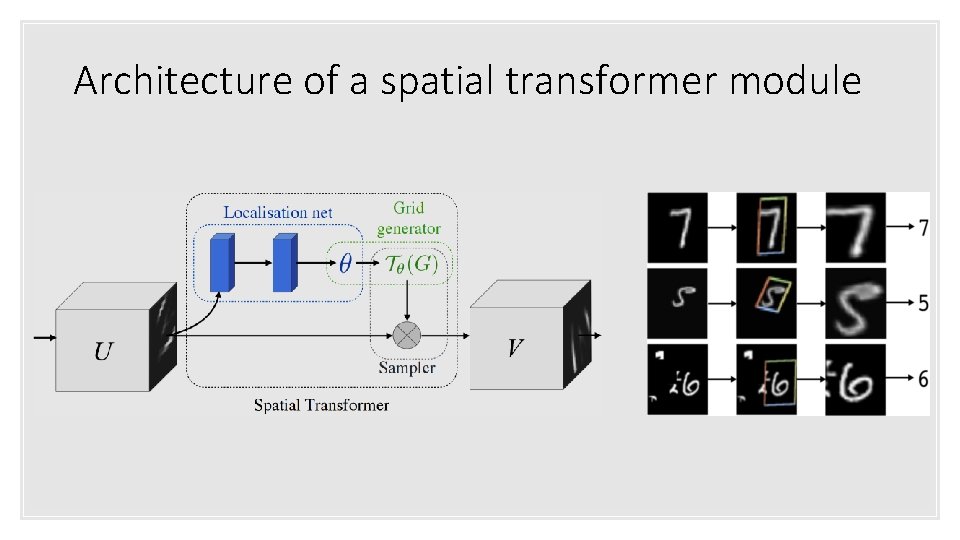
Spatial Transformer Networks (STN) • CNN lack the ability to be spatially invariant to the input data. • STN is a differentiable module giving neural networks the ability to actively spatially transform feature maps, conditional on the feature map itself, without any extra training supervision. • Jaderberg, M. , Simonyan, K. , & Zisserman, A. (2015). Spatial transformer networks. In Advances in neural information processing systems (pp. 2017 -2025).
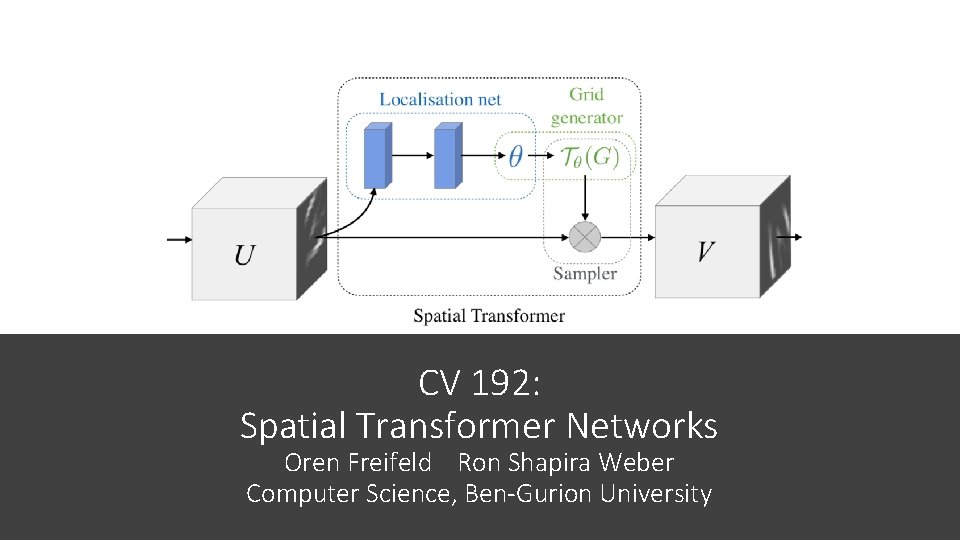
Architecture of a spatial transformer module
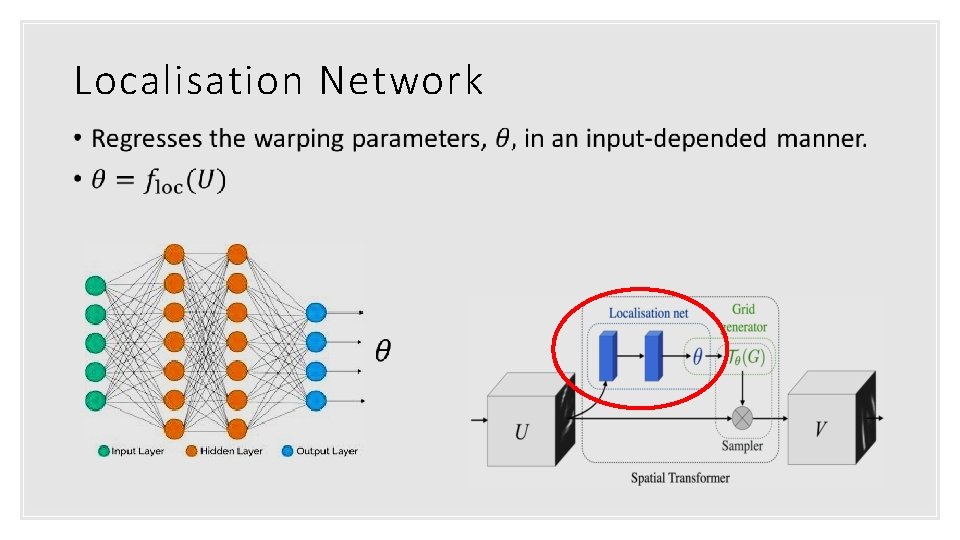
Localisation Network •
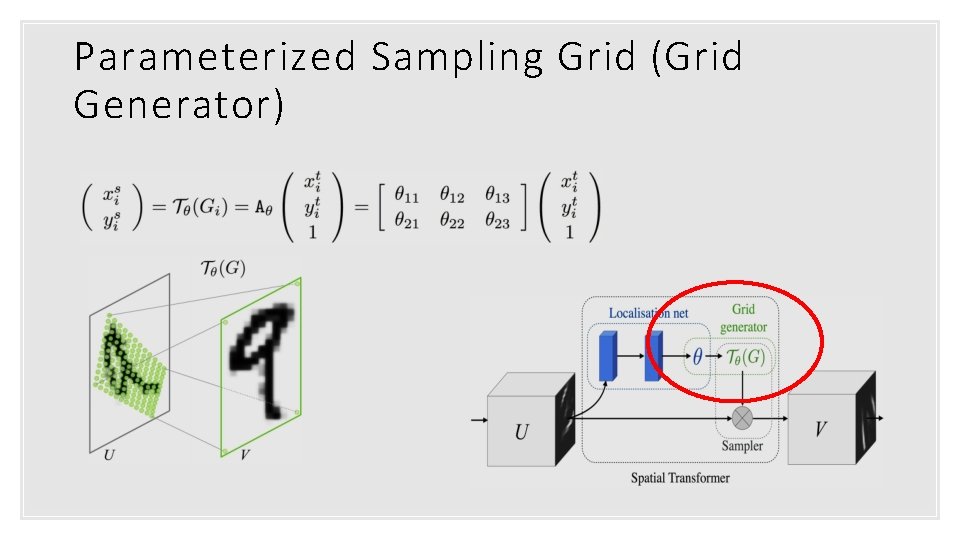
Parameterized Sampling Grid (Grid Generator)
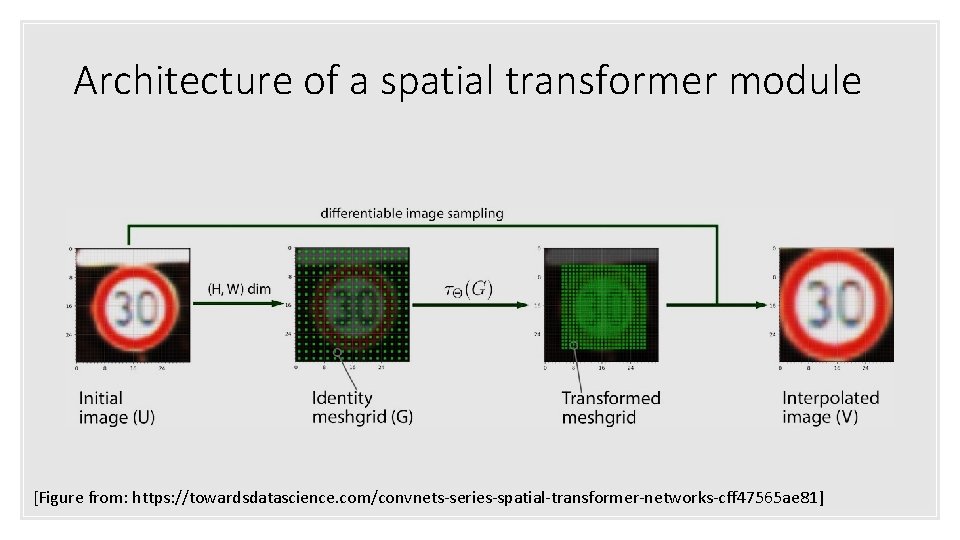
Architecture of a spatial transformer module [Figure from: https: //towardsdatascience. com/convnets-series-spatial-transformer-networks-cff 47565 ae 81]
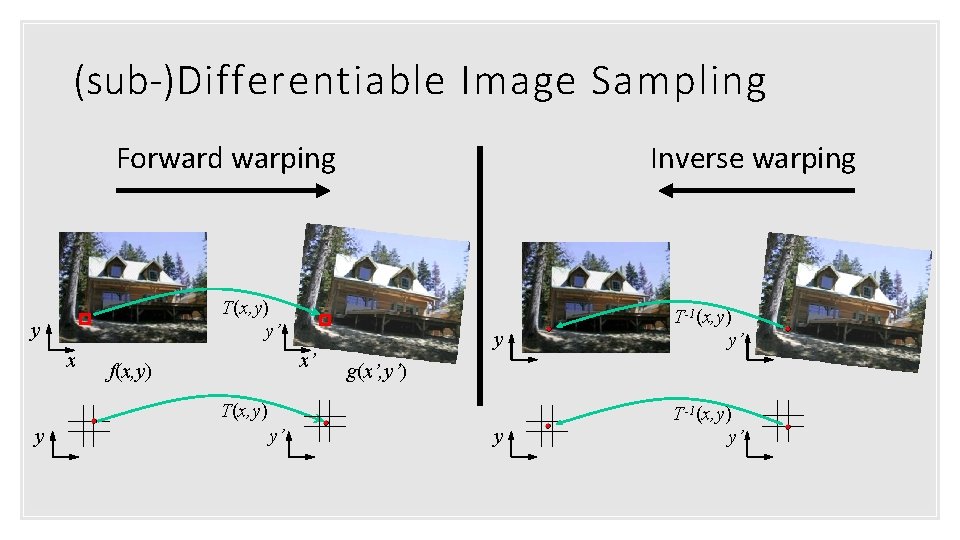
(sub-)Differentiable Image Sampling Inverse warping Forward warping T(x, y) y’ y x x’ f(x, y) y T-1(x, y) y’ g(x’, y’) T(x, y) y y’
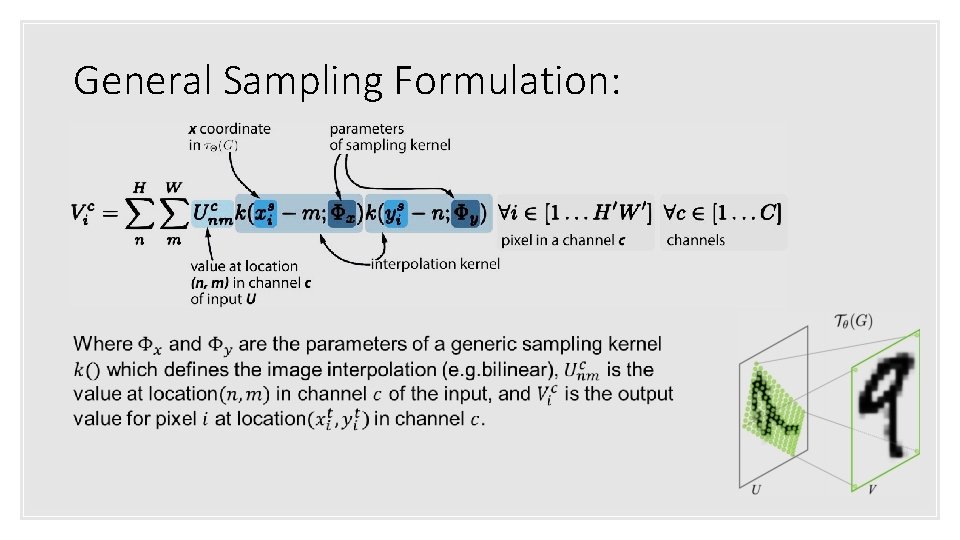
General Sampling Formulation:
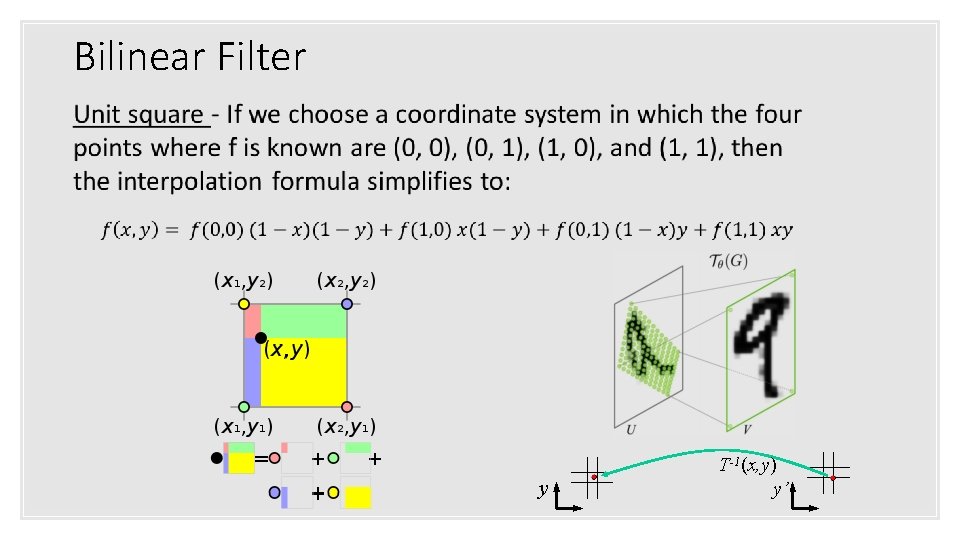
Bilinear Filter y T-1(x, y) y’
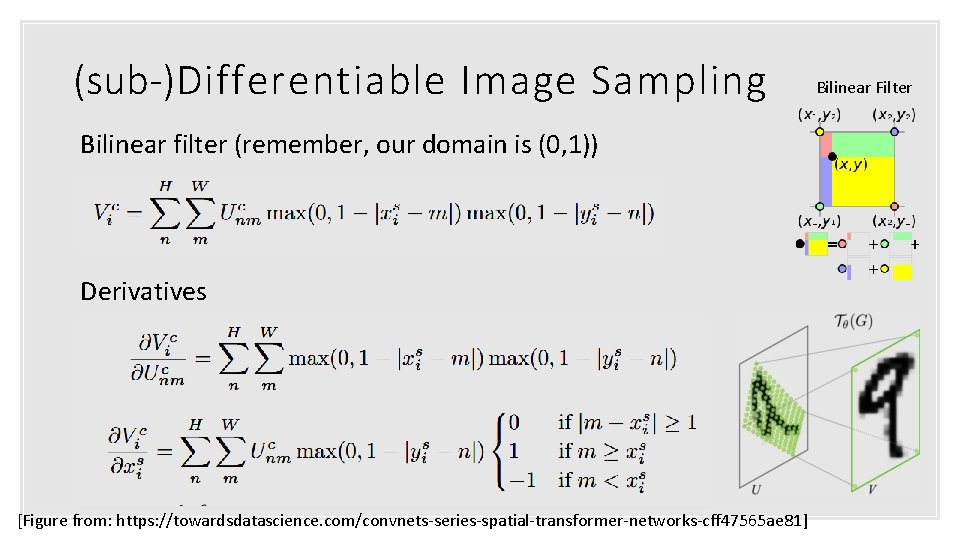
(sub-)Differentiable Image Sampling Bilinear filter (remember, our domain is (0, 1)) Derivatives [Figure from: https: //towardsdatascience. com/convnets-series-spatial-transformer-networks-cff 47565 ae 81] Bilinear Filter
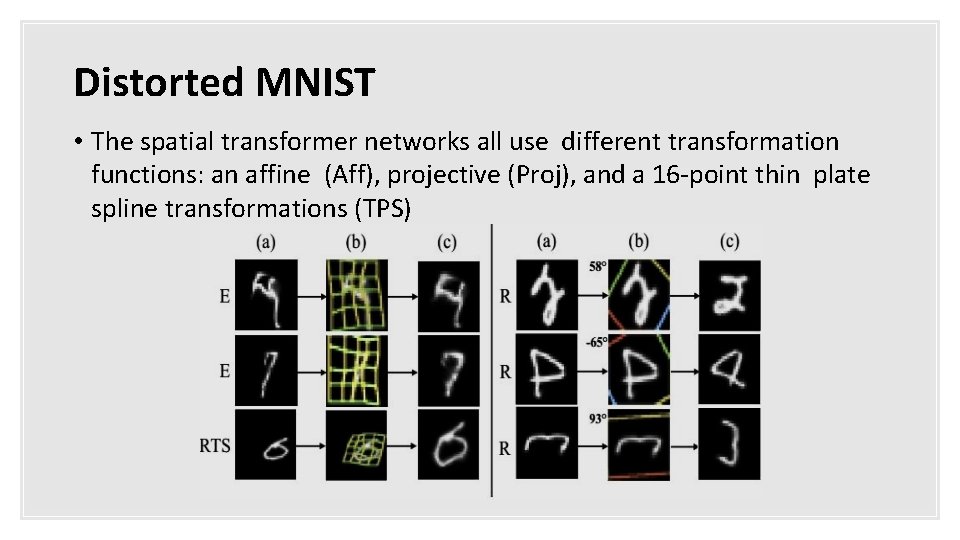
Experiments • Distorted versions of the MNIST handwriting dataset for classification • MNIST data that has been distorted in various ways: rotation (R), rotation, scale and translation (RTS), projective transformation (P), and elastic warping (E). • A challenging real-world dataset, Street View House Numbers for number recognition
Distorted MNIST • The spatial transformer networks all use different transformation functions: an affine (Aff), projective (Proj), and a 16 -point thin plate spline transformations (TPS)
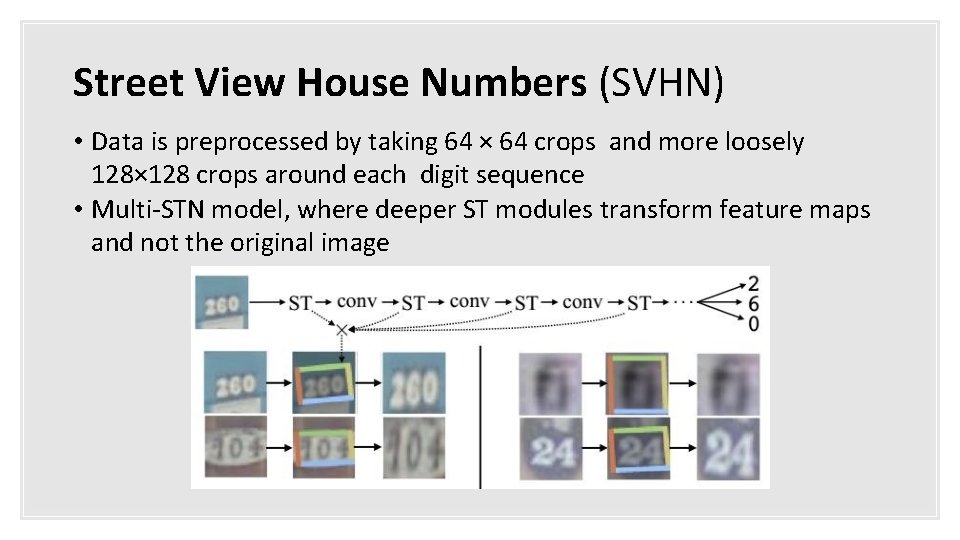
Street View House Numbers (SVHN) • Data is preprocessed by taking 64 × 64 crops and more loosely 128× 128 crops around each digit sequence • Multi-STN model, where deeper ST modules transform feature maps and not the original image
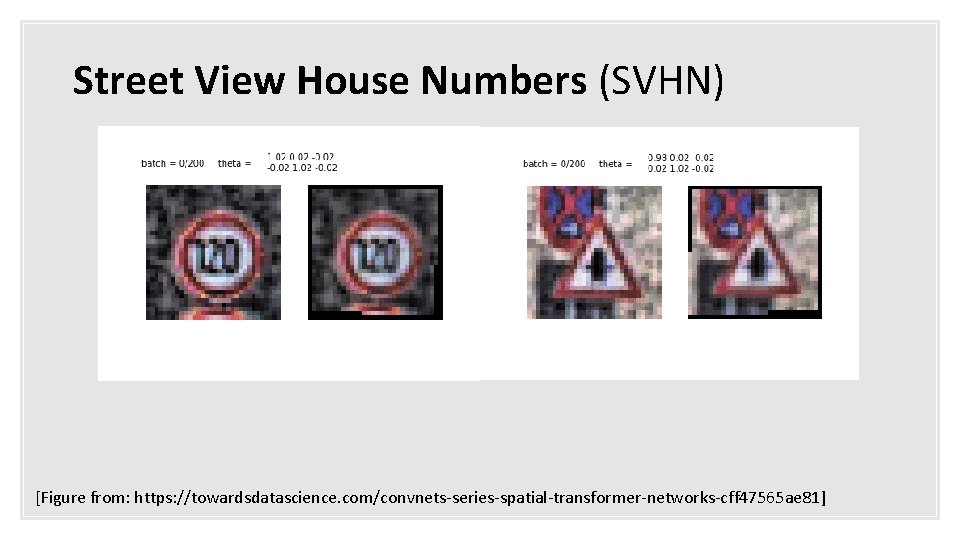
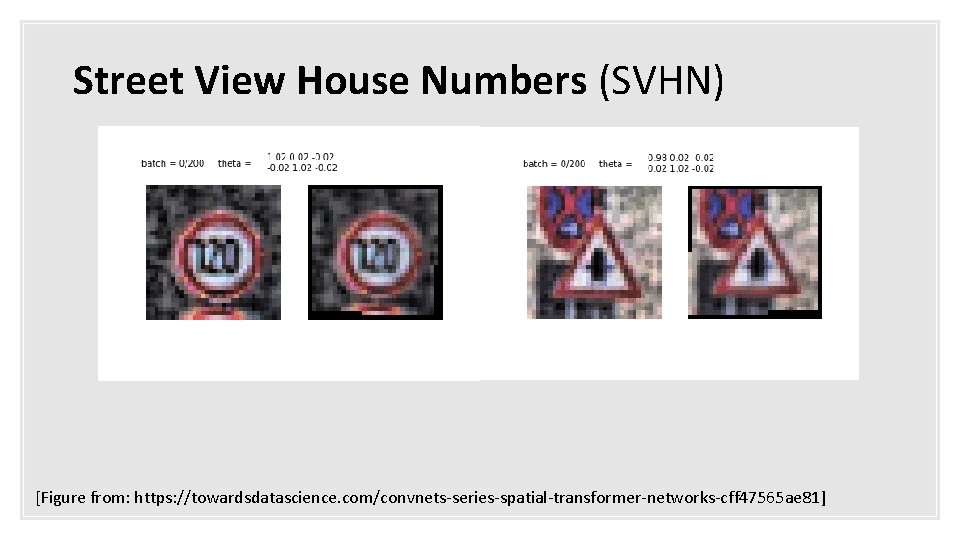
Street View House Numbers (SVHN) [Figure from: https: //towardsdatascience. com/convnets-series-spatial-transformer-networks-cff 47565 ae 81]
Street View House Numbers (SVHN) [Figure from: https: //towardsdatascience. com/convnets-series-spatial-transformer-networks-cff 47565 ae 81]
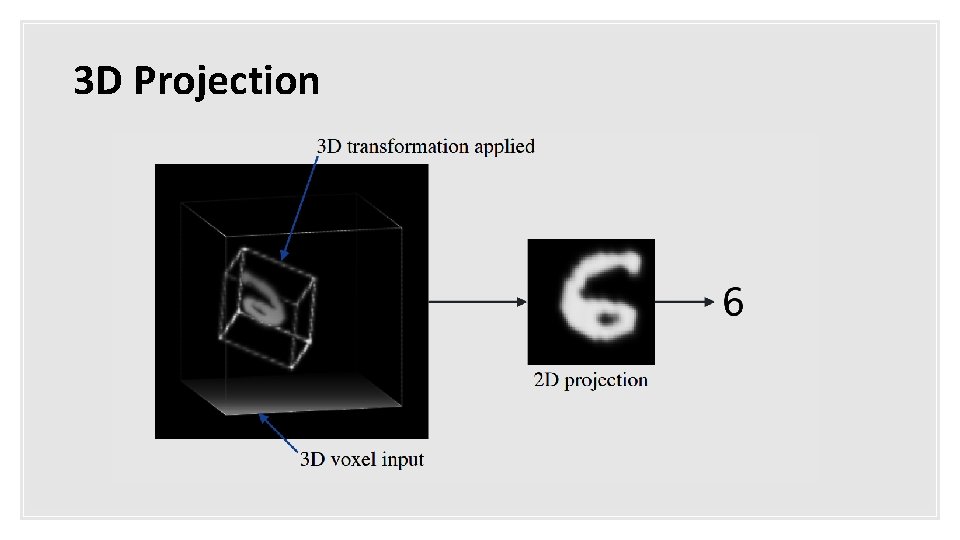
3 D Projection
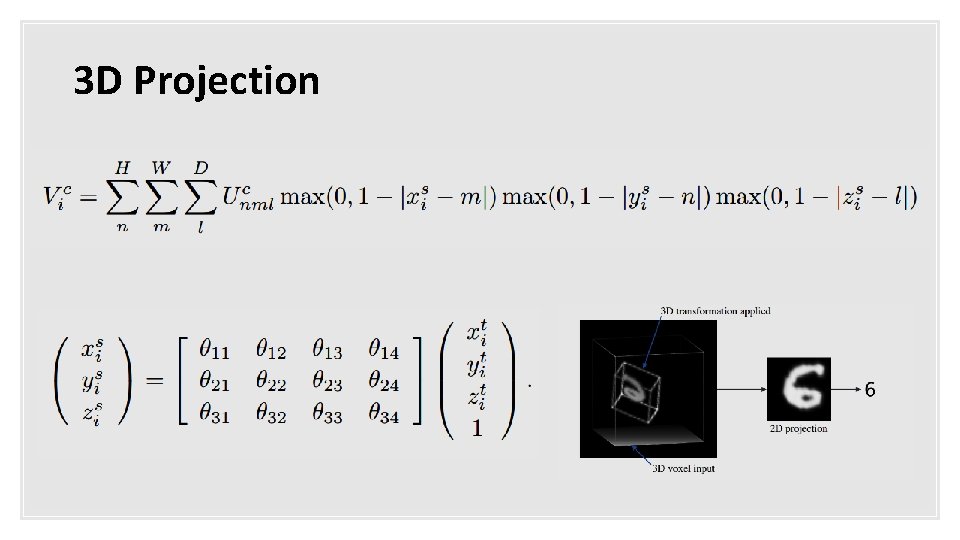
3 D Projection