CS 277 Data Mining Project Presentation Instructor Prof
- Slides: 25
CS 277 Data. Mining Project Presentation Instructor: Prof. Dave Newman Team: Hitesh Sajnani, Vaibhav Saini, Kusum Kumar Donald Bren School of Information and Computer Science University of California, Irvine
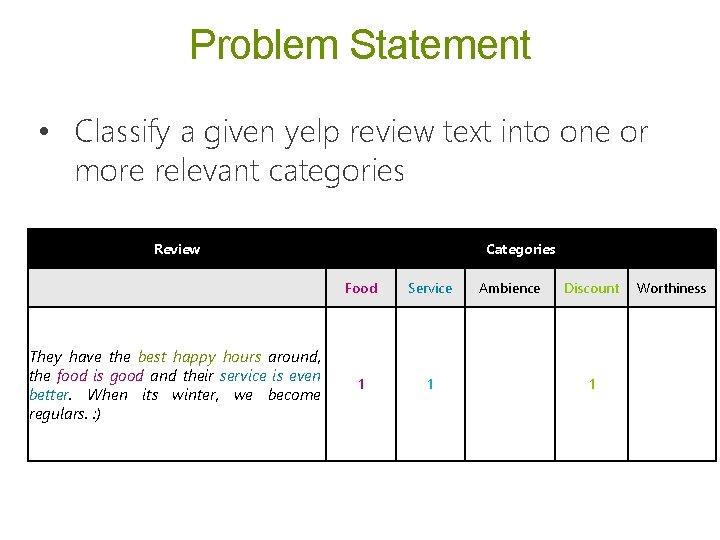
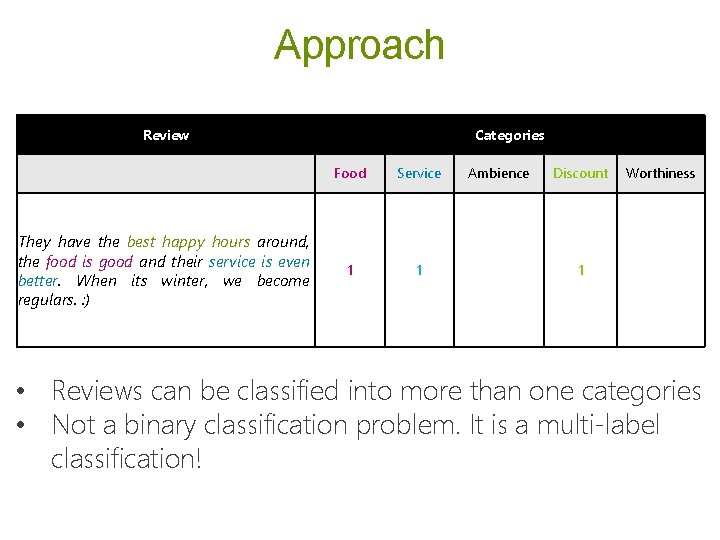
Problem Statement • Classify a given yelp review text into one or more relevant categories Review They have the best happy hours around, the food is good and their service is even better. When its winter, we become regulars. : ) Categories Food Service 1 1 Ambience Discount 1 Worthiness
Dataset Reviews s • Reviews from Food and Restaurant category • # Useful votes > 1 • Total 10, 000 reviews Classification categories • Identified categories using sample set of 400 random • • • reviews Refined categories using 200 more reviews Final categories: 5 Food, Ambience, Service, Deals/Discounts Worthiness
Data Annotation • • • 10, 000 reviews divided into 5 bins (w/ repetition) 6 researchers manually annotated reviews 225 man-hours of work! Discrepancy in 981 ambiguous reviews -- removed from analysis Total 9, 019 reviews: split into 80% train and 20% test
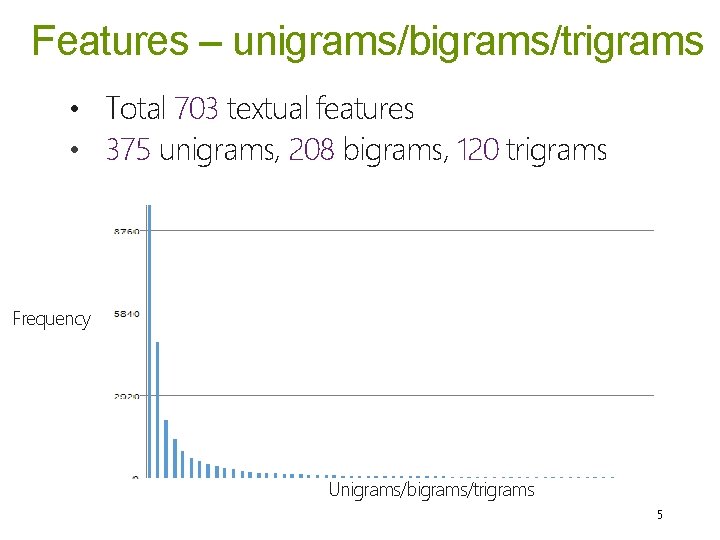
Features – unigrams/bigrams/trigrams • Total 703 textual features • 375 unigrams, 208 bigrams, 120 trigrams Frequency Unigrams/bigrams/trigrams 5
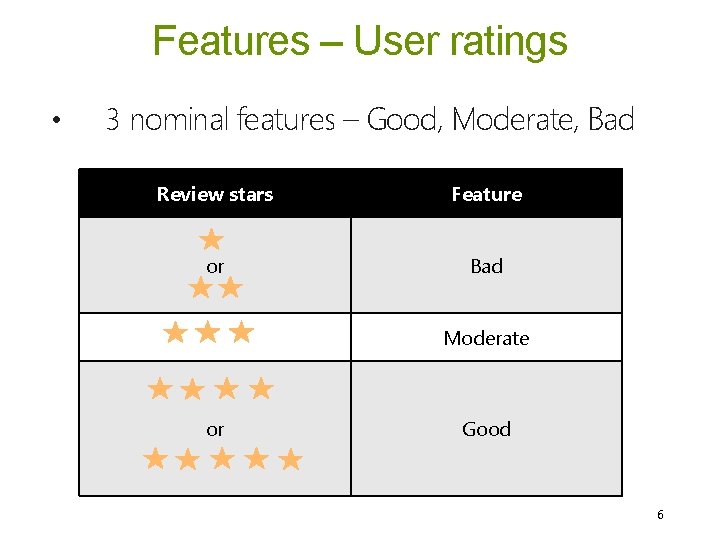
Features – User ratings • 3 nominal features – Good, Moderate, Bad Review stars Feature or Bad Moderate or Good 6
Approach Review They have the best happy hours around, the food is good and their service is even better. When its winter, we become regulars. : ) Categories Food Service 1 1 Ambience Discount Worthiness 1 • Reviews can be classified into more than one categories • Not a binary classification problem. It is a multi-label classification!
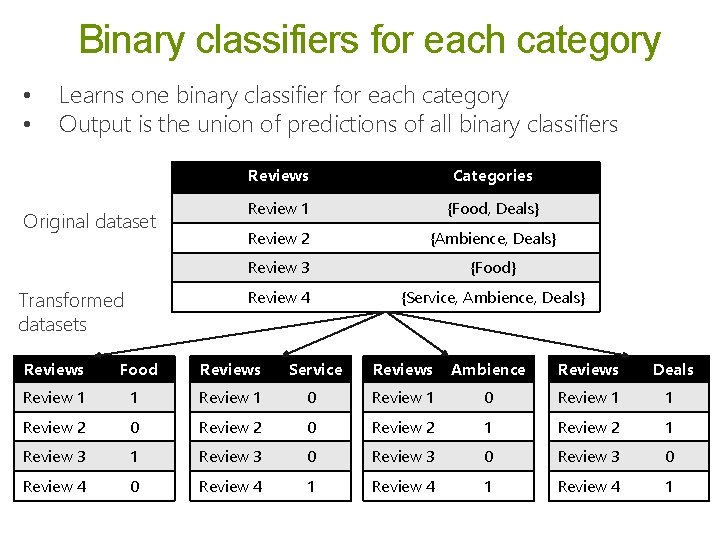
Binary classifiers for each category • • Learns one binary classifier for each category Output is the union of predictions of all binary classifiers Original dataset Transformed datasets Reviews Categories Review 1 {Food, Deals} Review 2 {Ambience, Deals} Review 3 {Food} Review 4 {Service, Ambience, Deals} Reviews Food Reviews Service Reviews Ambience Reviews Deals Review 1 1 Review 1 0 Review 1 1 Review 2 0 Review 2 1 Review 3 0 Review 3 0 Review 4 1
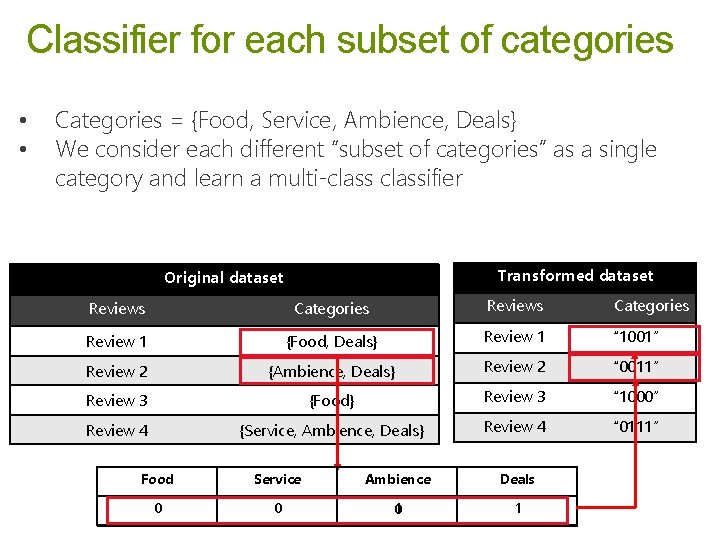
Classifier for each subset of categories • • Categories = {Food, Service, Ambience, Deals} We consider each different “subset of categories” as a single category and learn a multi-classifier Transformed dataset Original dataset Reviews Categories Review 1 {Food, Deals} Review 1 “ 1001” Review 2 {Ambience, Deals} Review 2 “ 0011” Review 3 {Food} Review 3 “ 1000” Review 4 {Service, Ambience, Deals} Review 4 “ 0111” Food Service Ambience Deals 0 1 0 1
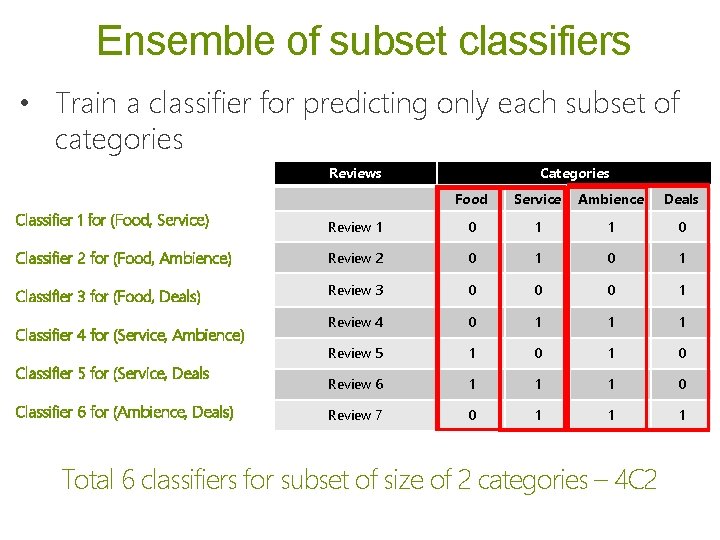
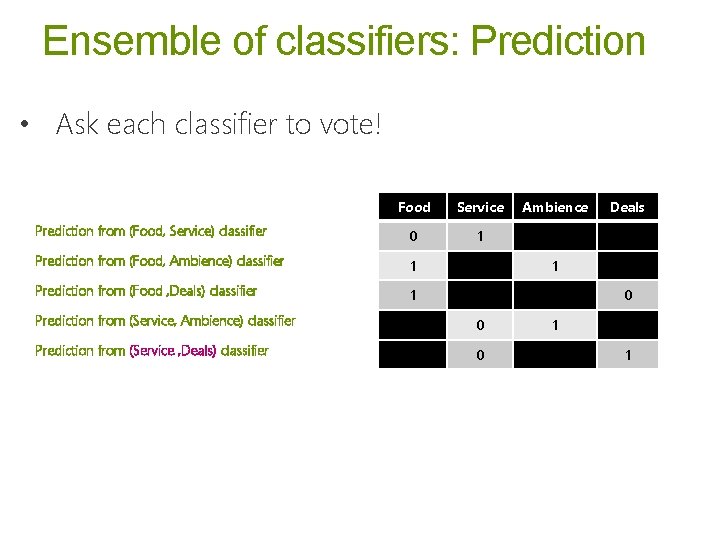
Ensemble of subset classifiers • Train a classifier for predicting only each subset of categories Reviews Categories Food Service Ambience Deals Classifier 1 for (Food, Service) Review 1 0 1 1 0 Classifier 2 for (Food, Ambience) Review 2 0 1 Classifier 3 for (Food, Deals) Review 3 0 0 0 1 Review 4 0 1 1 1 Review 5 1 0 Review 6 1 1 1 0 Review 7 0 1 1 1 Classifier 4 for (Service, Ambience) Classifier 5 for (Service, Deals Classifier 6 for (Ambience, Deals) Total 6 classifiers for subset of size of 2 categories – 4 C 2
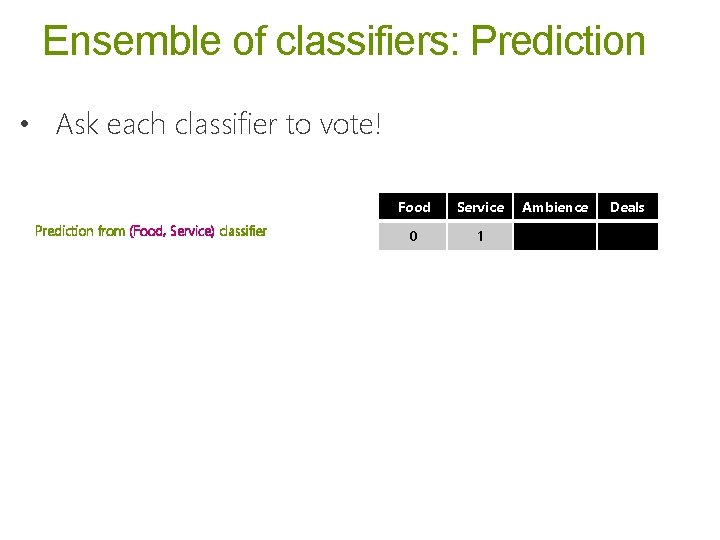
Ensemble of classifiers: Prediction • Ask each classifier to vote! Prediction from (Food, Service) classifier Food Service 0 1 Ambience Deals
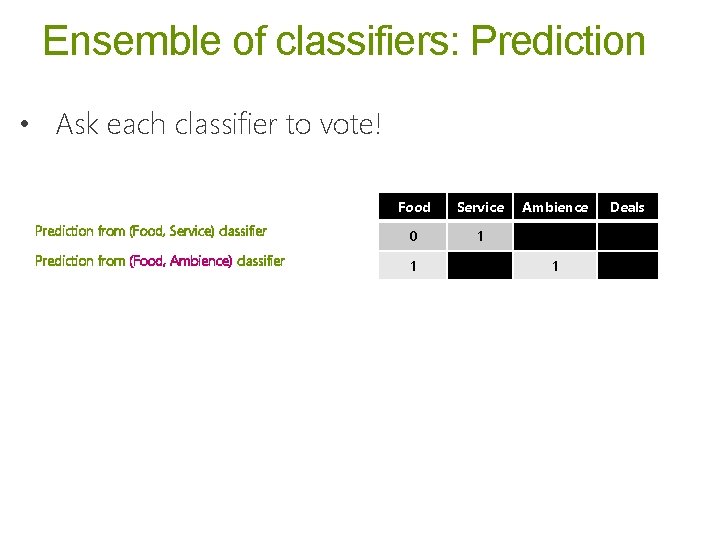
Ensemble of classifiers: Prediction • Ask each classifier to vote! Food Service Prediction from (Food, Service) classifier 0 1 Prediction from (Food, Ambience) classifier 1 Ambience 1 Deals
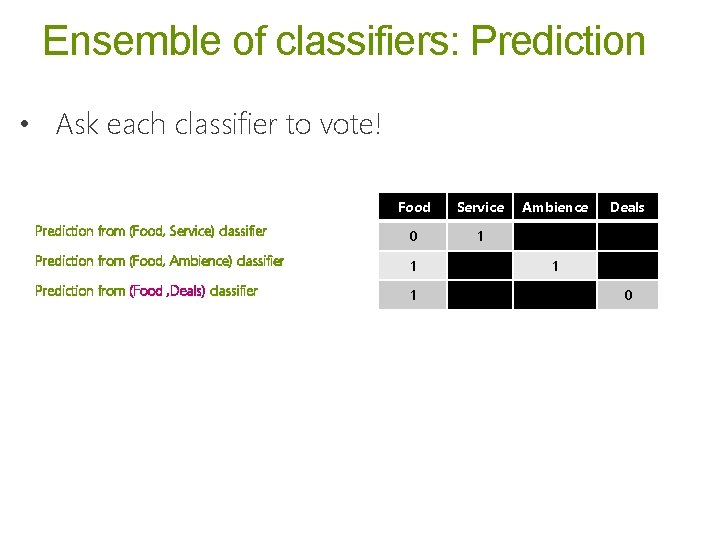
Ensemble of classifiers: Prediction • Ask each classifier to vote! Food Service Prediction from (Food, Service) classifier 0 1 Prediction from (Food, Ambience) classifier 1 Prediction from (Food , Deals) classifier 1 Ambience Deals 1 0
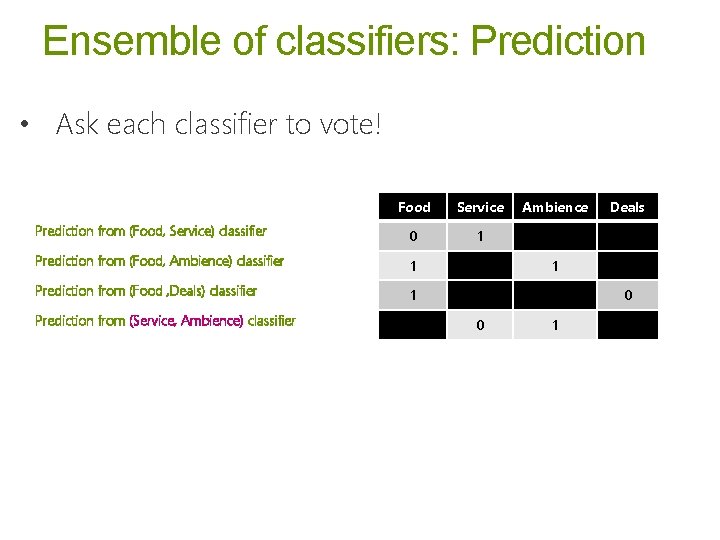
Ensemble of classifiers: Prediction • Ask each classifier to vote! Food Service Prediction from (Food, Service) classifier 0 1 Prediction from (Food, Ambience) classifier 1 Prediction from (Food , Deals) classifier 1 Prediction from (Service, Ambience) classifier Ambience Deals 1 0 0 1
Ensemble of classifiers: Prediction • Ask each classifier to vote! Food Service Prediction from (Food, Service) classifier 0 1 Prediction from (Food, Ambience) classifier 1 Prediction from (Food , Deals) classifier 1 Ambience Deals 1 0 Prediction from (Service, Ambience) classifier 0 Prediction from (Service , Deals) classifier 0 1 1
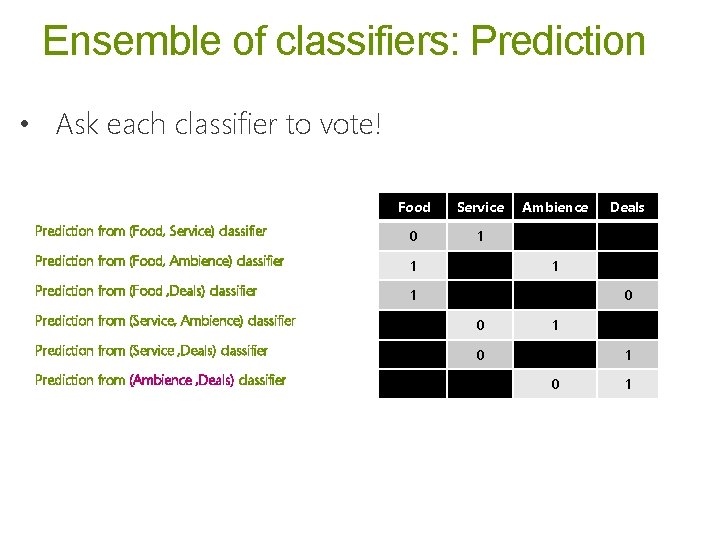
Ensemble of classifiers: Prediction • Ask each classifier to vote! Food Service Prediction from (Food, Service) classifier 0 1 Prediction from (Food, Ambience) classifier 1 Prediction from (Food , Deals) classifier 1 Deals 1 0 Prediction from (Service, Ambience) classifier 0 Prediction from (Service , Deals) classifier 0 Prediction from (Ambience , Deals) classifier Ambience 1 1 0 1
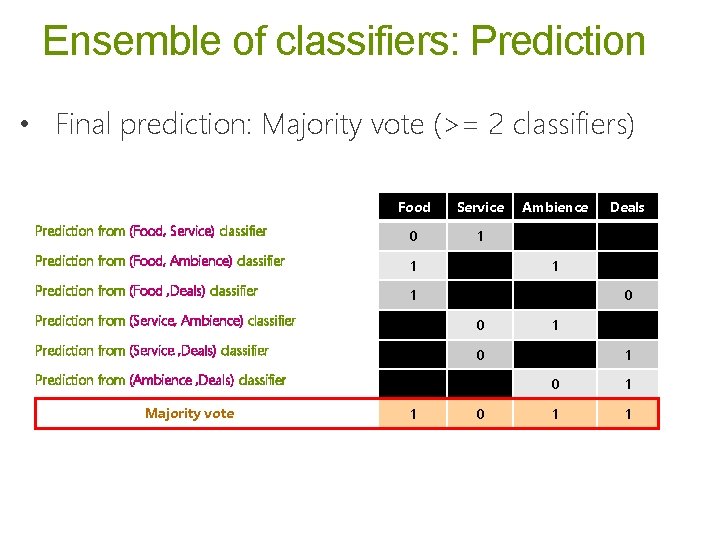
Ensemble of classifiers: Prediction • Final prediction: Majority vote (>= 2 classifiers) Food Service Prediction from (Food, Service) classifier 0 1 Prediction from (Food, Ambience) classifier 1 Prediction from (Food , Deals) classifier 1 0 0 Prediction from (Service , Deals) classifier 0 Prediction from (Ambience , Deals) classifier 1 Deals 1 Prediction from (Service, Ambience) classifier Majority vote Ambience 0 1 1 1
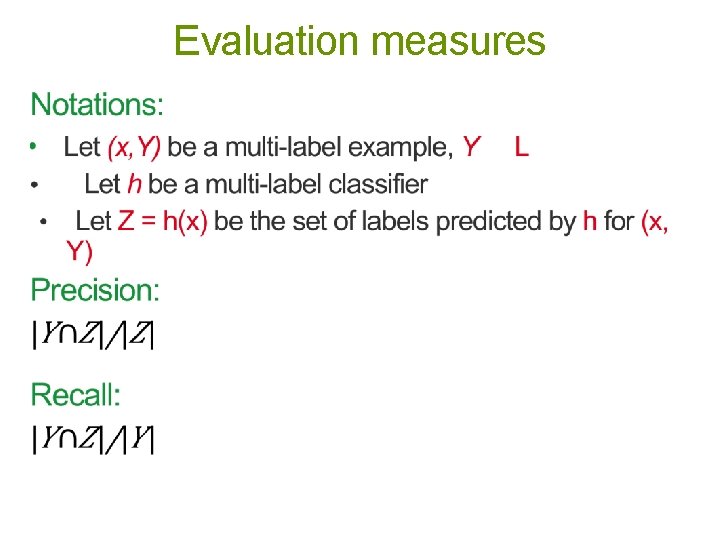
Evaluation measures
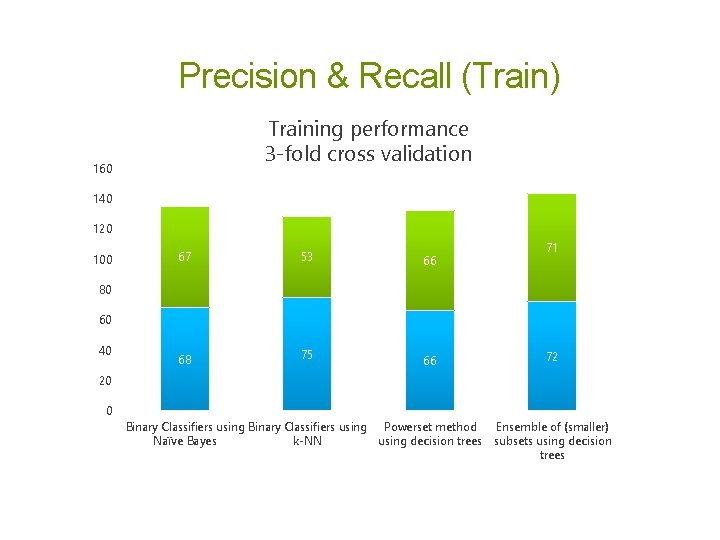
Precision & Recall (Train) Training performance 3 -fold cross validation 160 140 120 100 67 53 68 75 66 71 80 60 40 66 72 20 0 Binary Classifiers using Powerset method Ensemble of (smaller) Naïve Bayes k-NN using decision trees subsets using decision trees
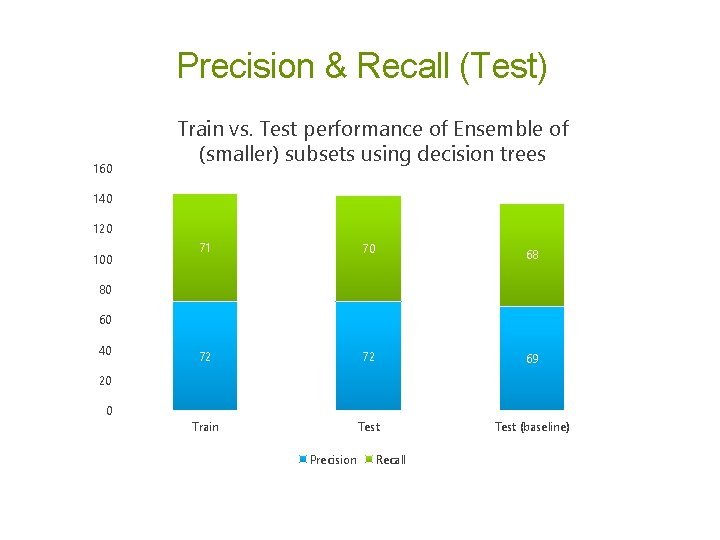
Precision & Recall (Test) 160 Train vs. Test performance of Ensemble of (smaller) subsets using decision trees 140 120 100 71 70 72 72 69 Train Test (baseline) 68 80 60 40 20 0 Precision Recall
Observation 1: Ensemble gave the best results
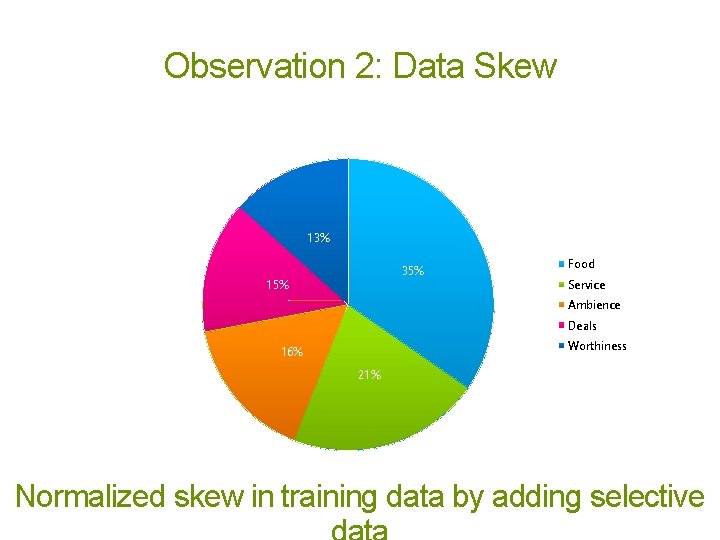
Observation 2: Data Skew Sales 13%7% 8% 35% 9% 15% 55% Food Service Ambience Deals Worthiness 21% 16% 21% Normalized skew in training data by adding selective
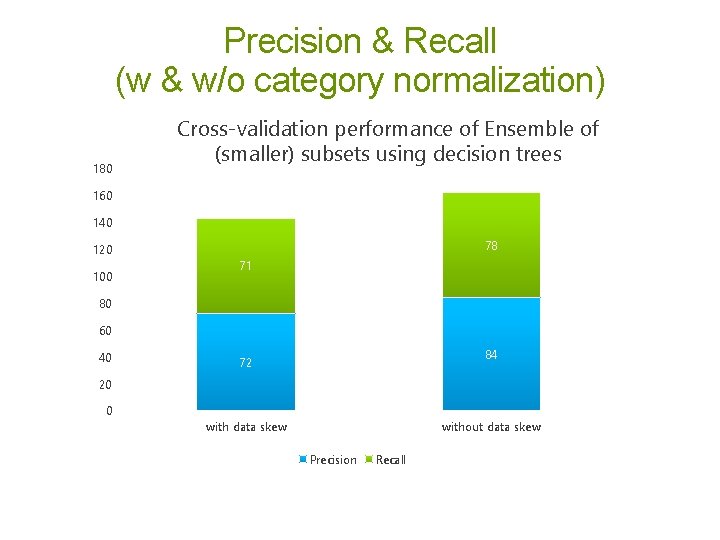
Precision & Recall (w & w/o category normalization) 180 Cross-validation performance of Ensemble of (smaller) subsets using decision trees 160 140 78 120 100 71 80 60 40 84 72 20 0 with data skew without data skew Precision Recall
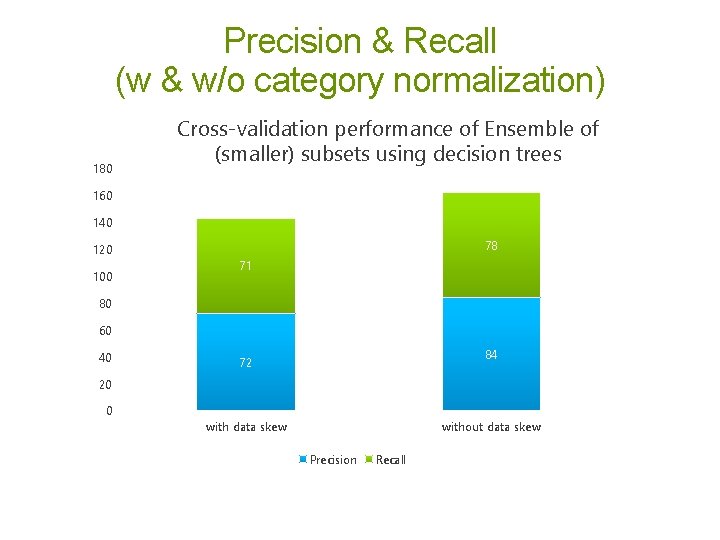
Precision & Recall (w & w/o category normalization) 180 Cross-validation performance of Ensemble of (smaller) subsets using decision trees 160 140 78 120 100 71 80 60 40 84 72 20 0 with data skew without data skew Precision Recall
http: //www. ics. uci. edu/~vpsaini/