Apache Hive and Stinger SQL in Hadoop Arun
- Slides: 26
Apache Hive and Stinger: SQL in Hadoop Arun Murthy (@acmurthy) Alan Gates (@alanfgates) Owen O’Malley (@owen_omalley) @hortonworks © Hortonworks Inc. 2013.
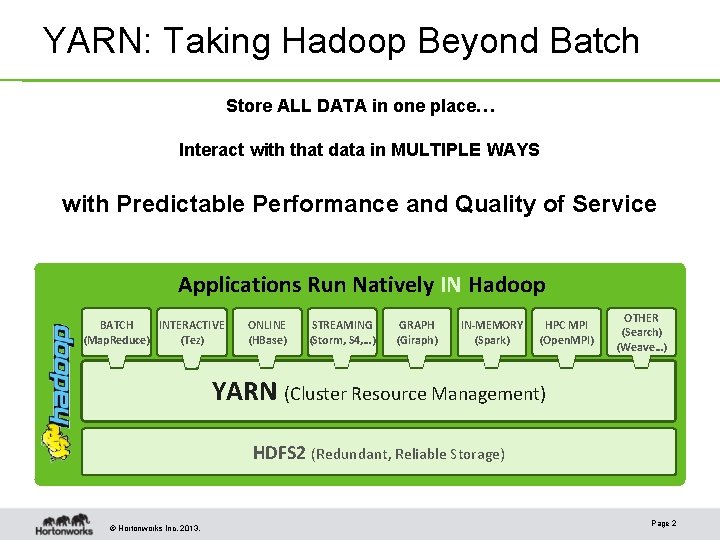
YARN: Taking Hadoop Beyond Batch Store ALL DATA in one place… Interact with that data in MULTIPLE WAYS with Predictable Performance and Quality of Service Applications Run Natively IN Hadoop BATCH INTERACTIVE (Map. Reduce) (Tez) ONLINE (HBase) STREAMING (Storm, S 4, …) GRAPH (Giraph) IN-MEMORY (Spark) HPC MPI (Open. MPI) OTHER (Search) (Weave…) YARN (Cluster Resource Management) HDFS 2 (Redundant, Reliable Storage) © Hortonworks Inc. 2013. Page 2
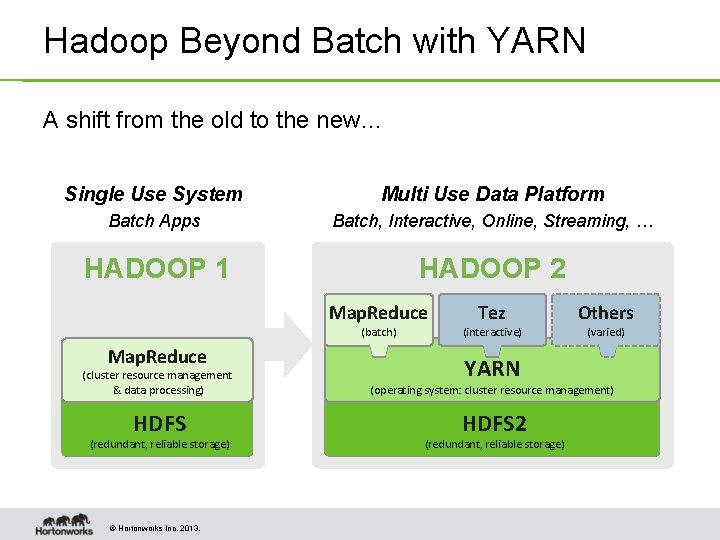
Hadoop Beyond Batch with YARN A shift from the old to the new… Single Use System Multi Use Data Platform Batch Apps Batch, Interactive, Online, Streaming, … HADOOP 1 HADOOP 2 Map. Reduce (batch) Map. Reduce Tez (interactive) YARN Others (varied) (cluster resource management & data processing) (operating system: cluster resource management) HDFS 2 (redundant, reliable storage) © Hortonworks Inc. 2013. (redundant, reliable storage)
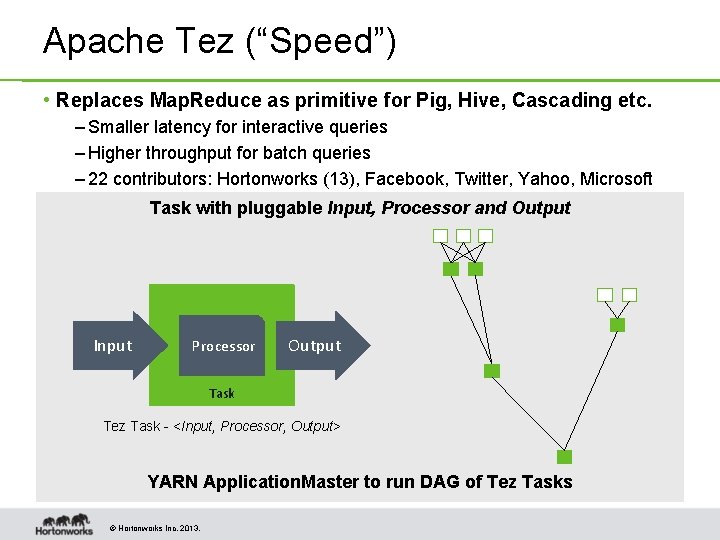
Apache Tez (“Speed”) • Replaces Map. Reduce as primitive for Pig, Hive, Cascading etc. – Smaller latency for interactive queries – Higher throughput for batch queries – 22 contributors: Hortonworks (13), Facebook, Twitter, Yahoo, Microsoft Task with pluggable Input, Processor and Output Input Processor Output Task Tez Task - <Input, Processor, Output> YARN Application. Master to run DAG of Tez Tasks © Hortonworks Inc. 2013.
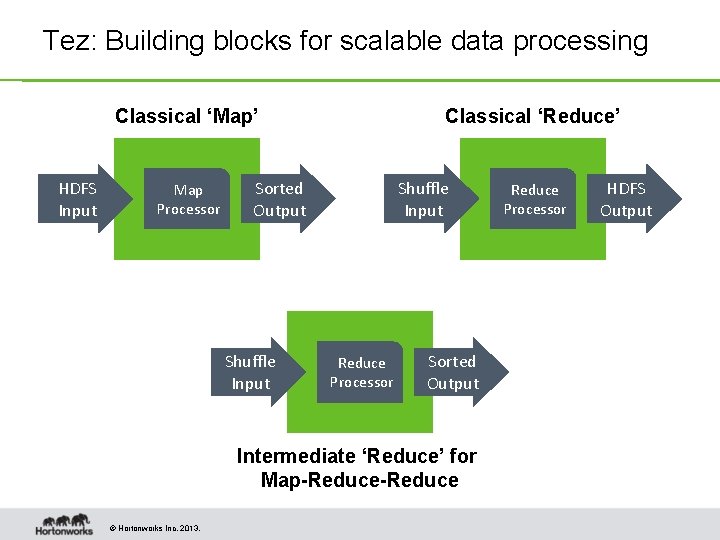
Tez: Building blocks for scalable data processing Classical ‘Map’ HDFS Input Map Processor Classical ‘Reduce’ Sorted Output Shuffle Input Reduce Processor Sorted Output Intermediate ‘Reduce’ for Map-Reduce © Hortonworks Inc. 2013. Reduce Processor HDFS Output
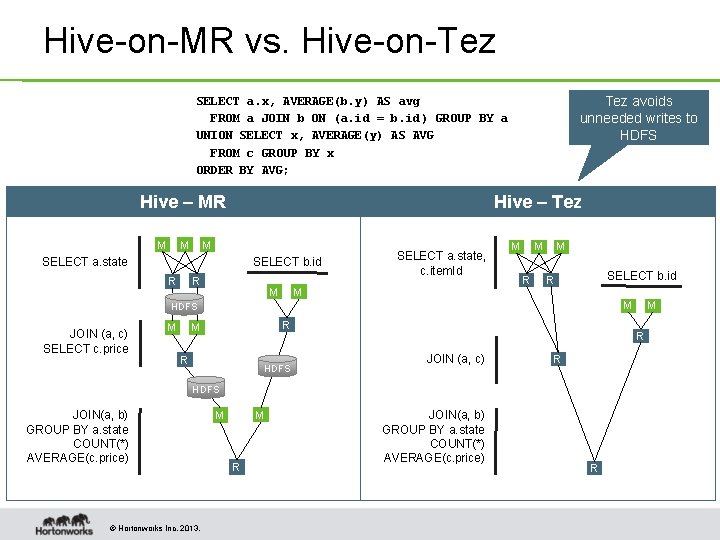
Hive-on-MR vs. Hive-on-Tez avoids unneeded writes to HDFS SELECT a. x, AVERAGE(b. y) AS avg FROM a JOIN b ON (a. id = b. id ) GROUP BY a UNION SELECT x, AVERAGE(y) AS AVG FROM c GROUP BY x ORDER BY AVG; Hive – MR M M Hive – Tez M SELECT a. state SELECT b. id R R M SELECT a. state, c. item. Id M M M R M SELECT b. id R M HDFS JOIN (a, c) SELECT c. price M R HDFS R JOIN (a, c) R HDFS JOIN(a, b) GROUP BY a. state COUNT(*) AVERAGE(c. price) © Hortonworks Inc. 2013. M M R M JOIN(a, b) GROUP BY a. state COUNT(*) AVERAGE(c. price) R
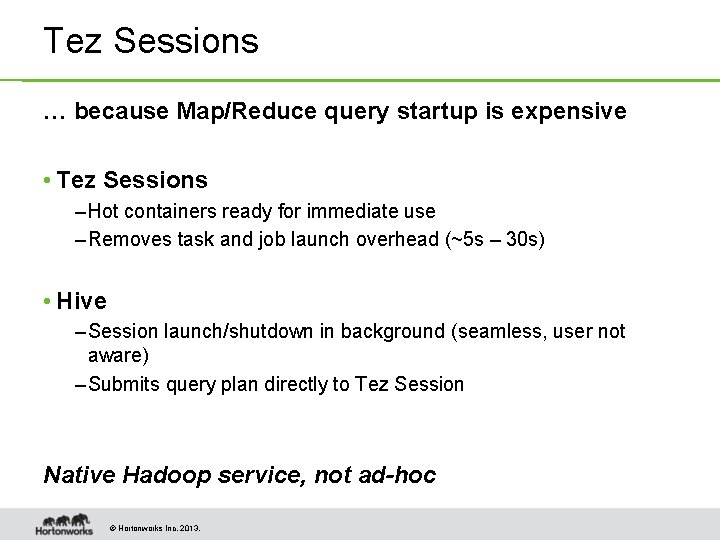
Tez Sessions … because Map/Reduce query startup is expensive • Tez Sessions – Hot containers ready for immediate use – Removes task and job launch overhead (~5 s – 30 s) • Hive – Session launch/shutdown in background (seamless, user not aware) – Submits query plan directly to Tez Session Native Hadoop service, not ad-hoc © Hortonworks Inc. 2013.
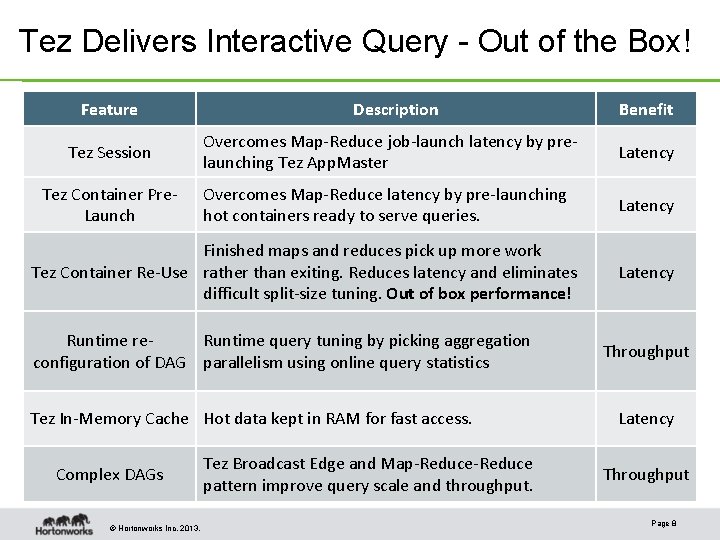
Tez Delivers Interactive Query - Out of the Box! Feature Tez Session Tez Container Pre. Launch Description Overcomes Map-Reduce job-launch latency by prelaunching Tez App. Master Latency Overcomes Map-Reduce latency by pre-launching hot containers ready to serve queries. Latency Finished maps and reduces pick up more work Tez Container Re-Use rather than exiting. Reduces latency and eliminates difficult split-size tuning. Out of box performance! Runtime re. Runtime query tuning by picking aggregation configuration of DAG parallelism using online query statistics Tez In-Memory Cache Hot data kept in RAM for fast access. Complex DAGs © Hortonworks Inc. 2013. Benefit Tez Broadcast Edge and Map-Reduce pattern improve query scale and throughput. Latency Throughput Page 8
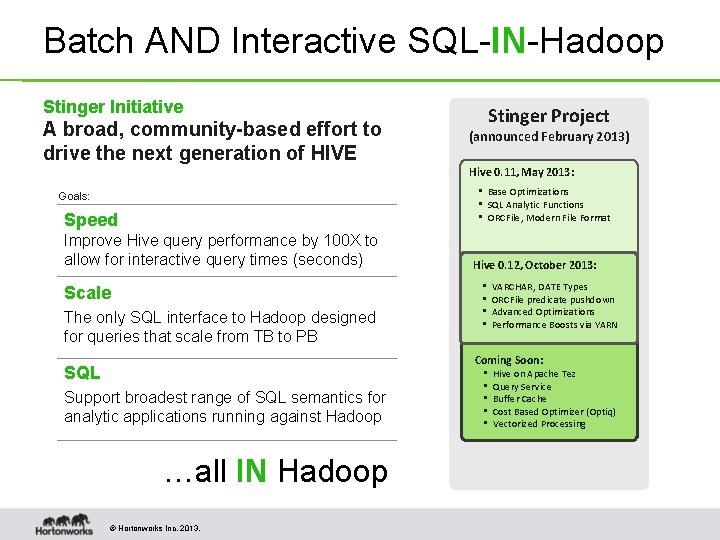
Batch AND Interactive SQL-IN-Hadoop Stinger Initiative A broad, community-based effort to drive the next generation of HIVE Stinger Project (announced February 2013) Hive 0. 11, May 2013: • Base Optimizations • SQL Analytic Functions • ORCFile, Modern File Format Goals: Speed Improve Hive query performance by 100 X to allow for interactive query times (seconds) Scale The only SQL interface to Hadoop designed for queries that scale from TB to PB Hive 0. 12, October 2013: • • VARCHAR, DATE Types ORCFile predicate pushdown Advanced Optimizations Performance Boosts via YARN Coming Soon: SQL Support broadest range of SQL semantics for analytic applications running against Hadoop …all IN Hadoop © Hortonworks Inc. 2013. • • • Hive on Apache Tez Query Service Buffer Cache Cost Based Optimizer (Optiq) Vectorized Processing
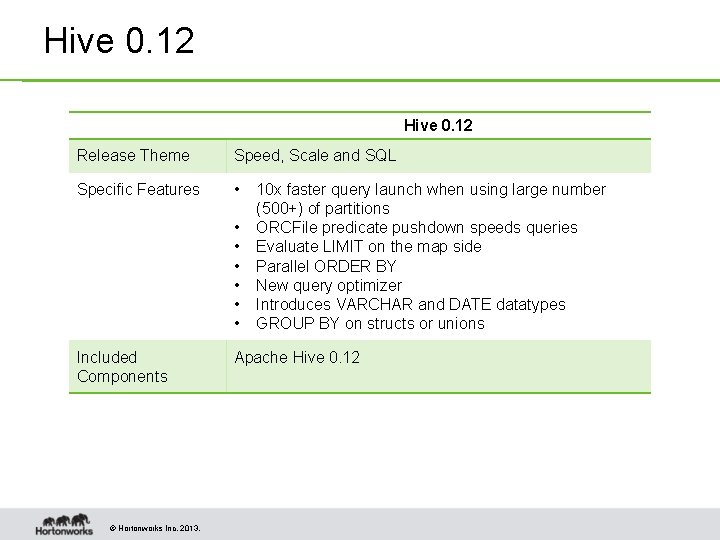
Hive 0. 12 Release Theme Speed, Scale and SQL Specific Features • • Included Components © Hortonworks Inc. 2013. 10 x faster query launch when using large number (500+) of partitions ORCFile predicate pushdown speeds queries Evaluate LIMIT on the map side Parallel ORDER BY New query optimizer Introduces VARCHAR and DATE datatypes GROUP BY on structs or unions Apache Hive 0. 12
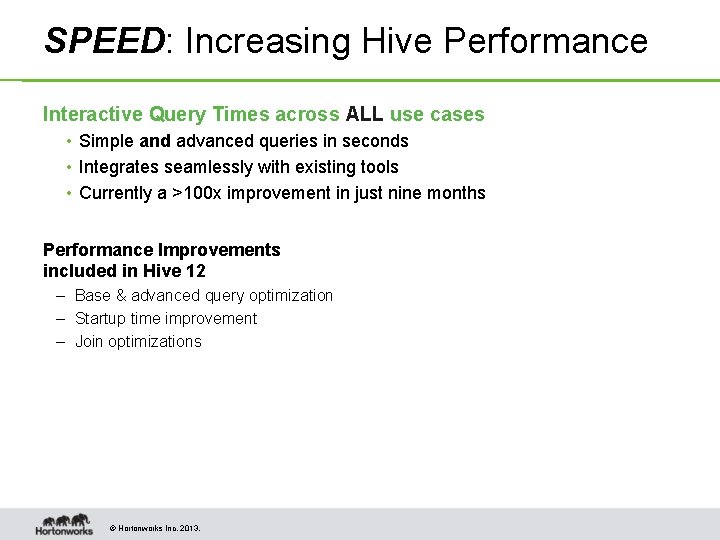
SPEED: Increasing Hive Performance Interactive Query Times across ALL use cases • Simple and advanced queries in seconds • Integrates seamlessly with existing tools • Currently a >100 x improvement in just nine months Performance Improvements included in Hive 12 – Base & advanced query optimization – Startup time improvement – Join optimizations © Hortonworks Inc. 2013.
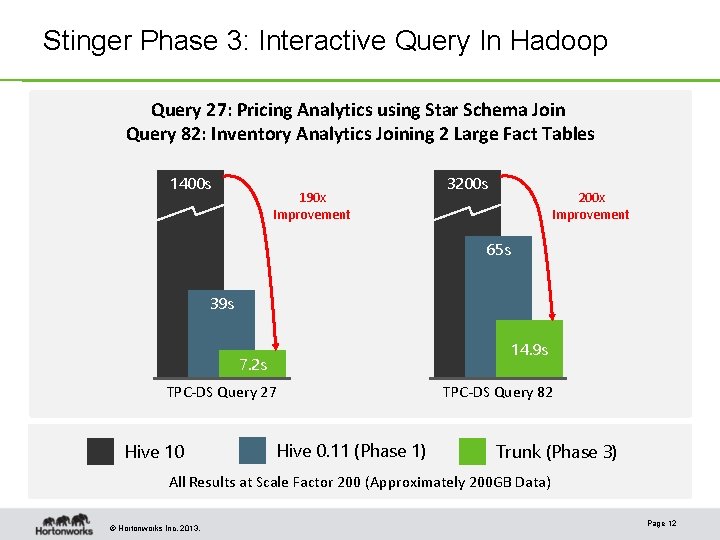
Stinger Phase 3: Interactive Query In Hadoop Query 27: Pricing Analytics using Star Schema Join Query 82: Inventory Analytics Joining 2 Large Fact Tables 1400 s 190 x Improvement 3200 s 200 x Improvement 65 s 39 s 14. 9 s 7. 2 s TPC-DS Query 27 Hive 10 Hive 0. 11 (Phase 1) TPC-DS Query 82 Trunk (Phase 3) All Results at Scale Factor 200 (Approximately 200 GB Data) © Hortonworks Inc. 2013. Page 12
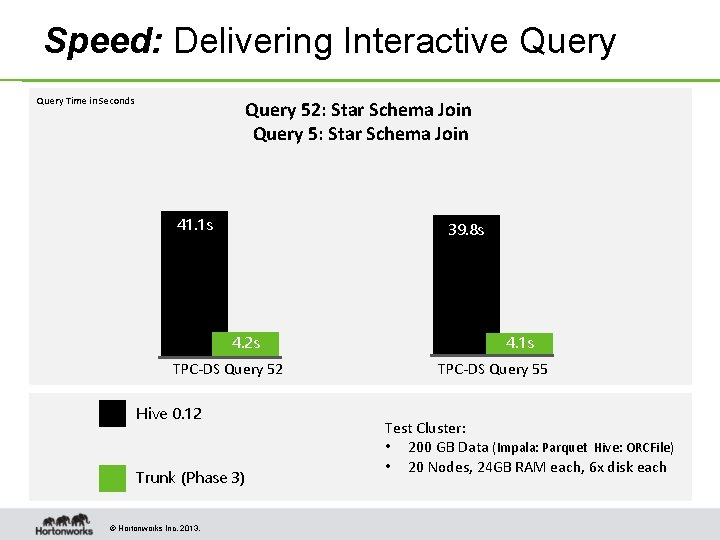
Speed: Delivering Interactive Query Time in Seconds Query 52: Star Schema Join Query 5: Star Schema Join 41. 1 s 39. 8 s 4. 2 s TPC-DS Query 52 Hive 0. 12 Trunk (Phase 3) © Hortonworks Inc. 2013. 4. 1 s TPC-DS Query 55 Test Cluster: • 200 GB Data (Impala: Parquet Hive: ORCFile) • 20 Nodes, 24 GB RAM each, 6 x disk each
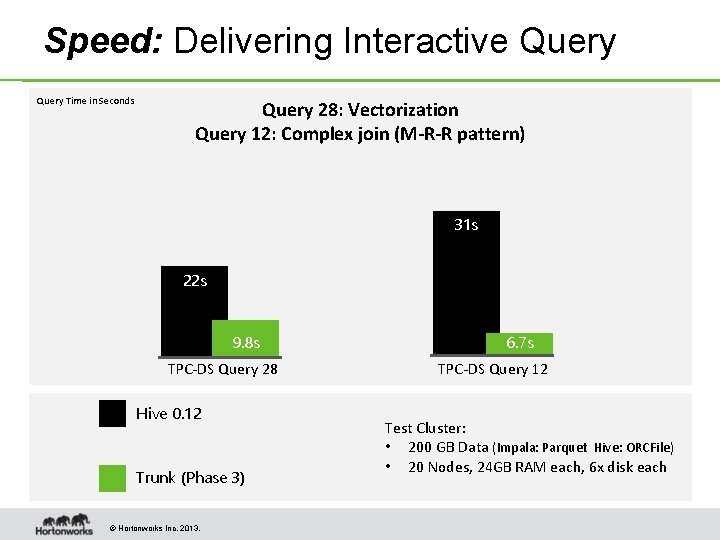
Speed: Delivering Interactive Query Time in Seconds Query 28: Vectorization Query 12: Complex join (M-R-R pattern) 31 s 22 s 9. 8 s TPC-DS Query 28 Hive 0. 12 Trunk (Phase 3) © Hortonworks Inc. 2013. 6. 7 s TPC-DS Query 12 Test Cluster: • 200 GB Data (Impala: Parquet Hive: ORCFile) • 20 Nodes, 24 GB RAM each, 6 x disk each
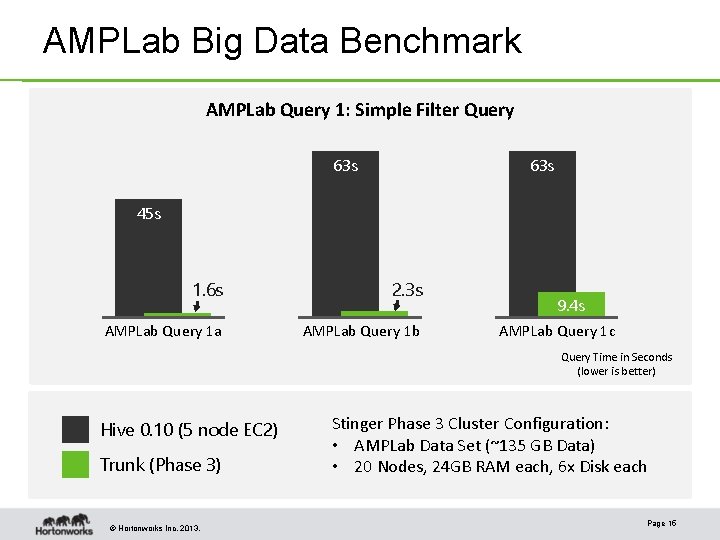
AMPLab Big Data Benchmark AMPLab Query 1: Simple Filter Query 63 s 45 s 1. 6 s 2. 3 s AMPLab Query 1 a AMPLab Query 1 b 9. 4 s AMPLab Query 1 c Query Time in Seconds (lower is better) Hive 0. 10 (5 node EC 2) Trunk (Phase 3) © Hortonworks Inc. 2013. Stinger Phase 3 Cluster Configuration: • AMPLab Data Set (~135 GB Data) • 20 Nodes, 24 GB RAM each, 6 x Disk each Page 15
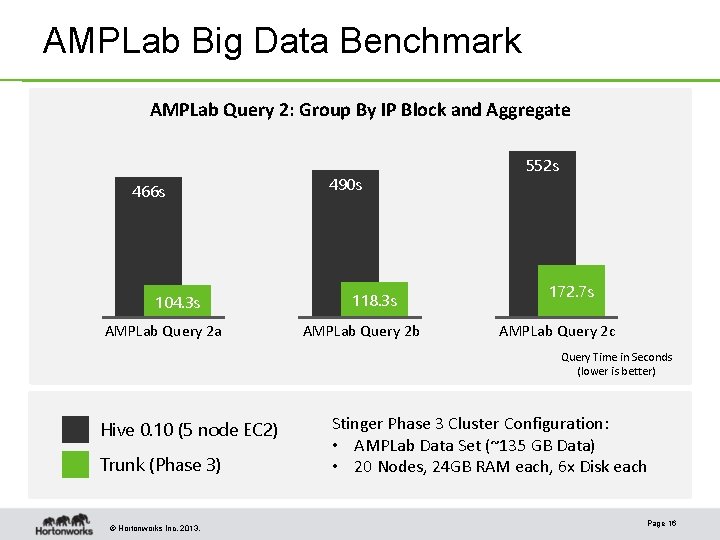
AMPLab Big Data Benchmark AMPLab Query 2: Group By IP Block and Aggregate 466 s 104. 3 s AMPLab Query 2 a 490 s 118. 3 s AMPLab Query 2 b 552 s 172. 7 s AMPLab Query 2 c Query Time in Seconds (lower is better) Hive 0. 10 (5 node EC 2) Trunk (Phase 3) © Hortonworks Inc. 2013. Stinger Phase 3 Cluster Configuration: • AMPLab Data Set (~135 GB Data) • 20 Nodes, 24 GB RAM each, 6 x Disk each Page 16
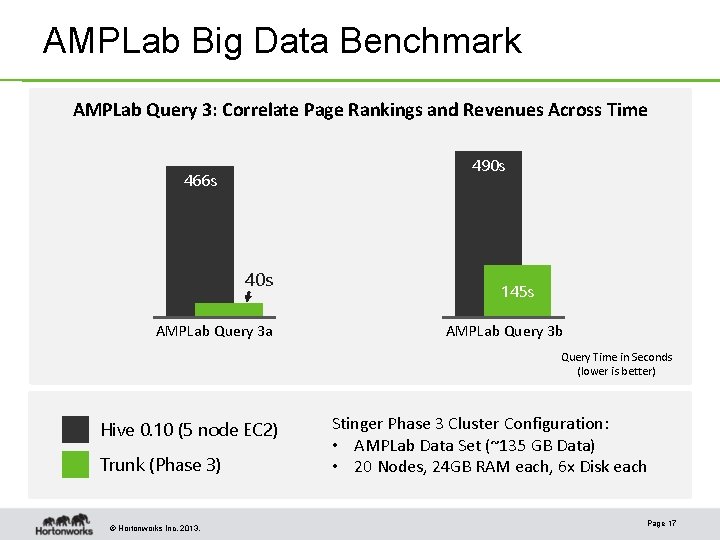
AMPLab Big Data Benchmark AMPLab Query 3: Correlate Page Rankings and Revenues Across Time 490 s 466 s 40 s AMPLab Query 3 a 145 s AMPLab Query 3 b Query Time in Seconds (lower is better) Hive 0. 10 (5 node EC 2) Trunk (Phase 3) © Hortonworks Inc. 2013. Stinger Phase 3 Cluster Configuration: • AMPLab Data Set (~135 GB Data) • 20 Nodes, 24 GB RAM each, 6 x Disk each Page 17
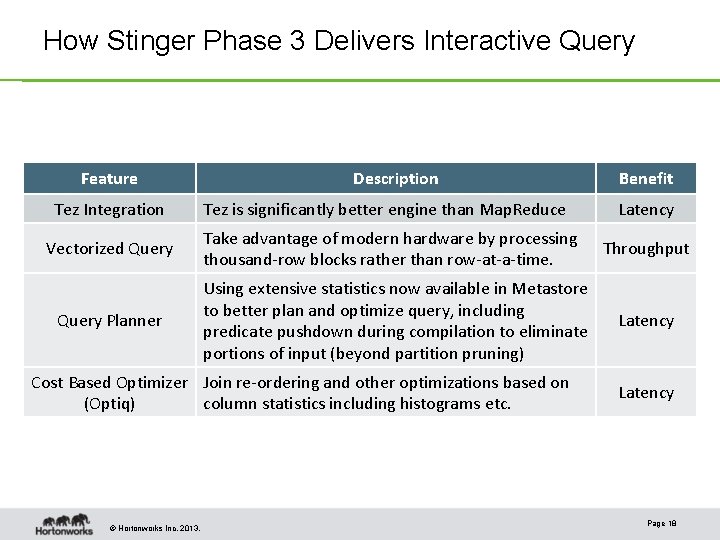
How Stinger Phase 3 Delivers Interactive Query Feature Tez Integration Description Tez is significantly better engine than Map. Reduce Benefit Latency Vectorized Query Take advantage of modern hardware by processing thousand-row blocks rather than row-at-a-time. Throughput Query Planner Using extensive statistics now available in Metastore to better plan and optimize query, including predicate pushdown during compilation to eliminate portions of input (beyond partition pruning) Latency Cost Based Optimizer Join re-ordering and other optimizations based on (Optiq) column statistics including histograms etc. © Hortonworks Inc. 2013. Latency Page 18
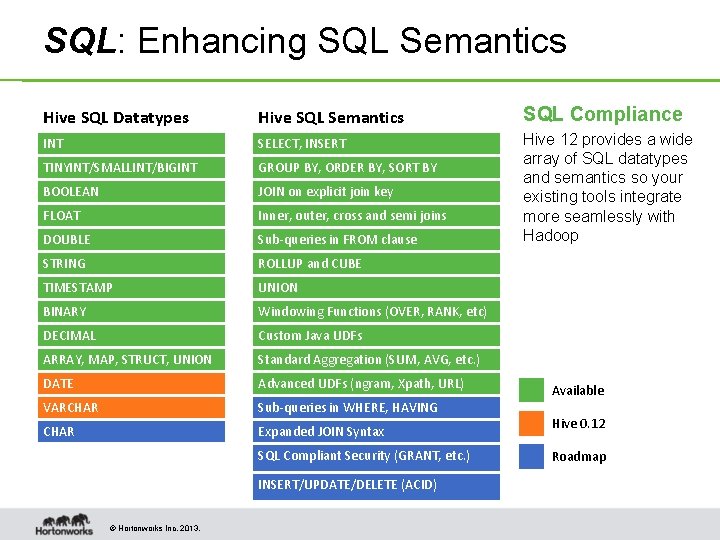
SQL: Enhancing SQL Semantics Hive SQL Datatypes Hive SQL Semantics SQL Compliance INT SELECT, INSERT TINYINT/SMALLINT/BIGINT GROUP BY, ORDER BY, SORT BY BOOLEAN JOIN on explicit join key FLOAT Inner, outer, cross and semi joins DOUBLE Sub-queries in FROM clause Hive 12 provides a wide array of SQL datatypes and semantics so your existing tools integrate more seamlessly with Hadoop STRING ROLLUP and CUBE TIMESTAMP UNION BINARY Windowing Functions (OVER, RANK, etc) DECIMAL Custom Java UDFs ARRAY, MAP, STRUCT, UNION Standard Aggregation (SUM, AVG, etc. ) DATE Advanced UDFs (ngram, Xpath, URL) VARCHAR Sub-queries in WHERE, HAVING CHAR Expanded JOIN Syntax SQL Compliant Security (GRANT, etc. ) INSERT/UPDATE/DELETE (ACID) © Hortonworks Inc. 2013. Available Hive 0. 12 Roadmap
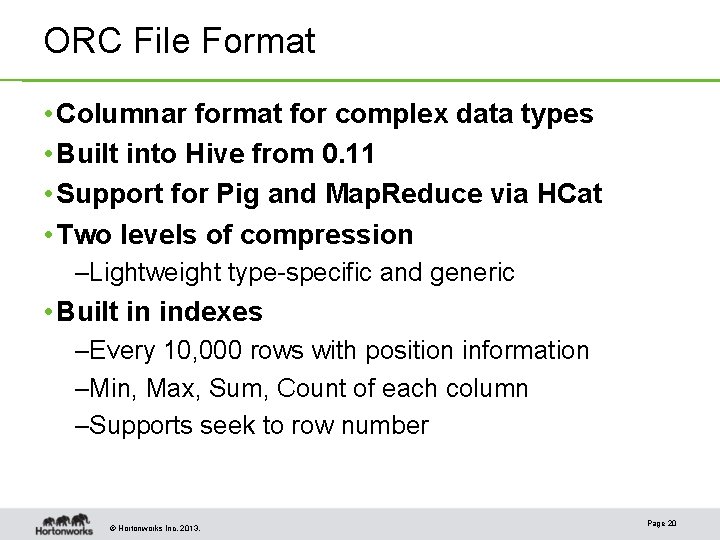
ORC File Format • Columnar format for complex data types • Built into Hive from 0. 11 • Support for Pig and Map. Reduce via HCat • Two levels of compression –Lightweight type-specific and generic • Built in indexes –Every 10, 000 rows with position information –Min, Max, Sum, Count of each column –Supports seek to row number © Hortonworks Inc. 2013. Page 20
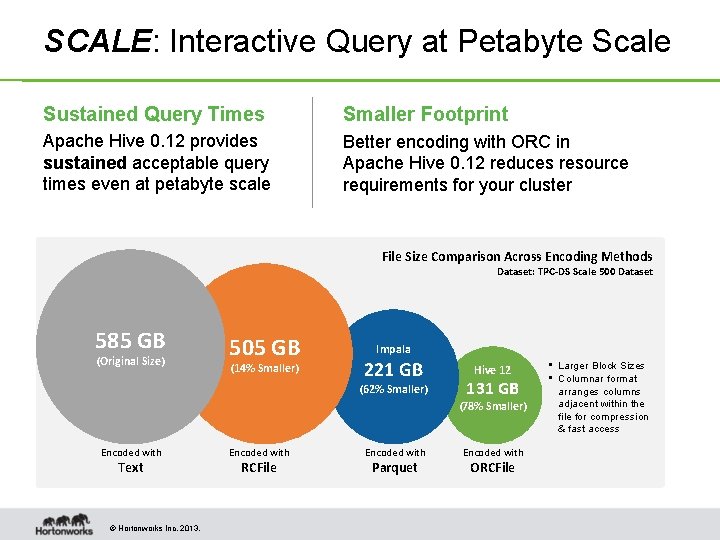
SCALE: Interactive Query at Petabyte Scale Sustained Query Times Smaller Footprint Apache Hive 0. 12 provides sustained acceptable query times even at petabyte scale Better encoding with ORC in Apache Hive 0. 12 reduces resource requirements for your cluster File Size Comparison Across Encoding Methods Dataset: TPC-DS Scale 500 Dataset 585 GB (Original Size) 505 GB (14% Smaller) Impala 221 GB (62% Smaller) Hive 12 131 GB (78% Smaller) Encoded with Text © Hortonworks Inc. 2013. Encoded with RCFile Encoded with Parquet Encoded with ORCFile • Larger Block Sizes • Columnar format arranges columns adjacent within the file for compression & fast access
ORC File Format • Hive 0. 12 –Predicate Push Down –Improved run length encoding –Adaptive string dictionaries –Padding stripes to HDFS block boundaries • Trunk –Stripe-based Input Splits –Input Split elimination –Vectorized Reader –Customized Pig Load and Store functions © Hortonworks Inc. 2013. Page 22
Vectorized Query Execution • Designed for Modern Processor Architectures –Avoid branching in the inner loop. –Make the most use of L 1 and L 2 cache. • How It Works –Process records in batches of 1, 000 rows –Generate code from templates to minimize branching. • What It Gives – 30 x improvement in rows processed per second. –Initial prototype: 100 M rows/sec on laptop © Hortonworks Inc. 2013. Page 23
HDFS Buffer Cache • Use memory mapped buffers for zero copy –Avoid overhead of going through Data. Node –Can mlock the block files into RAM • ORC Reader enhanced for zero-copy reads –New compression interfaces in Hadoop • Vectorization specific reader –Read 1000 rows at a time –Read into Hive’s internal representation © Hortonworks Inc. 2013.
Next Steps • Blog http: //hortonworks. com/blog/delivering-on-stinger-a-phase-3 -progress-update/ • Stinger Initiative http: //hortonworks. com/labs/stinger/ • Stinger Beta: HDP-2. 1 Beta, December, 2013 © Hortonworks Inc. 2013.
Thank You! @acmurthy @alanfgates @owen_omalley @hortonworks © Hortonworks Inc. 2013. Confidential and Proprietary.