On the computational efficiency of training neural network
- Slides: 24
On the computational efficiency of training neural network Roi Livni, Shai Shalev-Shwartz Ohad Shamir
Remainder on neural networks
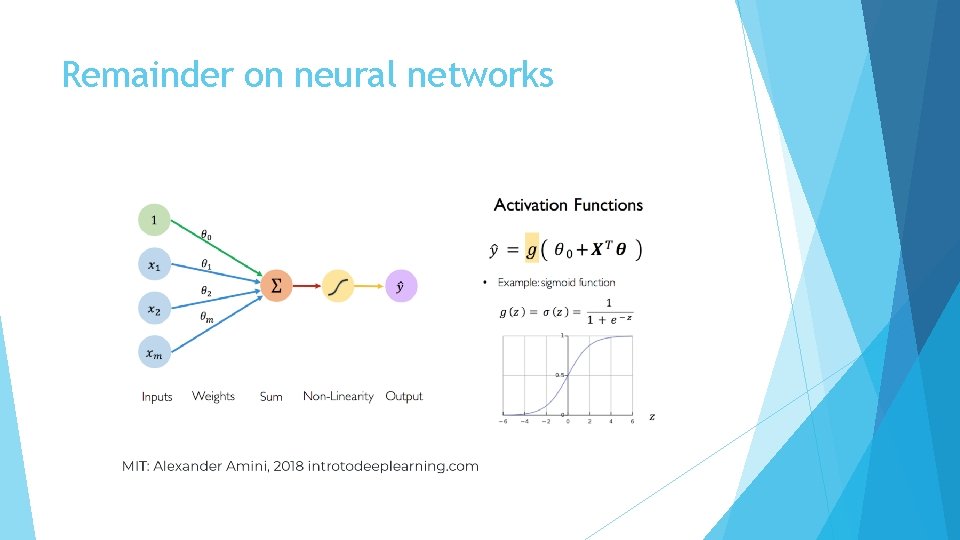
Remainder on neural networks
Why Neural networks? A NN architecture forms an Hypothesis class. Examine it with statistical ML perspectives Sample complexity - # of examples required to learn the class. Expressiveness – Type of functions that can be expressed. Training time – How much computation time is required to learn the class.
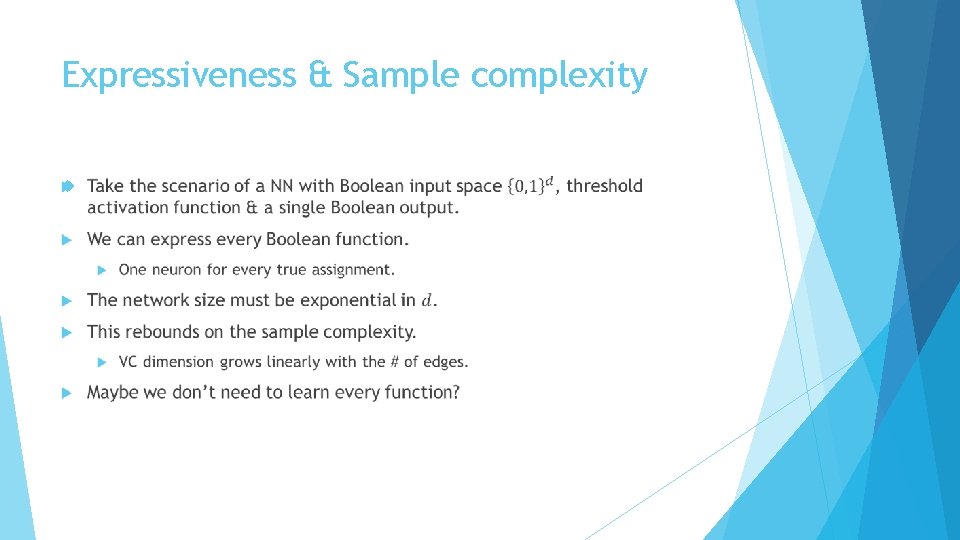
Expressiveness & Sample complexity
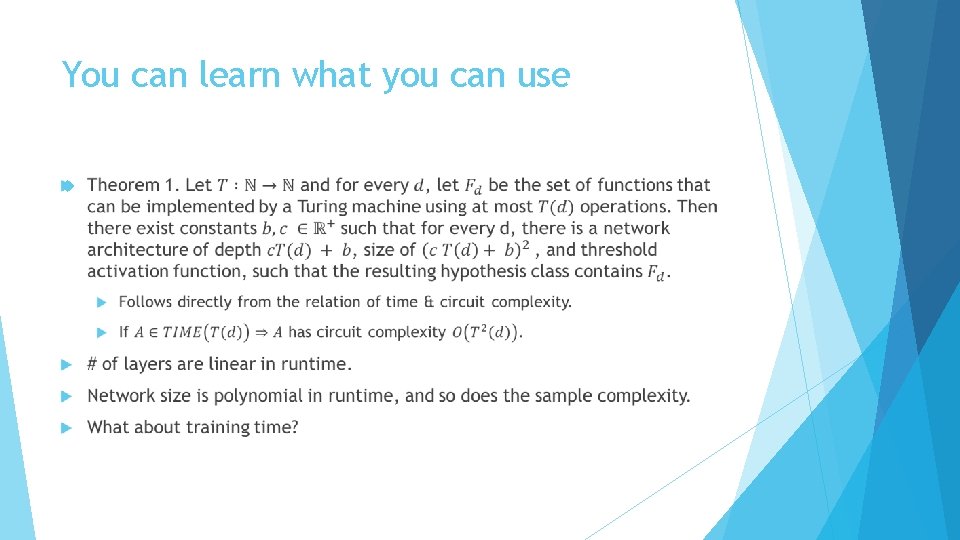
You can learn what you can use
Training time remains main caveat of NN Existing theoretical results are mostly negative. Example: By reducing to k-coloring, finding the weights of NN with depth 2 that best fit the training set is NP-hard. Most results focus on proper learning, but negative results also shown in improper learning. In practice, Modern-day NN are trained successfully, using several tricks: Changing the activation function. Over-specification, i. e. use a much larger NN then needed. Regularization on weights. We’ll revisit these aspects in this talk.
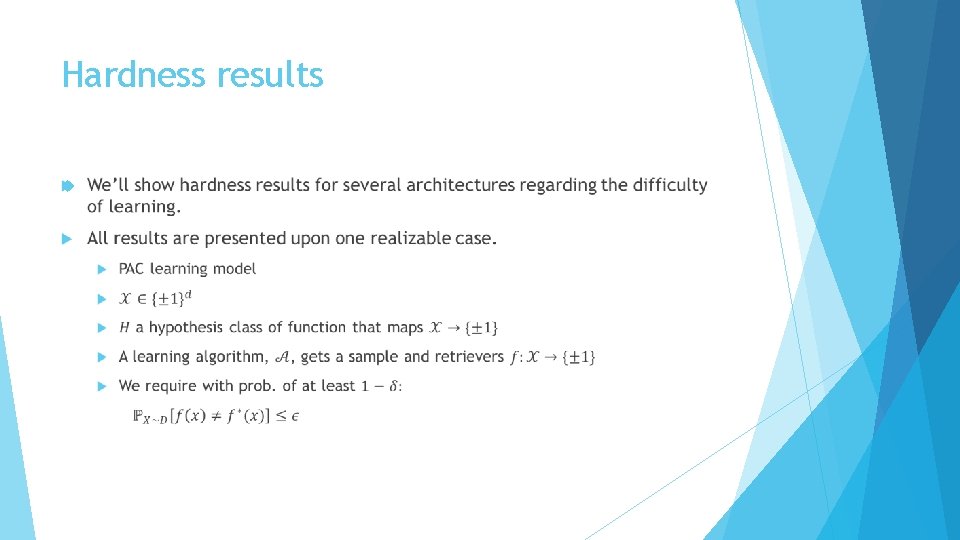
Hardness results
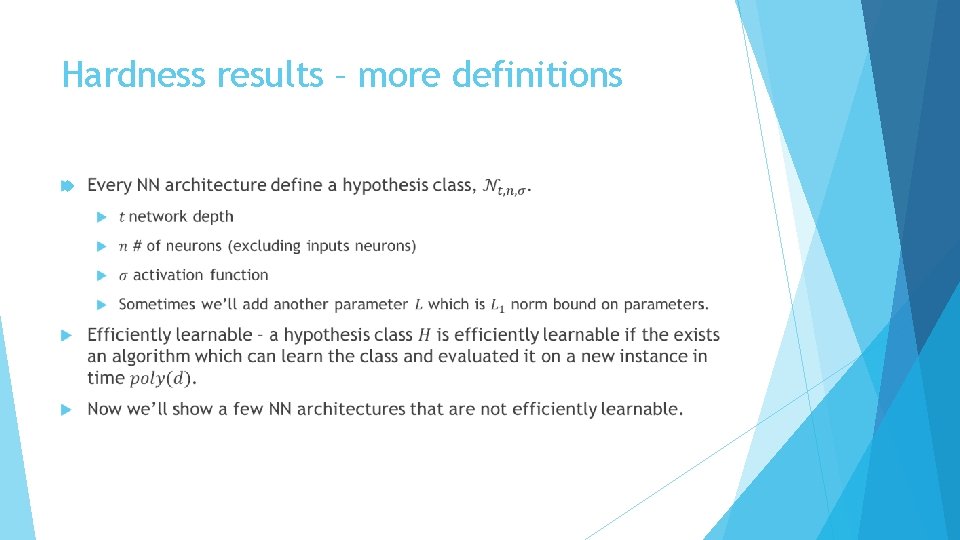
Hardness results – more definitions
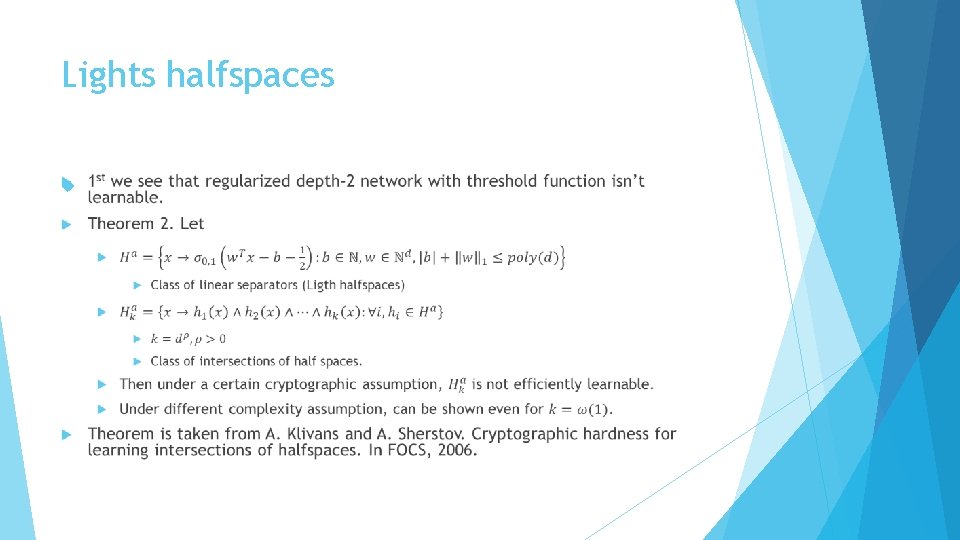
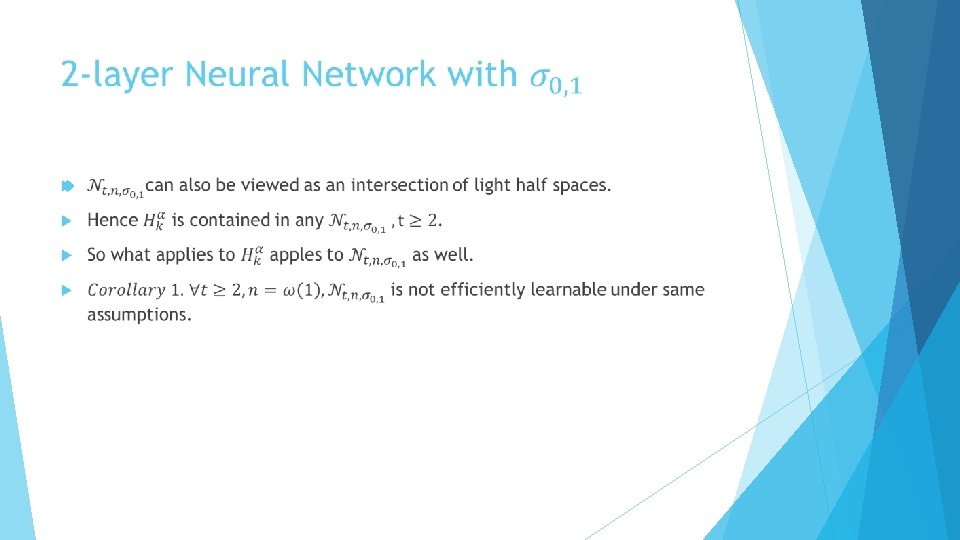
Lights halfspaces
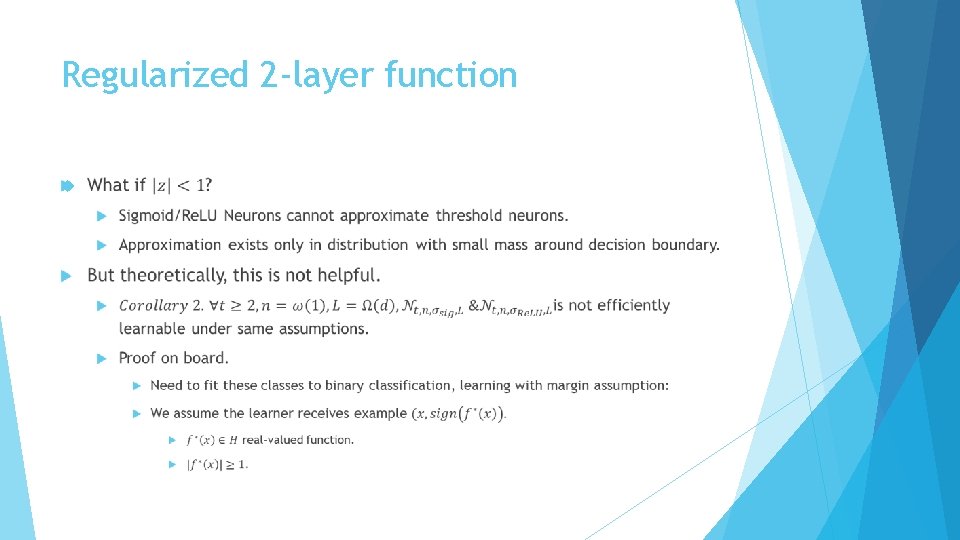
Regularized 2 -layer function
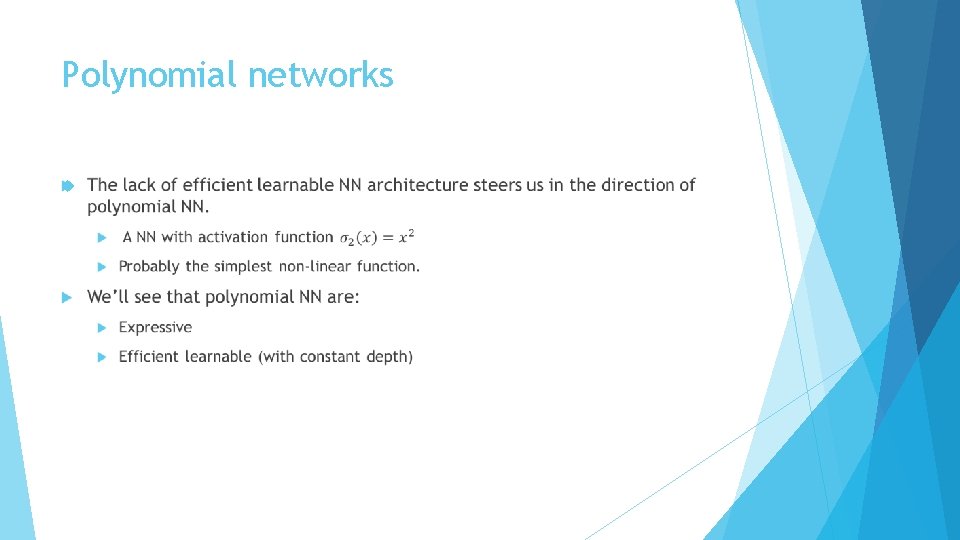
Polynomial networks
Polynomial networks
Polynomial networks
Polynomial networks
Polynomial network
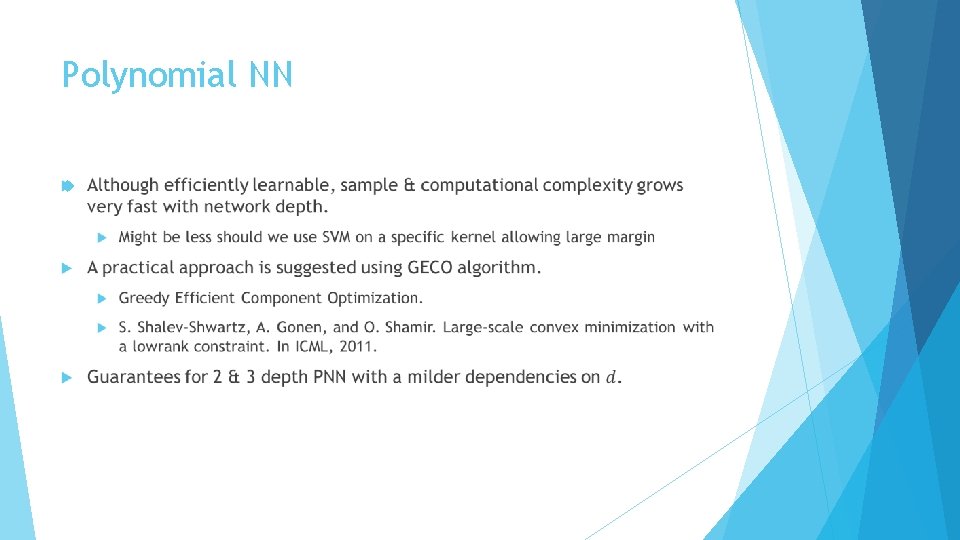
Polynomial NN
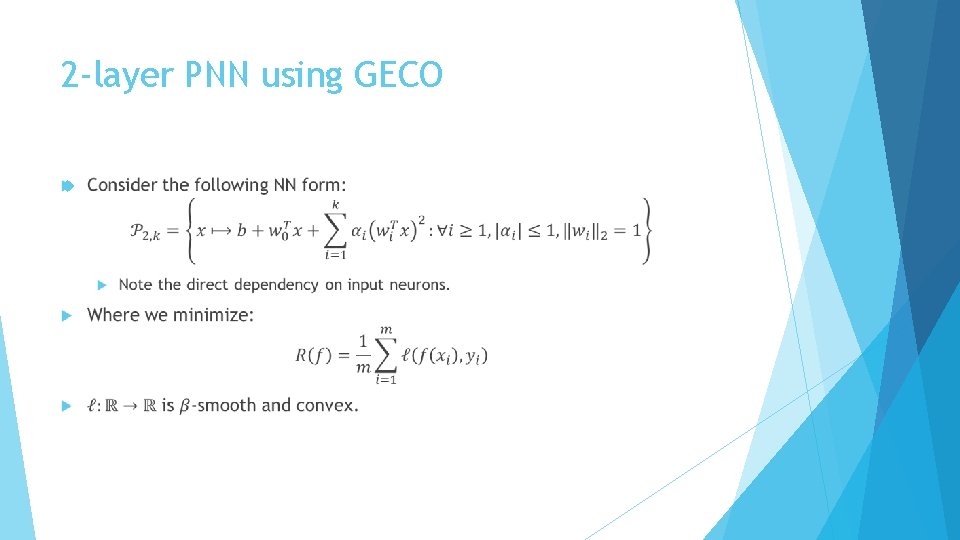
2 -layer PNN using GECO
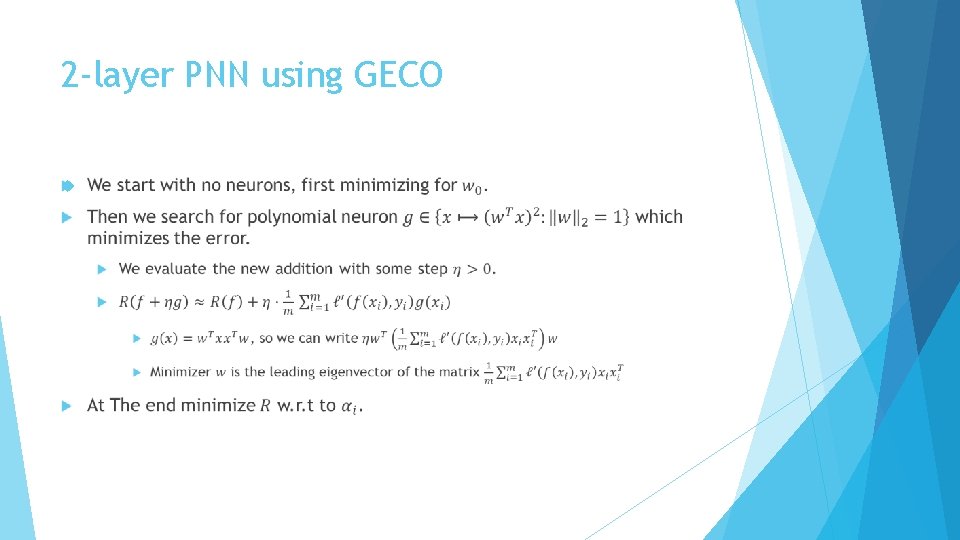
2 -layer PNN using GECO
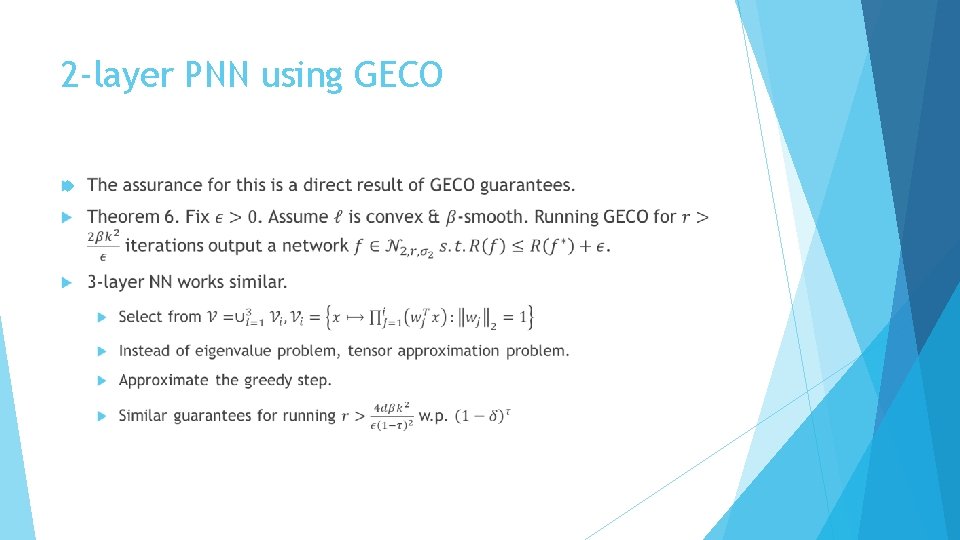
2 -layer PNN using GECO
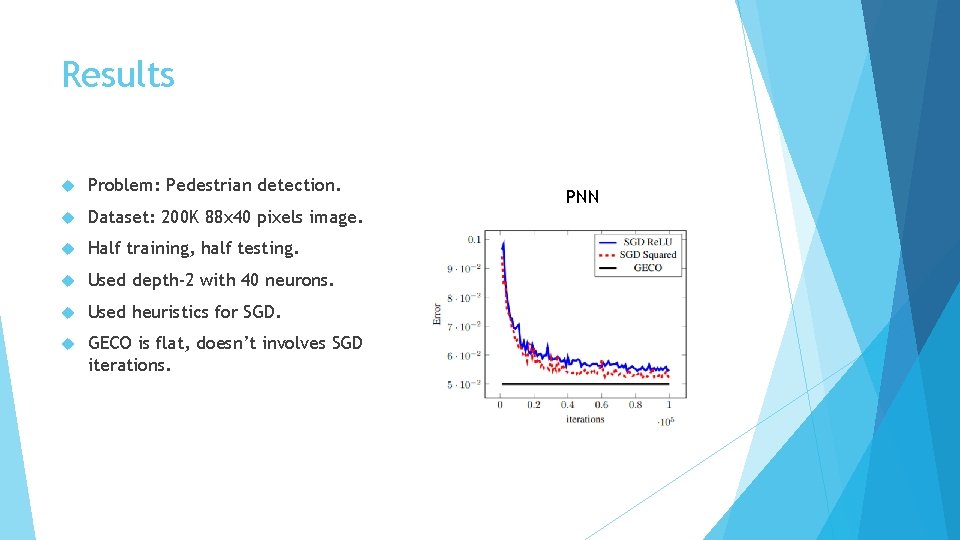
Results Problem: Pedestrian detection. Dataset: 200 K 88 x 40 pixels image. Half training, half testing. Used depth-2 with 40 neurons. Used heuristics for SGD. GECO is flat, doesn’t involves SGD iterations. PNN