Lecture 1 Flynns Taxonomy CDA 4150 Eurpides Montagne
- Slides: 51
Lecture 1: Flynn’s Taxonomy CDA 4150 Eurípides Montagne University of Central Florida 1
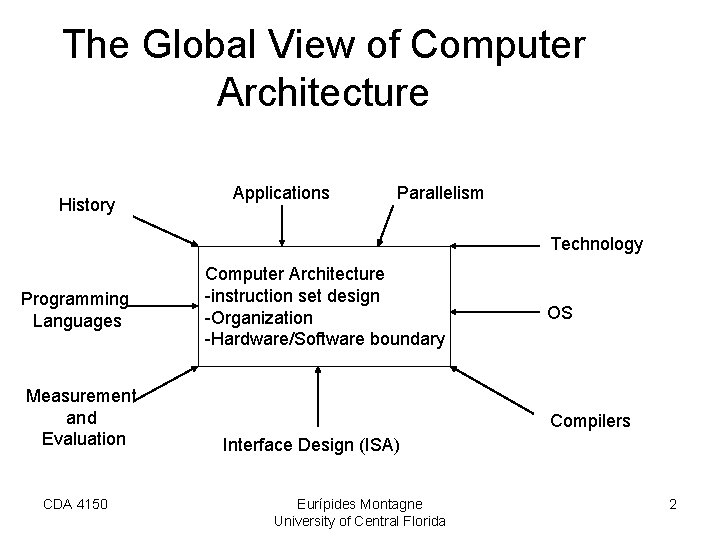
The Global View of Computer Architecture History Applications Parallelism Technology Programming Languages Measurement and Evaluation CDA 4150 Computer Architecture -instruction set design -Organization -Hardware/Software boundary OS Compilers Interface Design (ISA) Eurípides Montagne University of Central Florida 2
The Task of A Computer Designer – Determine what attributes are important for a new machine. – Design a machine to maximize performance while staying within cost constrains. CDA 4150 Eurípides Montagne University of Central Florida 3
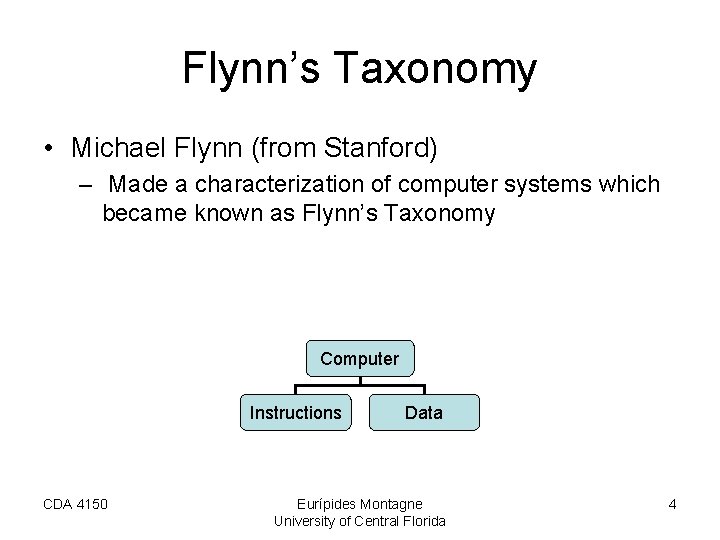
Flynn’s Taxonomy • Michael Flynn (from Stanford) – Made a characterization of computer systems which became known as Flynn’s Taxonomy Computer Instructions CDA 4150 Data Eurípides Montagne University of Central Florida 4
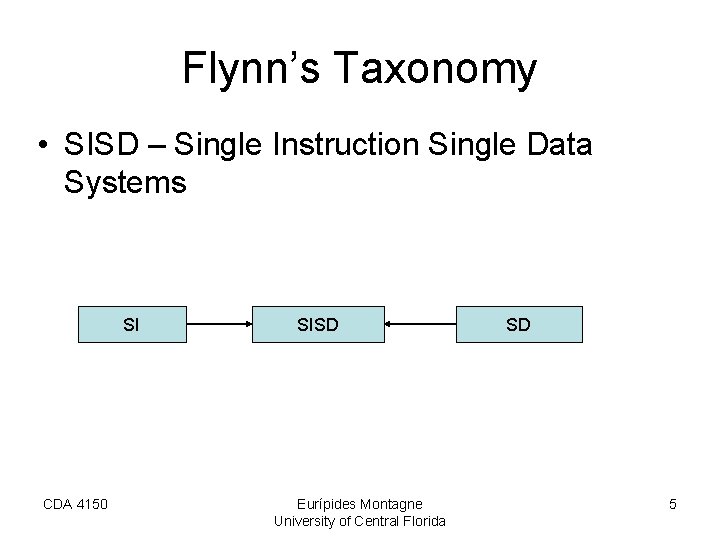
Flynn’s Taxonomy • SISD – Single Instruction Single Data Systems SI CDA 4150 SISD Eurípides Montagne University of Central Florida SD 5
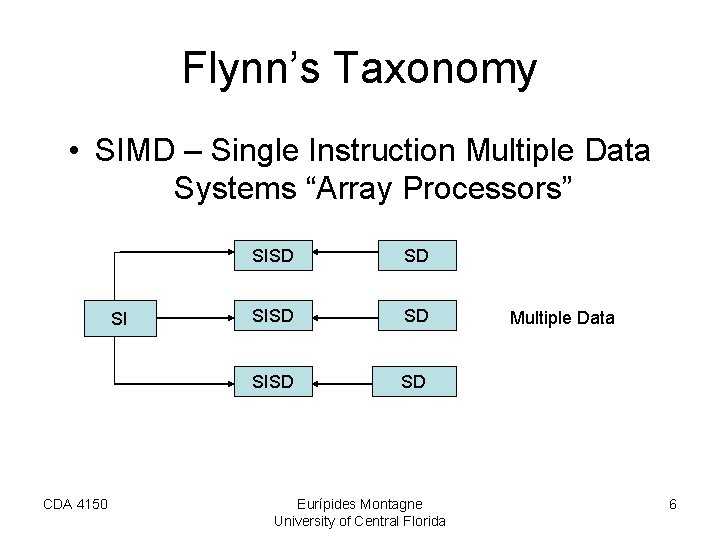
Flynn’s Taxonomy • SIMD – Single Instruction Multiple Data Systems “Array Processors” SI CDA 4150 SISD SD Eurípides Montagne University of Central Florida Multiple Data 6
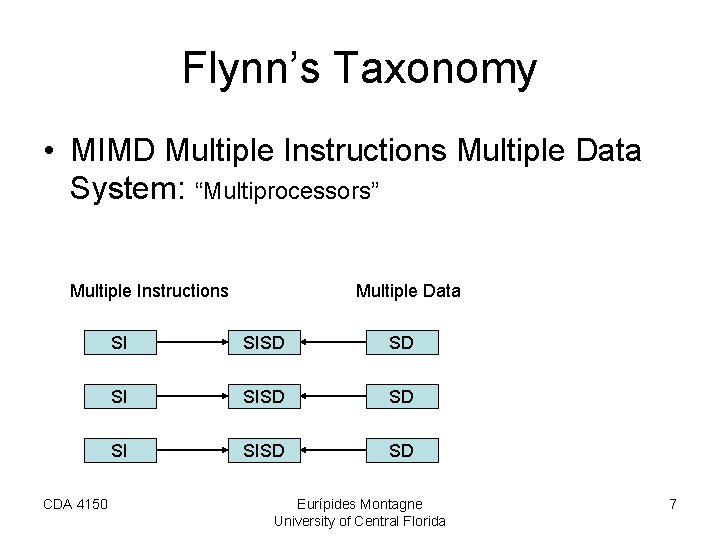
Flynn’s Taxonomy • MIMD Multiple Instructions Multiple Data System: “Multiprocessors” Multiple Instructions CDA 4150 Multiple Data SI SISD SD Eurípides Montagne University of Central Florida 7
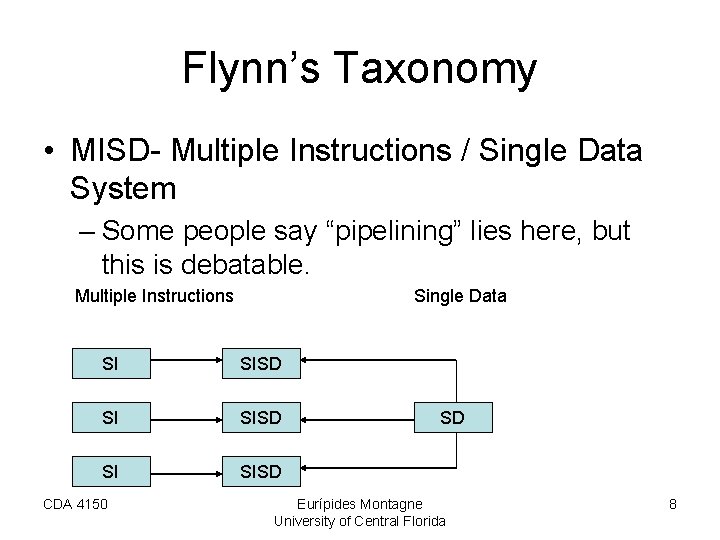
Flynn’s Taxonomy • MISD- Multiple Instructions / Single Data System – Some people say “pipelining” lies here, but this is debatable. Multiple Instructions Single Data SI SISD CDA 4150 SD Eurípides Montagne University of Central Florida 8
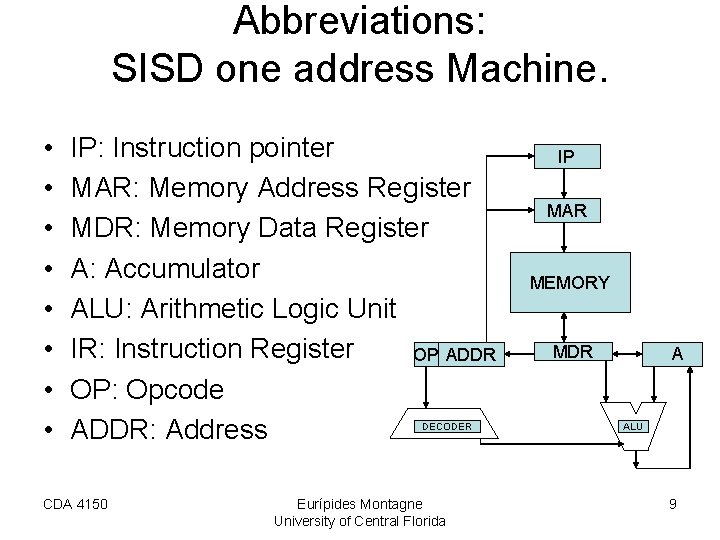
Abbreviations: SISD one address Machine. • • IP: Instruction pointer MAR: Memory Address Register MDR: Memory Data Register A: Accumulator ALU: Arithmetic Logic Unit IR: Instruction Register OP ADDR OP: Opcode ADDR: Address CDA 4150 DECODER Eurípides Montagne University of Central Florida IP MAR MEMORY MDR A ALU 9
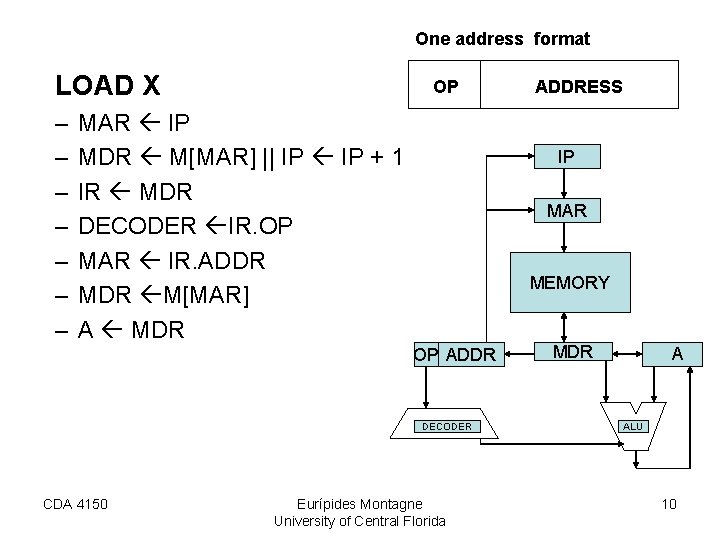
One address format LOAD X – – – – OP MAR IP MDR M[MAR] || IP + 1 IR MDR DECODER IR. OP MAR IR. ADDR M[MAR] A MDR IP MAR MEMORY OP ADDR DECODER CDA 4150 ADDRESS Eurípides Montagne University of Central Florida MDR A ALU 10
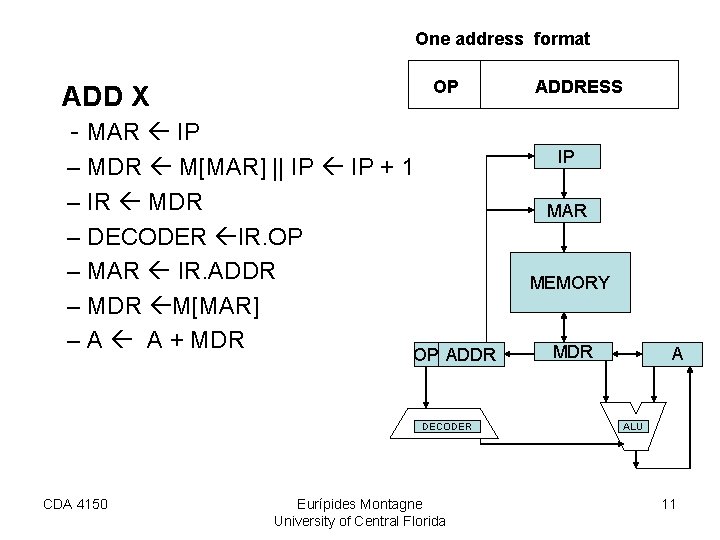
One address format OP ADD X - MAR IP IP – MDR M[MAR] || IP + 1 – IR MDR – DECODER IR. OP – MAR IR. ADDR – MDR M[MAR] – A A + MDR MAR MEMORY OP ADDR DECODER CDA 4150 ADDRESS Eurípides Montagne University of Central Florida MDR A ALU 11
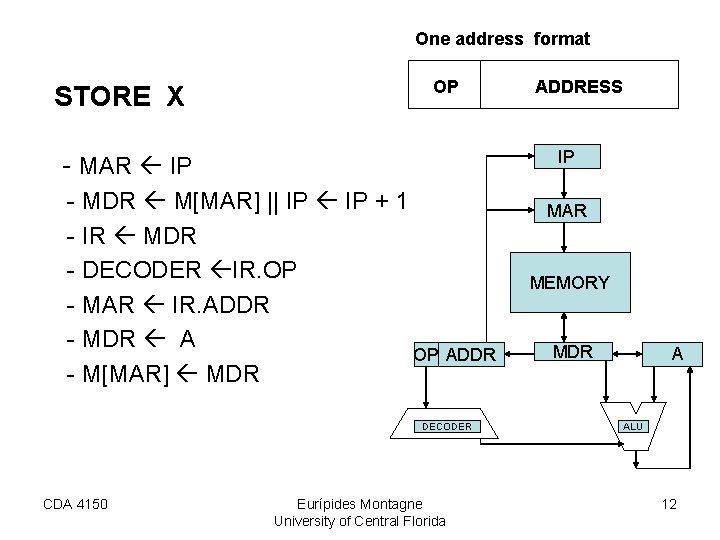
One address format STORE X OP IP - MAR IP - MDR M[MAR] || IP + 1 - IR MDR - DECODER IR. OP - MAR IR. ADDR - MDR A OP ADDR - M[MAR] MDR DECODER CDA 4150 ADDRESS Eurípides Montagne University of Central Florida MAR MEMORY MDR A ALU 12
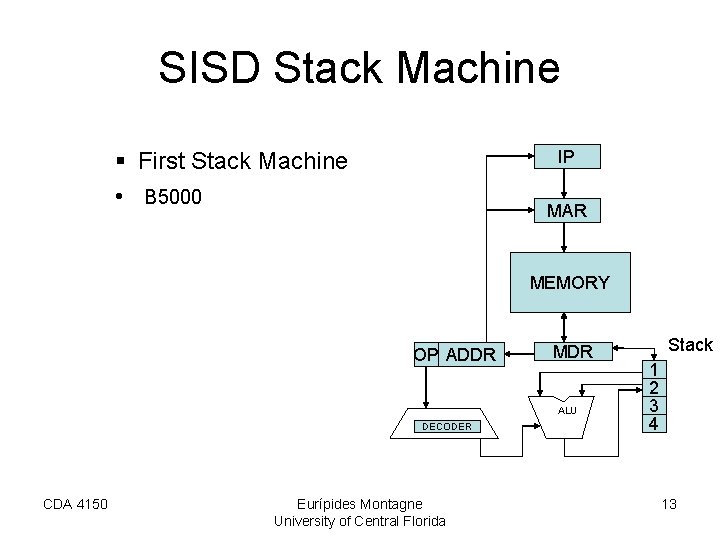
SISD Stack Machine IP § First Stack Machine • B 5000 MAR MEMORY OP ADDR MDR ALU DECODER CDA 4150 Eurípides Montagne University of Central Florida Stack 1 2 3 4 13
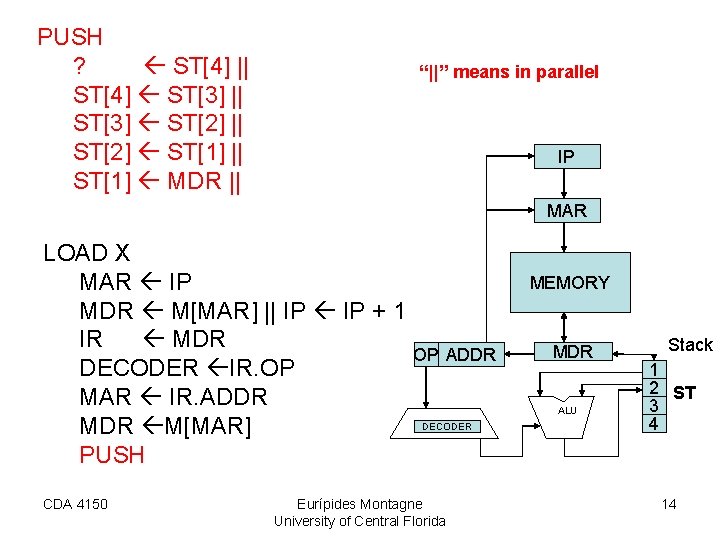
PUSH ? ST[4] || ST[4] ST[3] || ST[3] ST[2] || ST[2] ST[1] || ST[1] MDR || “||” means in parallel IP MAR LOAD X MAR IP MDR M[MAR] || IP + 1 IR MDR OP ADDR DECODER IR. OP MAR IR. ADDR DECODER MDR M[MAR] PUSH CDA 4150 Eurípides Montagne University of Central Florida MEMORY MDR ALU Stack 1 2 ST 3 4 14
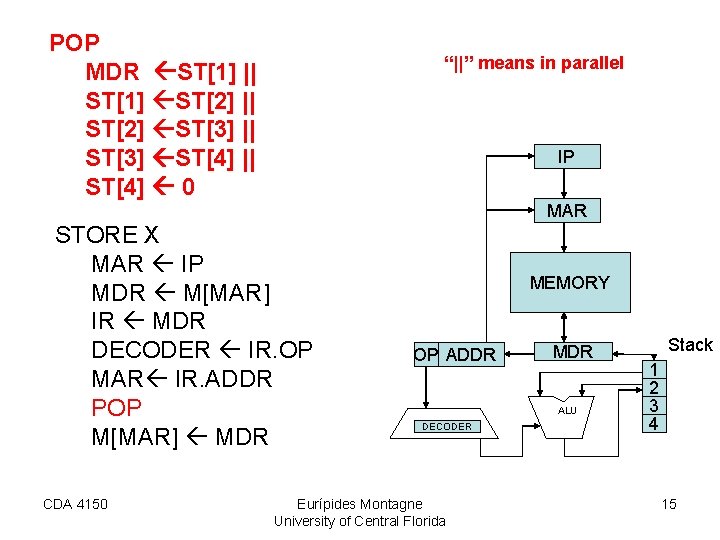
POP MDR ST[1] || ST[1] ST[2] || ST[2] ST[3] || ST[3] ST[4] || ST[4] 0 “||” means in parallel IP MAR STORE X MAR IP MDR M[MAR] IR MDR DECODER IR. OP MAR IR. ADDR POP M[MAR] MDR CDA 4150 MEMORY OP ADDR MDR ALU DECODER Eurípides Montagne University of Central Florida Stack 1 2 3 4 15
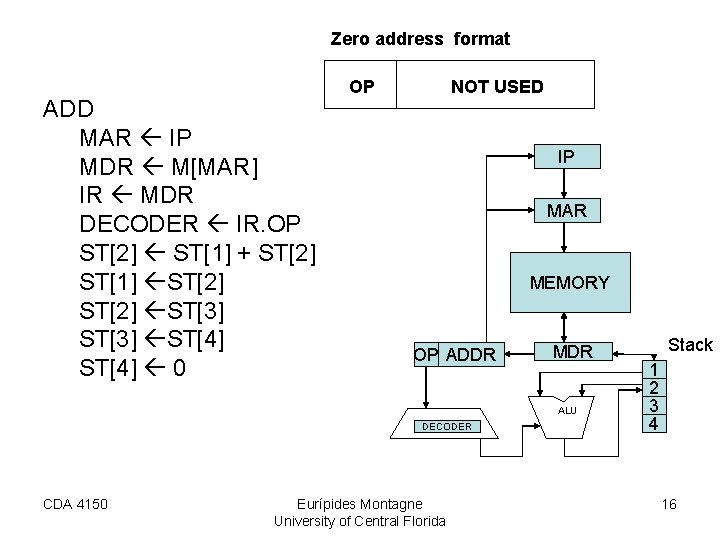
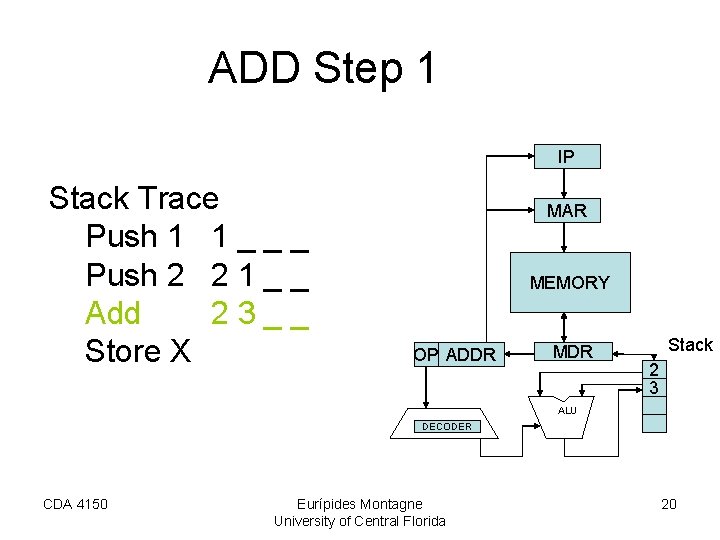
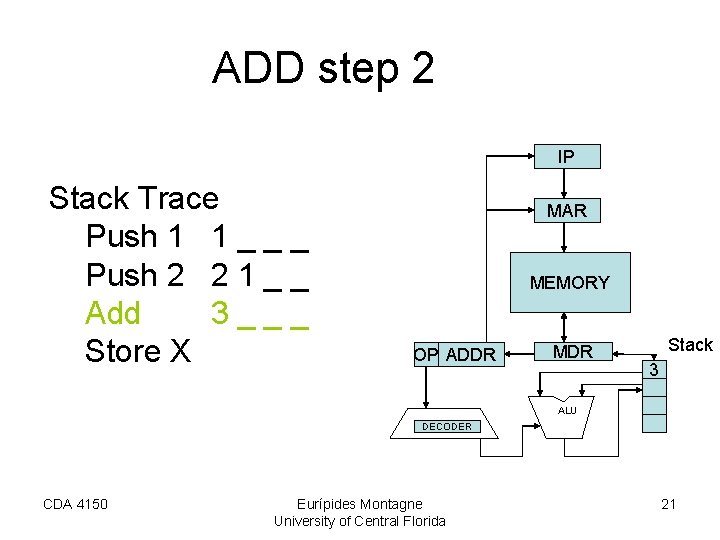
Zero address format ADD MAR IP MDR M[MAR] IR MDR DECODER IR. OP ST[2] ST[1] + ST[2] ST[1] ST[2] ST[3] ST[4] 0 OP NOT USED IP MAR MEMORY OP ADDR MDR ALU DECODER CDA 4150 Eurípides Montagne University of Central Florida Stack 1 2 3 4 16
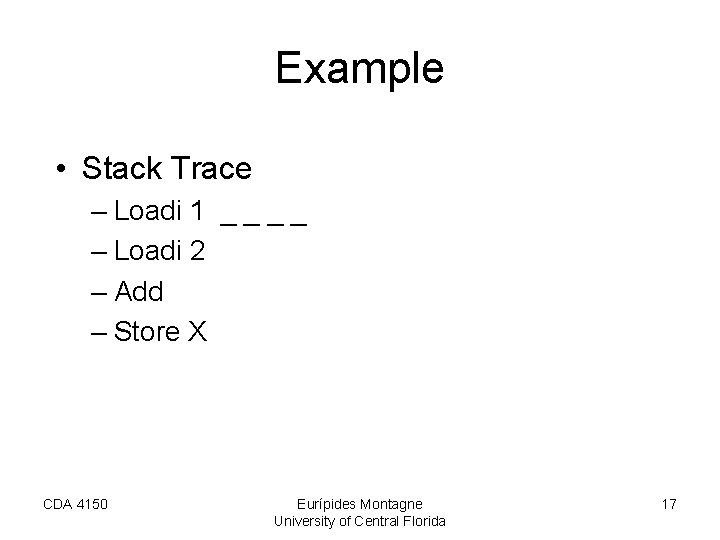
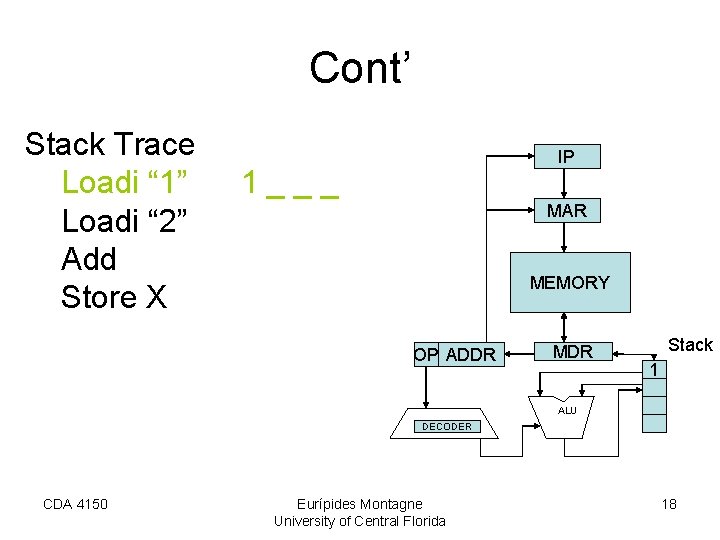
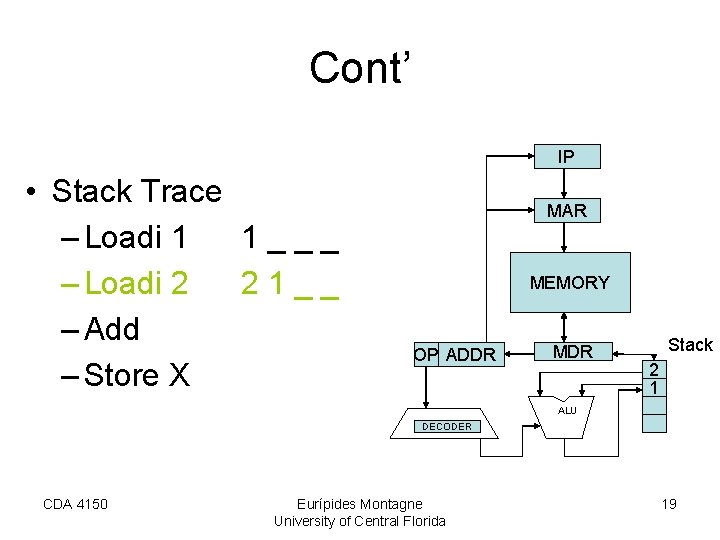
Example • Stack Trace – Loadi 1 _ _ – Loadi 2 – Add – Store X CDA 4150 Eurípides Montagne University of Central Florida 17
Cont’ Stack Trace Loadi “ 1” Loadi “ 2” Add Store X IP 1___ MAR MEMORY OP ADDR MDR Stack 1 ALU DECODER CDA 4150 Eurípides Montagne University of Central Florida 18
Cont’ IP • Stack Trace – Loadi 1 1___ – Loadi 2 21__ – Add – Store X MAR MEMORY OP ADDR MDR Stack 2 1 ALU DECODER CDA 4150 Eurípides Montagne University of Central Florida 19
ADD Step 1 IP Stack Trace Push 1 1 _ _ _ Push 2 2 1 _ _ Add 23__ Store X MAR MEMORY OP ADDR MDR Stack 2 3 ALU DECODER CDA 4150 Eurípides Montagne University of Central Florida 20
ADD step 2 IP Stack Trace Push 1 1 _ _ _ Push 2 2 1 _ _ Add 3___ Store X MAR MEMORY OP ADDR MDR Stack 3 ALU DECODER CDA 4150 Eurípides Montagne University of Central Florida 21
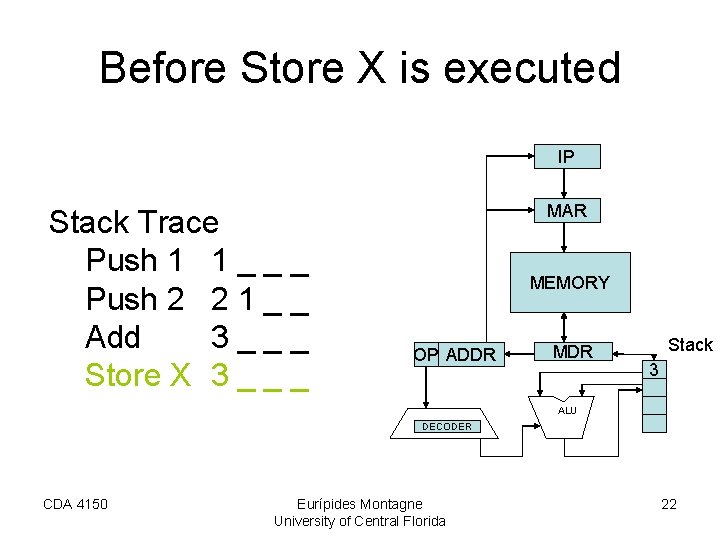
Before Store X is executed IP Stack Trace Push 1 1 _ _ _ Push 2 2 1 _ _ Add 3___ Store X 3 _ _ _ MAR MEMORY OP ADDR MDR Stack 3 ALU DECODER CDA 4150 Eurípides Montagne University of Central Florida 22
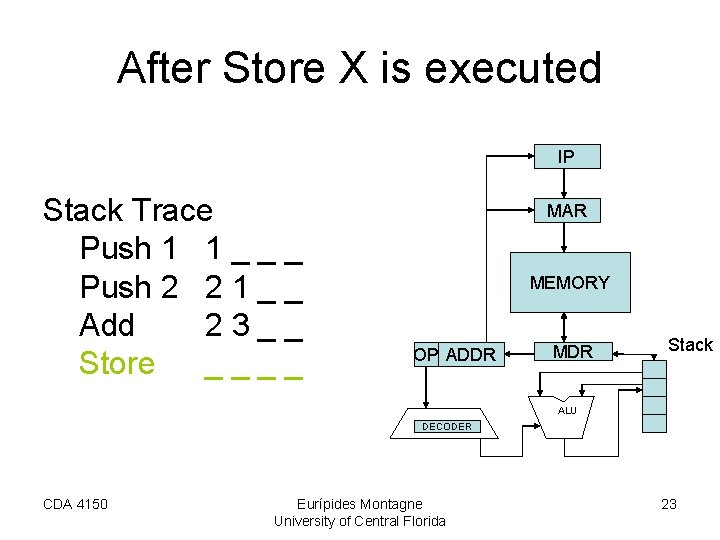
After Store X is executed IP Stack Trace Push 1 1 _ _ _ Push 2 2 1 _ _ Add 23__ Store ____ MAR MEMORY OP ADDR MDR Stack ALU DECODER CDA 4150 Eurípides Montagne University of Central Florida 23
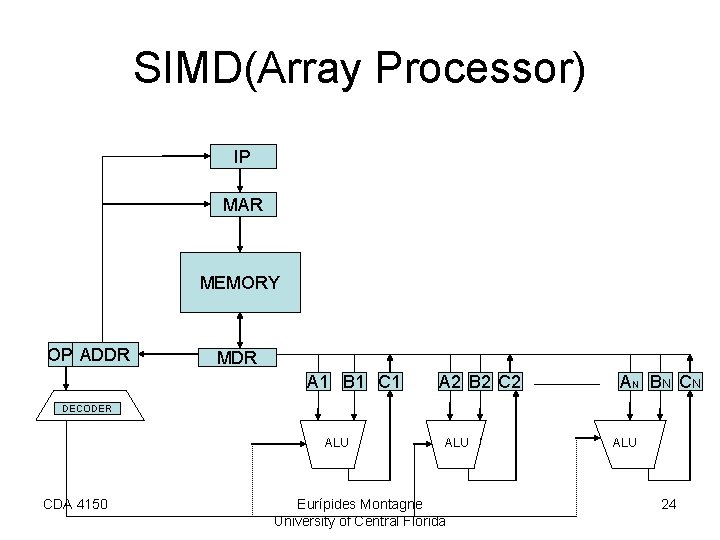
SIMD(Array Processor) IP MAR MEMORY OP ADDR MDR A 1 B 1 C 1 A 2 B 2 C 2 A N B N CN DECODER ALU CDA 4150 ALU Eurípides Montagne University of Central Florida ALU 24
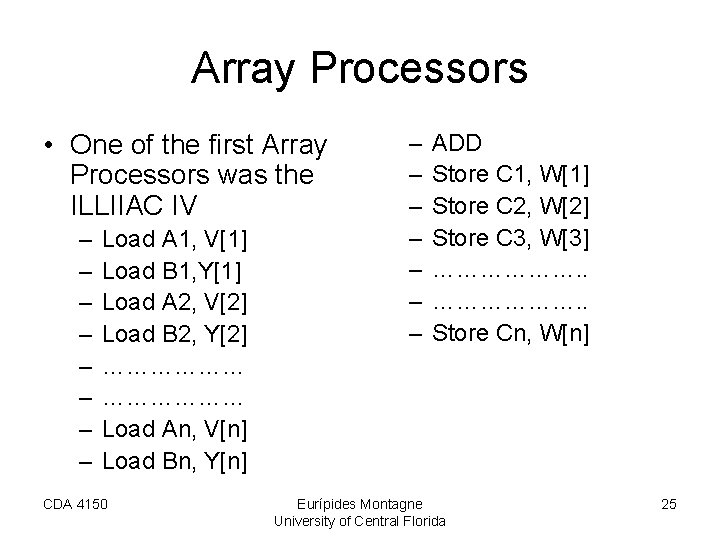
Array Processors • One of the first Array Processors was the ILLIIAC IV – – – – Load A 1, V[1] Load B 1, Y[1] Load A 2, V[2] Load B 2, Y[2] ……………… Load An, V[n] Load Bn, Y[n] CDA 4150 – – – – ADD Store C 1, W[1] Store C 2, W[2] Store C 3, W[3] ………………. . Store Cn, W[n] Eurípides Montagne University of Central Florida 25
Pipelining • Definition: Pipelining is an implementation technique whereby multiple instructions are overlapped in execution, taking advantage of parallelism that exists among actions needed to execute an instruction. • Example: Pipelining is similar to an automobile assembly line. CDA 4150 Eurípides Montagne University of Central Florida 26
Pipelining: Automobile Assembly line • • T 0: Frame| T 1: Frame| wheels T 2: Frame| wheels| Engine T 3: Frame| Wheels| Engine| Body New Car If it takes 1 hour to complete one car, and each of the above stages takes 15 minutes, then building the first car takes 1 hour; one car can produced every 15 minutes. This same principle can be applied to computer instructions. CDA 4150 Eurípides Montagne University of Central Florida 27
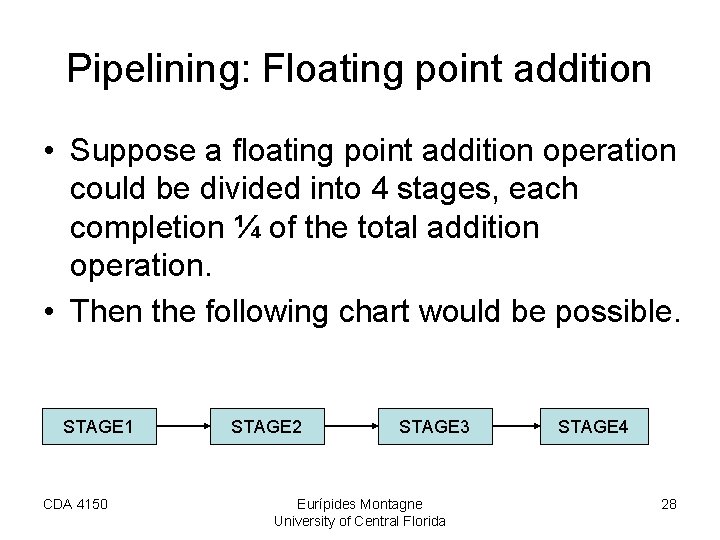
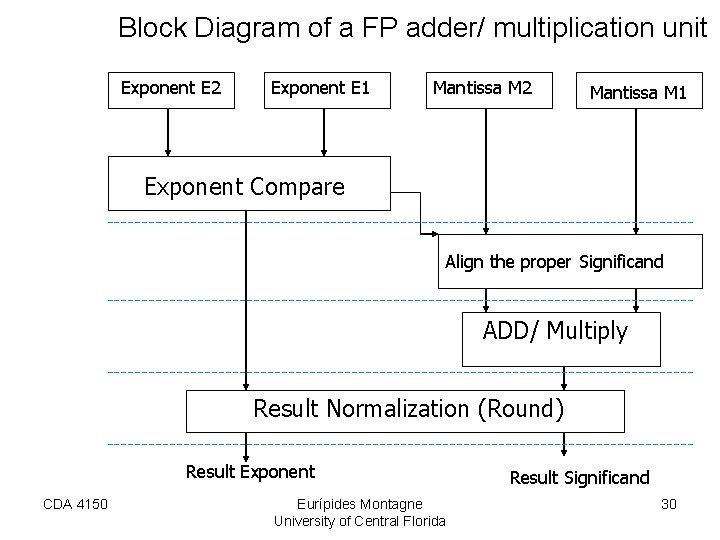
Pipelining: Floating point addition • Suppose a floating point addition operation could be divided into 4 stages, each completion ¼ of the total addition operation. • Then the following chart would be possible. STAGE 1 CDA 4150 STAGE 2 STAGE 3 Eurípides Montagne University of Central Florida STAGE 4 28
The steps • Step one: Compare and choose the exponents. • Step two: Set both numbers to the same exponent. • Step three: Perform addition/subtraction on the two numbers. • Last step: Normalization. CDA 4150 Eurípides Montagne University of Central Florida 29
Block Diagram of a FP adder/ multiplication unit Exponent E 2 Exponent E 1 Mantissa M 2 Mantissa M 1 Exponent Compare Align the proper Significand ADD/ Multiply Result Normalization (Round) Result Exponent CDA 4150 Eurípides Montagne University of Central Florida Result Significand 30
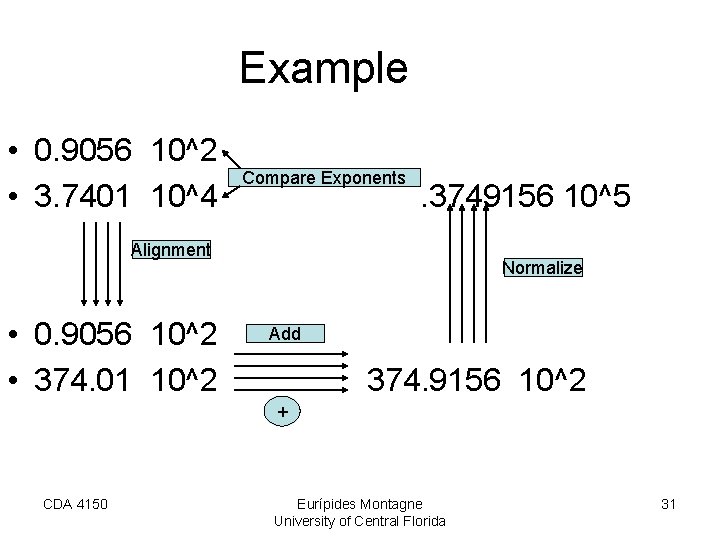
Example • 0. 9056 10^2 • 3. 7401 10^4 Compare Exponents . 3749156 10^5 Alignment • 0. 9056 10^2 • 374. 01 10^2 Normalize Add 374. 9156 10^2 + CDA 4150 Eurípides Montagne University of Central Florida 31
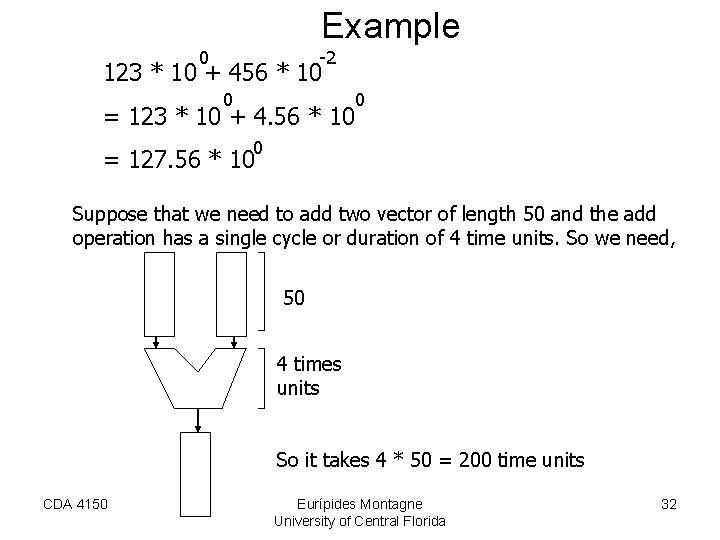
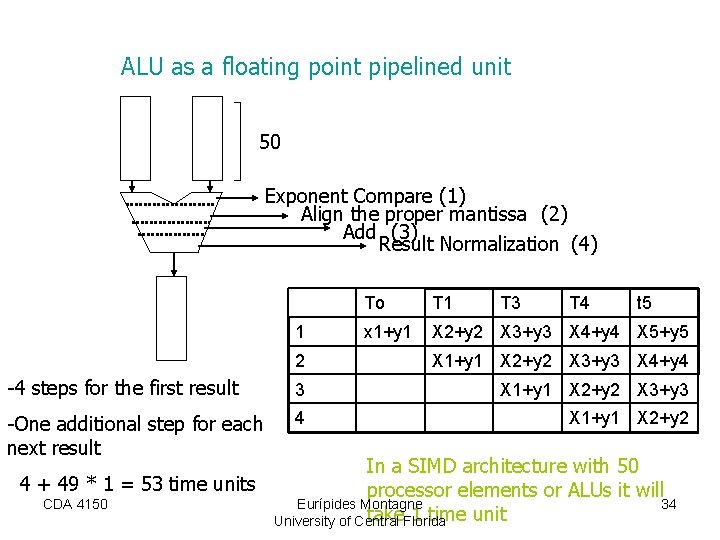
Example 0 -2 123 * 10 + 456 * 10 0 = 123 * 10 + 4. 56 * 10 0 0 = 127. 56 * 10 Suppose that we need to add two vector of length 50 and the add operation has a single cycle or duration of 4 time units. So we need, 50 4 times units So it takes 4 * 50 = 200 time units CDA 4150 Eurípides Montagne University of Central Florida 32
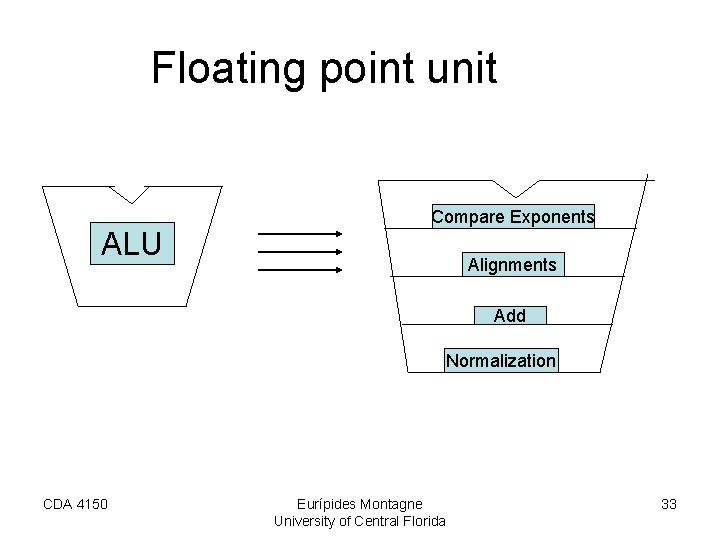
Floating point unit ALU Compare Exponents Alignments Add Normalization CDA 4150 Eurípides Montagne University of Central Florida 33
ALU as a floating point pipelined unit 50 Exponent Compare (1) Align the proper mantissa (2) Add (3) Result Normalization (4) 1 To T 1 T 3 T 4 t 5 x 1+y 1 X 2+y 2 X 3+y 3 X 4+y 4 X 5+y 5 2 X 1+y 1 X 2+y 2 X 3+y 3 X 4+y 4 -4 steps for the first result 3 X 1+y 1 X 2+y 2 X 3+y 3 -One additional step for each next result 4 X 1+y 1 X 2+y 2 In a SIMD architecture with 50 4 + 49 * 1 = 53 time units processor elements or ALUs it will CDA 4150 Eurípides Montagne 34 take 1 time unit University of Central Florida
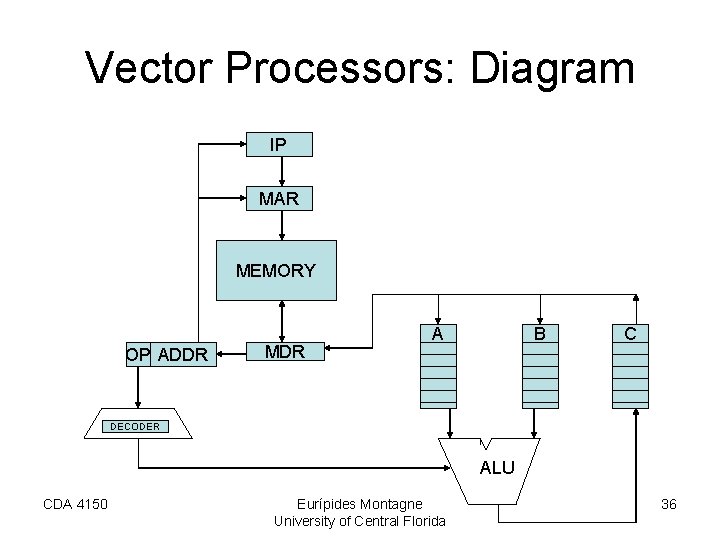
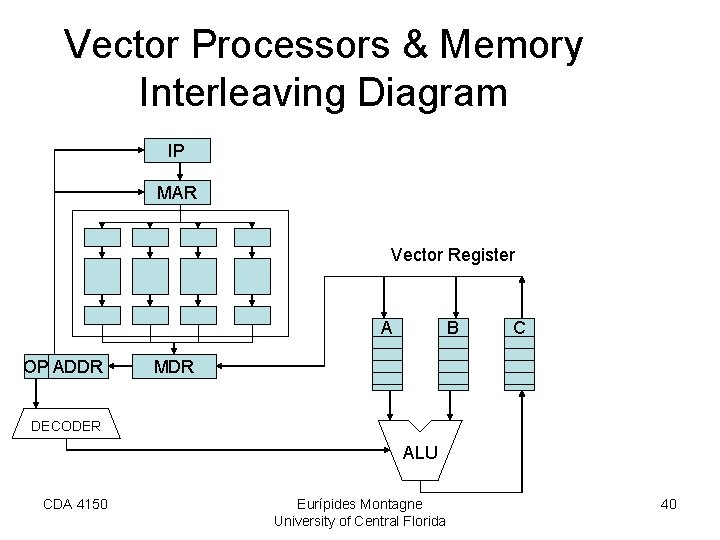
Vector processors Vector processor Characteristics: - Pipelining is used in processing. - Vector Registers are used to provide the ALU with constant input. - Memory interleaving is used to load input to the vector registers. - AKA Supercomputers. - the CRAY-1 is regarded as the first of these types. CDA 4150 Eurípides Montagne University of Central Florida 35
Vector Processors: Diagram IP MAR MEMORY OP ADDR MDR A B C DECODER ALU CDA 4150 Eurípides Montagne University of Central Florida 36
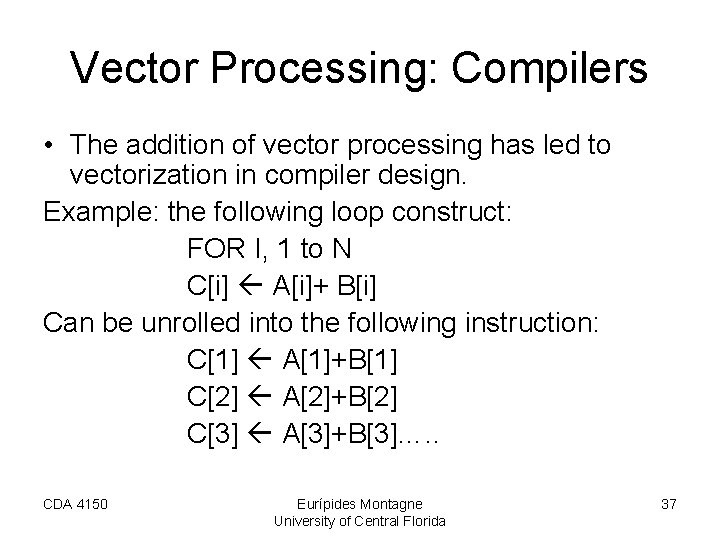
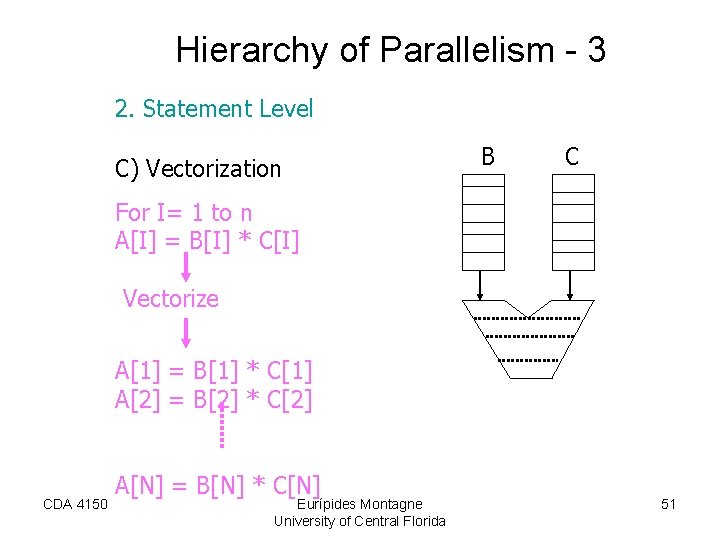
Vector Processing: Compilers • The addition of vector processing has led to vectorization in compiler design. Example: the following loop construct: FOR I, 1 to N C[i] A[i]+ B[i] Can be unrolled into the following instruction: C[1] A[1]+B[1] C[2] A[2]+B[2] C[3] A[3]+B[3]…. . CDA 4150 Eurípides Montagne University of Central Florida 37
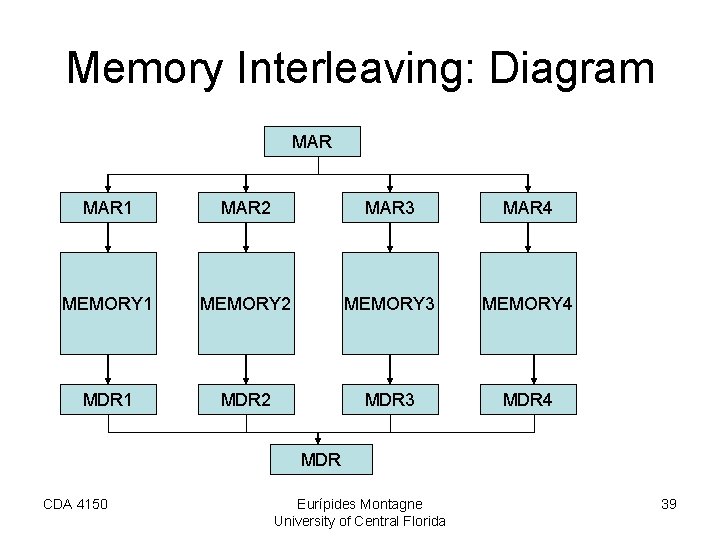
Memory Interleaving • Definition: Memory Interleaving is a design used to gain faster access to memory, by organizing memory into separate memory banks, each with their own MAR (memory address register). This allows parallel access and eliminates the required wait for a single MAR to finish a memory access. CDA 4150 Eurípides Montagne University of Central Florida 38
Memory Interleaving: Diagram MAR 1 MAR 2 MAR 3 MAR 4 MEMORY 1 MEMORY 2 MEMORY 3 MEMORY 4 MDR 1 MDR 2 MDR 3 MDR 4 MDR CDA 4150 Eurípides Montagne University of Central Florida 39
Vector Processors & Memory Interleaving Diagram IP MAR Vector Register A OP ADDR B C MDR DECODER ALU CDA 4150 Eurípides Montagne University of Central Florida 40
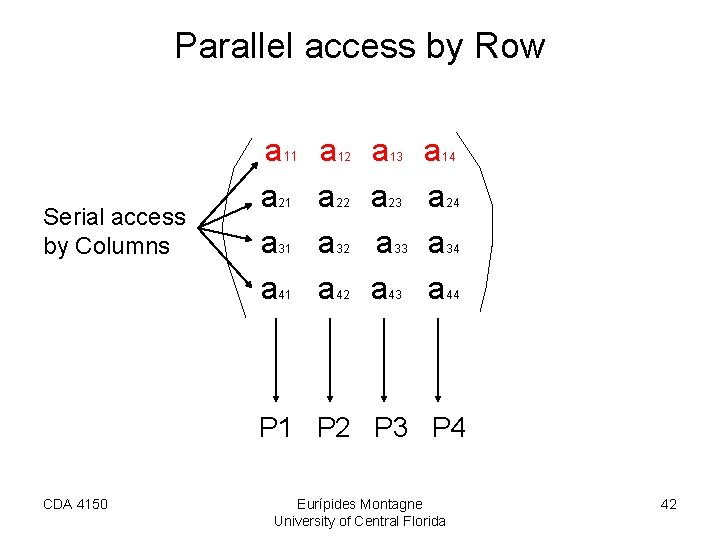
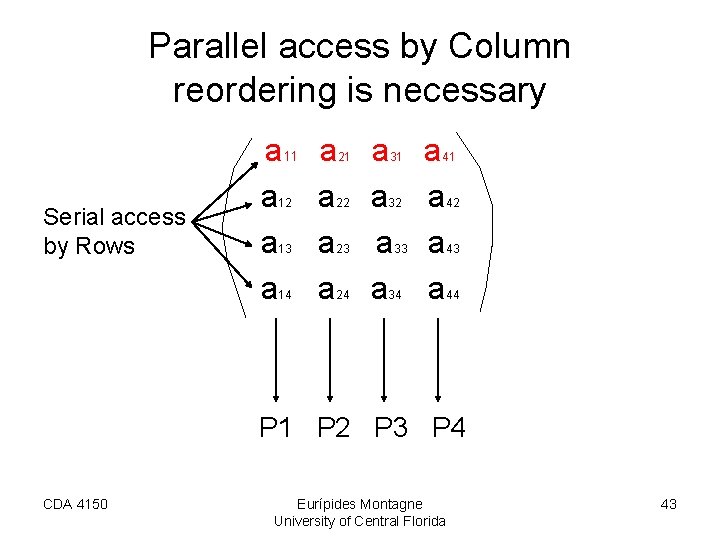
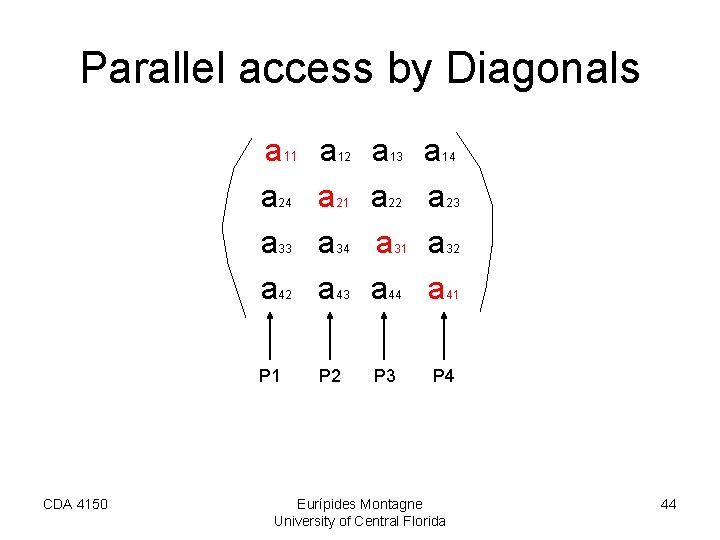
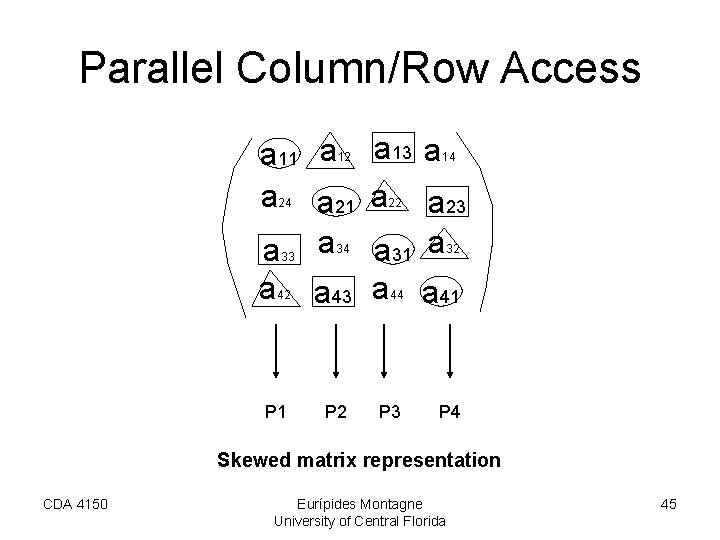
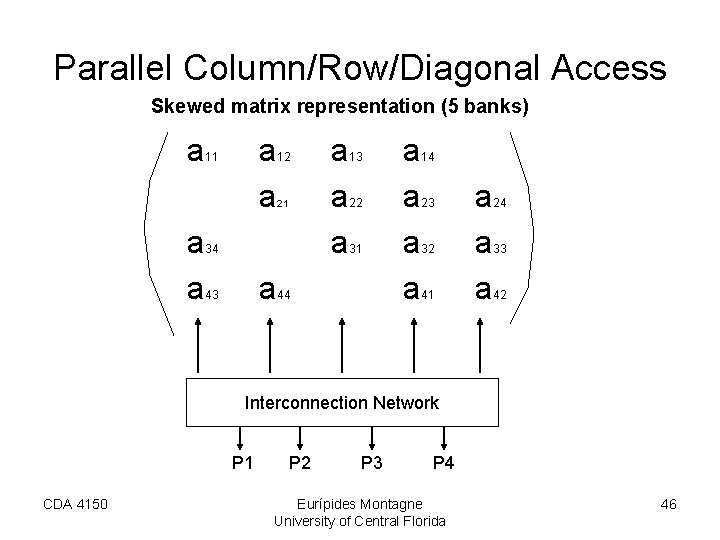
Matrix Access • Parallel access by Rows • Parallel access by Columns • Parallel access by Diagonals • Skewed matrix representation CDA 4150 Eurípides Montagne University of Central Florida 41
Parallel access by Row Serial access by Columns a 11 a a a 21 31 41 a a 12 22 32 42 a a a a 13 23 33 43 14 24 34 44 P 1 P 2 P 3 P 4 CDA 4150 Eurípides Montagne University of Central Florida 42
Parallel access by Column reordering is necessary Serial access by Rows a 11 a a a 12 13 14 a a 21 22 23 24 a a a a 31 32 33 34 41 42 43 44 P 1 P 2 P 3 P 4 CDA 4150 Eurípides Montagne University of Central Florida 43
Parallel access by Diagonals a 11 a a a a P 1 P 2 24 33 42 CDA 4150 12 21 34 43 a a a a 13 22 31 44 14 23 32 41 P 3 P 1 P 4 Eurípides Montagne University of Central Florida 44
Parallel Column/Row Access aa 1111 a aa a 21 a a 43 a 13 a aa 31 a P 1 P 2 P 3 24 33 33 42 12 21 34 423 13 22 31 44 a a 23 a aa 41 14 23 32 41 P 4 Skewed matrix representation CDA 4150 Eurípides Montagne University of Central Florida 45
Parallel Column/Row/Diagonal Access Skewed matrix representation (5 banks) a a a 11 12 21 34 a 43 a a a 13 22 31 44 a a 14 23 32 41 a a a 24 33 42 Interconnection Network P 1 CDA 4150 P 2 P 3 P 4 Eurípides Montagne University of Central Florida 46
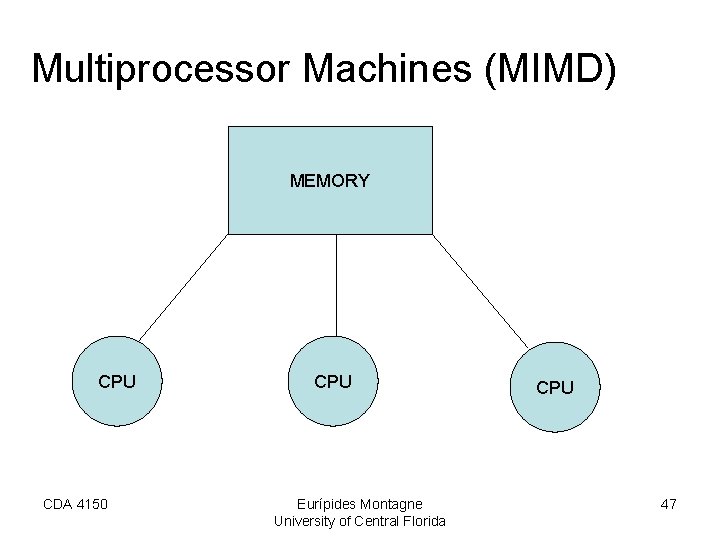
Multiprocessor Machines (MIMD) MEMORY CPU CDA 4150 CPU Eurípides Montagne University of Central Florida CPU 47
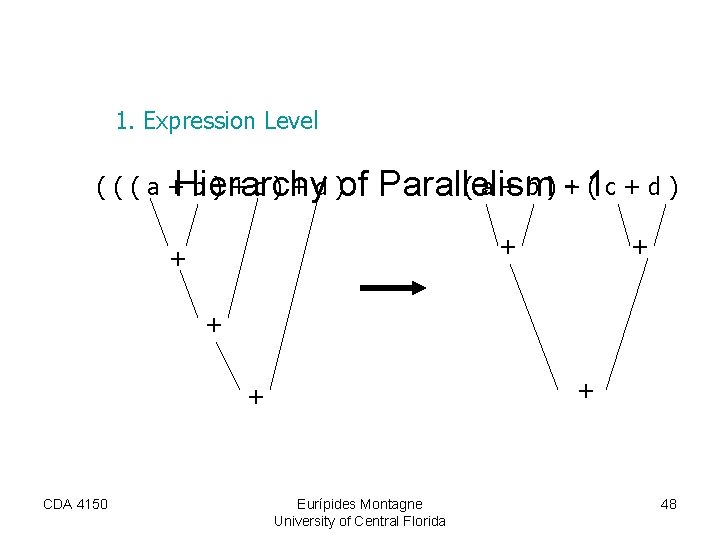
1. Expression Level ( ( ( a + b ) + c ) + d ) ( a + b ) + ( c + d ) Hierarchy of Parallelism - 1 + + + CDA 4150 Eurípides Montagne University of Central Florida 48
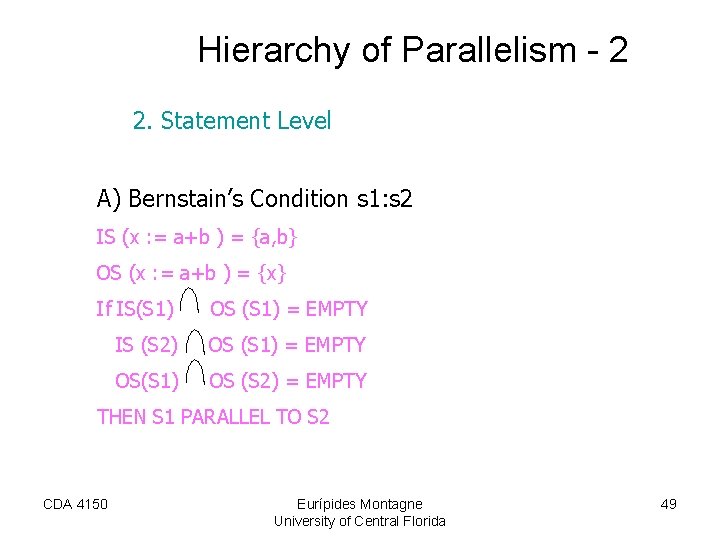
Hierarchy of Parallelism - 2 2. Statement Level A) Bernstain’s Condition s 1: s 2 IS (x : = a+b ) = {a, b} OS (x : = a+b ) = {x} If IS(S 1) OS (S 1) = EMPTY IS (S 2) OS (S 1) = EMPTY OS(S 1) OS (S 2) = EMPTY THEN S 1 PARALLEL TO S 2 CDA 4150 Eurípides Montagne University of Central Florida 49
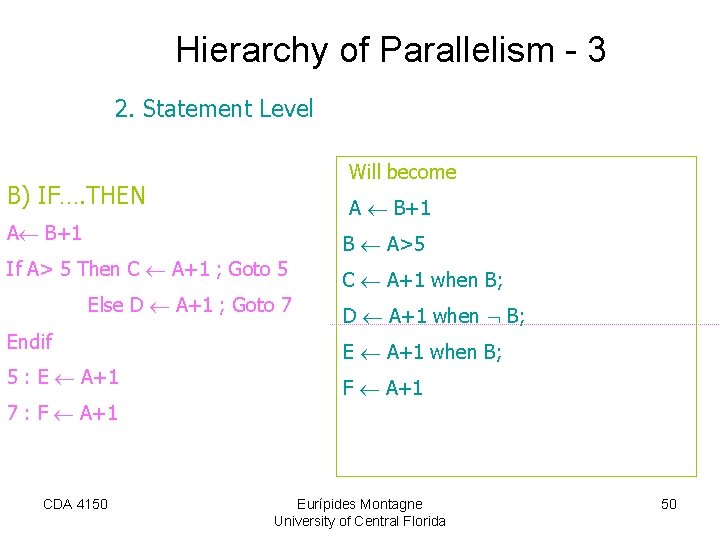
Hierarchy of Parallelism - 3 2. Statement Level Will become B) IF…. THEN A B+1 A B+1 B A>5 If A> 5 Then C A+1 ; Goto 5 Else D A+1 ; Goto 7 Endif 5 : E A+1 7 : F A+1 C A+1 when B; D A+1 when B; E A+1 when B; F A+1 CDA 4150 Eurípides Montagne University of Central Florida 50
Hierarchy of Parallelism - 3 2. Statement Level C) Vectorization B C For I= 1 to n A[I] = B[I] * C[I] Vectorize CDA 4150 A[1] = B[1] * C[1] A[2] = B[2] * C[2] A[N] = B[N] * C[N] Eurípides Montagne University of Central Florida 51