machine learning decision tree Matthew Dreher Definition of
- Slides: 14
machine learning decision tree Matthew Dreher
Definition of a decision tree Tree: is collection of node such that no cycles exist Subtree: is a subpart of a tree Forest: is a collection of trees Parent node: is the node that points to its child Child node: is a node being pointing to by it’s parent node Root node: topmost node in the tree hierarchy Leaf node: is node with no child node
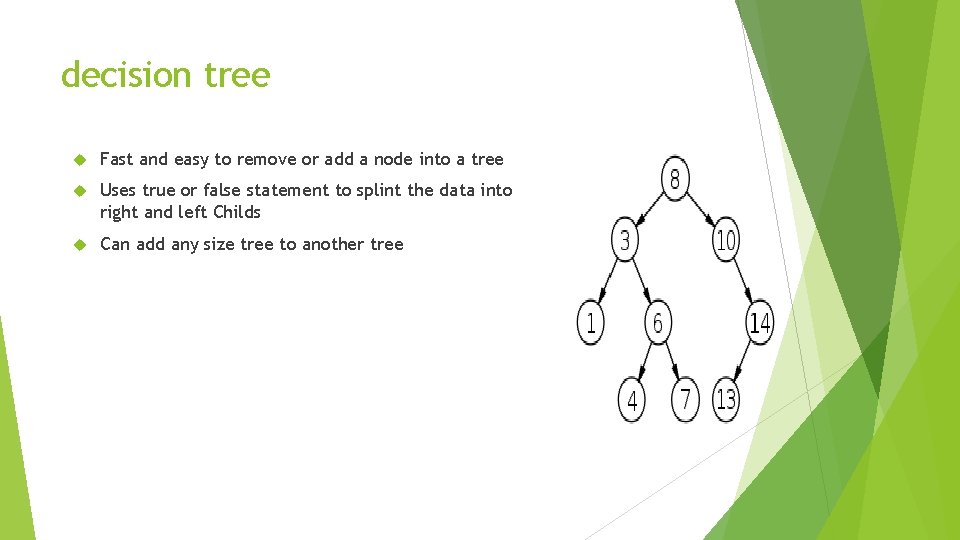
decision tree Fast and easy to remove or add a node into a tree Uses true or false statement to splint the data into right and left Childs Can add any size tree to another tree
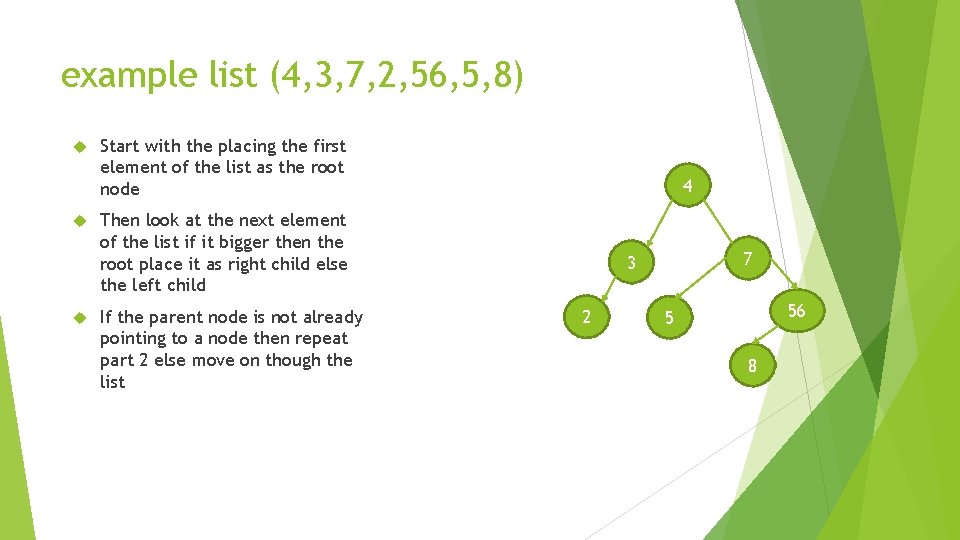
example list (4, 3, 7, 2, 56, 5, 8) Start with the placing the first element of the list as the root node 4 Then look at the next element of the list if it bigger then the root place it as right child else the left child If the parent node is not already pointing to a node then repeat part 2 else move on though the list 7 3 2 56 5 8
Part of a machine learning model Target variable: is the variable that the model is trying to predict decision variable; are the variable the model using to make its predict Training set: The actual dataset that we use to train the model Validation set: The sample of data used to provide an unbiased evaluation of a model fit on the training dataset while tuning model Test set: The sample of data used to provide an unbiased evaluation of a final model fit on the training dataset
gradient boosting Is a Supervised machine Learning technique For regression and classification problems Goal is to combine weak learners(normally a decision tree with Hight 1) into a single strong learner something that can accurately predict an outcome given information
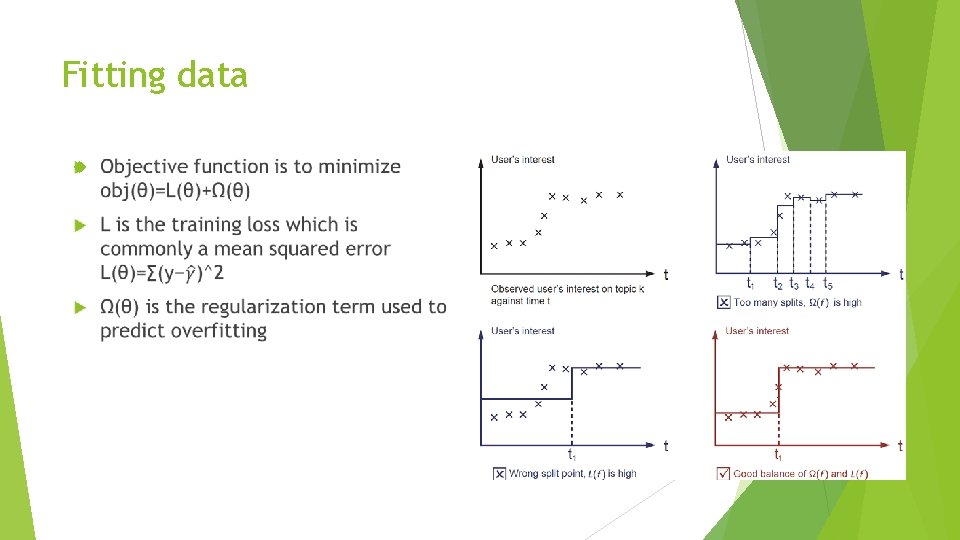
Fitting data
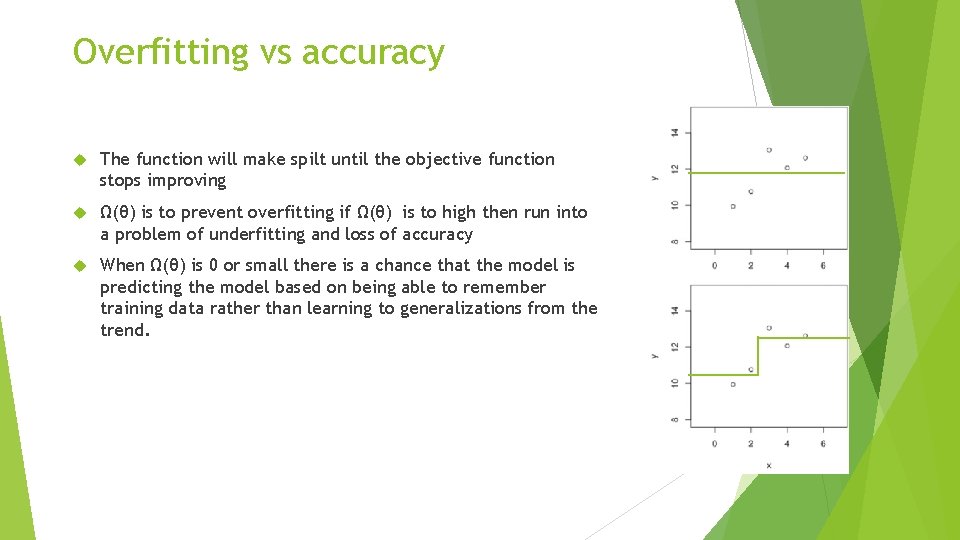
Overfitting vs accuracy The function will make spilt until the objective function stops improving Ω(θ) is to prevent overfitting if Ω(θ) is to high then run into a problem of underfitting and loss of accuracy When Ω(θ) is 0 or small there is a chance that the model is predicting the model based on being able to remember training data rather than learning to generalizations from the trend.
Real world example of use decision tree base machine learning (ML) Use of Covid mobility and case data and past revenue number to detriment the weekly revenue From start of with exploratory data analysis to deployment of model
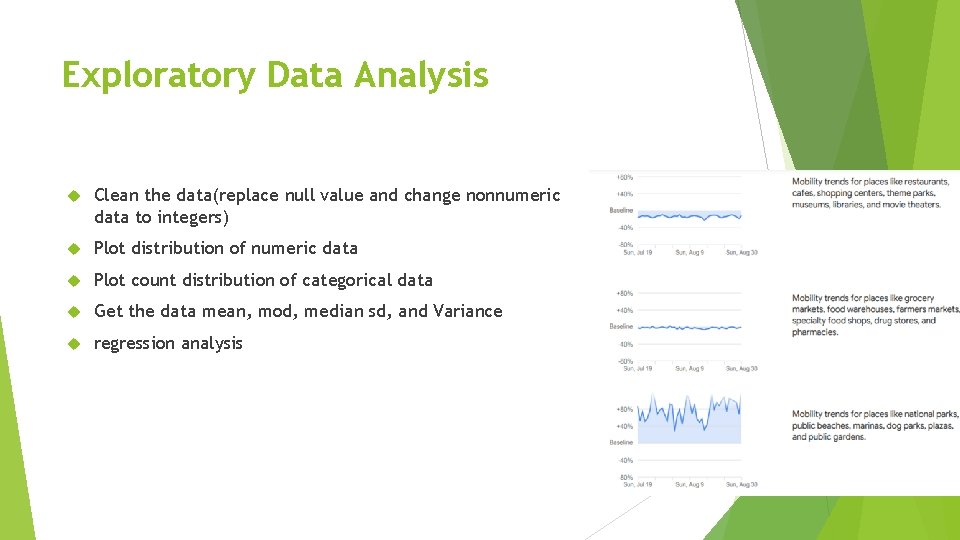
Exploratory Data Analysis Clean the data(replace null value and change nonnumeric data to integers) Plot distribution of numeric data Plot count distribution of categorical data Get the data mean, mod, median sd, and Variance regression analysis
Determine the target verbal and decision variable Target variable maybe be the following weeks info making it that you need to lag the current info with May have to go back to your data sets to find more decision variables
Split the data points into training and leaning data After setting up the data from use you would split the data into Depending of on your project split would be differently Thing to look for are number of data point and the number of parameters
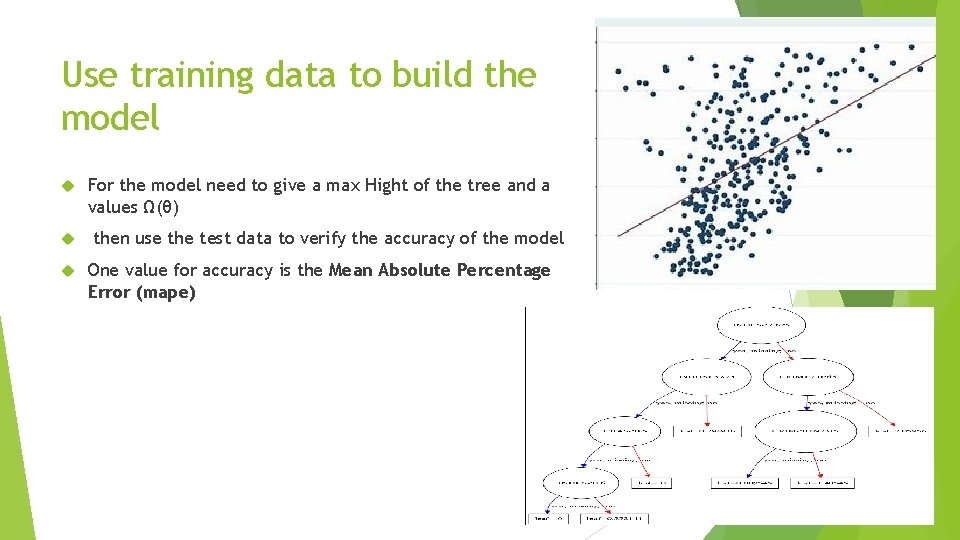
Use training data to build the model For the model need to give a max Hight of the tree and a values Ω(θ) then use the test data to verify the accuracy of the model One value for accuracy is the Mean Absolute Percentage Error (mape)
references https: //xgboost. readthedocs. io/en/latest/tutorials/model. html Data structures of and algorithms in python by Michael t. gooodrich, Roberto tamassia, Michael h Goldwasser