Overview of IU Digital Collections Search Hui Zhang
- Slides: 20
Overview of IU Digital Collections Search Hui Zhang Jon Dunn Indiana University Digital Library Program IU Digital Library Brown Bag October 19, 2011
Outline Introduction Demo and motivation – Jon Technical implementation – Hui Next steps and future work – Jon
Why cross-collection search? Support discovery across multiple content formats, collections, and repositories at IU Use cases: ◦ Multiple formats/collections within a single thematic grouping (e. g. Hoagy Carmichael) ◦ Show off the richness and diversity of IU’s digital collections (PR – see open. iu. edu) ◦ Find digital content at IU for teaching or research use
Why cross-collection search? Support discovery across multiple content formats, collections, and repositories at IU Use cases: ◦ Multiple formats/collections within a single thematic grouping (e. g. Hoagy Carmichael) ◦ Show off the richness and diversity of IU’s digital collections (PR – see open. iu. edu) ◦ Find digital content at IU for teaching or research use
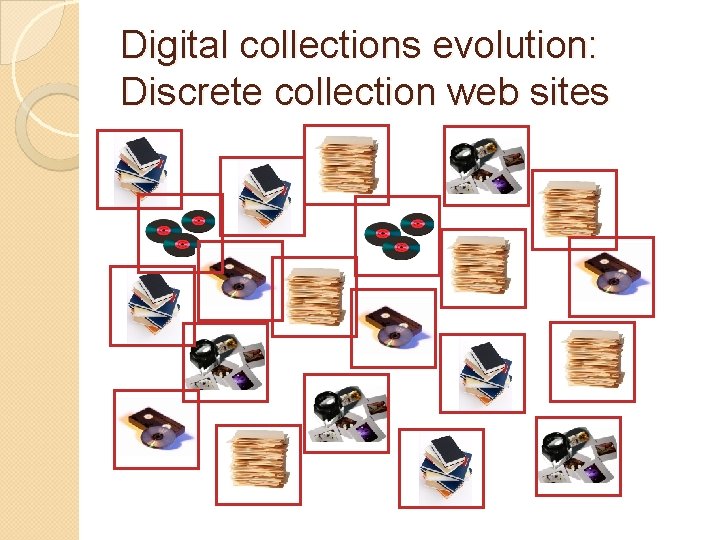
Digital collections evolution: Discrete collection web sites
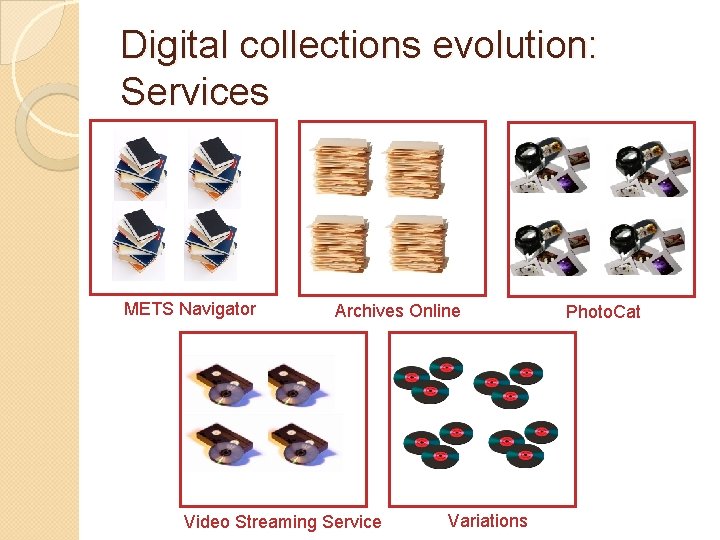
Digital collections evolution: Services METS Navigator Archives Online Video Streaming Service Variations Photo. Cat
Digital collections evolution: Services Advantages ◦ Can develop workflows for content ingestion and description that are both optimized and scalable ◦ Content stored in a common repository (Fedora) ◦ Can develop discovery interfaces optimized for particular content (e. g. images vs. music) ◦ Common services to expose content into other platforms (e. g. Google) Disadvantages ◦ “Siloing” discovery by content type can be an issue
Cross-collection search: First iteration Only selected collections with metadata in Fedora ◦ Includes Archives Online and most image collections ◦ Not video streaming, Variations, encoded text, IUScholar. Works, various “legacy” collections Metadata only (MODS) ◦ Stored natively as MODS in Fedora ◦ Disseminated on the fly from other formats (Photo. Cat 2) ◦ Transformed via XSLT from EAD (Archives Online)
Cross-collection search: First iteration Demonstration
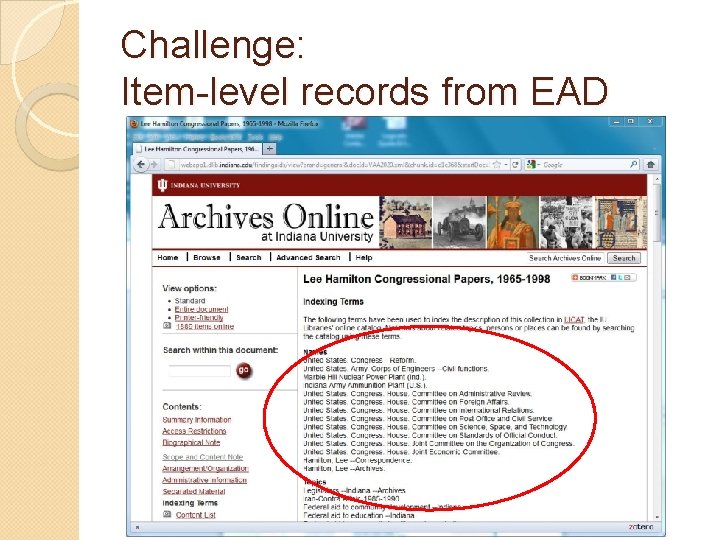
Challenge: Item-level records from EAD
Apache Solr Overview A Java-based web application, open source search server, Apache Lucene at its core • Demonstration • Solr vs. relational database • • Pros: full-text search, text analysis, flexible fields • Cons: no relational operation on fields • Solr vs. Lucene • Pros: web application, centralized configuration, facet • Cons: security, slower
Solr Schema and Configuration Schema: specify how the index is built ◦ field, field type ◦ dynamic. Field, copy. Field, unique. Key ◦ Text analysis: stop, stem, synonym, tokenization Configuration: specify Solr itself, query, data import
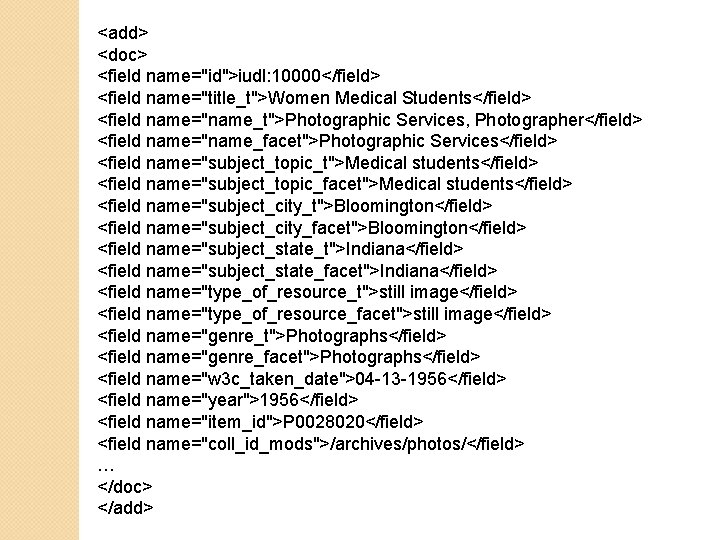
Converting MODS to Solr XML ◦ <add><doc><field>…</filed>…</doc></add> ◦ Can simply be “POST” into the Solr index Translation of MODS to Solr XML ◦ Use XSLT ◦ Called by the indexing program Extract facet values ◦ Format: MODS: typeof. Resource ◦ Collection: customized based on item’s Fedora PID
<add> <doc> <field name="id">iudl: 10000</field> <field name="title_t">Women Medical Students</field> <field name="name_t">Photographic Services, Photographer</field> <field name="name_facet">Photographic Services</field> <field name="subject_topic_t">Medical students</field> <field name="subject_topic_facet">Medical students</field> <field name="subject_city_t">Bloomington</field> <field name="subject_city_facet">Bloomington</field> <field name="subject_state_t">Indiana</field> <field name="subject_state_facet">Indiana</field> <field name="type_of_resource_t">still image</field> <field name="type_of_resource_facet">still image</field> <field name="genre_t">Photographs</field> <field name="genre_facet">Photographs</field> <field name="w 3 c_taken_date">04 -13 -1956</field> <field name="year">1956</field> <field name="item_id">P 0028020</field> <field name="coll_id_mods">/archives/photos/</field> … </doc> </add>
Solr Indexing Carried by two Java programs running under DLP’s Fedora Index Service framework The service can be invoked by a RESTful HTTP request, the Solr indexing is triggered based on conditions specified in the properties file The MODS records are extracted from the Fedora repository (natively stored) or generated by the get. MODS disseminator (Photocat 2 collections)
Overview of Blacklight An open source project developed for libraries with many potentials: ◦ As a library catalog ◦ As the discovery interface to a digital repository Optimized to handle diversified content (facet browsing) Originally developed by University of Virginia, has a growing community of active contributors and users Now part of Hydra Project Written in Ruby, runs on Rails, requires Solr
Customize Blacklight for DLP Collections Integrate blacklight with MODS-based index ◦ Blacklight by default expects MARC fields New functions and features ◦ Render thumbnail in result view ◦ Use collection website as the landing page Style and layout ◦ Standard IU banner and footer ◦ Color, font, and window size
Future Improvements Automatic update of Solr index ◦ Fedora repository communicates with the Solr indexing program via JMS about item update Include full-text content ◦ It is challenging to have full-text content and metadata in one index ◦ Optimize the indexing and search algorithms ◦ Search against full-text and use metadata as facets
Future Improvement (cont’d) Add ◦ ◦ ◦ more collections Other collections from Fedora Non-Fedora DLP collections Archives of Institutional Memory IUScholar. Works Repository? IUPUI Digital Collections (Content. DM)? Conduct usability evaluation Explore integration w/ new Blacklight- based discovery layer for IUCAT Variations on Video IMLS grant ◦ Hydra/Blacklight-based discovery on PBcore
Questions? Beta: http: //webapp 1. dlib. indiana. edu/dcs/ Send comments to: diglib@indiana. edu