
Translation Forum Russia 2019 Compensation models for MT

- Slides: 15
Translation Forum Russia 2019 Международная переводческая конференция Compensation models for MT post-editing Gábor Bessenyei CEO and co-founder Globalese
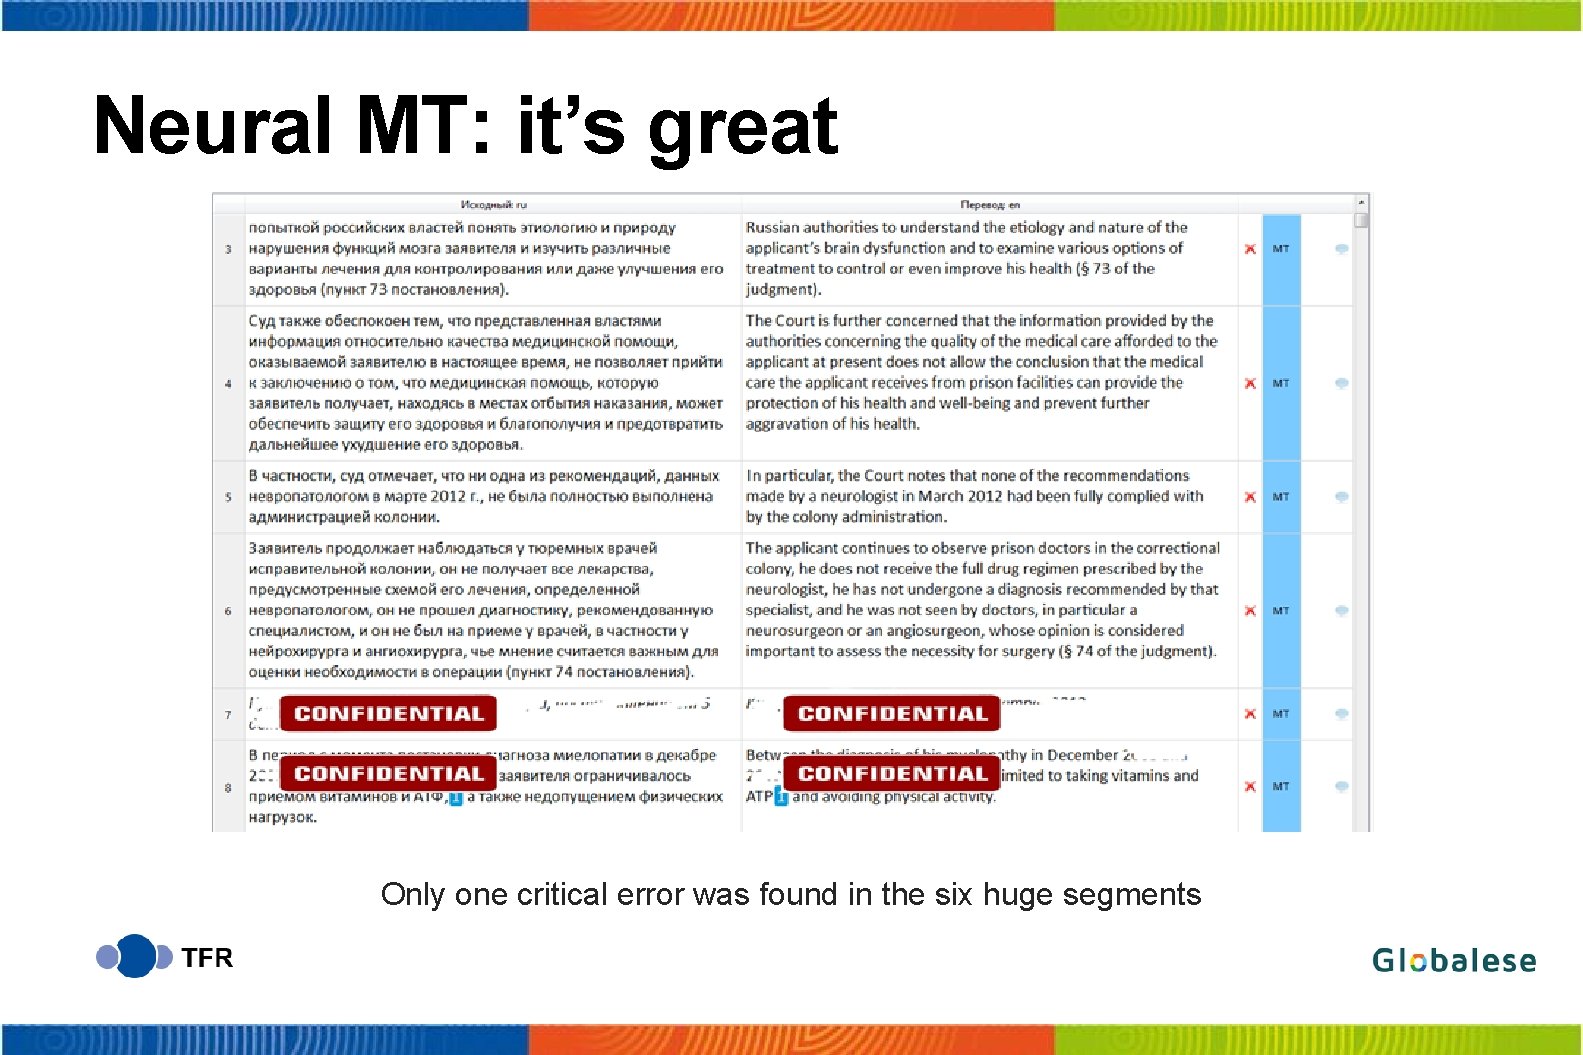
Neural MT: it’s great Only one critical error was found in the six huge segments
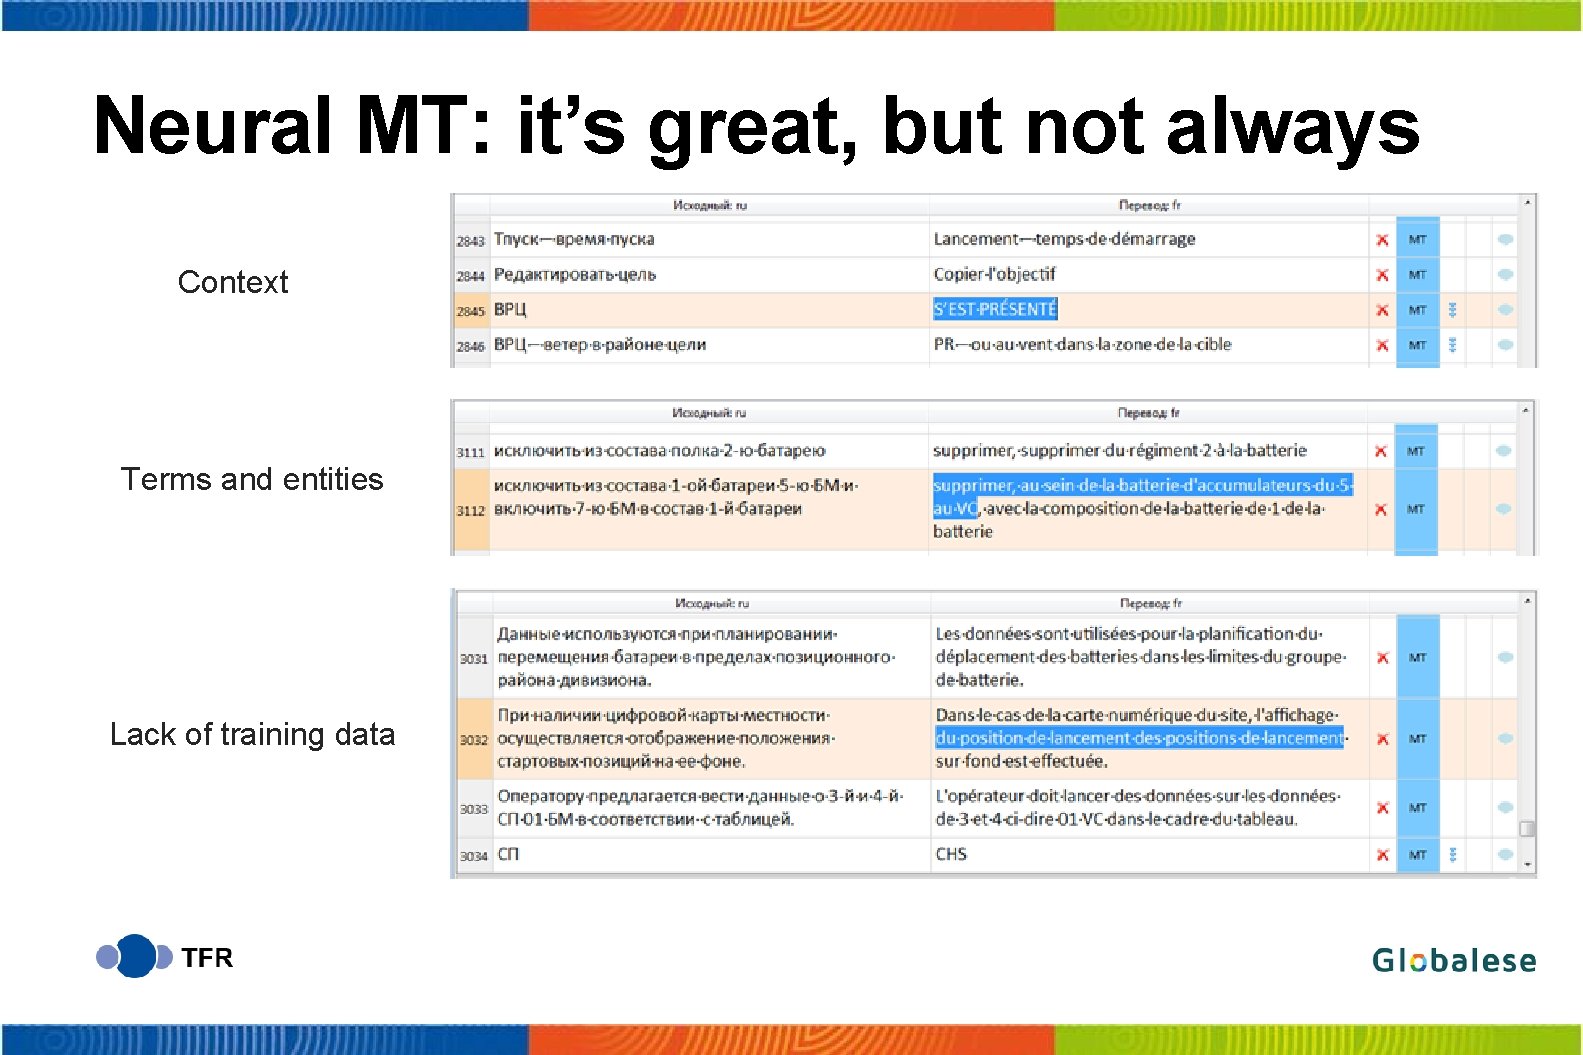
Neural MT: it’s great, but not always Context Terms and entities Lack of training data
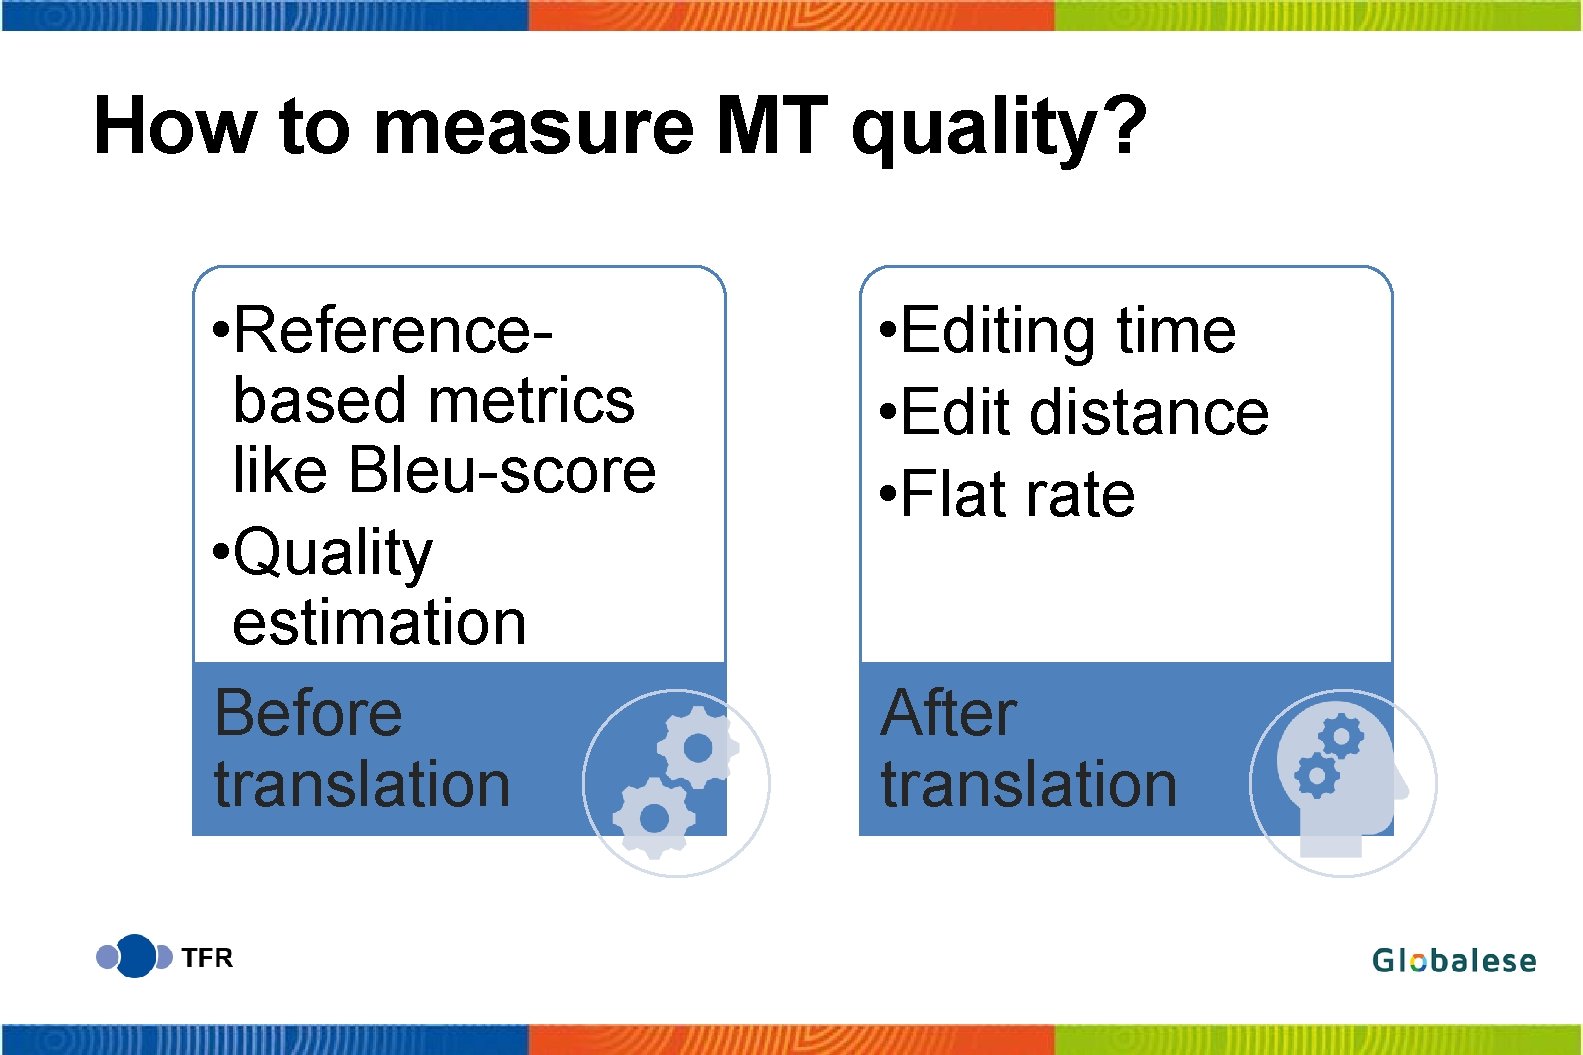
How to measure MT quality? • Referencebased metrics like Bleu-score • Quality estimation Before translation • Editing time • Edit distance • Flat rate After translation
Reference-based metrics TER RED NIST CDER WER Meteor Levenshtein Charac. TER AMBER F-Measure Bleu RIBES PER
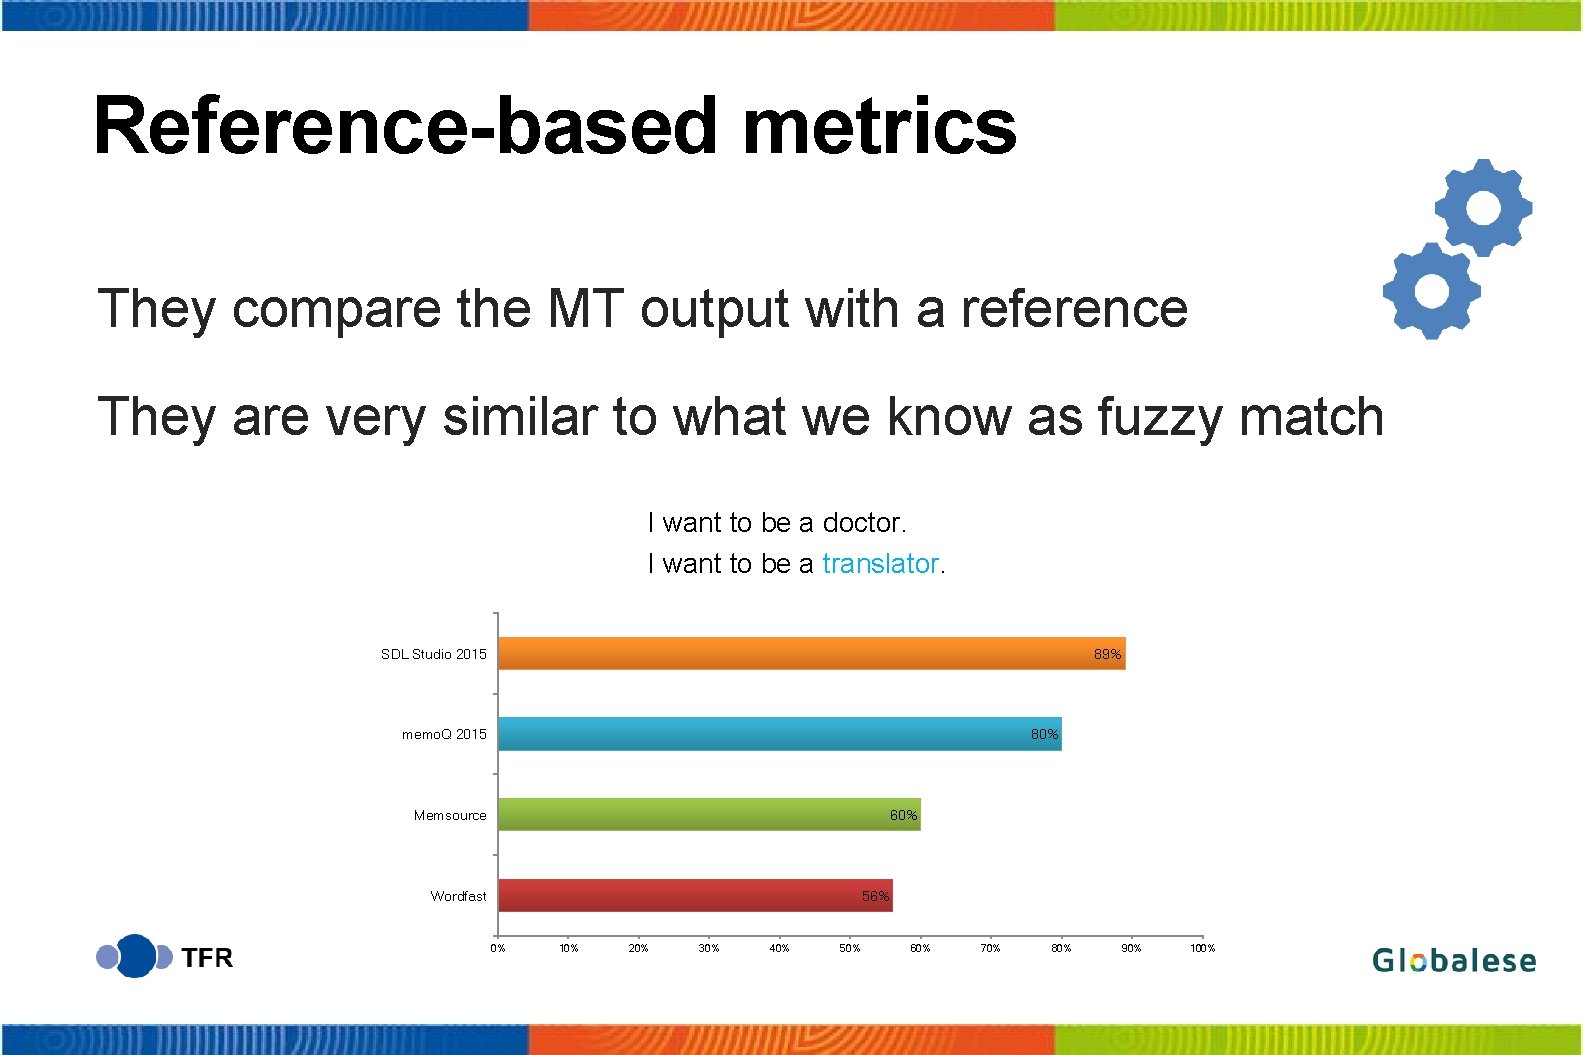
Reference-based metrics They compare the MT output with a reference They are very similar to what we know as fuzzy match I want to be doctor. free software. Source: The data collected can then be used in acreating I want to be a translator. Reference: Die gesammelten Daten können genutzt werden, um Freie Software zu erstellen. 89% SDL Studio 2015 Собранные данные могут быть использованы для создания свободного программного обеспечения. MT: Die gesammelten Daten können dann bei der Erstellung freier Software verwendet werden. memo. Q 2015 80% Затем собранные данные могут использоваться при создании свободного программного обеспечения. Meteor score: 0. 3843 Memsource 60% Wordfast 56% 0% 10% 20% 30% 40% 50% 60% 70% 80% 90% 100%
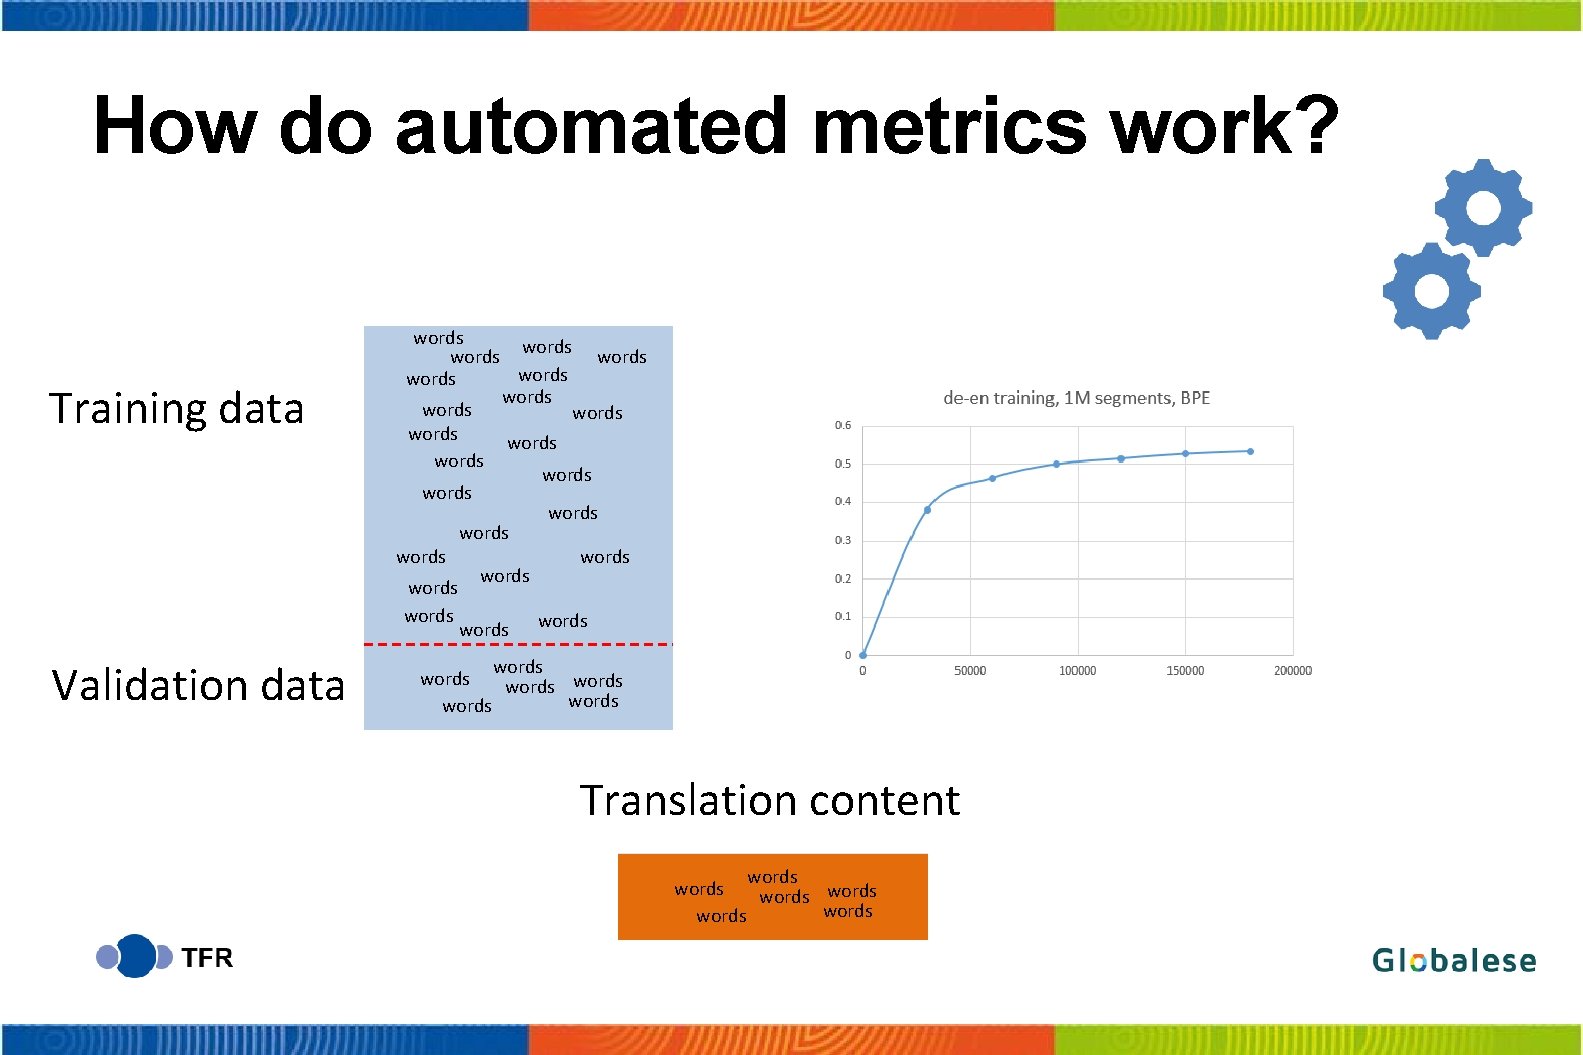
How do automated metrics work? Training data Validation data words words words words words words words words Translation content words words
Quality estimation MT quality prediction without a reference
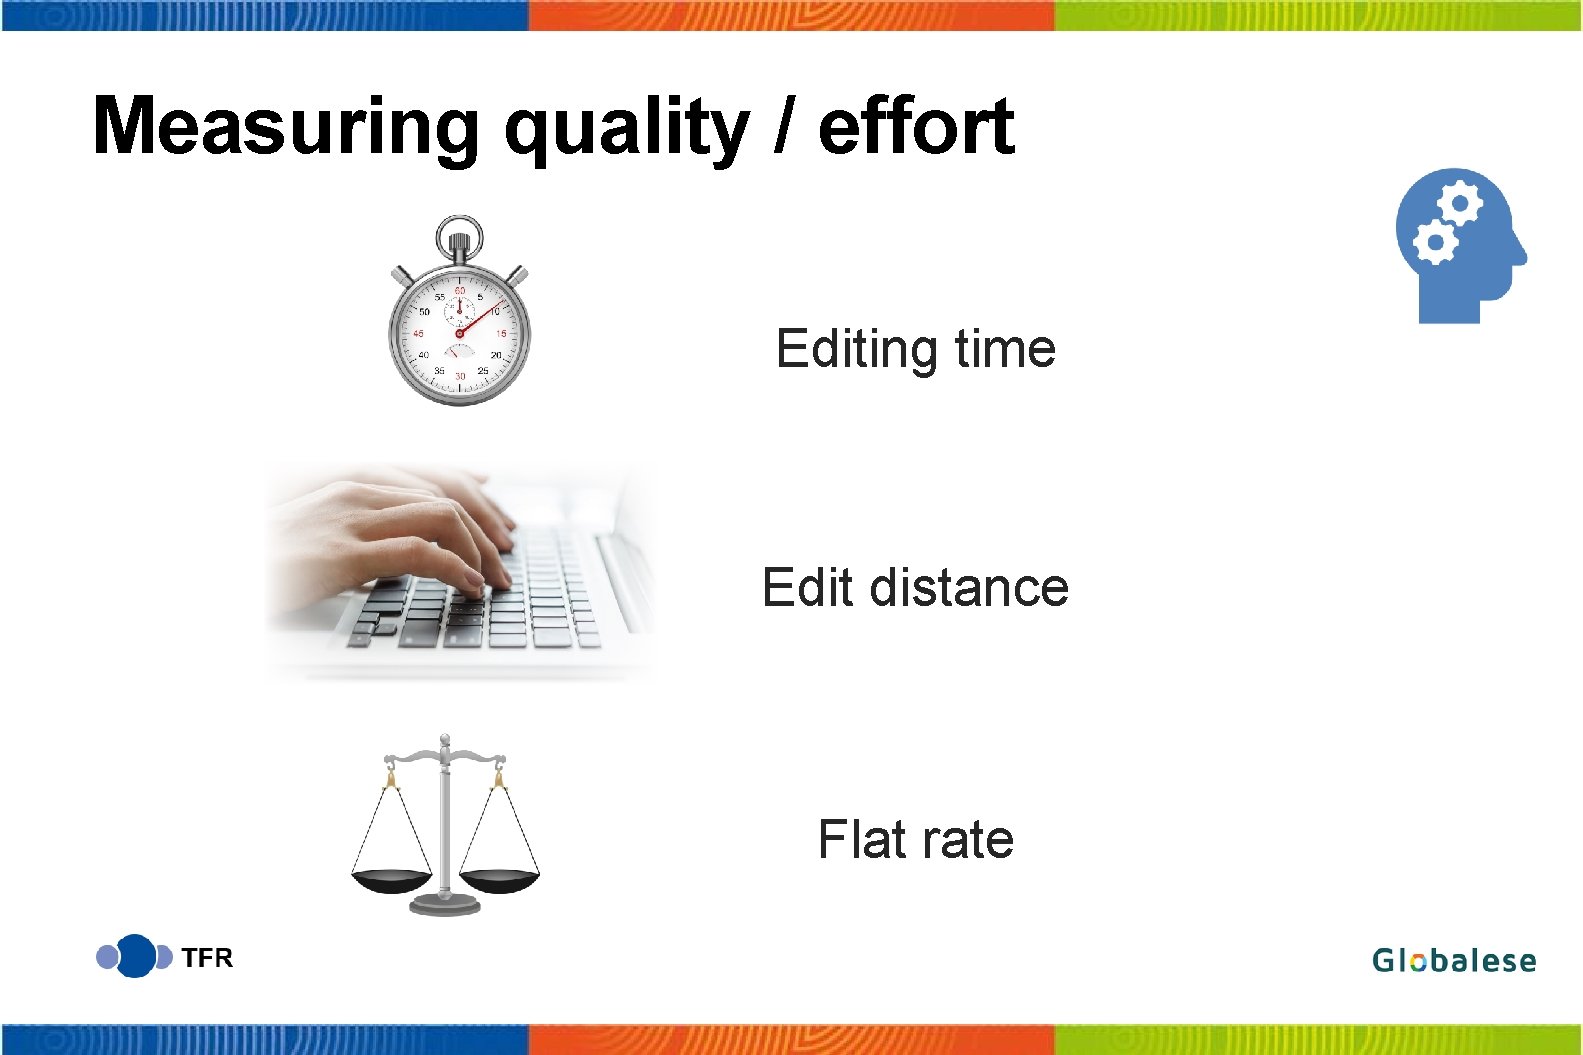
Measuring quality / effort Editing time Edit distance Flat rate
Editing time Pros Cons • High acceptance by translators • Rather fair • Supported by many CAT tools • Requires high level of trust • Cannot be calculated in advance • Subjective
Edit distance Pros Cons • Objective • Supported by many CAT-tools • High acceptance by translators • Danger of over-post-editing • Cannot be calculated in advance
Flat rate Pros Cons • Can be calculated in advance • Easy to understand • Easy to implement • Low acceptance by translators • Not necessarily fair
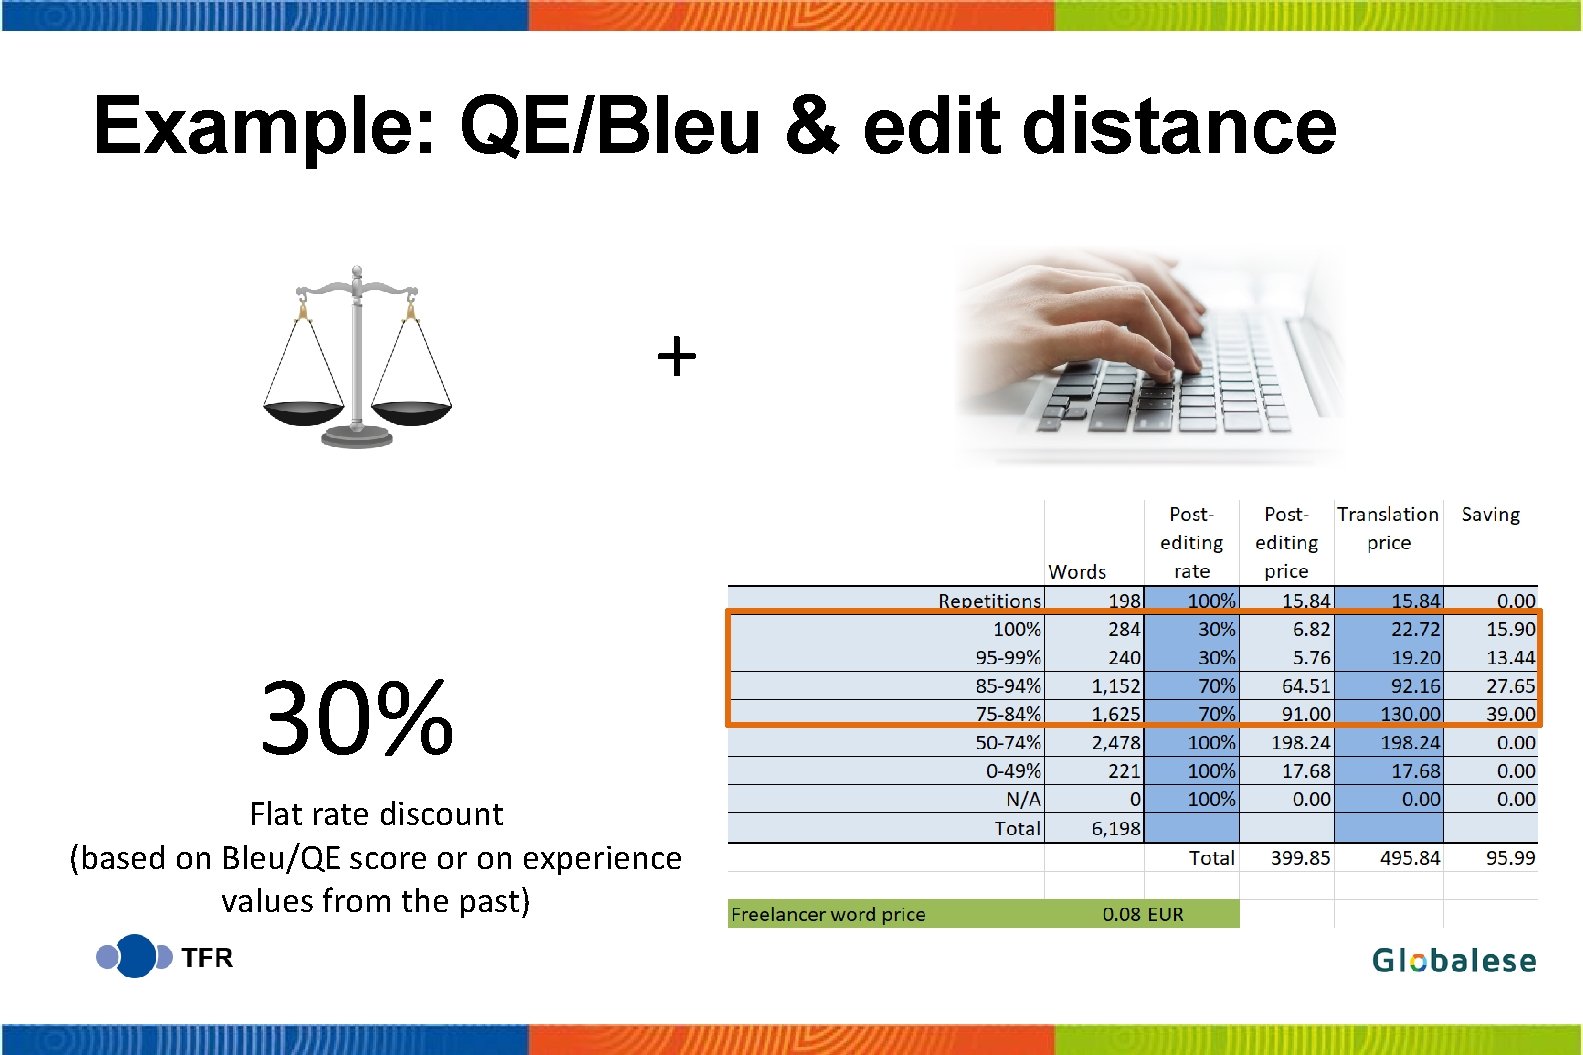
Example: QE/Bleu & edit distance + 30% Flat rate discount (based on Bleu/QE score or on experience values from the past)
Recommendations - Apply some basic KPIs (e. g. x words per our) - Try to create a model which is fine for everyone in the ecosystem - Do not accept flat rate blind or only based on samples - Involve internal translators or trusted freelancers/vendors in evaluation - Compensation / pricing model should be individual on project / engine level - Clarify the expected quality level (light/full PE)
Thank you for your attention! Any questions? Email me: gabor. bessenyei@globalese. ai www. globalese. ai