
Spoken Meadow Mari Corpus Data Design and Aims
- Slides: 13
Spoken Meadow Mari Corpus: Data, Design, and Aims Anna Volkova Mikhail Voronov
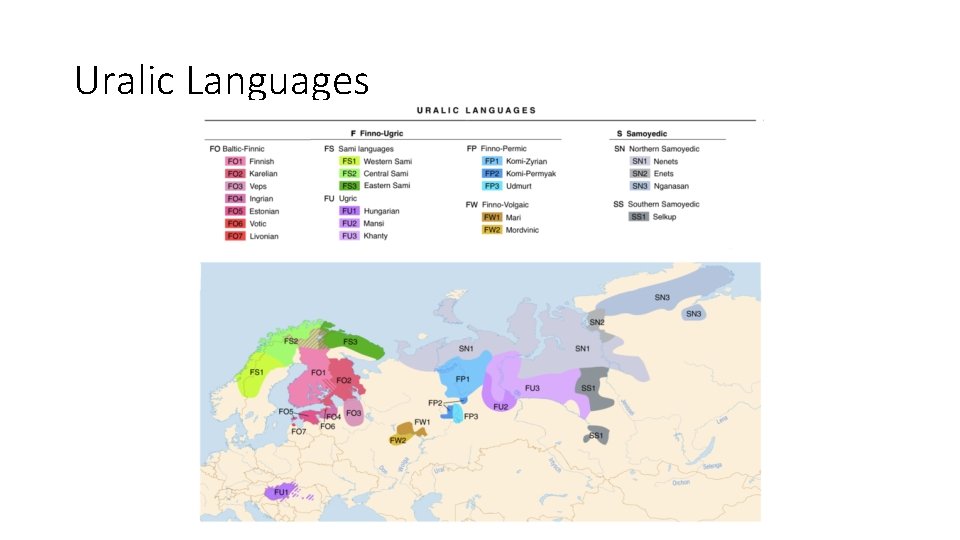
Uralic Languages
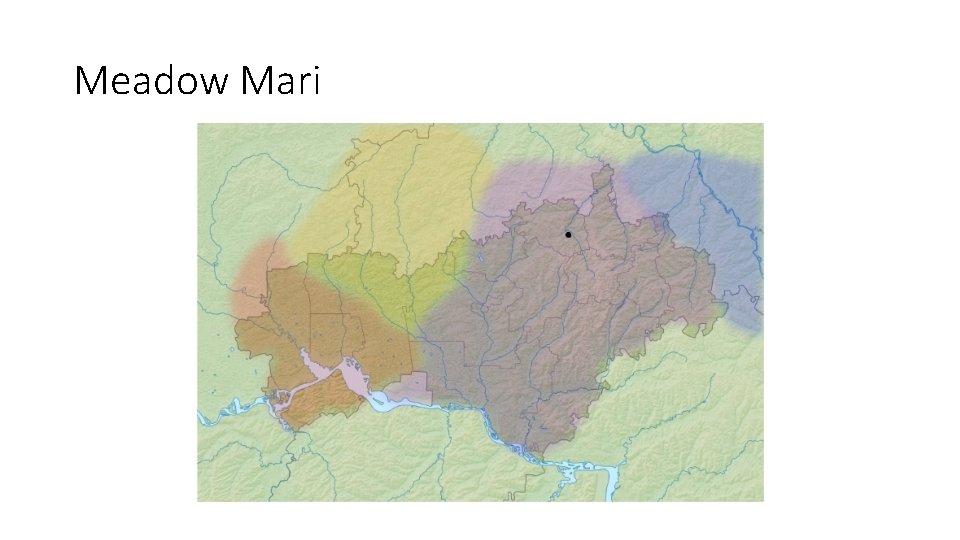
Meadow Mari
Meadow Mari • Uralic family, Finno-Ugric branch • ISO code [mhr] • Spoken by approximately 388, 000 (Ethnologue 2013); • 525, 500 speakers in 1993 (United Bible Societies); • 451, 000 speakers in the 2002 census • Ethnic Mari population (including Hill Mari) 548, 000 (2010 census); • 604, 300 in the 2002 census • Dictionaries • Grammars • Corpus of written texts: work in progress (Tromsø, The Arctic University of Norway) • Morphological analyzer (Jeremy Bradley)
Aims • An algorithm for creating spoken minority languages corpora • A spoken Meadow Mari corpus which may be used as: • A research tool for linguists: • Typological observations • Contact phenomena • Dialectal variation • A study resource for people learning Meadow Mari: • Dialectal variation • Intonation • Language material for creating exercises
Applications for Linguists • Checking grammatical hypotheses (e. g. discontinuous past) • Assessing grammatical phenomena distribution in discourse • Research on: • • Language interference Borrowing Intonation Etc.
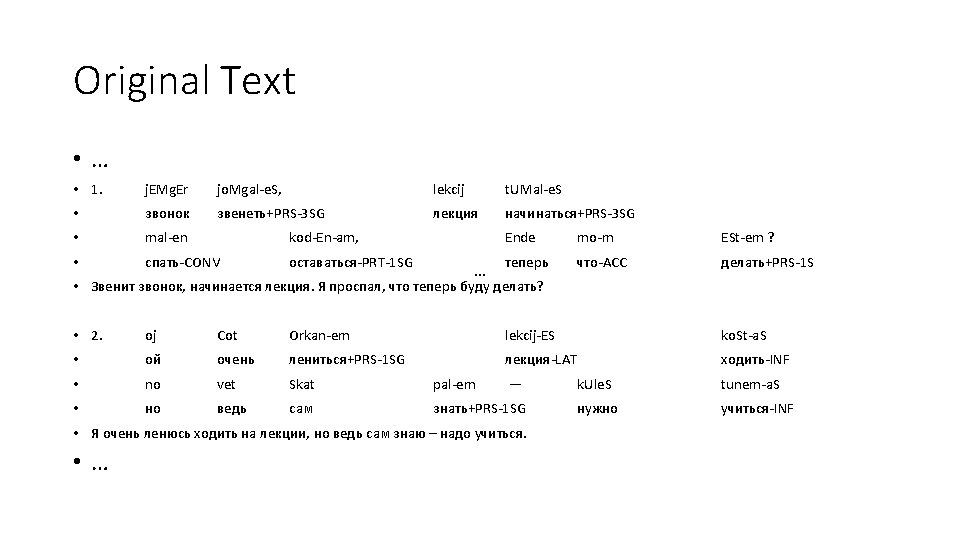
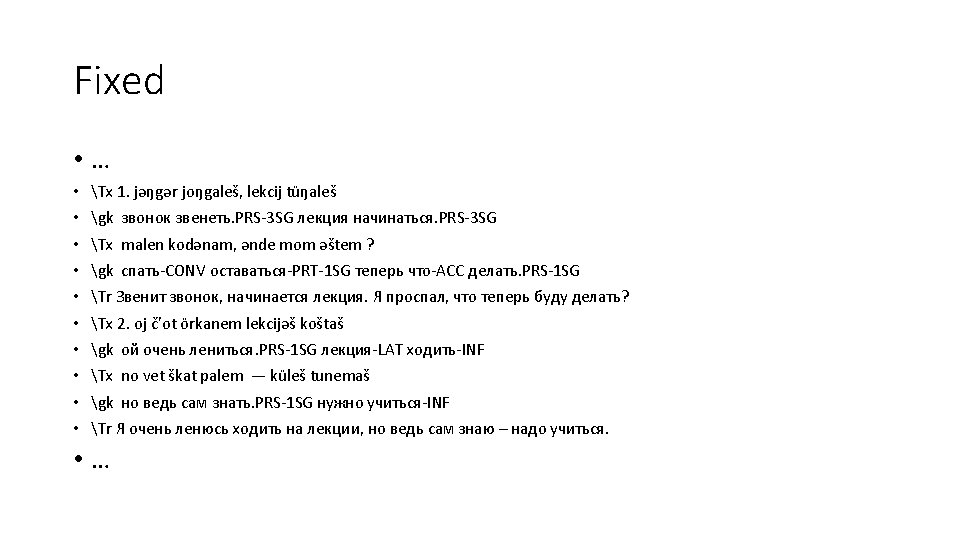
Our Data • Gathered by two MSU expeditions: 2000 and 2001 to the Staryj Torjal village • 79 audio files • 322 Mb (WAV) • 365 text files • Around 59 unique • Format: MS-Word and RTF files with Meadow Mari sentences, glosses (not always) and translation • Original sentences are written without the use of Unicode • Misha wrote a Python script that fixes the original sentences and adds tags to the lines facilitating importing into Fieldworks
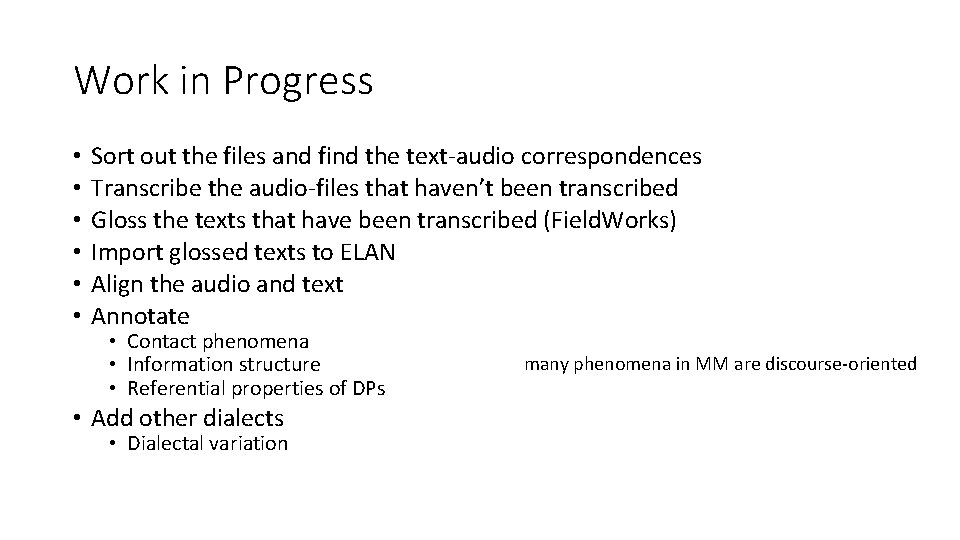
Work in Progress • • • Sort out the files and find the text-audio correspondences Transcribe the audio-files that haven’t been transcribed Gloss the texts that have been transcribed (Field. Works) Import glossed texts to ELAN Align the audio and text Annotate • Contact phenomena • Information structure • Referential properties of DPs • Add other dialects • Dialectal variation many phenomena in MM are discourse-oriented
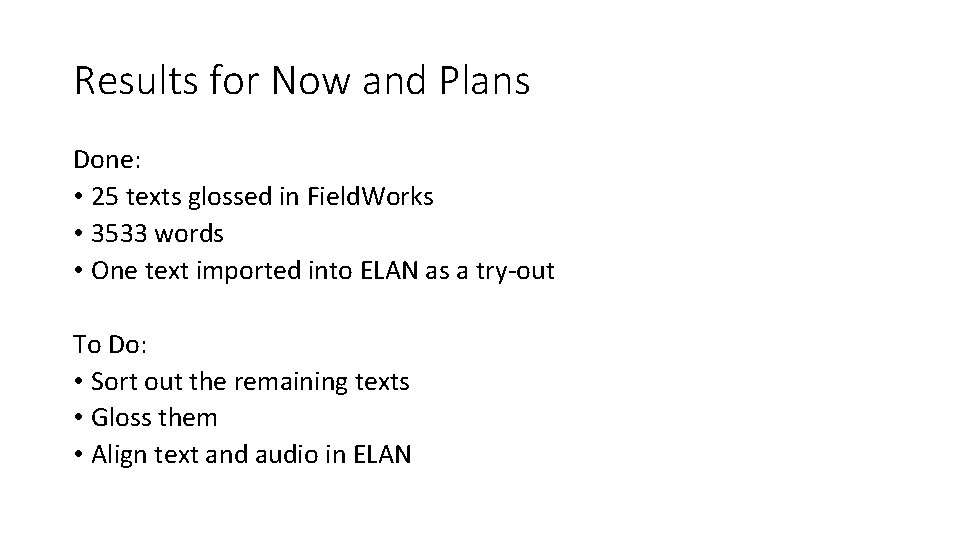
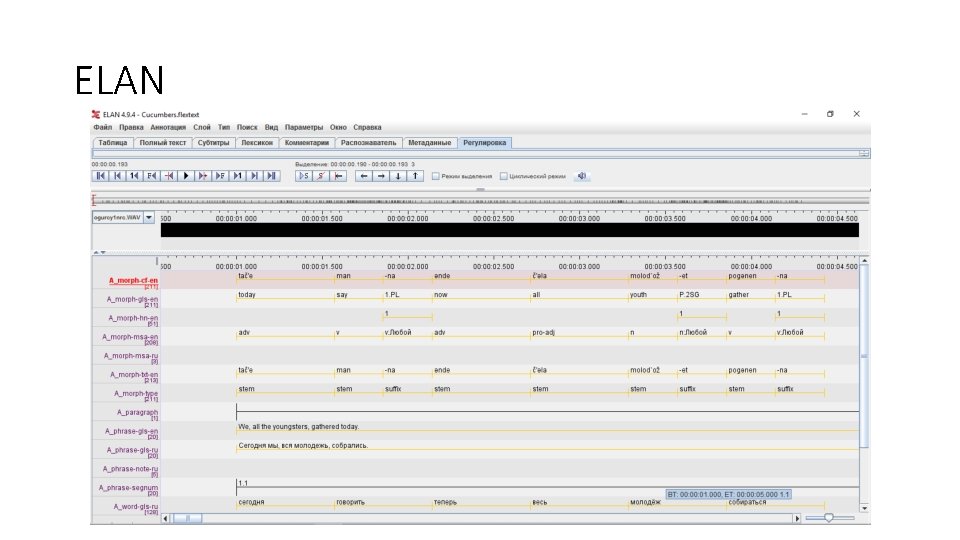
Results for Now and Plans Done: • 25 texts glossed in Field. Works • 3533 words • One text imported into ELAN as a try-out To Do: • Sort out the remaining texts • Gloss them • Align text and audio in ELAN
ELAN
Questions and Doubts • From to ELAN to an online corpus with a full search functionality – ? • Field. Works usage?