
Sorting We have actually seen already two efficient
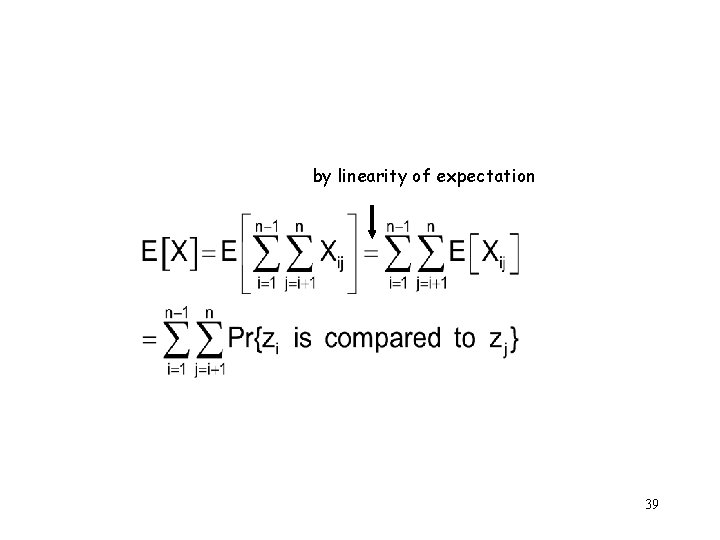
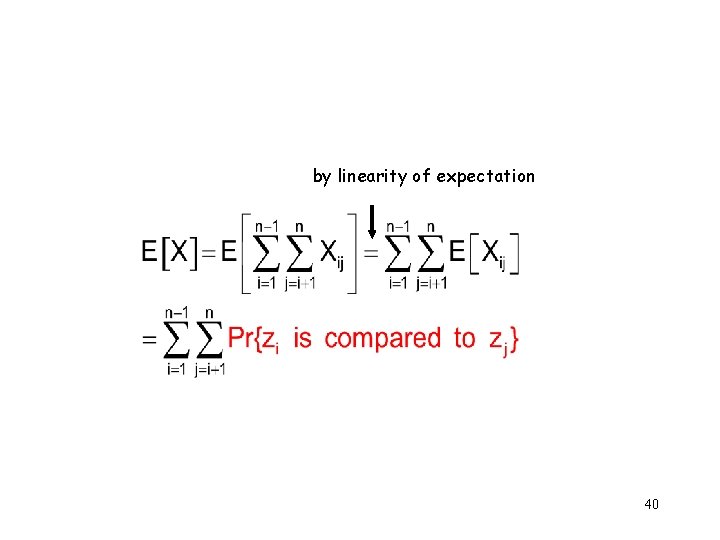
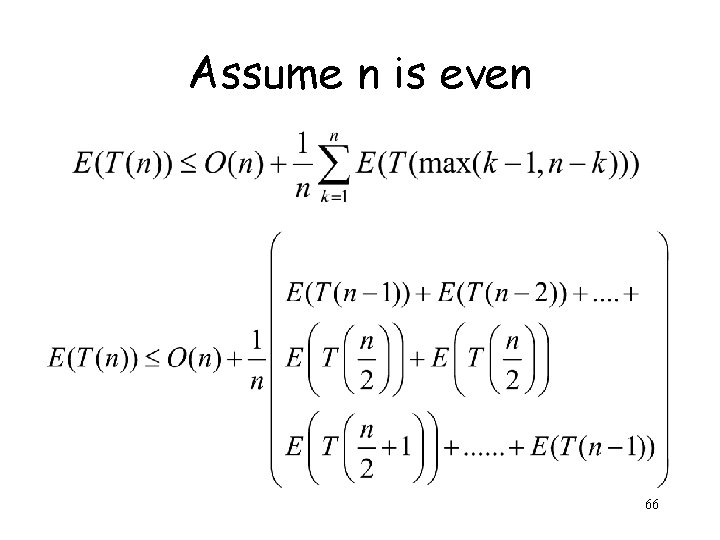
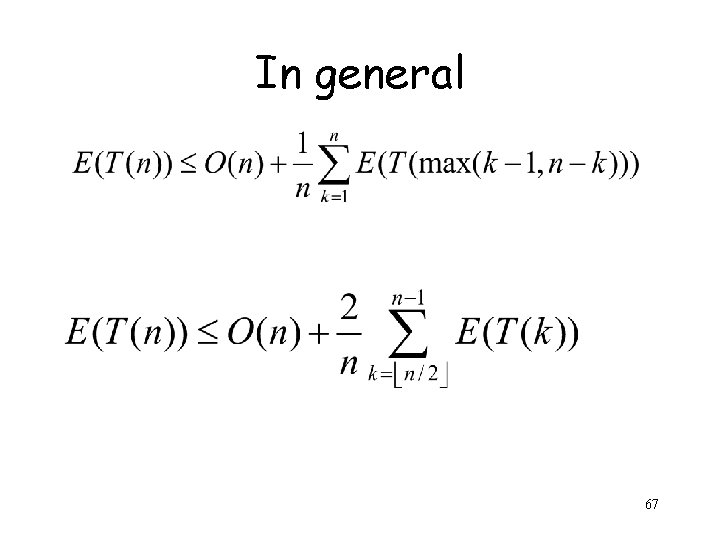
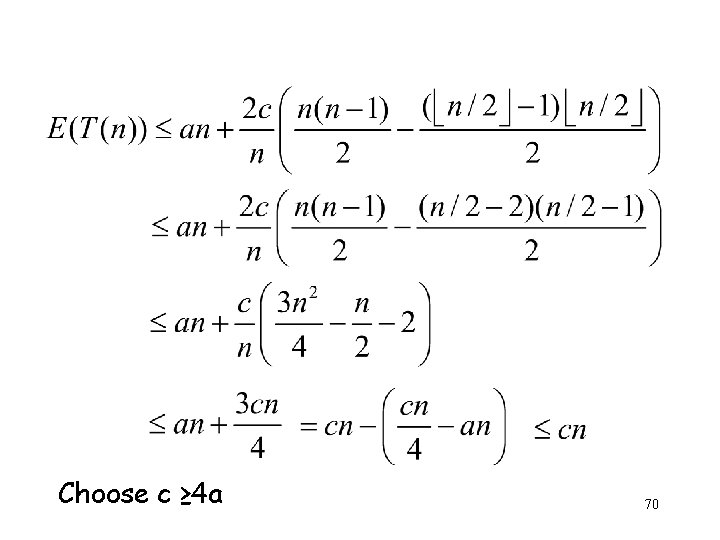
- Slides: 98
Sorting • We have actually seen already two efficient ways to sort: 1
A kind of “insertion” sort • Insert the elements into a red-black tree one by one • Traverse the tree in in-order and collect the keys • Takes O(nlog(n)) time 2
Heapsort (Willians, Floyd, 1964) • Put the elements in an array • Make the array into a heap • Do a deletemin and put the deleted element at the last position of the array 3
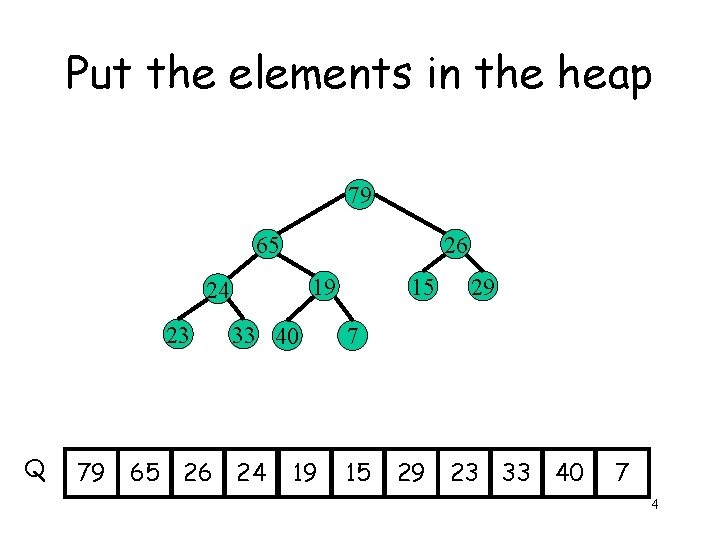
Put the elements in the heap 79 65 26 19 24 23 Q 79 65 33 40 26 24 19 15 29 7 15 29 23 33 40 7 4
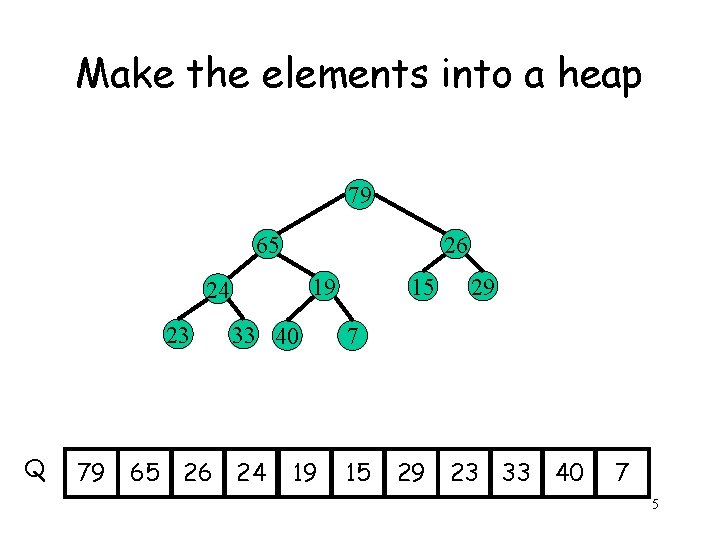
Make the elements into a heap 79 65 26 19 24 23 Q 79 65 33 40 26 24 19 15 29 7 15 29 23 33 40 7 5
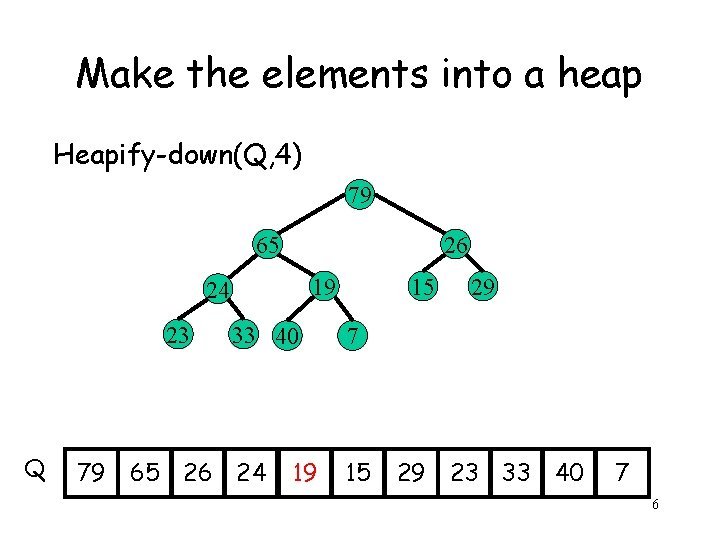
Make the elements into a heap Heapify-down(Q, 4) 79 65 26 19 24 23 Q 79 65 33 40 26 24 19 15 29 7 15 29 23 33 40 7 6
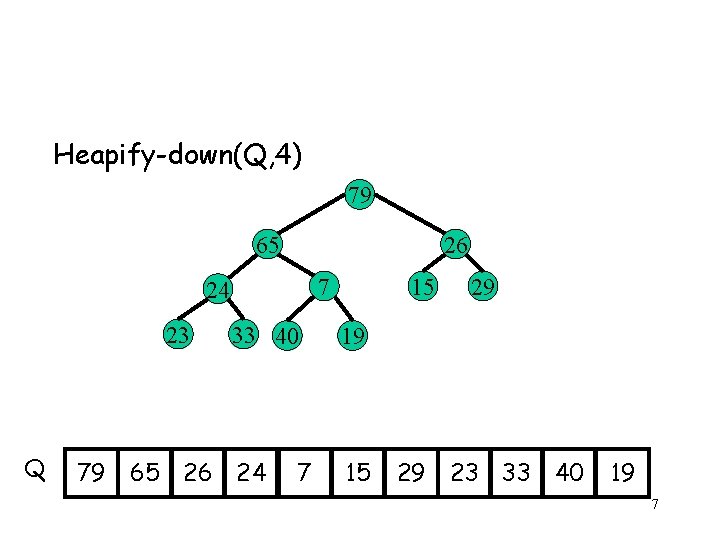
Heapify-down(Q, 4) 79 65 26 7 24 23 Q 79 65 33 40 26 24 7 15 29 19 15 29 23 33 40 19 7
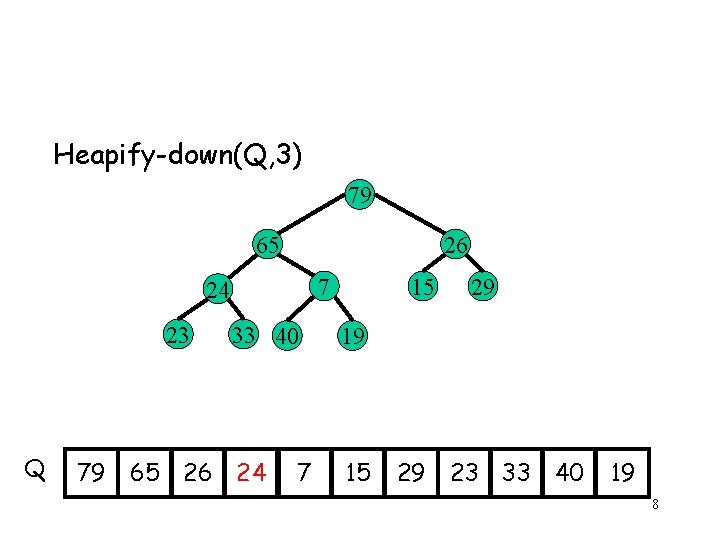
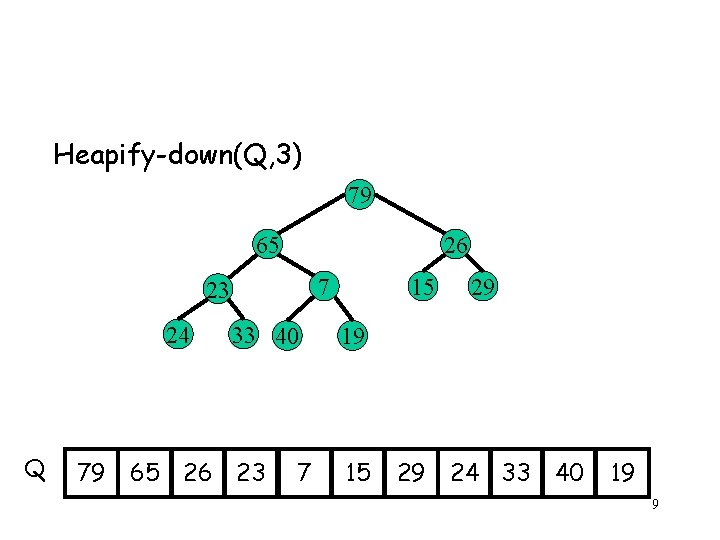
Heapify-down(Q, 3) 79 65 26 7 24 23 Q 79 65 33 40 26 24 7 15 29 19 15 29 23 33 40 19 8
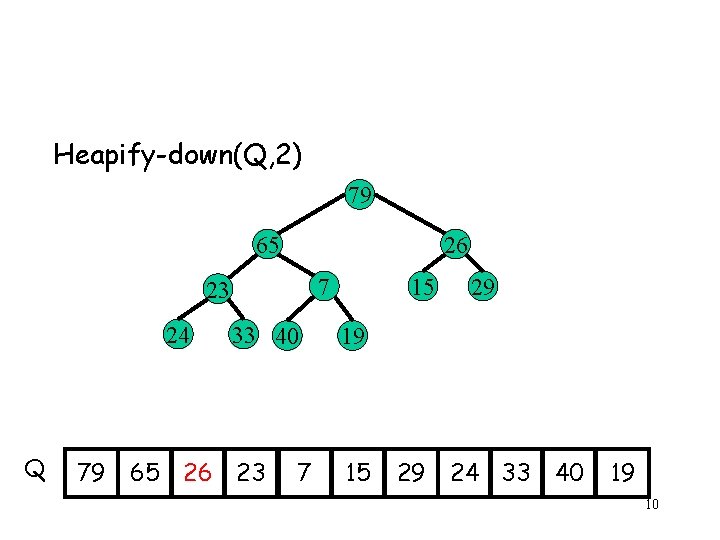
Heapify-down(Q, 3) 79 65 26 7 23 24 Q 79 65 33 40 26 23 7 15 29 19 15 29 24 33 40 19 9
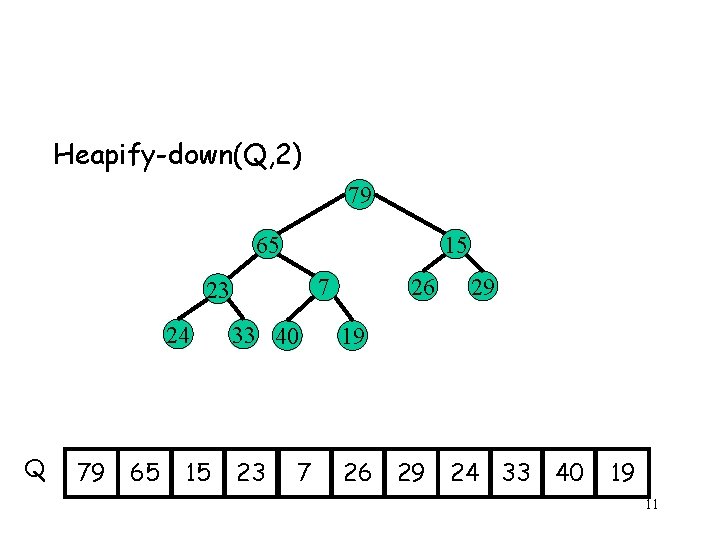
Heapify-down(Q, 2) 79 65 26 7 23 24 Q 79 65 33 40 26 23 7 15 29 19 15 29 24 33 40 19 10
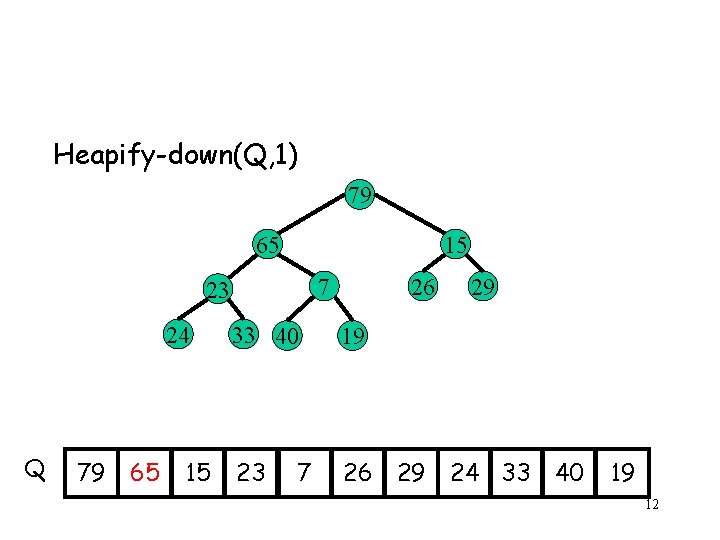
Heapify-down(Q, 2) 79 65 15 7 23 24 Q 79 65 15 26 33 40 19 23 26 7 29 29 24 33 40 19 11
Heapify-down(Q, 1) 79 65 15 7 23 24 Q 79 65 15 26 33 40 19 23 26 7 29 29 24 33 40 19 12
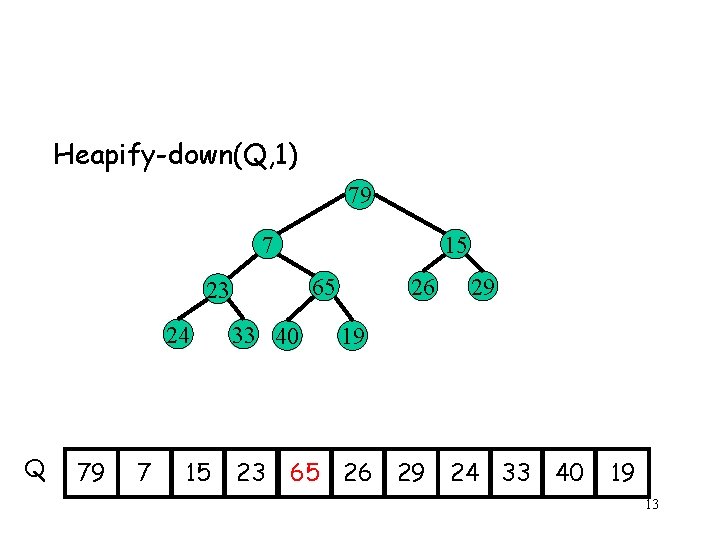
Heapify-down(Q, 1) 79 7 15 65 23 24 Q 79 7 15 33 40 23 26 29 19 65 26 29 24 33 40 19 13
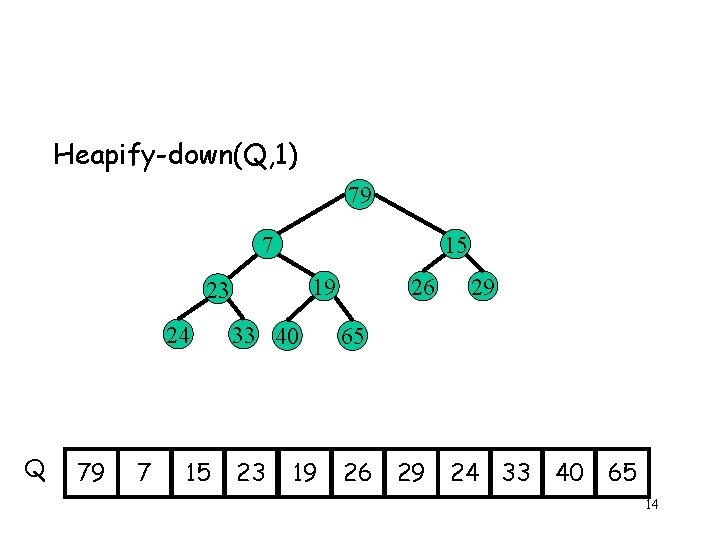
Heapify-down(Q, 1) 79 7 15 19 23 24 Q 79 7 15 26 33 40 65 23 26 19 29 29 24 33 40 65 14
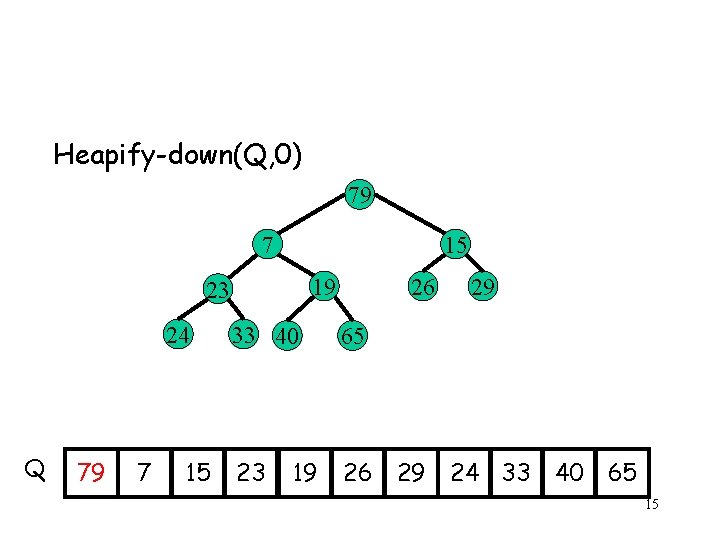
Heapify-down(Q, 0) 79 7 15 19 23 24 Q 79 7 15 26 33 40 65 23 26 19 29 29 24 33 40 65 15
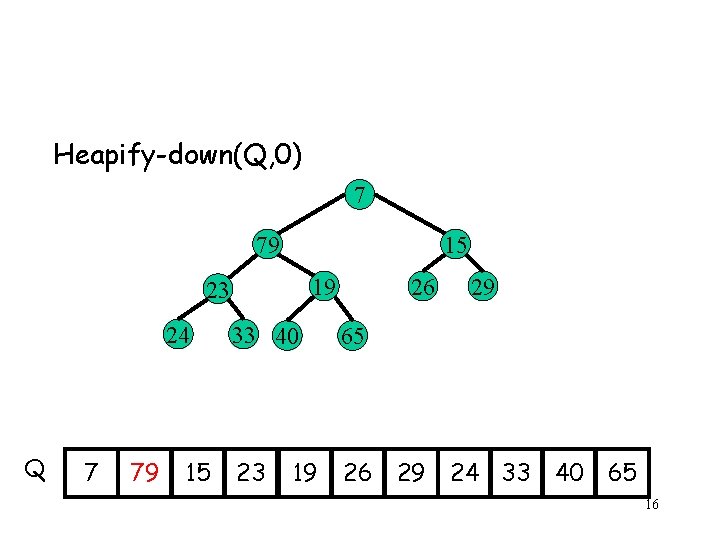
Heapify-down(Q, 0) 7 79 15 19 23 24 Q 7 79 15 26 33 40 65 23 26 19 29 29 24 33 40 65 16
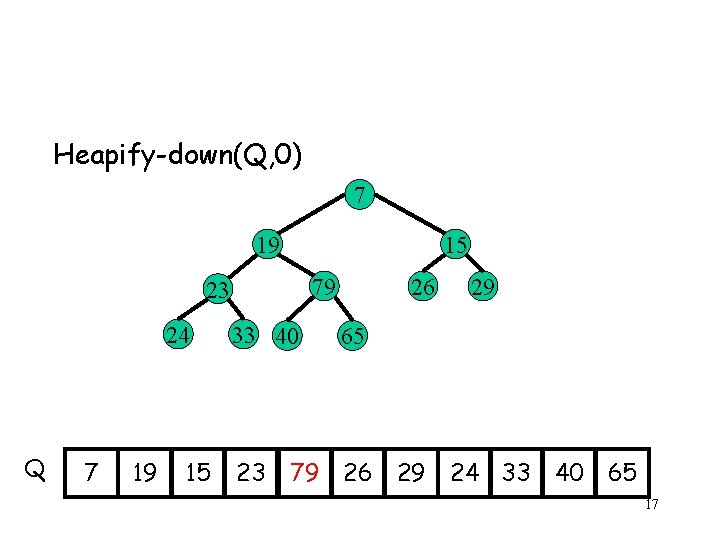
Heapify-down(Q, 0) 7 19 15 79 23 24 Q 7 19 15 33 40 23 26 29 65 79 26 29 24 33 40 65 17
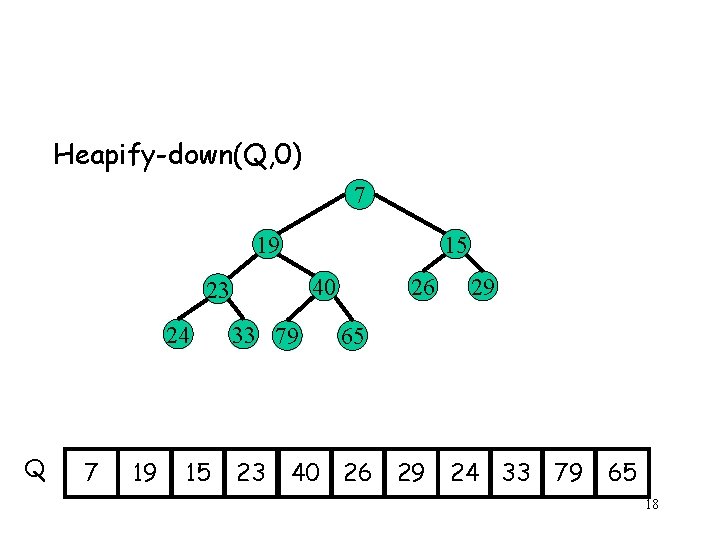
Heapify-down(Q, 0) 7 19 15 40 23 24 Q 7 19 15 33 79 23 26 29 65 40 26 29 24 33 79 65 18
Summery • We can build the heap in linear time (we already did this analysis) • We still have to deletemin the elements one by one in order to sort that will take O(nlog(n)) 20
Quicksort (Hoare 1961) 21
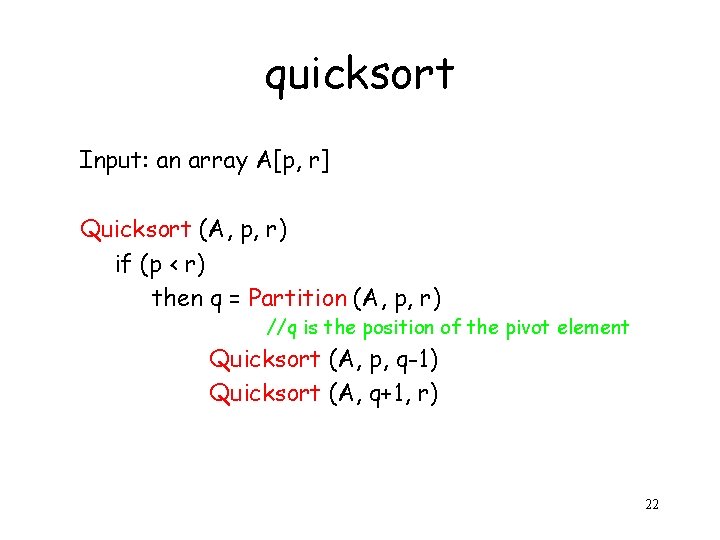
quicksort Input: an array A[p, r] Quicksort (A, p, r) if (p < r) then q = Partition (A, p, r) //q is the position of the pivot element Quicksort (A, p, q-1) Quicksort (A, q+1, r) 22
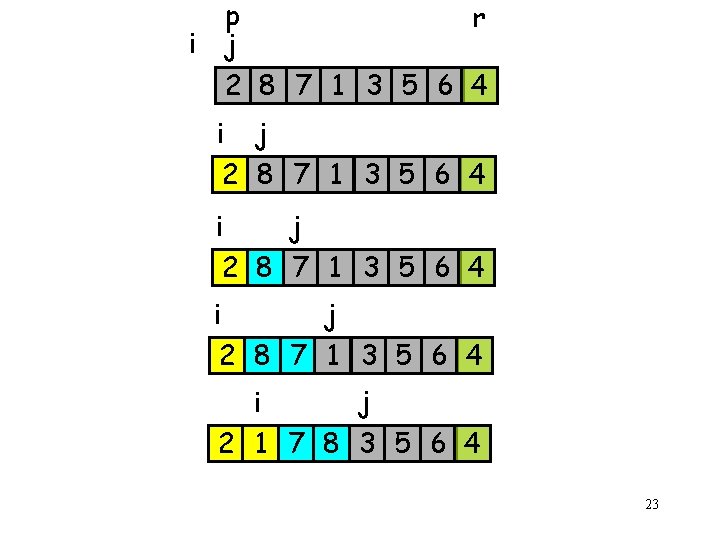
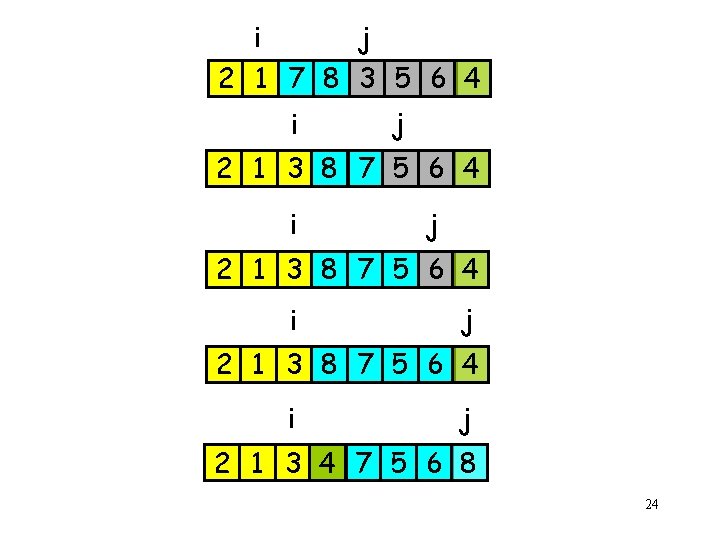
p r i j 2 8 7 1 3 5 6 4 j i 2 1 7 8 3 5 6 4 23
j i 2 1 7 8 3 5 6 4 i j 2 1 3 8 7 5 6 4 i j 2 1 3 4 7 5 6 8 24
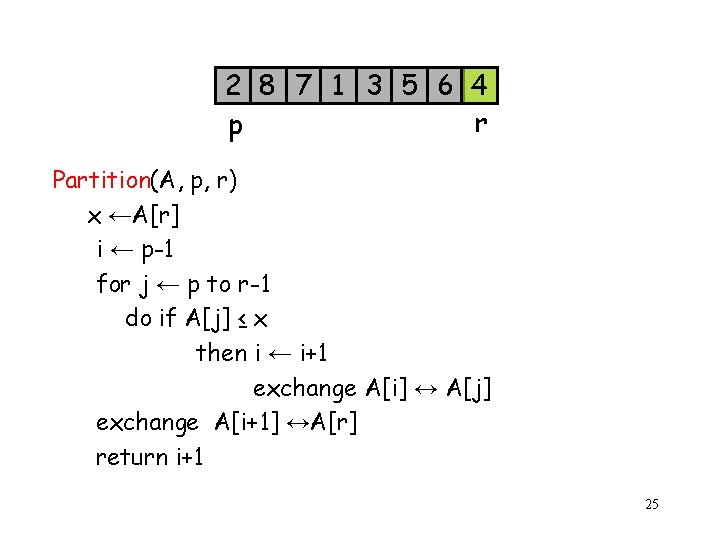
2 8 7 1 3 5 6 4 r p Partition(A, p, r) x ←A[r] i ← p-1 for j ← p to r-1 do if A[j] ≤ x then i ← i+1 exchange A[i] ↔ A[j] exchange A[i+1] ↔A[r] return i+1 25
Analysis • Running time is proportional to the number of comparisons • Each pair is compared at most once O(n 2) • In fact for each n there is an input of size n on which quicksort takes cn 2 Ω(n 2) 26
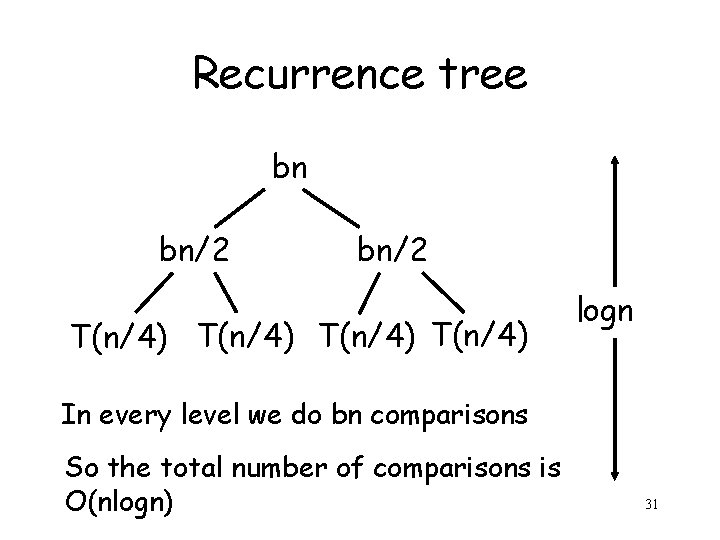
But • Assume that the split is even in each iteration 27
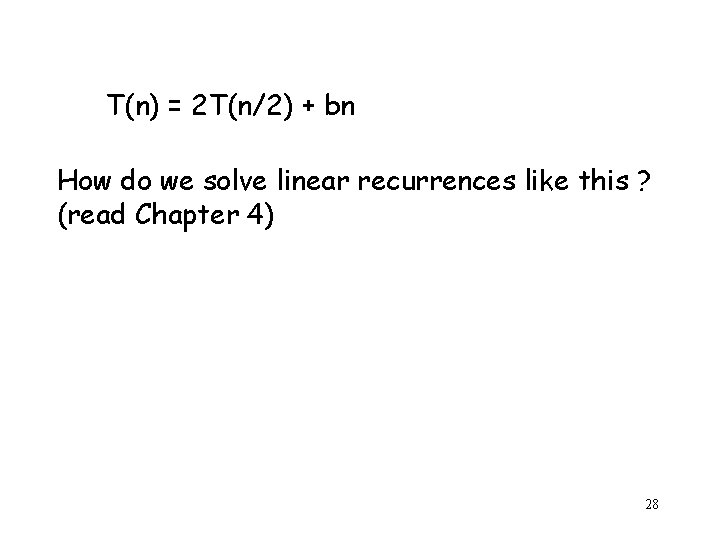
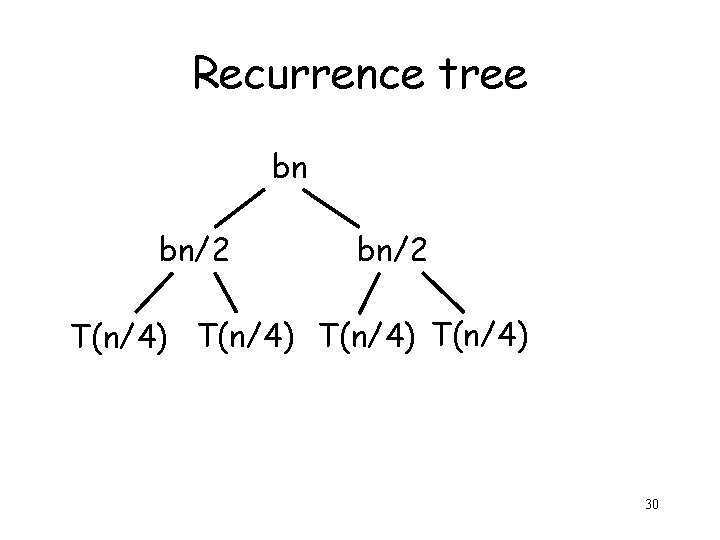
T(n) = 2 T(n/2) + bn How do we solve linear recurrences like this ? (read Chapter 4) 28
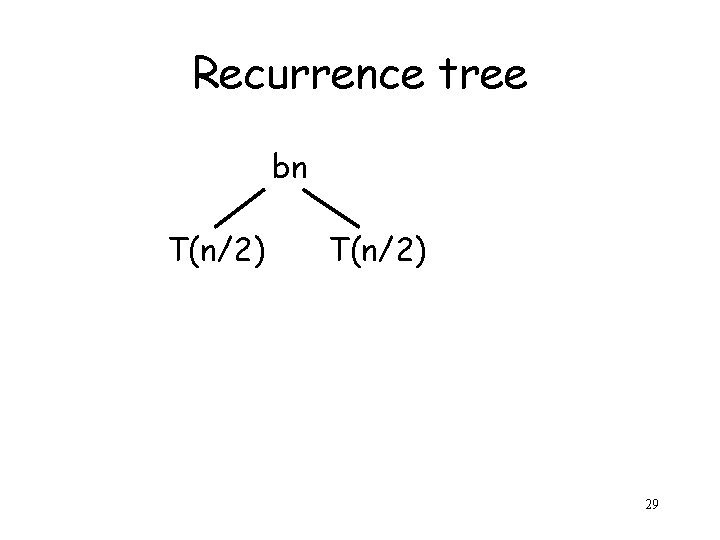
Recurrence tree bn T(n/2) 29
Recurrence tree bn bn/2 T(n/4) 30
Recurrence tree bn bn/2 T(n/4) logn In every level we do bn comparisons So the total number of comparisons is O(nlogn) 31
Observations • We can’t guarantee good splits • But intuitively on random inputs we will get good splits 34
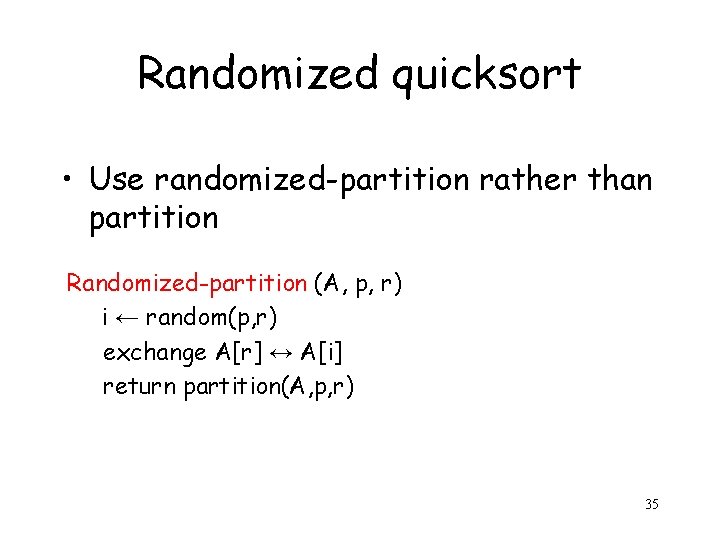
Randomized quicksort • Use randomized-partition rather than partition Randomized-partition (A, p, r) i ← random(p, r) exchange A[r] ↔ A[i] return partition(A, p, r) 35
• On the same input we will get a different running time in each run ! • Look at the average for one particular input of all these running times 36
Expected # of comparisons Let X be the expected # of comparisons This is a random variable Want to know E(X) 37
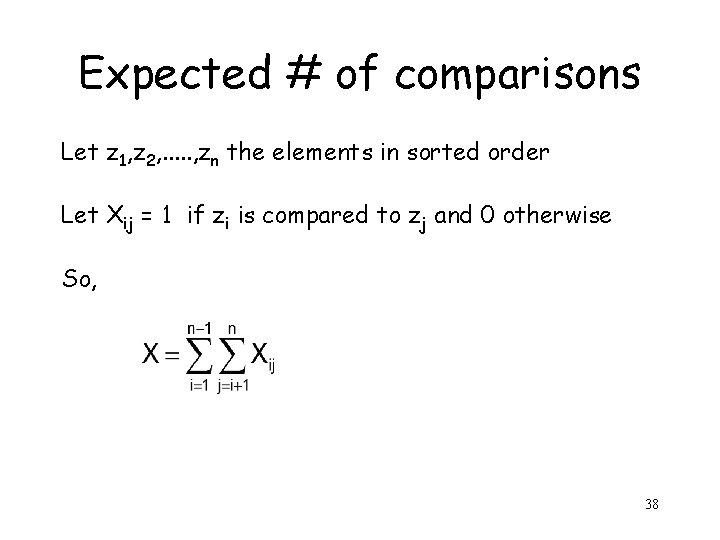
Expected # of comparisons Let z 1, z 2, . . . , zn the elements in sorted order Let Xij = 1 if zi is compared to zj and 0 otherwise So, 38
by linearity of expectation 39
by linearity of expectation 40
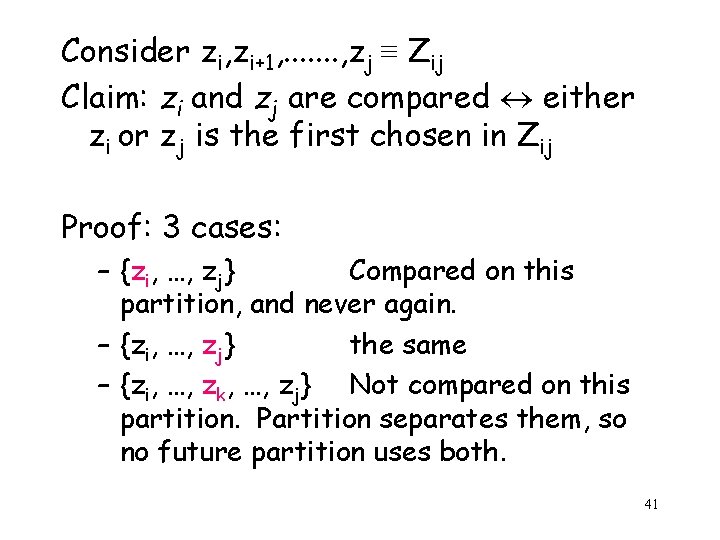
Consider zi, zi+1, . . . . , zj ≡ Zij Claim: zi and zj are compared either zi or zj is the first chosen in Zij Proof: 3 cases: – {zi, …, zj} Compared on this partition, and never again. – {zi, …, zj} the same – {zi, …, zk, …, zj} Not compared on this partition. Partition separates them, so no future partition uses both. 41
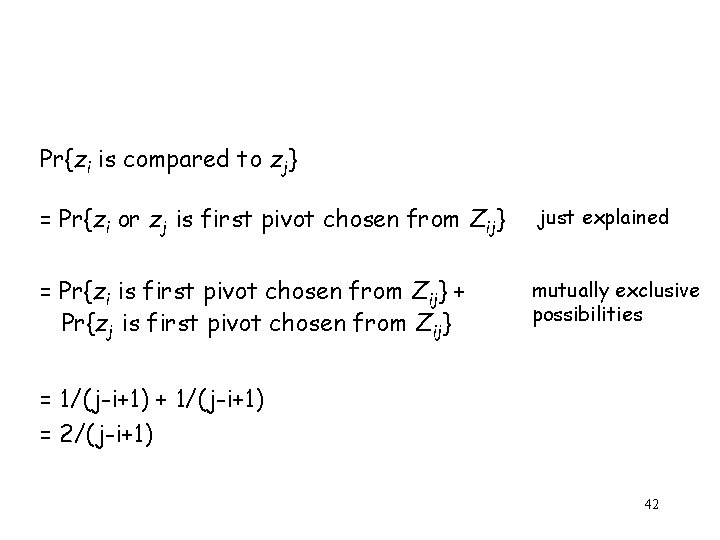
Pr{zi is compared to zj} = Pr{zi or zj is first pivot chosen from Zij} just explained = Pr{zi is first pivot chosen from Zij} + Pr{zj is first pivot chosen from Zij} mutually exclusive possibilities = 1/(j-i+1) + 1/(j-i+1) = 2/(j-i+1) 42
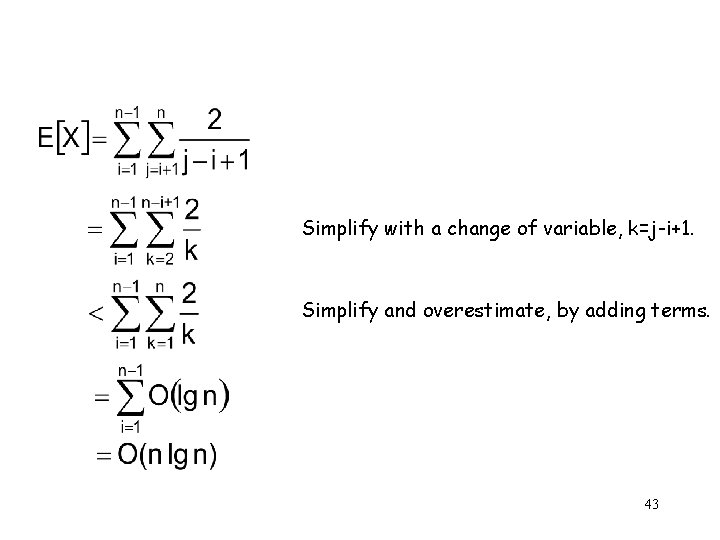
Simplify with a change of variable, k=j-i+1. Simplify and overestimate, by adding terms. 43
Lower bound for sorting in the comparison model 44
A lower bound • Comparison model: We assume that the operation from which we deduce order among keys are comparisons • Then we prove that we need Ω(nlogn) comparisons on the worst case 45
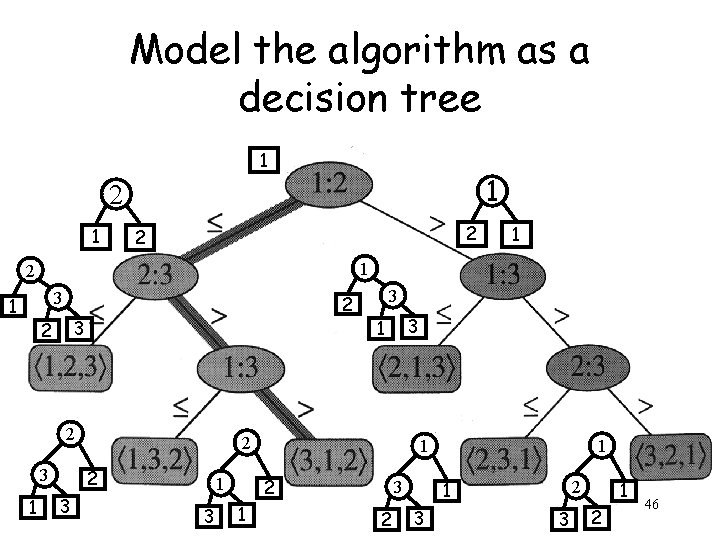
Model the algorithm as a decision tree 1 1 2 2 1 2 3 2 2 3 1 1 3 1 2 2 3 3 1 3 2 1 1 1 3 2 2 1 3 3 1 2 46
Important Observations • Every algorithm can be represented as a (binary) tree like this • Each path corresponds to a run on some input • The worst case # of comparisons corresponds to the longest path 47
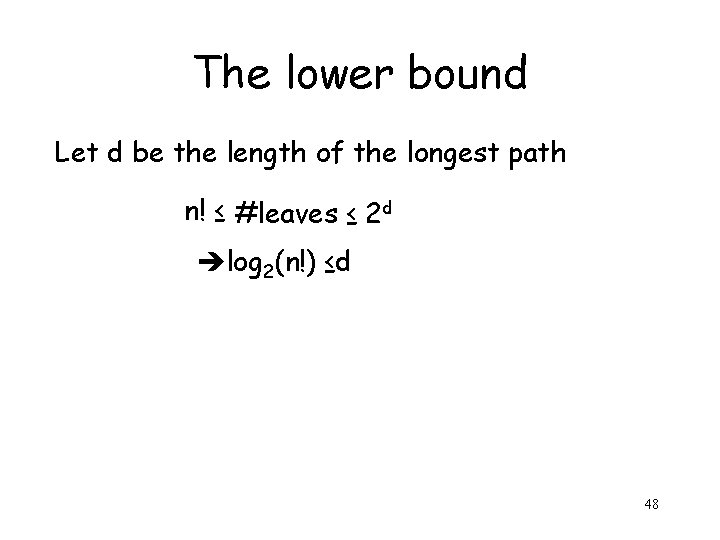
The lower bound Let d be the length of the longest path n! ≤ #leaves ≤ 2 d log 2(n!) ≤d 48
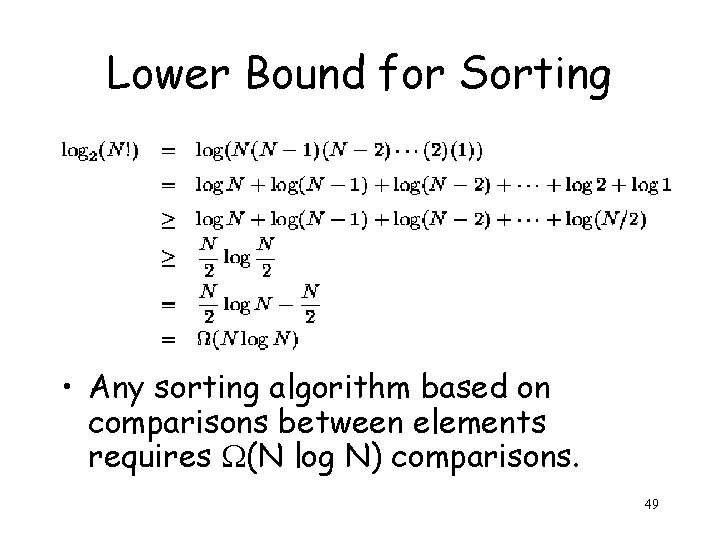
Lower Bound for Sorting • Any sorting algorithm based on comparisons between elements requires (N log N) comparisons. 49
Beating the lower bound • We can beat the lower bound if we can deduce order relations between keys not by comparisons Examples: • Count sort • Radix sort 50
Linear time sorting • Or assume something about the input: random, “almost sorted” 51
Sorting an almost sorted input • Suppose we know that the input is “almost” sorted • Let I be the number of “inversions” in the input: The number of pairs ai, aj such that i<j and ai>aj 52
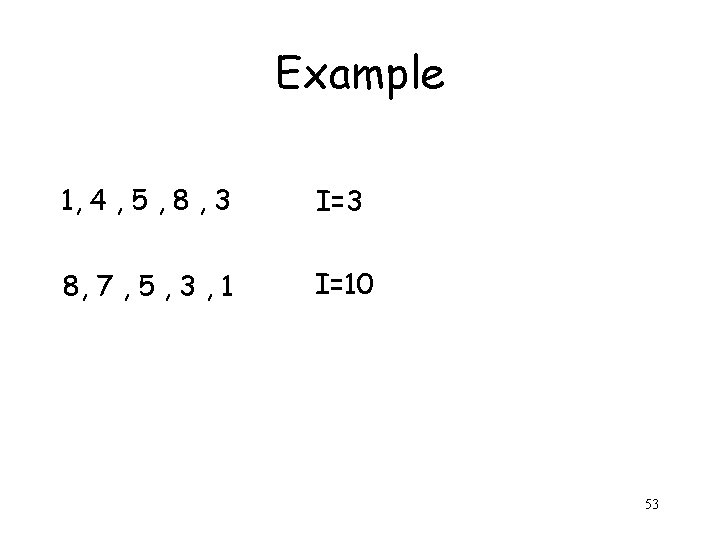
Example 1, 4 , 5 , 8 , 3 I=3 8, 7 , 5 , 3 , 1 I=10 53
• Think of “insertion sort” using a list • When we insert the next item ak, how deep it gets into the list? • As the number of inversions ai, ak for i < k lets call this Ik 54
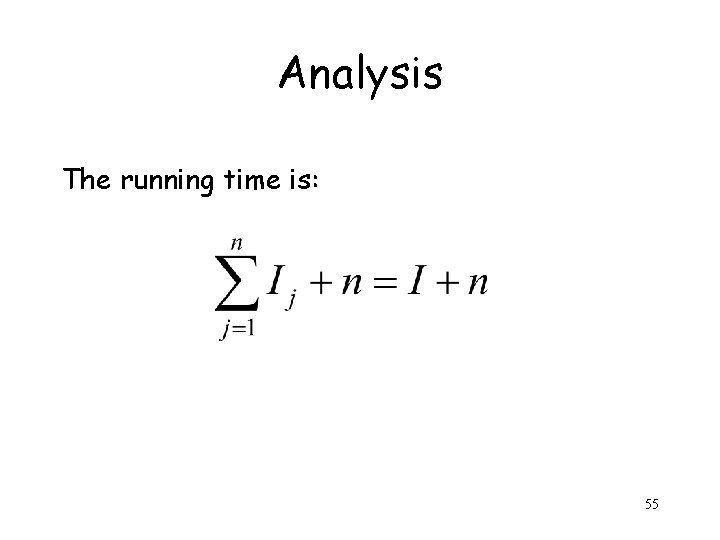
Analysis The running time is: 55
Thoughts • When I=Ω(n 2) the running time is Ω(n 2) • But we would like it to be O(nlog(n)) for any input, and faster whan I is small 56
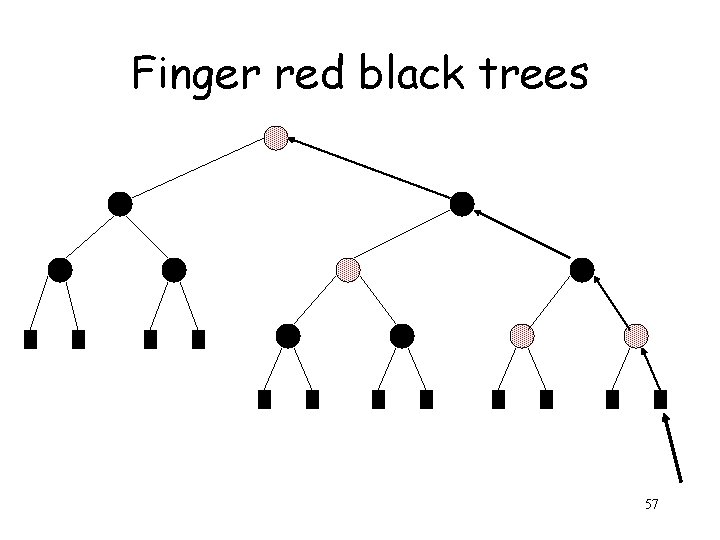
Finger red black trees 57
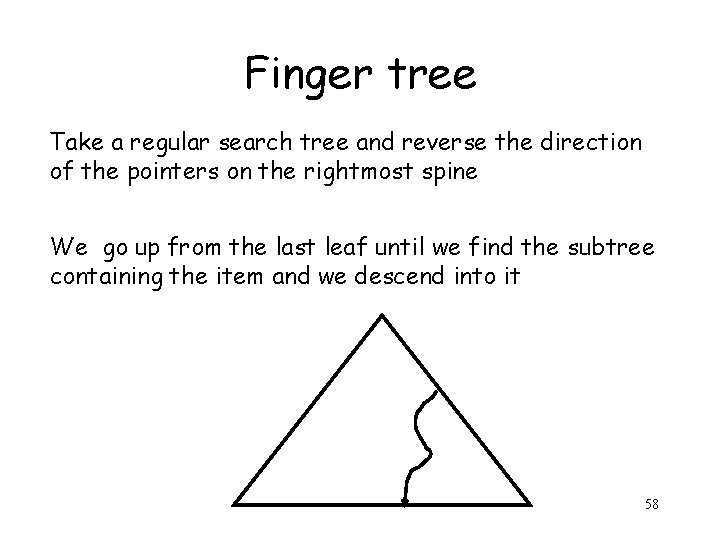
Finger tree Take a regular search tree and reverse the direction of the pointers on the rightmost spine We go up from the last leaf until we find the subtree containing the item and we descend into it 58
Finger trees Say we search for a position at distance d from the end Then we go up to height O(log(d)) So search for the dth position takes O(log(d)) time Insertions and deletions still take O(log n) worst case time but O(log(d)) amortized time 59
Back to sorting • Suppose we implement the insertion sort using a finger search tree • When we insert item k then d=O(Ik) and it take O(log(Ik)) time 60
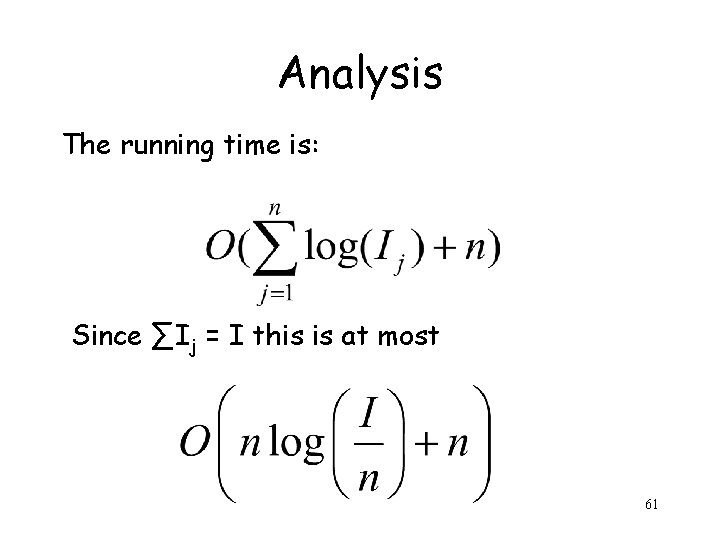
Analysis The running time is: Since ∑Ij = I this is at most 61
Selection Find the kth element 62
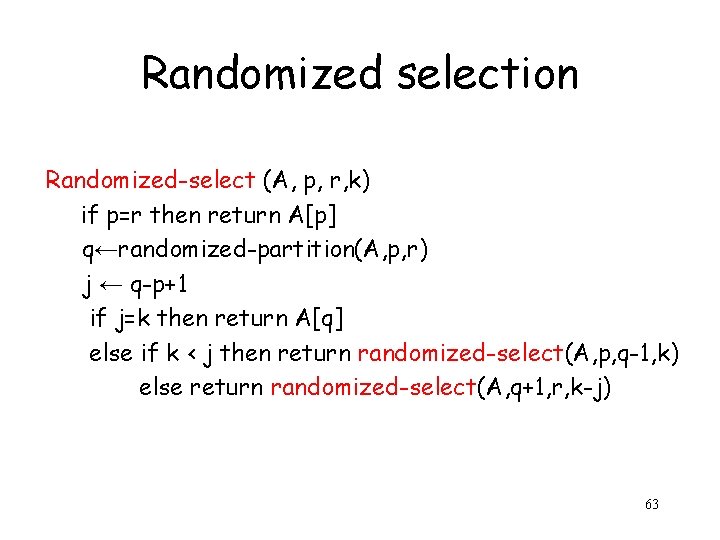
Randomized selection Randomized-select (A, p, r, k) if p=r then return A[p] q←randomized-partition(A, p, r) j ← q-p+1 if j=k then return A[q] else if k < j then return randomized-select(A, p, q-1, k) else return randomized-select(A, q+1, r, k-j) 63
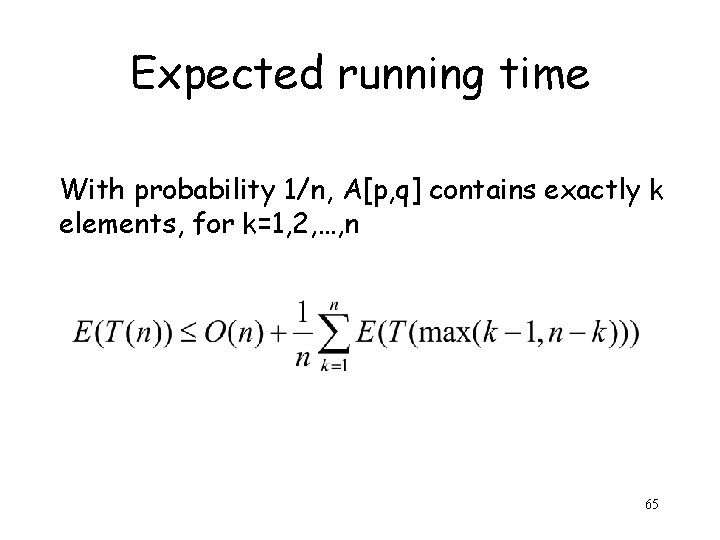
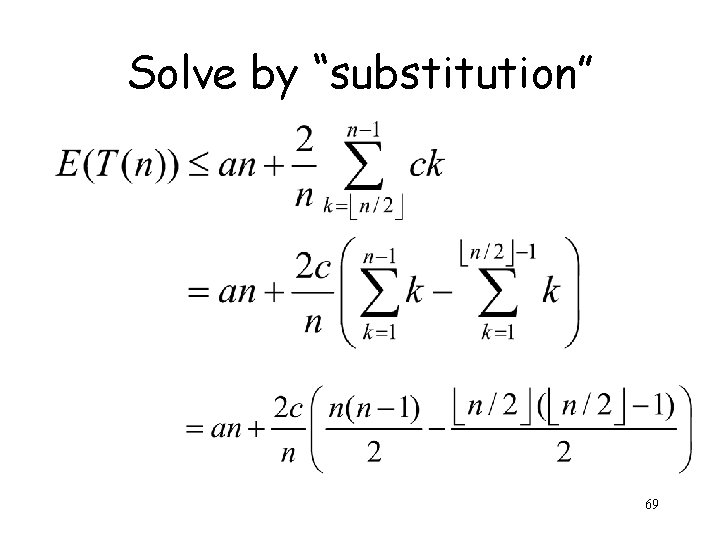
Expected running time With probability 1/n, A[p, q] contains exactly k elements, for k=1, 2, …, n 65
Assume n is even 66
In general 67
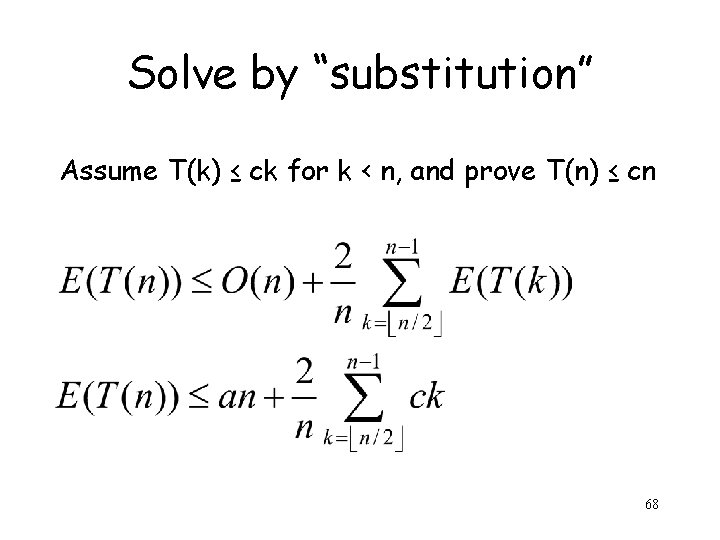
Solve by “substitution” Assume T(k) ≤ ck for k < n, and prove T(n) ≤ cn 68
Solve by “substitution” 69
Choose c ≥ 4 a 70
Selection in linear worst case time Blum, Floyd, Pratt, Rivest, and Tarjan (1973) 71
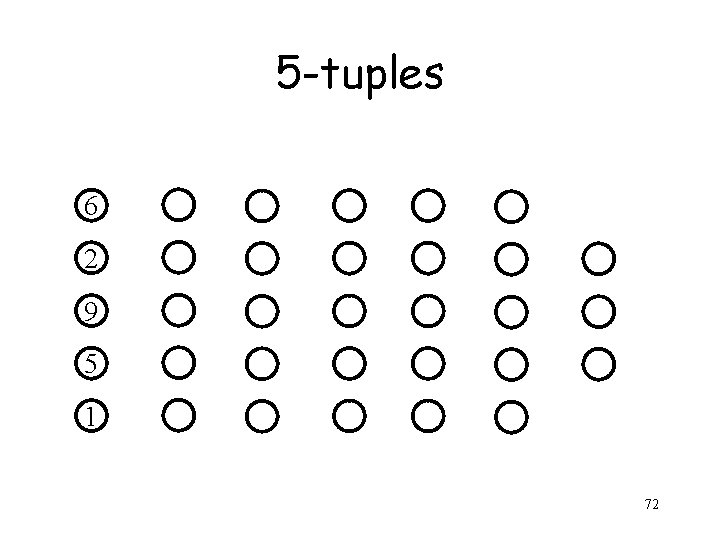
5 -tuples 6 2 9 5 1 72
Sort the tuples 9 6 5 2 1 73
Recursively find the median of the medians 9 6 5 2 1 74
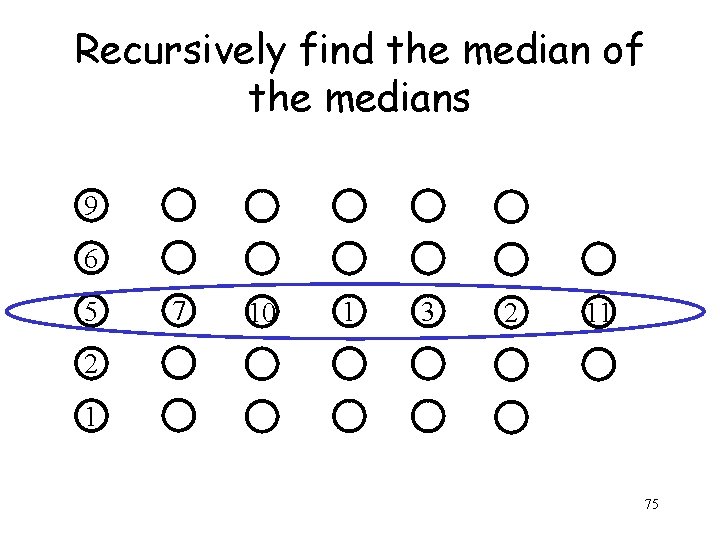
Recursively find the median of the medians 9 6 5 7 10 1 3 2 11 2 1 75
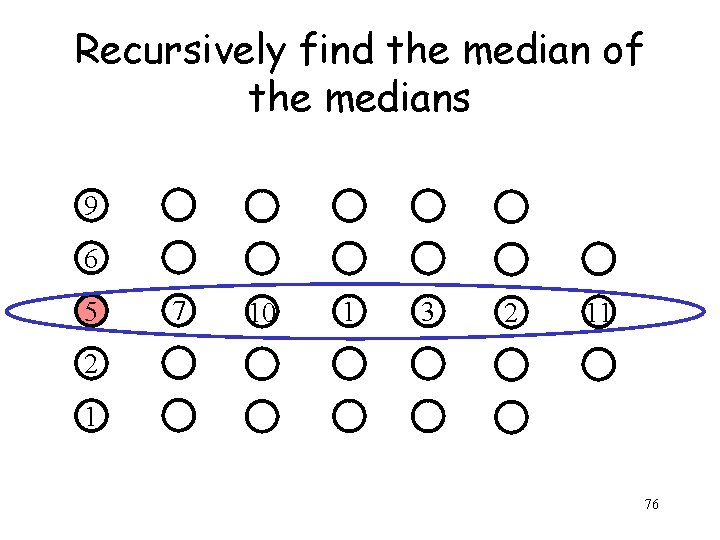
Recursively find the median of the medians 9 6 5 7 10 1 3 2 11 2 1 76
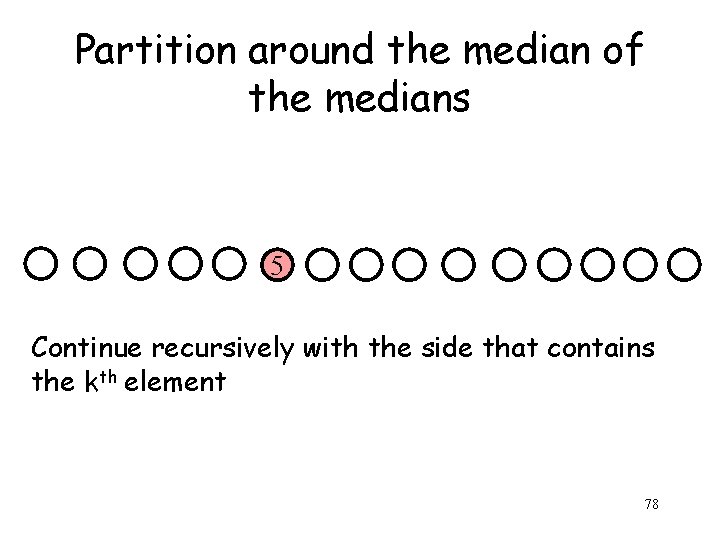
Partition around the median of the medians 5 Continue recursively with the side that contains the kth element 78
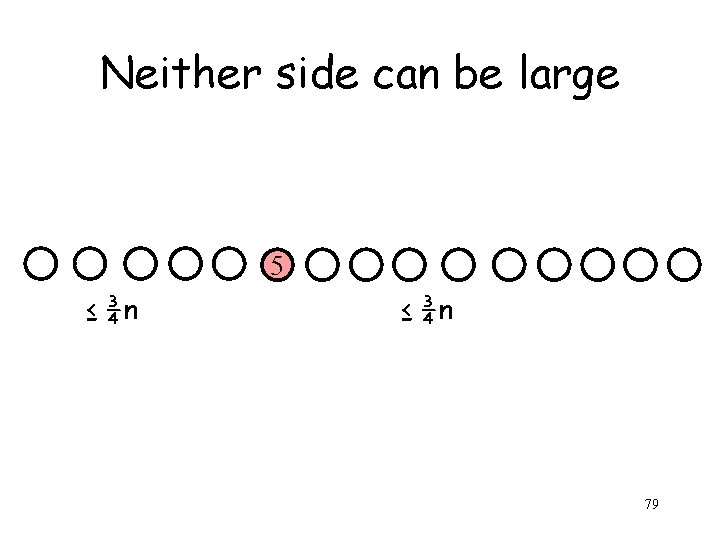
Neither side can be large 5 ≤ ¾n 79
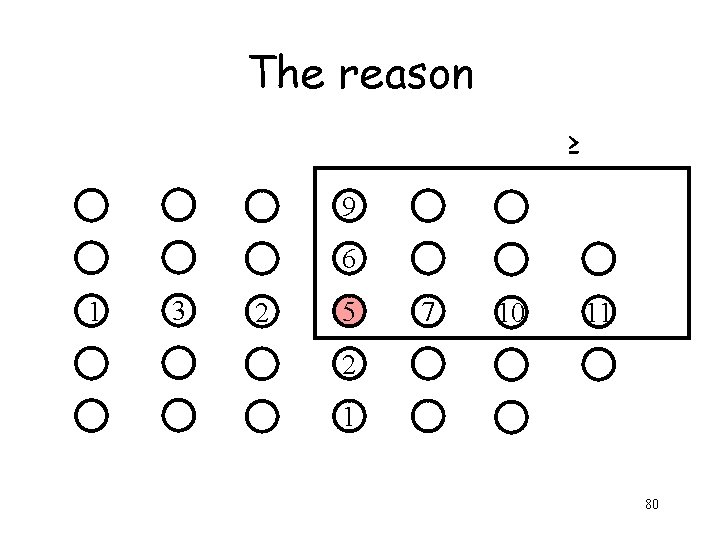
The reason ≥ 9 6 1 3 2 5 7 10 11 2 1 80
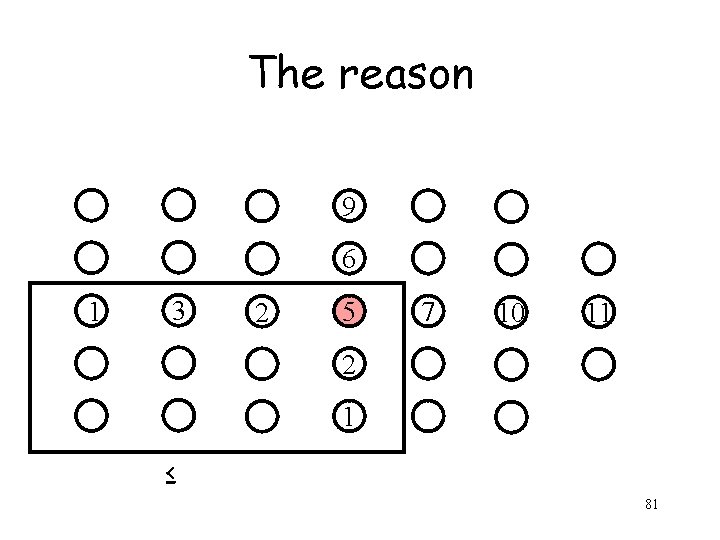
The reason 9 6 1 3 2 5 7 10 11 2 1 ≤ 81
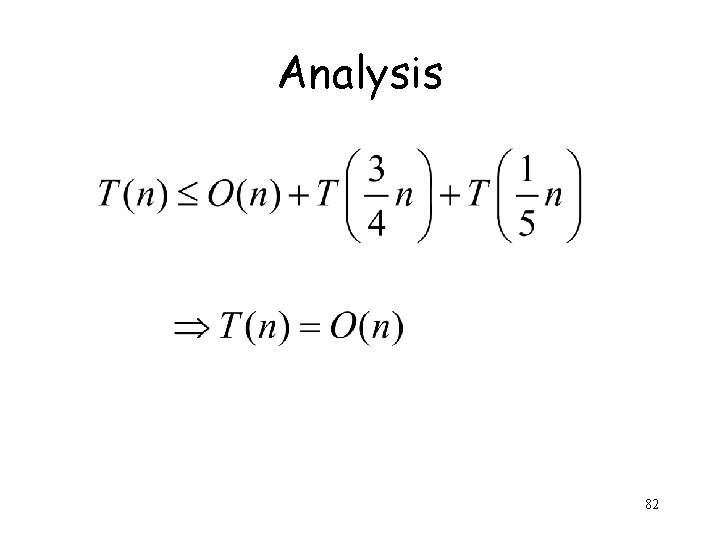
Analysis 82
Order statistics, a dynamic version rank and select 83
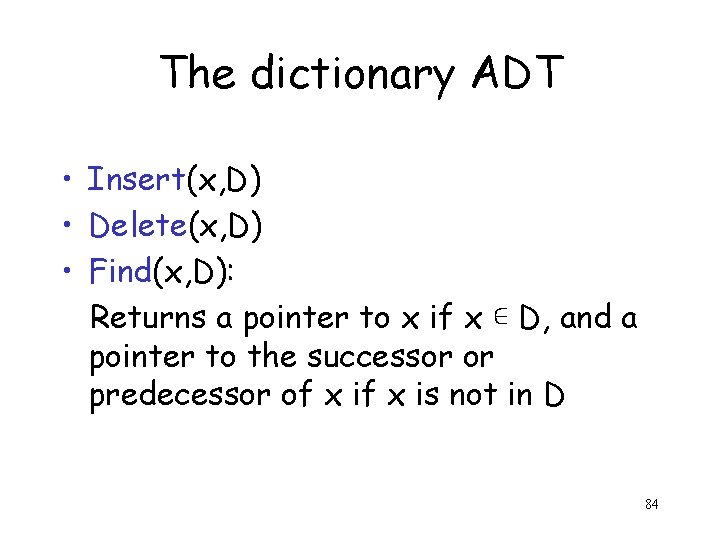
The dictionary ADT • Insert(x, D) • Delete(x, D) • Find(x, D): Returns a pointer to x if x ∊ D, and a pointer to the successor or predecessor of x is not in D 84
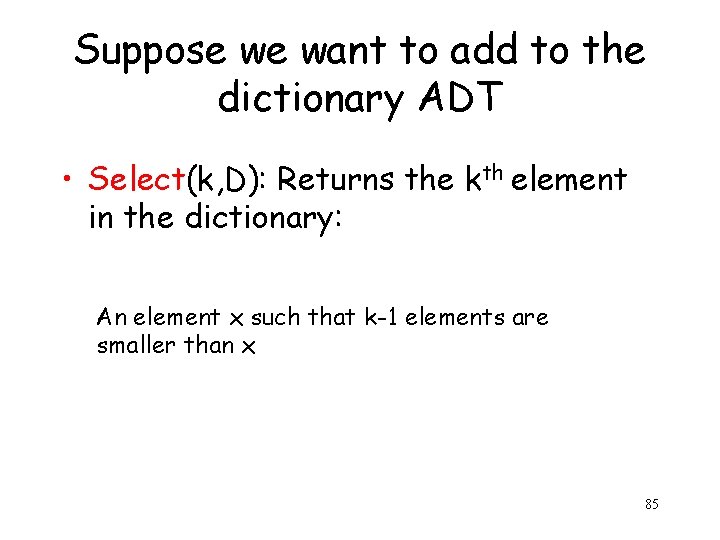
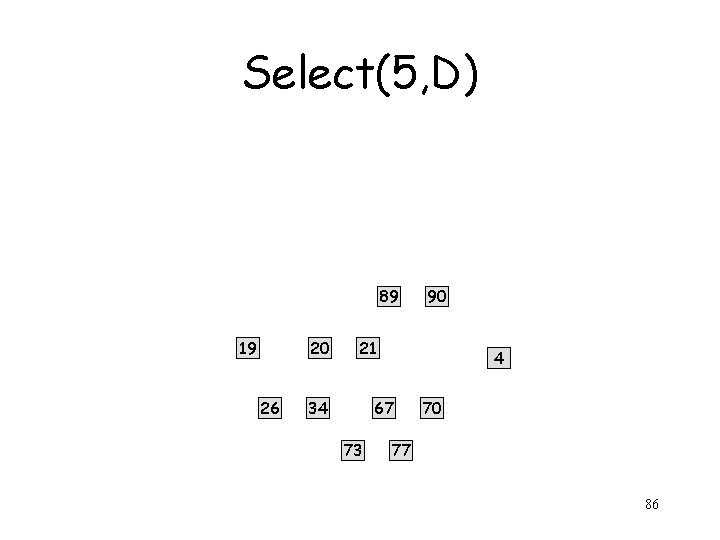
Suppose we want to add to the dictionary ADT • Select(k, D): Returns the kth element in the dictionary: An element x such that k-1 elements are smaller than x 85
Select(5, D) 89 19 20 26 90 21 34 4 67 73 70 77 86
Select(5, D) 89 19 20 26 90 21 34 4 67 73 70 77 87
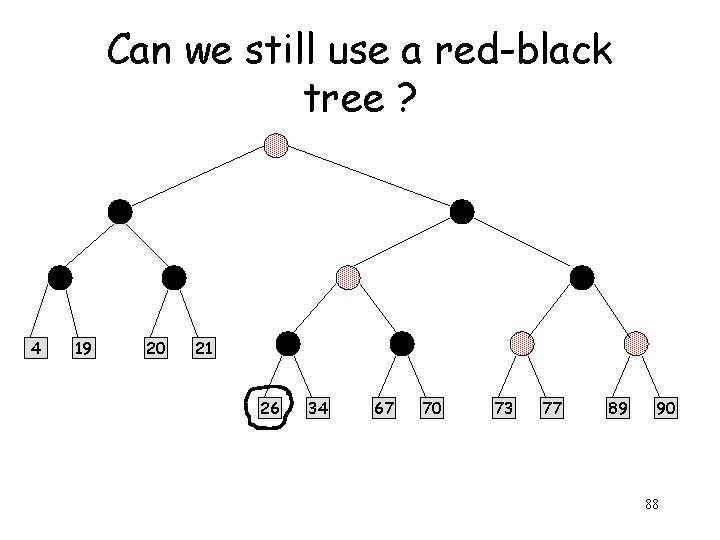
Can we still use a red-black tree ? 4 19 20 21 26 34 67 70 73 77 89 90 88
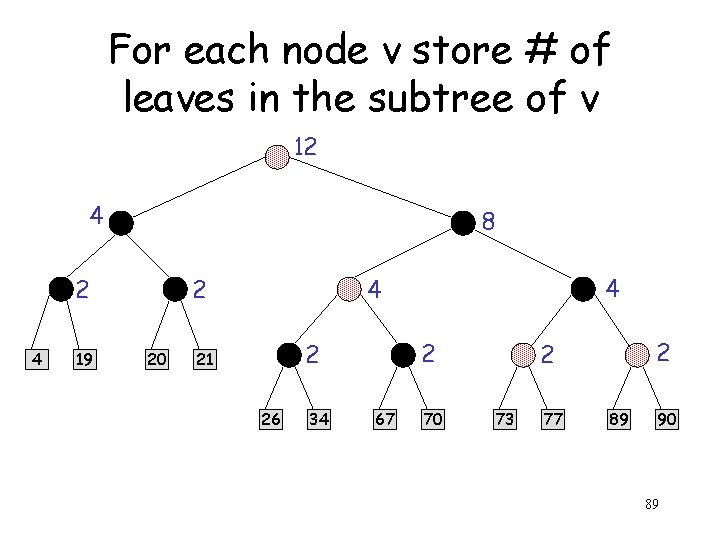
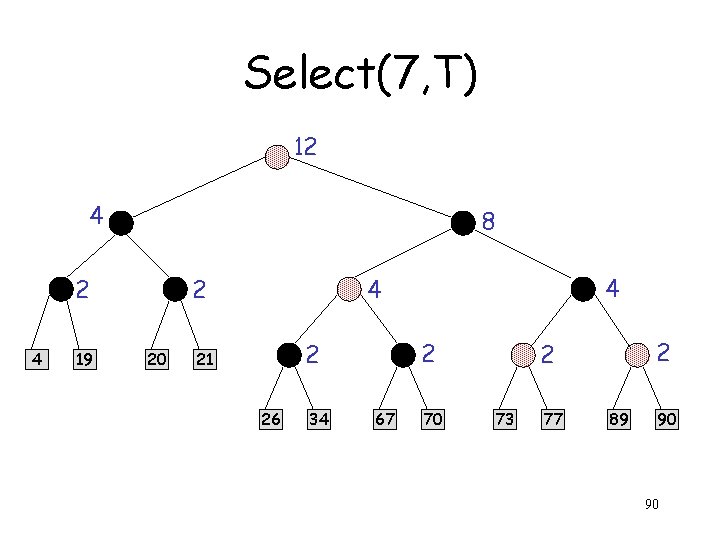
For each node v store # of leaves in the subtree of v 12 4 8 2 4 19 2 20 4 4 2 2 21 26 34 67 70 2 2 73 77 89 90 89
Select(7, T) 12 4 8 2 4 19 2 20 4 4 2 2 21 26 34 67 70 2 2 73 77 89 90 90
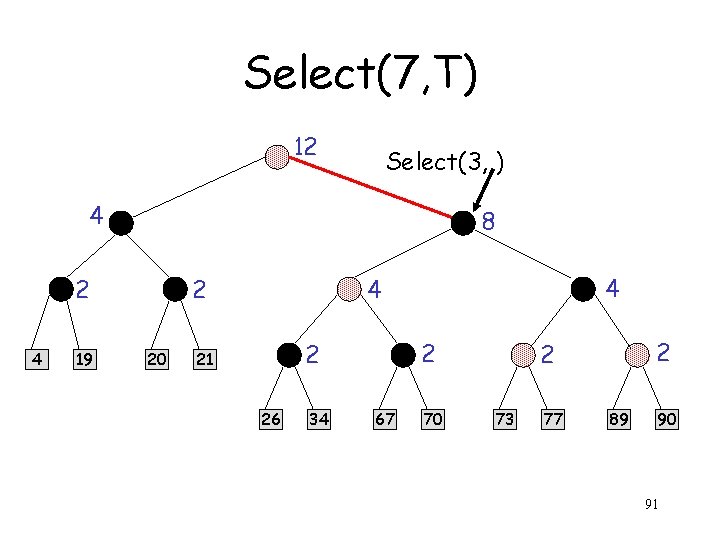
Select(7, T) 12 Select(3, ) 4 8 2 4 19 2 20 4 4 2 2 21 26 34 67 70 2 2 73 77 89 90 91
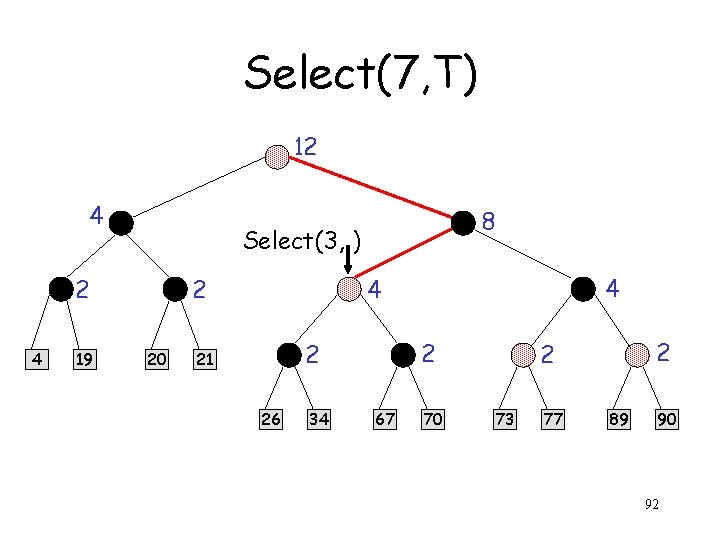
Select(7, T) 12 4 Select(3, ) 2 4 19 8 2 20 4 4 2 2 21 26 34 67 70 2 2 73 77 89 90 92
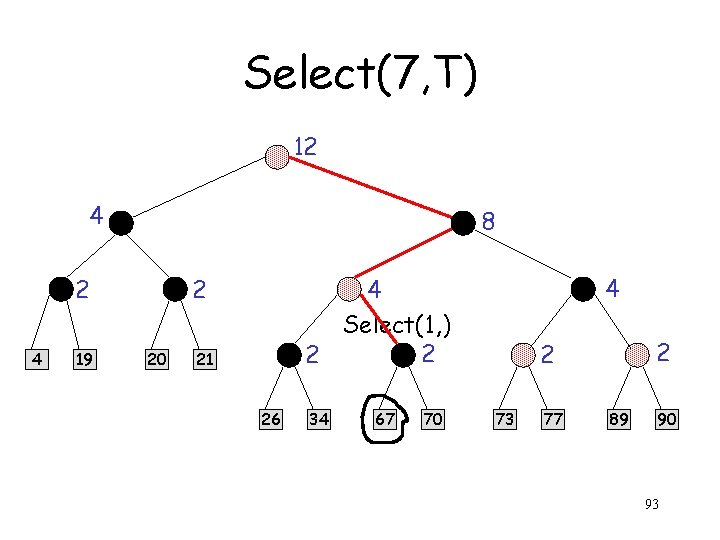
Select(7, T) 12 4 8 2 4 19 2 20 4 4 Select(1, ) 2 2 21 26 34 67 70 2 2 73 77 89 90 93
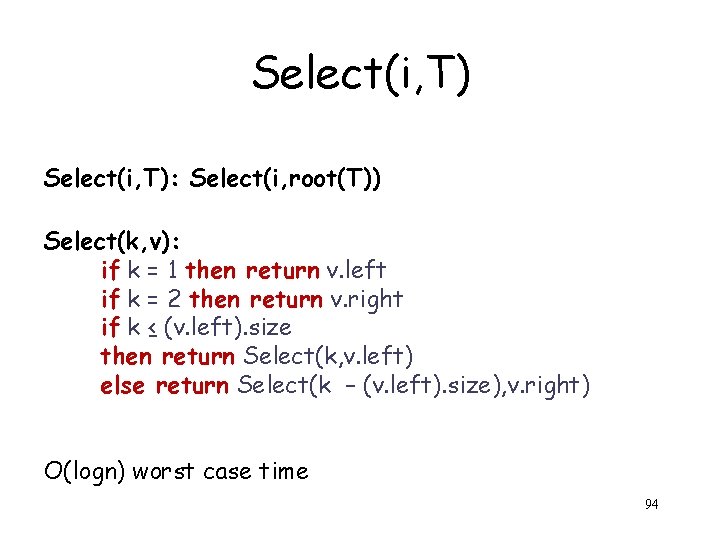
Select(i, T): Select(i, root(T)) Select(k, v): if k = 1 then return v. left if k = 2 then return v. right if k ≤ (v. left). size then return Select(k, v. left) else return Select(k – (v. left). size), v. right) O(logn) worst case time 94
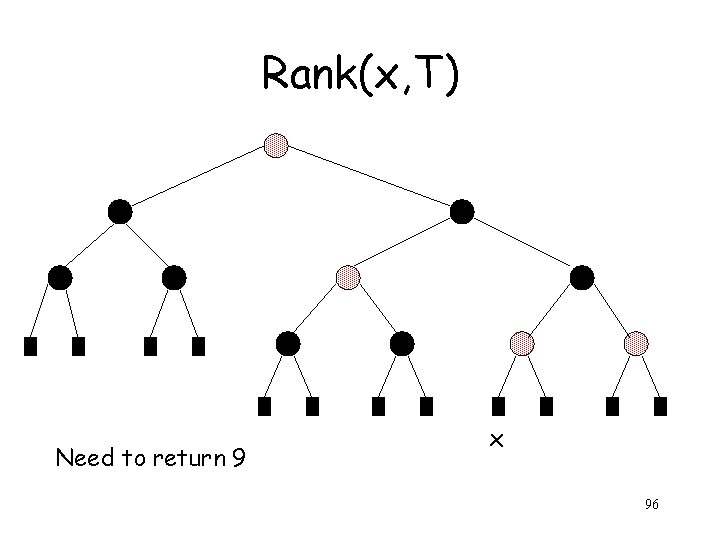
Rank(x, T) • Return the index of x in T 95
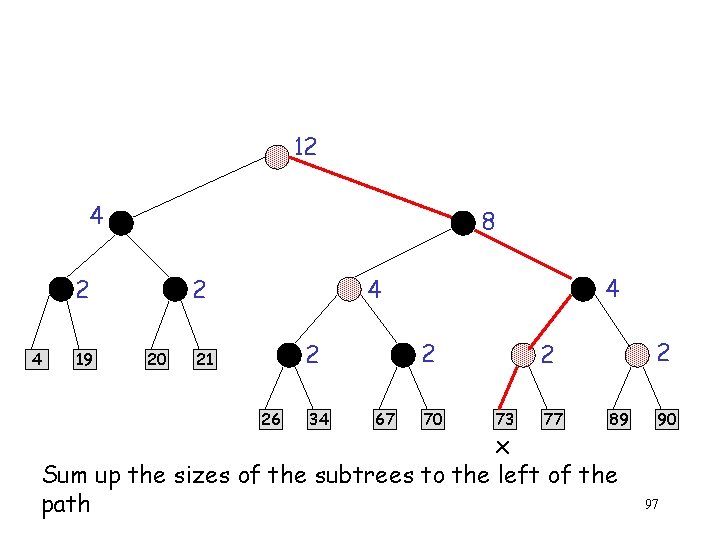
Rank(x, T) Need to return 9 x 96
12 4 8 2 4 19 2 20 4 4 2 2 21 26 34 67 70 2 2 73 77 89 x Sum up the sizes of the subtrees to the left of the path 90 97
Rank(x, T) • Write the p-code 98
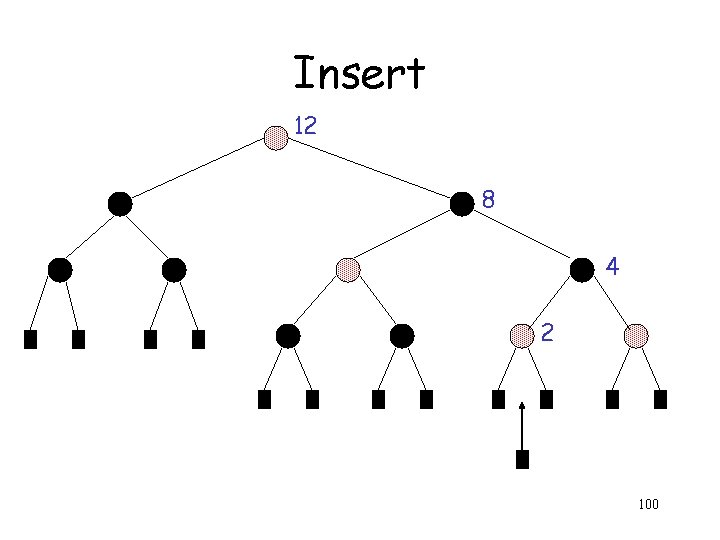
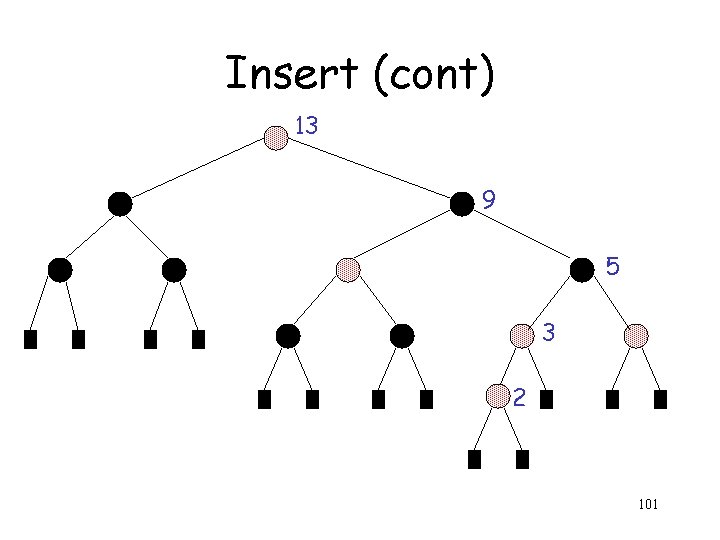
Insertion and deletions • Consider insertion, deletion is similar 99
Insert 12 8 4 2 100
Insert (cont) 13 9 5 3 2 101
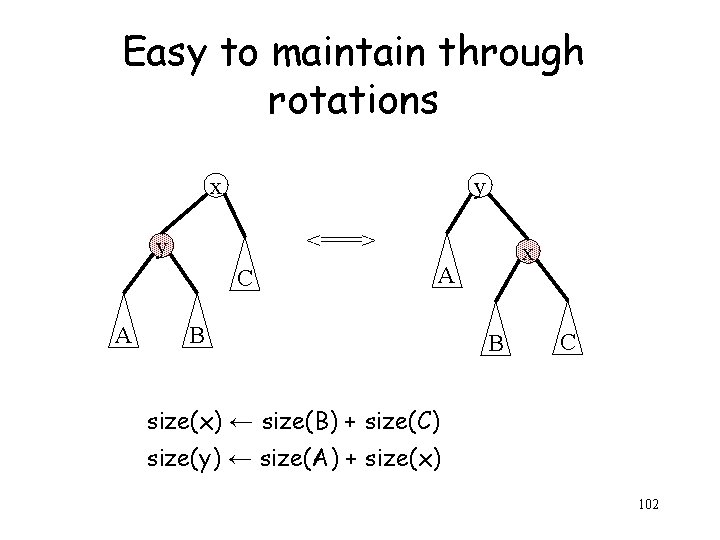
Easy to maintain through rotations x y <===> y C A x A B B C size(x) ← size(B) + size(C) size(y) ← size(A) + size(x) 102
Summary • Insertion and deletion and other dictionary operations still take O(log n) time 103