
Research at the Computer Engineering Laboratory of Delft
Research at the Computer Engineering Laboratory of Delft University of Technology Ben Juurlink
Outline n General Information u u u n n Group Interests Group Projects u u n n Group Location Group Formation Group Funding Molen -Iliad MOVE Pamela PUB library Concluding Remarks Universidad Polytecnica de Catalunya 2
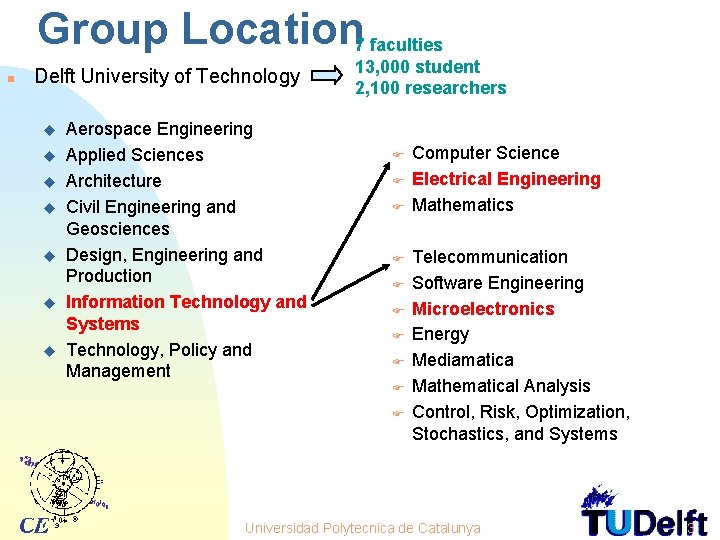
Group Location 7 faculties n Delft University of Technology u u u u Aerospace Engineering Applied Sciences Architecture Civil Engineering and Geosciences Design, Engineering and Production Information Technology and Systems Technology, Policy and Management 13, 000 student 2, 100 researchers F F F F F Computer Science Electrical Engineering Mathematics Telecommunication Software Engineering Microelectronics Energy Mediamatica Mathematical Analysis Control, Risk, Optimization, Stochastics, and Systems Universidad Polytecnica de Catalunya 3
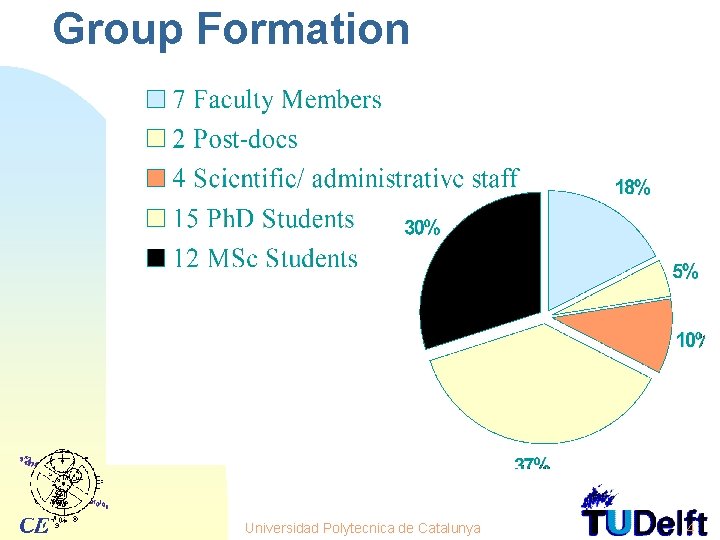
Group Formation Universidad Polytecnica de Catalunya 4
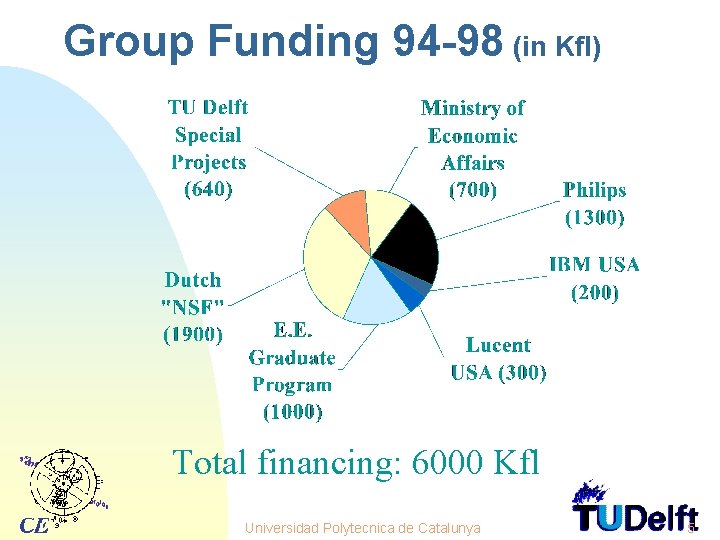
Group Funding 94 -98 (in Kfl) Total financing: 6000 Kfl Universidad Polytecnica de Catalunya 5
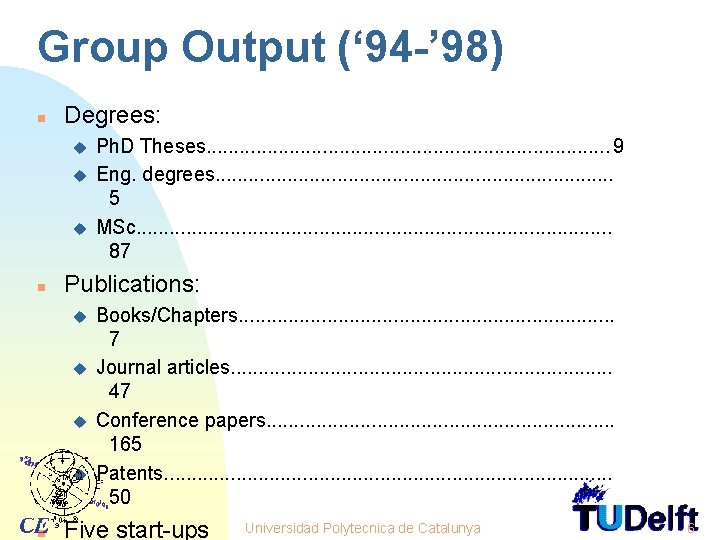
Group Output (‘ 94 -’ 98) n Degrees: u u u n Publications: u u n Ph. D Theses. . . . . 9 Eng. degrees. . . . . 5 MSc. . . . . . 87 Books/Chapters. . . . . 7 Journal articles. . . . . 47 Conference papers. . . . 165 Patents. . . . . 50 Five start-ups Universidad Polytecnica de Catalunya 6
Computer Engineering n n Computer Engineering: Analysis of data processing requirements for electronic data processing units and systems and the design (synthesis) of their architecture, implementation, and realization Architecture: Determine the function to perform Implementation: Establish a method to achieve the function Realization: Use available means to materialize the method Universidad Polytecnica de Catalunya 7
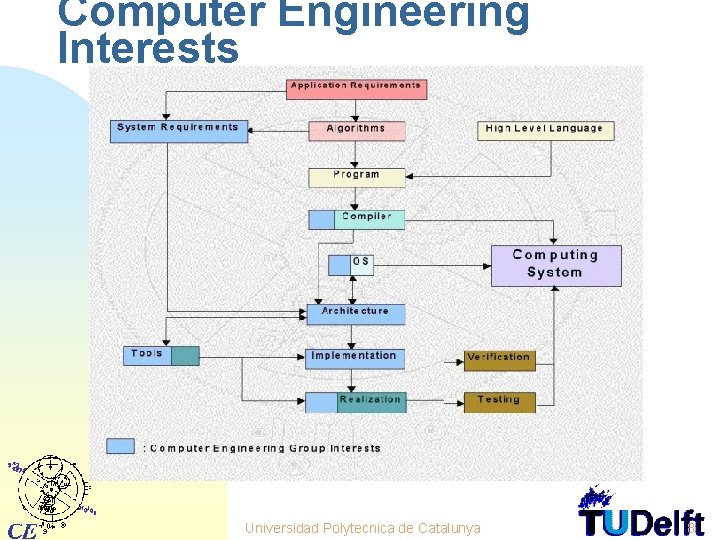
Computer Engineering Interests Universidad Polytecnica de Catalunya 8
Group Projects MOLEN : Embedded system architecture, multimedia, Java. MOVE : Embedded system synthesis, compilers, hardware software co-design. PAMELA : Performance analysis and languages. D-ILIAD : Computer architecture, implementation, computer arithmetic, switches. Universidad Polytecnica de Catalunya 9
MOLEN Embedded System Design n Topics: u Embedded Processor Architectures u Multimedia u Java u Embedded System Tools u Embedded Agents Current Contributions: u Java Processor u Multimedia Instructions u Specialized Units u FPGA Units Future Directions: u Reconfigurable embedded processors Universidad Polytecnica de Catalunya 10

Molen Multimedia Instruction and Functional Unit n n Published at EUROMICRO’ 98 Motion estimation, sum of absolute differences: s = 0; for (j=0; j<h; j++){ if ((v = p 1[0]-p 2[0])<0) v = -v; s += v; if ((v = p 1[1]-p 2[1])<0) v = -v; s += v; . . . if ((v = p 1[15]-p 2[15])<0) v = -v; s += v; if (s >= distlim) break; p 1 += lx; p 2 += lx; } n Formula: Universidad Polytecnica de Catalunya 11
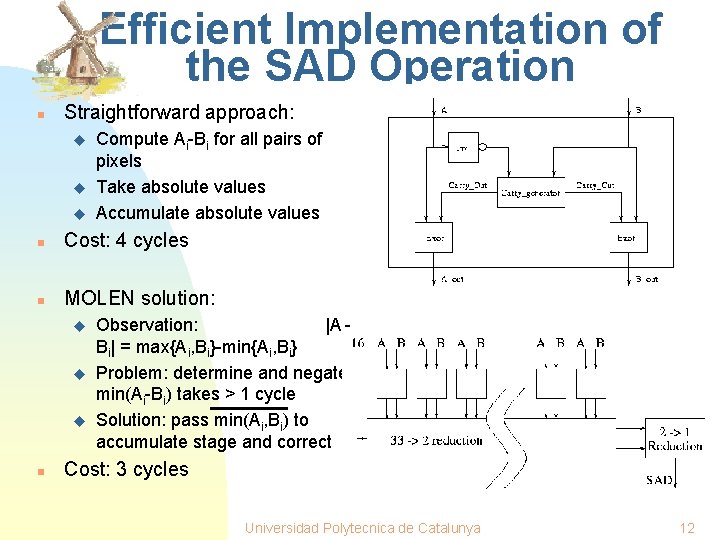
Efficient Implementation of the SAD Operation n Straightforward approach: u u u Compute Ai-Bi for all pairs of pixels Take absolute values Accumulate absolute values n Cost: 4 cycles n MOLEN solution: u u u n Observation: |Ai. Bi| = max{Ai, Bi}-min{Ai, Bi} Problem: determine and negate min(Ai-Bi) takes > 1 cycle Solution: pass min(Ai, Bi) to accumulate stage and correct Cost: 3 cycles Universidad Polytecnica de Catalunya 12
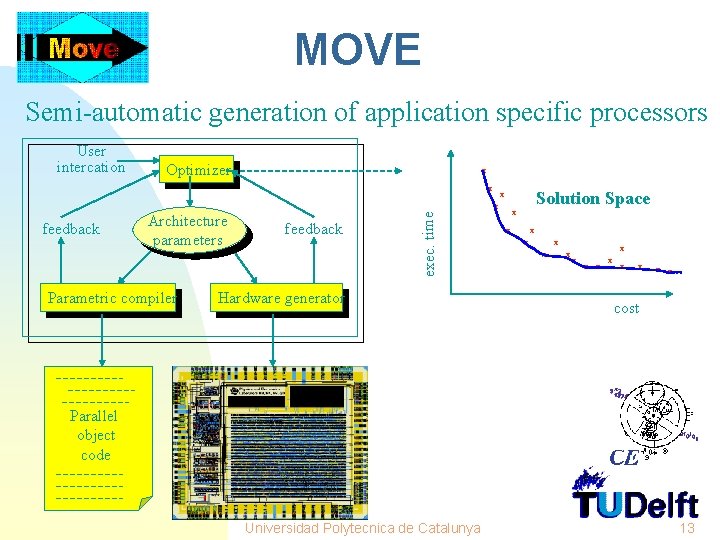
MOVE Semi-automatic generation of application specific processors User intercation Optimizer x x Solution Space x feedback Architecture parameters Parametric compiler feedback exec. time x Hardware generator x x x x cost Parallel object code Universidad Polytecnica de Catalunya 13
MOVE n n Current Contributions: u Transport triggered architecture u Operational design framework (add any unit you like, no restrictions) u Several cheap designs (data logger, video-enhancer, MPEGdecoder, wireless communications) Future Directions: u Tune your application to suit your processor u System design u Multiprocessor TTA u Low-power processors Universidad Polytecnica de Catalunya 14
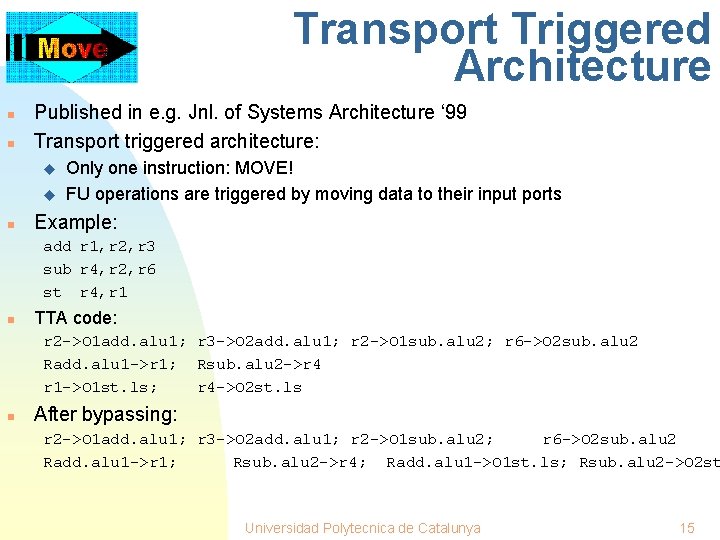
Transport Triggered Architecture n n Published in e. g. Jnl. of Systems Architecture ‘ 99 Transport triggered architecture: u u n Only one instruction: MOVE! FU operations are triggered by moving data to their input ports Example: add r 1, r 2, r 3 sub r 4, r 2, r 6 st r 4, r 1 n TTA code: r 2 ->O 1 add. alu 1; r 3 ->O 2 add. alu 1; r 2 ->O 1 sub. alu 2; r 6 ->O 2 sub. alu 2 Radd. alu 1 ->r 1; Rsub. alu 2 ->r 4 r 1 ->O 1 st. ls; r 4 ->O 2 st. ls n After bypassing: r 2 ->O 1 add. alu 1; r 3 ->O 2 add. alu 1; r 2 ->O 1 sub. alu 2; r 6 ->O 2 sub. alu 2 Radd. alu 1 ->r 1; Rsub. alu 2 ->r 4; Radd. alu 1 ->O 1 st. ls; Rsub. alu 2 ->O 2 st Universidad Polytecnica de Catalunya 15
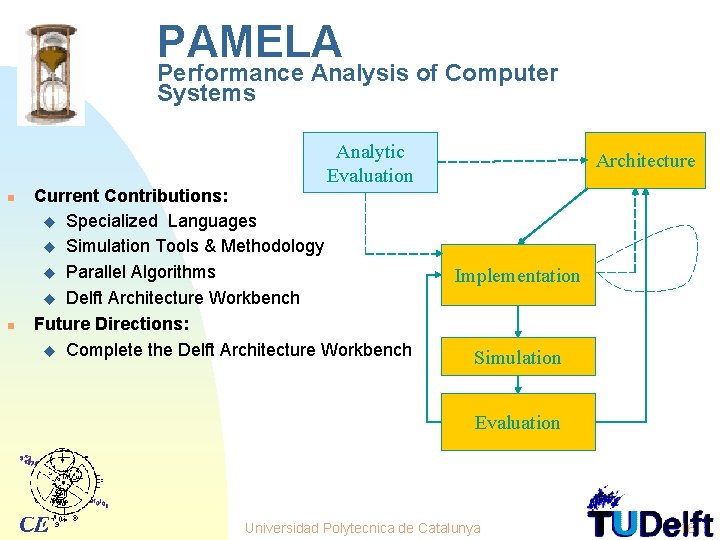
PAMELA Performance Analysis of Computer Systems Analytic Evaluation n n Current Contributions: u Specialized Languages u Simulation Tools & Methodology u Parallel Algorithms u Delft Architecture Workbench Future Directions: u Complete the Delft Architecture Workbench Architecture Implementation Simulation Evaluation Universidad Polytecnica de Catalunya 16
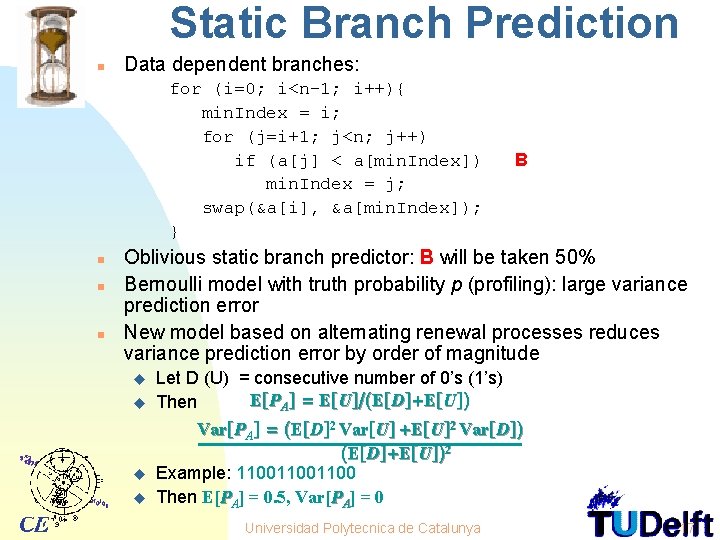
Static Branch Prediction n Data dependent branches: for (i=0; i<n-1; i++){ min. Index = i; for (j=i+1; j<n; j++) if (a[j] < a[min. Index]) min. Index = j; swap(&a[i], &a[min. Index]); } n n n B Oblivious static branch predictor: B will be taken 50% Bernoulli model with truth probability p (profiling): large variance prediction error New model based on alternating renewal processes reduces variance prediction error by order of magnitude u u Let D (U) = consecutive number of 0’s (1’s) E[PA] = E[U]/(E[D]+E[U]) Then Var[PA] = (E[D]2 Var[U] +E[U]2 Var[D]) (E[D]+E[U])2 Example: 11001100 Then E[PA] = 0. 5, Var[PA] = 0 Universidad Polytecnica de Catalunya 17
D-Iliad High Performance General Purpose Computers n Topics: u u n Current Contributions: u u n Uni & Multiprocessors Internet Processing Computer Design High Speed Switches Instruction level parallel machines (Superscalar, SCISM) New “Complex” Instructions New Designs of Arithmetic Processing New Switch Design Future Directions: u New Architectural paradigm Universidad Polytecnica de Catalunya 18
Complex Streamed Instructions n n See PACT’ 01, Euro. Par’ 01 Drawbacks of MMX-like extensions: u u n Multimedia (MM) register size architecturally visible and fixed. Ways out: F add MM FUs and increase issue width • expensive F increase MM register size • existing codes have to be recompile/rewritten • not beneficial due to small sub-matrices overhead for converting between packed data types and alignment Proposed solution: Complex Streamed Instructions (CSI) u u two-dimensional vector (stream) architecture, streams of arbitrary length stream is specified by set of stream control registers conversion between data types in hardware no loop control and address generation overhead Universidad Polytecnica de Catalunya 19
The Need for a Parallel Computation Model n n n Parallel computing has not been very successful One reason: lack of a standard parallel computation model Properties that a suitable parallel computation model should possess: u u u n Scalability Portability Predictability Model proposed by Valiant (1990) u Bulk-Synchronous Parallel (BSP) model Universidad Polytecnica de Catalunya 20
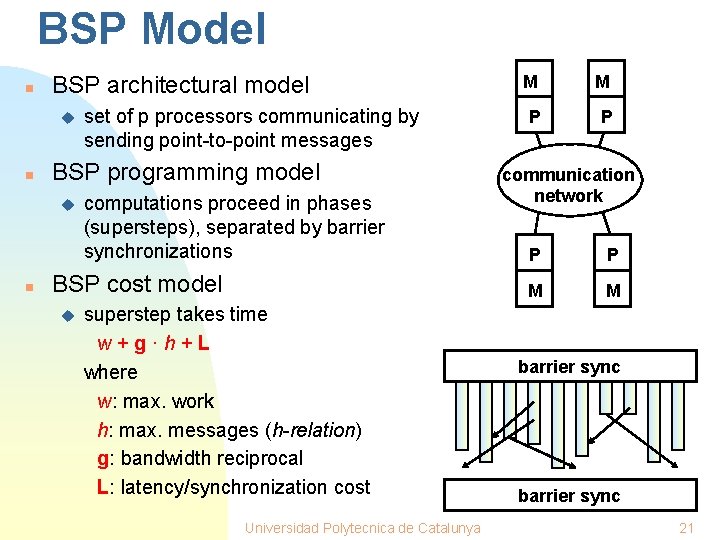
BSP Model n BSP architectural model u n BSP programming model u n set of p processors communicating by sending point-to-point messages computations proceed in phases (supersteps), separated by barrier synchronizations BSP cost model u superstep takes time w+g·h+L where w: max. work h: max. messages (h-relation) g: bandwidth reciprocal L: latency/synchronization cost Universidad Polytecnica de Catalunya M M P P communication network P P M M barrier sync 21
PUB Library n Paderborn University BSP (PUB) library (IPDPS’ 99) basics: u u u n SPMD no receive operation; barrier synchronization signifies end of all communication operations only non-blocking communication primitives buffered and unbuffered communication message is placed in buffer associated with destination processor from which it can be retrieved after the next barrier sync Additional features: u u u (non-blocking) collective communication primitives ability to partition the processors running different BSP computations on the same system (in different threads) Universidad Polytecnica de Catalunya 22
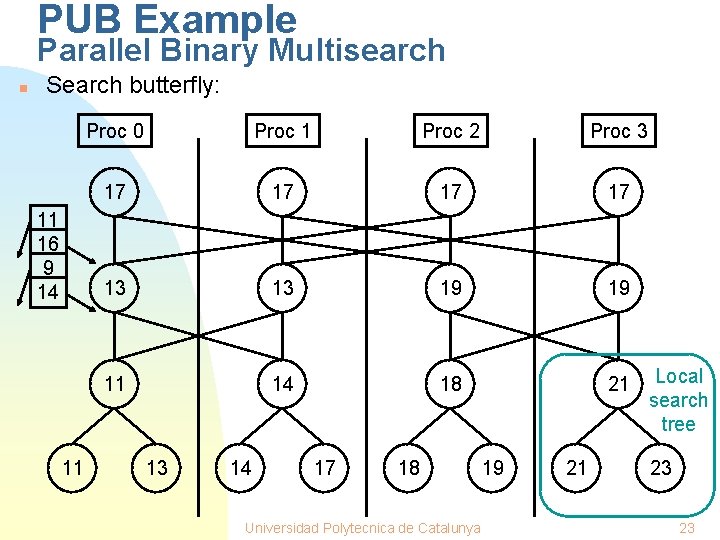
PUB Example Parallel Binary Multisearch n Search butterfly: 11 16 9 14 11 Proc 0 Proc 1 Proc 2 Proc 3 17 17 13 13 19 19 11 14 18 21 13 14 17 18 Universidad Polytecnica de Catalunya 19 21 Local search tree 23 23
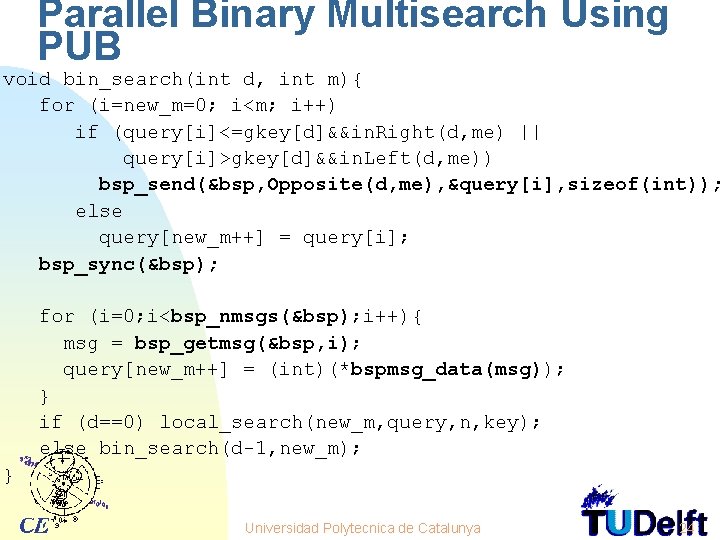
Parallel Binary Multisearch Using PUB void bin_search(int d, int m){ for (i=new_m=0; i<m; i++) if (query[i]<=gkey[d]&&in. Right(d, me) || query[i]>gkey[d]&&in. Left(d, me)) bsp_send(&bsp, Opposite(d, me), &query[i], sizeof(int)); else query[new_m++] = query[i]; bsp_sync(&bsp); for (i=0; i<bsp_nmsgs(&bsp); i++){ msg = bsp_getmsg(&bsp, i); query[new_m++] = (int)(*bspmsg_data(msg)); } if (d==0) local_search(new_m, query, n, key); else bin_search(d-1, new_m); } Universidad Polytecnica de Catalunya 24
Concluding Remarks n Not discussed: u u u u n testing ISA extensions for sparse matrix computations computer arithmetic usingle-electron technology reconfigurable processors network processors low power. . . For further information, please contact me (benj@ce. et. tudelft. nl) or see u u u ce. et. tudelft. nl/~benj www. upb. de/~pub Thank You Universidad Polytecnica de Catalunya 25
- Slides: 25