
RCF Status Extended outage of the Mass Storage
- Slides: 4
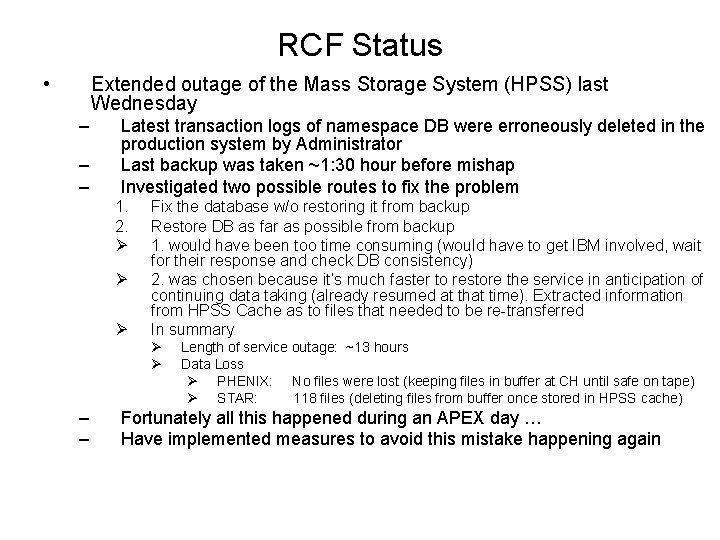
RCF Status • Extended outage of the Mass Storage System (HPSS) last Wednesday – – – Latest transaction logs of namespace DB were erroneously deleted in the production system by Administrator Last backup was taken ~1: 30 hour before mishap Investigated two possible routes to fix the problem 1. 2. Ø Ø Ø Fix the database w/o restoring it from backup Restore DB as far as possible from backup 1. would have been too time consuming (would have to get IBM involved, wait for their response and check DB consistency) 2. was chosen because it’s much faster to restore the service in anticipation of continuing data taking (already resumed at that time). Extracted information from HPSS Cache as to files that needed to be re-transferred In summary Ø Ø – – Length of service outage: ~13 hours Data Loss Ø PHENIX: No files were lost (keeping files in buffer at CH until safe on tape) Ø STAR: 118 files (deleting files from buffer once stored in HPSS cache) Fortunately all this happened during an APEX day … Have implemented measures to avoid this mistake happening again
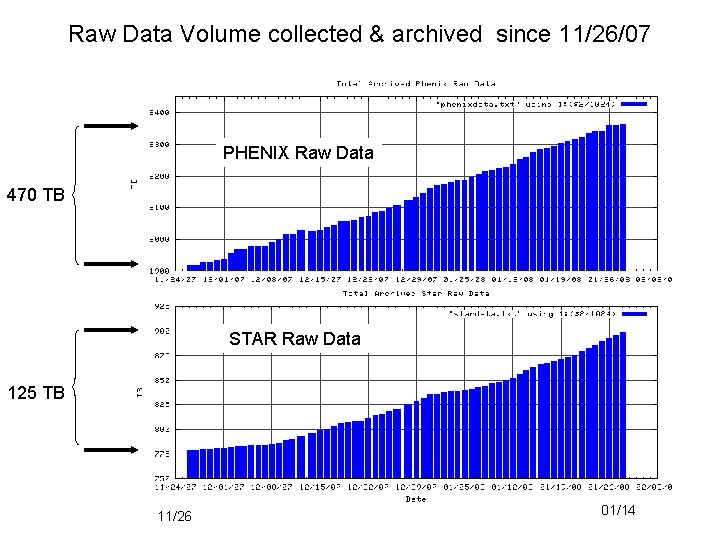
Raw Data Volume collected & archived since 11/26/07 PHENIX Raw Data 470 TB STAR Raw Data 125 TB 11/26 01/14
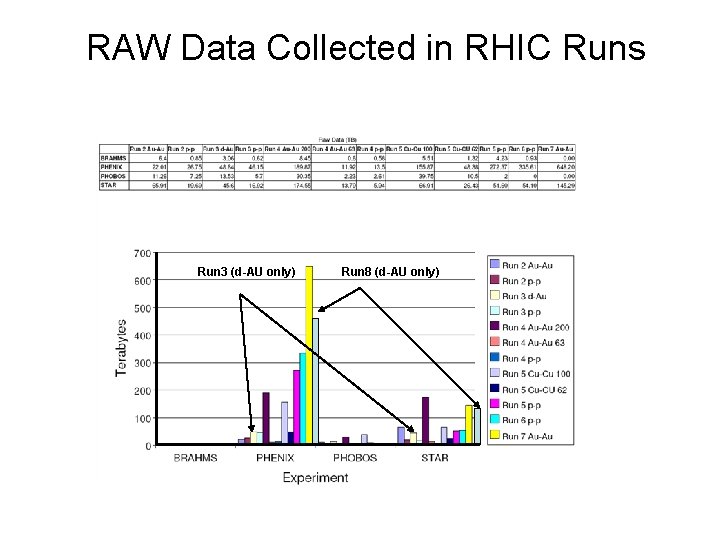
RAW Data Collected in RHIC Runs Run 3 (d-AU only) Run 8 (d-AU only)
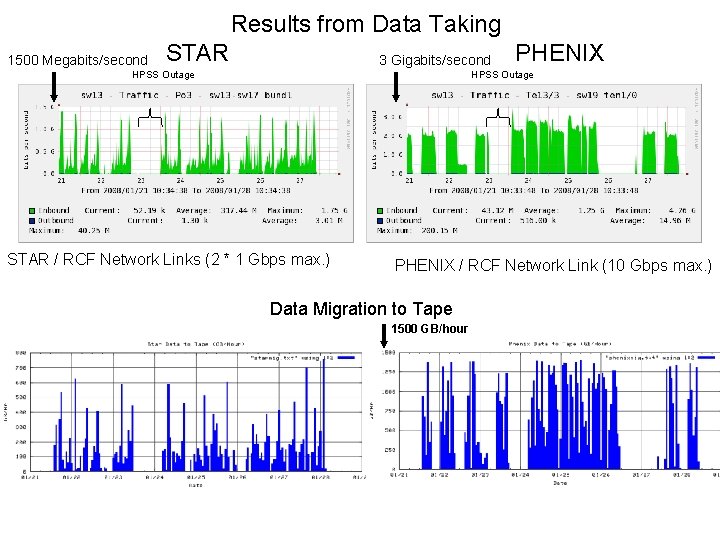
Results from Data Taking 1500 Megabits/second STAR 3 Gigabits/second PHENIX HPSS Outage 6, 000 GB STAR / RCF Network Links (2 * 1 Gbps max. ) PHENIX / RCF Network Link (10 Gbps max. ) Data Migration to Tape 1500 GB/hour