
Partitioned Interleaved Bloom Filter Using Optane DC Persistent
Partitioned Interleaved Bloom Filter Using Optane DC Persistent Memory Enrico Seiler, Freie Universität Berlin, Max Planck Institute for Molecular Genetics (Knut Reinert, Svenja Mehringer) IXPUG 2019
Next generation sequencing IXPUG 2019 Picture: Jonathan Bailey, NHGRI 2
Current genomic analysis IXPUG 2019 3
NGS applications Ch. IP-Seq IXPUG 2019 RNA-Seq 4
NGS applications Hi. C-Seq IXPUG 2019 Variation mapping 5
NGS applications Biallelic frequencies (cancer signatures) IXPUG 2019 Bisulphite mapping 6
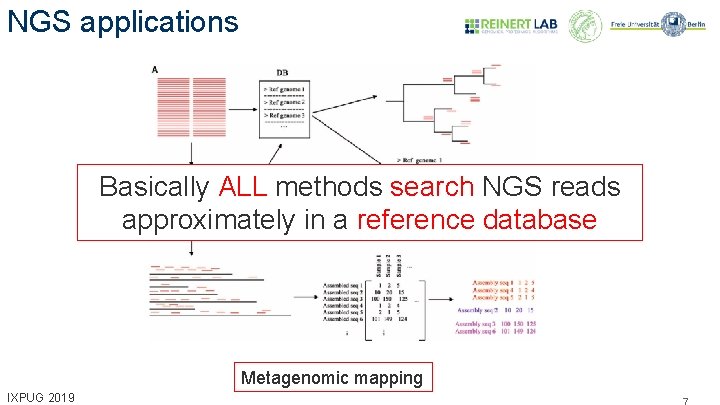
NGS applications Basically ALL methods search NGS reads approximately in a reference database Metagenomic mapping IXPUG 2019 7
Methods for searching There are two main approaches: A) Alignment based -> build compressed suffix array and map read ---- Data structure not dynamic, not practical to build for over 30 Gi. B B) Alignment free -> built k-mer lookup table and compare k-mer composition of reference and read ---- Also grows large for over 10 Gi. B and large k +++ Faster to build than CSA => Currently most approaches use k-mer based methods IXPUG 2019 8
Earth genome How many k-mers are there? IXPUG 2019 9
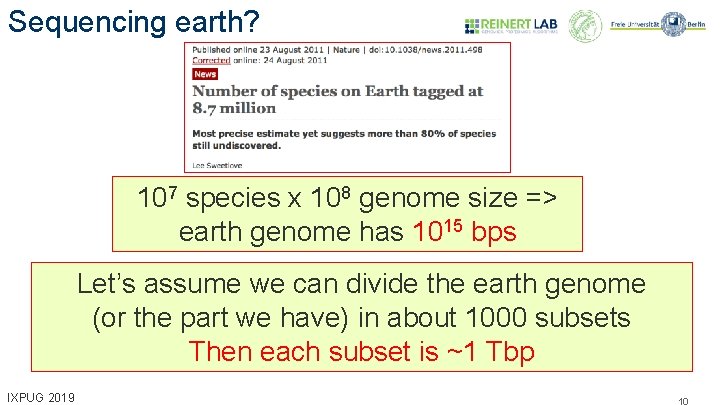
Sequencing earth? 107 species x 108 genome size => earth genome has 1015 bps Let’s assume we can divide the earth genome (or the part we have) in about 1000 subsets Then each subset is ~1 Tbp IXPUG 2019 10
Needs partitioning 1 Tbp of sequence contains too many different k-mers for k > 19 e. g. a 30 Gi. B metagenomics data set contains ~1010 different 19 -mers => We need to partition the sequence into bins IXPUG 2019 11
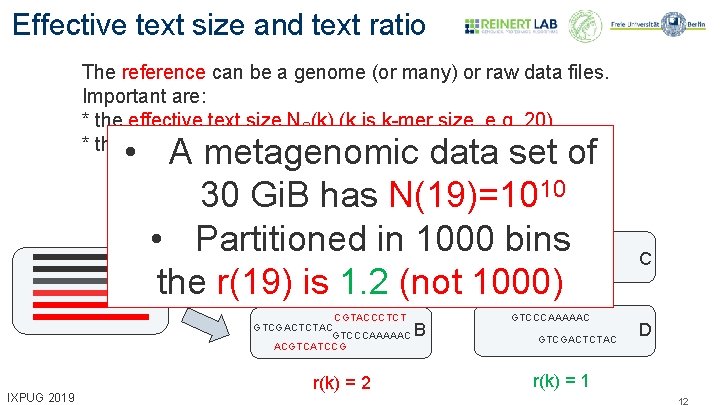
Effective text size and text ratio The reference can be a genome (or many) or raw data files. Important are: * the effective text size NS(k) (k is k-mer size, e. g. 20) * the effective text ratio of a partition of S (here in 2 bins): • A metagenomic data set of 30 Gi. B has N(19)=1010 • Partitioned in 1000 bins A Sthe r(19) is 1. 2 (not 1000) CGTACCCTCT GTCGACTCTAC ACGTCATCCG GTCCCAAAAAC CGTACCCTCT GTCGACTCTAC GTCCCAAAAAC ACGTCATCCG IXPUG 2019 r(k) = 2 ACGTCATCCG CGTACCCTCT B GTCCCAAAAAC GTCGACTCTAC C D r(k) = 1 12
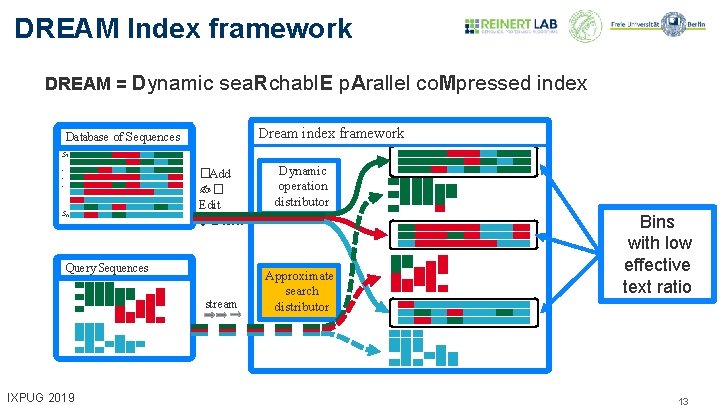
DREAM Index framework DREAM = Dynamic sea. Rchabl. E p. Arallel co. Mpressed index Dream index framework Database of Sequences S 1. . . . SN �Add ✍� Edit ✗Delete Query Sequences stream IXPUG 2019 Dynamic operation distributor Approximate search distributor Bins with low effective text ratio 13
Can we search a NGS read in a database of size 1 Ti. B partitioned into bins? IXPUG 2019 14
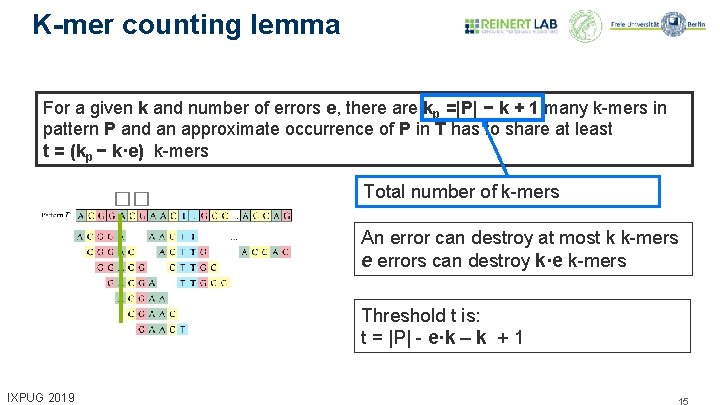
K-mer counting lemma For a given k and number of errors e, there are kp =|P| − k + 1 many k-mers in pattern P and an approximate occurrence of P in T has to share at least t = (kp − k·e) k-mers �� Total number of k-mers An error can destroy at most k k-mers e errors can destroy k·e k-mers Threshold t is: t = |P| - e·k – k + 1 IXPUG 2019 15
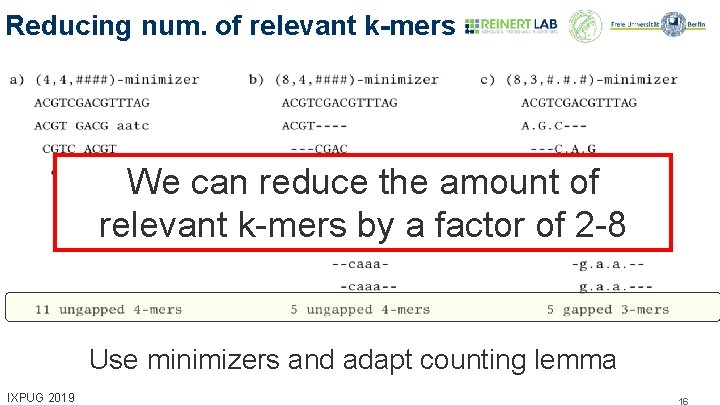
Reducing num. of relevant k-mers We can reduce the amount of relevant k-mers by a factor of 2 -8 Use minimizers and adapt counting lemma IXPUG 2019 16
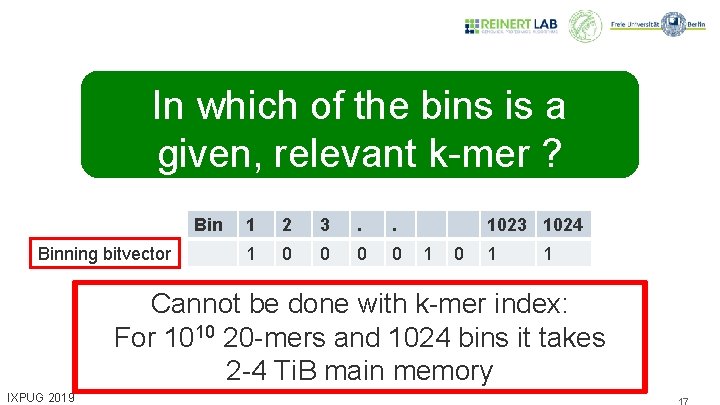
In which of the bins is a given, relevant k-mer ? Binning bitvector 1 2 3 . . 1 0 0 1023 1024 1 0 1 1 Cannot be done with k-mer index: For 1010 20 -mers and 1024 bins it takes 2 -4 Ti. B main memory IXPUG 2019 17
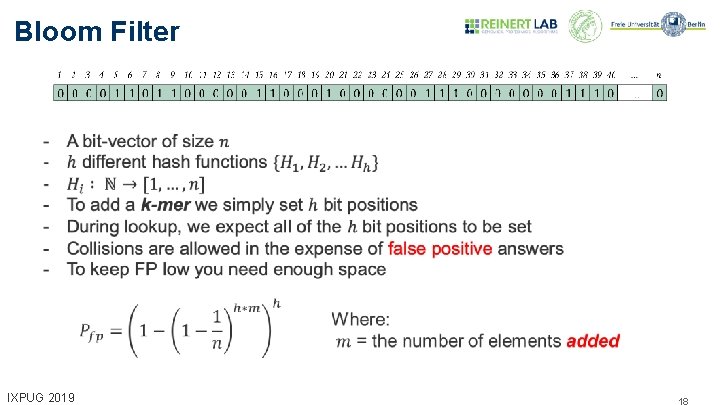
Bloom Filter IXPUG 2019 18
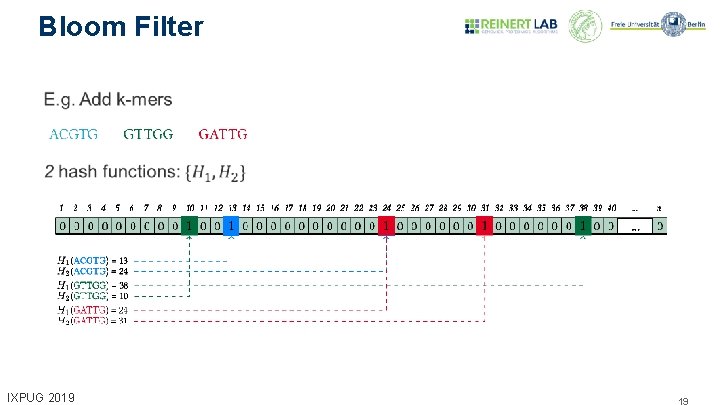
Bloom Filter IXPUG 2019 19
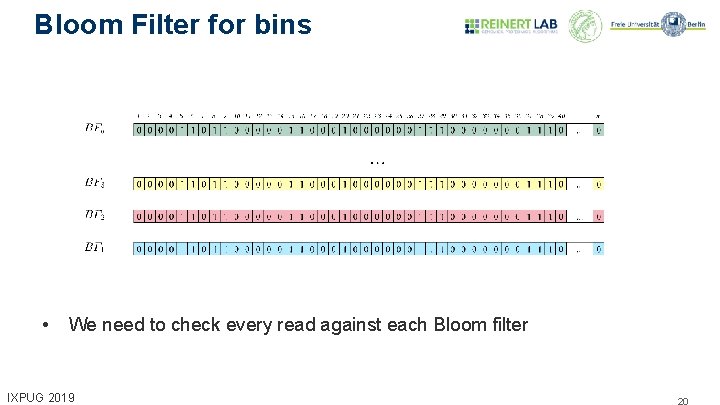
Bloom Filter for bins • We need to check every read against each Bloom filter IXPUG 2019 20
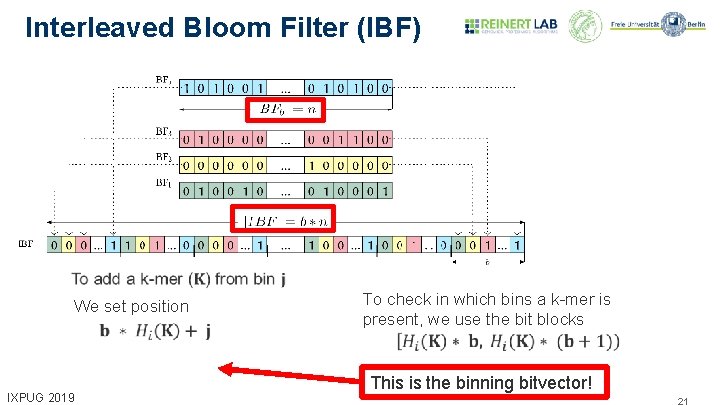
Interleaved Bloom Filter (IBF) We set position IXPUG 2019 To check in which bins a k-mer is present, we use the bit blocks This is the binning bitvector! 21
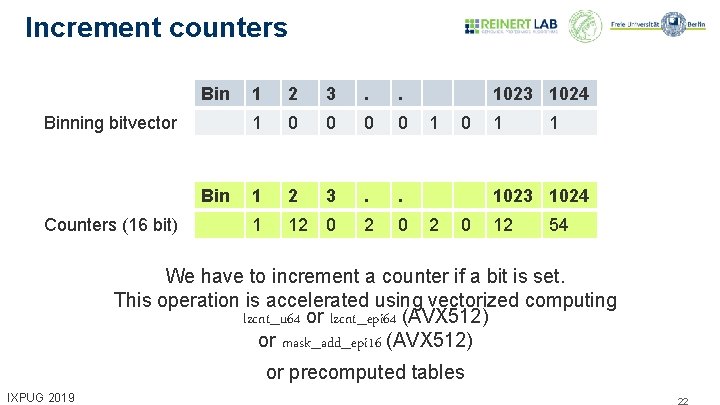
Increment counters Binning bitvector Bin Counters (16 bit) 1 2 3 . . 1 0 0 1 2 3 . . 1 12 0 1023 1024 1 0 1 1 1023 1024 2 0 12 54 We have to increment a counter if a bit is set. This operation is accelerated using vectorized computing lzcnt_u 64 or lzcnt_epi 64 (AVX 512) or mask_add_epi 16 (AVX 512) or precomputed tables IXPUG 2019 22
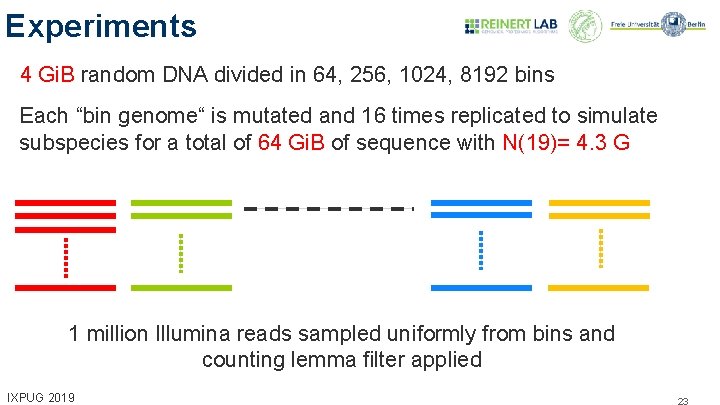
Experiments 4 Gi. B random DNA divided in 64, 256, 1024, 8192 bins Each “bin genome“ is mutated and 16 times replicated to simulate subspecies for a total of 64 Gi. B of sequence with N(19)= 4. 3 G 1 million Illumina reads sampled uniformly from bins and counting lemma filter applied IXPUG 2019 23
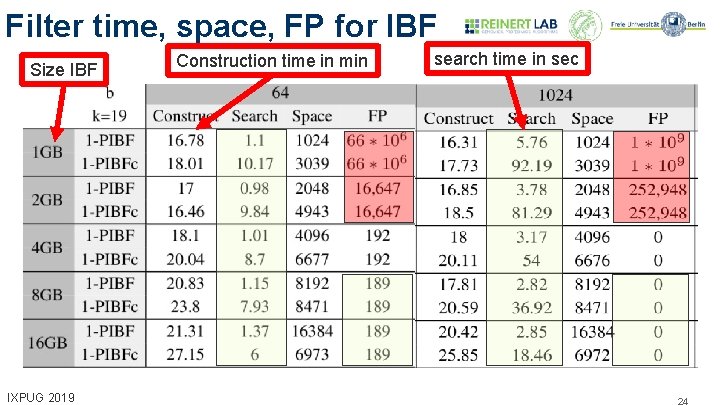
Filter time, space, FP for IBF Size IBF IXPUG 2019 Construction time in min search time in sec 24
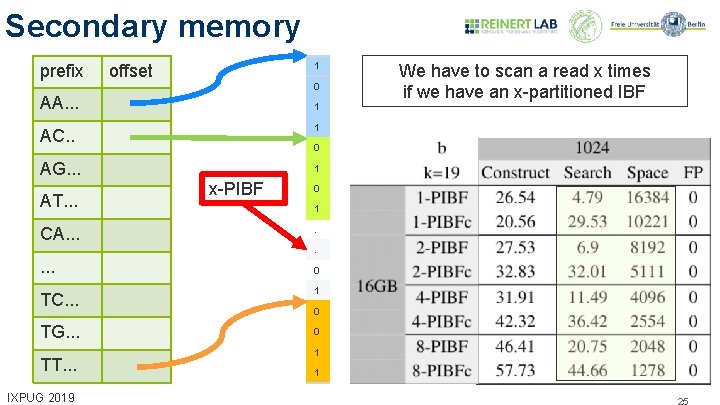
Secondary memory prefix 1 offset 0 AA. . . 1 AC. . 1 AG. . . 1 AT. . . 0 x-PIBF 0 1 CA. . . . 0 . TC. . . 1 TG. . . 0 TT. . . IXPUG 2019 We have to scan a read x times if we have an x-partitioned IBF 0 1 1 25
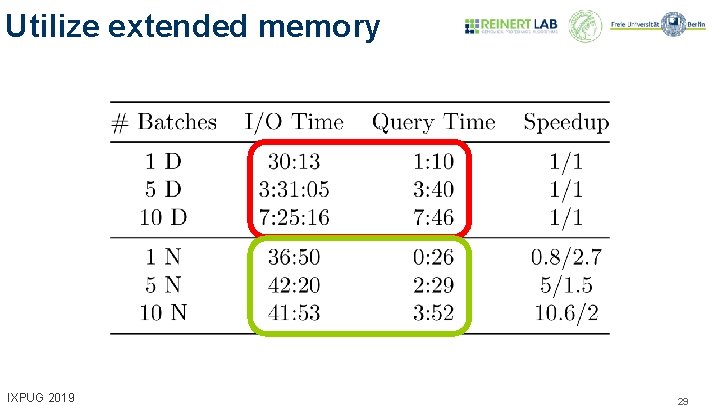
Intel Optane DC PMM 2 basic modes: - use as filesystem - use as memory extension 3 scenarios: - use as extended memory, but do not utilize - use as filesystem - use as extended memory, utilize Run times on an 1 Ti. B 8 -PIBF using a machine with Cascade Lake CPU with 96 threads, 192 Gi. B DRAM, 1. 5 Ti. B Optane NVRAM 1, 5 and 10 batches of 1 million Illumina reads IXPUG 2019 26
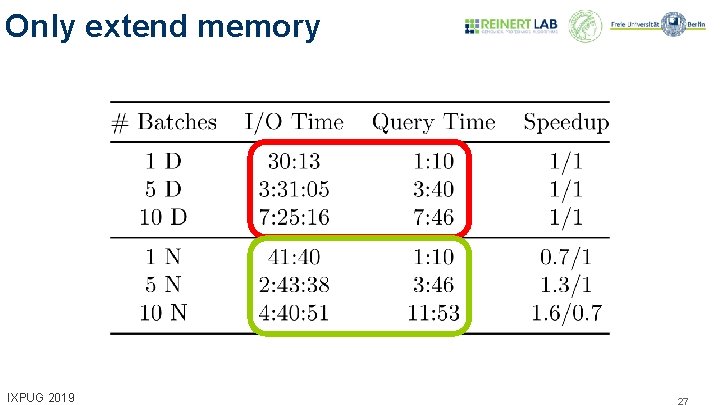
Only extend memory IXPUG 2019 27
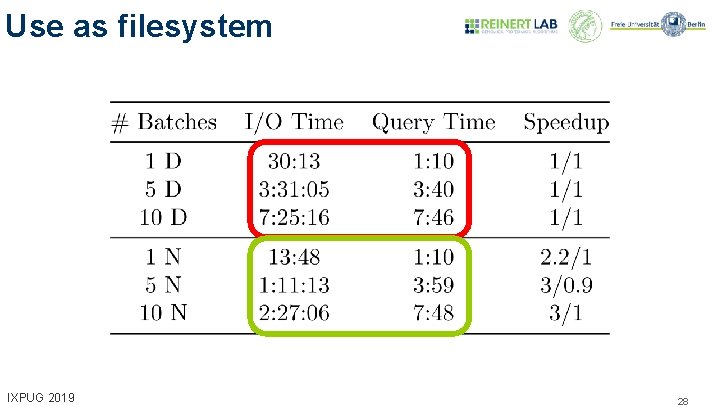
Use as filesystem IXPUG 2019 28
Utilize extended memory IXPUG 2019 29
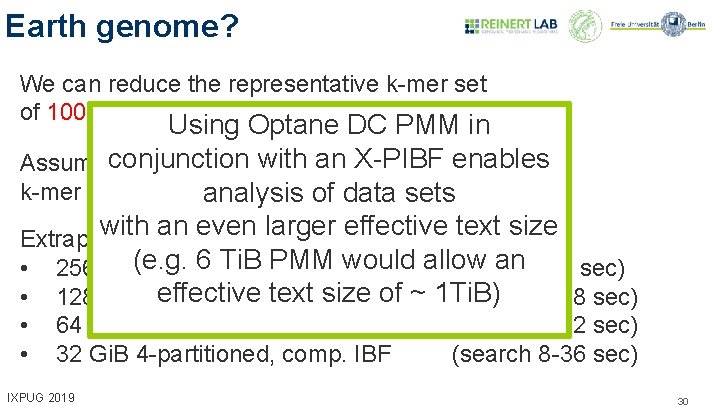
Earth genome? We can reduce the representative k-mer set of 1000 G to about 256 G using minimizers Using Optane DC PMM in conjunction with an X-PIBF enables Assume a factor of 4 redundance in k-mer content yielding 64 G effective text size analysis of data sets with an even larger effective text size Extrapolating our results (we had 4 G) we will need: (e. g. 6 Ti. B PMM would allow an • 256 Gi. B IBF (search 2 -3 sec) effective text size of ~ 1 Ti. B) • 128 Gi. B comp. IBF (search 9 -18 sec) • • 64 Gi. B 4 -partitioned IBF 32 Gi. B 4 -partitioned, comp. IBF IXPUG 2019 (search 4 -12 sec) (search 8 -36 sec) 30
• Please follow us under: • @Seq. An. Lib • www. seqan. de IXPUG 2019
- Slides: 31