
Overview of Spark project Presented by Yin Zhu
Overview of Spark project Presented by Yin Zhu (yinz@ust. hk) Materials from • http: //spark-project. org/documentation/ • Hadoop in Practice by A. Holmes • My demo code: https: //bitbucket. org/blackswift/spark-example 25 March 2013
Outline Review of Map. Reduce (15’) Going Through Spark (NSDI’ 12) Slides (30’) Demo (15’)
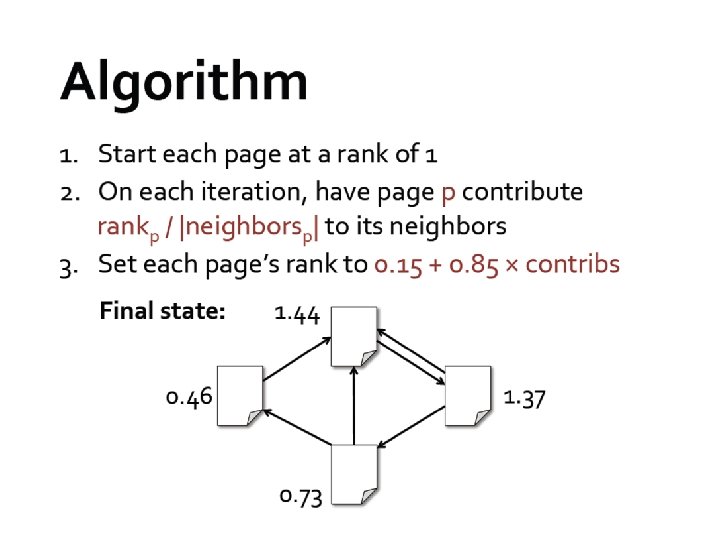
Review of Map. Reduce Pagerank implemented in Scala and Hadoop Why Pagerank? >More complicated than the “hello world” Word. Count >Widely used in search engines, very large scale input (the whole web graph!) >Iterative algorithm (typical style for most numerical algorithms for data mining)
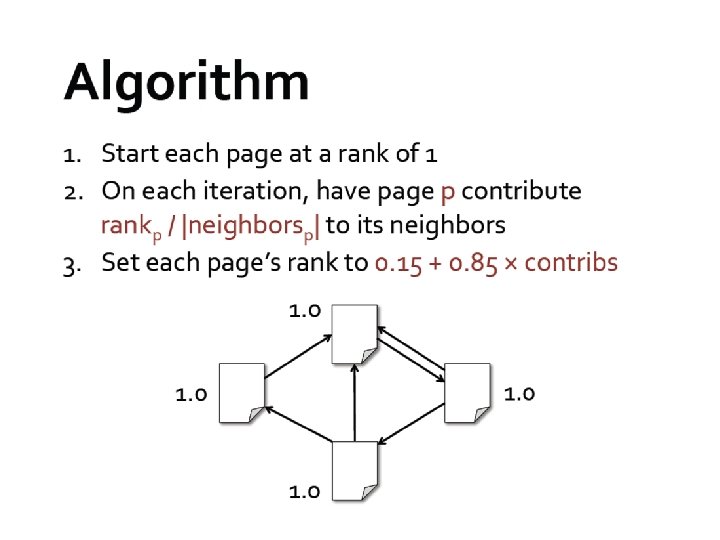
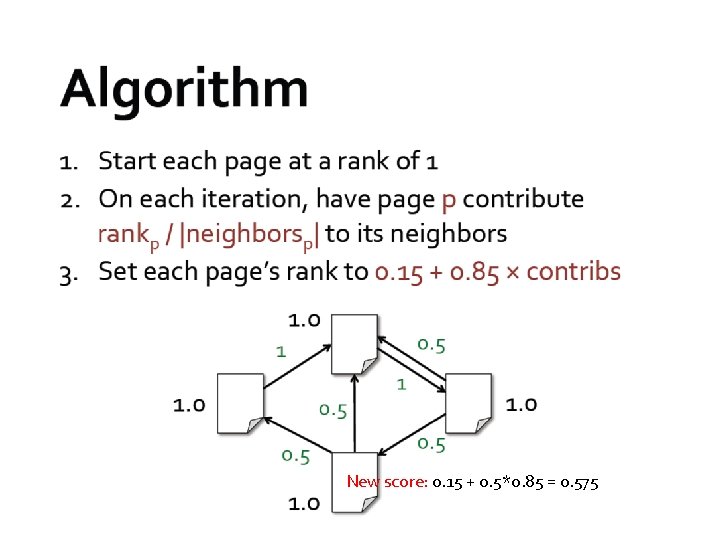
New score: 0. 15 + 0. 5*0. 85 = 0. 575
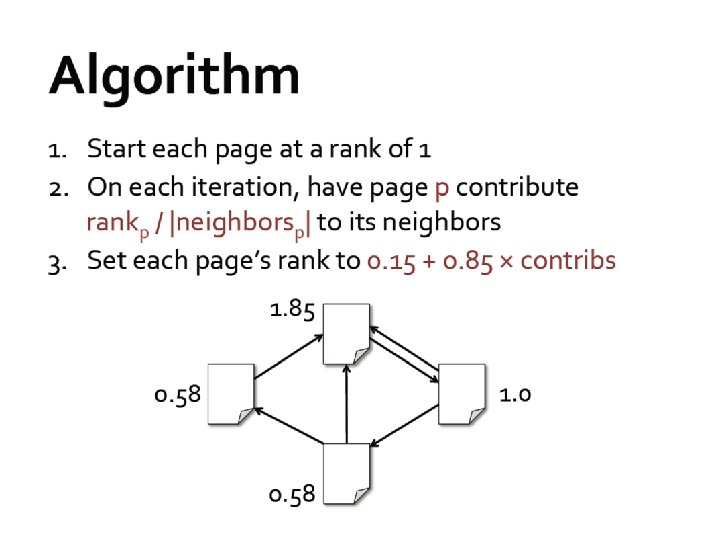
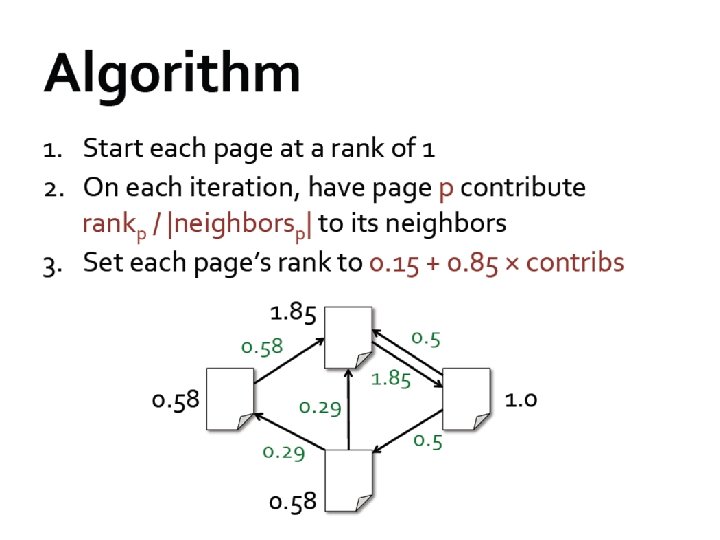
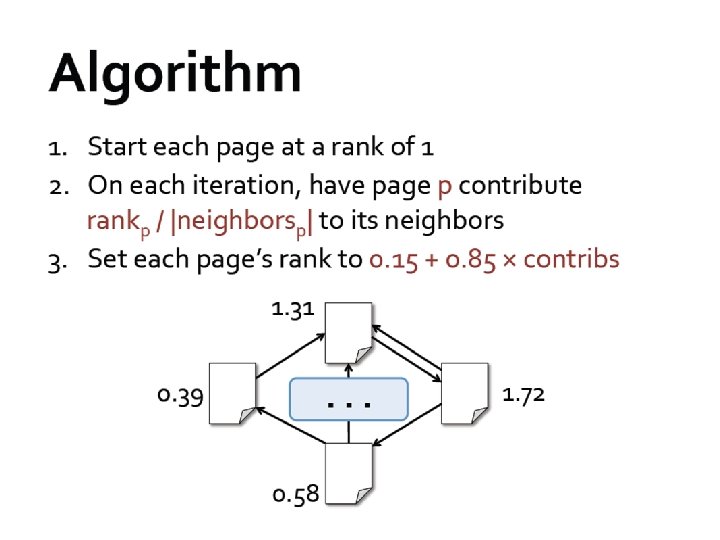
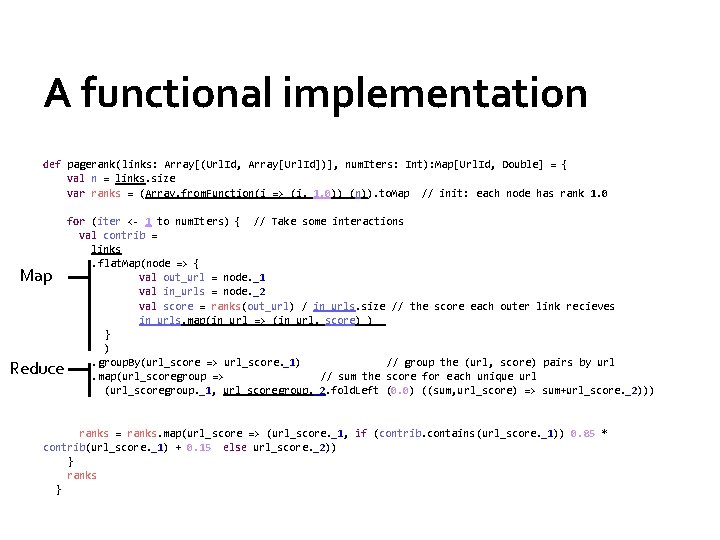
A functional implementation def pagerank(links: Array[(Url. Id, Array[Url. Id])], num. Iters: Int): Map[Url. Id, Double] = { val n = links. size var ranks = (Array. from. Function(i => (i, 1. 0)) (n)). to. Map // init: each node has rank 1. 0 for (iter <- 1 to num. Iters) { // Take some interactions val contrib = links . flat. Map(node => { val out_url = node. _1 val in_urls = node. _2 val score = ranks(out_url) / in_urls. size // the score each outer link recieves in_urls. map(in_url => (in_url, score) ) } ) . group. By(url_score => url_score. _1) // group the (url, score) pairs by url . map(url_scoregroup => // sum the score for each unique url (url_scoregroup. _1, url_scoregroup. _2. fold. Left (0. 0) ((sum, url_score) => sum+url_score. _2))) ranks = ranks. map(url_score => (url_score. _1, if (contrib. contains(url_score. _1)) 0. 85 * contrib(url_score. _1) + 0. 15 else url_score. _2)) } ranks } Map Reduce
Hadoop implementation https: //github. com/alexholmes/hadoopbook/tree/master/src/main/java/com/manning/h ip/ch 7/pagerank
Hadoop/Map. Reduce implementation Fault tolerance the result after each iteration is saved to Disk Speed/Disk IO disk IO is proportional to the # of iterations ideally the link graph should be loaded for only once
Resilient Distributed Datasets A Fault-Tolerant Abstraction for In-Memory Cluster Computing Matei Zaharia, Mosharaf Chowdhury, Tathagata Das, Ankur Dave, Justin Ma, Murphy Mc. Cauley, Michael Franklin, Scott Shenker, Ion Stoica UC Berkeley UC BERKELEY
Motivation Map. Reduce greatly simplified “big data” analysis on large, unreliable clusters But as soon as it got popular, users wanted more: » More complex, multi-stage applications (e. g. iterative machine learning & graph processing) » More interactive ad-hoc queries Response: specialized frameworks for some of these apps (e. g. Pregel for graph processing)
Motivation Complex apps and interactive queries both need one thing that Map. Reduce lacks: Efficient primitives for data sharing In Map. Reduce, the only way to share data across jobs is stable storage slow!
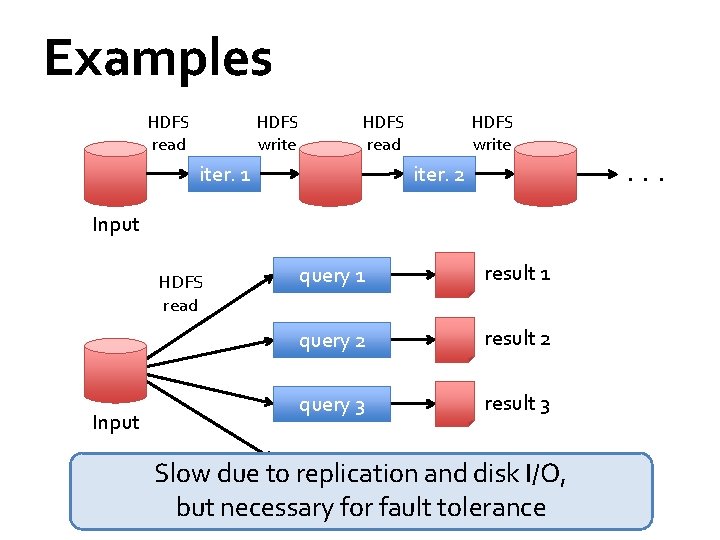
Examples HDFS read HDFS write HDFS read iter. 1 HDFS write . . . iter. 2 Input HDFS read Input query 1 result 1 query 2 result 2 query 3 result 3 . . . Slow due to replication and disk I/O, but necessary for fault tolerance
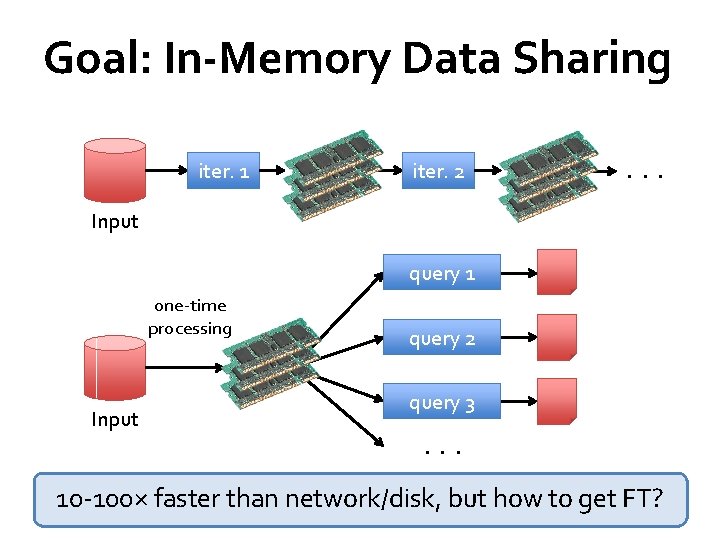
Goal: In-Memory Data Sharing iter. 1 iter. 2 . . . Input query 1 one-time processing Input query 2 query 3. . . 10 -100× faster than network/disk, but how to get FT?
Challenge How to design a distributed memory abstraction that is both fault-tolerant and efficient?
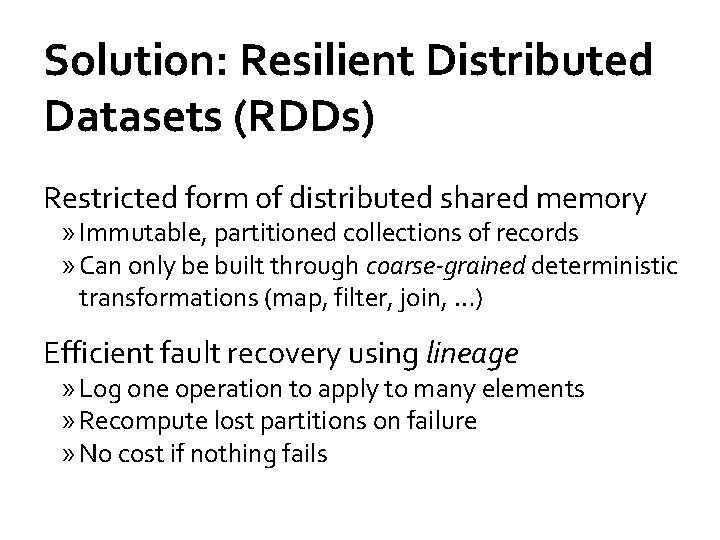
Solution: Resilient Distributed Datasets (RDDs) Restricted form of distributed shared memory » Immutable, partitioned collections of records » Can only be built through coarse-grained deterministic transformations (map, filter, join, …) Efficient fault recovery using lineage » Log one operation to apply to many elements » Recompute lost partitions on failure » No cost if nothing fails
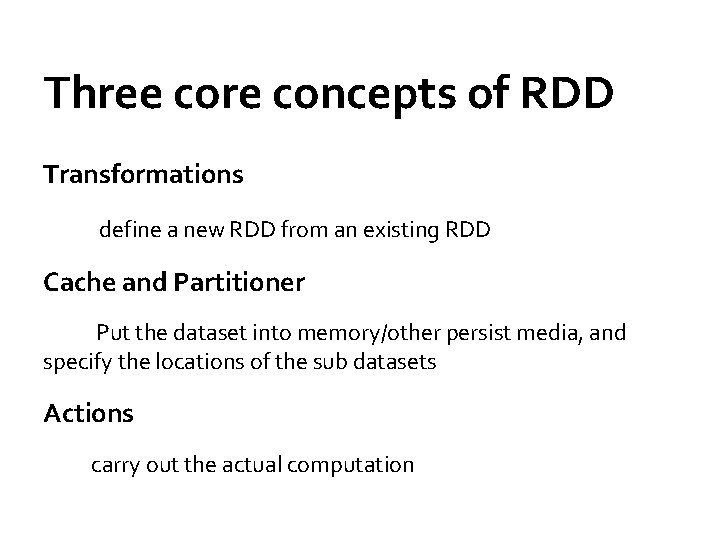
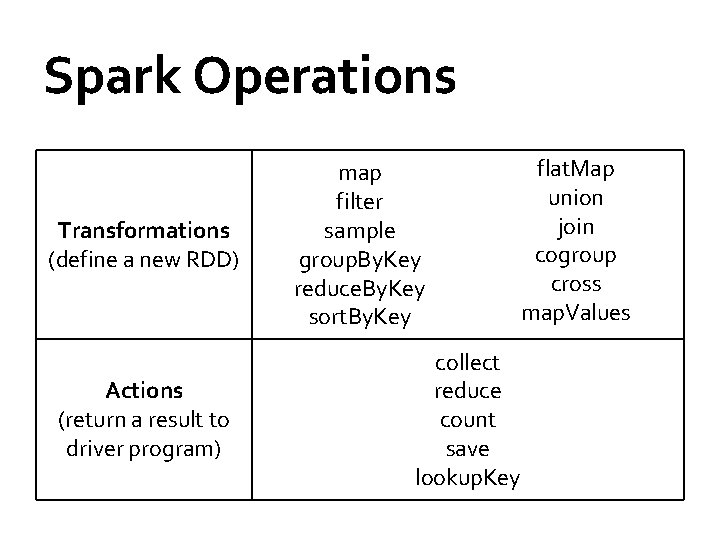
Three core concepts of RDD Transformations define a new RDD from an existing RDD Cache and Partitioner Put the dataset into memory/other persist media, and specify the locations of the sub datasets Actions carry out the actual computation
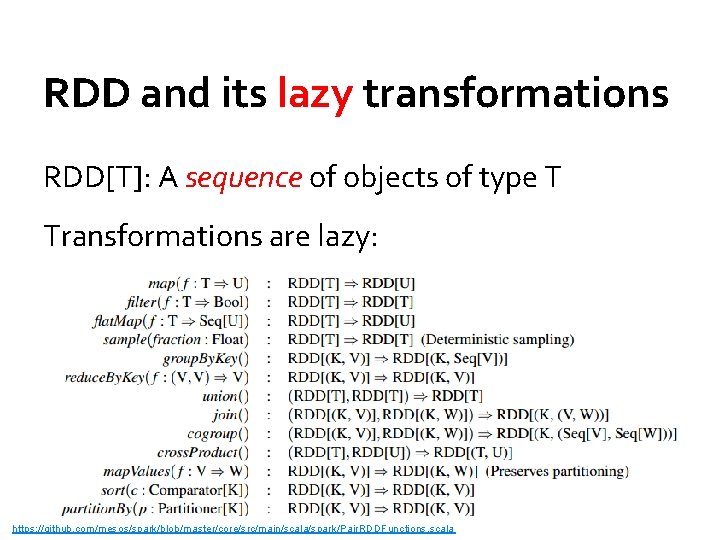
RDD and its lazy transformations RDD[T]: A sequence of objects of type T Transformations are lazy: https: //github. com/mesos/spark/blob/master/core/src/main/scala/spark/Pair. RDDFunctions. scala
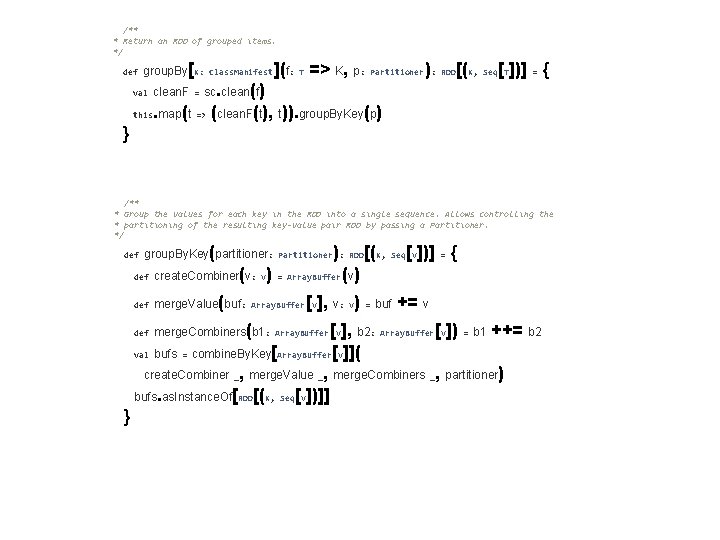
/** * Return an RDD of grouped items. */ [ def group. By K: Class. Manifest ](f: T => K, p: Partitioner ): RDD[(K, Seq[T])] = { . clean(f) this. map(t => (clean. F(t), t)). group. By. Key(p) } val clean. F = sc /** * Group the values for each key in the RDD into a single sequence. Allows controlling the * partitioning of the resulting key-value pair RDD by passing a Partitioner. */ (partitioner: Partitioner ): RDD[(K, Seq[V])] = { def create. Combiner(v: V) = Array. Buffer (v) def group. By. Key (buf: Array. Buffer [V], v: V) = buf += v def merge. Value (b 1: Array. Buffer [V], b 2: Array. Buffer [V]) = b 1 ++= b 2 val bufs = combine. By. Key[Array. Buffer [V]]( create. Combiner _, merge. Value _, merge. Combiners _, partitioner) bufs. as. Instance. Of[RDD[(K, Seq[V])]] } def merge. Combiners
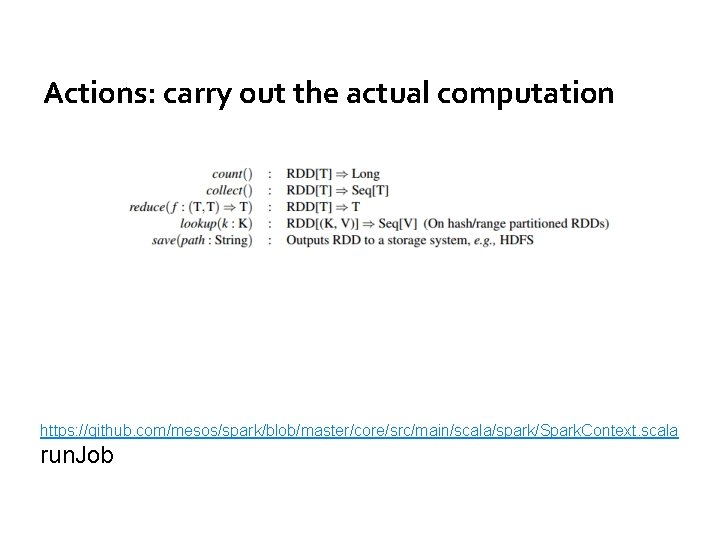
Actions: carry out the actual computation https: //github. com/mesos/spark/blob/master/core/src/main/scala/spark/Spark. Context. scala run. Job
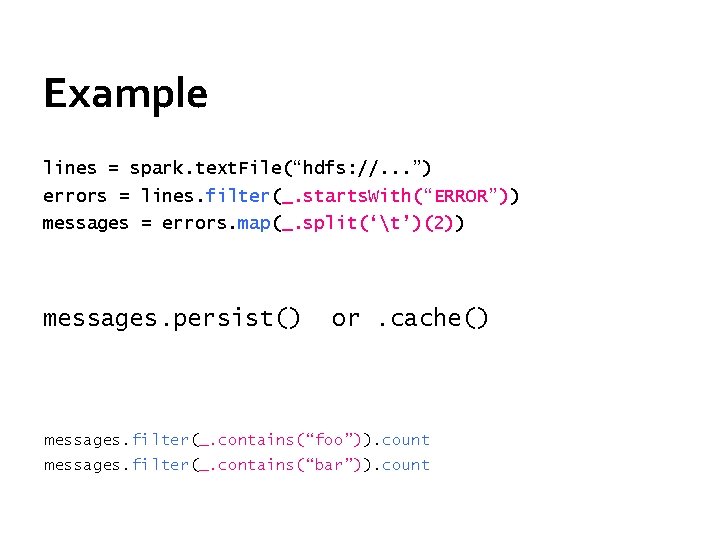
Example lines = spark. text. File(“hdfs: //. . . ”) errors = lines. filter(_. starts. With(“ERROR”)) messages = errors. map(_. split(‘t’)(2)) messages. persist() or. cache() messages. filter(_. contains(“foo”)). count messages. filter(_. contains(“bar”)). count
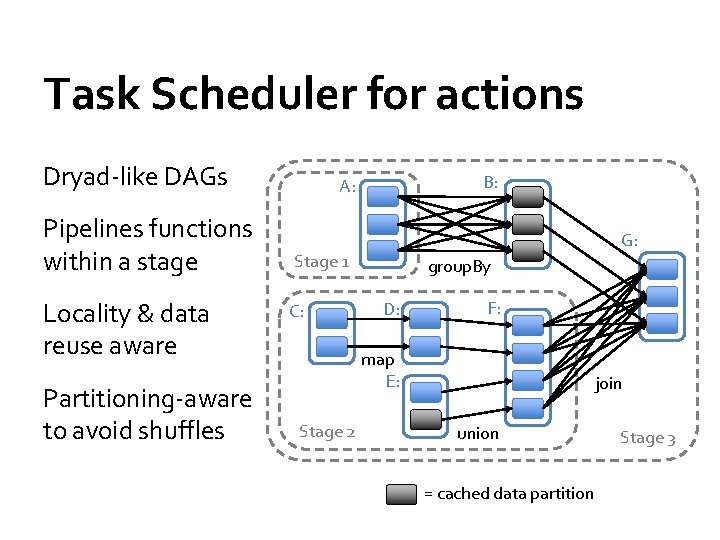
Task Scheduler for actions Dryad-like DAGs Pipelines functions within a stage Locality & data reuse aware Partitioning-aware to avoid shuffles B: A: G: Stage 1 C: group. By D: F: map E: Stage 2 join union = cached data partition Stage 3
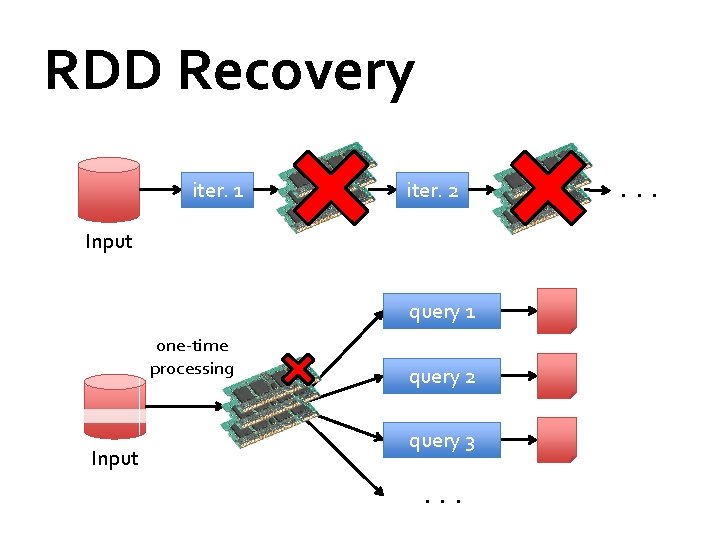
RDD Recovery iter. 1 iter. 2 Input query 1 one-time processing Input query 2 query 3. . .
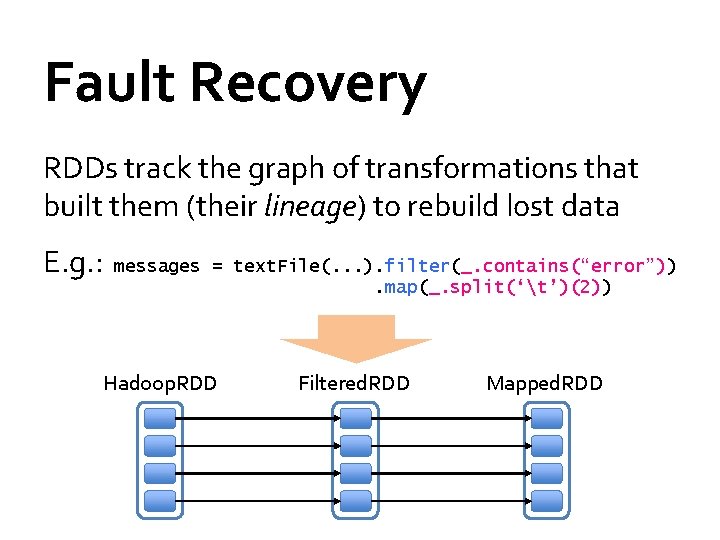
Fault Recovery RDDs track the graph of transformations that built them (their lineage) to rebuild lost data E. g. : messages = text. File(. . . ). filter(_. contains(“error”)). map(_. split(‘t’)(2)) Hadoop. RDD Filtered. RDD path = hdfs: //… func = _. contains(. . . ) Mapped. RDD func = _. split(…)
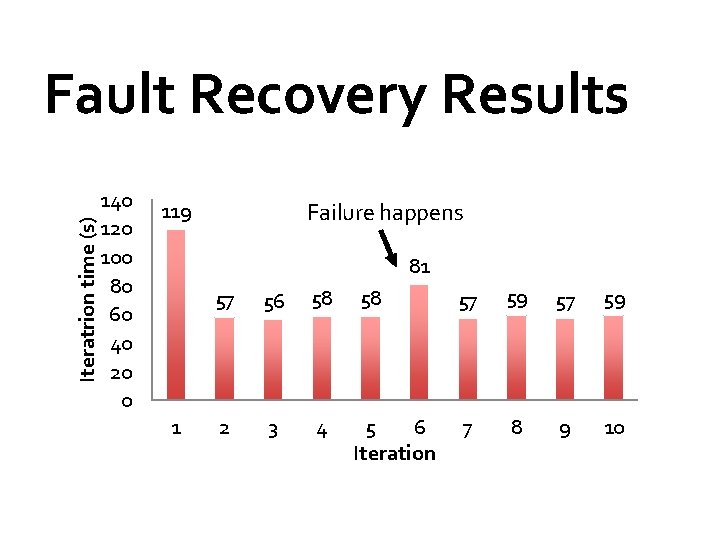
Iteratrion time (s) Fault Recovery Results 140 120 100 80 60 40 20 0 119 Failure happens 81 1 57 56 58 58 57 59 2 3 4 5 6 Iteration 7 8 9 10
Generality of RDDs Despite their restrictions, RDDs can express surprisingly many parallel algorithms » These naturally apply the same operation to many items Unify many current programming models » Data flow models: Map. Reduce, Dryad, SQL, … » Specialized models for iterative apps: BSP (Pregel), iterative Map. Reduce (Haloop), bulk incremental, … Support new apps that these models don’t
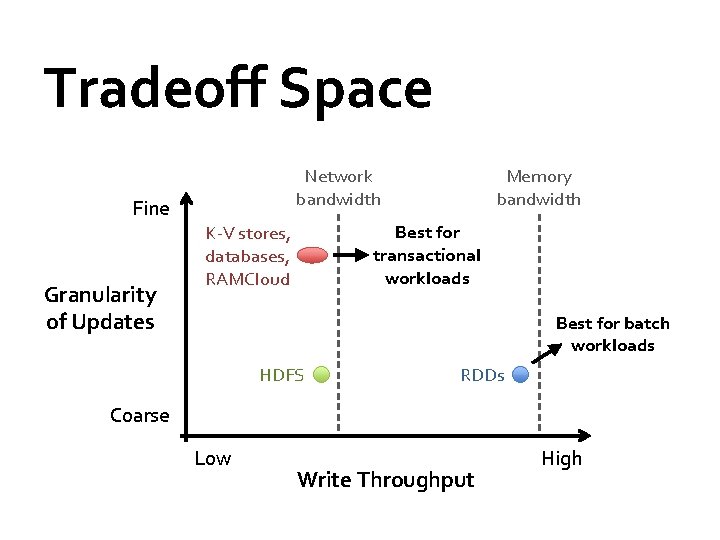
Tradeoff Space Fine Granularity of Updates Network bandwidth Memory bandwidth Best for transactional workloads K-V stores, databases, RAMCloud Best for batch workloads HDFS RDDs Coarse Low Write Throughput High
Outline Spark programming interface Implementation Demo How people are using Spark
Spark Programming Interface Dryad. LINQ-like API in the Scala language Usable interactively from Scala interpreter Provides: » Resilient distributed datasets (RDDs) » Operations on RDDs: transformations (build new RDDs), actions (compute and output results) » Control of each RDD’s partitioning (layout across nodes) and persistence (storage in RAM, on disk, etc)
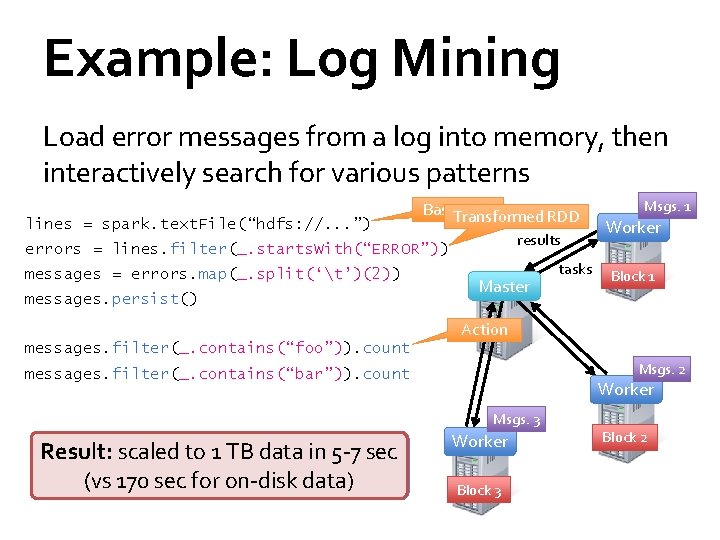
Example: Log Mining Load error messages from a log into memory, then interactively search for various patterns lines = spark. text. File(“hdfs: //. . . ”) Base. Transformed RDD results errors = lines. filter(_. starts. With(“ERROR”)) messages = errors. map(_. split(‘t’)(2)) messages. persist() Master tasks Msgs. 1 Worker Block 1 Action messages. filter(_. contains(“foo”)). count Msgs. 2 messages. filter(_. contains(“bar”)). count Worker Msgs. 3 full-text of Wikipedia Result: scaled tosearch 1 TB data in 5 -7 sec in <1(vs sec 170 (vssec 20 for secon-disk for on-disk data) Worker Block 3 Block 2
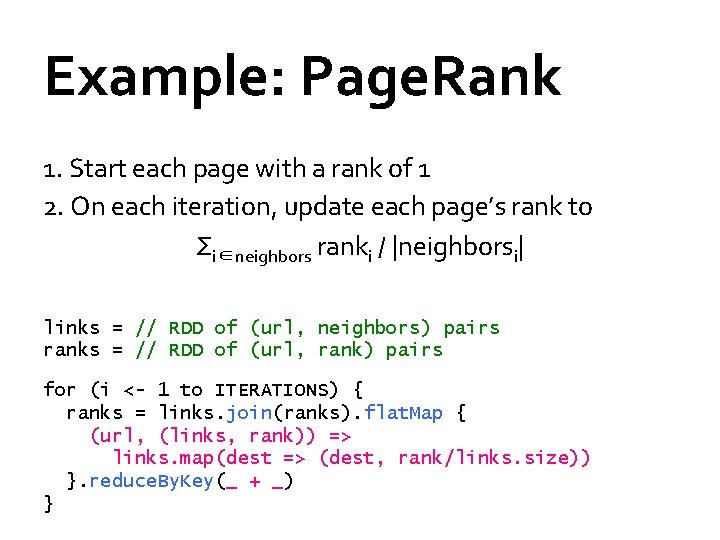
Example: Page. Rank 1. Start each page with a rank of 1 2. On each iteration, update each page’s rank to Σi∈neighbors ranki / |neighborsi| links = // RDD of (url, neighbors) pairs ranks = // RDD of (url, rank) pairs for (i <- 1 to ITERATIONS) { ranks = links. join(ranks). flat. Map { (url, (links, rank)) => links. map(dest => (dest, rank/links. size)) }. reduce. By. Key(_ + _) }
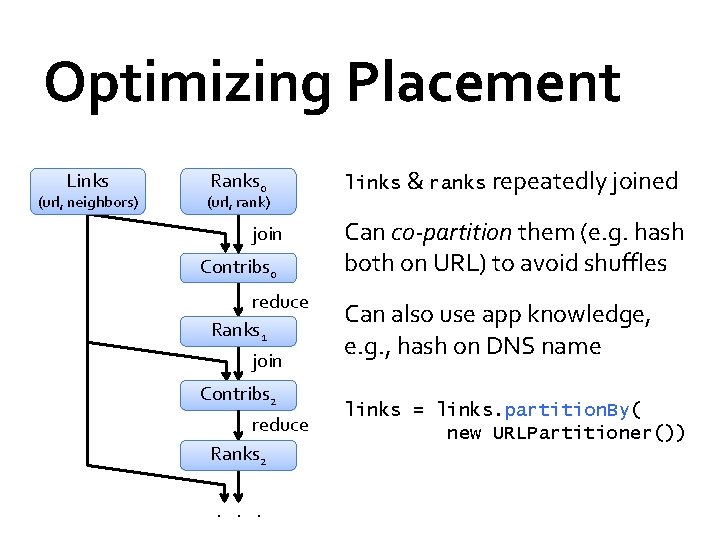
Optimizing Placement Links (url, neighbors) Ranks 0 (url, rank) join Contribs 0 reduce Ranks 1 join Contribs 2 reduce Ranks 2 . . . links & ranks repeatedly joined Can co-partition them (e. g. hash both on URL) to avoid shuffles Can also use app knowledge, e. g. , hash on DNS name links = links. partition. By( new URLPartitioner())
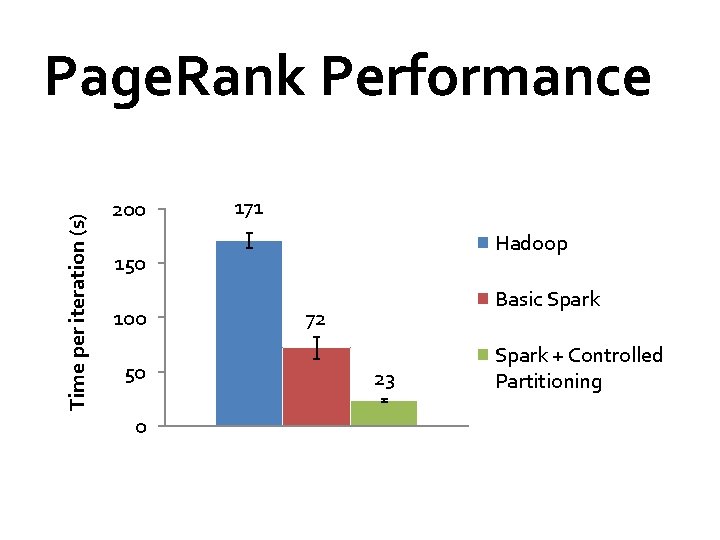
Time per iteration (s) Page. Rank Performance 200 171 Hadoop 150 100 50 0 Basic Spark 72 23 Spark + Controlled Partitioning
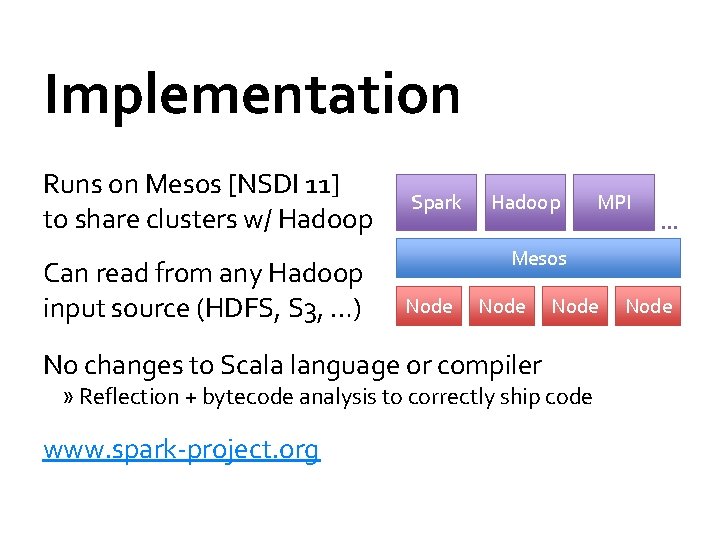
Implementation Runs on Mesos [NSDI 11] to share clusters w/ Hadoop Can read from any Hadoop input source (HDFS, S 3, …) Spark Hadoop … Mesos Node No changes to Scala language or compiler Node » Reflection + bytecode analysis to correctly ship code www. spark-project. org MPI Node
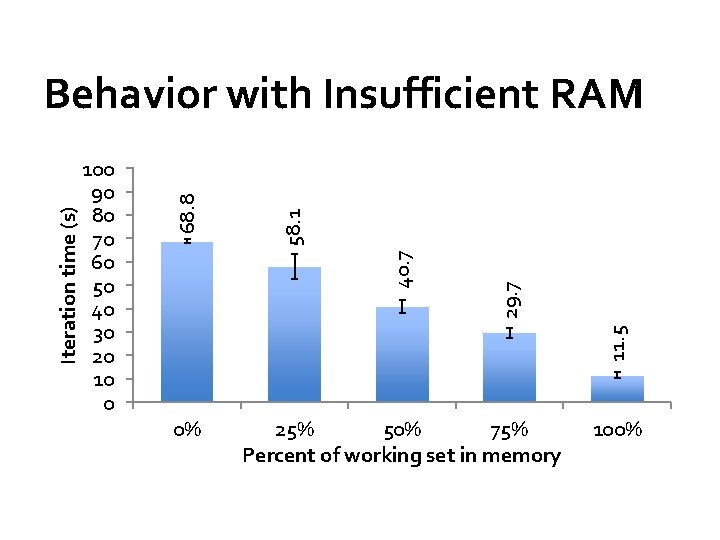
11. 5 29. 7 40. 7 58. 1 100 90 80 70 60 50 40 30 20 10 0 68. 8 Iteration time (s) Behavior with Insufficient RAM 0% 25% 50% 75% Percent of working set in memory 100%
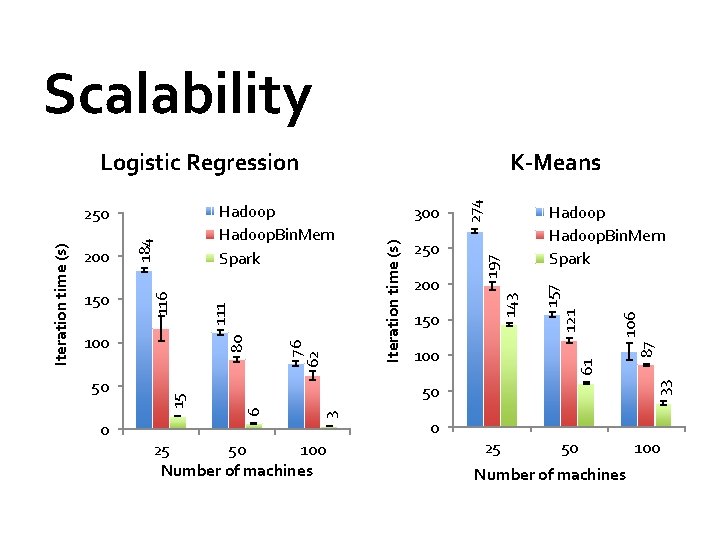
Scalability 87 106 121 150 Hadoop. Bin. Mem Spark 157 200 143 250 197 100 61 Iteration time (s) 300 6 25 50 100 Number of machines 0 33 50 3 0 15 50 80 100 76 62 116 184 Iteration time (s) 150 111 Hadoop. Bin. Mem Spark 250 200 K-Means 274 Logistic Regression 25 50 Number of machines 100
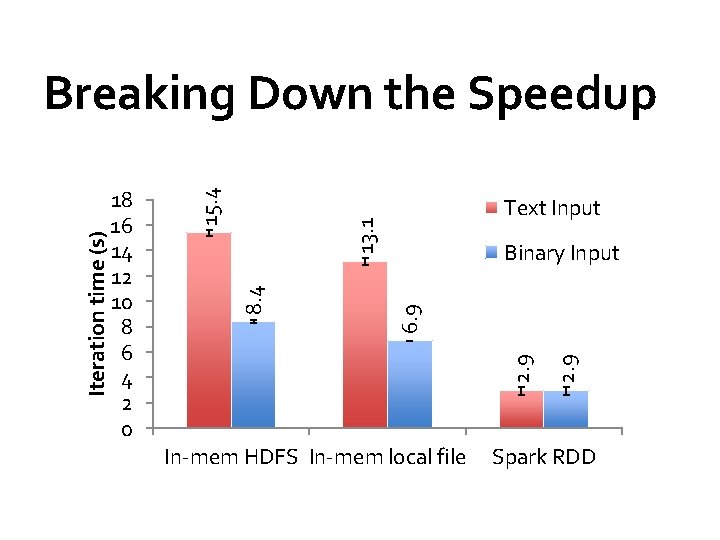
Text Input 13. 1 2. 9 6. 9 Binary Input In-mem HDFS In-mem local file 2. 9 15. 4 18 16 14 12 10 8 6 4 2 0 8. 4 Iteration time (s) Breaking Down the Speedup Spark RDD
Spark Operations Transformations (define a new RDD) Actions (return a result to driver program) map filter sample group. By. Key reduce. By. Key sort. By. Key flat. Map union join cogroup cross map. Values collect reduce count save lookup. Key
Demo
Open Source Community 15 contributors, 5+ companies using Spark, 3+ applications projects at Berkeley User applications: » Data mining 40 x faster than Hadoop (Conviva) » Exploratory log analysis (Foursquare) » Traffic prediction via EM (Mobile Millennium) » Twitter spam classification (Monarch) » DNA sequence analysis (SNAP) » . . .
Related Work RAMCloud, Piccolo, Graph. Lab, parallel DBs » Fine-grained writes requiring replication for resilience Pregel, iterative Map. Reduce » Specialized models; can’t run arbitrary / ad-hoc queries Dryad. LINQ, Flume. Java » Language-integrated “distributed dataset” API, but cannot share datasets efficiently across queries Nectar [OSDI 10] » Automatic expression caching, but over distributed FS Pac. Man [NSDI 12] » Memory cache for HDFS, but writes still go to network/disk
Conclusion RDDs offer a simple and efficient programming model for a broad range of applications Leverage the coarse-grained nature of many parallel algorithms for low-overhead recovery Try it out at www. spark-project. org
- Slides: 45