
OSP 324 Microsoft Office 365 Service Reliability and
OSP 324 Microsoft Office 365 Service Reliability and Disaster Recovery Kumar Venkateswar, Sr. Program Manager Microsoft Corporation
Agenda What is the uptime in Office 365? Why is it good? What does Microsoft do to make sure it is? How do these numbers translate into my organization? What happens when I have an outage? How does our approach differ from our competitors? What’s next? How does Microsoft make sure it keeps getting better?
What is the uptime in Office 365? Why is it good? What does Microsoft do to make sure it is? How do these numbers translate into my organization? What happens when I have an outage? How does our approach differ from our competitors? What’s next? How does Microsoft make sure it keeps getting better?
6
What is the uptime in Office 365? Why is it good? What does Microsoft do to make sure it is? How do these numbers translate into my organization? What happens when I have an outage? How does our approach differ from our competitors? What’s next? How does Microsoft make sure it keeps getting better?

2005 Exchange Hosted Services (now part of Office 365) 2002 Xbox Live 1998 1997 Hotmail 1995 Windows Update 8 Bing / MSN search
Offers the most resilient and predictable service availability experience for the cloud. Backed by the most responsive support available and a comprehensive 99. 9% financially backed SLA 9
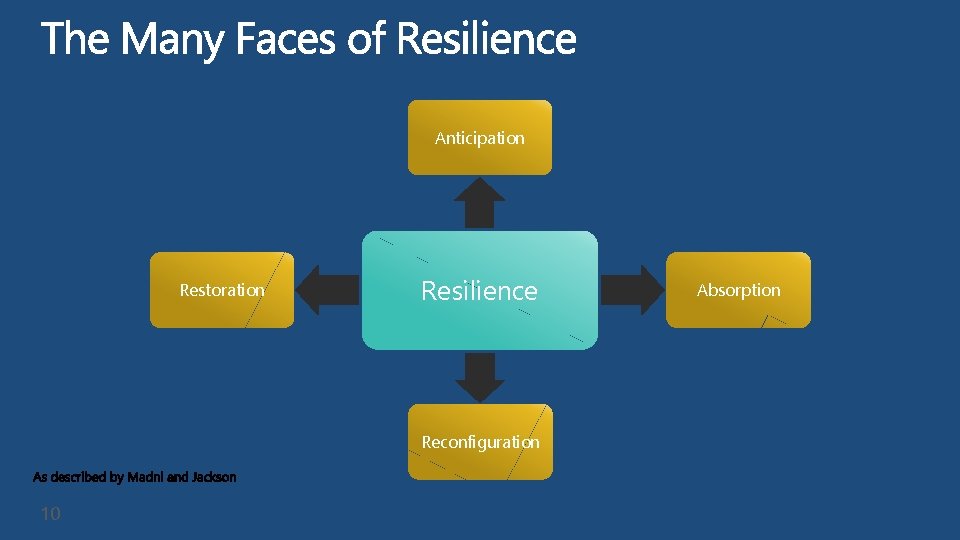
Anticipation Restoration Resilience Reconfiguration 10 Absorption
• Functional redundancy • Context spanning • Physical redundancy • Graceful degradation • Reorganization • Human backup • Drift correction • “Human-in-loop” • “Neutral” state • Predictability • Inspectability • Complexity avoidance • Intent awareness • Learning/Adaptation As described by Madni and Jackson 11
Functional Redundancy • Online and offline functionality in order to provide continued functionality even in the light of failures Physical Redundancy • Office 365 provides physical redundancy at multiple levels to protect against hardware failures • Data in transit and at rest • Network and hardware redundancy • Facilities and power redundancy • At least 2 datacenters per region 12
Reorganization • Active load balancing to restructure the system against rare extreme load conditions • Response to hardware failures 13
Human Backup and “Human-in-Loop” • Monitoring system attempts automated recovery actions, and alerts 24 x 7 on-call engineer when recovery does not succeed • On-call engineers are core product group members (dev, test, and PM) in the relevant area for the alert for rapid response and relevant information collection 14
Inspectability and Predictability • Detailed logging and tracing to avoid unnecessary assumptions by on-call engineers • Deviations from normal behavior deliver alerts to oncall engineers, enabling relevant information collection and rapid resolution 15
Complexity Avoidance • Standardized hardware and automated deployment model Context Spanning • Recovery across “failure domains” tested regularly, including regional disasters • Service component isolation to avoid failure cascades. Graceful Degradation and Drift Correction • Built-in workload management mechanisms to avoid catastrophic impact and degrade gracefully 16
What is the uptime in Office 365? Why is it good? What does Microsoft do to make sure it is? How do these numbers translate into my organization? What happens when I have an outage? How does our approach differ from our competitors? What’s next? How does Microsoft make sure it keeps getting better?
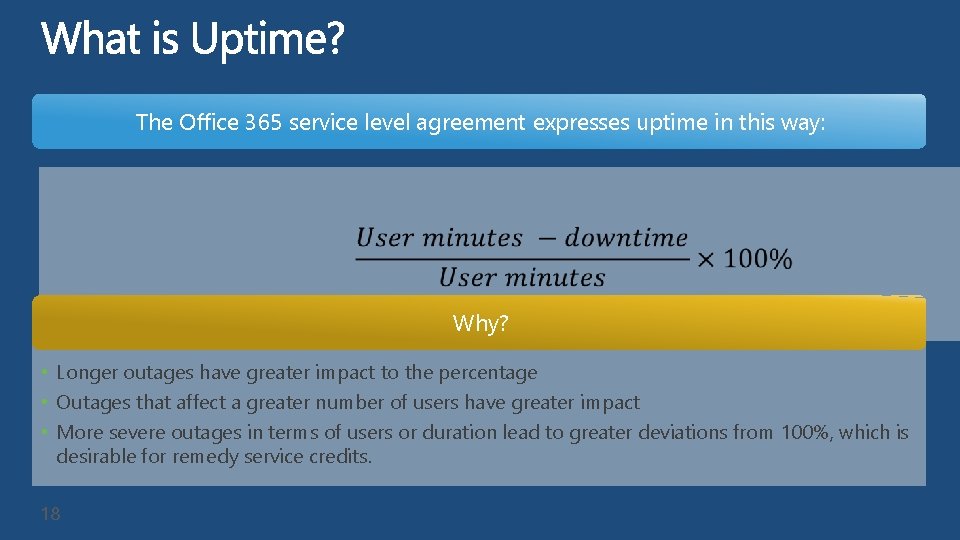
The Office 365 service level agreement expresses uptime in this way: Why? • Longer outages have greater impact to the percentage • Outages that affect a greater number of users have greater impact • More severe outages in terms of users or duration lead to greater deviations from 100%, which is desirable for remedy service credits. 18
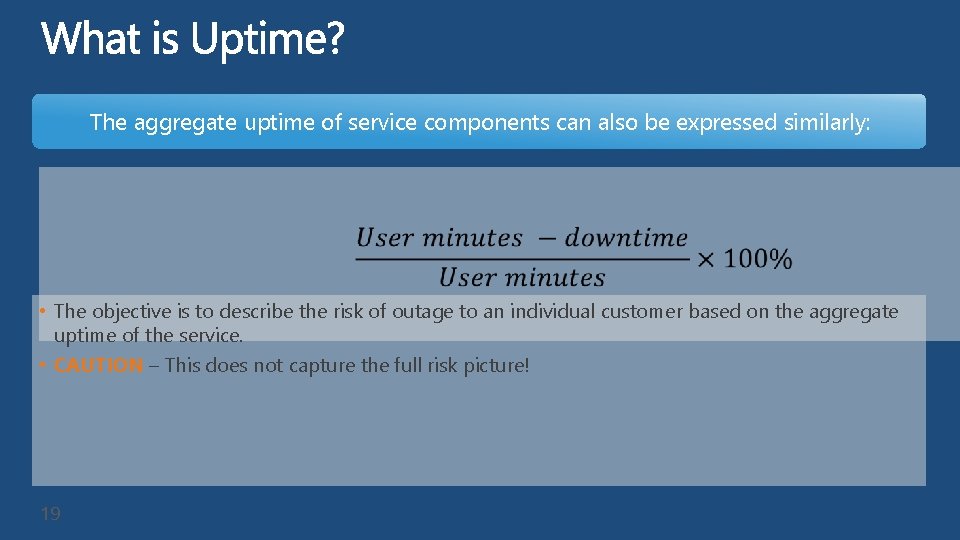
The aggregate uptime of service components can also be expressed similarly: • The objective is to describe the risk of outage to an individual customer based on the aggregate uptime of the service. • CAUTION – This does not capture the full risk picture! 19
What are the caveats with this aggregate uptime number, particularly when it is used to compare different services? • Downtime that is not dependent on the number of users is still adjusted by the number of users. • The aggregate uptime is heavily dependent on the definition of downtime. • Different cloud services provide different functionality, making uptime hard to compare. • Productivity loss due to downtime differs by service. 20
What is the uptime in Office 365? Why is it good? What does Microsoft do to make sure it is? How do these numbers translate into my organization? What happens when I have an outage? How does our approach differ from our competitors? What’s next? How does Microsoft make sure it keeps getting better?
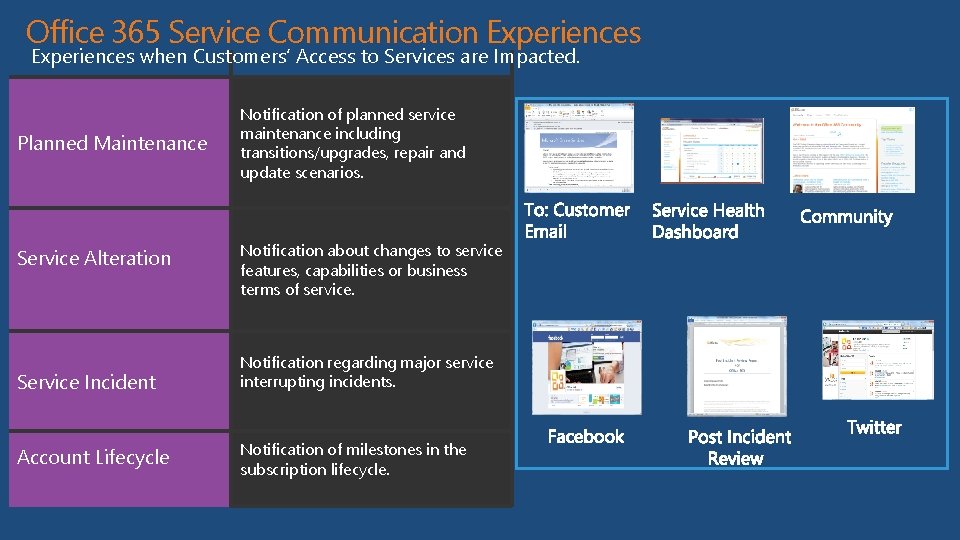
Office 365 Service Communication Experiences when Customers’ Access to Services are Impacted. Planned Maintenance Service Alteration Service Incident Account Lifecycle Notification of planned service maintenance including transitions/upgrades, repair and update scenarios. Notification about changes to service features, capabilities or business terms of service. Notification regarding major service interrupting incidents. Notification of milestones in the subscription lifecycle.
Backed by the most responsive support available and a comprehensive 99. 9% financially backed SLA
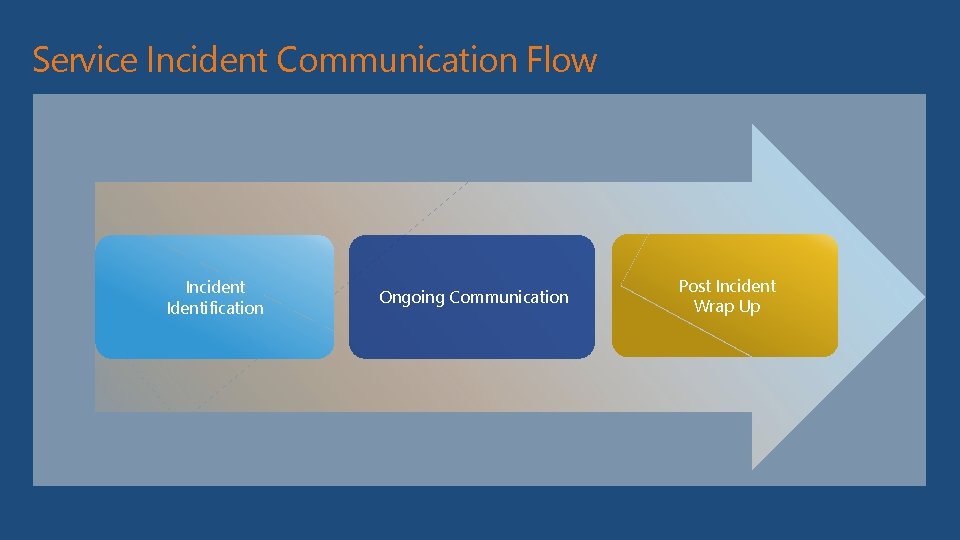
Service Incident Communication Flow Incident Identification Ongoing Communication Post Incident Wrap Up
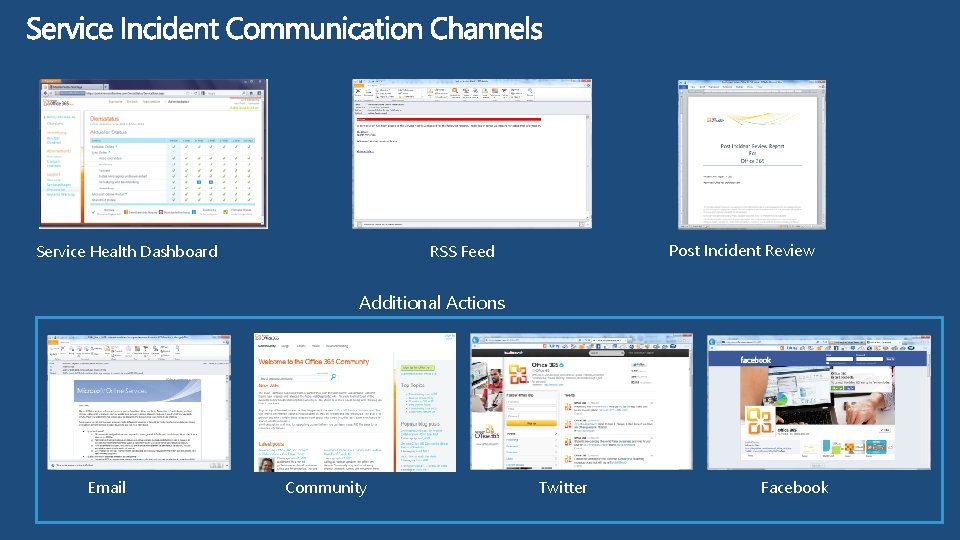
Service Health Dashboard Post Incident Review RSS Feed Additional Actions Email Community Twitter Facebook
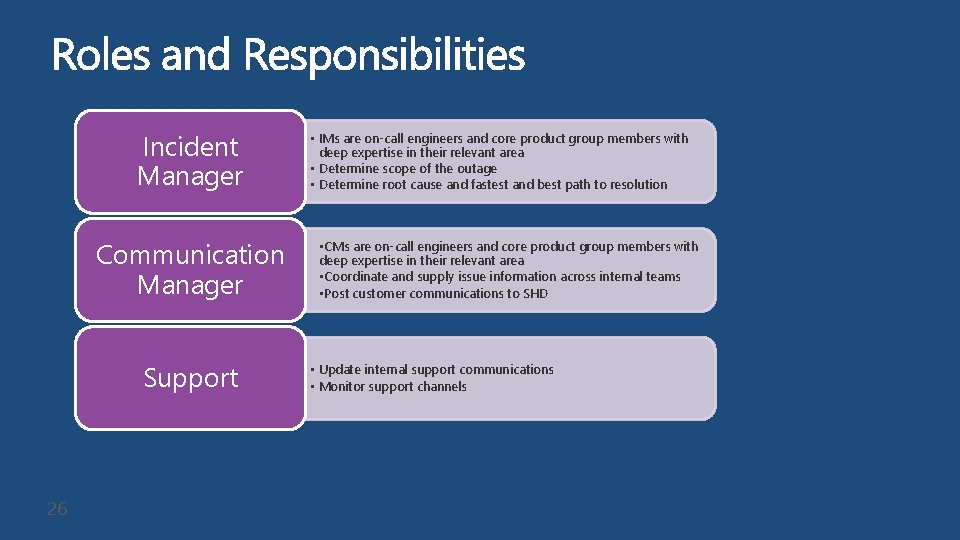
Incident Manager Communication Manager Support 26 • IMs are on-call engineers and core product group members with deep expertise in their relevant area • Determine scope of the outage • Determine root cause and fastest and best path to resolution • CMs are on-call engineers and core product group members with deep expertise in their relevant area • Coordinate and supply issue information across internal teams • Post customer communications to SHD • Update internal support communications • Monitor support channels
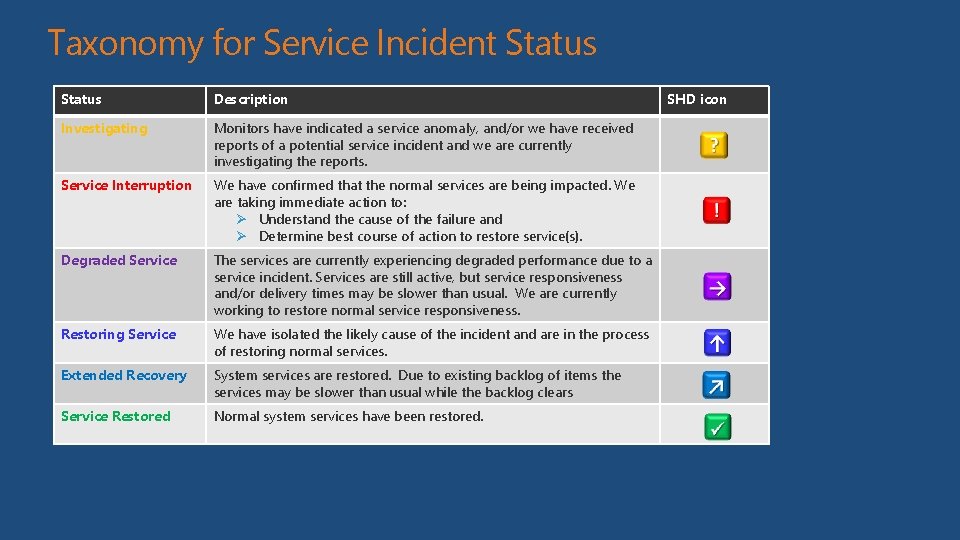
Taxonomy for Service Incident Status Description Investigating Monitors have indicated a service anomaly, and/or we have received reports of a potential service incident and we are currently investigating the reports. Service Interruption We have confirmed that the normal services are being impacted. We are taking immediate action to: Ø Understand the cause of the failure and Ø Determine best course of action to restore service(s). Degraded Service The services are currently experiencing degraded performance due to a service incident. Services are still active, but service responsiveness and/or delivery times may be slower than usual. We are currently working to restore normal service responsiveness. Restoring Service We have isolated the likely cause of the incident and are in the process of restoring normal services. Extended Recovery System services are restored. Due to existing backlog of items the services may be slower than usual while the backlog clears Service Restored Normal system services have been restored. SHD icon
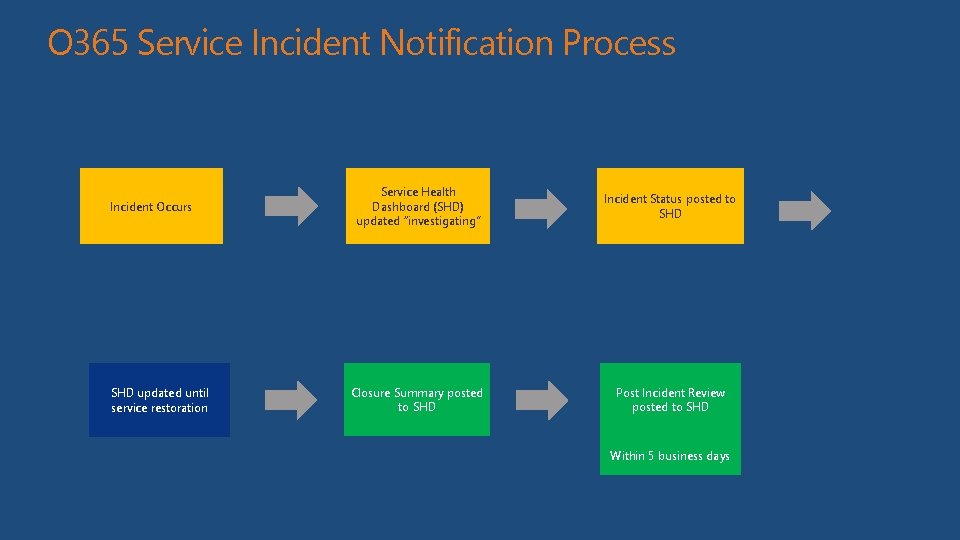
O 365 Service Incident Notification Process Incident Occurs SHD updated until service restoration Service Health Dashboard (SHD) updated “investigating” Incident Status posted to SHD Closure Summary posted to SHD Post Incident Review posted to SHD Within 5 business days
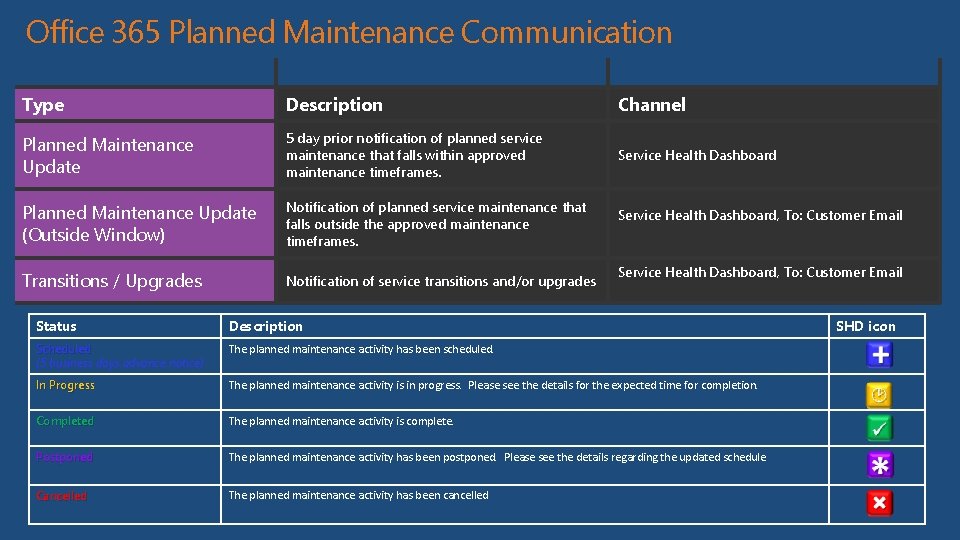
Office 365 Planned Maintenance Communication Type Description Channel Planned Maintenance Update 5 day prior notification of planned service maintenance that falls within approved maintenance timeframes. Service Health Dashboard Planned Maintenance Update (Outside Window) Notification of planned service maintenance that falls outside the approved maintenance timeframes. Transitions / Upgrades Notification of service transitions and/or upgrades Service Health Dashboard, To: Customer Email Status Description Scheduled (5 business days advance notice) The planned maintenance activity has been scheduled. In Progress The planned maintenance activity is in progress. Please see the details for the expected time for completion. Completed The planned maintenance activity is complete. Postponed The planned maintenance activity has been postponed. Please see the details regarding the updated schedule Cancelled The planned maintenance activity has been cancelled SHD icon
What is the uptime in Office 365? Why is it good? What does Microsoft do to make sure it is? How do these numbers translate into my organization? What happens when I have an outage? How does our approach differ from our competitors? What’s next? How does Microsoft make sure it keeps getting better?
Microsoft is the company that businesses look to for the software they need to boost productivity and operate with efficiency, effectiveness, and intelligence. Microsoft Office Division, the division that produces Office 365, produced over half of Microsoft’s operating income. For some of our competitors, productivity is a minor side business at best. 31
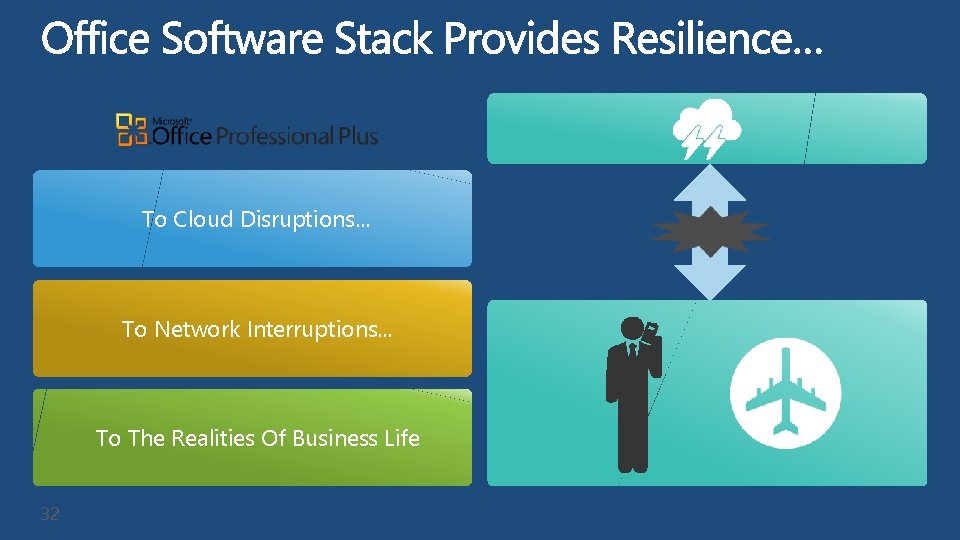
To Cloud Disruptions… To Network Interruptions… To The Realities Of Business Life 32
The Office 365 service level agreement covers all services – no exceptions! The definition of downtime for Office 365 is more than the “server-side error rate” – it covers real functionality, when users are unable to read, write, access, send, receive data.
The Office 365 service level agreement refers to all end users, not just those exceeding a particular threshold. 34
The recovery time objective (RTO) and recovery point objective (RPO) are based on regular verification and what we believe we can deliver in a real disaster. Some of our competitors claim a zero RTO and zero RPO, even if they have needed to restore from tape in the past! 35
What is the uptime in Office 365? Why is it good? What does Microsoft do to make sure it is? How do these numbers translate into my organization? What happens when I have an outage? How does our approach differ from our competitors? What’s next? How does Microsoft make sure it keeps getting better?
37
38
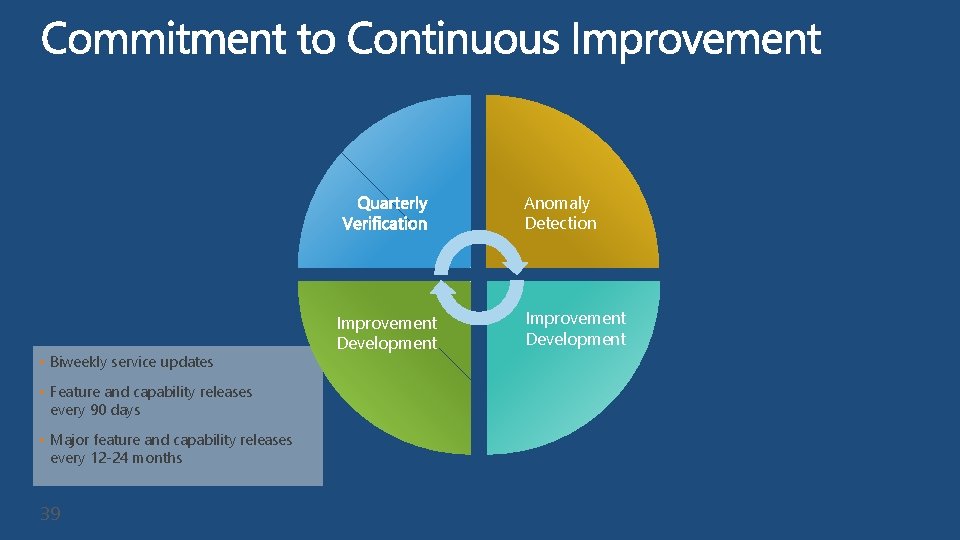
Anomaly Detection • Biweekly service updates • Feature and capability releases every 90 days • Major feature and capability releases every 12 -24 months 39 Improvement Development
Microsoft Office 365 will continue to offers the most resilient and predictable service availability experience for the cloud. Backed by the most responsive support available and a the most comprehensive financially backed SLA to reflect our commitment to meet your service availability needs. 40
Learning Connect. Share. Discuss. Microsoft Certification & Training Resources http: //europe. msteched. com www. microsoft. com/learning Tech. Net Resources for IT Professionals Resources for Developers http: //microsoft. com/technet http: //microsoft. com/msdn
Evaluations Submit your evals online http: //europe. msteched. com/sessions
- Slides: 45