
NTK network structure Arthur Jacot Franck Gabriel and
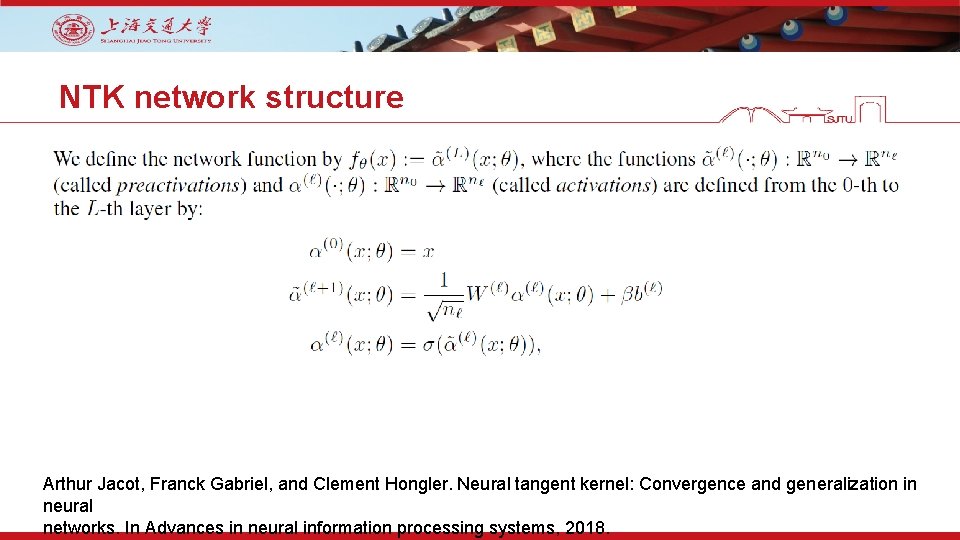
NTK network structure Arthur Jacot, Franck Gabriel, and Clement Hongler. Neural tangent kernel: Convergence and generalization in neural networks. In Advances in neural information processing systems, 2018.
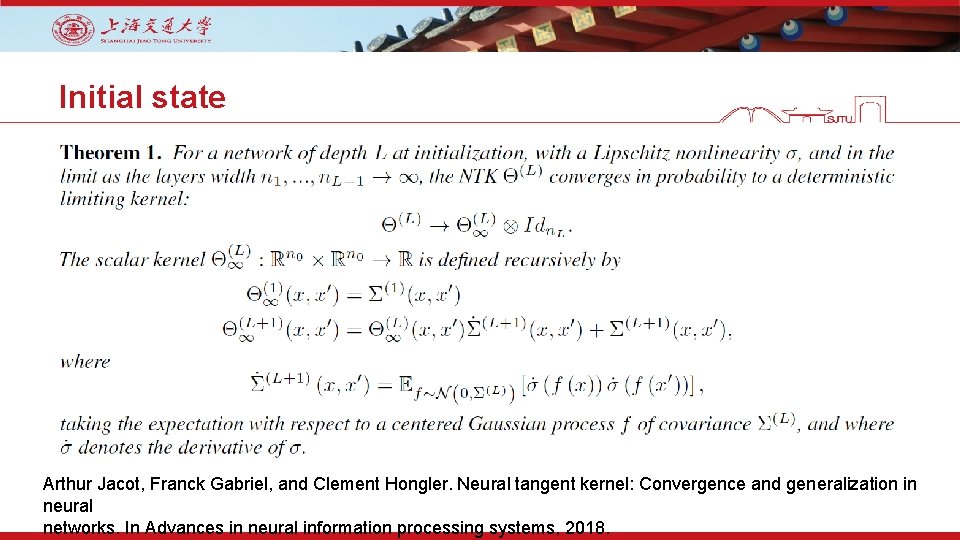
Initial state Arthur Jacot, Franck Gabriel, and Clement Hongler. Neural tangent kernel: Convergence and generalization in neural networks. In Advances in neural information processing systems, 2018.
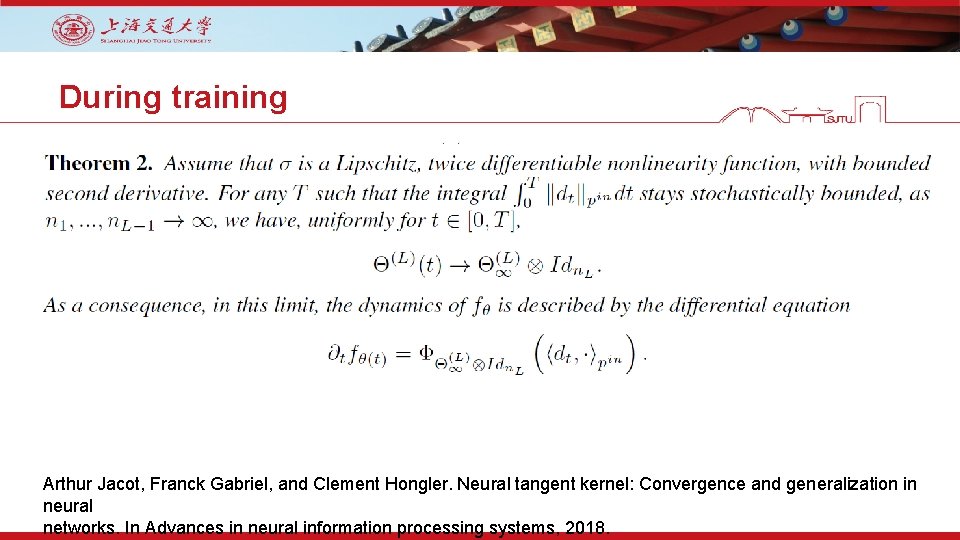
During training Arthur Jacot, Franck Gabriel, and Clement Hongler. Neural tangent kernel: Convergence and generalization in neural networks. In Advances in neural information processing systems, 2018.
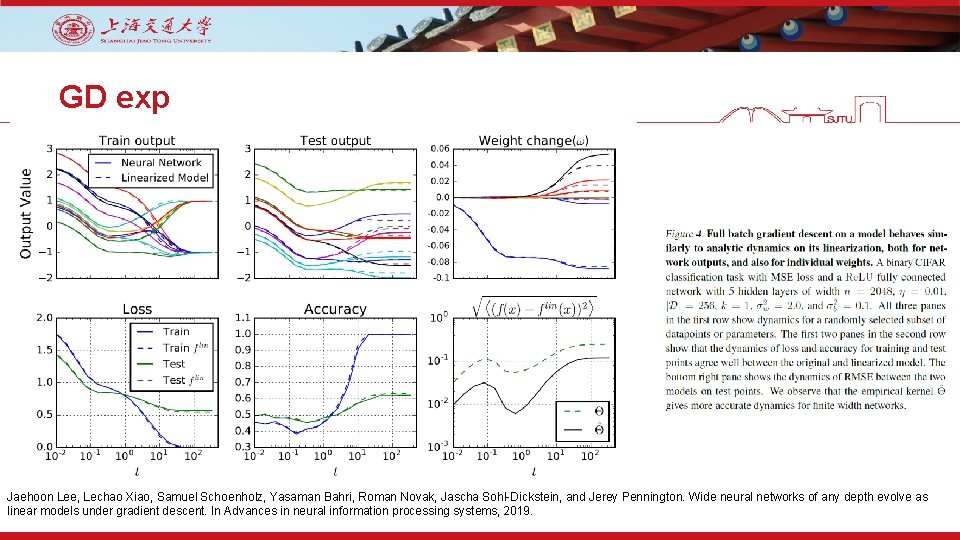
GD exp Jaehoon Lee, Lechao Xiao, Samuel Schoenholz, Yasaman Bahri, Roman Novak, Jascha Sohl-Dickstein, and Jerey Pennington. Wide neural networks of any depth evolve as linear models under gradient descent. In Advances in neural information processing systems, 2019.
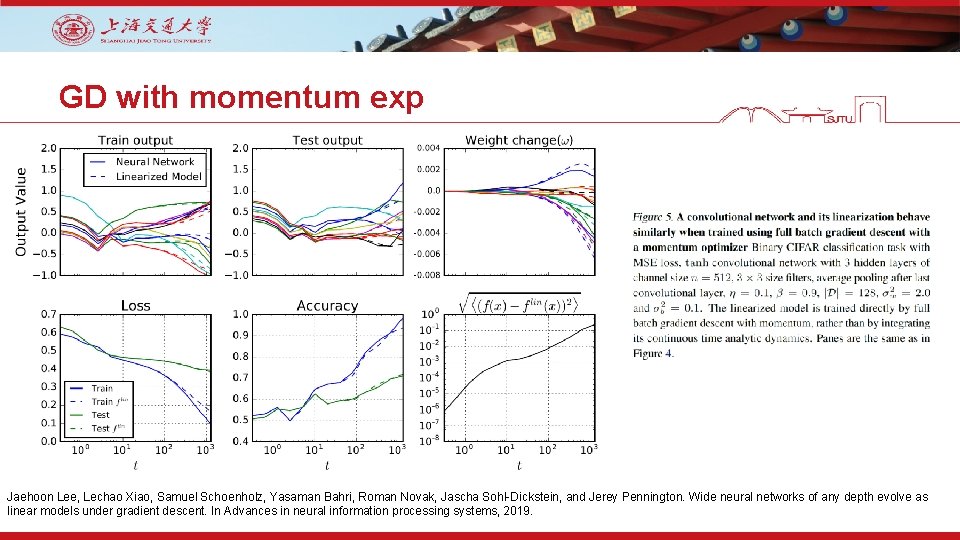
GD with momentum exp Jaehoon Lee, Lechao Xiao, Samuel Schoenholz, Yasaman Bahri, Roman Novak, Jascha Sohl-Dickstein, and Jerey Pennington. Wide neural networks of any depth evolve as linear models under gradient descent. In Advances in neural information processing systems, 2019.
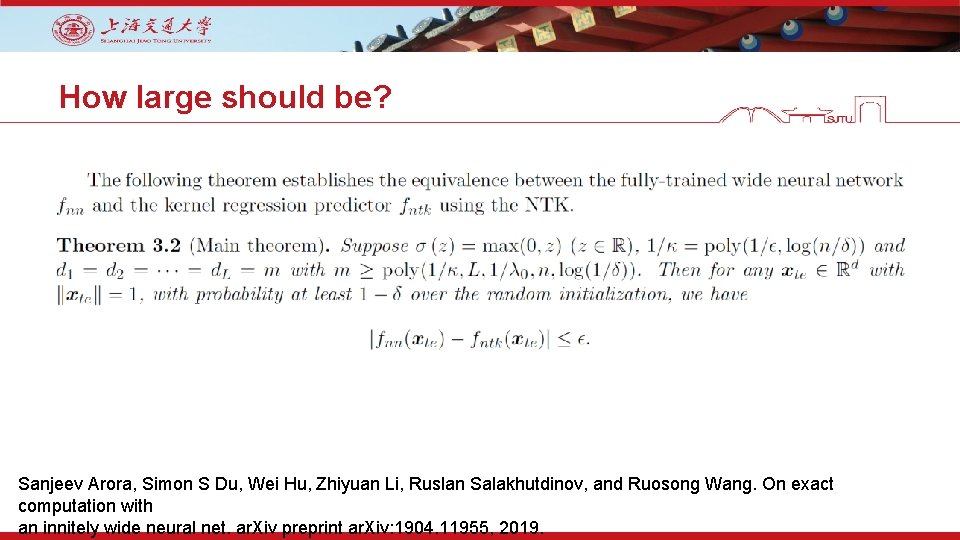
How large should be? Sanjeev Arora, Simon S Du, Wei Hu, Zhiyuan Li, Ruslan Salakhutdinov, and Ruosong Wang. On exact computation with an innitely wide neural net. ar. Xiv preprint ar. Xiv: 1904. 11955, 2019.
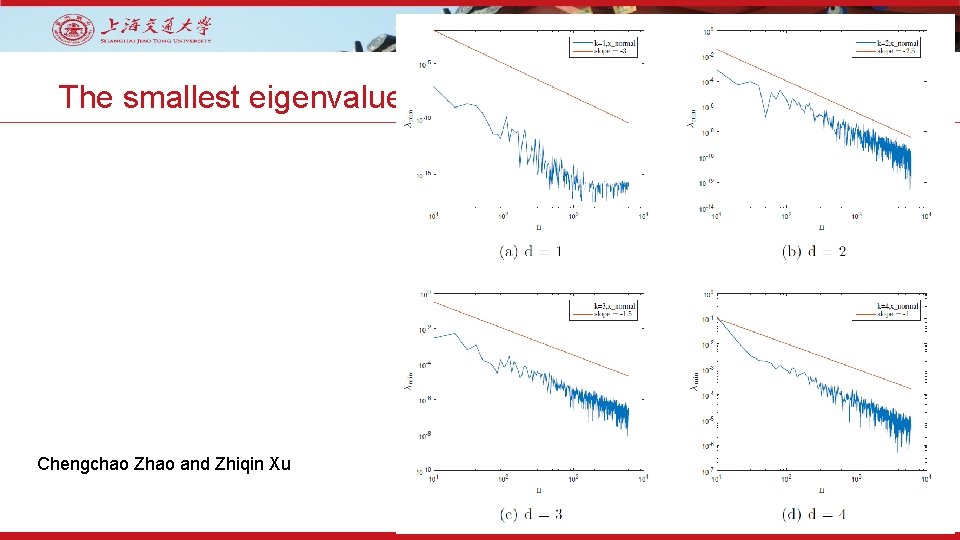
The smallest eigenvalue Chengchao Zhao and Zhiqin Xu
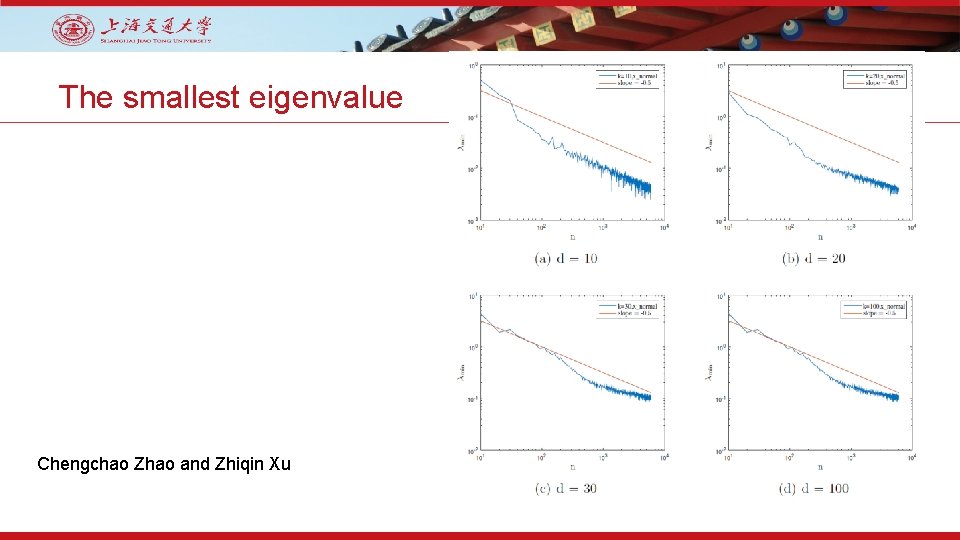
The smallest eigenvalue Chengchao Zhao and Zhiqin Xu
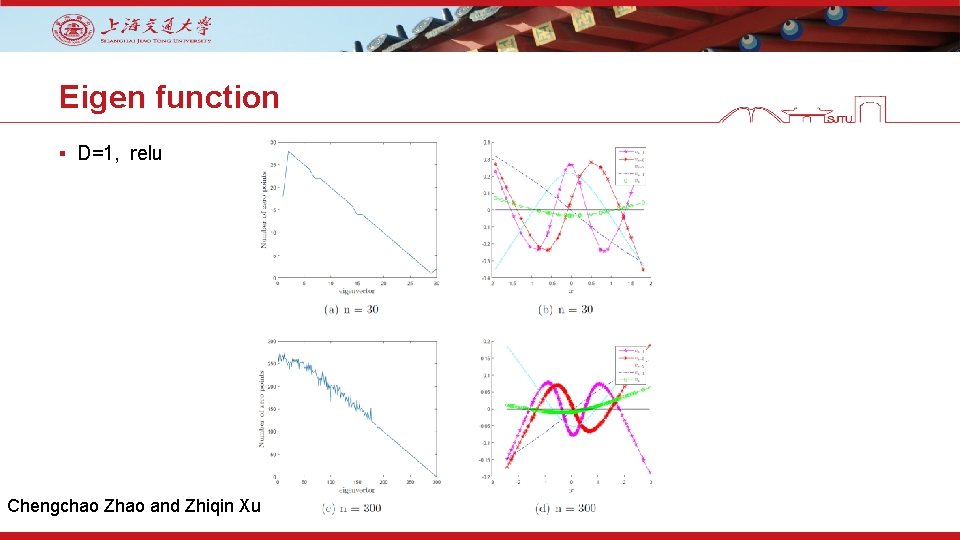
Eigen function ▪ D=1, relu Chengchao Zhao and Zhiqin Xu
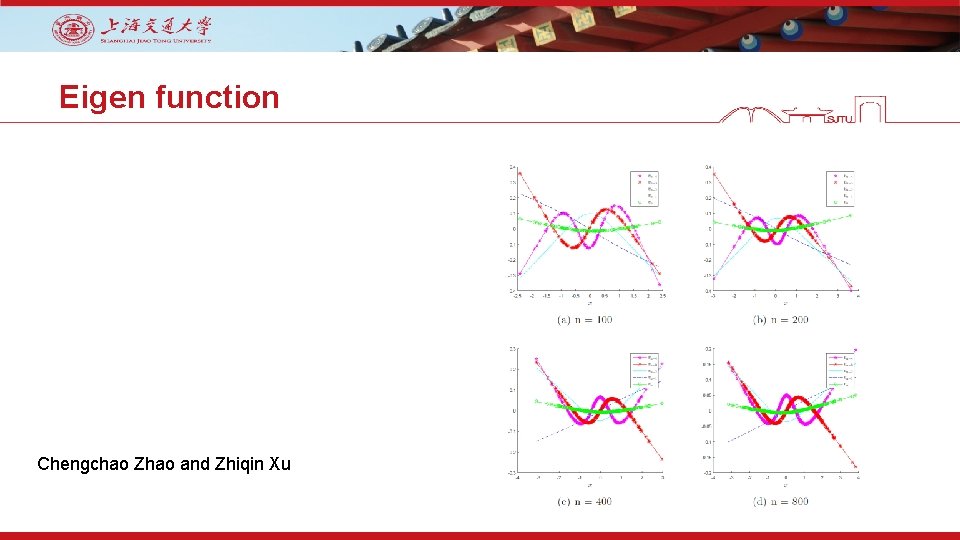
Eigen function Chengchao Zhao and Zhiqin Xu
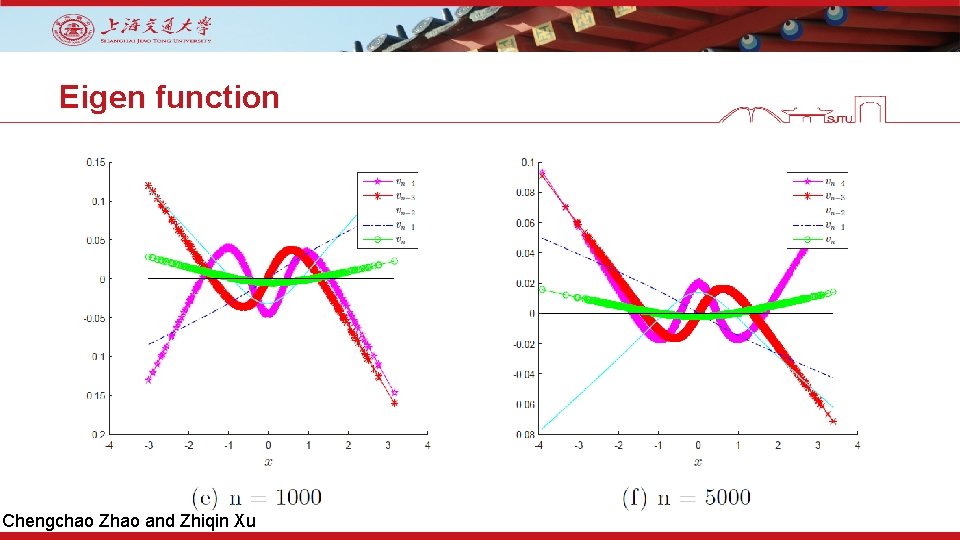
Eigen function Chengchao Zhao and Zhiqin Xu
What can we do from the NTK? ▪ Study the error source of neural network? Such as initialization ▪ Study the Frequency principle explicitly? ▪ Study the generalization error of neural network?
- Slides: 13