
Ngram Search Engine on Wikipedia Satoshi Sekine NYU
- Slides: 17
N-gram Search Engine on Wikipedia Satoshi Sekine (NYU) Kapil Dalwani (JHU) July 30 th, 2009 Lexical Knowledge from Ngrams
Hammer : Fast and multifunctional n-gram search engine Search ngram: FAST OUTPUT: frequency to text ng ra m s INPUT: token, POS, chunk, NE July 30 th, 2009 Lexical Knowledge from Ngrams 2
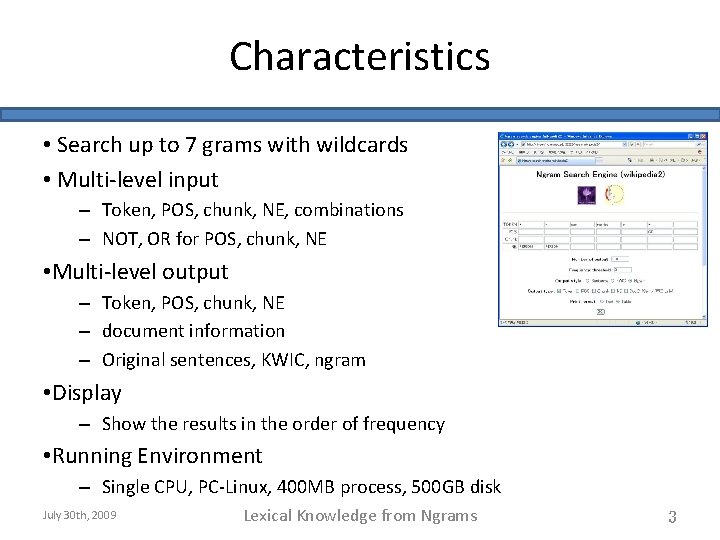
Characteristics • Search up to 7 grams with wildcards • Multi-level input – Token, POS, chunk, NE, combinations – NOT, OR for POS, chunk, NE • Multi-level output – Token, POS, chunk, NE – document information – Original sentences, KWIC, ngram • Display – Show the results in the order of frequency • Running Environment – Single CPU, PC-Linux, 400 MB process, 500 GB disk July 30 th, 2009 Lexical Knowledge from Ngrams 3
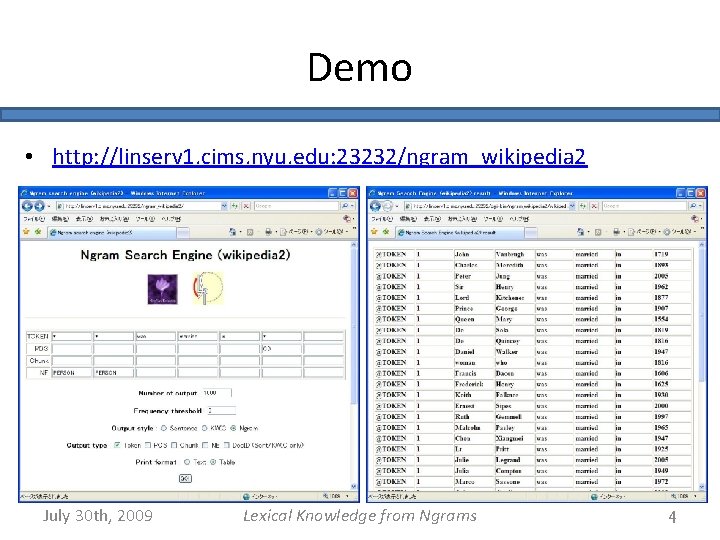
Demo • http: //linserv 1. cims. nyu. edu: 23232/ngram_wikipedia 2 July 30 th, 2009 Lexical Knowledge from Ngrams 4
Available for you • Web system – At NYU • http: //nlp. cs. nyu. edu/nsearch – At JHU? • USB Hard drive July 30 th, 2009 Lexical Knowledge from Ngrams 5
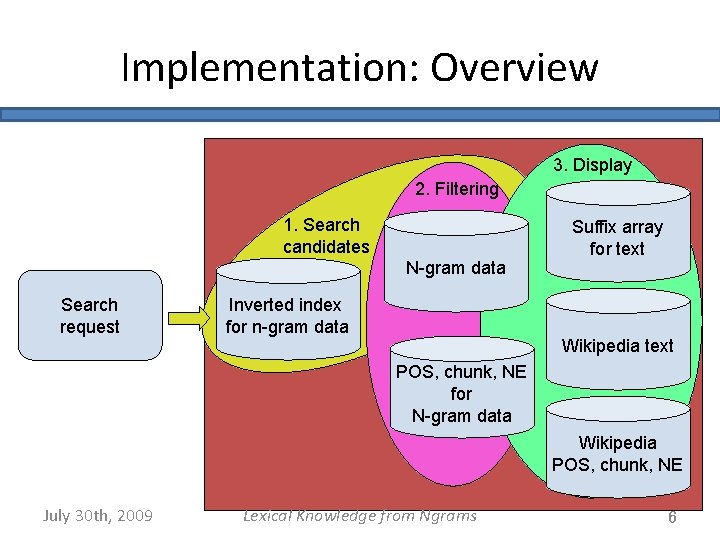
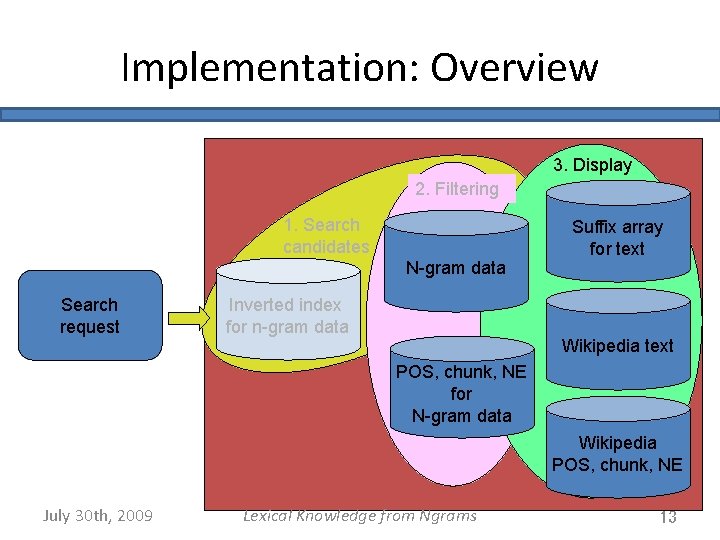
Implementation: Overview 3. Display 2. Filtering 1. Search candidates N-gram data Search request Inverted index for n-gram data Suffix array for text Wikipedia text POS, chunk, NE for N-gram data Wikipedia POS, chunk, NE July 30 th, 2009 Lexical Knowledge from Ngrams 6
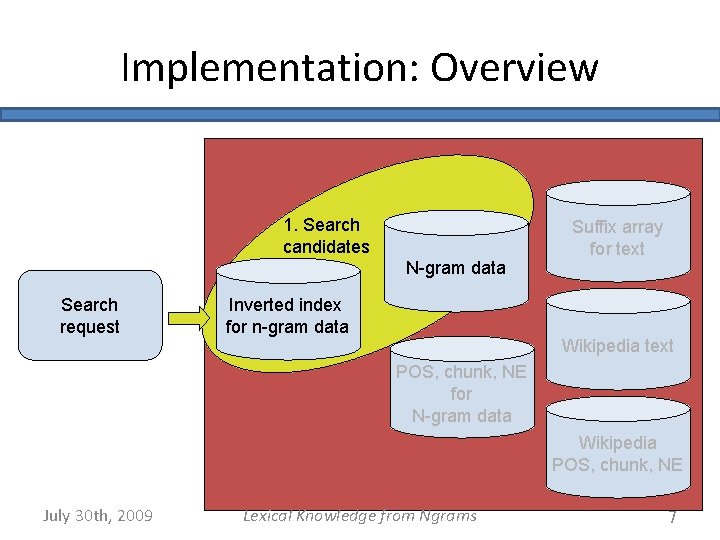
Implementation: Overview 1. Search candidates N-gram data Search request Inverted index for n-gram data Suffix array for text Wikipedia text POS, chunk, NE for N-gram data Wikipedia POS, chunk, NE July 30 th, 2009 Lexical Knowledge from Ngrams 7
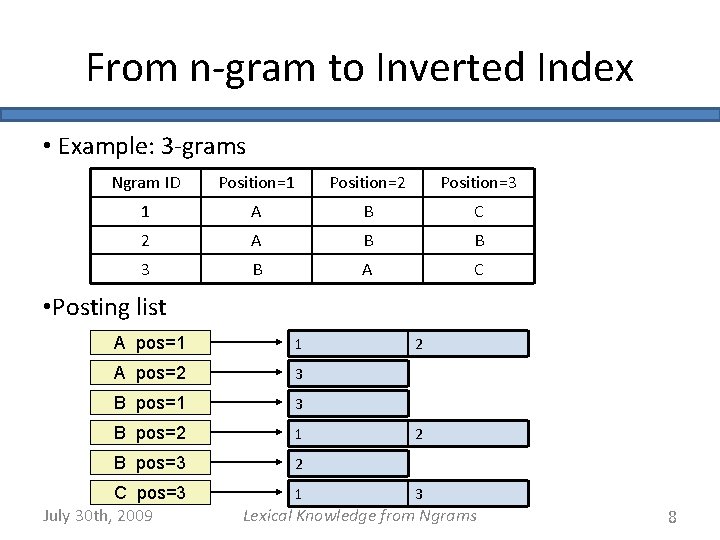
From n-gram to Inverted Index • Example: 3 -grams Ngram ID Position=1 Position=2 Position=3 1 A B C 2 A B B 3 B A C • Posting list A pos=1 1 A pos=2 3 B pos=1 3 B pos=2 1 B pos=3 2 C pos=3 July 30 th, 2009 1 2 2 3 Lexical Knowledge from Ngrams 8
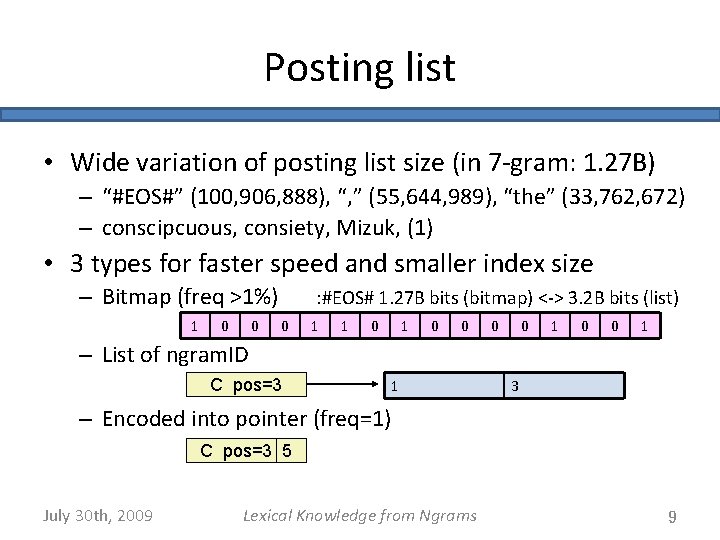
Posting list • Wide variation of posting list size (in 7 -gram: 1. 27 B) – “#EOS#” (100, 906, 888), “, ” (55, 644, 989), “the” (33, 762, 672) – conscipcuous, consiety, Mizuk, (1) • 3 types for faster speed and smaller index size – Bitmap (freq >1%) 1 0 0 : #EOS# 1. 27 B bits (bitmap) <-> 3. 2 B bits (list) 0 1 1 0 0 0 0 1 – List of ngram. ID C pos=3 1 3 – Encoded into pointer (freq=1) C pos=3 5 July 30 th, 2009 Lexical Knowledge from Ngrams 9
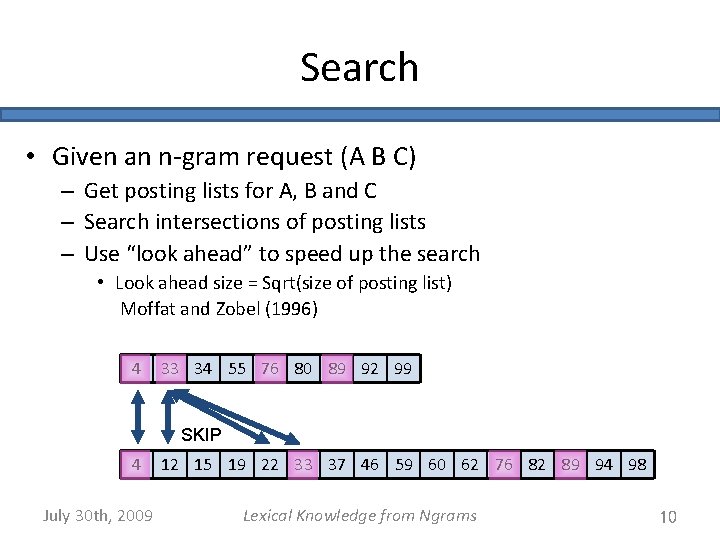
Search • Given an n-gram request (A B C) – Get posting lists for A, B and C – Search intersections of posting lists – Use “look ahead” to speed up the search • Look ahead size = Sqrt(size of posting list) Moffat and Zobel (1996) 4 33 34 55 76 80 89 92 99 SKIP 4 July 30 th, 2009 12 15 19 22 33 37 46 59 60 62 76 82 89 94 98 Lexical Knowledge from Ngrams 10
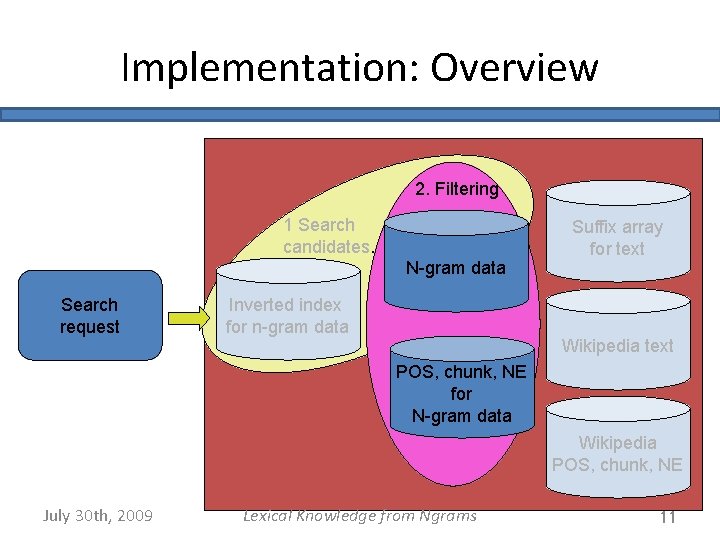
Implementation: Overview 2. Filtering 1 Search candidates. N-gram data Search request Inverted index for n-gram data Suffix array for text Wikipedia text POS, chunk, NE for N-gram data Wikipedia POS, chunk, NE July 30 th, 2009 Lexical Knowledge from Ngrams 11
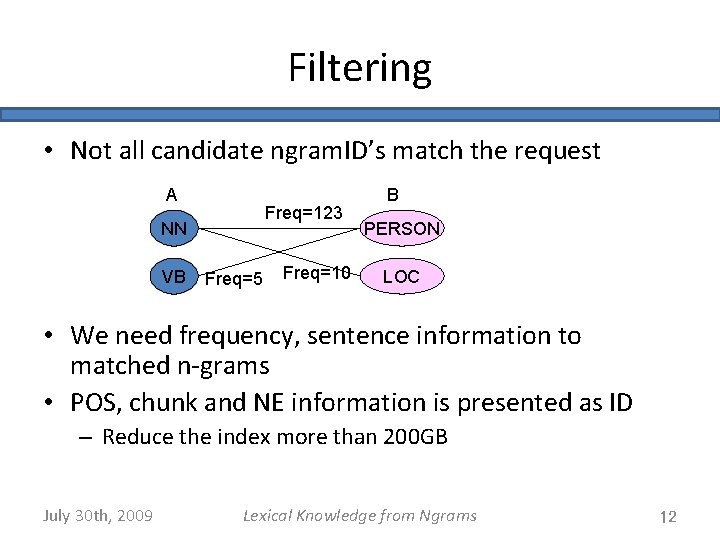
Filtering • Not all candidate ngram. ID’s match the request A Freq=123 NN VB Freq=5 Freq=10 B PERSON LOC • We need frequency, sentence information to matched n-grams • POS, chunk and NE information is presented as ID – Reduce the index more than 200 GB July 30 th, 2009 Lexical Knowledge from Ngrams 12
Implementation: Overview 3. Display 2. Filtering 1. Search candidates N-gram data Search request Inverted index for n-gram data Suffix array for text Wikipedia text POS, chunk, NE for N-gram data Wikipedia POS, chunk, NE July 30 th, 2009 Lexical Knowledge from Ngrams 13
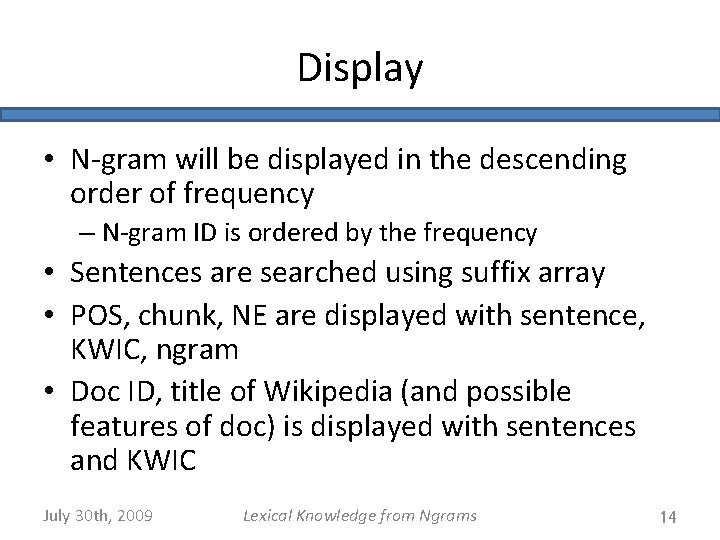
Display • N-gram will be displayed in the descending order of frequency – N-gram ID is ordered by the frequency • Sentences are searched using suffix array • POS, chunk, NE are displayed with sentence, KWIC, ngram • Doc ID, title of Wikipedia (and possible features of doc) is displayed with sentences and KWIC July 30 th, 2009 Lexical Knowledge from Ngrams 14
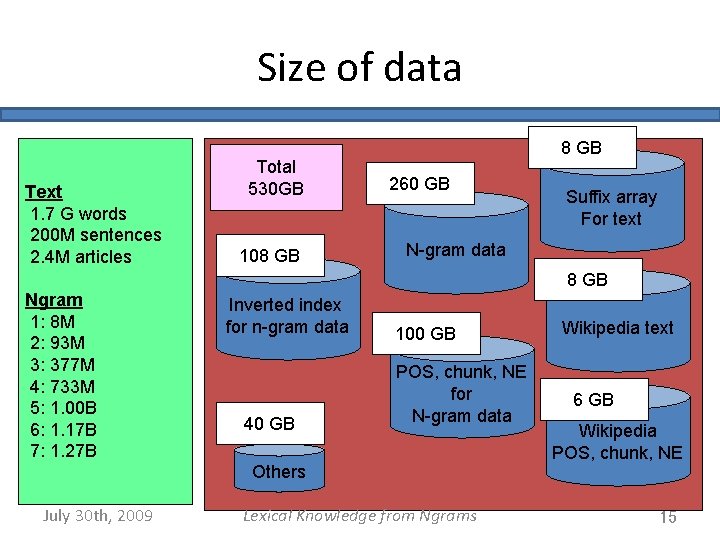
Size of data Text 1. 7 G words 200 M sentences 2. 4 M articles Total 530 GB 108 GB 260 GB Suffix array For text N-gram data 8 GB Ngram 1: 8 M 2: 93 M 3: 377 M 4: 733 M 5: 1. 00 B 6: 1. 17 B 7: 1. 27 B Inverted index for n-gram data 40 GB 100 GB POS, chunk, NE for N-gram data Others July 30 th, 2009 Lexical Knowledge from Ngrams Wikipedia text 6 GB Wikipedia POS, chunk, NE 15
Future Work • Other information (ex: parse, coref, relation, genre, discourse…) • Longer n-gram • Compress index, dictionary • Ease the indexing load – Now we need a big memory machine – Distributing indexing • Union operation for tokens July 30 th, 2009 Lexical Knowledge from Ngrams 16
Available for you • Web demo – At NYU • http: //nlp. cs. nyu. edu/nsearch – At JHU? • USB Hard drive July 30 th, 2009 Lexical Knowledge from Ngrams 17