
Modeling Mutual Context of Object and Human Pose
Modeling Mutual Context of Object and Human Pose in Human-Object Interaction Activities Bangpeng Yao and Li Fei-Fei Computer Science Department, Stanford University {bangpeng, feifeili}@cs. stanford. edu 1
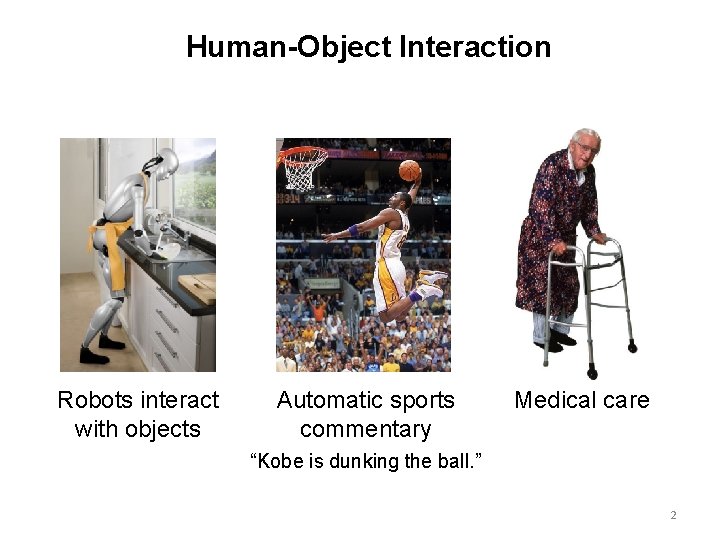
Human-Object Interaction Robots interact with objects Automatic sports commentary Medical care “Kobe is dunking the ball. ” 2
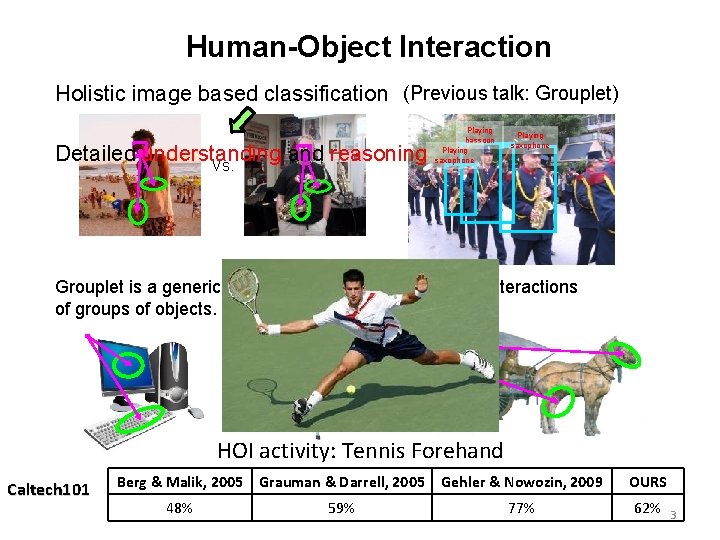
Human-Object Interaction Holistic image based classification (Previous talk: Grouplet) Detailed understanding and reasoning Vs. Playing bassoon Playing saxophone Grouplet is a generic feature for structured objects, or interactions of groups of objects. HOI activity: Tennis Forehand Caltech 101 Berg & Malik, 2005 Grauman & Darrell, 2005 Gehler & Nowozin, 2009 OURS 48% 59% 77% 62% 3
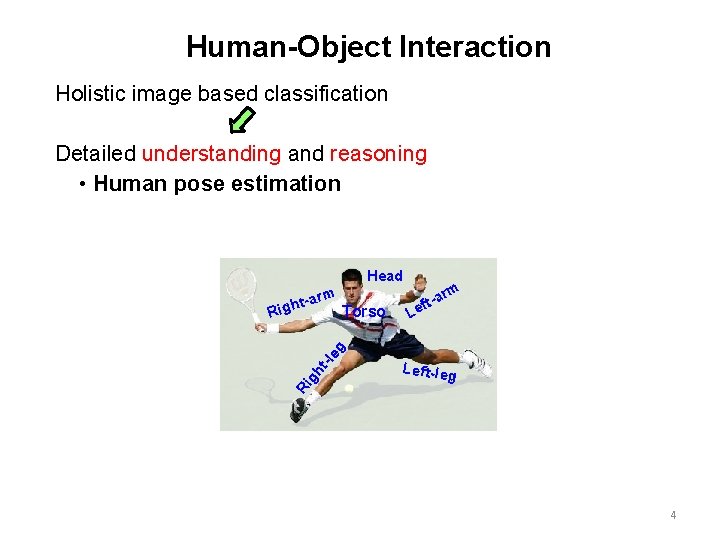
Human-Object Interaction Holistic image based classification Detailed understanding and reasoning • Human pose estimation Head -arm ight Torso L Left-leg Ri gh t-l eg R m -ar t f e 4
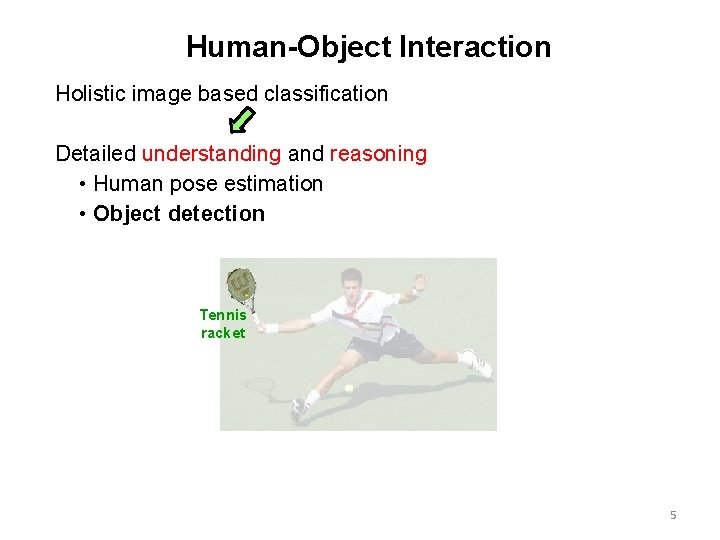
Human-Object Interaction Holistic image based classification Detailed understanding and reasoning • Human pose estimation • Object detection Tennis racket 5
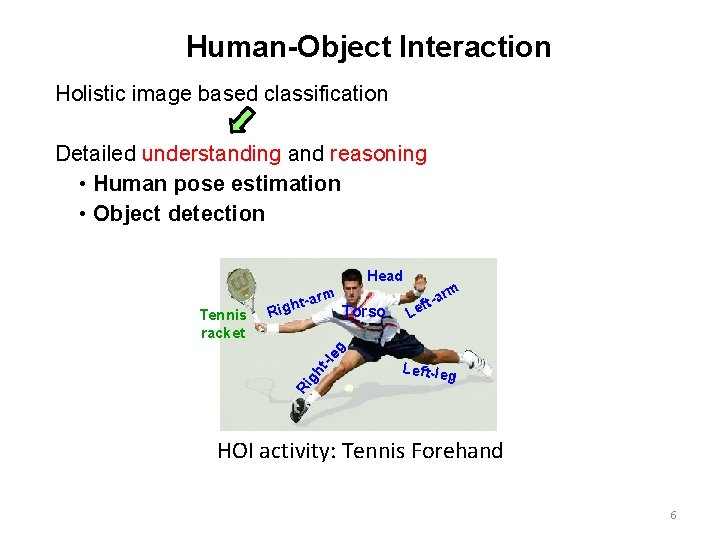
Human-Object Interaction Holistic image based classification Detailed understanding and reasoning • Human pose estimation • Object detection Head R Torso m -ar t f e L Left-leg Ri gh t-l eg Tennis racket -arm ight HOI activity: Tennis Forehand 6
Outline • Background and Intuition • Mutual Context of Object and Human Pose § Model Representation § Model Learning § Model Inference • Experiments • Conclusion 7
Outline • Background and Intuition • Mutual Context of Object and Human Pose § Model Representation § Model Learning § Model Inference • Experiments • Conclusion 8
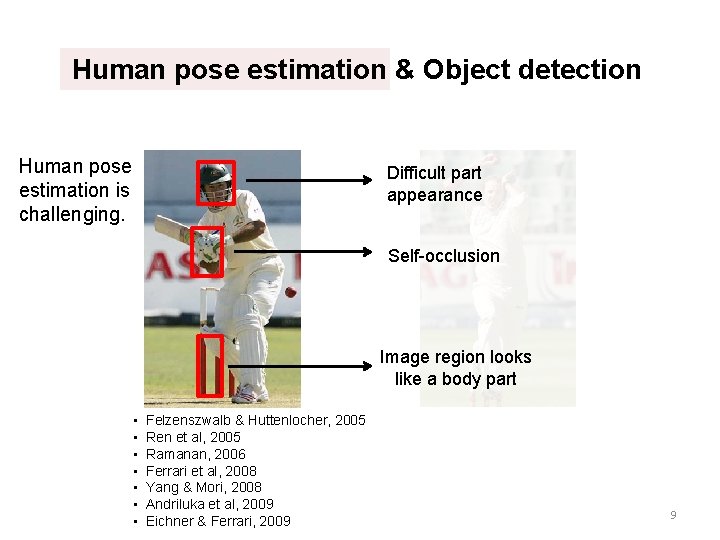
Human pose estimation & Object detection Human pose estimation is challenging. Difficult part appearance Self-occlusion Image region looks like a body part • • Felzenszwalb & Huttenlocher, 2005 Ren et al, 2005 Ramanan, 2006 Ferrari et al, 2008 Yang & Mori, 2008 Andriluka et al, 2009 Eichner & Ferrari, 2009 9
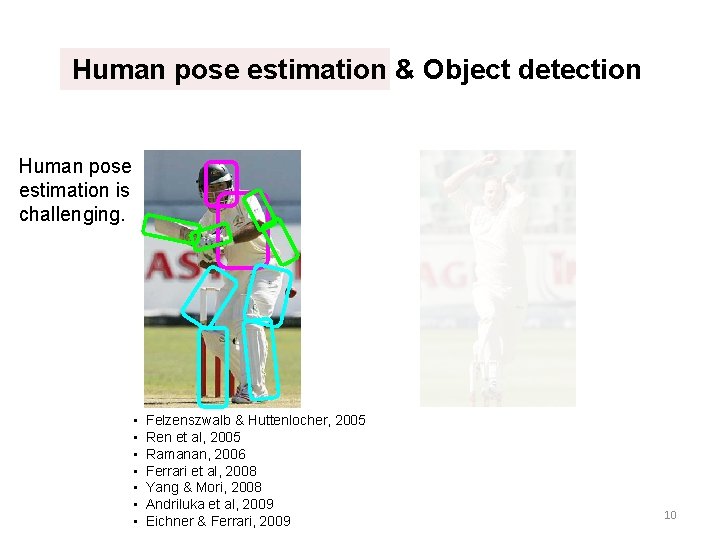
Human pose estimation & Object detection Human pose estimation is challenging. • • Felzenszwalb & Huttenlocher, 2005 Ren et al, 2005 Ramanan, 2006 Ferrari et al, 2008 Yang & Mori, 2008 Andriluka et al, 2009 Eichner & Ferrari, 2009 10
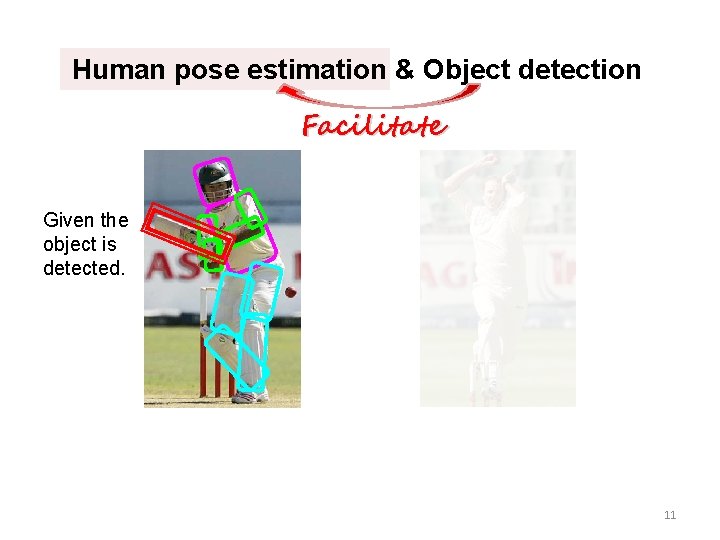
Human pose estimation & Object detection Facilitate Given the object is detected. 11
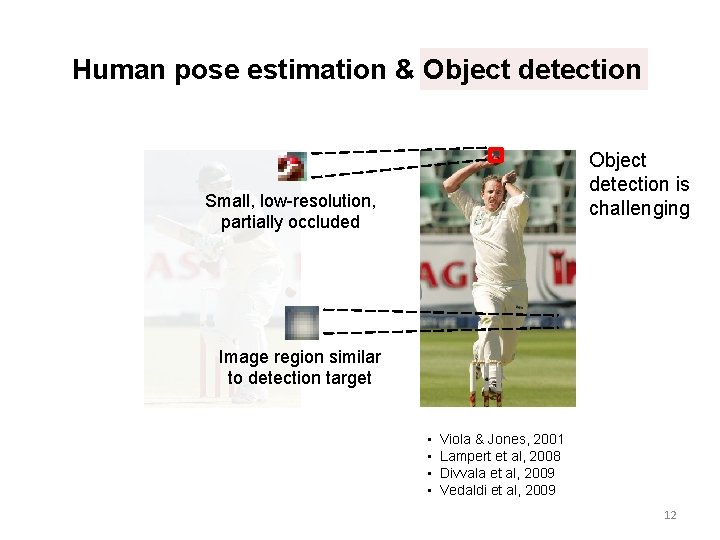
Human pose estimation & Object detection is challenging Small, low-resolution, partially occluded Image region similar to detection target • • Viola & Jones, 2001 Lampert et al, 2008 Divvala et al, 2009 Vedaldi et al, 2009 12
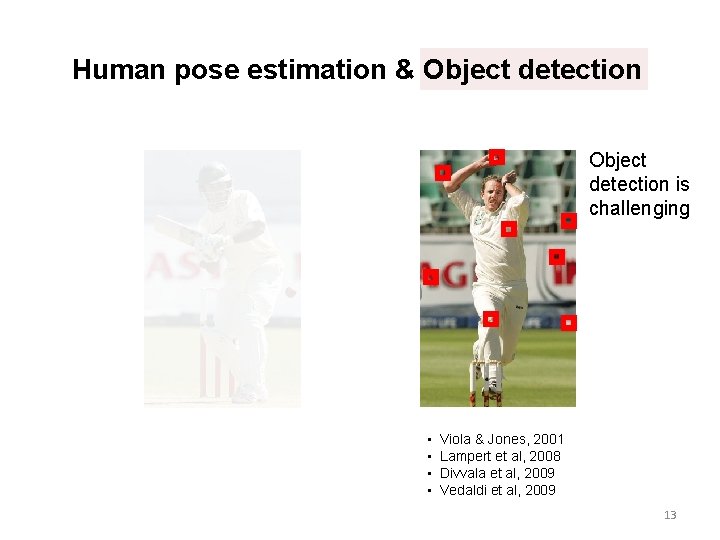
Human pose estimation & Object detection is challenging • • Viola & Jones, 2001 Lampert et al, 2008 Divvala et al, 2009 Vedaldi et al, 2009 13
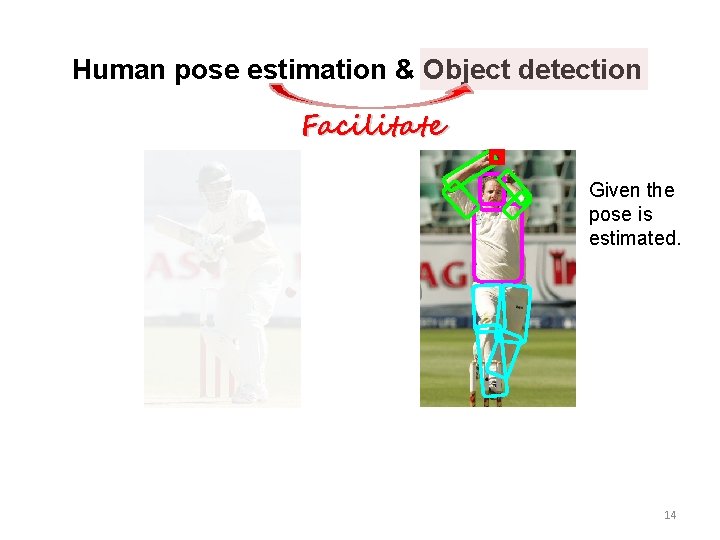
Human pose estimation & Object detection Facilitate Given the pose is estimated. 14
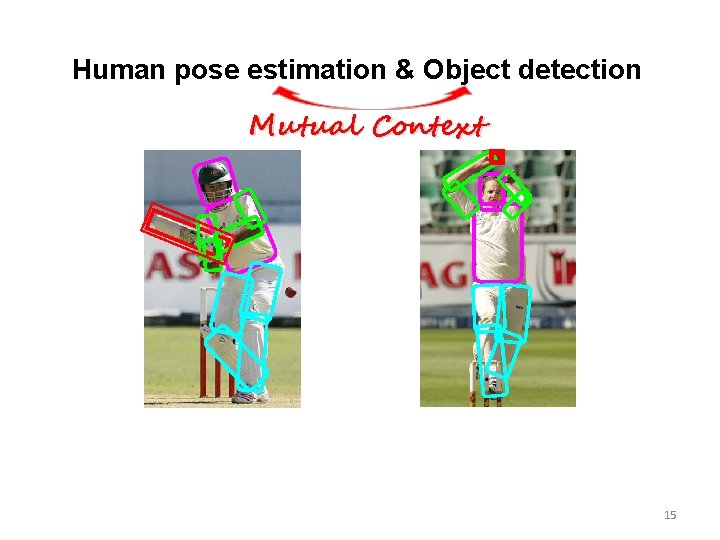
Human pose estimation & Object detection Mutual Context 15
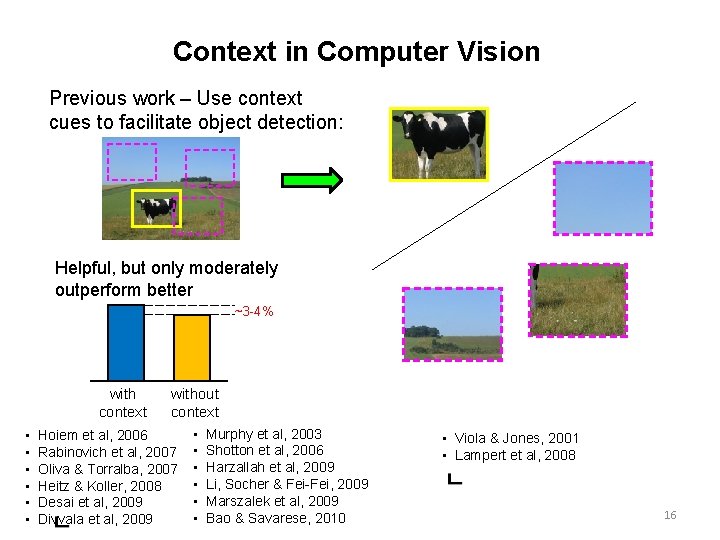
Context in Computer Vision Previous work – Use context cues to facilitate object detection: Helpful, but only moderately outperform better ~3 -4% with context • • • without context • Murphy et al, 2003 Hoiem et al, 2006 Rabinovich et al, 2007 • Shotton et al, 2006 Oliva & Torralba, 2007 • Harzallah et al, 2009 • Li, Socher & Fei-Fei, 2009 Heitz & Koller, 2008 • Marszalek et al, 2009 Desai et al, 2009 • Bao & Savarese, 2010 Divvala et al, 2009 • Viola & Jones, 2001 • Lampert et al, 2008 16
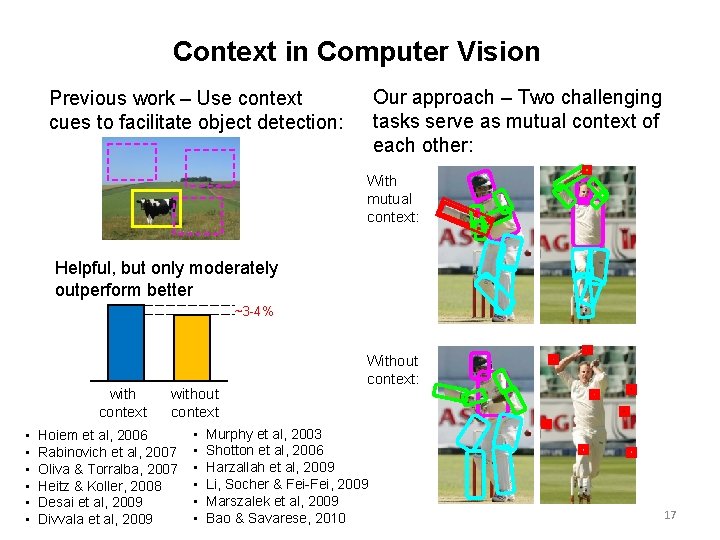
Context in Computer Vision Our approach – Two challenging tasks serve as mutual context of each other: Previous work – Use context cues to facilitate object detection: With mutual context: Helpful, but only moderately outperform better ~3 -4% with context • • • Without context: without context • Murphy et al, 2003 Hoiem et al, 2006 Rabinovich et al, 2007 • Shotton et al, 2006 Oliva & Torralba, 2007 • Harzallah et al, 2009 • Li, Socher & Fei-Fei, 2009 Heitz & Koller, 2008 • Marszalek et al, 2009 Desai et al, 2009 • Bao & Savarese, 2010 Divvala et al, 2009 17
Outline • Background and Intuition • Mutual Context of Object and Human Pose § Model Representation § Model Learning § Model Inference • Experiments • Conclusion 18
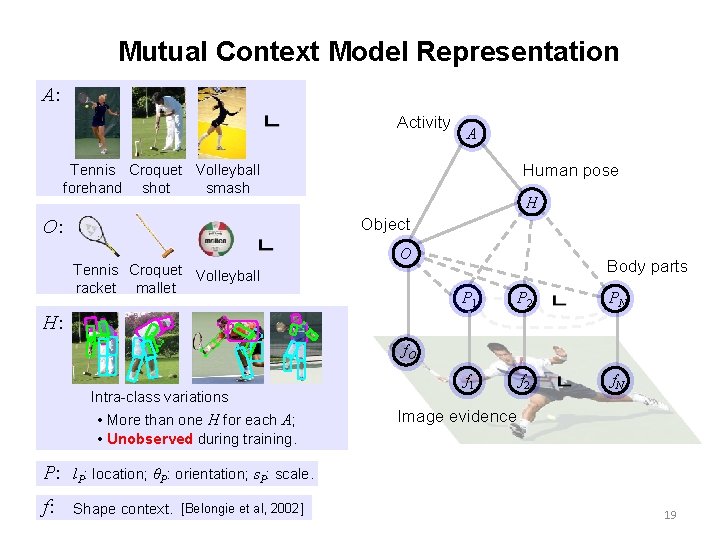
Mutual Context Model Representation A: Activity A Human pose Tennis Croquet Volleyball forehand shot smash H Object O: Tennis Croquet Volleyball racket mallet O Body parts P 1 P 2 PN f 1 f 2 f. N H: f. O Intra-class variations • More than one H for each A; • Unobserved during training. P: l. P: location; θP: orientation; s. P: scale. f: Shape context. [Belongie et al, 2002] Image evidence 19
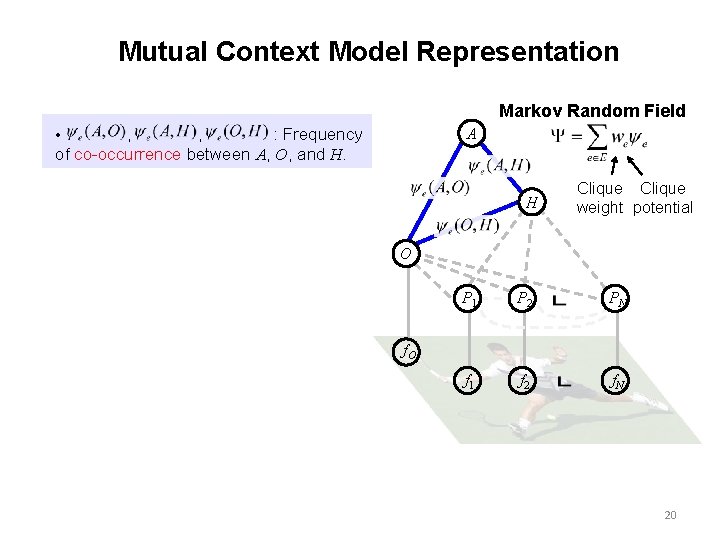
Mutual Context Model Representation Markov Random Field A : Frequency of co-occurrence between A, O, and H. • , , H Clique weight potential O P 1 P 2 PN f 1 f 2 f. N f. O 20
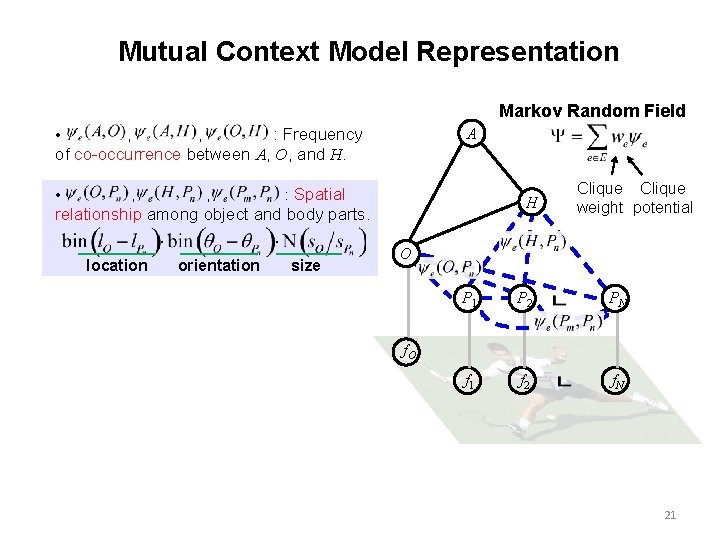
Mutual Context Model Representation Markov Random Field A : Frequency of co-occurrence between A, O, and H. • , , , : Spatial H relationship among object and body parts. location orientation size Clique weight potential O P 1 P 2 PN f 1 f 2 f. N f. O 21
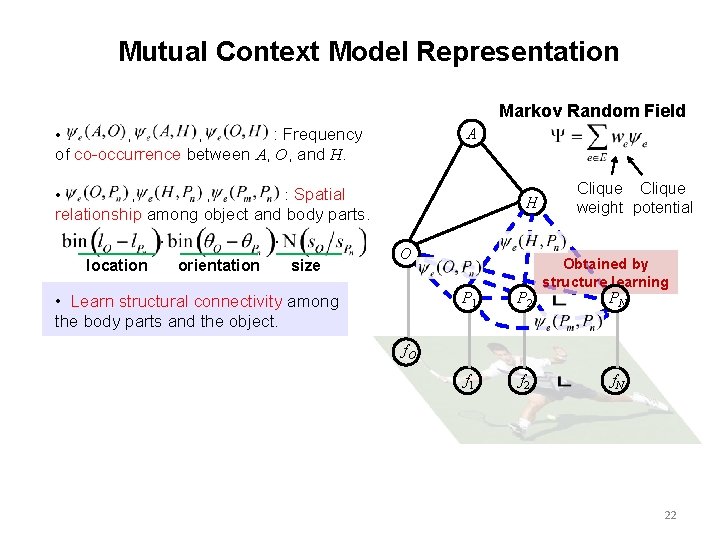
Mutual Context Model Representation Markov Random Field A : Frequency of co-occurrence between A, O, and H. • , , , : Spatial H relationship among object and body parts. location orientation size O • Learn structural connectivity among the body parts and the object. P 1 P 2 f 1 f 2 Clique weight potential Obtained by structure learning PN f. O f. N 22
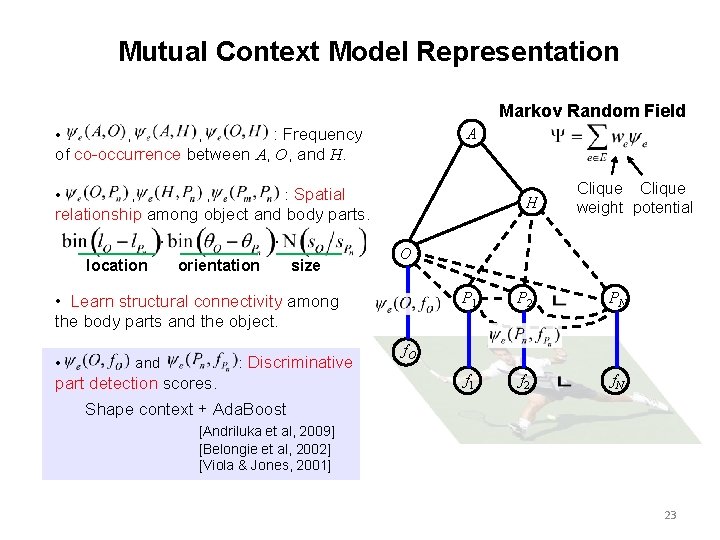
Mutual Context Model Representation Markov Random Field A : Frequency of co-occurrence between A, O, and H. • , , : Spatial , H relationship among object and body parts. location orientation size O • Learn structural connectivity among the body parts and the object. • : Discriminative and part detection scores. Clique weight potential P 1 P 2 PN f 1 f 2 f. N f. O Shape context + Ada. Boost [Andriluka et al, 2009] [Belongie et al, 2002] [Viola & Jones, 2001] 23
Outline • Background and Intuition • Mutual Context of Object and Human Pose § Model Representation § Model Learning § Model Inference • Experiments • Conclusion 24
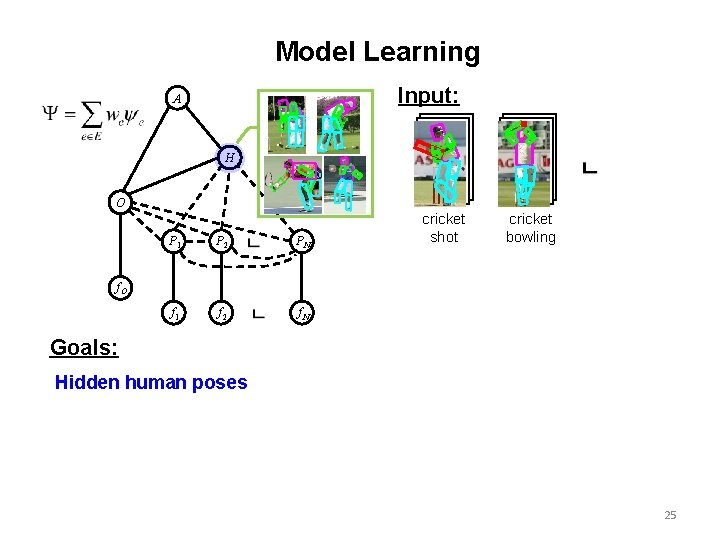
Model Learning Input: A H O P 1 P 2 PN f 1 f 2 f. N cricket shot cricket bowling f. O Goals: Hidden human poses 25
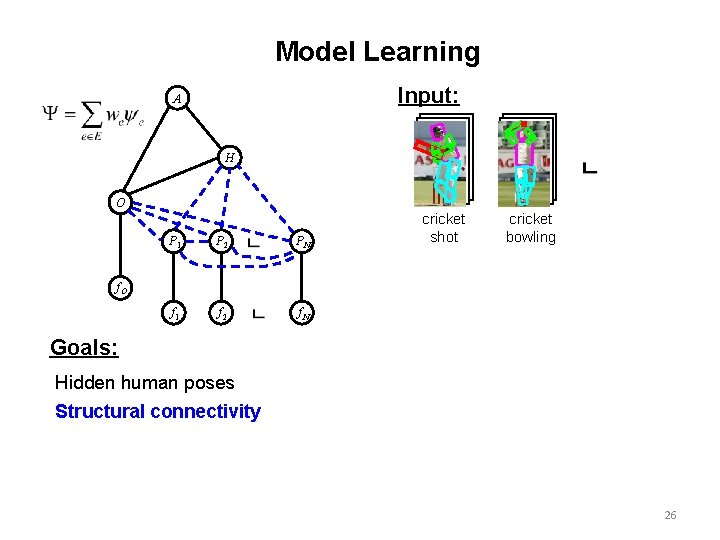
Model Learning Input: A H O P 1 P 2 PN f 1 f 2 f. N cricket shot cricket bowling f. O Goals: Hidden human poses Structural connectivity 26
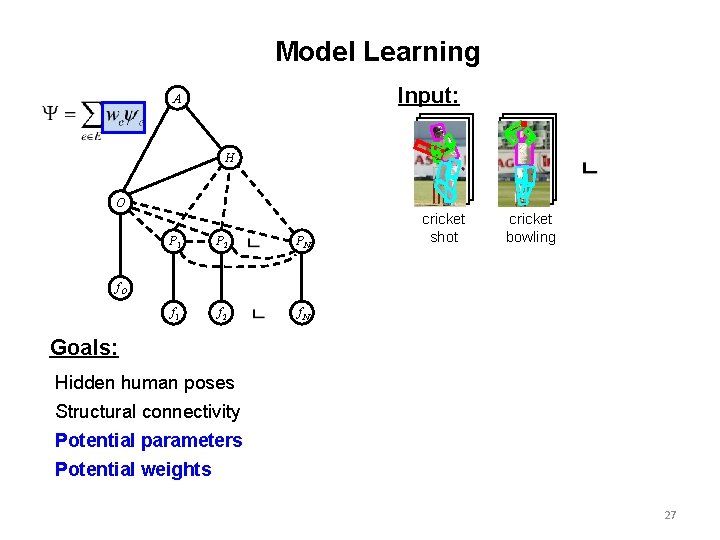
Model Learning Input: A H O P 1 P 2 PN f 1 f 2 f. N cricket shot cricket bowling f. O Goals: Hidden human poses Structural connectivity Potential parameters Potential weights 27
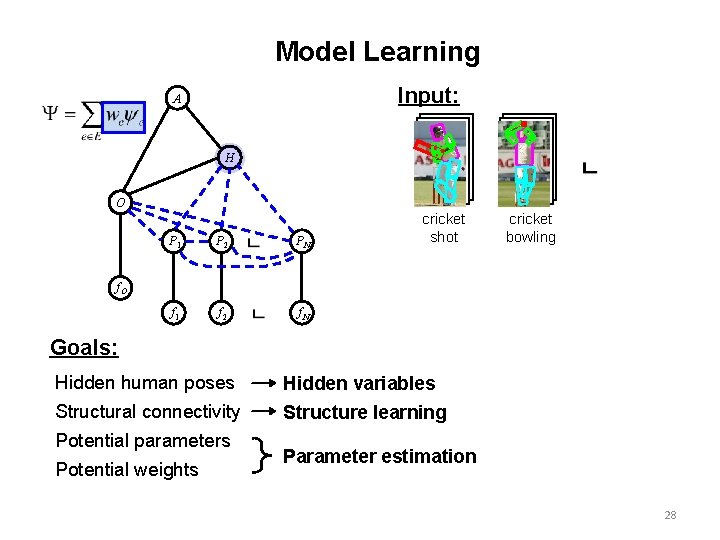
Model Learning Input: A H O P 1 P 2 PN f 1 f 2 f. N cricket shot cricket bowling f. O Goals: Hidden human poses Hidden variables Structural connectivity Structure learning Potential parameters Potential weights Parameter estimation 28
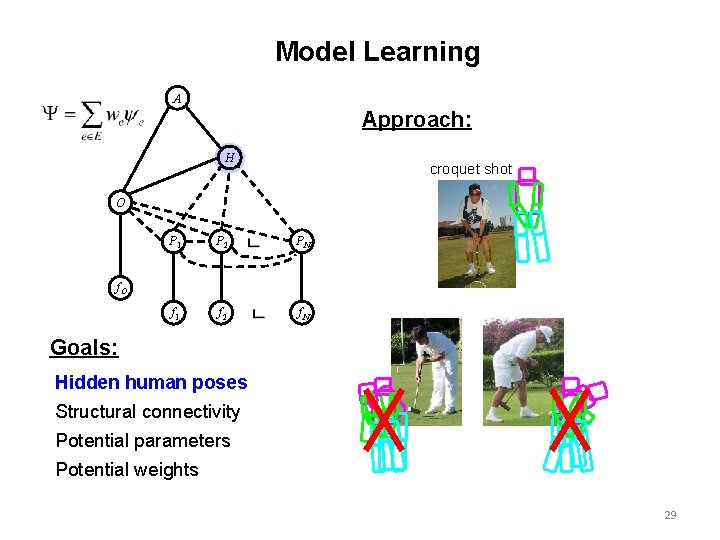
Model Learning A Approach: H croquet shot O P 1 P 2 PN f 1 f 2 f. N f. O Goals: Hidden human poses Structural connectivity Potential parameters Potential weights 29
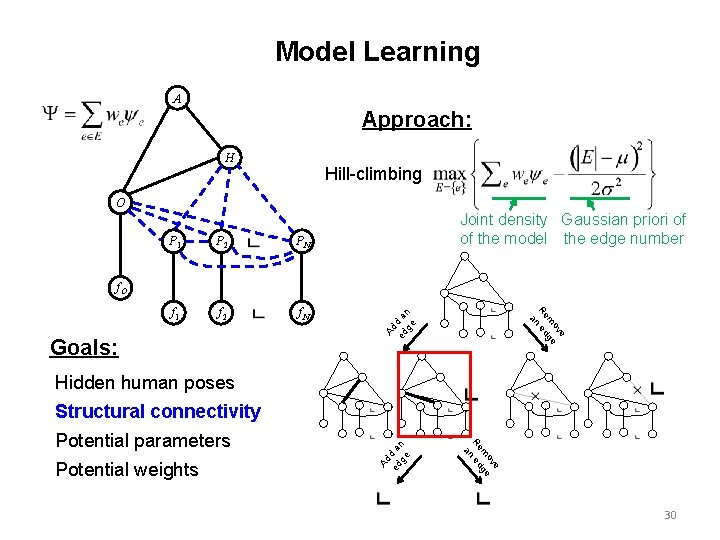
Model Learning A Approach: H Hill-climbing O P 1 P 2 PN f 1 f 2 f. N Joint density Gaussian priori of of the model the edge number f. O Ad ed d a ge n e ov m ge Re n ed a Goals: Hidden human poses Potential weights e ov m ge Re n ed a Potential parameters Ad ed d a ge n Structural connectivity 30
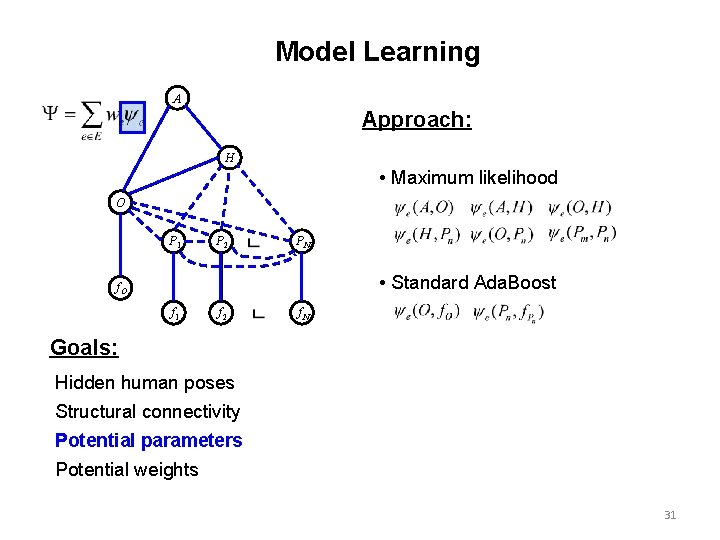
Model Learning A Approach: H • Maximum likelihood O P 1 P 2 PN • Standard Ada. Boost f. O f 1 f 2 f. N Goals: Hidden human poses Structural connectivity Potential parameters Potential weights 31
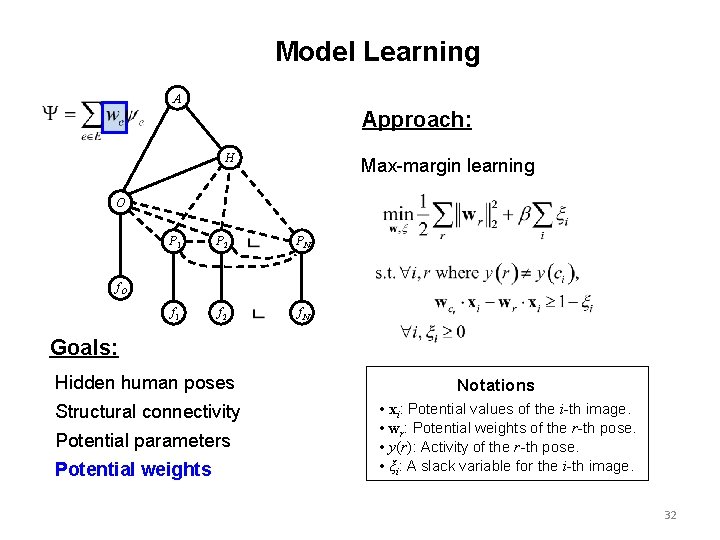
Model Learning A Approach: H Max-margin learning O P 1 P 2 PN f 1 f 2 f. N f. O Goals: Hidden human poses Structural connectivity Potential parameters Potential weights Notations • xi: Potential values of the i-th image. • wr: Potential weights of the r-th pose. • y(r): Activity of the r-th pose. • ξi: A slack variable for the i-th image. 32
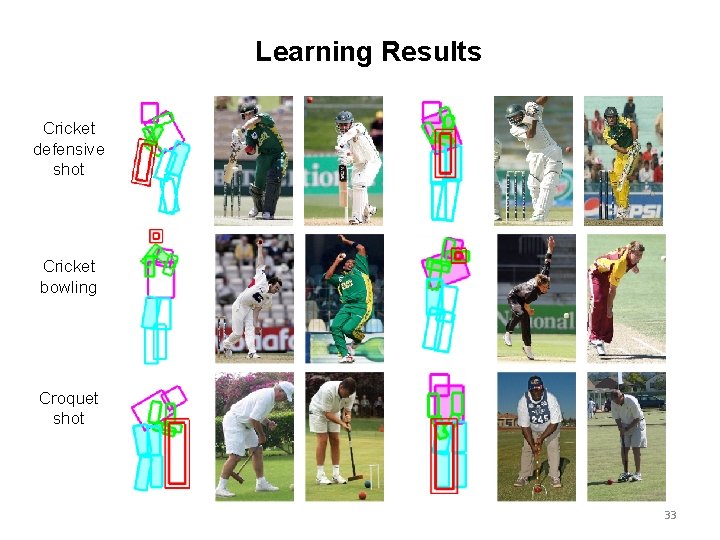
Learning Results Cricket defensive shot Cricket bowling Croquet shot 33
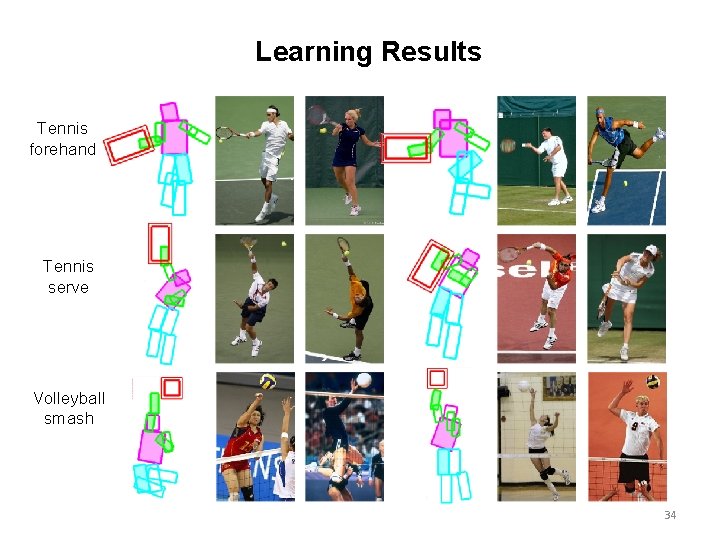
Learning Results Tennis forehand Tennis serve Volleyball smash 34
Outline • Background and Intuition • Mutual Context of Object and Human Pose § Model Representation § Model Learning § Model Inference • Experiments • Conclusion 35
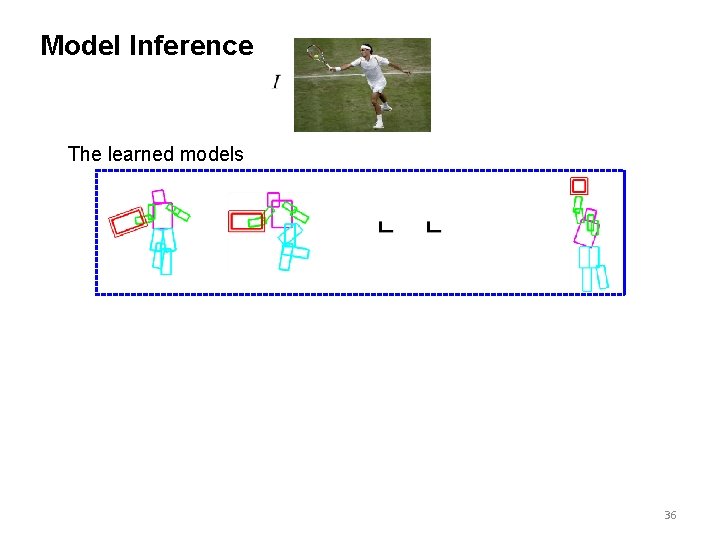
Model Inference The learned models 36
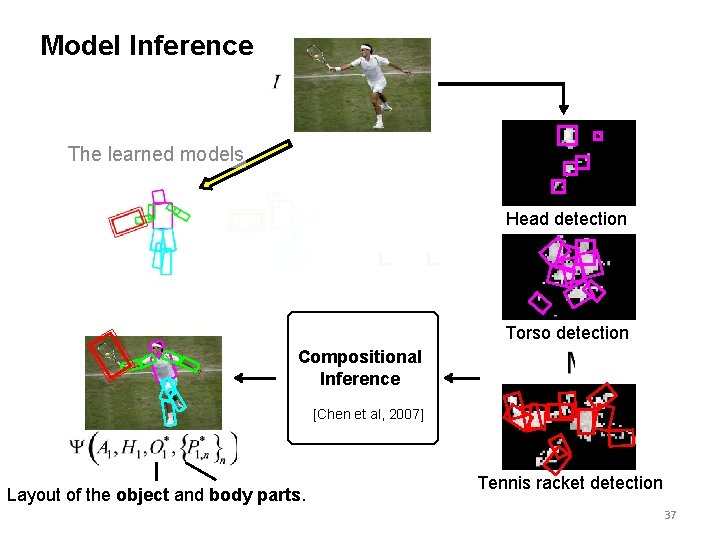
Model Inference The learned models Head detection Torso detection Compositional Inference [Chen et al, 2007] Layout of the object and body parts. Tennis racket detection 37
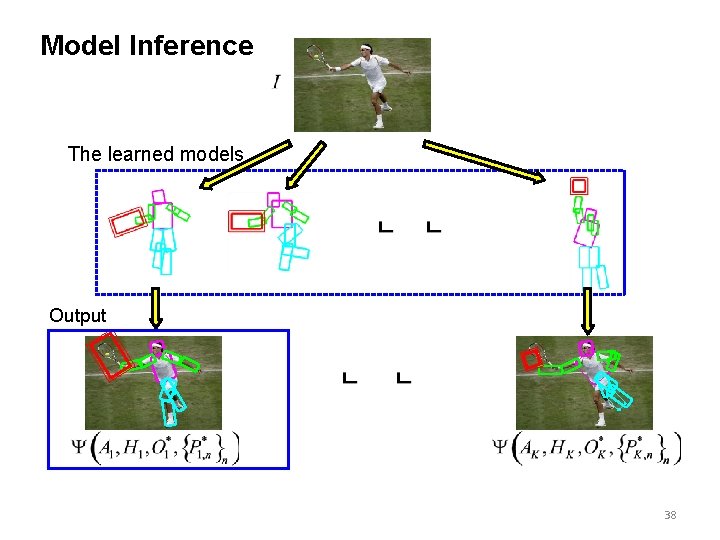
Model Inference The learned models Output 38
Outline • Background and Intuition • Mutual Context of Object and Human Pose § Model Representation § Model Learning § Model Inference • Experiments • Conclusion 39
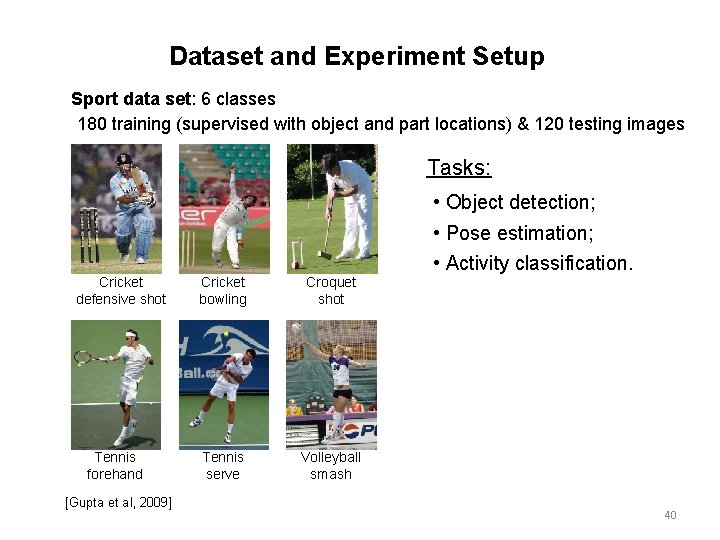
Dataset and Experiment Setup Sport data set: 6 classes 180 training (supervised with object and part locations) & 120 testing images Tasks: • Object detection; • Pose estimation; • Activity classification. Cricket defensive shot Tennis forehand [Gupta et al, 2009] Cricket bowling Croquet shot Tennis serve Volleyball smash 40
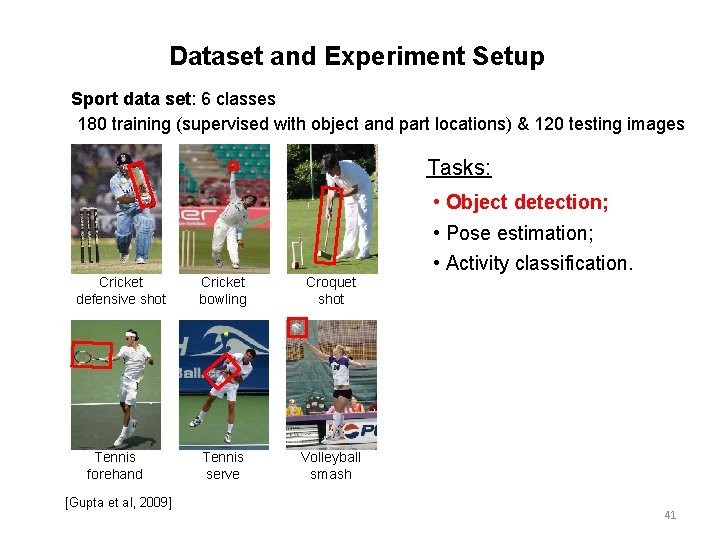
Dataset and Experiment Setup Sport data set: 6 classes 180 training (supervised with object and part locations) & 120 testing images Tasks: • Object detection; • Pose estimation; • Activity classification. Cricket defensive shot Tennis forehand [Gupta et al, 2009] Cricket bowling Croquet shot Tennis serve Volleyball smash 41
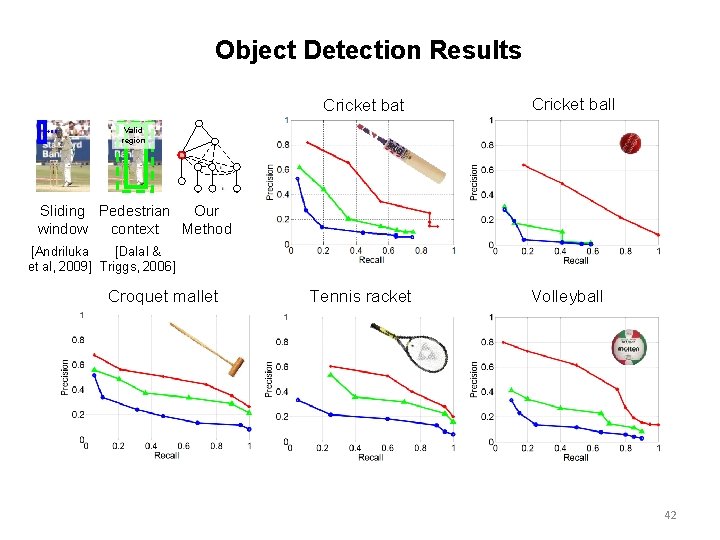
Object Detection Results Cricket bat Cricket ball Valid region Sliding Pedestrian Our window context Method [Andriluka [Dalal & et al, 2009] Triggs, 2006] Croquet mallet Tennis racket Volleyball 42
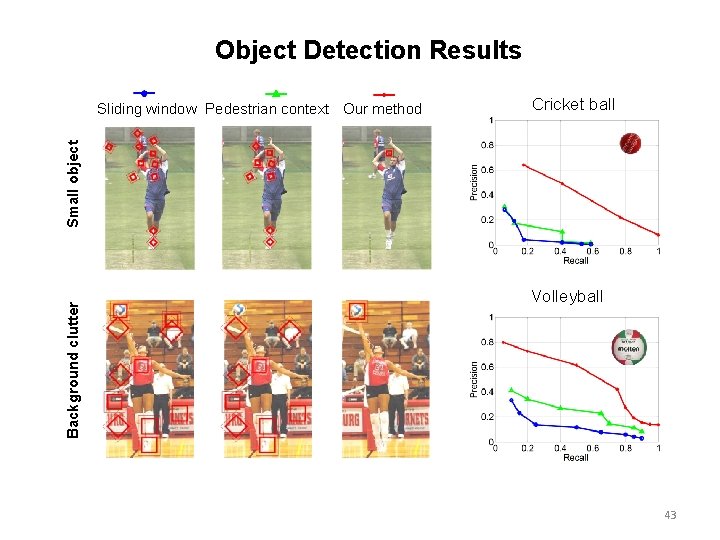
Object Detection Results Cricket ball Background clutter Small object Sliding window Pedestrian context Our method Volleyball 43 43
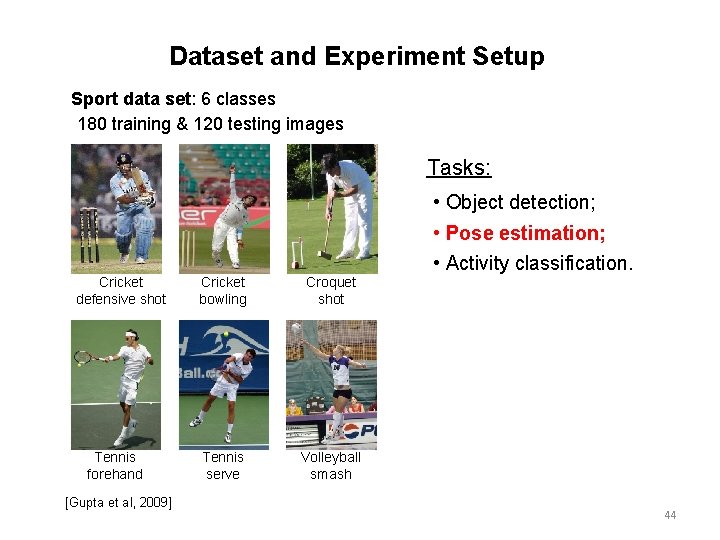
Dataset and Experiment Setup Sport data set: 6 classes 180 training & 120 testing images Tasks: • Object detection; • Pose estimation; • Activity classification. Cricket defensive shot Tennis forehand [Gupta et al, 2009] Cricket bowling Croquet shot Tennis serve Volleyball smash 44
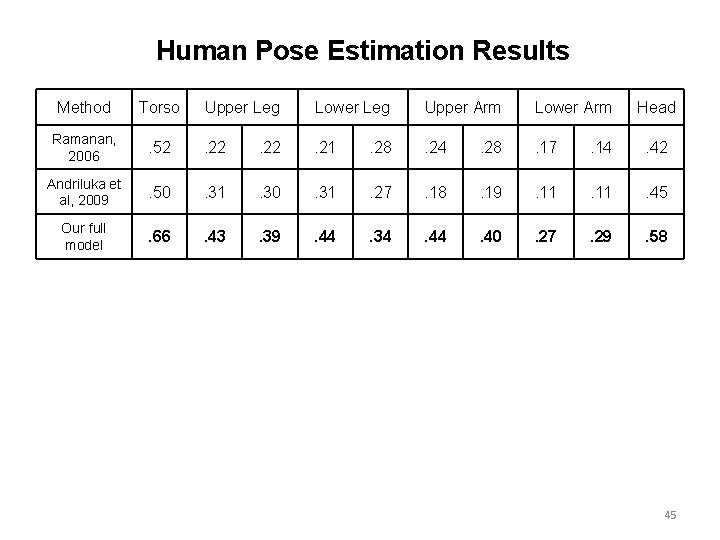
Human Pose Estimation Results Method Torso Upper Leg Lower Leg Upper Arm Lower Arm Ramanan, 2006 Head . 52 . 22 . 21 . 28 . 24 . 28 . 17 . 14 . 42 Andriluka et al, 2009 . 50 . 31 . 30 . 31 . 27 . 18 . 19 . 11 . 45 Our full model . 66 . 43 . 39 . 44 . 34 . 40 . 27 . 29 . 58 45
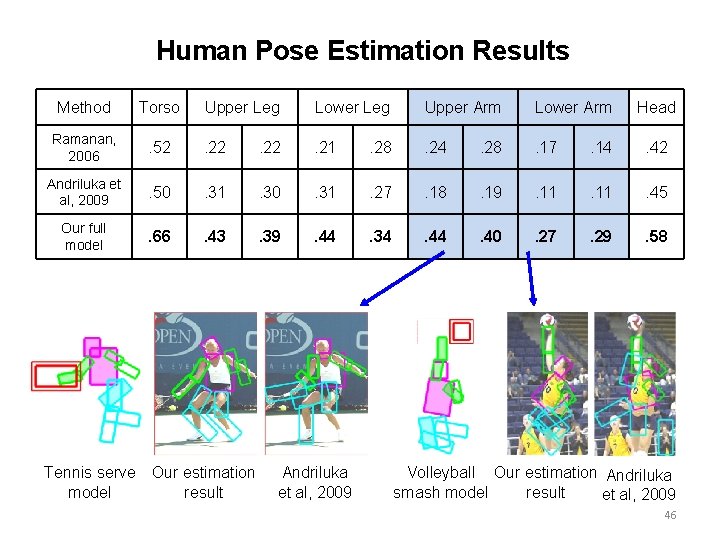
Human Pose Estimation Results Method Torso Upper Leg Lower Leg Upper Arm Lower Arm Ramanan, 2006 . 52 . 22 . 21 . 28 . 24 . 28 . 17 . 14 . 42 Andriluka et al, 2009 . 50 . 31 . 30 . 31 . 27 . 18 . 19 . 11 . 45 Our full model . 66 . 43 . 39 . 44 . 34 . 40 . 27 . 29 . 58 Tennis serve model Our estimation result Andriluka et al, 2009 Head Volleyball Our estimation Andriluka smash model result et al, 2009 46
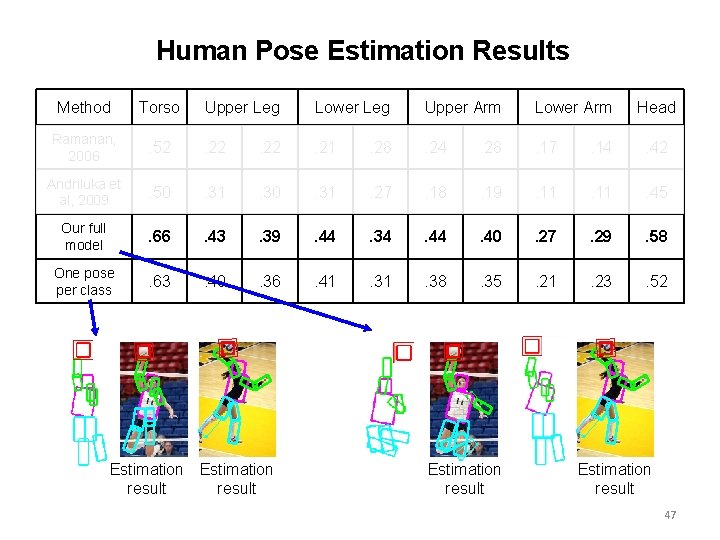
Human Pose Estimation Results Method Torso Upper Leg Lower Leg Upper Arm Lower Arm Ramanan, 2006 . 52 . 22 . 21 . 28 . 24 . 28 . 17 . 14 . 42 Andriluka et al, 2009 . 50 . 31 . 30 . 31 . 27 . 18 . 19 . 11 . 45 Our full model . 66 . 43 . 39 . 44 . 34 . 40 . 27 . 29 . 58 One pose per class . 63 . 40 . 36 . 41 . 38 . 35 . 21 . 23 . 52 Estimation result Head Estimation result 47
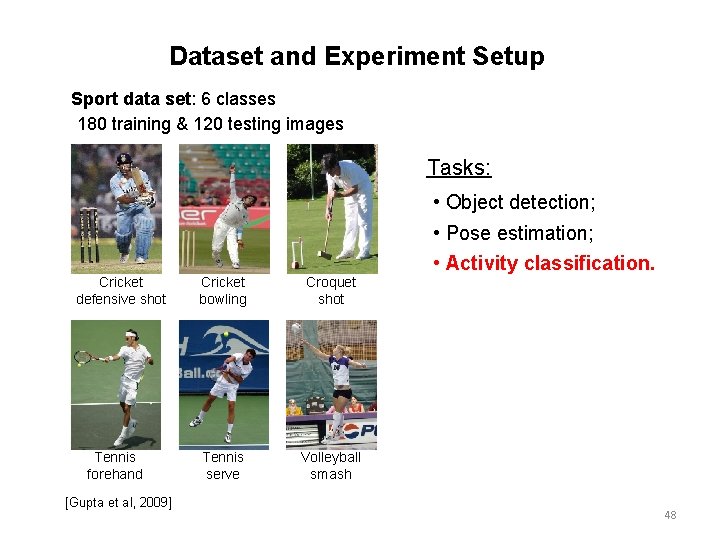
Dataset and Experiment Setup Sport data set: 6 classes 180 training & 120 testing images Tasks: • Object detection; • Pose estimation; • Activity classification. Cricket defensive shot Tennis forehand [Gupta et al, 2009] Cricket bowling Croquet shot Tennis serve Volleyball smash 48
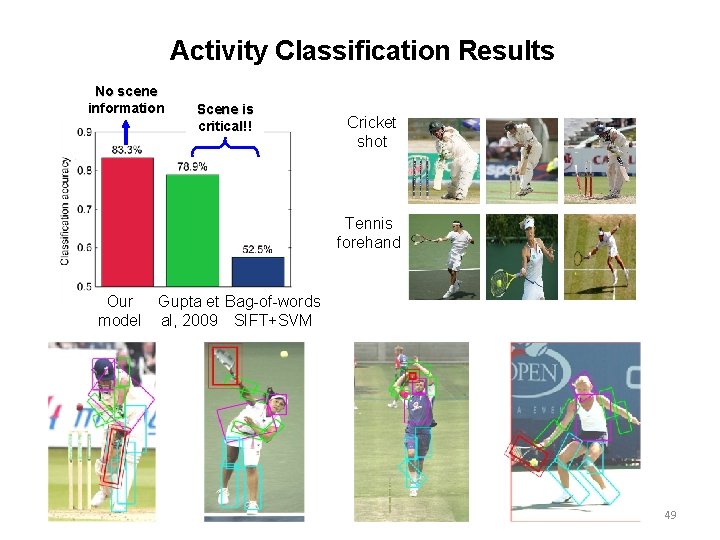
Activity Classification Results No scene information Scene is critical!! Cricket shot Tennis forehand Our model Gupta et Bag-of-words al, 2009 SIFT+SVM 49
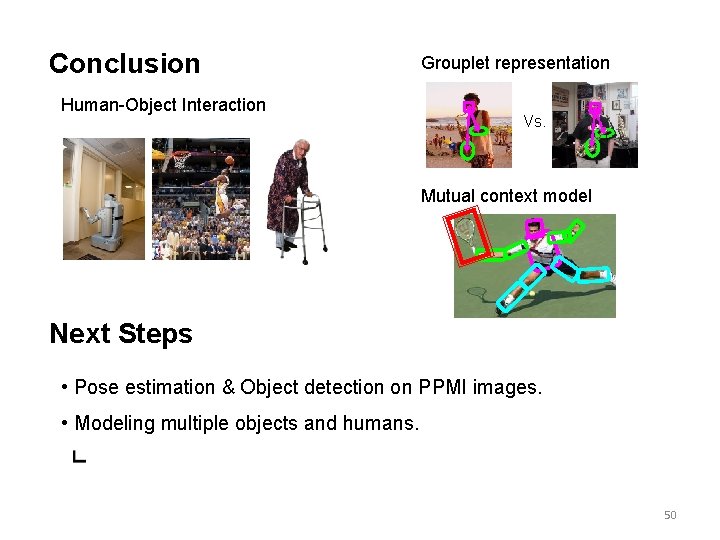
Conclusion Human-Object Interaction Grouplet representation Vs. Mutual context model Next Steps • Pose estimation & Object detection on PPMI images. • Modeling multiple objects and humans. 50
Acknowledgment • Stanford Vision Lab reviewers: – Barry Chai (1985 -2010) – Juan Carlos Niebles – Hao Su • Silvio Savarese, U. Michigan • Anonymous reviewers 51
- Slides: 51