
Making Order from Chaos Using Metagenome Data as
- Slides: 66
Making Order from Chaos: Using Metagenome Data as Traits in Individuals and as Markers in Entire Ecosystems“ Andrew K Benson W. W. Marshall Distinguished Professor of Biotechnology Director, Core for Applied Genomics and Ecology Professor, Dept. of Food Science University of Nebraska
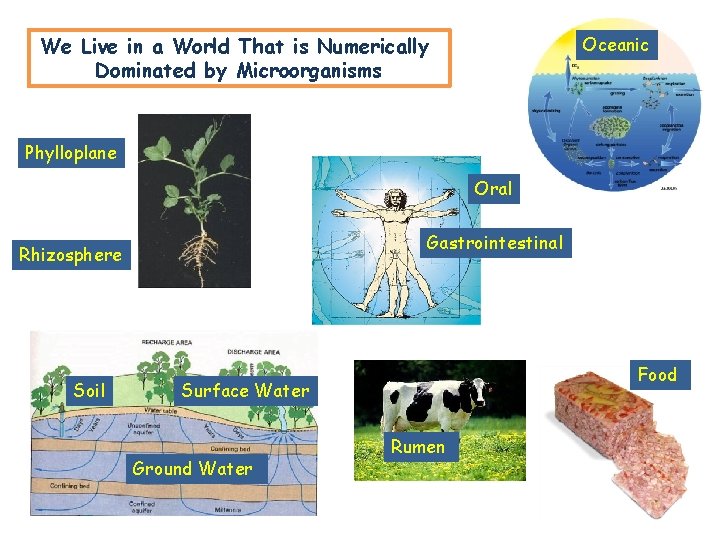
We Live in a World That is Numerically Dominated by Microorganisms Oceanic Phylloplane Oral Gastrointestinal Rhizosphere Soil Food Surface Water Ground Water Rumen
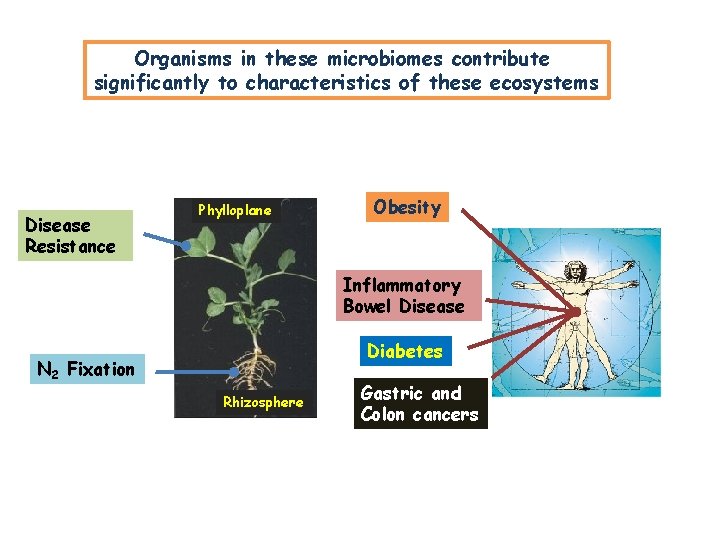
Organisms in these microbiomes contribute significantly to characteristics of these ecosystems Disease Resistance Phylloplane Obesity Inflammatory Bowel Disease Diabetes N 2 Fixation Rhizosphere Gastric and Colon cancers
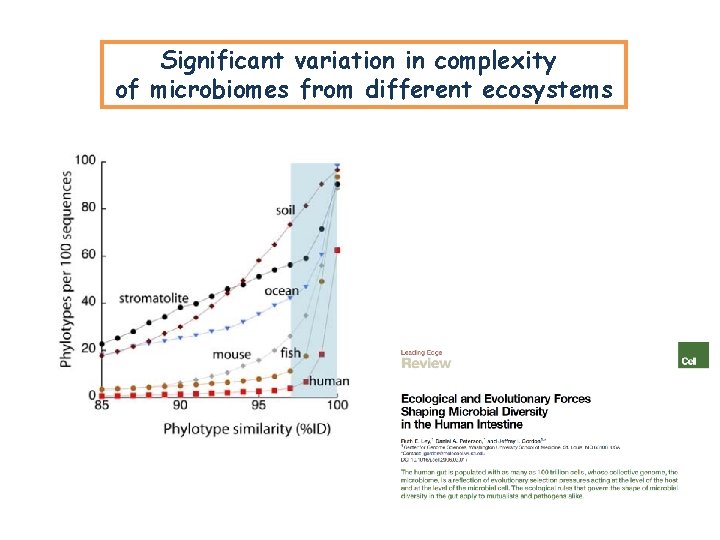
Significant variation in complexity of microbiomes from different ecosystems
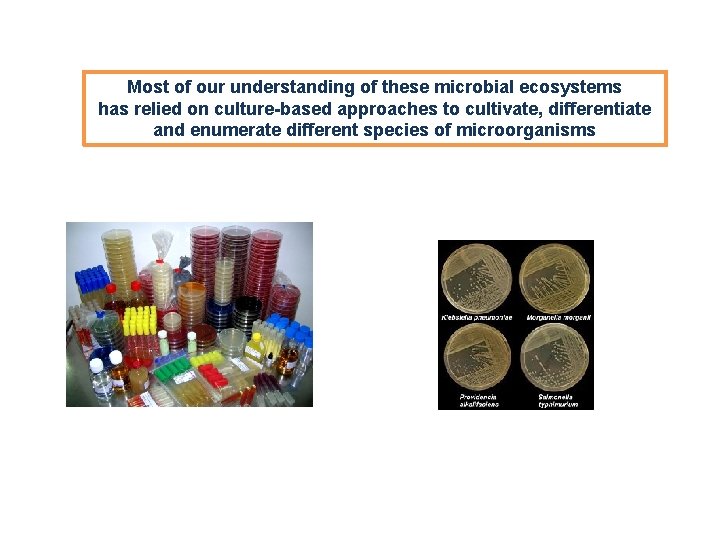
Most of our understanding of these microbial ecosystems has relied on culture-based approaches to cultivate, differentiate and enumerate different species of microorganisms
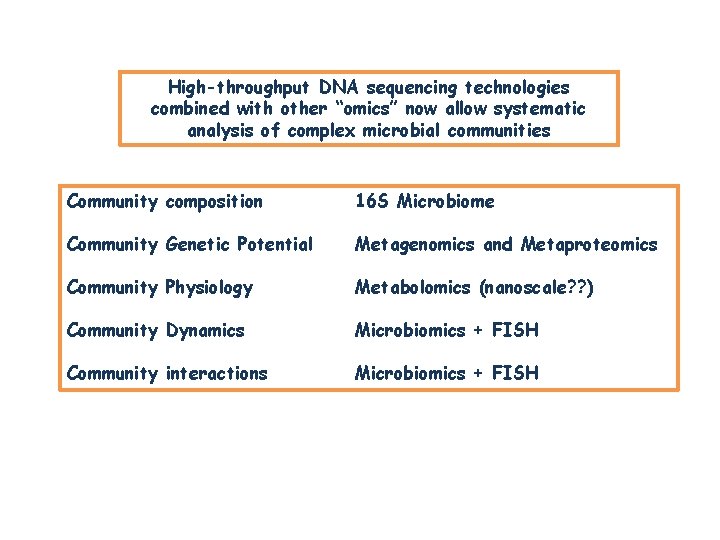
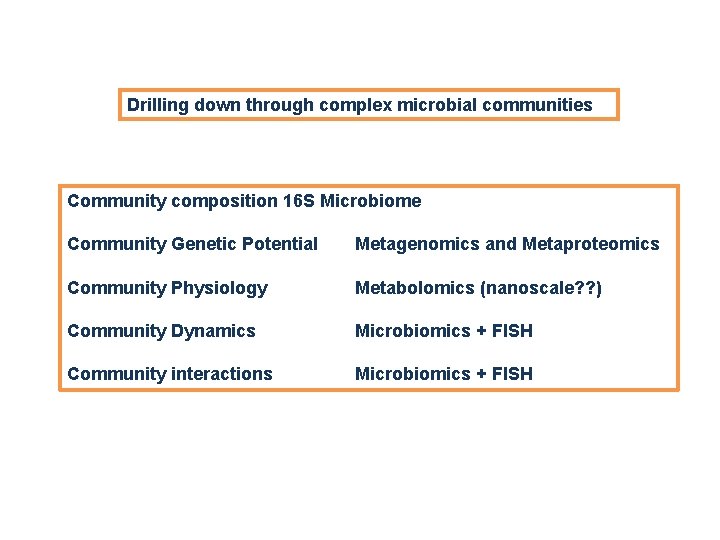
High-throughput DNA sequencing technologies combined with other “omics” now allow systematic analysis of complex microbial communities Community composition 16 S Microbiome Community Genetic Potential Metagenomics and Metaproteomics Community Physiology Metabolomics (nanoscale? ? ) Community Dynamics Microbiomics + FISH Community interactions Microbiomics + FISH
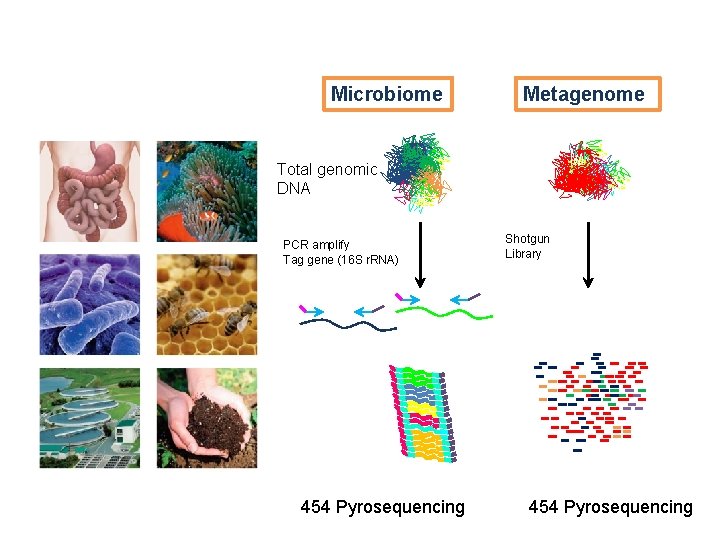
Microbiome Metagenome Total genomic DNA PCR amplify Tag gene (16 S r. RNA) 454 Pyrosequencing Shotgun Library 454 Pyrosequencing
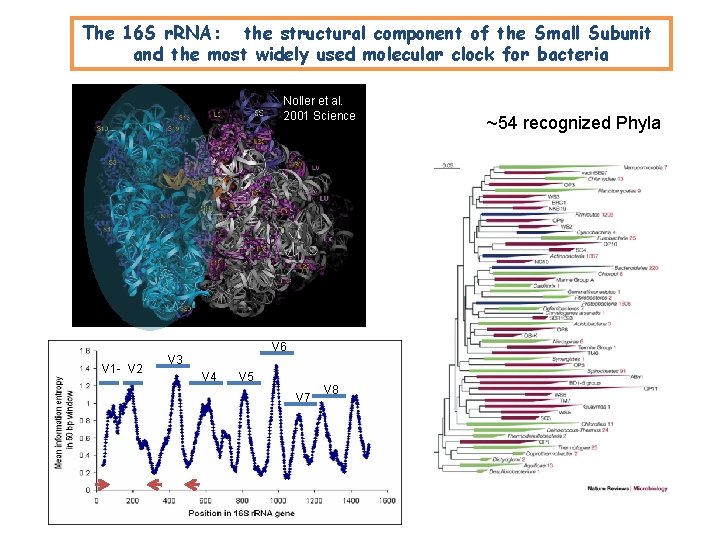
The 16 S r. RNA: the structural component of the Small Subunit and the most widely used molecular clock for bacteria Noller et al. 2001 Science V 1 - V 2 V 6 V 3 V 4 V 5 V 7 V 8 ~54 recognized Phyla
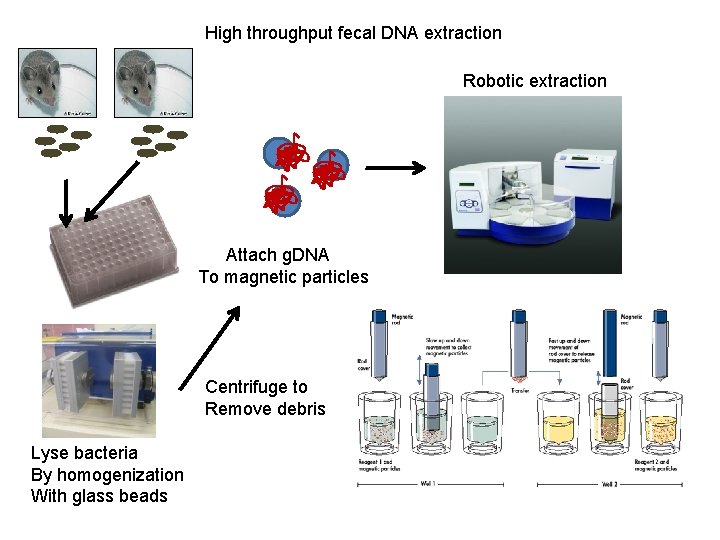
High throughput fecal DNA extraction Robotic extraction Attach g. DNA To magnetic particles Centrifuge to Remove debris Lyse bacteria By homogenization With glass beads
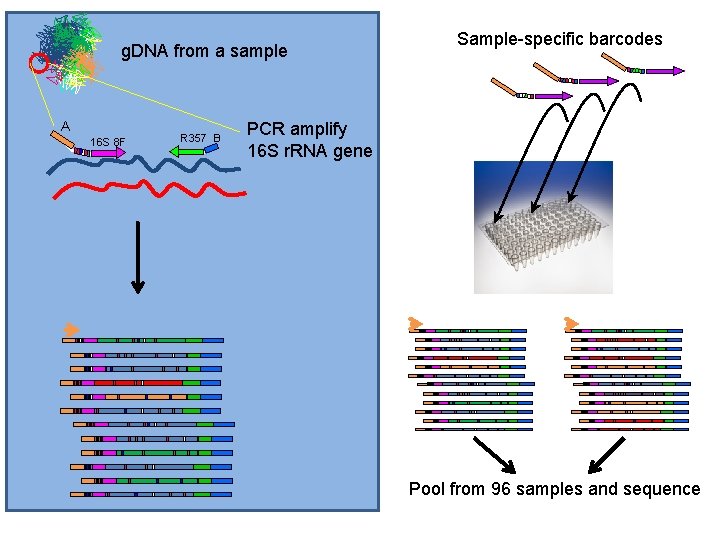
g. DNA from a sample A 16 S 8 F R 357 B Sample-specific barcodes PCR amplify 16 S r. RNA gene Pool from 96 samples and sequence
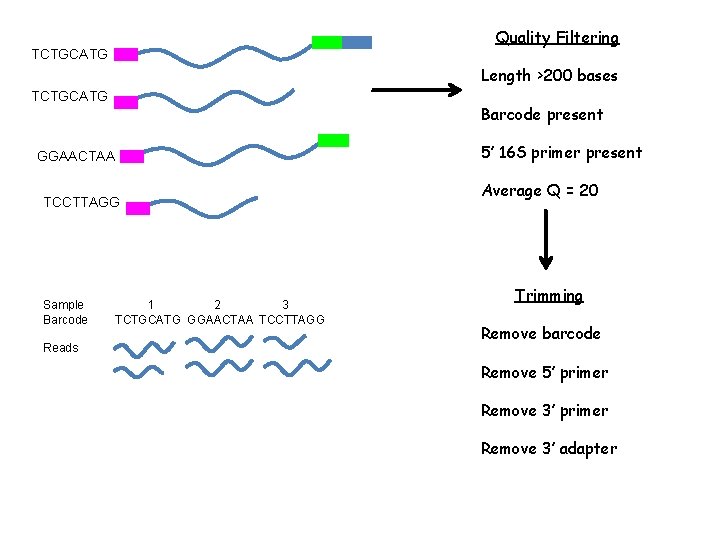
Quality Filtering TCTGCATG Length >200 bases TCTGCATG Barcode present 5’ 16 S primer present GGAACTAA TCCTTAGG Sample Barcode Reads 1 2 3 TCTGCATG GGAACTAA TCCTTAGG Average Q = 20 Trimming Remove barcode Remove 5’ primer Remove 3’ adapter
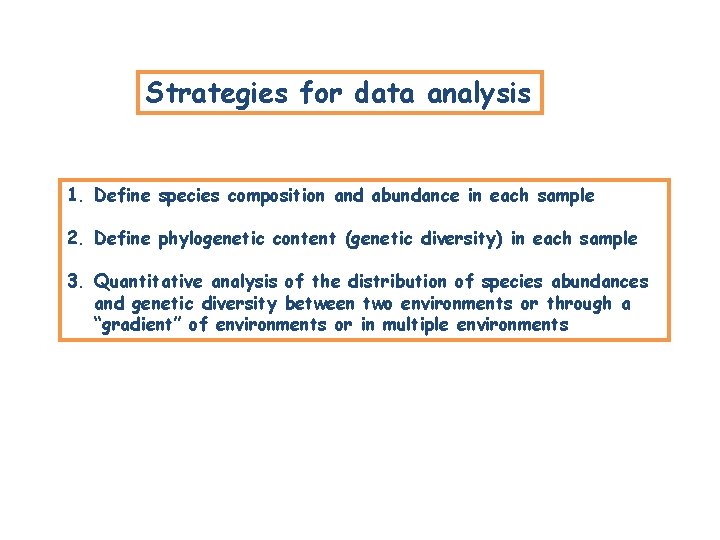
Strategies for data analysis 1. Define species composition and abundance in each sample 2. Define phylogenetic content (genetic diversity) in each sample 3. Quantitative analysis of the distribution of species abundances and genetic diversity between two environments or through a “gradient” of environments or in multiple environments
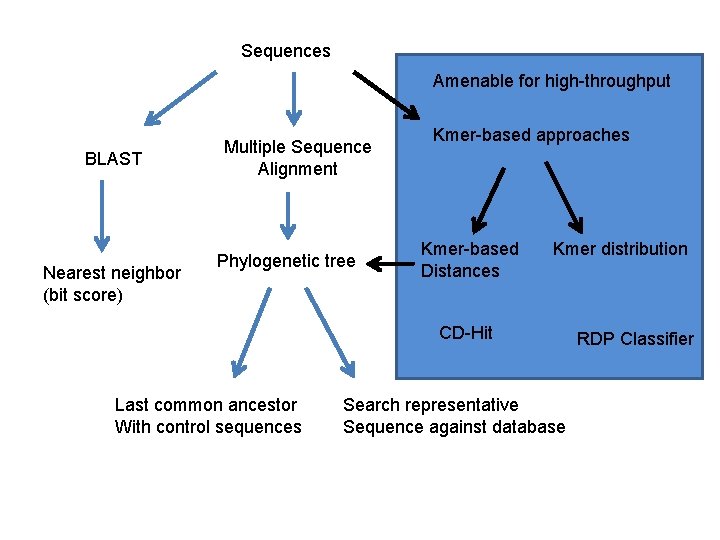
Sequences Amenable for high-throughput BLAST Nearest neighbor (bit score) Multiple Sequence Alignment Phylogenetic tree Kmer-based approaches Kmer-based Distances Kmer distribution CD-Hit Last common ancestor With control sequences Search representative Sequence against database RDP Classifier
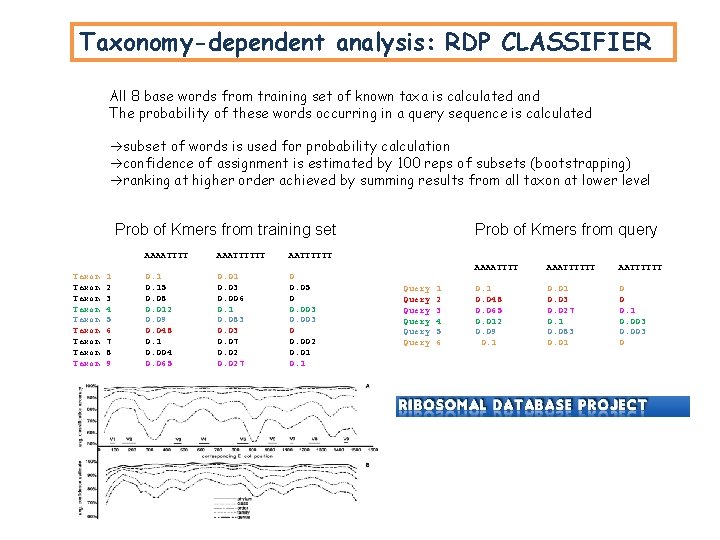
Taxonomy-dependent analysis: RDP CLASSIFIER All 8 base words from training set of known taxa is calculated and The probability of these words occurring in a query sequence is calculated subset of words is used for probability calculation confidence of assignment is estimated by 100 reps of subsets (bootstrapping) ranking at higher order achieved by summing results from all taxon at lower level Prob of Kmers from training set Taxon Taxon Taxon 1 2 3 4 5 6 7 8 9 AAAATTTTTT 0. 15 0. 08 0. 012 0. 09 0. 048 0. 1 0. 004 0. 065 0. 01 0. 03 0. 006 0. 1 0. 083 0. 07 0. 027 0 0. 05 0 0. 003 0 0. 002 0. 01 0. 1 Prob of Kmers from query Query Query 1 2 3 4 5 6 AAAATTTTTT 0. 1 0. 048 0. 065 0. 012 0. 09 0. 1 0. 03 0. 027 0. 1 0. 083 0. 01 0 0 0. 1 0. 003 0
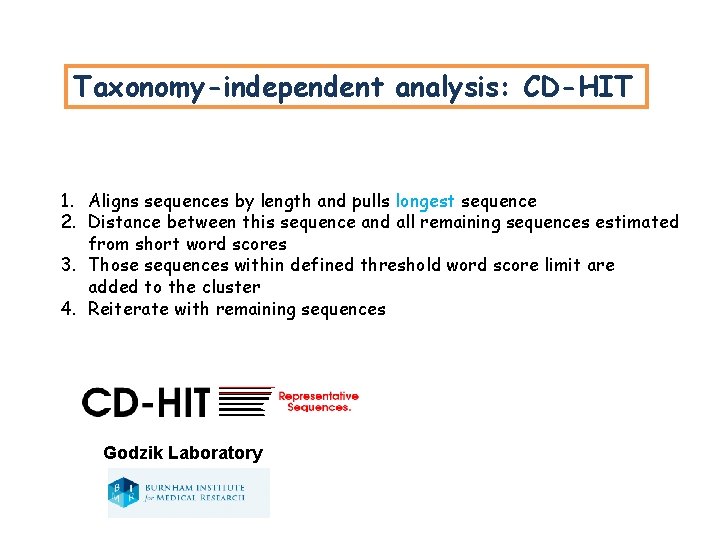
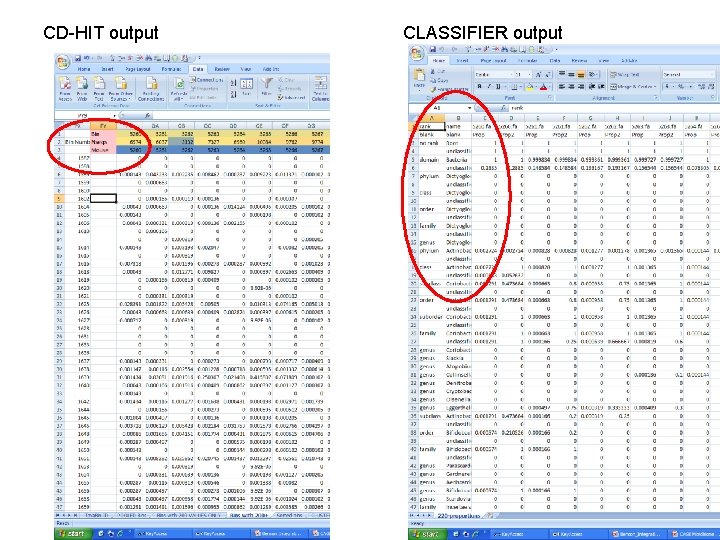
Taxonomy-independent analysis: CD-HIT 1. Aligns sequences by length and pulls longest sequence 2. Distance between this sequence and all remaining sequences estimated from short word scores 3. Those sequences within defined threshold word score limit are added to the cluster 4. Reiterate with remaining sequences Godzik Laboratory
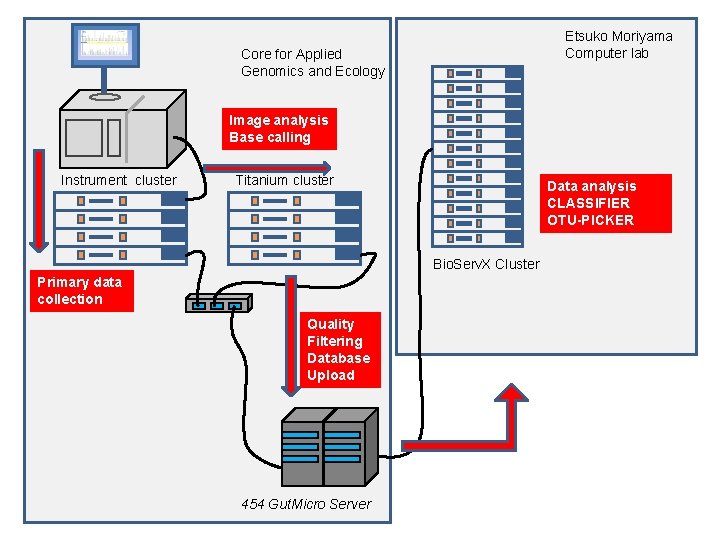
Etsuko Moriyama Computer lab Core for Applied Genomics and Ecology Image analysis Base calling Instrument cluster Titanium cluster Data analysis CLASSIFIER OTU-PICKER Bio. Serv. X Cluster Primary data collection Quality Filtering Database Upload 454 Gut. Micro Server
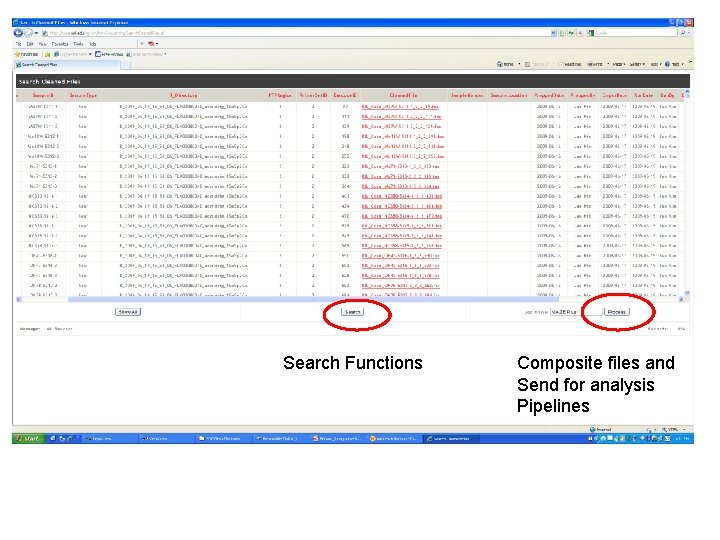
Search Functions Composite files and Send for analysis Pipelines
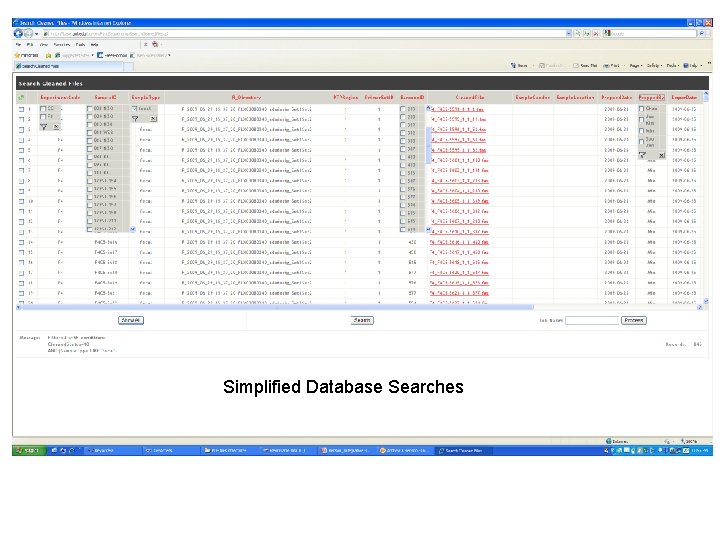
Simplified Database Searches
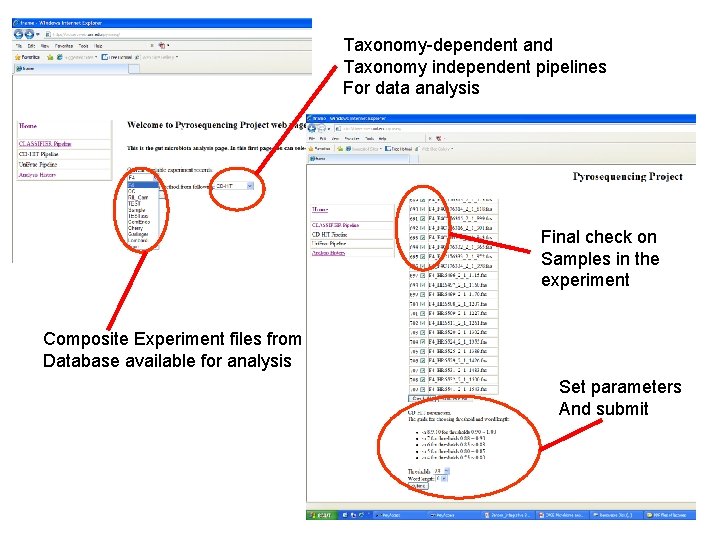
Taxonomy-dependent and Taxonomy independent pipelines For data analysis Final check on Samples in the experiment Composite Experiment files from Database available for analysis Set parameters And submit
CD-HIT output CLASSIFIER output
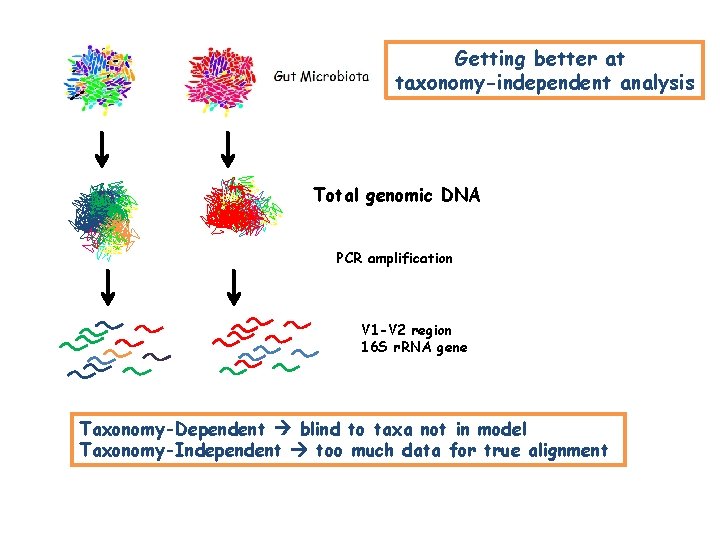
Getting better at taxonomy-independent analysis Total genomic DNA PCR amplification V 1 -V 2 region 16 S r. RNA gene Taxonomy-Dependent blind to taxa not in model Taxonomy-Independent too much data for true alignment
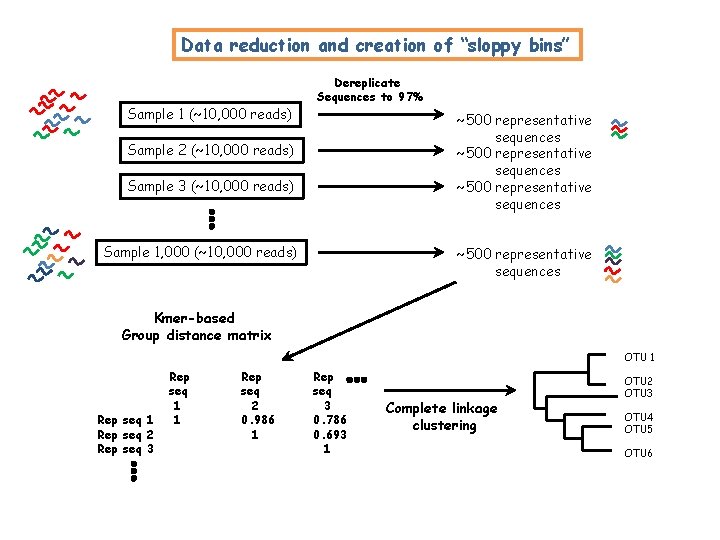
Data reduction and creation of “sloppy bins” Sample 1 (~10, 000 reads) Dereplicate Sequences to 97% ~500 representative sequences Sample 2 (~10, 000 reads) Sample 3 (~10, 000 reads) Sample 1, 000 (~10, 000 reads) ~500 representative sequences Kmer-based Group distance matrix OTU 1 Rep seq 2 Rep seq 3 Rep seq 1 1 Rep seq 2 0. 986 1 Rep seq 3 0. 786 0. 693 1 Complete linkage clustering OTU 2 OTU 3 OTU 4 OTU 5 OTU 6
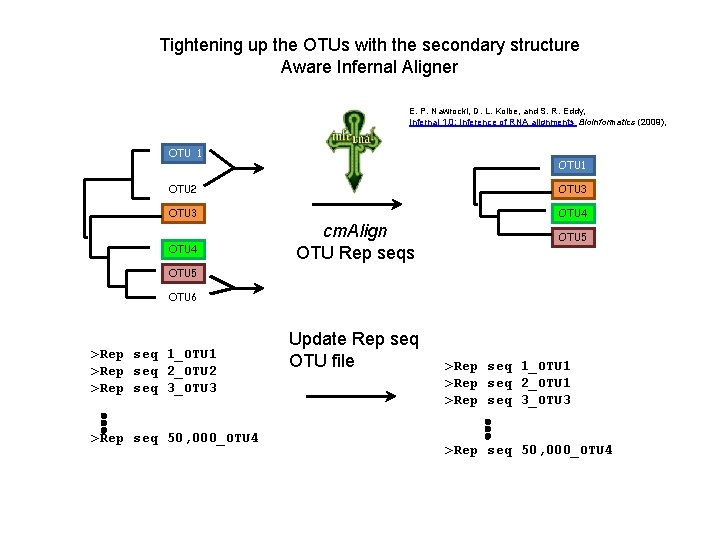
Tightening up the OTUs with the secondary structure Aware Infernal Aligner E. P. Nawrocki, D. L. Kolbe, and S. R. Eddy, Infernal 1. 0: Inference of RNA alignments Bioinformatics (2009), OTU 1 OTU 2 OTU 3 OTU 4 cm. Align OTU Rep seqs OTU 5 OTU 6 >Rep seq 1_OTU 1 >Rep seq 2_OTU 2 >Rep seq 3_OTU 3 >Rep seq 50, 000_OTU 4 Update Rep seq OTU file >Rep seq 1_OTU 1 >Rep seq 2_OTU 1 >Rep seq 3_OTU 3 >Rep seq 50, 000_OTU 4
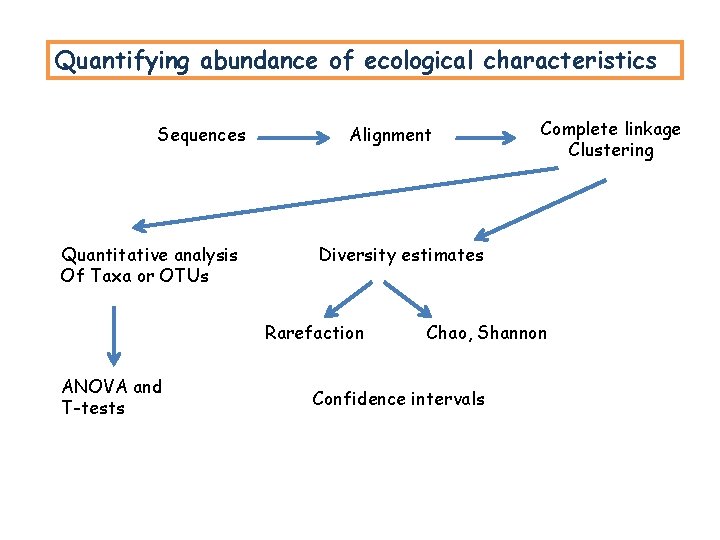
Quantifying abundance of ecological characteristics Sequences Quantitative analysis Of Taxa or OTUs Alignment Diversity estimates Rarefaction ANOVA and T-tests Complete linkage Clustering Chao, Shannon Confidence intervals
From guts to greens Applications
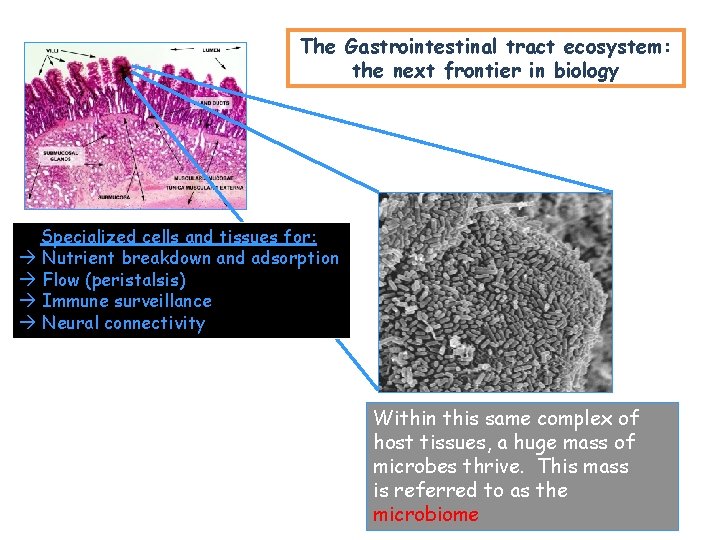
The Gastrointestinal tract ecosystem: the next frontier in biology Specialized cells and tissues for: Nutrient breakdown and adsorption Flow (peristalsis) Immune surveillance Neural connectivity Within this same complex of host tissues, a huge mass of microbes thrive. This mass is referred to as the microbiome
How complex is the microbiome Population density: 106 cells/ml in the ileum 1013 cells/gram in the colon Species richness: 5 major phyla, 1, 800 genera, 2, 000 -10, 000 species of bacteria Genetic coding content: 20 -30 billion bases (10 times the human content) Highly variable between individuals: extensive variation at the species/strain level The microbiome essentially acts as a metabolic organ, encoding pathways for: Nutrient breakdown, adsorption, utilization Signaling within the microbiota and to the host Immune stimulation/suppression…just to name a few
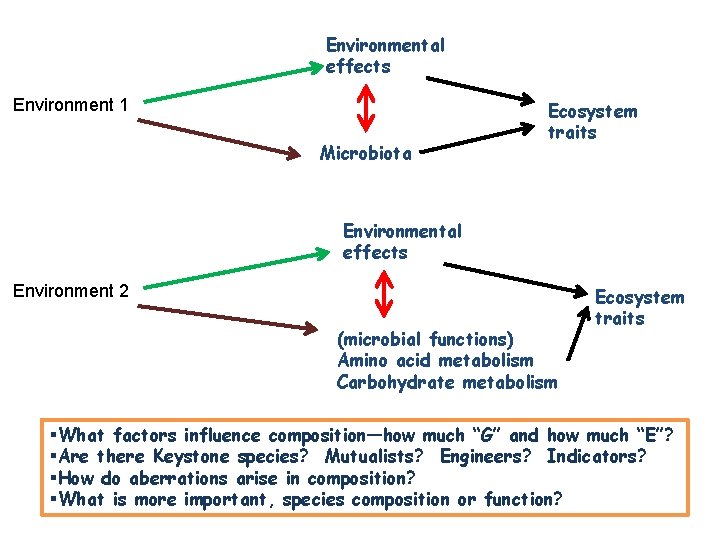
Fundamental questions about composition of the gut microbiome 1. Sterile at birth rapidly colonized from maternal environment 2. Successive waves of colonization stabilizes to climax community after weaning 3. Some resistance to perturbation memory? §What factors influence composition—how much “G” and how much “E”? §Are there Keystone species? Mutualists? Engineers? §How do aberrations arise in composition? §What is more important, species composition or function?
Health Disease Heart disease Obesity Cancer Diabetes IBD
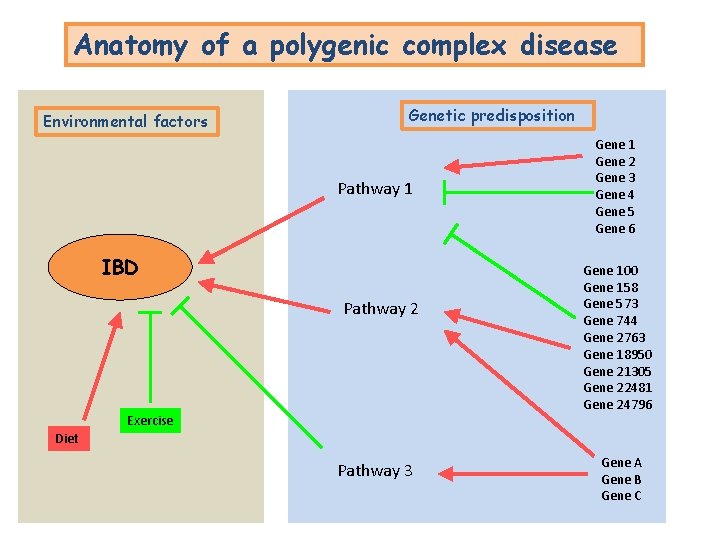
Anatomy of a polygenic complex disease Environmental factors Genetic predisposition Pathway 1 IBD Pathway 2 Exercise Gene 1 Gene 2 Gene 3 Gene 4 Gene 5 Gene 6 Gene 100 Gene 158 Gene 573 Gene 744 Gene 2763 Gene 18950 Gene 21305 Gene 22481 Gene 24796 Diet Pathway 3 Gene A Gene B Gene C
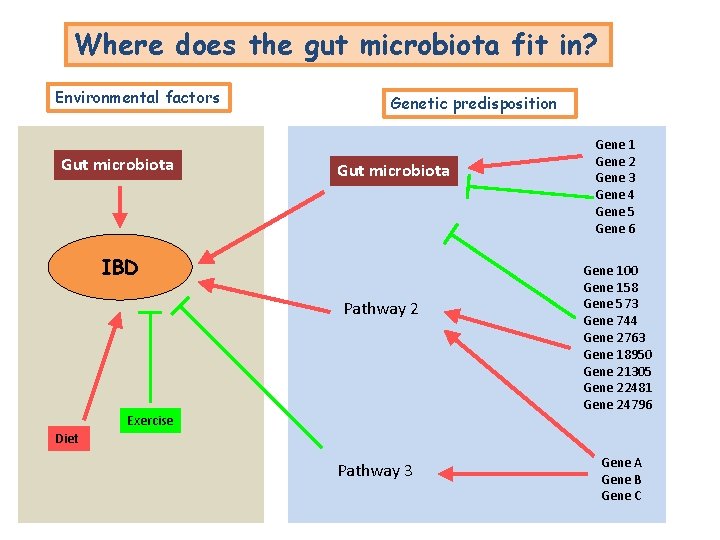
Where does the gut microbiota fit in? Environmental factors Gut microbiota Genetic predisposition Gut microbiota IBD Pathway 2 Exercise Gene 1 Gene 2 Gene 3 Gene 4 Gene 5 Gene 6 Gene 100 Gene 158 Gene 573 Gene 744 Gene 2763 Gene 18950 Gene 21305 Gene 22481 Gene 24796 Diet Pathway 3 Gene A Gene B Gene C
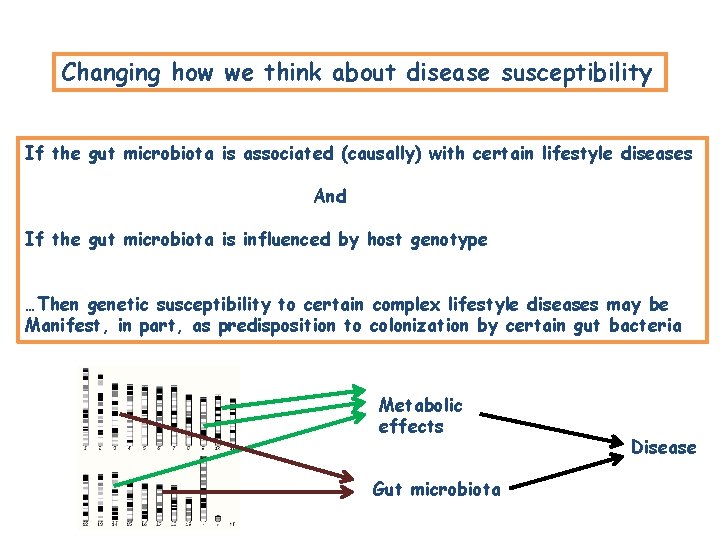
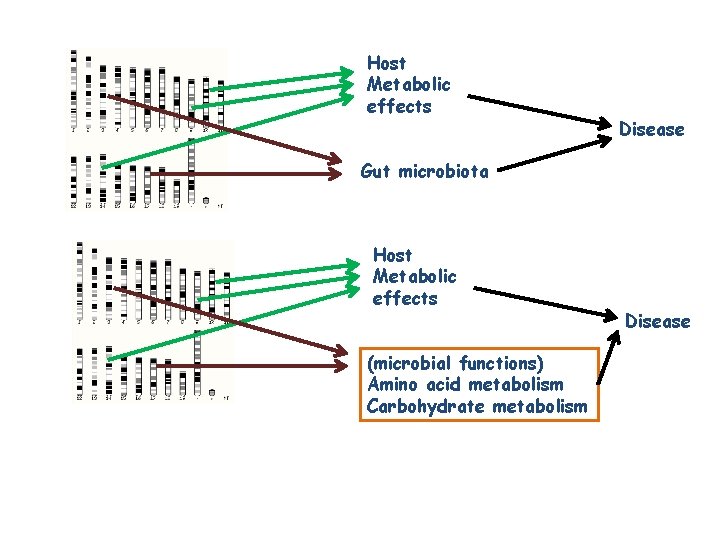
Changing how we think about disease susceptibility If the gut microbiota is associated (causally) with certain lifestyle diseases And If the gut microbiota is influenced by host genotype …Then genetic susceptibility to certain complex lifestyle diseases may be Manifest, in part, as predisposition to colonization by certain gut bacteria Metabolic effects Gut microbiota Disease
Systematic approaches to measure the degree of genotypic influence at the individual level 1. Selective Breeding Models 2. Genetic mapping models Artificial selection models If host genotype has significant influence… Then we should be able to observe significant effects of host genotype on microbiome composition in selective breeding experiments
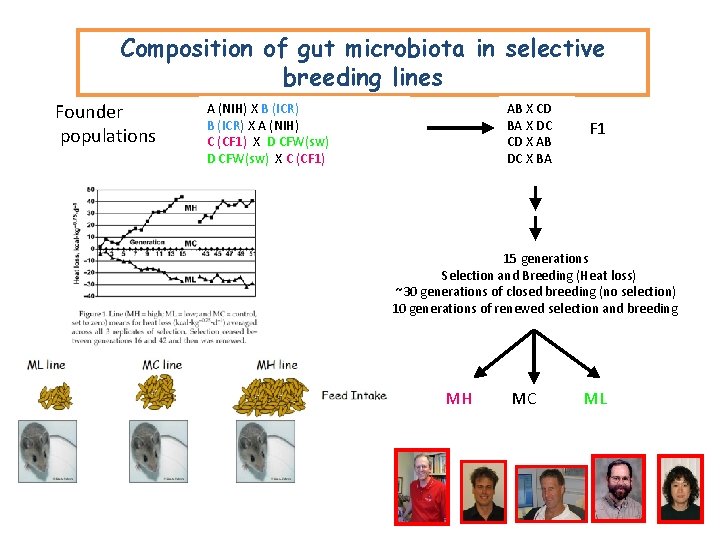
Composition of gut microbiota in selective breeding lines Founder populations A (NIH) X B (ICR) X A (NIH) C (CF 1) X D CFW(sw) X C (CF 1) AB X CD BA X DC CD X AB DC X BA F 1 15 generations Selection and Breeding (Heat loss) ~30 generations of closed breeding (no selection) 10 generations of renewed selection and breeding MH MC ML
Artificial selection models Multiple generations of selective mating Host genetic diversity high decreased genetic diversity If host genotype has significant influence… Then we should observe significant effects of artificial selection on microbiome composition
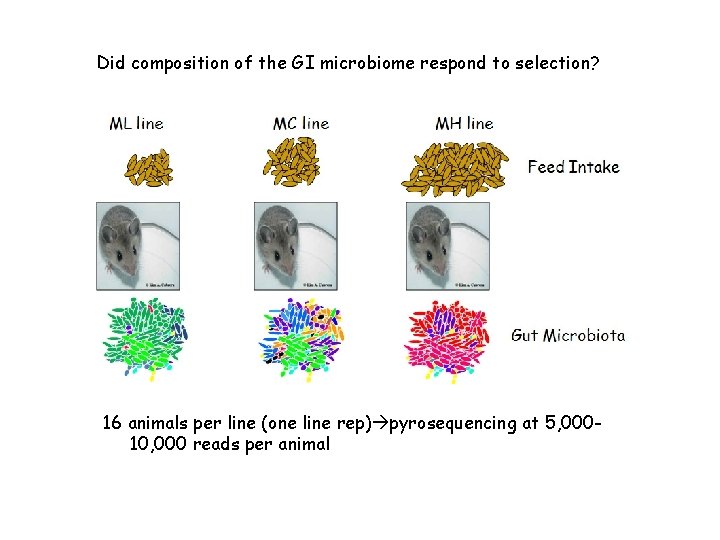
Did composition of the GI microbiome respond to selection? 16 animals per line (one line rep) pyrosequencing at 5, 00010, 000 reads per animal
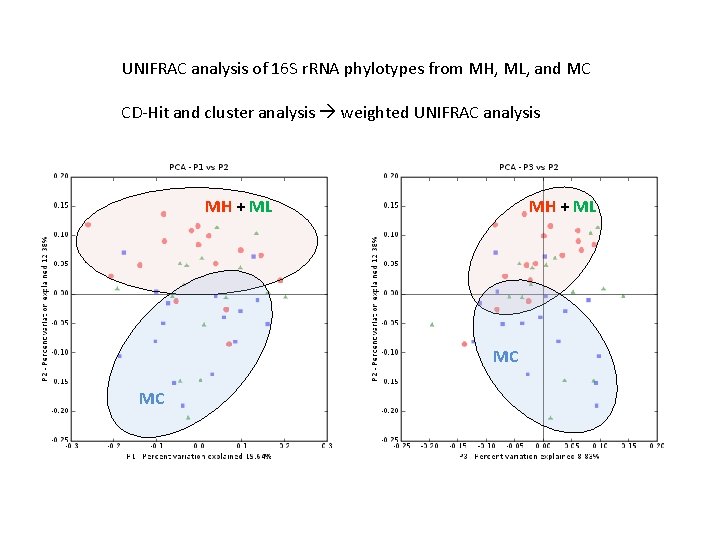
UNIFRAC analysis of 16 S r. RNA phylotypes from MH, ML, and MC CD-Hit and cluster analysis weighted UNIFRAC analysis MH + ML MC MC
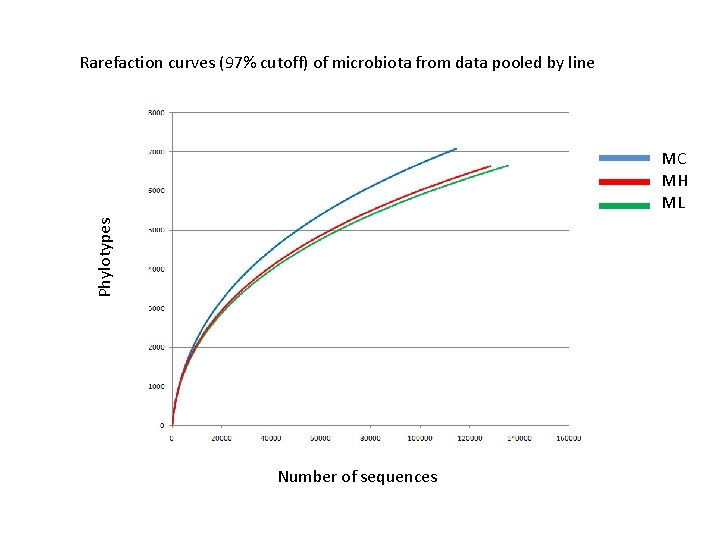
Rarefaction curves (97% cutoff) of microbiota from data pooled by line Phylotypes MC MH ML Number of sequences
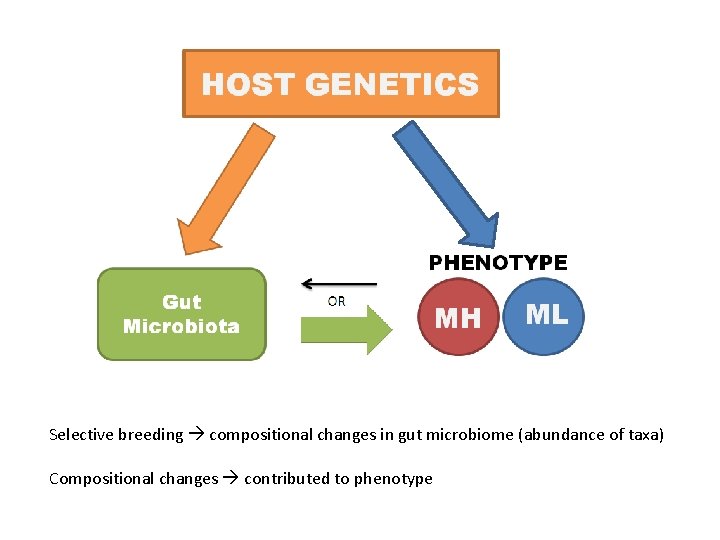
Selective breeding compositional changes in gut microbiome (abundance of taxa) Compositional changes contributed to phenotype
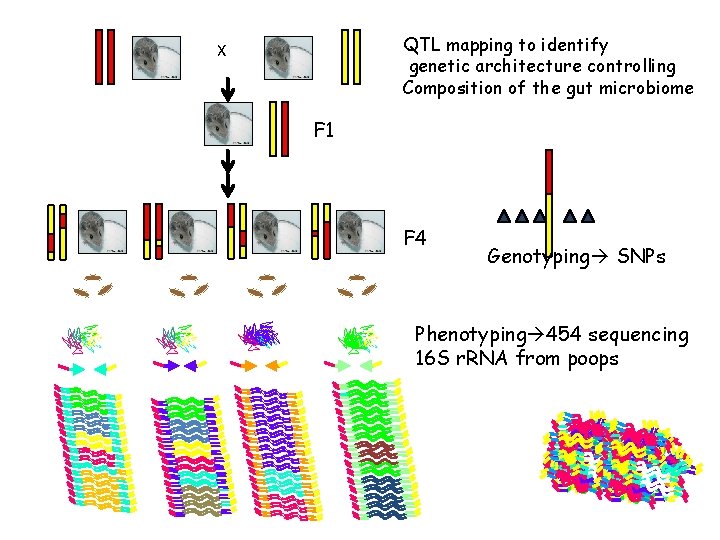
What about direct evidence? If there is significant effect of host genotype, then it should behave as a polygenic phenotype: microbiome composition should co-segregate with multiple genomic markers in breeding populations Mouse Genomics Daniel Pomp (Univ. of North Carolina) Statistics and Bioinformatics Steve Kachman (STATS) Etsuko Moriyama (Bio. Sci)
QTL mapping to identify genetic architecture controlling Composition of the gut microbiome X F 1 F 4 Genotyping SNPs Phenotyping 454 sequencing 16 S r. RNA from poops
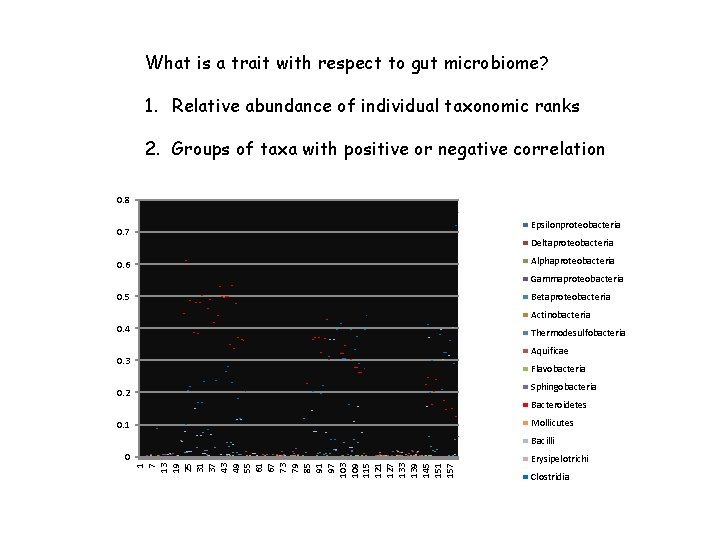
What is a trait with respect to gut microbiome? 1. Relative abundance of individual taxonomic ranks 2. Groups of taxa with positive or negative correlation 0. 8 Epsilonproteobacteria 0. 7 Deltaproteobacteria Alphaproteobacteria 0. 6 Gammaproteobacteria 0. 5 Betaproteobacteria Actinobacteria 0. 4 Thermodesulfobacteria Aquificae 0. 3 Flavobacteria Sphingobacteria 0. 2 Bacteroidetes Mollicutes 0. 1 Bacilli 1 7 13 19 25 31 37 43 49 55 61 67 73 79 85 91 97 103 109 115 121 127 133 139 145 151 157 0 Erysipelotrichi Clostridia
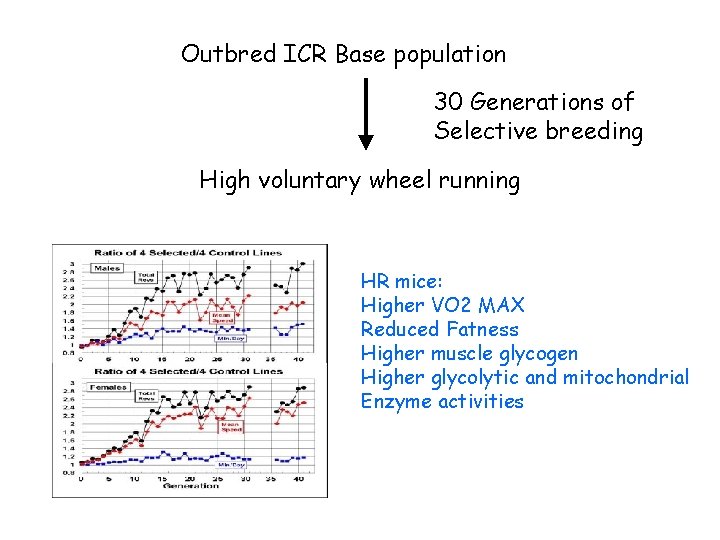
Outbred ICR Base population 30 Generations of Selective breeding High voluntary wheel running HR mice: Higher VO 2 MAX Reduced Fatness Higher muscle glycogen Higher glycolytic and mitochondrial Enzyme activities
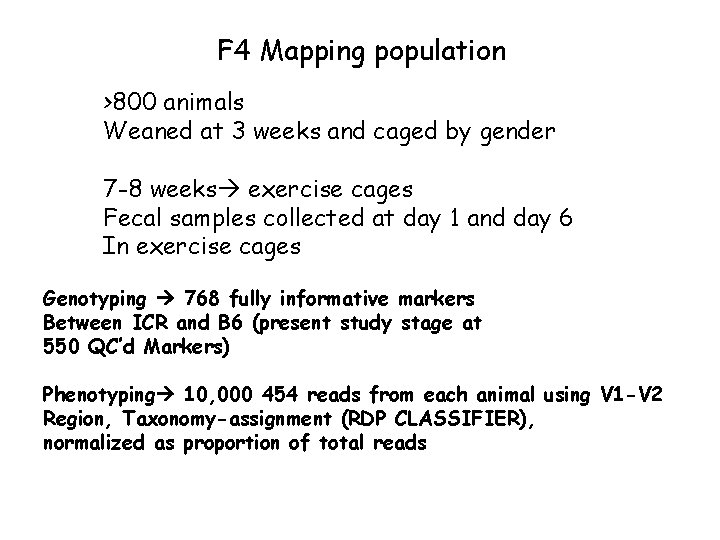
F 4 Mapping population >800 animals Weaned at 3 weeks and caged by gender 7 -8 weeks exercise cages Fecal samples collected at day 1 and day 6 In exercise cages Genotyping 768 fully informative markers Between ICR and B 6 (present study stage at 550 QC’d Markers) Phenotyping 10, 000 454 reads from each animal using V 1 -V 2 Region, Taxonomy-assignment (RDP CLASSIFIER), normalized as proportion of total reads
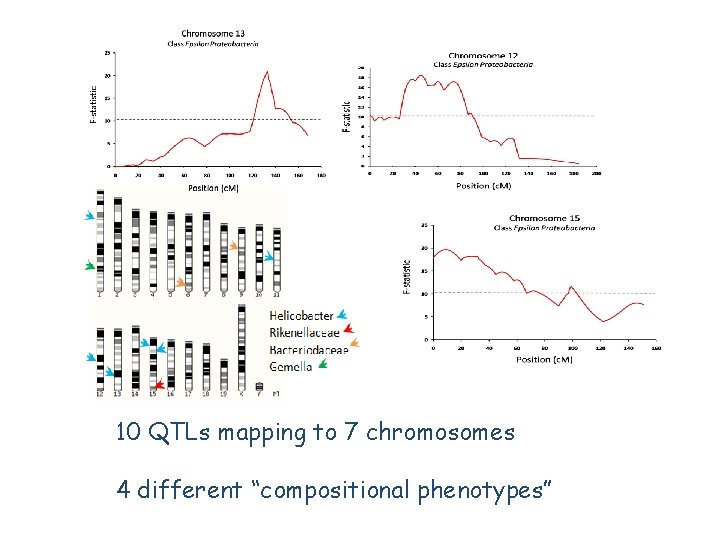
QTLs mapped from 200 animals of the F 4 cross 10 QTLs mapping to 7 chromosomes 4 different “compositional phenotypes”
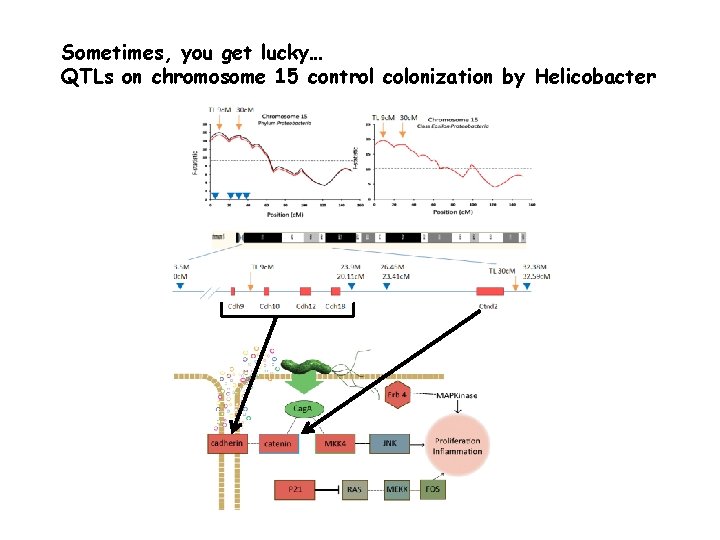
Sometimes, you get lucky… QTLs on chromosome 15 control colonization by Helicobacter
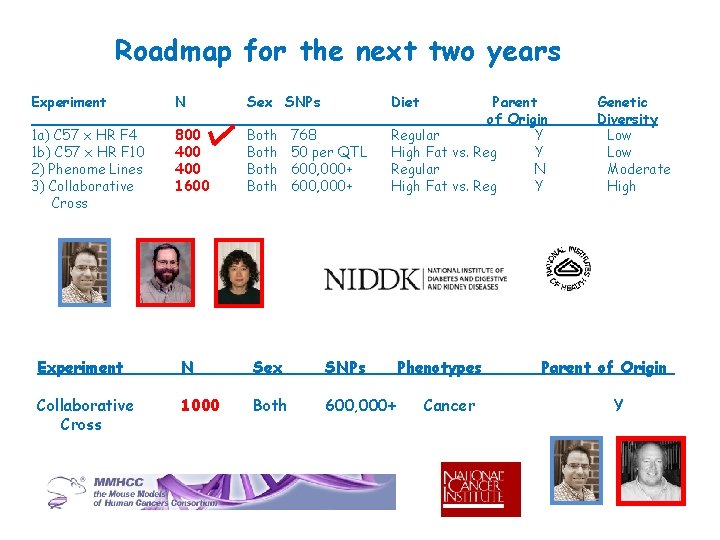
Roadmap for the next two years Experiment N Sex SNPs 1 a) C 57 x HR F 4 1 b) C 57 x HR F 10 2) Phenome Lines 3) Collaborative Cross 800 400 1600 Both Diet 768 50 per QTL 600, 000+ Parent of Origin Regular Y High Fat vs. Reg Y Regular N High Fat vs. Reg Y Experiment N Sex SNPs Collaborative Cross 1000 Both 600, 000+ Phenotypes Cancer Genetic Diversity Low Moderate High Parent of Origin Y
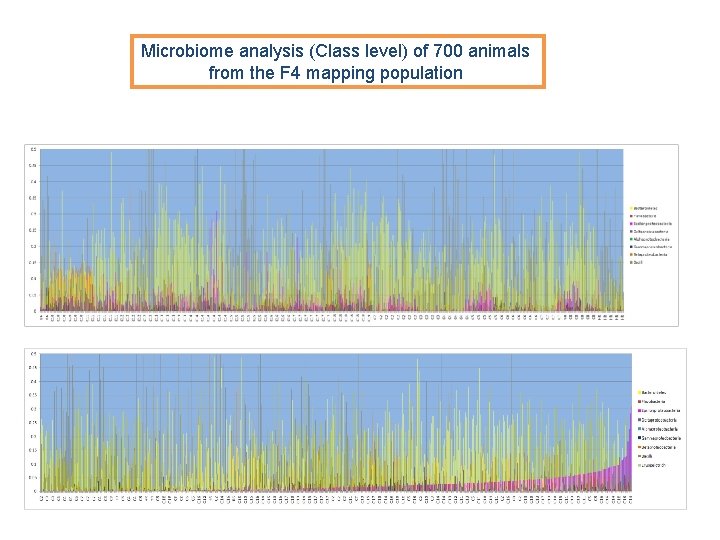
Microbiome analysis (Class level) of 700 animals from the F 4 mapping population
Are strong effects of host genetics conserved in plants? Plants also susceptible to infectious disease Microbiome of phylloplane (epiphytes and endophytes) May play protective role Much more prone to environmental variation?
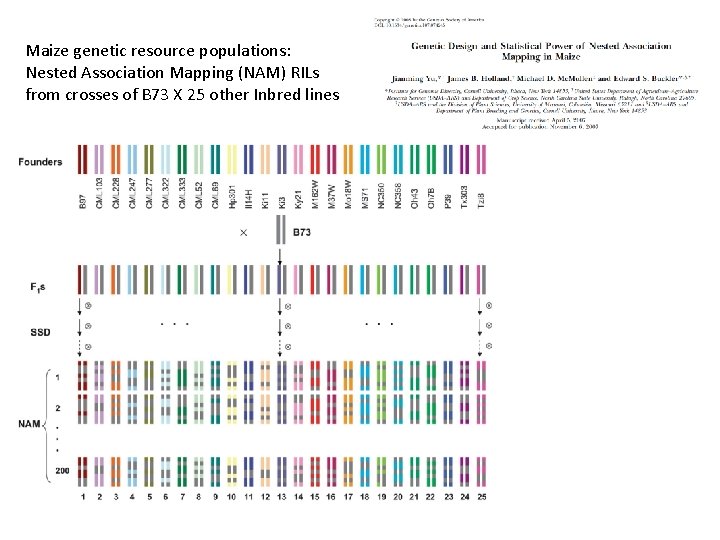
Maize genetic resource populations: Nested Association Mapping (NAM) RILs from crosses of B 73 X 25 other Inbred lines
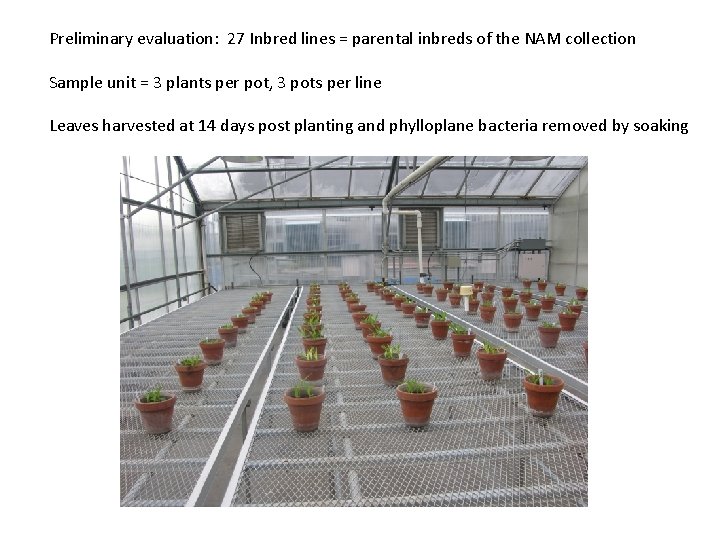
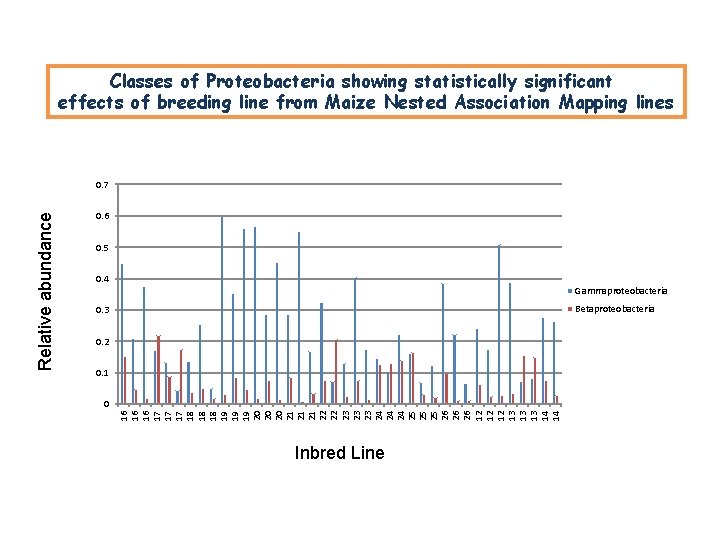
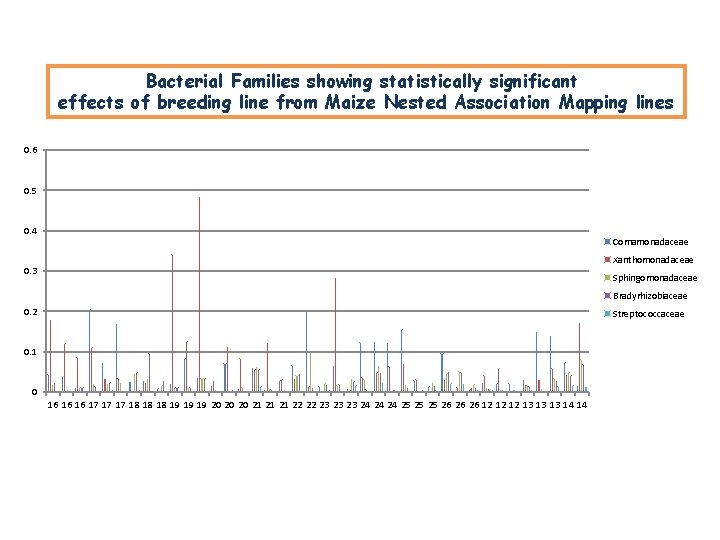
Preliminary evaluation: 27 Inbred lines = parental inbreds of the NAM collection Sample unit = 3 plants per pot, 3 pots per line Leaves harvested at 14 days post planting and phylloplane bacteria removed by soaking
Classes of Proteobacteria showing statistically significant effects of breeding line from Maize Nested Association Mapping lines 0. 6 0. 5 0. 4 Gammaproteobacteria Betaproteobacteria 0. 3 0. 2 0. 1 0 16 16 16 17 17 17 18 18 18 19 19 19 20 20 20 21 21 21 22 22 23 23 23 24 24 24 25 25 25 26 26 26 12 12 12 13 13 13 14 14 Relative abundance 0. 7 Inbred Line
Bacterial Families showing statistically significant effects of breeding line from Maize Nested Association Mapping lines 0. 6 0. 5 0. 4 Comamonadaceae Xanthomonadaceae 0. 3 Sphingomonadaceae Bradyrhizobiaceae 0. 2 Streptococcaceae 0. 1 0 16 16 16 17 17 17 18 18 18 19 19 19 20 20 20 21 21 21 22 22 23 23 23 24 24 24 25 25 25 26 26 26 12 12 12 13 13 13 14 14
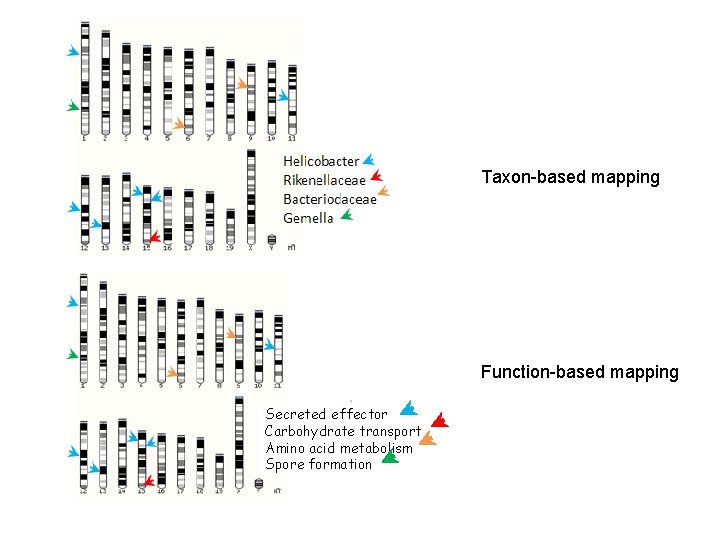
Taxon-based mapping Function-based mapping Secreted effector Carbohydrate transport Amino acid metabolism Spore formation
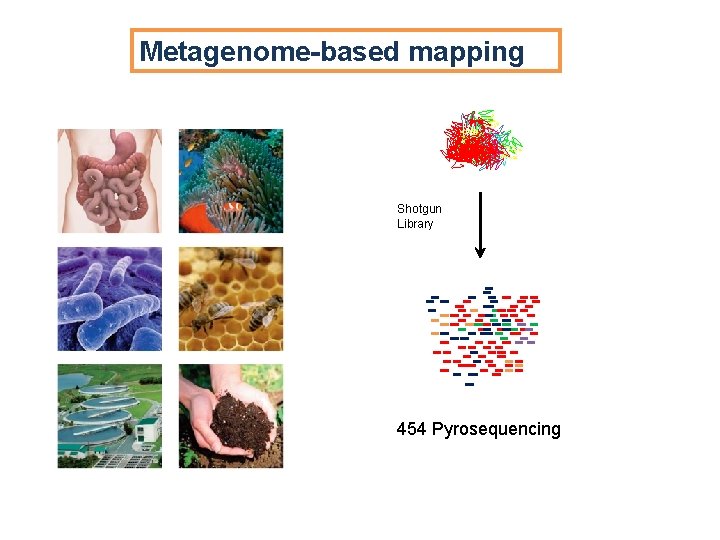
Metagenome-based mapping Shotgun Library 454 Pyrosequencing
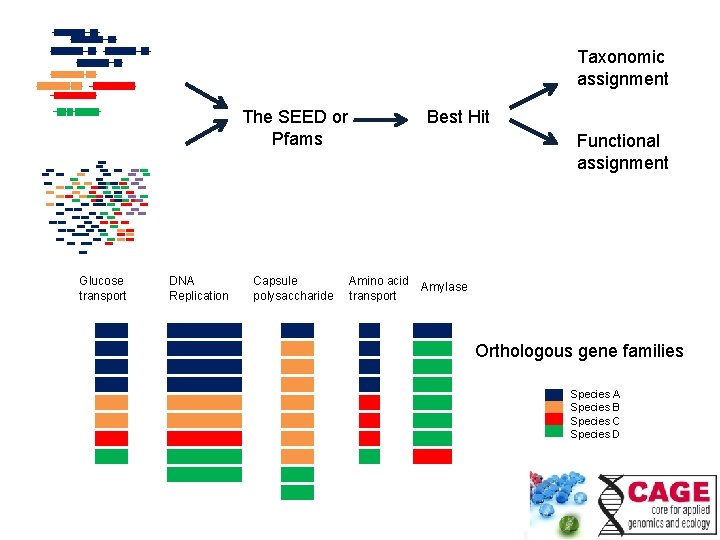
Taxonomic assignment The SEED or Pfams Glucose transport DNA Replication Capsule polysaccharide Best Hit Functional assignment Amino acid transport Amylase Orthologous gene families Species A Species B Species C Species D
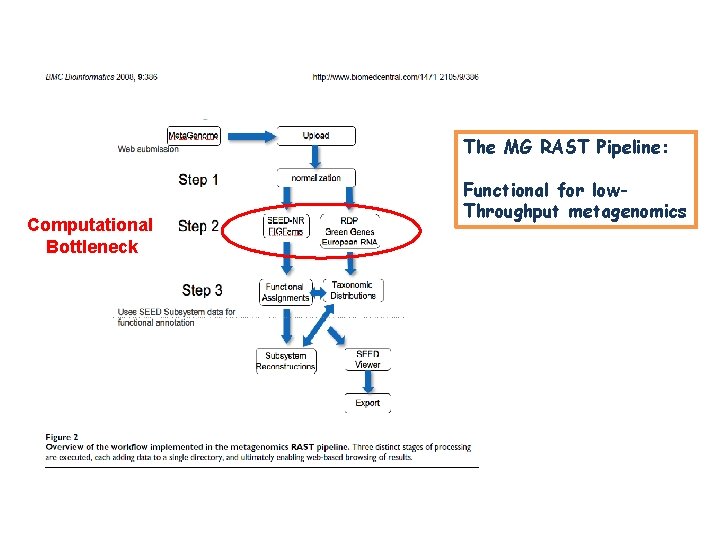
The MG RAST Pipeline: Computational Bottleneck Functional for low. Throughput metagenomics
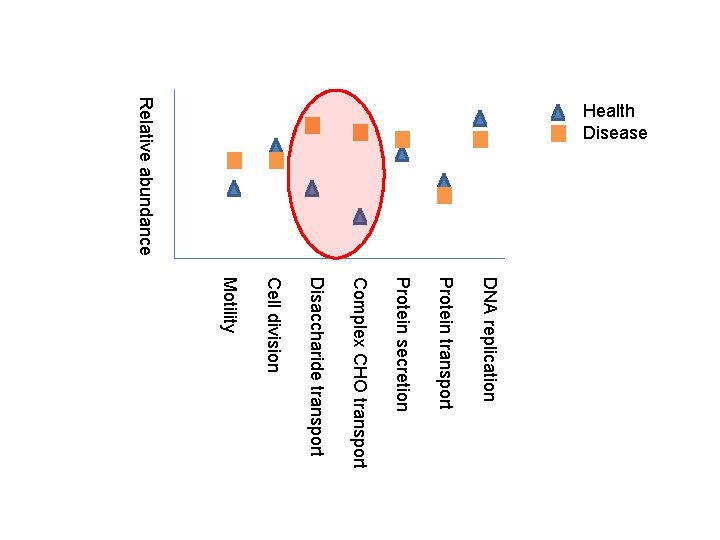
Relative abundance Health Disease DNA replication Protein transport Protein secretion Complex CHO transport Disaccharide transport Cell division Motility
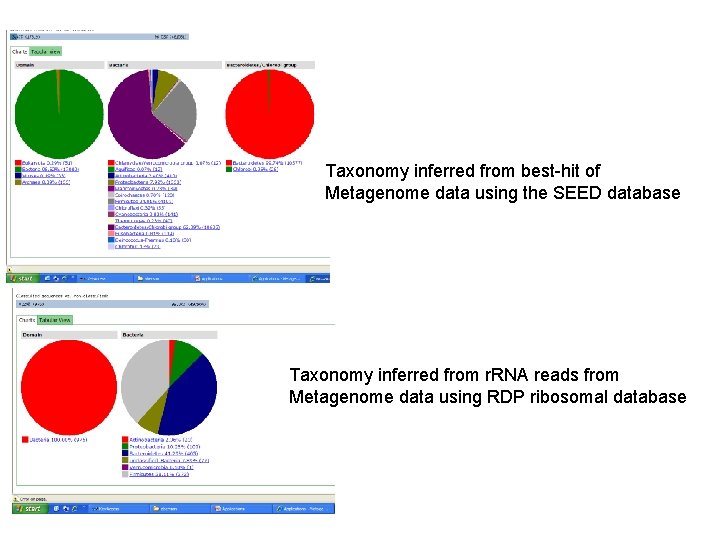
Taxonomy inferred from best-hit of Metagenome data using the SEED database Taxonomy inferred from r. RNA reads from Metagenome data using RDP ribosomal database
Host Metabolic effects Disease Gut microbiota Host Metabolic effects (microbial functions) Amino acid metabolism Carbohydrate metabolism Disease
Environmental effects Environment 1 Microbiota Ecosystem traits Environmental effects Environment 2 (microbial functions) Amino acid metabolism Carbohydrate metabolism Ecosystem traits §What factors influence composition—how much “G” and how much “E”? §Are there Keystone species? Mutualists? Engineers? Indicators? §How do aberrations arise in composition? §What is more important, species composition or function?
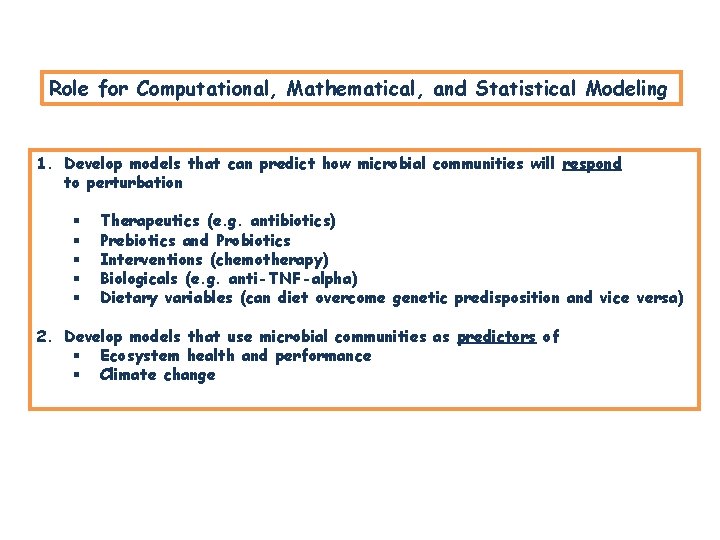
Role for Computational, Mathematical, and Statistical Modeling 1. Develop models that can predict how microbial communities will respond to perturbation § § § Therapeutics (e. g. antibiotics) Prebiotics and Probiotics Interventions (chemotherapy) Biologicals (e. g. anti-TNF-alpha) Dietary variables (can diet overcome genetic predisposition and vice versa) 2. Develop models that use microbial communities as predictors of § Ecosystem health and performance § Climate change
Drilling down through complex microbial communities Community composition 16 S Microbiome Community Genetic Potential Metagenomics and Metaproteomics Community Physiology Metabolomics (nanoscale? ? ) Community Dynamics Microbiomics + FISH Community interactions Microbiomics + FISH
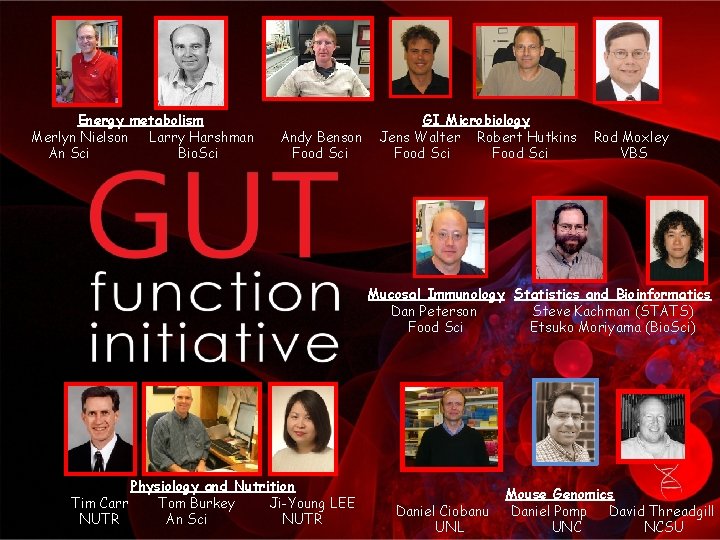
Energy metabolism Merlyn Nielson Larry Harshman An Sci Bio. Sci Andy Benson Food Sci GI Microbiology Jens Walter Robert Hutkins Food Sci Rod Moxley VBS Mucosal Immunology Statistics and Bioinformatics Dan Peterson Steve Kachman (STATS) Food Sci Etsuko Moriyama (Bio. Sci) Physiology and Nutrition Tim Carr Tom Burkey Ji-Young LEE NUTR An Sci NUTR Daniel Ciobanu UNL Mouse Genomics Daniel Pomp David Threadgill UNC NCSU
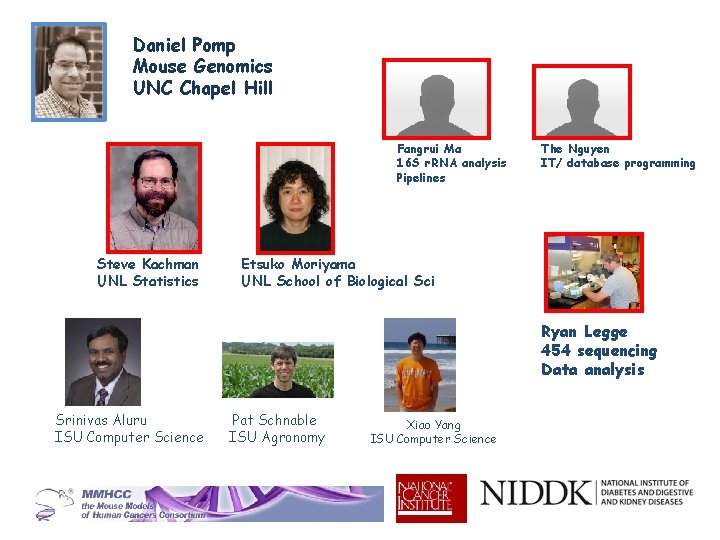
Daniel Pomp Mouse Genomics UNC Chapel Hill Fangrui Ma 16 S r. RNA analysis Pipelines Steve Kachman UNL Statistics The Nguyen IT/ database programming Etsuko Moriyama UNL School of Biological Sci Ryan Legge 454 sequencing Data analysis Srinivas Aluru ISU Computer Science Pat Schnable ISU Agronomy Xiao Yang ISU Computer Science