
Lecture 2 Learning without Overlearning Isabelle Guyon isabelleclopinet
Lecture 2: Learning without Over-learning Isabelle Guyon isabelle@clopinet. com
Machine Learning • Learning machines include: – – Linear discriminant (including Naïve Bayes) Kernel methods Neural networks Decision trees • Learning is tuning: – Parameters (weights w or a, threshold b) – Hyperparameters (basis functions, kernels, number of units)
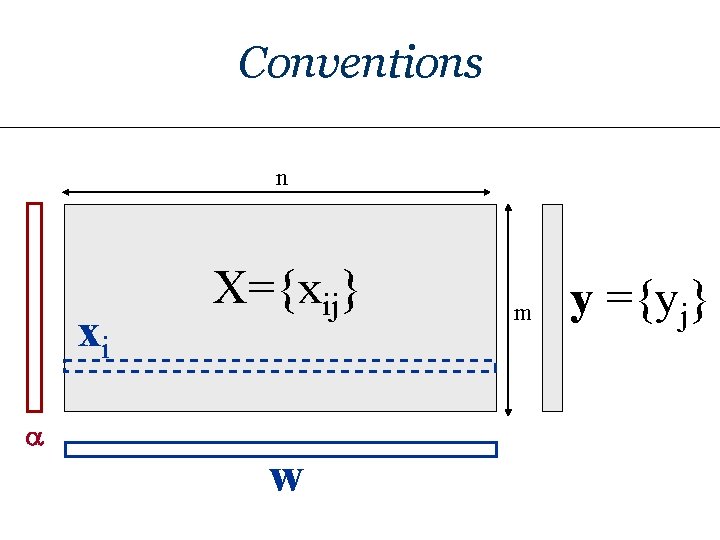
Conventions n xi a X={xij} w m y ={yj}
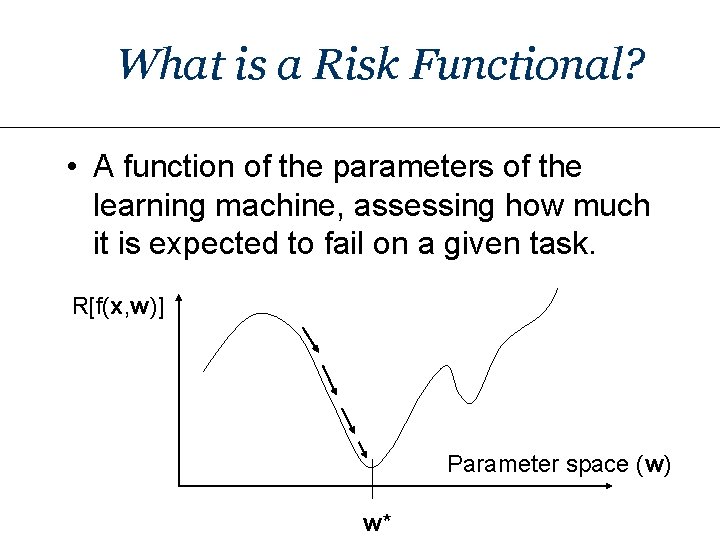
What is a Risk Functional? • A function of the parameters of the learning machine, assessing how much it is expected to fail on a given task. R[f(x, w)] Parameter space (w) w*
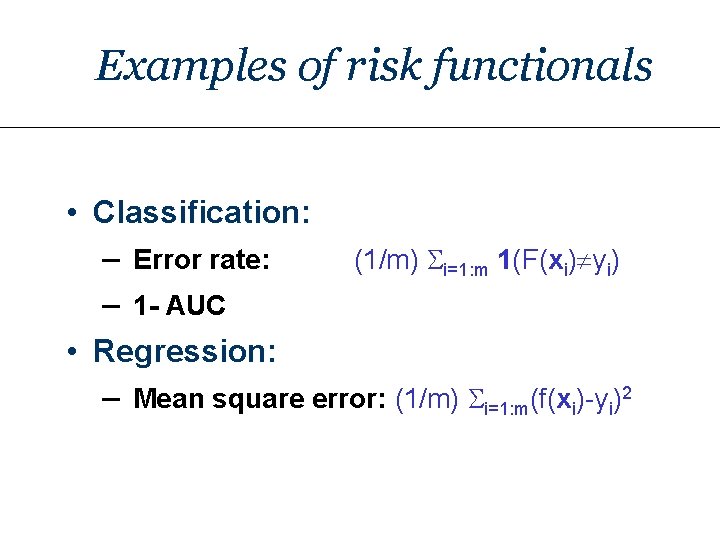
Examples of risk functionals • Classification: – Error rate: (1/m) i=1: m 1(F(xi) yi) – 1 - AUC • Regression: – Mean square error: (1/m) i=1: m(f(xi)-yi)2
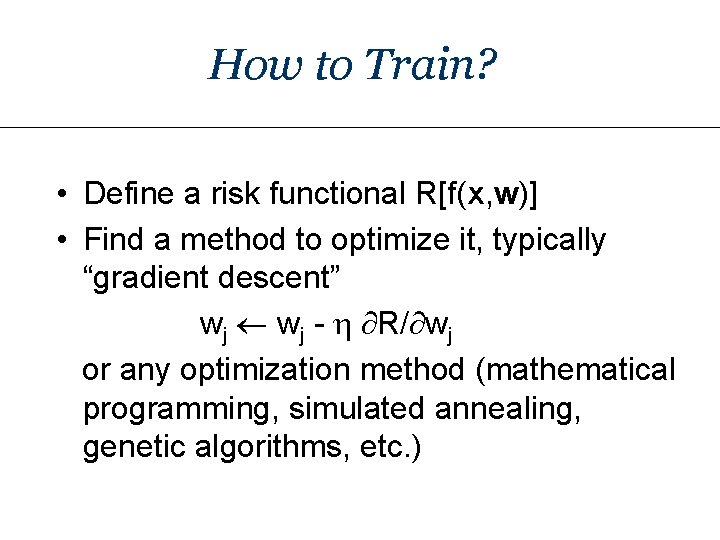
How to Train? • Define a risk functional R[f(x, w)] • Find a method to optimize it, typically “gradient descent” wj - R/ wj or any optimization method (mathematical programming, simulated annealing, genetic algorithms, etc. )
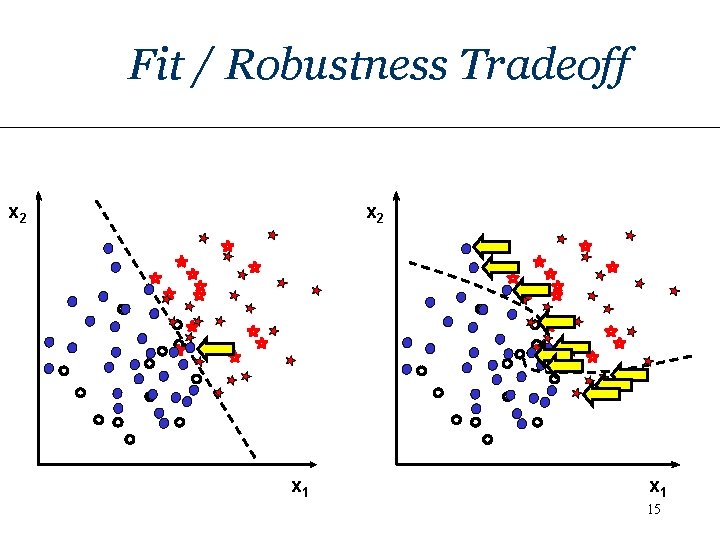
Fit / Robustness Tradeoff x 2 x 1 15
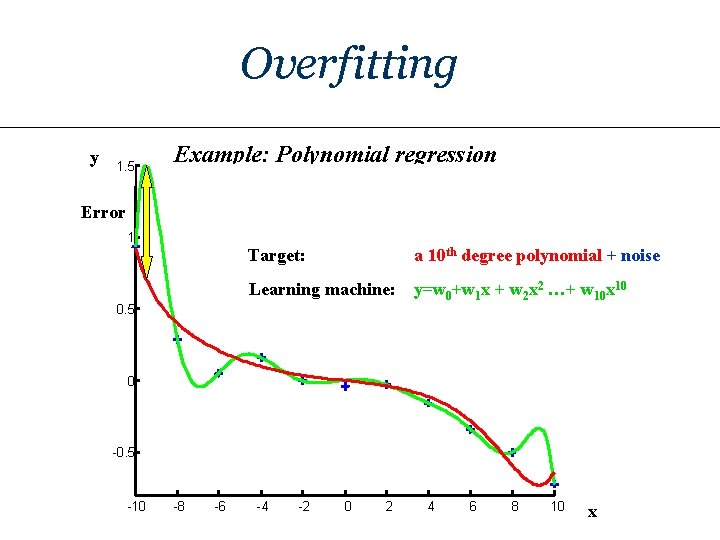
Overfitting y 1. 5 Example: Polynomial regression Error 1 Target: a 10 th degree polynomial + noise Learning machine: y=w 0+w 1 x + w 2 x 2 …+ w 10 x 10 0. 5 0 -0. 5 -10 -8 -6 -4 -2 0 2 4 6 8 10 x
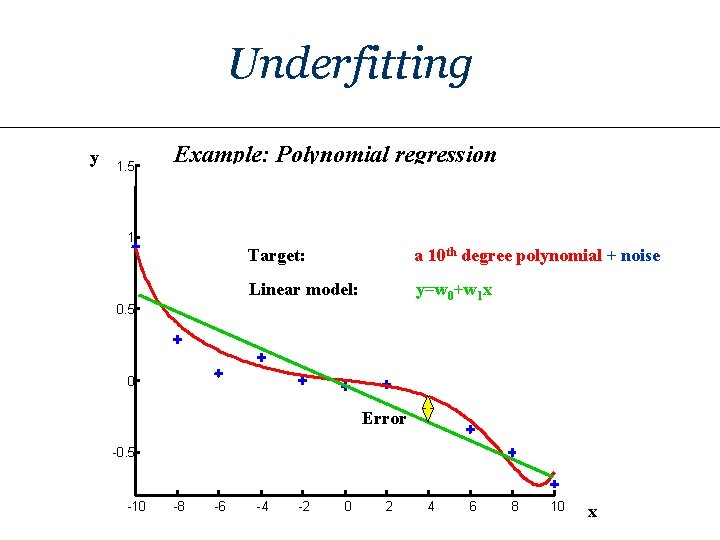
Underfitting y 1. 5 Example: Polynomial regression 1 Target: a 10 th degree polynomial + noise Linear model: y=w 0+w 1 x 0. 5 0 Error -0. 5 -10 -8 -6 -4 -2 0 2 4 6 8 10 x
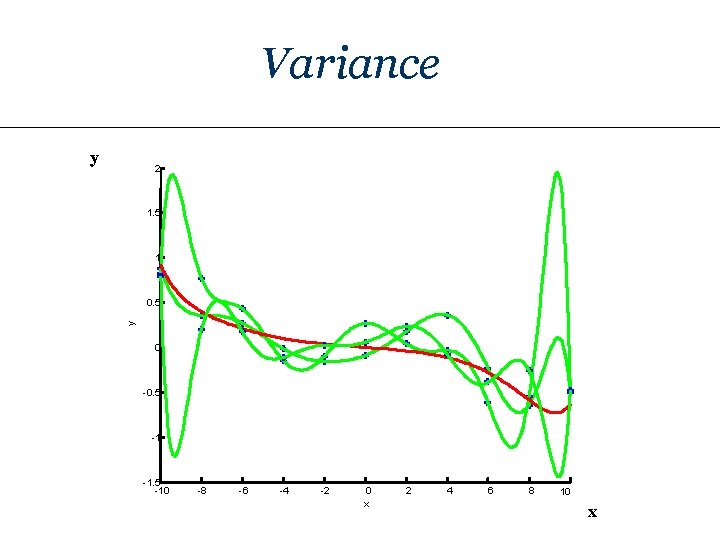
Variance y 2 1. 5 1 y 0. 5 0 -0. 5 -1 -1. 5 -10 -8 -6 -4 -2 0 x 2 4 6 8 10 x
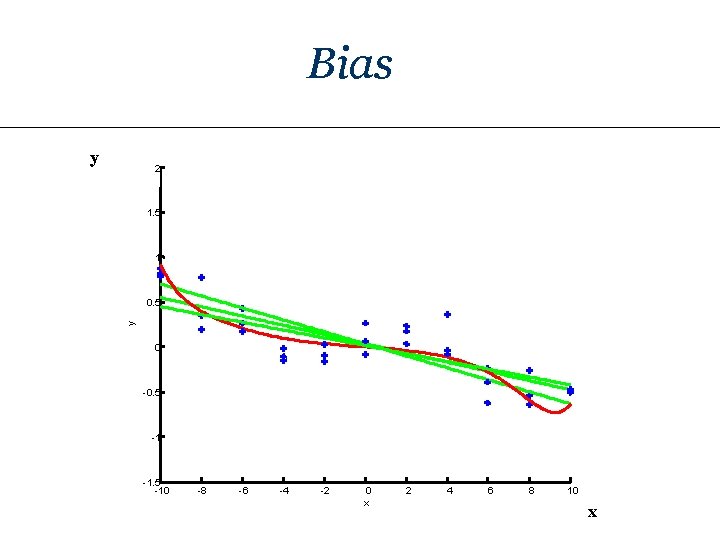
Bias y 2 1. 5 1 y 0. 5 0 -0. 5 -1 -1. 5 -10 -8 -6 -4 -2 0 x 2 4 6 8 10 x
Ockham’s Razor • Principle proposed by William of Ockham in the fourteenth century: “Pluralitas non est ponenda sine neccesitate”. • Of two theories providing similarly good predictions, prefer the simplest one. • Shave off unnecessary parameters of your models.
The Power of Amnesia • The human brain is made out of billions of cells or Neurons, which are highly interconnected by synapses. • Exposure to enriched environments with extra sensory and social stimulation enhances the connectivity of the synapses, but children and adolescents can lose them up to 20 million per day.
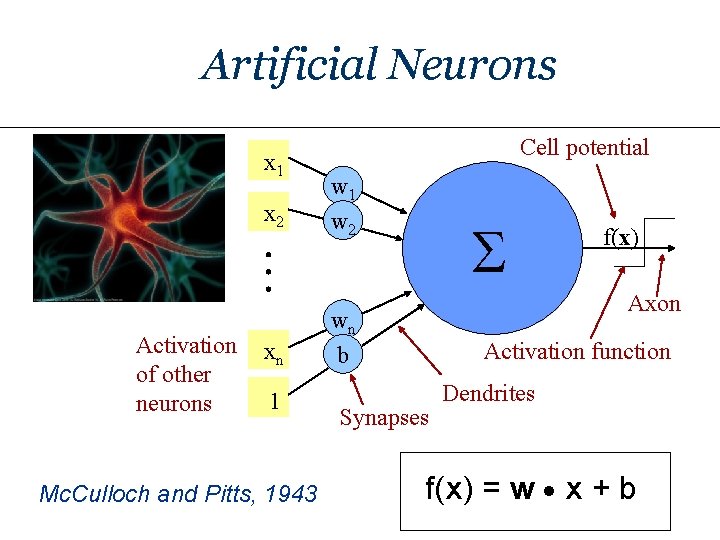
Artificial Neurons x 1 x 2 Activation of other neurons xn 1 Mc. Culloch and Pitts, 1943 Cell potential w 1 w 2 f(x) Axon wn b Activation function Synapses Dendrites f(x) = w x + b
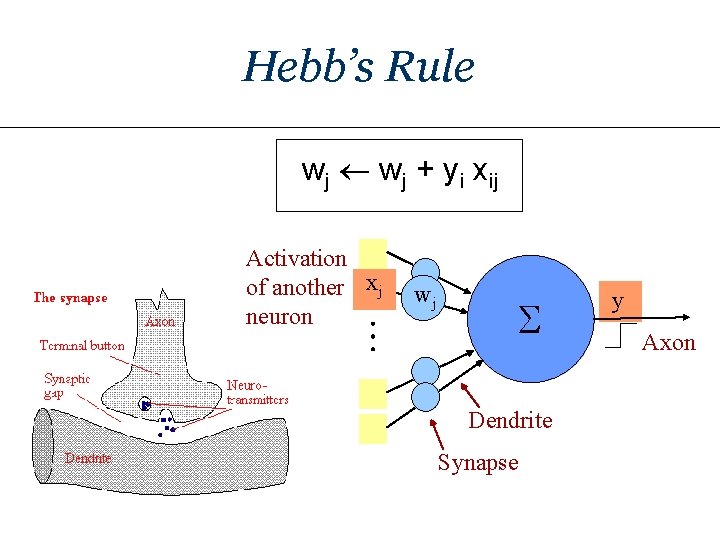
Hebb’s Rule wj + yi xij Activation of another xj neuron wj Dendrite Synapse y Axon
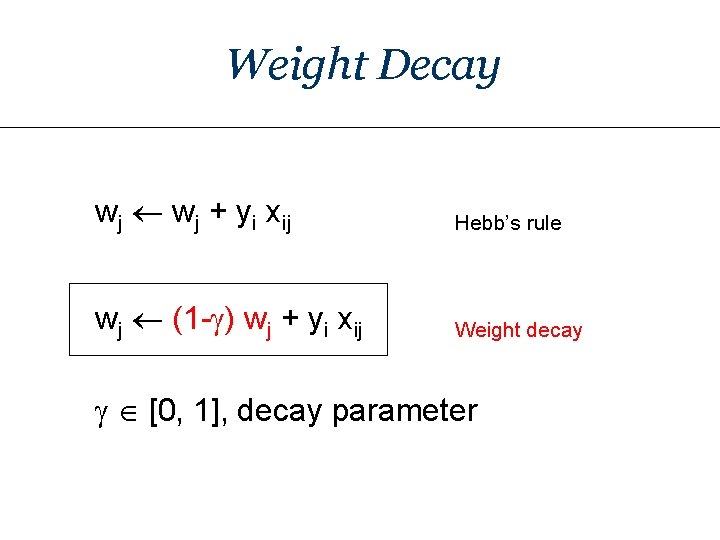
Weight Decay wj + yi xij Hebb’s rule wj (1 -g) wj + yi xij Weight decay g [0, 1], decay parameter
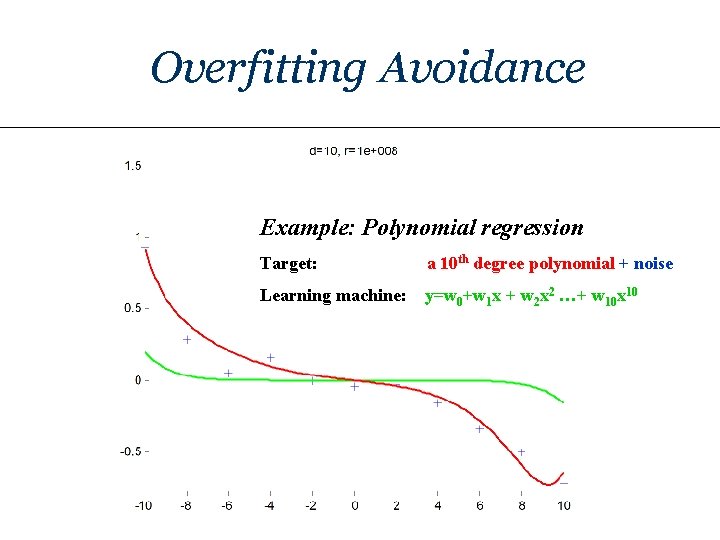
Overfitting Avoidance Example: Polynomial regression Target: a 10 th degree polynomial + noise Learning machine: y=w 0+w 1 x + w 2 x 2 …+ w 10 x 10
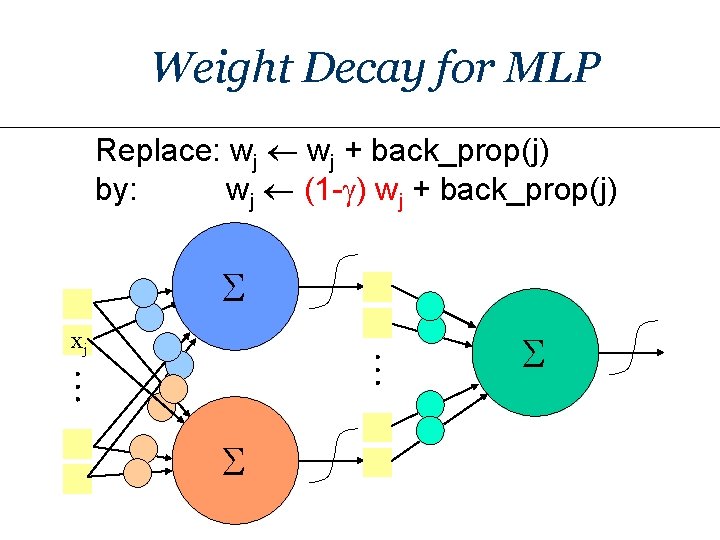
Weight Decay for MLP Replace: wj + back_prop(j) by: wj (1 -g) wj + back_prop(j) xj
Theoretical Foundations • • Structural Risk Minimization Bayesian priors Minimum Description Length Bayes/variance tradeoff
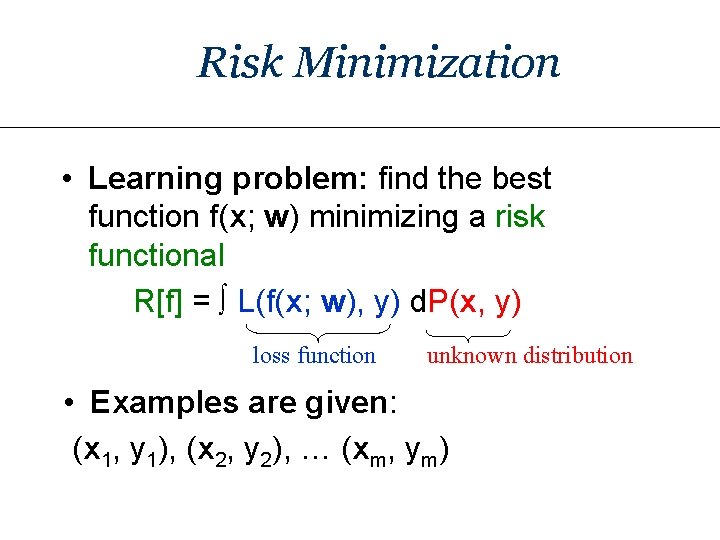
Risk Minimization • Learning problem: find the best function f(x; w) minimizing a risk functional R[f] = L(f(x; w), y) d. P(x, y) loss function unknown distribution • Examples are given: (x 1, y 1), (x 2, y 2), … (xm, ym)
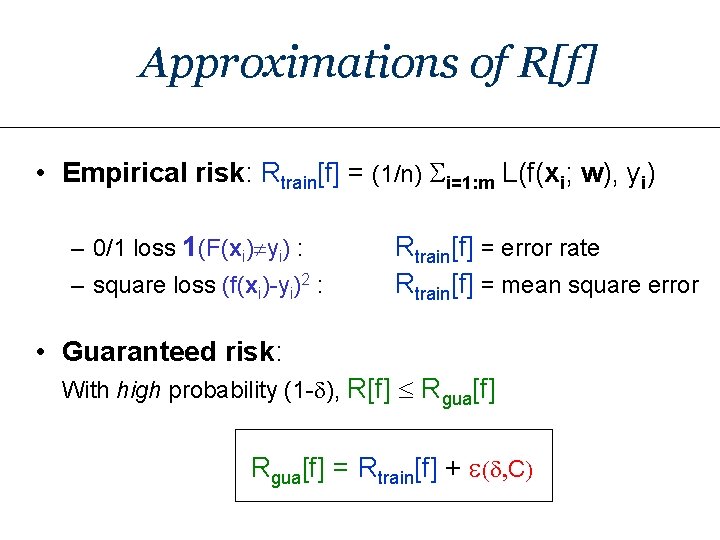
Approximations of R[f] • Empirical risk: Rtrain[f] = (1/n) i=1: m L(f(xi; w), yi) – 0/1 loss 1(F(xi) yi) : – square loss (f(xi)-yi)2 : Rtrain[f] = error rate Rtrain[f] = mean square error • Guaranteed risk: With high probability (1 -d), R[f] Rgua[f] = Rtrain[f] + e(d, C)
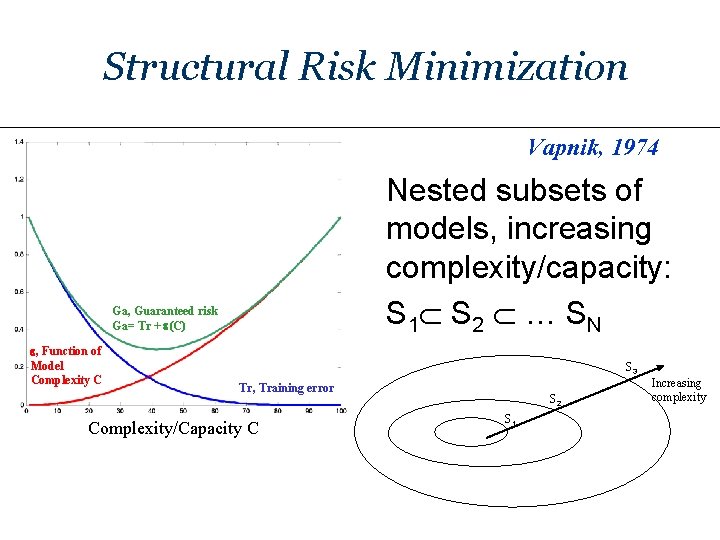
Structural Risk Minimization Vapnik, 1974 Nested subsets of models, increasing complexity/capacity: S 1 S 2 … SN Ga, Guaranteed risk Ga= Tr + e(C) e, Function of Model Complexity C S 3 Tr, Training error Complexity/Capacity C S 2 S 1 Increasing complexity

SRM Example (linear model) S 1 S 2 … SN R • Rank with ||w||2 = i wi 2 Sk = { w | ||w||2 < wk 2 }, w 1<w 2<…<wn • Minimization under constraint: min Rtrain[f] s. t. ||w||2 < wk 2 capacity • Lagrangian: Rreg[f, g] = Rtrain[f] + g ||w||2
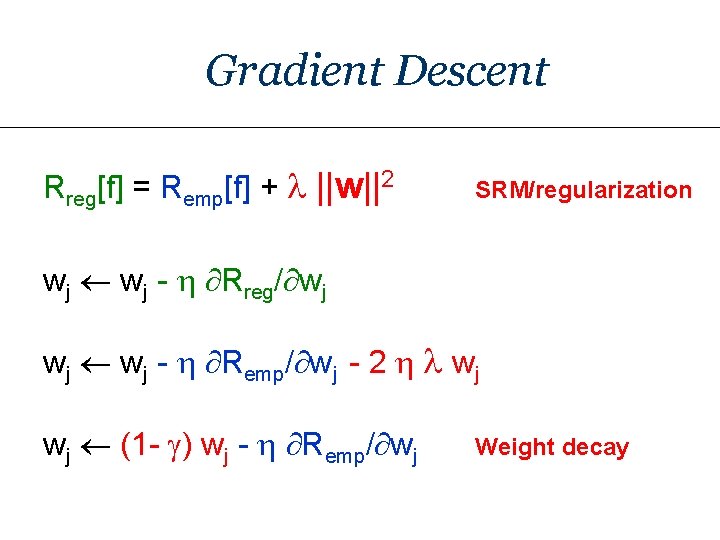
Gradient Descent Rreg[f] = Remp[f] + l ||w||2 SRM/regularization wj - Rreg/ wj wj - Remp/ wj - 2 l wj wj (1 - g) wj - Remp/ wj Weight decay
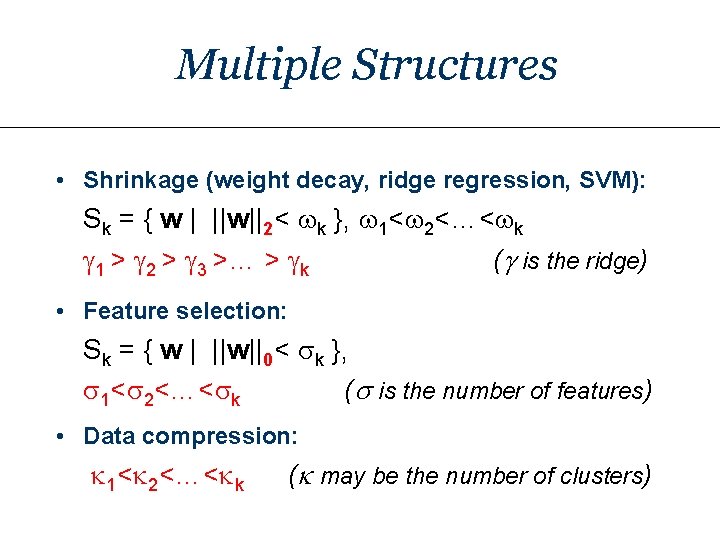
Multiple Structures • Shrinkage (weight decay, ridge regression, SVM): Sk = { w | ||w||2< wk }, w 1<w 2<…<wk g 1 > g 2 > g 3 >… > gk (g is the ridge) • Feature selection: Sk = { w | ||w||0< sk }, s 1<s 2<…<sk (s is the number of features) • Data compression: k 1<k 2<…<kk ( k may be the number of clusters)
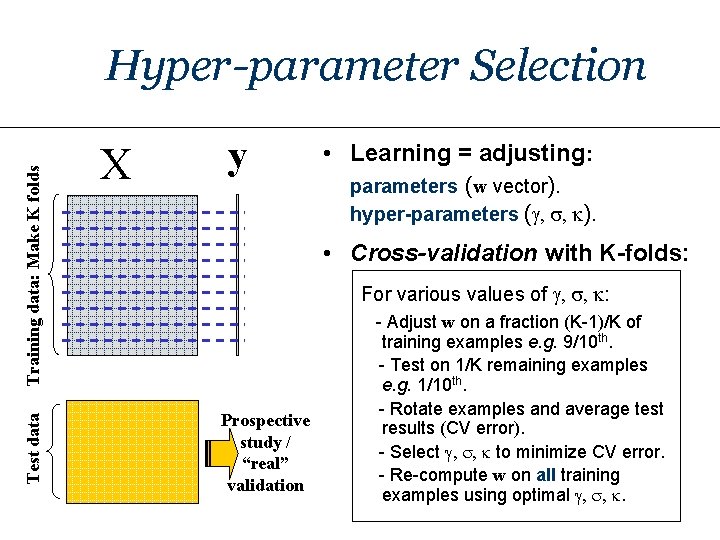
Test data Training data: Make K folds Hyper-parameter Selection X y • Learning = adjusting: parameters (w vector). hyper-parameters (g, s, k). • Cross-validation with K-folds: For various values of g, s, k: - Adjust w on a fraction (K-1)/K of Prospective study / “real” validation training examples e. g. 9/10 th. - Test on 1/K remaining examples e. g. 1/10 th. - Rotate examples and average test results (CV error). - Select g, s, k to minimize CV error. - Re-compute w on all training examples using optimal g, s, k.
Summary • High complexity models may “overfit”: – Fit perfectly training examples – Generalize poorly to new cases • SRM solution: organize the models in nested subsets such that in every structure element complexity < threshold. • Regularization: Formalize learning as a constrained optimization problem, minimize regularized risk = training error + l penalty.
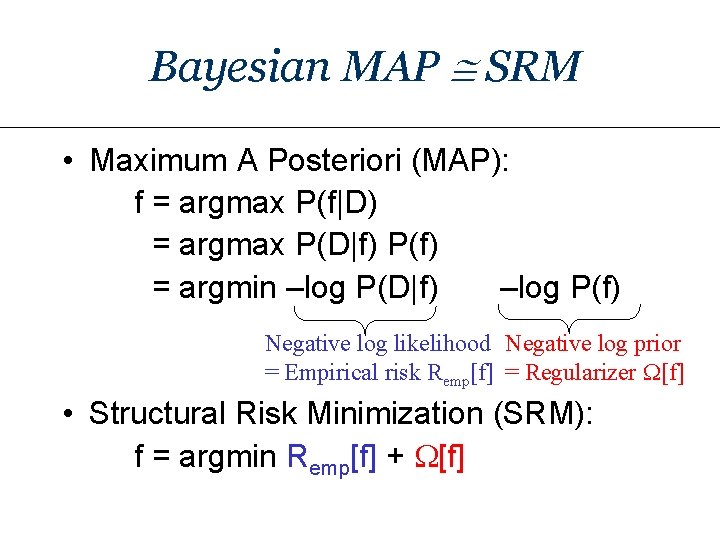
Bayesian MAP SRM • Maximum A Posteriori (MAP): f = argmax P(f|D) = argmax P(D|f) P(f) = argmin –log P(D|f) –log P(f) Negative log likelihood Negative log prior = Empirical risk Remp[f] = Regularizer W[f] • Structural Risk Minimization (SRM): f = argmin Remp[f] + W[f]
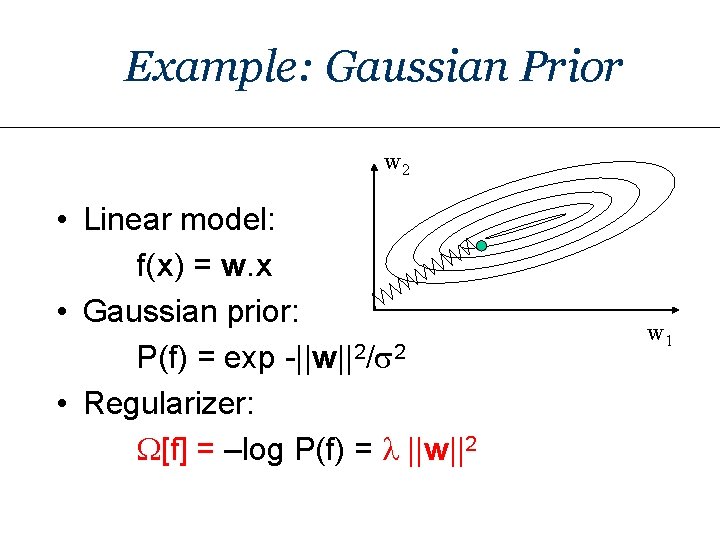
Example: Gaussian Prior w 2 • Linear model: f(x) = w. x • Gaussian prior: P(f) = exp -||w||2/s 2 • Regularizer: W[f] = –log P(f) = l ||w||2 w 1
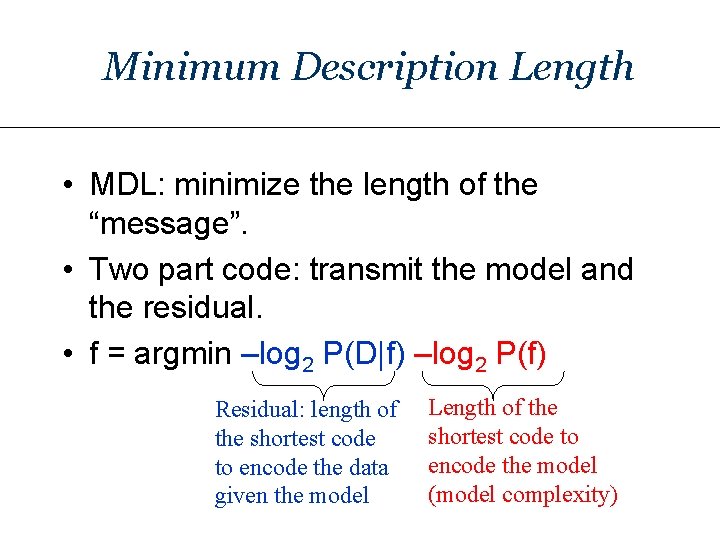
Minimum Description Length • MDL: minimize the length of the “message”. • Two part code: transmit the model and the residual. • f = argmin –log 2 P(D|f) –log 2 P(f) Residual: length of the shortest code to encode the data given the model Length of the shortest code to encode the model (model complexity)
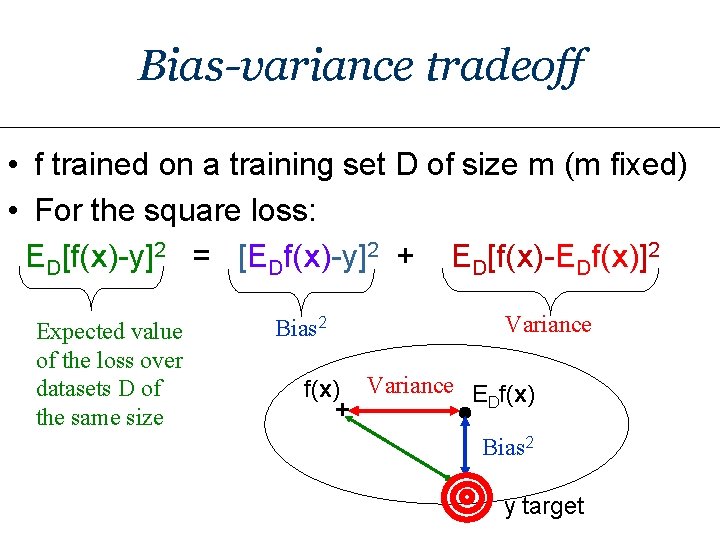
Bias-variance tradeoff • f trained on a training set D of size m (m fixed) • For the square loss: ED[f(x)-y]2 = [EDf(x)-y]2 + ED[f(x)-EDf(x)]2 Expected value of the loss over datasets D of the same size Bias 2 f(x) Variance E f(x) D Bias 2 y target
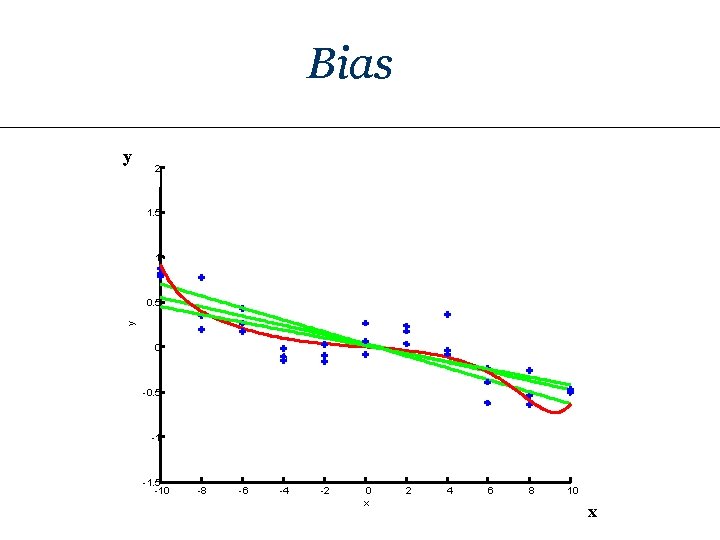
Bias y 2 1. 5 1 y 0. 5 0 -0. 5 -1 -1. 5 -10 -8 -6 -4 -2 0 x 2 4 6 8 10 x
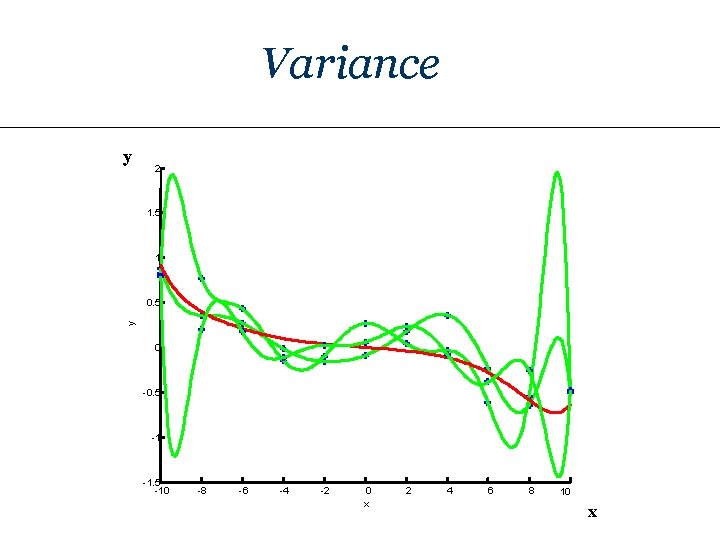
Variance y 2 1. 5 1 y 0. 5 0 -0. 5 -1 -1. 5 -10 -8 -6 -4 -2 0 x 2 4 6 8 10 x
The Effect of SRM Reduces the variance… …at the expense of introducing some bias.
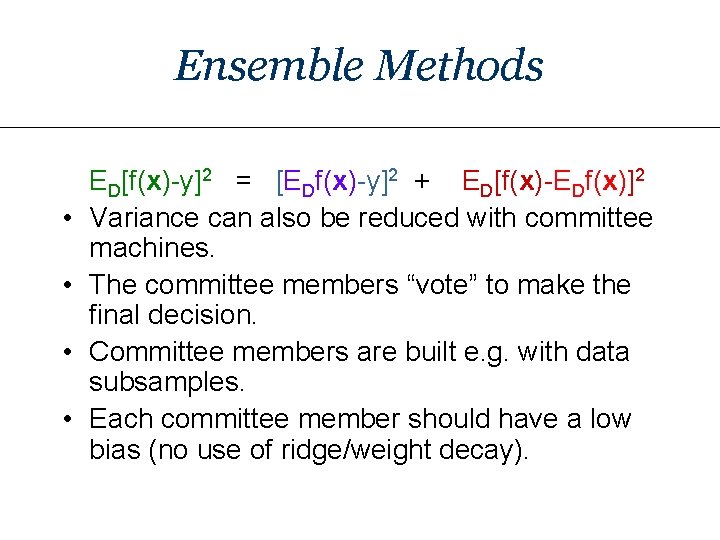
Ensemble Methods • • ED[f(x)-y]2 = [EDf(x)-y]2 + ED[f(x)-EDf(x)]2 Variance can also be reduced with committee machines. The committee members “vote” to make the final decision. Committee members are built e. g. with data subsamples. Each committee member should have a low bias (no use of ridge/weight decay).
Overall summary • Weight decay is a powerful means of overfitting avoidance (||w||2 regularizer). • It has several theoretical justifications: SRM, Bayesian prior, MDL. • It controls variance in the learning machine family, but introduces bias. • Variance can also be controlled with ensemble methods.
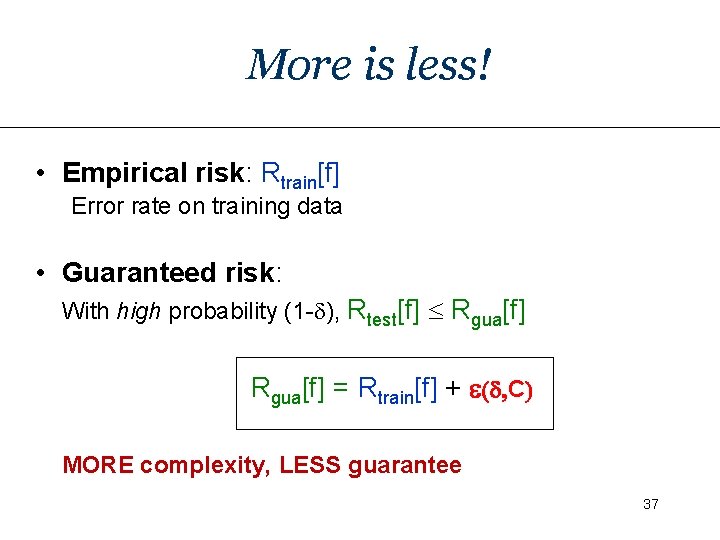
More is less! • Empirical risk: Rtrain[f] Error rate on training data • Guaranteed risk: With high probability (1 -d), Rtest[f] Rgua[f] = Rtrain[f] + e(d, C) MORE complexity, LESS guarantee 37
Weight decay Idea: minimize a guaranteed risk Rgua[f] = Rtrain[f] + e(d, C) use e(d, C) = g ||w||2 Minimize the training error and model complexity Optimize g by cross-validation 38
More is less, again! • Empirical risk: RCV[f] Cross-validation error on training data • Guaranteed risk: With high probability (1 -d), Rtest[f] Rgua[f] = RCV[f] + e(d, number of things tried) MORE things tried, LESS guarantee 39
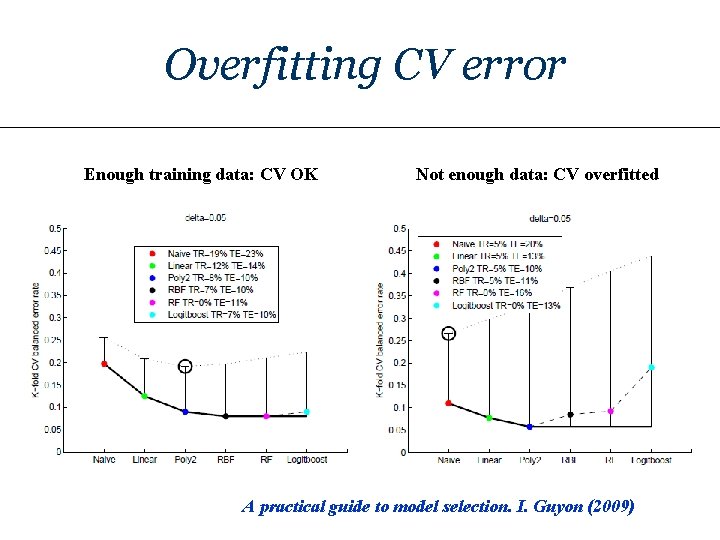
Overfitting CV error Enough training data: CV OK Not enough data: CV overfitted A practical guide to model selection. I. Guyon (2009)
Want to Learn More? • • • Statistical Learning Theory, V. Vapnik. Theoretical book. Reference book on generatization, VC dimension, Structural Risk Minimization, SVMs, ISBN : 0471030031. Structural risk minimization for character recognition, I. Guyon, V. Vapnik, B. Boser, L. Bottou, and S. A. Solla. In J. E. Moody et al. , editor, Advances in Neural Information Processing Systems 4 (NIPS 91), pages 471 --479, San Mateo CA, Morgan Kaufmann, 1992. http: //clopinet. com/isabelle/Papers/srm. ps. Z Kernel Ridge Regression Tutorial, I. Guyon. http: //clopinet. com/isabelle/Projects/ETH/Kernel. Ridge. pdf Feature Extraction: Foundations and Applications. I. Guyon et al, Eds. Book for practitioners with datasets of NIPS 2003 challenge, tutorials, best performing methods, Matlab code, teaching material. http: //clopinet. com/fextract-book A practical guide to model selection. I. Guyon In: Proceedings of the machine learning summer school (2009). http: //eprints. pascalnetwork. org/archive/00005768/
Challenges in Machine Learning (collection published by Microtome) http: //www. mtome. com/Publications/Ci. ML/ciml. html
- Slides: 42