
Internet Archive Web Datamining Raymie Stata UC Santa
Internet Archive & Web Datamining Raymie Stata UC Santa Cruz & Internet Archive
Agenda • State of the Archive – Collections – Infrastructure (freecache) • Internet Analytics – Information carnivores
Archive Overview • Started in 1996 • Transitioned from “Archive of the Internet” to “Archive on the Internet” • Transitioning to “Digital Library of the Future” • Funding from private foundations, plus lots of volunteers
Digital Library of the Future Universal Access to Human Knowledge • Information is accessible to anyone from anywhere • The best and broadest information is available • We imagine a small network of very large, regional, “mega” digital libraries
Web collection • Over 10 B pages, 200 TB, 50 M sites – Broad crawls (20 TB snapshot/2 months) – Narrow crawls (elections, 9/11) – “Heritage crawls” – Writing new crawler : -( • Wayback machine – Success! 4 M hits/day – Have search engine, but hidden! – Policy has been tested, remains same
Moving images • 2500 Movies • “Open source movies” – Upload your movie to the Archive – Build a movie at the Archive!
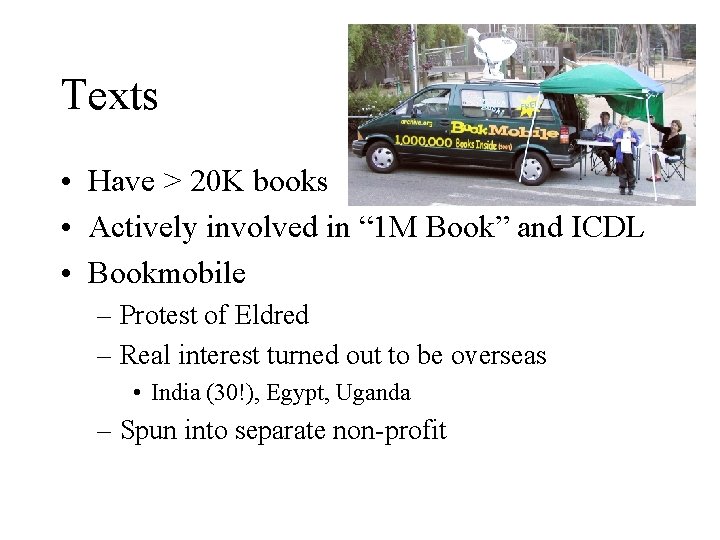
Texts • Have > 20 K books • Actively involved in “ 1 M Book” and ICDL • Bookmobile – Protest of Eldred – Real interest turned out to be overseas • India (30!), Egypt, Uganda – Spun into separate non-profit
Audio - e. Tree • Around 5, 000 concerts from 250 bands – Growing 30 concerts, 1 band/day • Largest consumer of bandwidth – Consistent 85 Mbps (downloads) • Same policy as Wayback – We respect requests
Infrastructure • Infinite bandwidth and storage – Core competency of the Archive – Vision, not reality – But striving for it makes us better • Recent challenges – Moving from 250 TB to 1 PB – Supporting e. Tree bandwidth
The Petabyte challenge • Finally having problems predicted – Power, cooling, disk failures dominating – Need larger staff, real software engineering • BUT: – Took much longer than anticipated – Sticking to our philosophies • Commodity hardware • Widely used software + simple scripts
The Petabyte architecture • New datacenter – To solve our power and cooling problems • Better “procurement” process • File-level mirroring – Use basic FS, simple scripts – Preparing for geoplexing (vs. file-level RAID) • Elimination of inter-crawl copies – This is currently our “backup”
The (e. Tree) bandwidth challenge • Can we do better than simply buying more bandwidth? • Yes! Find other people willing to help • Cooperative/open-source CDN
Freecache. org • It shouldn’t cost you to give away content • To distribute using freecache, simply: – Replace: href=http: //X/Y – With: href=http: //freecache. org/http: //X/Y • To be a distribution node, simply install a 1 K perl-script on your Apache server
Freecache design • Content routing done centrally • Right now, routing is random – Working on “closeness-driven” routing • LRU eviction policy • Throttles “cheaters” • Broken browsers have been a problem
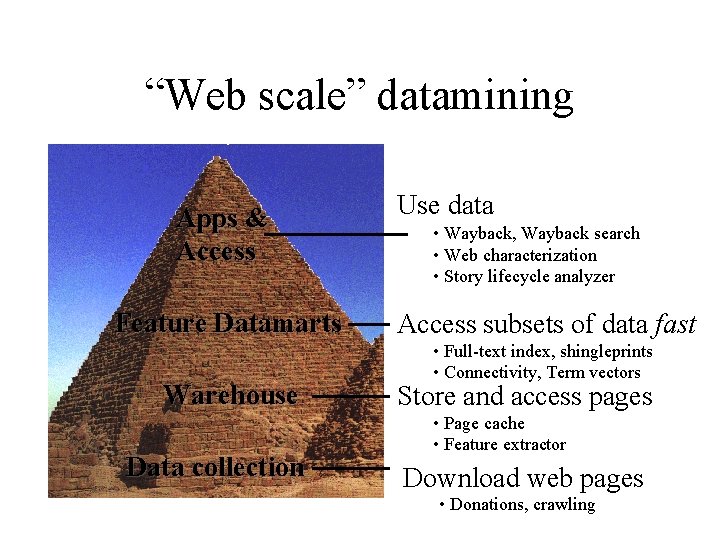
“Web scale” datamining Apps & Access Feature Datamarts Warehouse Data collection Use data • Wayback, Wayback search • Web characterization • Story lifecycle analyzer Access subsets of data fast • Full-text index, shingleprints • Connectivity, Term vectors Store and access pages • Page cache • Feature extractor Download web pages • Donations, crawling
Tools for Web mining • Very similar to the Astronomy project – Need indexes, parallelism – Need to move computation to the data – Strategies to deal with different result-set sizes • Current focus is on the “warehouse”
Web datamining using Web Carnivores
The Carnivore Analogy [Etzioni 96] Web pages
The Carnivore Analogy Search engines Web pages
The Carnivore Analogy Carnivore apps Search engines Web pages
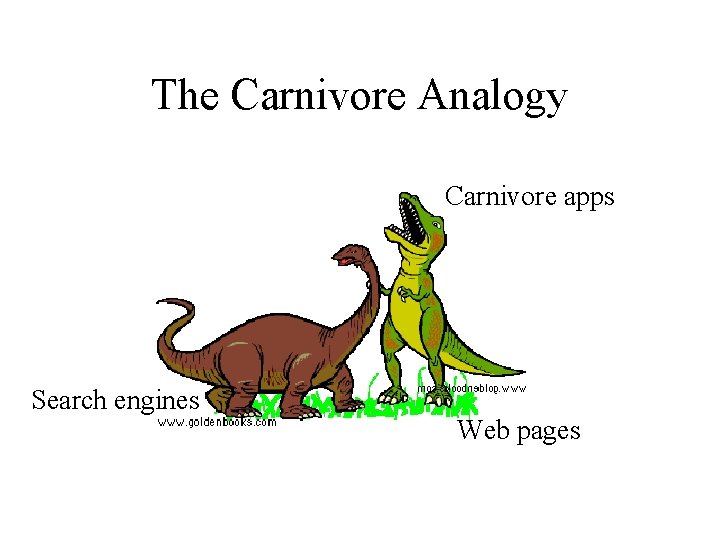
Carnivores • Search engines have what you want – Google has 3 B pages: “It’s in there” – No need to crawl anymore • However, their general-purpose interface do not always yield good results for specific information needs
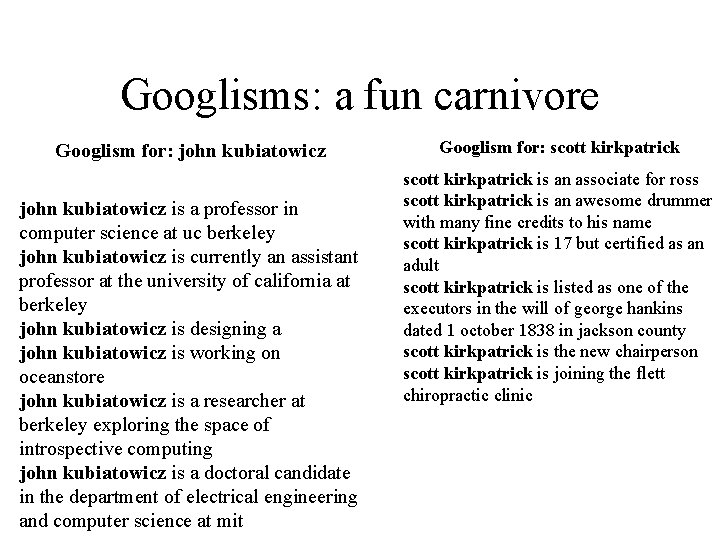
Googlisms: a fun carnivore Googlism for: john kubiatowicz is a professor in computer science at uc berkeley john kubiatowicz is currently an assistant professor at the university of california at berkeley john kubiatowicz is designing a john kubiatowicz is working on oceanstore john kubiatowicz is a researcher at berkeley exploring the space of introspective computing john kubiatowicz is a doctoral candidate in the department of electrical engineering and computer science at mit Googlism for: scott kirkpatrick is an associate for ross scott kirkpatrick is an awesome drummer with many fine credits to his name scott kirkpatrick is 17 but certified as an adult scott kirkpatrick is listed as one of the executors in the will of george hankins dated 1 october 1838 in jackson county scott kirkpatrick is the new chairperson scott kirkpatrick is joining the flett chiropractic clinic
A carnivore for genre search • Genre classifies documents by its intent – Why was the document written • Search engines search by topic, not genre • Idea: build a carnivore for genre search
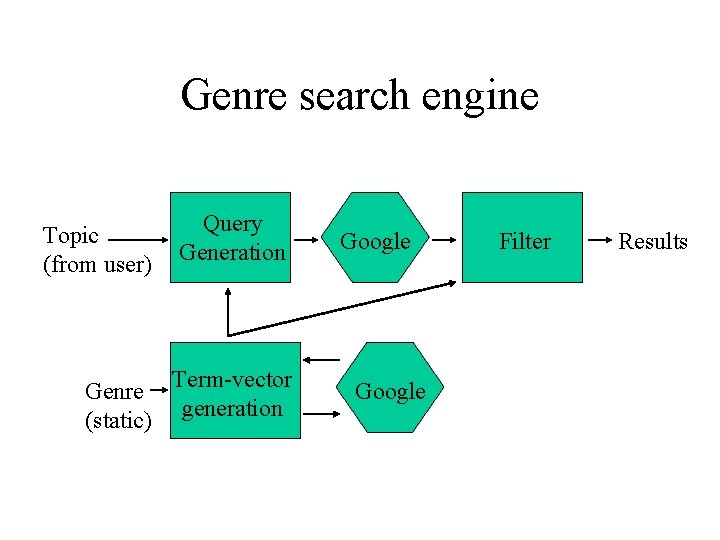
Genre search engine Topic (from user) Query Generation Genre Term-vector (static) generation Google Filter Results
Making it work • Query templates – Details of query matters • PMI-IR for genre terms • Discrimination as well as genre vector
User study • Genre: “Buying guides” – Education for product selection – Lots on the Web, but hard to find – (Agreement on what they are) • Results – Topic by itself: 0% P@10 (ie, none in top 10) – Topic + “buying guide: ” 33% – Our carnivore: 51%
- Slides: 26