
IBM Intelligent Miner for Text John Tullis De
IBM Intelligent Miner for Text John Tullis De. Paul Instructor john. d. tullis@us. arthurandersen. com Copyrighted material John Tullis 2/26/2021 page 1
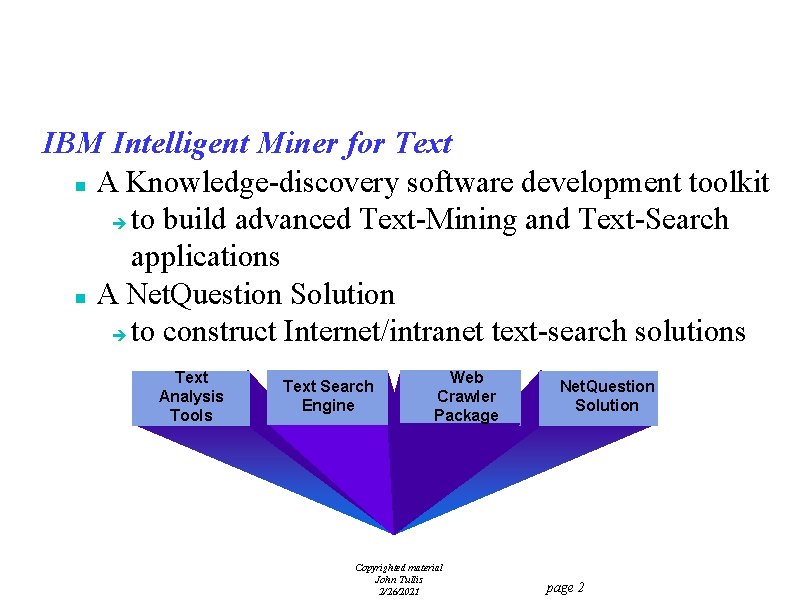
IBM Intelligent Miner for Text n A Knowledge-discovery software development toolkit è to build advanced Text-Mining and Text-Search applications n A Net. Question Solution è to construct Internet/intranet text-search solutions Text Analysis Tools Text Search Engine Web Crawler Package Copyrighted material John Tullis 2/26/2021 Net. Question Solution page 2
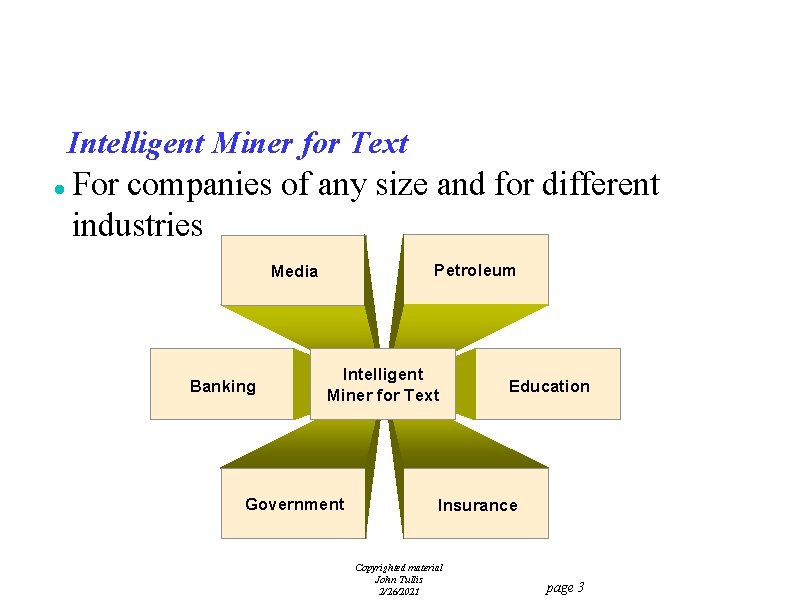
Intelligent Miner for Text l For companies of any size and for different industries Petroleum Media Banking Intelligent Miner for Text Government Education Insurance Copyrighted material John Tullis 2/26/2021 page 3
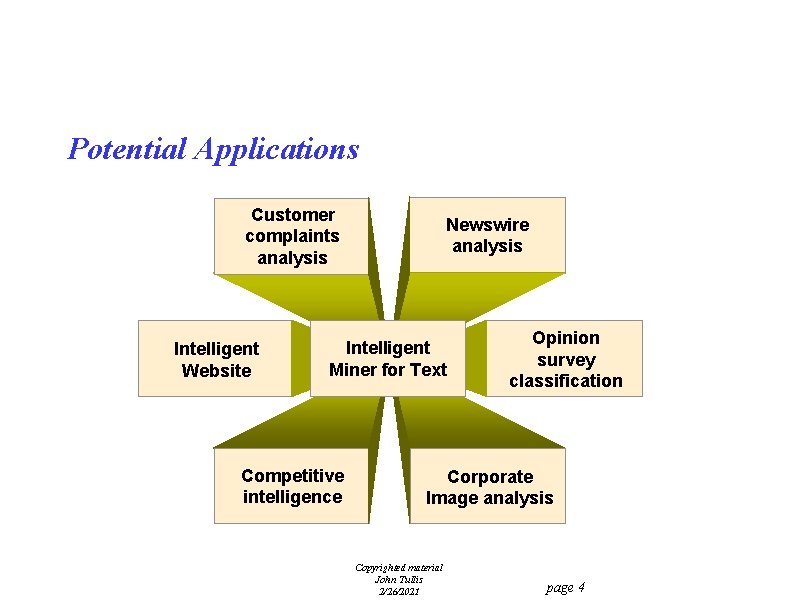
Potential Applications Customer complaints analysis Intelligent Website Newswire analysis Intelligent Miner for Text Competitive intelligence Opinion survey classification Corporate Image analysis Copyrighted material John Tullis 2/26/2021 page 4
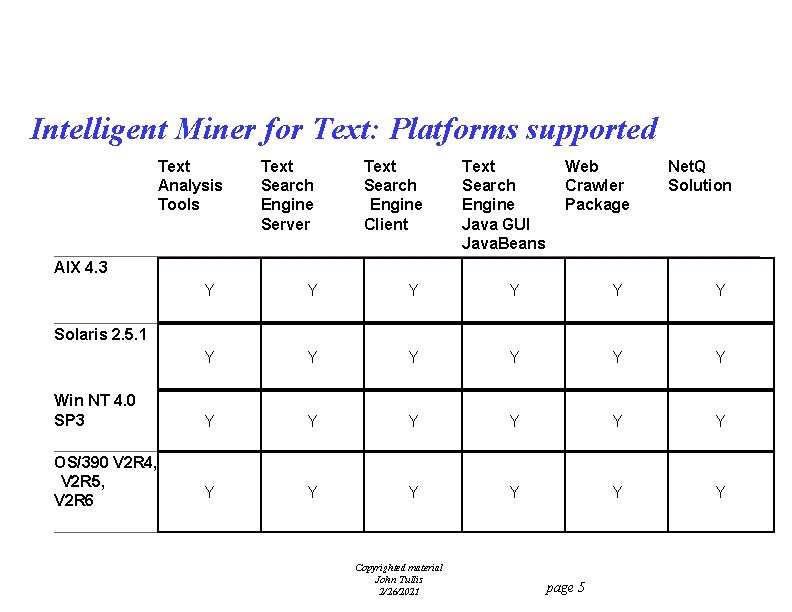
Intelligent Miner for Text: Platforms supported Text Analysis Tools Text Search Engine Server Text Search Engine Client Text Search Engine Java GUI Java. Beans Web Crawler Package Net. Q Solution AIX 4. 3 Y Y Y Y Y Y Solaris 2. 5. 1 Win NT 4. 0 SP 3 OS/390 V 2 R 4, V 2 R 5, V 2 R 6 Copyrighted material John Tullis 2/26/2021 page 5
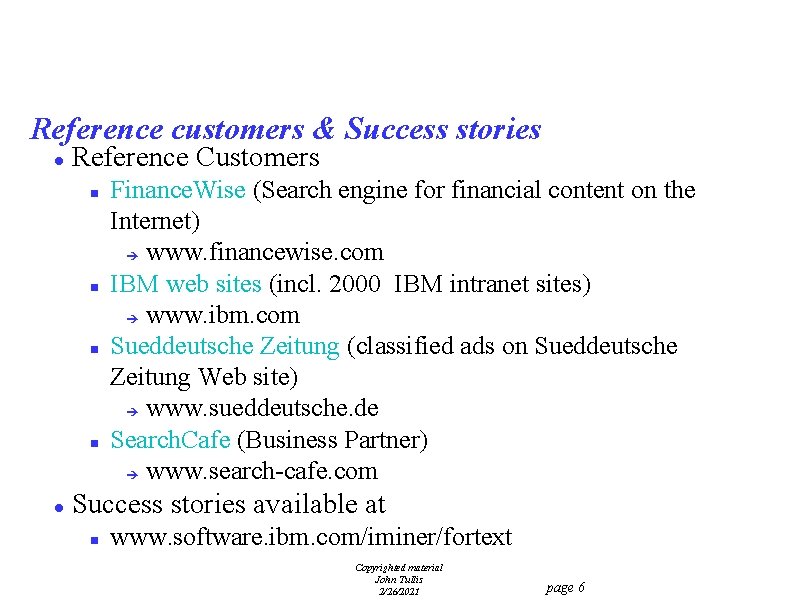
Reference customers & Success stories l Reference Customers n n l Finance. Wise (Search engine for financial content on the Internet) è www. financewise. com IBM web sites (incl. 2000 IBM intranet sites) è www. ibm. com Sueddeutsche Zeitung (classified ads on Sueddeutsche Zeitung Web site) è www. sueddeutsche. de Search. Cafe (Business Partner) è www. search-cafe. com Success stories available at n www. software. ibm. com/iminer/fortext Copyrighted material John Tullis 2/26/2021 page 6
Component: Text Analysis Tools Copyrighted material John Tullis 2/26/2021 page 7
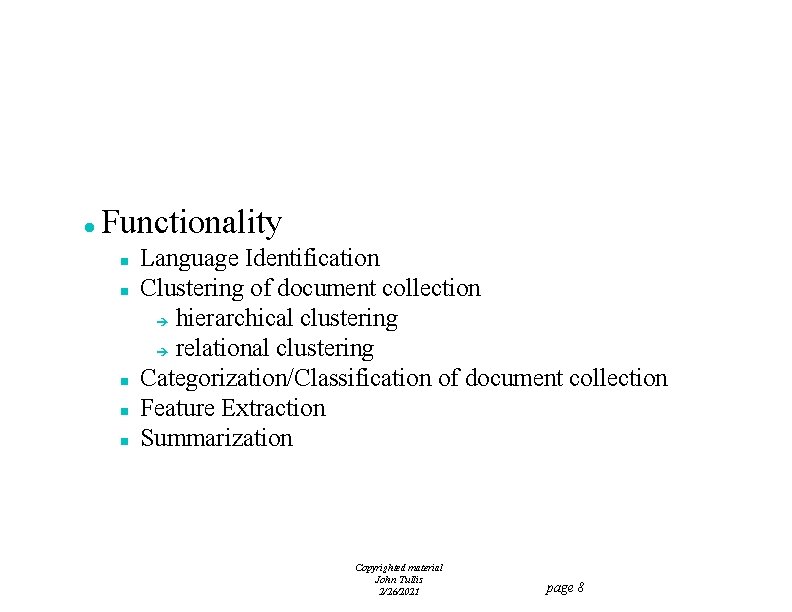
l Functionality n n n Language Identification Clustering of document collection è hierarchical clustering è relational clustering Categorization/Classification of document collection Feature Extraction Summarization Copyrighted material John Tullis 2/26/2021 page 8
Text Analysis Tools l To automate tasks previously done manually n automatically identifies the language of a document n automatically groups related documents based on their content, without requiring predefined classes n automatically assigns documents to one or more user-defined categories n automatically recognizes significant items in text, such as names, technical terms, and abbreviations n automatically extracts sentences from a document to create a document summary Copyrighted material John Tullis 2/26/2021 page 9
Text Analysis • Text analysis tools are available in a command line format structured to function like common UNIX or DOS command line formats. • Text analysis tools can be used individually or in a combined mode depending on the required task. • Configuration files allow document format flexibility and performance tuning for text searches. Command line switches provide additional flexibility by permitting the user to set runtime parameters. • The documents need to be provided in plain text format. For other formats, conversion tools can be obtained from third parties such as KEYpak (http: //www. keypak. com/ Copyrighted material John Tullis 2/26/2021 page 10
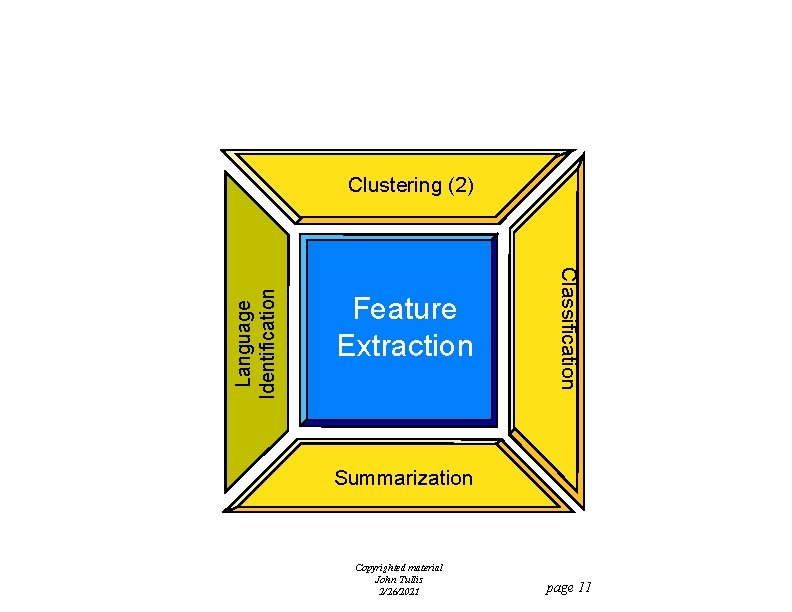
Feature Extraction Classification Language Identification Clustering (2) Summarization Copyrighted material John Tullis 2/26/2021 page 11
Text Analysis Tools: Feature Extraction l l l To recognize significant vocabulary items To recognize all names referring to a single entity To provide the location of all person names, places and organization in a text To find multi-word terms that have a meaning of their own To find abbreviations introduced in a text and links them with their full forms To recognize named relationships Copyrighted material John Tullis 2/26/2021 page 12
Text Analysis Tools: Feature Extraction • Produces statistics for each vocabulary item. • Associates terms to canonical forms (i. e. "related" associated to the term "relate") • Feature extraction can be used as a preprocessor for the Clustering utility to bias (or control) clustering activities. • Feature extraction can be run in two modes: 1) Lookup mode which refers to a schema generated by a training set and produces statistics for vocabulary items as they relate to the rest of the schema as well as within the document 2) Exploration mode which requires no training and yields textual data statistics for vocabulary items as they relate within the scope of the document(s) specified Copyrighted material John Tullis 2/26/2021 page 13
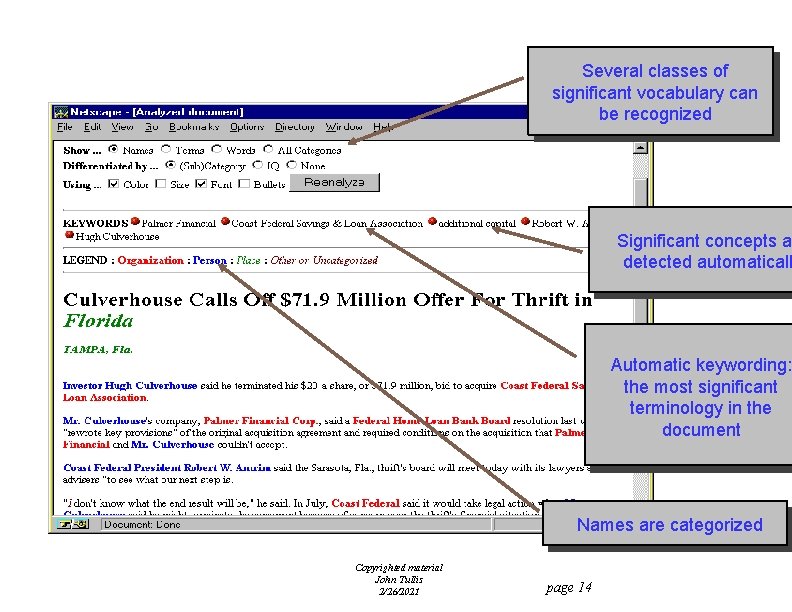
Several classes of significant vocabulary can be recognized Significant concepts ar detected automaticall Automatic keywording: the most significant terminology in the document Names are categorized Copyrighted material John Tullis 2/26/2021 page 14
Feature Extraction - statistics & analysis • Application here shows how one can use the statistics and analysis produced by the feature extraction. • Highlighting of selected items within a document by using the location information in the feature extract (all vocabulary terms have location information to accomplish this). • Selected categories can be filtered upon. • A significance measure for each vocabulary item is produced by feature extraction which allows prioritization of keywords within the scope of individual documents or entire collections. • This is a sample application which is not included in the software installation. Copyrighted material John Tullis 2/26/2021 page 15
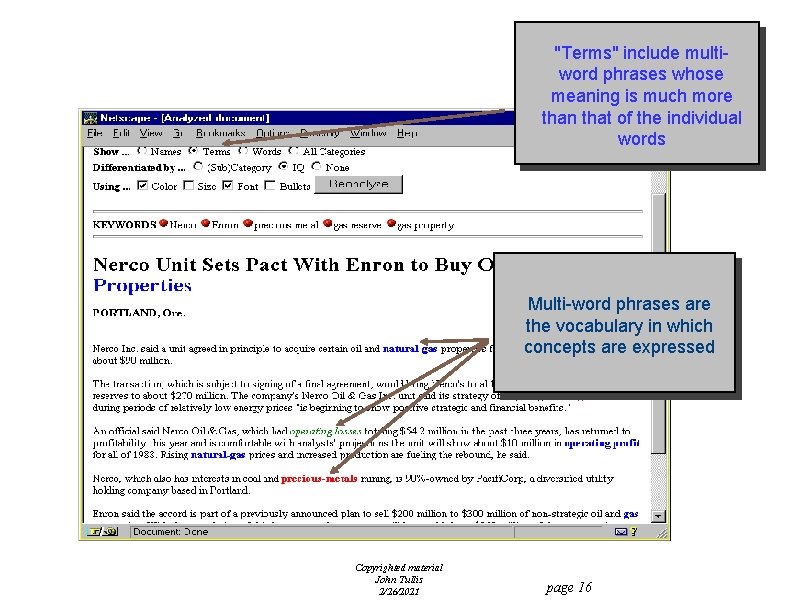
"Terms" include multiword phrases whose meaning is much more than that of the individual words Multi-word phrases are the vocabulary in which concepts are expressed Copyrighted material John Tullis 2/26/2021 page 16
Feature Extraction - statistics & analysis • Recognizes multi-word phrases by pattern recognition meaning if a two word pattern appears with an acceptable frequency then it is included as an extracted vocabulary item in the output. • More heuristics are applied than mentioned but generally this is the textual processing which occurs. • Concepts can be FORMULATED from the multi-word terms. The feature extraction utility assists in emphasizing prevalent multi-word terms. Copyrighted material John Tullis 2/26/2021 page 17
Feature Extraction Classification Language Identification Clustering (2) Summarization Copyrighted material John Tullis 2/26/2021 page 18
Language Identification given a document, discover automatically the language(s) in which the document is written l It can be used to l restrict search results by languages è organize the crawls by languages è route documents to language translators è Copyrighted material John Tullis 2/26/2021 page 19
Language Identification • A 16 language dictionary is shipped with the Intelligent Miner for Text to be used by the Language Identification utility. • The Language Identification utility also comes with a utility which can be used to add to the shipped dictionary file to extend language identification. (You can even invent your own language and add it to the dictionary!) • Documents can be analyzed for language content meaning the output of Language Identification can produce multiple degrees of language content in one pass (i. e. Document ABC has 75% English, 20% German, etc. ). This is possible using a command line option. • Allows further document organization by language and a degree of internationalization to applications. Copyrighted material John Tullis 2/26/2021 page 20
Feature Extraction Classification Language Identification Clustering (2) Summarization Copyrighted material John Tullis 2/26/2021 page 21
Categorization/Classification l l l given a defined taxonomy, it can assign documents to preexisting categories utilizes feature extraction capacities to do document comparisons efficiently two stages è training using sample documents è category assignment Copyrighted material John Tullis 2/26/2021 page 22
Categorization/Classification • Users determine the taxonomy for organizing the documents into topics. • Users create training sets to define categories and use the supplied training utility. • Each document is analyzed and a rank value assigned as it relates to each category. • A command line switch allows the user to display varying numbers of categories with the document's associated rank value. • REMEMBER: The categories are predefined by the user. Copyrighted material John Tullis 2/26/2021 page 23
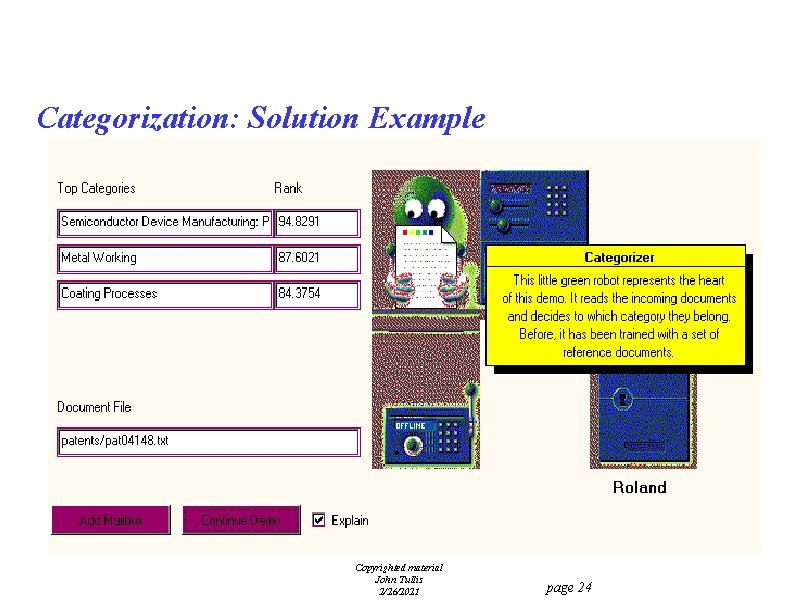
Categorization: Solution Example Copyrighted material John Tullis 2/26/2021 page 24
Feature Extraction Classification Language Identification Clustering (2) Summarization Copyrighted material John Tullis 2/26/2021 page 25
Clustering l Functions to automatically group related documents based on their content, without requiring predefined classes è objects within a group are more similar to each other than to members of any other group è two approaches - Hierarchical clustering and binary relational clustering è Copyrighted material John Tullis 2/26/2021 page 26
Clustering - Details l l Preprocessing steps n Analyze data input stream and divide it into individual textual components to be used for clustering n Extract portions of individual textual components to be used for clustering (uses Feature Extraction as a preprocessor) n Customize stop word list Hierarchical clustering n Structure document collection using lexical affinity based on similarity function n Build clustering tree showing relationships between clusters of documents of varying granularity Copyrighted material John Tullis 2/26/2021 page 27
Clustering - Details Slicing n Customize tree by applying adjustable thresholds to reduce complexity and zoom-in on concepts of interest è Use default threshold values for specific document collection è Note - slicing allows merging similar clusters into a single cluster. l Clustering Output Formats n HTML file viewable by browser n Textual description to be parsed (in the format of a tree) l Copyrighted material John Tullis 2/26/2021 page 28
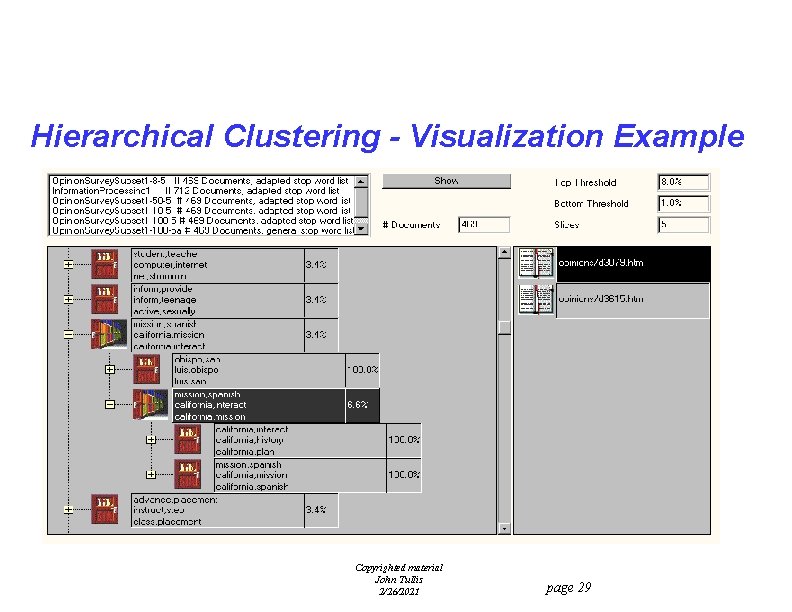
Hierarchical Clustering - Visualization Example Copyrighted material John Tullis 2/26/2021 page 29
Clustering - Details • This is a sample application which shows the use of the clustering results in an HTML format. This application is not shipped with the software. • The HTML output can be configured to place actual document paths in the display on the browser so users may easily view the documents which were clustered RIGHT FROM THE BROWSER. • Clusters each have labels which are generated from three 2 word pairings which are the most common lexical affinities • Similarity values in the application are represented by percentages. This is normalized as the similarity values actually range from 0 to 1000. Copyrighted material John Tullis 2/26/2021 page 30
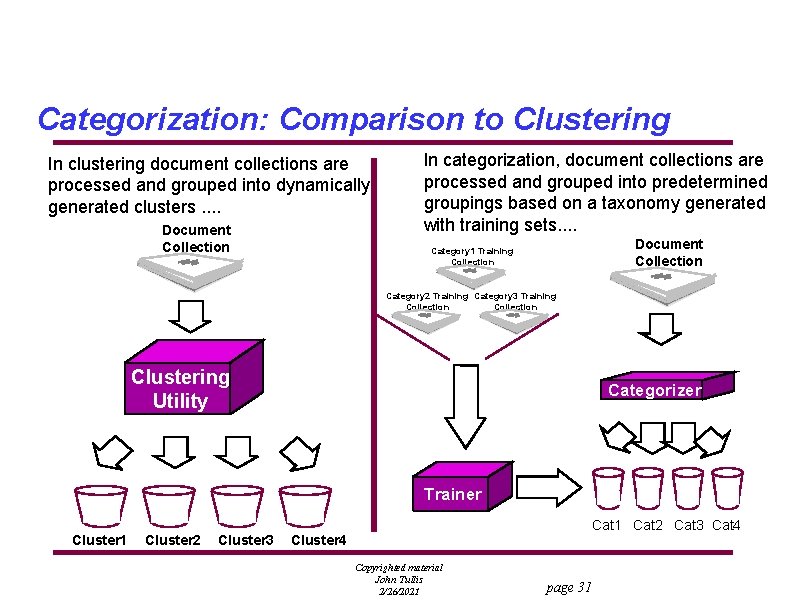
Categorization: Comparison to Clustering In clustering document collections are processed and grouped into dynamically generated clusters. . Document Collection In categorization, document collections are processed and grouped into predetermined groupings based on a taxonomy generated with training sets. . Document Collection Category 1 Training Collection Category 2 Training Category 3 Training Collection Clustering Utility Categorizer Trainer Cluster 1 Cluster 2 Cluster 3 Cat 1 Cat 2 Cat 3 Cat 4 Cluster 4 Copyrighted material John Tullis 2/26/2021 page 31
Feature Extraction Classification Language Identification Clustering (2) Summarization Copyrighted material John Tullis 2/26/2021 page 32
Summarization l Extracts sentences from a document to create a document summary n Sentence selection is based on document structure and ranking of extracted features Copyrighted material John Tullis 2/26/2021 page 33
Component: Text Search Engine Copyrighted material John Tullis 2/26/2021 page 34
Text Search Engine Boolean queries Hybrid queries Fuzzy search Free-text queries Synonyms search Copyrighted material John Tullis 2/26/2021 page 35
Text Search Engine l Search Engine offers multiple search paradigms - boolean, free text, fuzzy, hybrid, etc. è supports linguistic analysis for documents in 21 languages including Arabic and Hebrew è features Boolean queries, precise term search and fuzzy search for 4 DBCS languages è l Mining Functions to extract key features in text è to cluster result list è to refine queries è l Integrated in IBM DB 2 Digital Library and IBM DB 2 UDB Text Extender Copyrighted material John Tullis 2/26/2021 page 36
Text Search Engine • A user can refine searches meaning that they can reuse previous search result sets to perform additional searches. • Multilingual linguistic analysis performed: • - basic text analysis (recognizing terms, normalizing terms, recognizing sentence boundaries) • - reducing terms to their base form • - stop word filtering • - decomposition (splitting compound terms) Copyrighted material John Tullis 2/26/2021 page 37
Basic Text Seach Engine functions l Included as part of the basic functional set in the Text Search Engine n n n n n Precise index ngram index linguistic index 21 SBCS languages 4 DBCS languages relevance ranking boolean queries free text queries fuzzy and phonetical searches thesaurus support Copyrighted material John Tullis 2/26/2021 page 38
Text Search Engine: Details n n Document support for single byte character set language Document support for double byte character set languages Linguistic search: è Dictionaries and synonyms lists for SBCS languages è Terms are reduced to their base form, terms are decomposed, terms are normalized to stand form è Boolean query: Operators: AND, NOT, OR è Natural language query/free text query: To formulate a query in natural language Hybrid query: è To combine a natural language query with a Boolean search term Copyrighted material John Tullis 2/26/2021 page 39
Text Search Engine: Details n n Fuzzy query: è To find misspell words: TOYOTA/TOYOTTA, DATABASE/DATABSAE Phonetical query: è Technique: remove vowel (s) from search term and replace it/them with masking characters, eliminate duplicate consonants è To search for similar-sounding words: COLOR/COLOUR, SMITH/SMYTH, JANET/JEANNETTE. . . è Wildcard support for Boolean queries : Front, middle and end masking for word and character masking Copyrighted material John Tullis 2/26/2021 page 40
Text Search Engine: Even more details! l Section support n n n l Able to define a section of a document Restrict the search to given sections Example : define a section called Summary è Limit search scope within the Summary section Thesaurus support n n n for all index types and many languages ngram index thesaurus (workstation only) è Synonyms and broader/narrower terms è DBCS language synonym support Not supported for Bi. Di languages or Russian Copyrighted material John Tullis 2/26/2021 page 41
Text Search Engine: Text Mining Functions l Provides text mining functions for English documents Feature extractions è Organize result list è l Supports query refinement method for English documents n User assigns value to single documents Copyrighted material John Tullis 2/26/2021 page 42
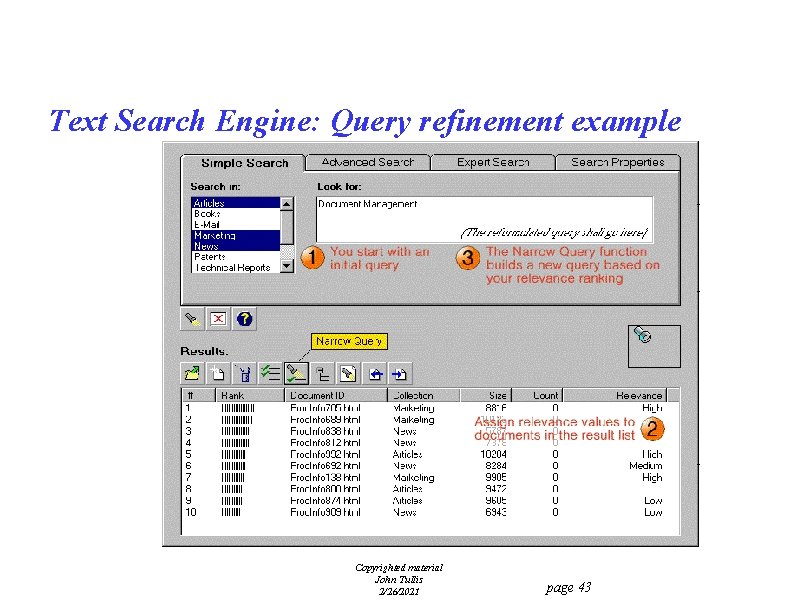
Text Search Engine: Query refinement example Copyrighted material John Tullis 2/26/2021 page 43
Query Refinement Example • This is a snap shot of the Java GUI which is shipped with Intelligent Miner for Text. The source code and instructions are shipped and must be compiled by the end user to be operational. • Interacts with the Text. Miner Java server. • Comprised of Java Beans which are shipped with Intelligent Miner for Text. The Beans can also be built and integrated into other applications to interact with Intelligent Miner for text. • The Java GUI provides a "ready-to-go" search GUI to interact with the Advanced Search engine. User can perform various levels of queries and even browse the documents themselves by double clicking in the window. • Users must use a full Java enabled browser to run this pure Java applet. Copyrighted material John Tullis 2/26/2021 page 44
Where to find the Text Search Engine functions Basic functions n S/390 Text Search Download for OS/390 V 2. 4 - V 2. 6 n IM 4 T V 2. 3 workstations l Extended functions (result list clustering, relevance feedback/query refinement, feature index) n IM 4 T V 2. 3 for OS/390 n IM 4 T V 2. 3 for Workstations l Copyrighted material John Tullis 2/26/2021 page 45
Component: Java & Java. Beans Copyrighted material John Tullis 2/26/2021 page 46
Java Components Java Search GUI - fully operational, NLS enabled l Java. Beans for Rapid Application Development n Search n Administration l Source is available and intended to be used as a 'starter kit' l Works with the Text Search Engine l Copyrighted material John Tullis 2/26/2021 page 47
Java Components - Details l l GUI Enhancements n Enhanced error recovery, help Use with Net. Scape and MS Internet Explorer n Internet Explorer 3. 02 and 4. 0 for NT n Internet Explorer 4. 0 for Win 95/98 n Net. Scape Navigator 3. 0/4. 0 for Win 95/98/NT n Net. Scape Navigator 3. 0/4. 0 Solaris/SPARC n Net. Scape Navigator 3. 0 for Solaris/x 86 Supported via plugin found at n http: //java. sun. com/products/plugin/1. 1. 1/index. html Sun's Hot. Java Browser Copyrighted material John Tullis 2/26/2021 page 48
Component: Web. Crawler Copyrighted material John Tullis 2/26/2021 page 49
Web Crawler l Is a Robot used to collect HTML pages for indexing n Customizable as to which HTML links are to be crawled (include and exclude patterns. . . ) n Results are stored è Data objects on AIX/NT file systems è Metadata in DB 2 n Parallel crawling, results combined n HTML page change frequency used as revisiting factor n External subsystems can be notified of web changes detected by the crawler n Create individual crawler using crawler toolkit Copyrighted material John Tullis 2/26/2021 page 50
Web Crawler details • Uses regular expression configuration files to filter or retain crawled URL. • The data object are actual URL or documents. The size and type of URL to be stored are also configurable using provided configuration file structure. • Storage is scaleable by mounting disk storage to file system storage locations • Multiple crawlers can be run at once. The only known limitation is physical machine processing and storage capacities. Copyrighted material John Tullis 2/26/2021 page 51
Web Crawler details • Crawlers will dynamically adjust to increase monitoring for pages which change more frequently and vice-versa. This feature is also user configurable. • Flexible API toolkit provide for the web crawler to assist in tasks such as forwarding of workflow messages • API toolkit can also be used to allow the user to build their own crawler using provided components. Sample code is included to assist in the development. Copyrighted material John Tullis 2/26/2021 page 52
Web Crawler Package l consists of 2 components n n A ready-to-run Web Crawler A Web Crawler toolkit to build customized Web crawlers Copyrighted material John Tullis 2/26/2021 page 53
The Net. Question Solution Copyrighted material John Tullis 2/26/2021 page 54
Net. Question Solution A Pre-built ready to use Internet/intranet textsearch solution for searching a local Web server l A multiserver domain solution based on the Text Search Engine and Web Crawler l Copyrighted material John Tullis 2/26/2021 page 55
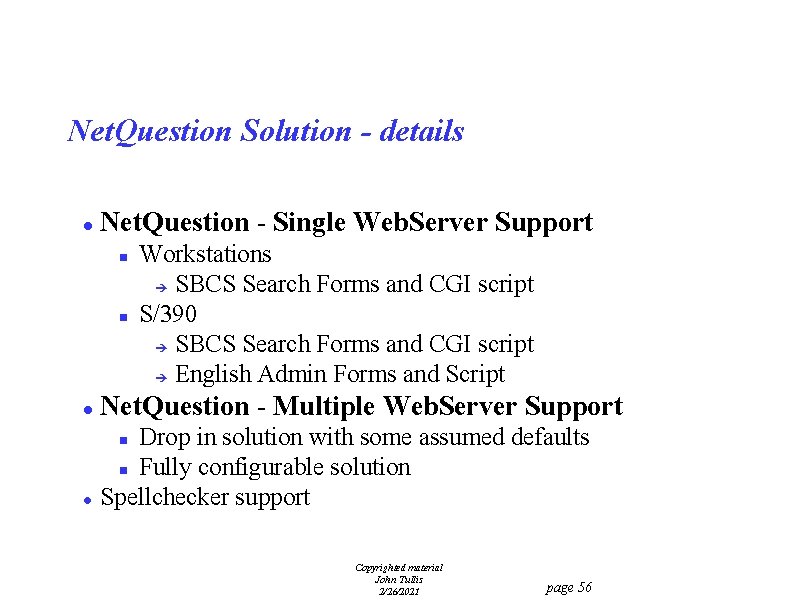
Net. Question Solution - details l Net. Question - Single Web. Server Support n n Workstations è SBCS Search Forms and CGI script S/390 è SBCS Search Forms and CGI script è English Admin Forms and Script l Net. Question - Multiple Web. Server Support l Drop in solution with some assumed defaults n Fully configurable solution Spellchecker support n Copyrighted material John Tullis 2/26/2021 page 56
Natural Language Support Copyrighted material John Tullis 2/26/2021 page 57
NLS Support l l l IBM Text Search Engine n 18 SBCS Languages è US English, UK English, Catalan, Danish, Dutch, German, Swiss German, Spanish, Finnish, French, Canadian French, Icelandic, Italian, Norwegian Bokma. , Norwegian Nynmal, Portuguese, Brazilian Portuguese, and Swedish plus Russian, Hebrew (Bi. Di), Arabic (Bi. Di) n 4 DBCS Languages (Japanese, S Chinese, T Chinese, Korean) Text Analysis Tools n Language ID can identify 14 languages n all other tools are English only EURO support (new code page 8859 -15) n TATools to recognize Euro Abbr Copyrighted material John Tullis 2/26/2021 page 58
NLS Support - Messages and GUI l l l Fully enabled messages across all platforms Ship translations in all Group I languages (English , French, German, Italian, Spanish, Brazilian Portugese, Simplified Chinese, Traditional Chinese, Japanese, Korean) Java Search GUI sample is enabled, not to be translated Java. Beans not enabled Net. Q Solution on S/390 n NLS for Search forms and scripts (English, French, German, Italian, Spanish, Brazilian Portugese, Danish, Swedish, Norwegian, Finnish, Simplified Chinese, Traditional Chinese, Japanese, Korean) n No NLS of Admin Search forms and scripts Copyrighted material John Tullis 2/26/2021 page 59
Documentation Copyrighted material John Tullis 2/26/2021 page 60
Documentation l l On-line Documentation in HTML for workstation product S/390 Relies upon documentation on workstation CD-ROMs PDFs are shipped on workstation CD-ROMs Online Documentation Search available for all workstation platforms Copyrighted material John Tullis 2/26/2021 page 61
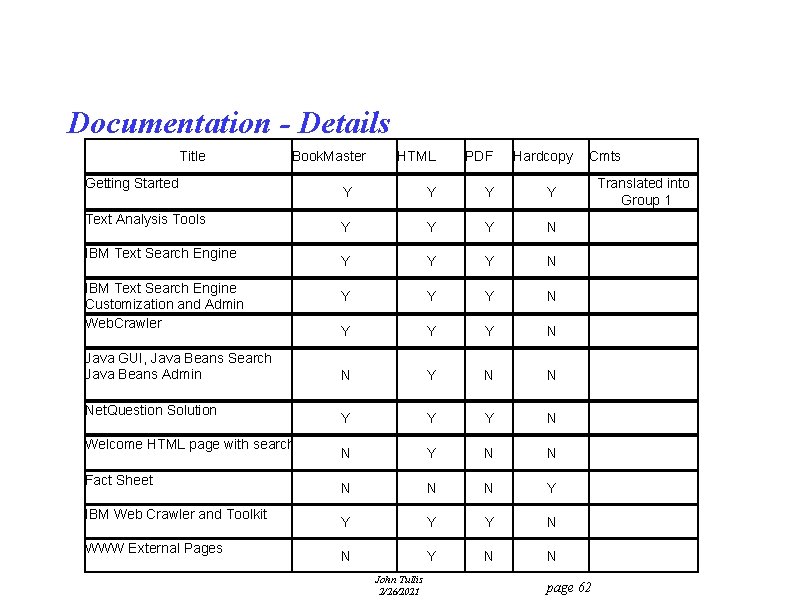
Documentation - Details Title Book. Master Getting Started Text Analysis Tools IBM Text Search Engine Customization and Admin Web. Crawler Java GUI, Java Beans Search Java Beans Admin Net. Question Solution Welcome HTML page with search Fact Sheet IBM Web Crawler and Toolkit WWW External Pages HTML PDF Y Y Y Y N Y Y Y N N N Y Y N Y N N N Copyrighted material John Tullis 2/26/2021 Hardcopy Cmts page 62 Translated into Group 1
Presentation Summary Copyrighted material John Tullis 2/26/2021 page 63
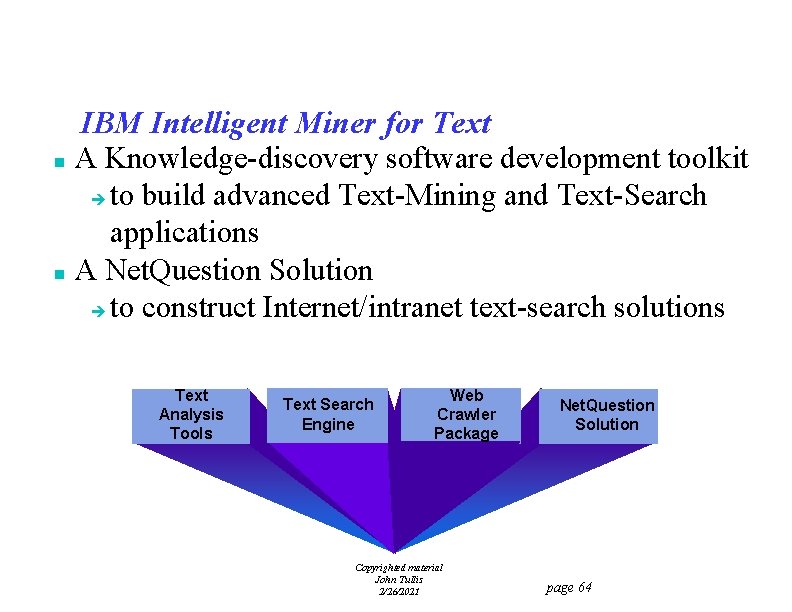
IBM Intelligent Miner for Text n A Knowledge-discovery software development toolkit è to build advanced Text-Mining and Text-Search applications n A Net. Question Solution è to construct Internet/intranet text-search solutions Text Analysis Tools Text Search Engine Web Crawler Package Copyrighted material John Tullis 2/26/2021 Net. Question Solution page 64
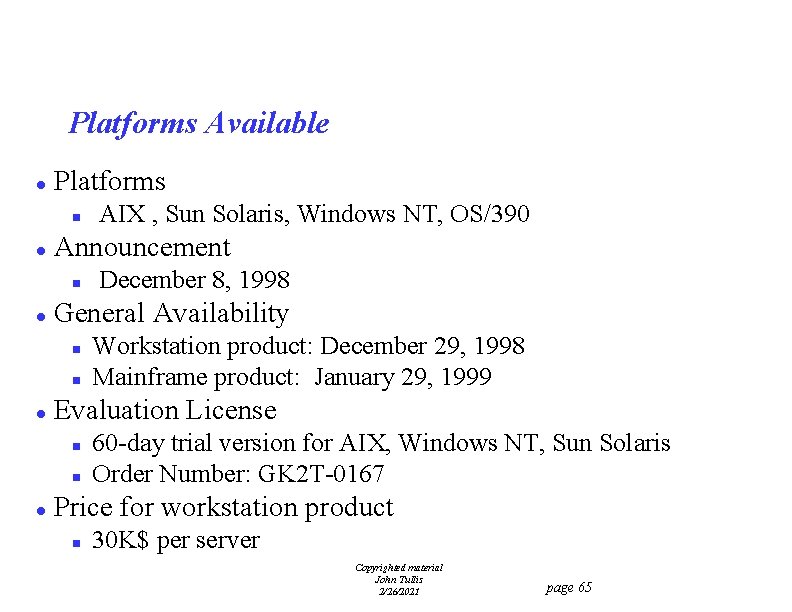
Platforms Available l Platforms n l Announcement n l n Workstation product: December 29, 1998 Mainframe product: January 29, 1999 Evaluation License n n l December 8, 1998 General Availability n l AIX , Sun Solaris, Windows NT, OS/390 60 -day trial version for AIX, Windows NT, Sun Solaris Order Number: GK 2 T-0167 Price for workstation product n 30 K$ per server Copyrighted material John Tullis 2/26/2021 page 65
Intelligent Miner for Text n Web presence è Product Features, Downloads, News, Library, Business partners, Case studies, Service, Support, Feedback è www. software. ibm. com/iminer/fortext Copyrighted material John Tullis 2/26/2021 page 66
- Slides: 66