
Googles Map Reduce Commodity Clusters Web data sets
Google’s Map Reduce
Commodity Clusters • Web data sets can be very large – Tens to hundreds of terabytes • Standard architecture emerging: – Cluster of commodity Linux nodes – Gigabit Ethernet interconnect • How to organize computations on this architecture?
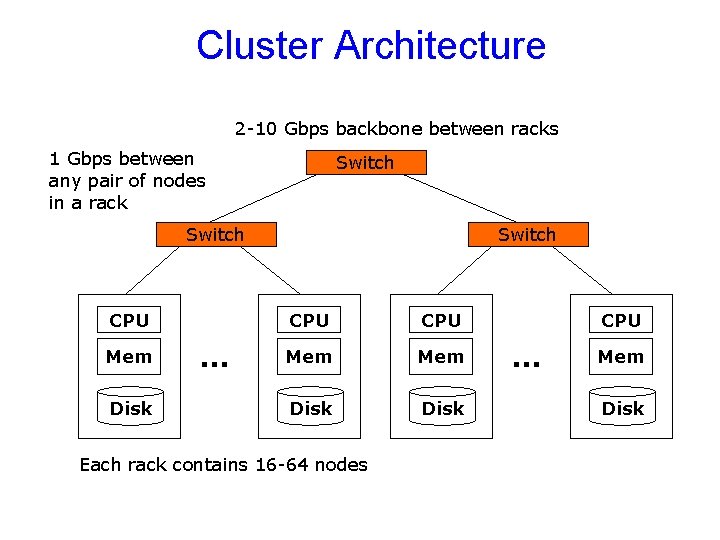
Cluster Architecture 2 -10 Gbps backbone between racks 1 Gbps between any pair of nodes in a rack Switch CPU Mem Disk … Switch CPU Mem Disk Each rack contains 16 -64 nodes CPU … Mem Disk
Map Reduce • Map-reduce is a high-level programming system that allows database processes to be written simply. • The user writes code for two functions, map and reduce. • A master controller divides the input data into chunks, and assigns different processors to execute the map function on each chunk. • Other processors, perhaps the same ones, are then assigned to perform the reduce function on pieces of the output from the map function.
The Map Function • Each map process is given a chunk of input data • Input is thought of as a set of key-value records. • Output is a set of key-value pairs. – Of course not the same as the key-value pairs in the input. – The "keys" are not true keys in the database sense. • That is, there can be many pairs with the same key value.
Map Example Constructing an Inverted Index Map Function • Input is a set of (i, d) pairs – i is document ID – d is corresponding document. • The map function scans d and for each word w it finds, it emits the pair (w, i). – Notice that in the output, the word is the key and the document ID is the associated value. • Output is a list of word-ID pairs. – Not necessary to catch duplicate words in the document; this can be done later, at the reduce phase.
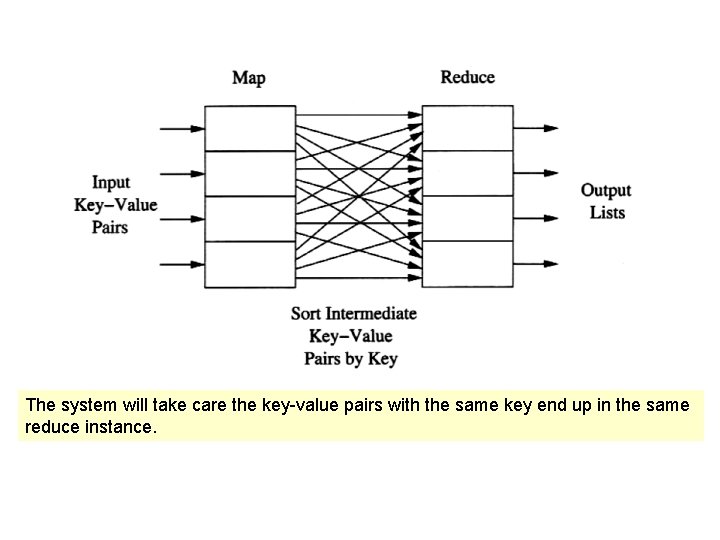
The system will take care the key-value pairs with the same key end up in the same reduce instance.
The Reduce Function • Input to reduce is a set of key-value pairs that were output by map instances. – All the key-value pairs with the same key end up in the same reduce instance. – A set (k, v 1), …, (k, vn) of key-value pairs can be considered as (k, [v 1, …, vn]). • Reduce function combines the list of values associated with a given key k.
Reduce Example Constructing an Inverted Index Reduce Function • The intermediate result consists of pairs of the form (w, [i 1, i 2, …, in]), – where the i's are a list of document ID's, one for each occurrence of word w. • The reduce function takes a list of ID's, eliminates duplicates, and sorts the list of unique ID's.
Parallelism • This organization of the computation makes excellent use of whatever parallelism is available. • The map function works on a single document, so we could have as many processes and processors as there are documents in the database. • The reduce function works on a single word, so we could have as many processes and processors as there are words in the database. • Of course, it is unlikely that we would use so many processors in practice.
Another Example – Word Count Construct a word count. • For each word w that appears at least once in our database of documents, output pair (w, c), where c is the number of times w appears among all the documents. The map function • Input is a document. • Goes through the document, and each time it encounters another word w, it emits the pair (w, 1). • Intermediate result is a list of pairs (w 1, 1), (w 2, 1), …. The reduce function • Input is a pair (w, [1, 1, . . . , 1]), with a 1 for each occurrence of word w. • Sums the 1's, producing the count. • Output is word-count pairs (w, c).
What about Joins? R(A, B) S(B, C) The map function • Input is key-value pairs (X, t), – X is either R or S, – t is a tuple of the relation named by X. • Output is a single pair (b, (R, a)) or (b, (S, c)) depending on X – b is the B-value of t (if X=R). – c is the C-value of t (if X=C). The reduce function • Input is a pair (b, [(R, a), (S, c), …]). • Extracts all the A-values associated with R and all C-values associated with S. These are paired in all possible ways, with the b in the middle to form a tuple of the result.
Reading • Jeffrey Dean and Sanjay Ghemawat, Map. Reduce: Simplified Data Processing on Large Clusters http: //labs. google. com/papers/mapreduce. html • Hadoop (Apache) – Open Source implementation of Map. Reduce http: //hadoop. apache. org/core
- Slides: 13