
FINDING INFORMATION ON THE WEB Srinivasan Seshadri CTO
FINDING INFORMATION ON THE WEB Srinivasan Seshadri CTO Kosmix
EARLY INTERNET (1992 – 1994) Mozilla Browser People linked to others home pages and other interesting pages People really browsed
INTERNET (1995 – 2002) Search - Altavista, Lycos Google Used Hyperlink Graph Structure to Rank Results
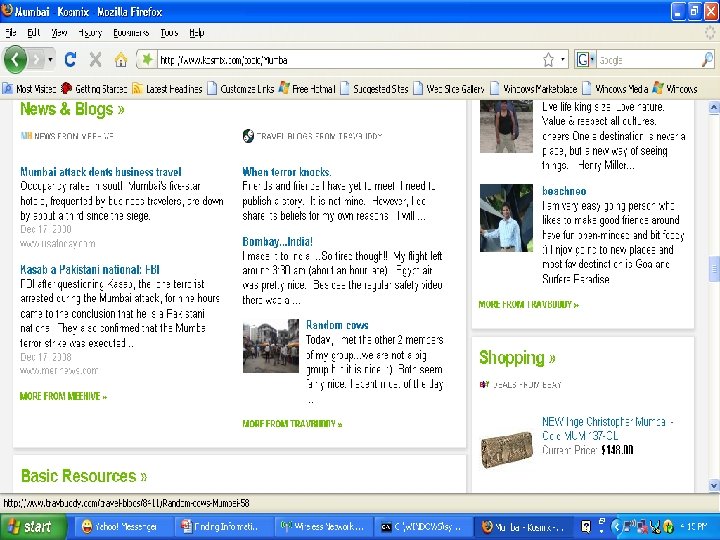
INTERNET NOW Kosmix bringing back joys of browsing and exploring 360 degree view of any topic Topic Home page (why not a topic ) Top Informational Sites for a topic and a preview (snippets) are the results!
INFORMATION TYPES Factual Information (Wiki etc. ) Videos Images Forum Discussions Question and Answers News Blogs Structured Information
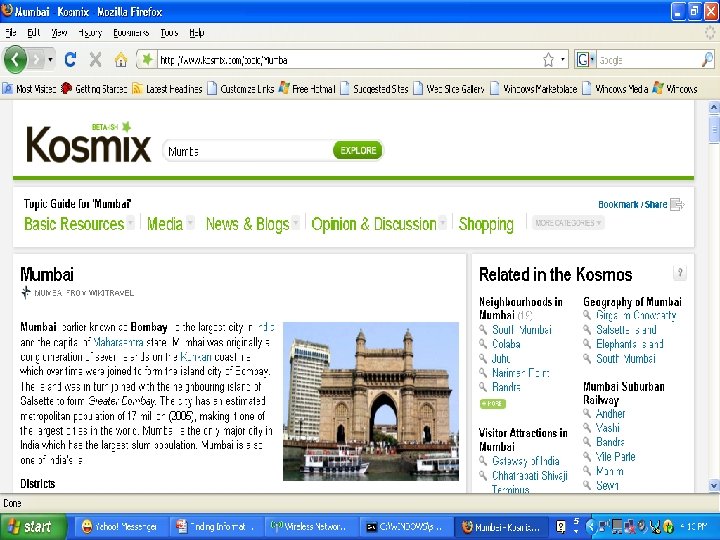
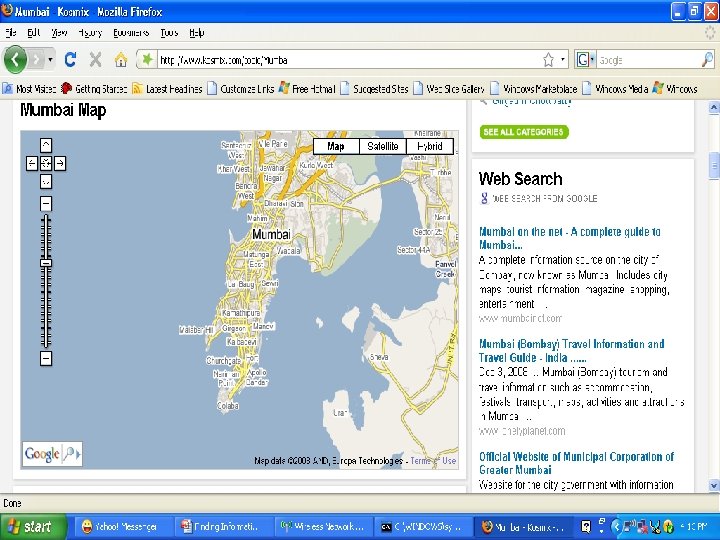
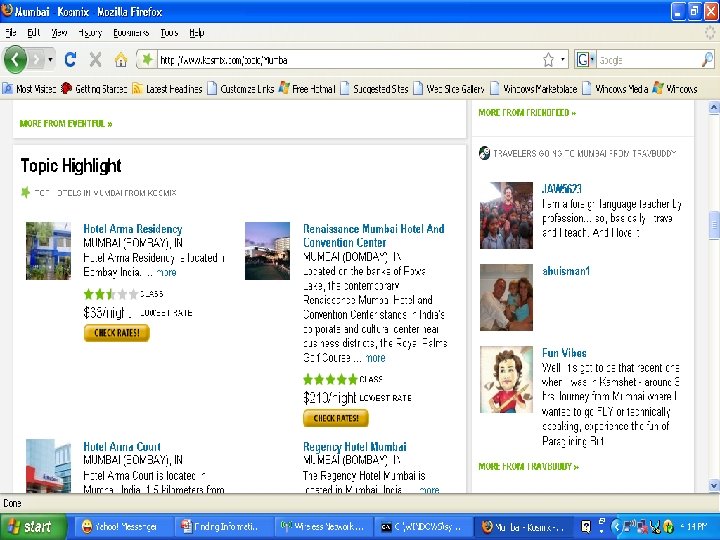
FUTURE OF SEARCH First step towards providing multiple pivot points for a topic or search Need to make this conversational, stateful – like talking to an expert on the topic. .
TRANSIENT INTENT AND PERSISTENT INTENT TRANSIENT INTENT Searching for a needle in the haystack Exploring the haystack for a topic PERSISTENT INTENT Interested in the topic for a long time Carnatic Music, Indian Cricket, Internet Industry, Venture Capital
INFORMATION Deliver information to the consumer what they want when they want how they want where they want
PERSONALIZED NEWSPAPER My World is Changing Can not keep track of it Can my world come to me?
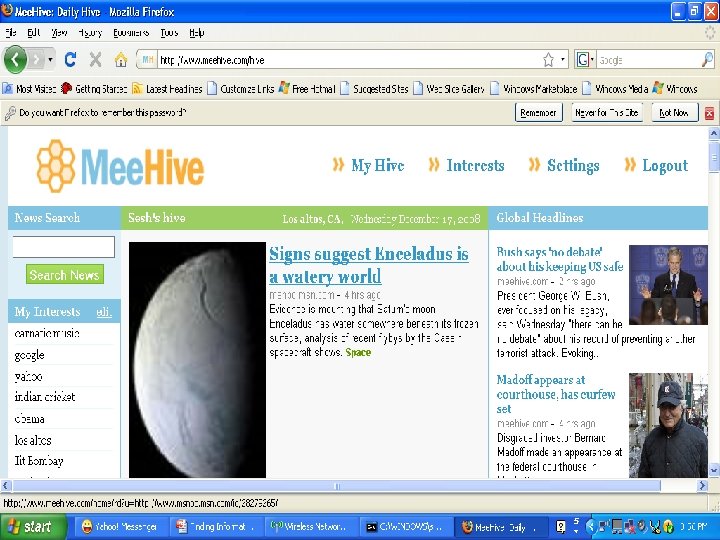
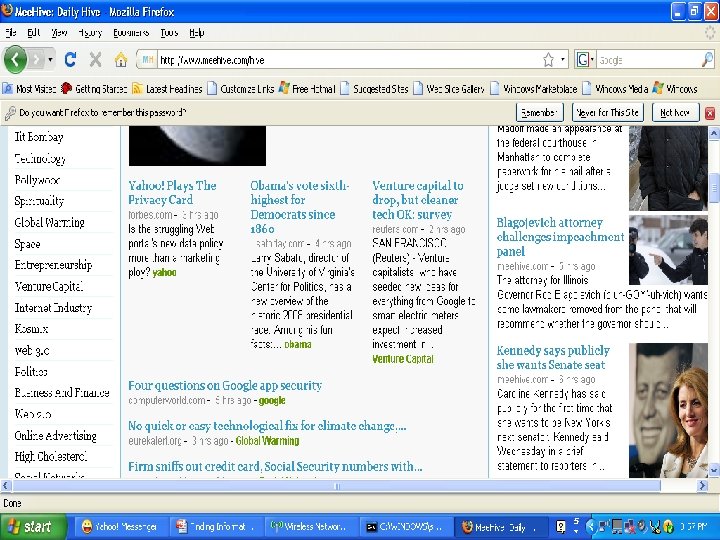
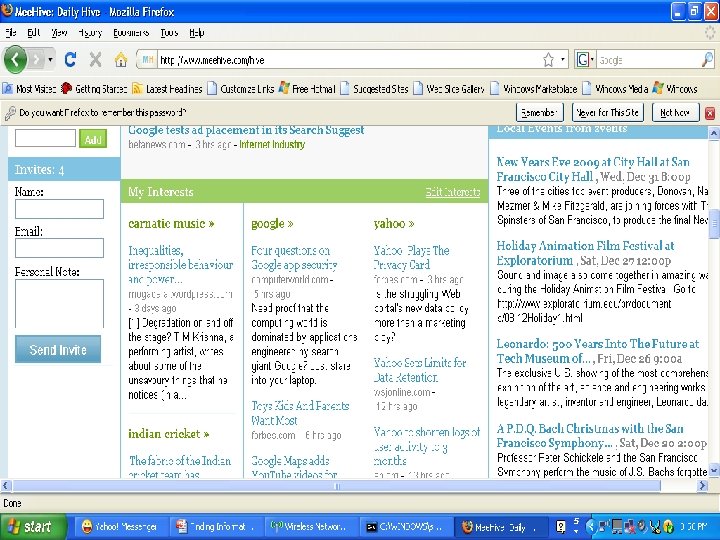
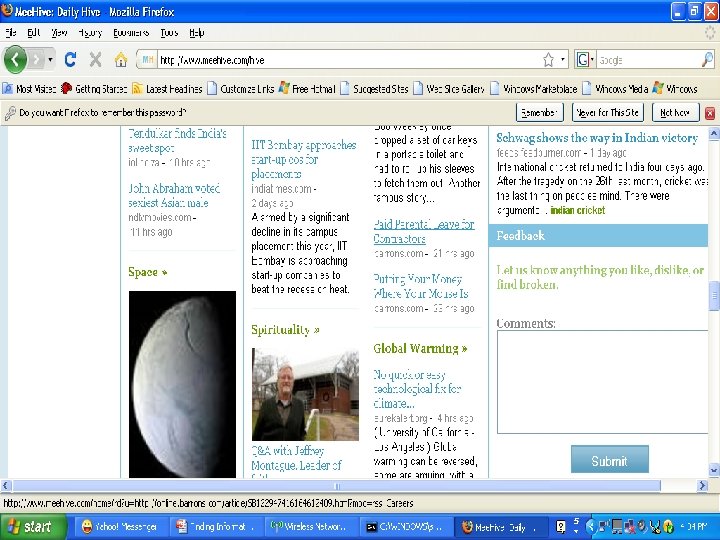
MEDIA INDUSTRY AND INTERNET Huge pressure on newspapers Ad spending moving online More and more content online Reputed journalists have their own blogs Content Production; Aggregation and Distribution is becoming disaggregated Vanilla online newspaper does not exploit what the internet enables Ability to personalize to nano interests Publish a personalized newspaper for everyone any time
KEY TECHNOLOGY INGREDIENTS Cloud Computing Categorization Relevance
CLOUD COMPUTING AT KOSMIX Storage: Biggest Productivity boost in kosmix in the first year Getting machines to be remotely rebooted! KFS (Kosmix File System) further lowered the time to make data accessible after machine failures Computation: Long Running Computations need to be broken into small restartable/replayable components
CLOUD COMPUTING AT KOSMIX Computation Templates: Most of the computation could be expressed as some variant of a single table scan and some aggregate operation (group by) -- called Map. Reduce by google Map. Reduce not friendly enough to non programmers SQL not powerful enough in many situations Need a nice scripting language. .
OPPORTUNITY? Many many companies trying to provide interesting web services A gold mine of information in the web that can be used by companies Impractical for each of the companies to build a huge web scale support system (crawling, indexing, KFS, Map. Reduce etc. ) Further most companies want slivers of the web (typically category based slivers – health forums; travel news sites etc. ) Web and all the derived information is the biggest database perhaps -- can some one make this accessible and easy to use (using some pay you go model) or perhaps some non profit (academia? ) angle here?
CATEGORIZATION Concept Space: space in which all connections are made within kosmix Documents, Queries, External Modules, Advertisements, People are all mapped to points in this space and matched. . Internet Industry, Venture Capital documents need to be mapped to these categories even if they don’t contain the original words
KATEGORIZATION AT KOSMIX Leverage human curated sources Wiki corpus is a majorr source of knowledge Huge Automatically Curated Taxonomy 6 million concepts Building a Concept Graph with relationship labels where possible Use a web index to match short pieces of texts with concepts and use taxonomy to refine the matches
RELEVANCE Need to combine multiple signals into one number to enable ranking Say Query Relevance Score and Page Relevance Score (text score and page rank) Signals need to be made comparable Normalization alone (making ranges the same) is not enough Need to reconcile different distributions Deviations from the mean
RELEVANCE More data always beats smarter algorithms Adding positions information in the index greatly increases quality Adding stemming saw a CTR rise of 10% Adding anchors (and page rank) distinguished google Adding origin of anchors (hosts) is a much better measure of independent votes Using demand side popularity (alexa, quantcast) complement web popularity
RELEVANCE What is a news story? Cluster news articles. . Use size of cluster as a measure of popularity How does one do this efficiently? Needs to be online since interests/queries are ad hoc Need to combine some offline preclustering and online methods
SUMMARY Consumer: Internet has come a long way in terms of getting information to people Utopian goal of a smart, chatty expert still far away – kosmix. com is a great first step Need good tools to keep on top of the information explosion – personalized newspaper (meehive. com) is our first stab at this. . Technology: Need to deal with large volume of data Efficient Data Analysis and Annotation (e. g. , Categorization) Humming Next Gen Database System that grows incrementally, immune to failures, expressive for non programmers
- Slides: 28