
Experiences with the g Lite WMS Andrea Sciab
Experiences with the g. Lite WMS Andrea Sciabà CERN JRA 1 All-Hands meeting 8 -10 November 2006 Abingdon, UK
Outline n n Motivations Testing and using the g. Lite WMS n n n n The The ATLAS experience CMS experience LHCb experience ARDA experience Current status of the g. Lite 3. 0 WMS First look to the g. Lite 3. 1 WMS Conclusions
Motivations (I) n The LCG Resource Broker is robust but n The code is basically frozen n The Network Server submission is too slow n n Job submission may require tens of seconds/job when the RB is loaded The maximum job rate is limited n n no new features difficult to have bug fixes Experience from the LHC experiments indicates that the LCG RB cannot handle more than ~7000 jobs/day It does not support the renewal of VOMS proxies n VOMS proxies are now the standard because they allow for fine -grained authorization (data access, job priorities)
Motivations (II) n The g. Lite WMS improves on almost every aspect n Higher job submission and dispatching rate n n n More job types (DAG, collections, parametric) Automatic zipping of sandboxes and many other features n n Typical submission rate: 0. 5 s/job Typical dispatching rate: 3/s job Job Perusal, support for VOViews with VOMS FQAN-based access control, … The goal is to have also a g. Lite WMS at least as robust as the LCG RB n Not yet completely accomplished
Testing the g. Lite WMS (I) n A intensive testing activity started on mid July involving n n A few g. Lite WMS were installed at CERN, CNAF and Milan n n Initial tag: 3. 0. 2 RC 6 Bug fixes deployed as soon as available All instances were kept synchronized All the WMS were configured to see the EGEE production Grid n n Developers (JRA 1) SA 1, SA 3 EIS team (on behalf of the experiments) Necessary to run tests at a realistic scale The tests were primarily done by submitting jobs to LCG CEs n n The g. Lite 3. 0 CE is still too unreliable The focus was more on “getting the jobs done” than debugging the g. Lite CE
Testing the g. Lite WMS (II) n The testing process was primarily driven by ATLAS and CMS n ATLAS n n Committed to use the g. Lite WMS for the official Monte Carlo production on EGEE resources if the WMS did not work, part of the MC production stopped! The job load is determined by the production assignments CMS n n n A real CMSSW application was run but it did not perform real work The number of submitted jobs and collections was changed to determine the scalability of the WMS Now the g. Lite WMS is being used in production for the CSA 06
History of the bug fixes n n Upgrade of Condor (6. 7. 10 6. 7. 19) Fixed bug #18123 n n Condor configuration heavily modified n n n Job Wrapper tried to upload also non-existent files Discovered very poor I/O disk performance of the rb 102. cern. ch node and reconfigured the RAID arrays for optimal performance n n to speed up Condor submission Fixed bug #18725 n n To cure the tendency of DAGs to die GRIDMANAGER_MAX_JOBMANAGERS_PER_RESOURCE increased n n LB processes stuck in infinite loop This cured the high mortality of DAGs due to LB connection timeouts Reduced the number of planners per DAG to limit the number of concurrent planners, which used a lot of swap Reduced the number of WMProxy server processes n Limited but not cured the usage of swap memory by the WMProxy server
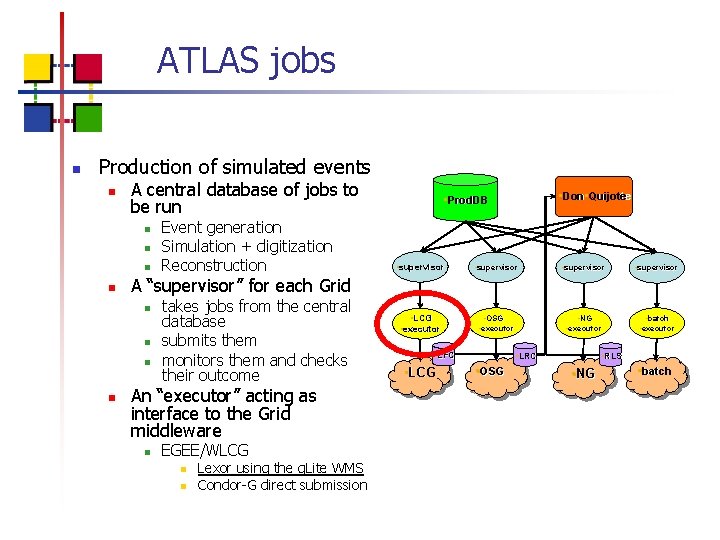
ATLAS jobs n Production of simulated events n A central database of jobs to be run n n • supervisor • LCG • executor • OSG • executor • NG • executor • batch • executor A “supervisor” for each Grid n n Event generation Simulation + digitization Reconstruction • Don • Quijote Quijotte • Prod. DB takes jobs from the central database submits them monitors them and checks their outcome An “executor” acting as interface to the Grid middleware n EGEE/WLCG n n Lexor using the g. Lite WMS Condor-G direct submission • LFC • • LCG • LRC • • OSG GRID 3 • RLS • • NG NG • • batch
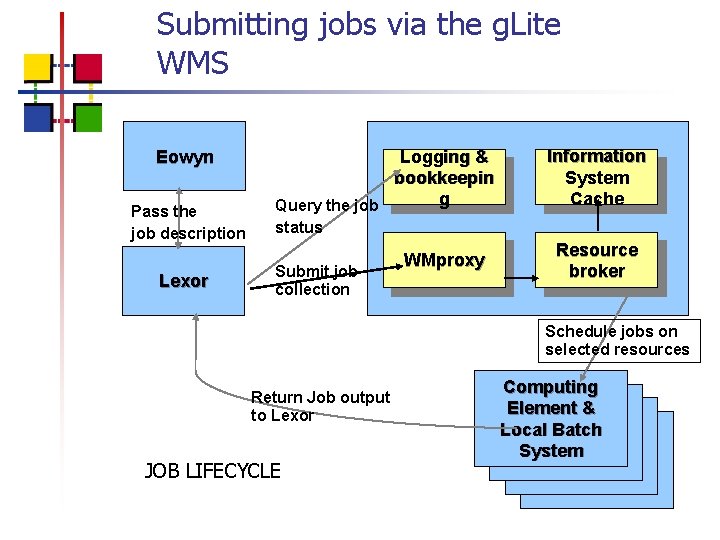
Submitting jobs via the g. Lite WMS Eowyn Pass the job description Lexor Logging & bookkeepin g Query the job Information System Cache status Submit job collection WMproxy Resource broker Schedule jobs on selected resources Return Job output to Lexor JOB LIFECYCLE Computing Element & Computing Local Batch Computing Element Computing System Element
ATLAS Tests n Job characteristics n Simulation n n Approximate CPU time: 3 h Job submission n Bulk submission n Approximate CPU time: 20 h Reconstruction n n Approximate CPU time: 3 h The supervisor groups jobs to be executed in collections of 100 jobs each Each job in a collection can run on a different site Also synthetic tests run n Very simple jobs (“Hello world”) that can run anywhere To study the impact of the shallow resubmission To assess the reliability of the bulk submission
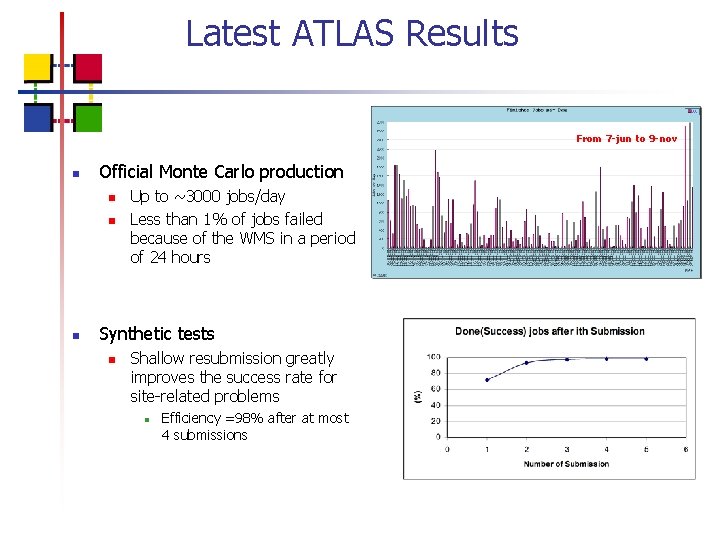
Latest ATLAS Results From 7 -jun to 9 -nov n Official Monte Carlo production n Up to ~3000 jobs/day Less than 1% of jobs failed because of the WMS in a period of 24 hours Synthetic tests n Shallow resubmission greatly improves the success rate for site-related problems n Efficiency =98% after at most 4 submissions
ATLAS issues n LB in Milan failed to update job status n n Missing documentation for g. Lite 3. 1 new features DAGMan-based collections too fragile to be used by final users n n interlogd LB daemon stuck Cured by a restart of glite-lb-logger but not understood Timescale to get rid of DAGMan for collections? Still missing from UI the Python bindings for the WMS client API
CMS jobs n Job characteristics n n Software: CMSSW 0. 6. 1 Data analyzed: test sample preinstalled at CMS sites Approximate CPU time: 30’ Job submission n n Predefined number of jobs submitted at each CMS site Various mechanisms tested n n Network Server WMProxy n n Collections n n ~20% faster submission rate than via NS Best possible submission speed Submission in parallel from up to three User Interfaces
CMS testing process 1. 2. 3. 4. 5. 6. 7. 8. The submission is started The total submission time is measured The job status changes are monitored The time to have all the jobs moved to Scheduled status is measured All job failures are investigated and classified A report is sent to support-exp-glite-rb@cern. ch Bugs are identified, understood and fixed The process is iterated several times
CMS results (I) n n Non-bulk submission was soon found to be as reliable as for the LCG RB Bulk submission was plagued for long by serious problems n n n n Mass cancellation of DAG nodes Very slow Condor submission rate Excessive use of swap memory Service crashes (e. g. Log. Monitor) Submission failures due to timeouts under load Truncation of file name in input sandbox files Almost all of the serious problems have been eventually fixed The g. Lite WMS is now sufficiently stable to be used for real work with some effort n But still much more fragile than the LCG RB
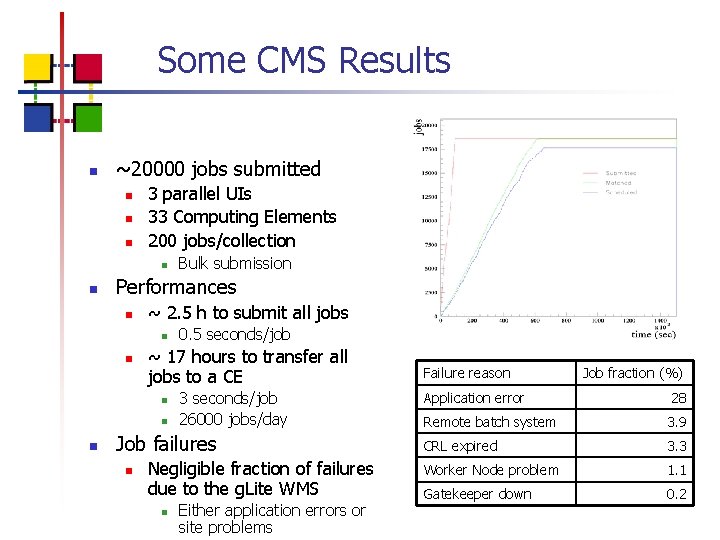
Some CMS Results n ~20000 jobs submitted n n n 3 parallel UIs 33 Computing Elements 200 jobs/collection n n Performances n ~ 2. 5 h to submit all jobs n n 0. 5 seconds/job ~ 17 hours to transfer all jobs to a CE n n n Bulk submission 3 seconds/job 26000 jobs/day Job failures n Negligible fraction of failures due to the g. Lite WMS n Either application errors or site problems Failure reason Application error Job fraction (%) 28 Remote batch system 3. 9 CRL expired 3. 3 Worker Node problem 1. 1 Gatekeeper down 0. 2
Other CMS results n Submission of 25000 jobs/day spread over 24 hours n n n Already too heavy on the system Too much memory used Submission of 15000 jobs/day with a standalone LB server n Totally safe
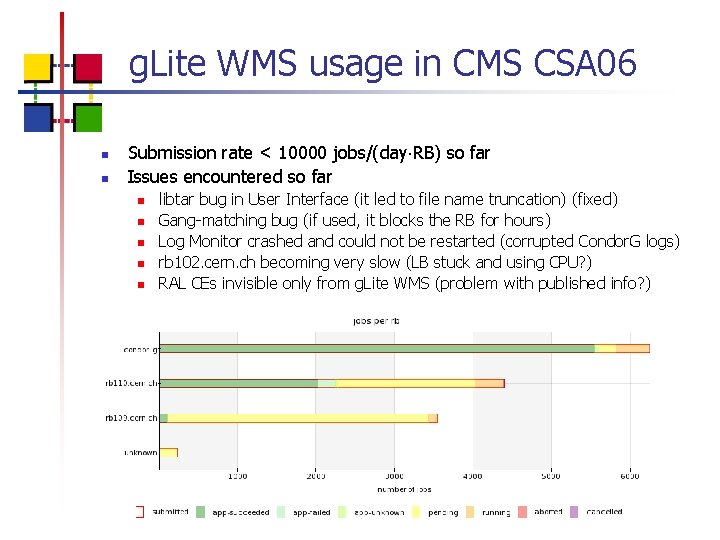
g. Lite WMS usage in CMS CSA 06 n n Submission rate < 10000 jobs/(day RB) so far Issues encountered so far n n n libtar bug in User Interface (it led to file name truncation) (fixed) Gang-matching bug (if used, it blocks the RB for hours) Log Monitor crashed and could not be restarted (corrupted Condor. G logs) rb 102. cern. ch becoming very slow (LB stuck and using CPU? ) RAL CEs invisible only from g. Lite WMS (problem with published info? )
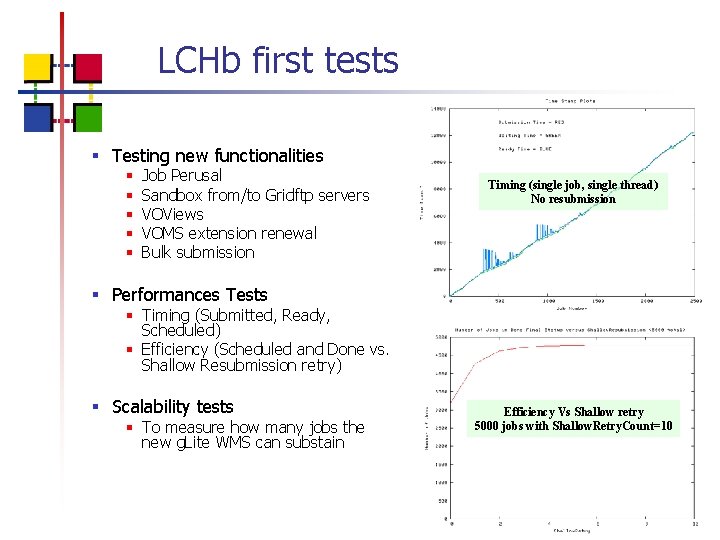
LCHb first tests § Testing new functionalities § § § Job Perusal Sandbox from/to Gridftp servers VOViews VOMS extension renewal Bulk submission Timing (single job, single thread) No resubmission § Performances Tests § Timing (Submitted, Ready, Scheduled) § Efficiency (Scheduled and Done vs. Shallow Resubmission retry) § Scalability tests § To measure how many jobs the new g. Lite WMS can substain Efficiency Vs Shallow retry 5000 jobs with Shallow. Retry. Count=10
LHCb issues n Proxy exception: Proxy validity starting time in the future Please check client date/time Method: job. Submit Error code: 1222 n n Operation failed Unable to submit the job to the service: https: //cert-rb 04. cnaf. infn. it: 7443/glite_wms_wmproxy_server SOAP version mismatch or invalid SOAP message Error code: SOAPENV: Version. Mismatch n n Message obtained for 10 threads, 500 jobs each from a single UI (UI was not overloaded) Inconsistent status timestamp using glite-job-status although the job was successfully executed. Glite-job-logging-info holds the right information n n Message obtained during single thread and single job submission Submitted Waiting Ready Scheduled Running Done : : : Fri Sep 29 12: 33: 38 2006 --Fri Sep 29 12: 37: 30 2006 Fri Sep 29 12: 38: 43 2006 Fri Sep 29 12: 43: 21 2006 CEST CEST Default Ranking problem: in less than 3 hours more than 800 jobs went to Bari n Fuzzy rank switched off nonetheless this points a wrong behavior of default rank

Job reliability studies n n Trying to improve the knowledge about the failure reasons for Grid jobs Collecting statistics Pictorial representations of the job history Not yet enabled on g. Lite WMS n n The g. Lite RBs are not yet sending info to R-GMA Now the same framework is used to collect FTS failure statistics Most common failure reasons from 400 K jobs Cannot read Job. Wrapper output both from Condor and from Maradona 51 k Job Retry. Count 27 k Got a job held event reason: Unspecified gridmanager error 21 k Globus error 131: the user proxy expired job is still running 20 k Job got an error while in the Condor. G queue 20 k No compatible resources 15 k Cannot download <file> from <file> 6 k 7 authentication with the remote server failed 3 k 22 the job manager failed to crate an internal script argument file 3 k Other errors 26 K
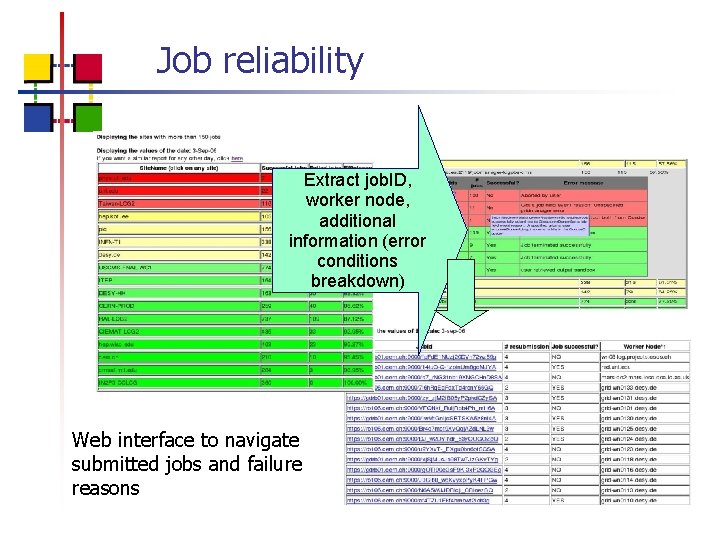
Job reliability Extract job. ID, worker node, additional information (error conditions breakdown) Web interface to navigate submitted jobs and failure reasons
Configuration parameters to tune n Number of planners/DAG n Needs to be optimized as a function of the number of collections n n Number of WMProxy processes n n Too many of them take too much memory GLITE_WMS_QUERY_TIMEOUT n n Too many DAGs too many planners If too short, queries to LB can fail under heavy load Time between retries when a job is not matched to any CE n If too short, the WMS spends too much time in matchmaking
Some unsolved bugs in g. Lite 3. 0 n The number of WMProxy processes can increase beyond limits if large collections are submitted (>1000 jobs) n n Duplicated CEs in the list of matched CEs n n Due to the introduction of VOViews Log. Monitor repeatedly dies n n due to callouts to create job directories Due to corrupted Condor. G log files Some CEs do not appear in the Information Supermarket n n But they are seen by LCG RBs impossible to submit jobs to some sites (like RAL!)
Desired features n Automatic proxy delegation with a non-random deleg. ID n n n Already foreseen Configurable duration of the time interval during which the WM tries to match a job to a CE Cancellation of single collection nodes
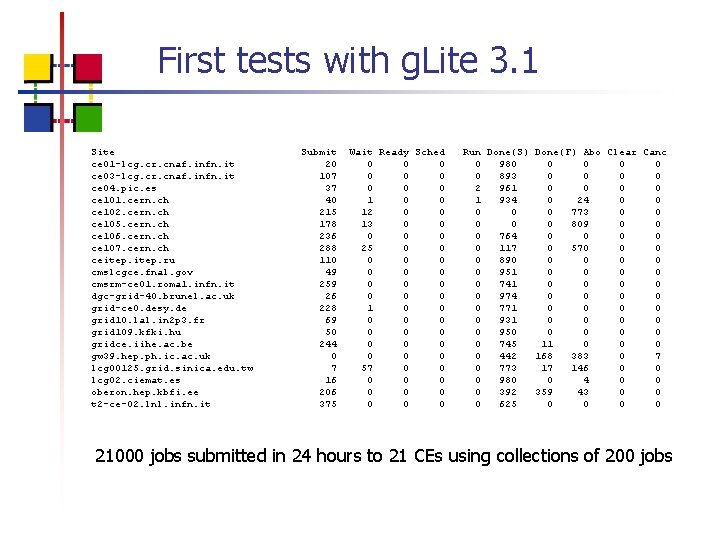
First tests with g. Lite 3. 1 Site ce 01 -lcg. cr. cnaf. infn. it ce 03 -lcg. cr. cnaf. infn. it ce 04. pic. es ce 101. cern. ch ce 102. cern. ch ce 105. cern. ch ce 106. cern. ch ce 107. cern. ch ceitep. ru cmslcgce. fnal. gov cmsrm-ce 01. roma 1. infn. it dgc-grid-40. brunel. ac. uk grid-ce 0. desy. de grid 10. lal. in 2 p 3. fr grid 109. kfki. hu gridce. iihe. ac. be gw 39. hep. ph. ic. ac. uk lcg 00125. grid. sinica. edu. tw lcg 02. ciemat. es oberon. hep. kbfi. ee t 2 -ce-02. lnl. infn. it Submit 20 107 37 40 215 178 236 288 110 49 259 26 228 69 50 244 0 7 16 206 375 Wait Ready Sched 0 0 0 0 0 12 0 0 13 0 0 0 25 0 0 0 0 1 0 0 0 0 57 0 0 0 Run Done(S) Done(F) Abo Clear Canc 0 980 0 0 893 0 0 2 961 0 0 1 934 0 24 0 0 0 773 0 0 0 809 0 0 0 764 0 0 0 117 0 570 0 890 0 0 951 0 0 0 741 0 0 0 974 0 0 0 771 0 0 0 931 0 0 0 950 0 0 745 11 0 0 442 168 383 0 773 17 146 0 0 0 980 0 4 0 0 0 392 359 43 0 0 0 625 0 0 21000 jobs submitted in 24 hours to 21 CEs using collections of 200 jobs
Results on first tests on 3. 1 n ~20% of jobs affected by a bug which makes the look as still Submitted even if they finished n n Some DAGs aborted n n Sequence code of some events is wrong A Reg. Job event at the end understood how to fix it error message "cannot create LB context" No other WMS-related errors seen
Conclusions n n The g. Lite WMS is used in production by ATLAS and CMS Significant progresses were made in the last few months to bring it to an acceptable level of stability It is not yet in a condition where it can run unattended for several days without problems with a realistic load Given that the performances and the feature set are fine enough, for the applications the main focus should now be on robustness and reliability n n n Automatic refusal of new jobs when too loaded Memory usage under control Collections not as DAGs Services should do their best not to die. . .
- Slides: 28