
ENGLISH VIETNAMESE CROSSLANGUAGE PARAPHRASE IDENTIFICATION USING HYBRID METHOD
ENGLISH- VIETNAMESE CROSS-LANGUAGE PARAPHRASE IDENTIFICATION USING HYBRID METHOD Le Thanh Nguyen Text Mining and Applications Workshop – 14 th May 2018
Paraphrase identification "Paraphrase identification is such an important task of identifying the similarity between two text segments in a natural language understanding system. They are annoted with binary judgments. " Rutal S. Mahajan and Mukesh A. Zaveri
Paraphrase identification - English sentence: An older man is drinking orange juice at a restaurant. - English sentence: An older man is drinking juice. => Paraphrase! - English sentence: A person on a horse jumps over a broken down airplane. - English sentence: A person is at a diner, ordering an omelette. => Not paraphrase!

Paraphrase identification - Vietnamese sentence: Nếu tôi đặt hàng bây giờ, không biết khi nào tôi có thể nhận được sản phẩm đó. - English sentence: If I order now, I wonder when I can receive the product. => Paraphrase! - Vietnamese sentence: Với một phiên dịch như ông thì mọi việc sẽ tốt đẹp thôi. - English sentence: She dicided to branch out alone and launch a campaign. => Not paraphrase!
Paraphrase identification task plays a very important role and influences the processing quality of many NLP tasks such as: ü Querying information ü Text summarization ü Evaluating the translation quality ü Plagiarism detection ü etc
Our research Related work Proposed method Experimental results Limitation Future work Summary
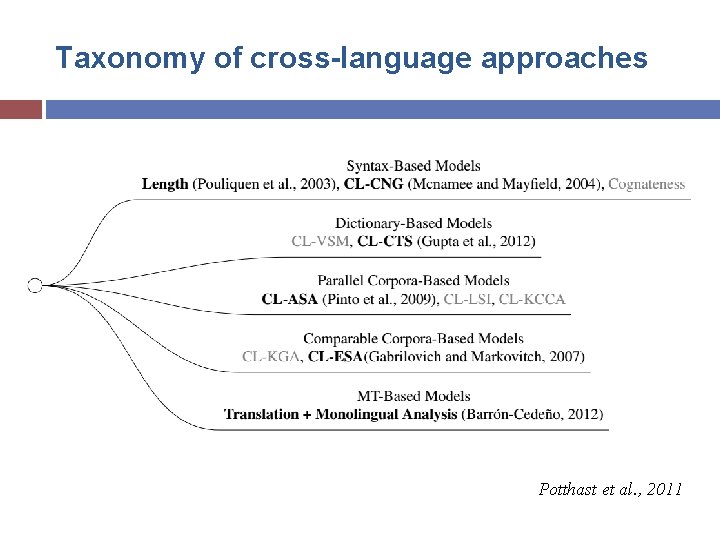
Taxonomy of cross-language approaches Potthast et al. , 2011
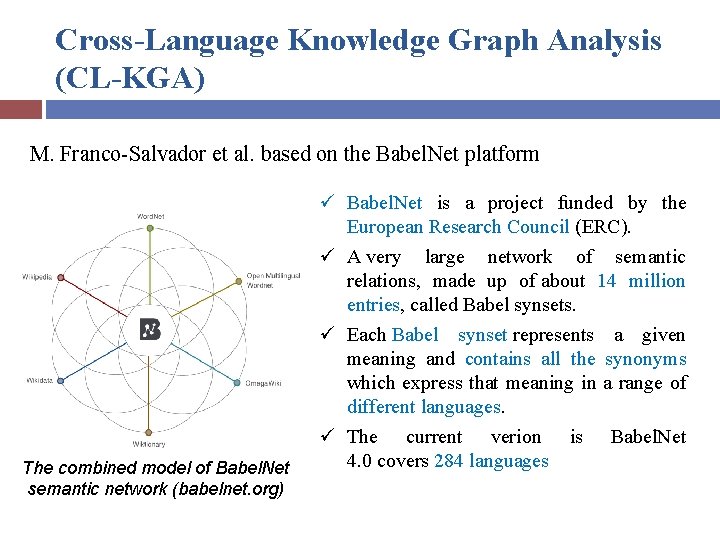
Cross-Language Knowledge Graph Analysis (CL-KGA) M. Franco-Salvador et al. based on the Babel. Net platform The combined model of Babel. Net semantic network (babelnet. org) ü Babel. Net is a project funded by the European Research Council (ERC). ü A very large network of semantic relations, made up of about 14 million entries, called Babel synsets. ü Each Babel synset represents a given meaning and contains all the synonyms which express that meaning in a range of different languages. ü The current verion is Babel. Net 4. 0 covers 284 languages
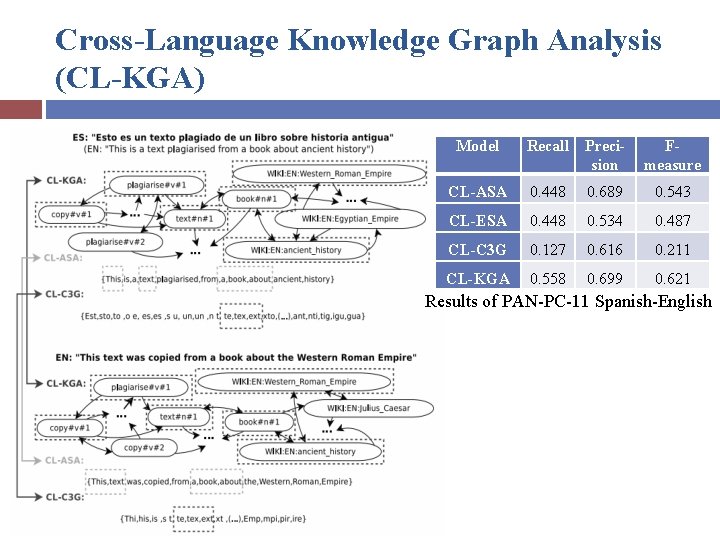
Cross-Language Knowledge Graph Analysis (CL-KGA) Model Recall Precision Fmeasure CL-ASA 0. 448 0. 689 0. 543 CL-ESA 0. 448 0. 534 0. 487 CL-C 3 G 0. 127 0. 616 0. 211 CL-KGA 0. 558 0. 699 0. 621 Results of PAN-PC-11 Spanish-English
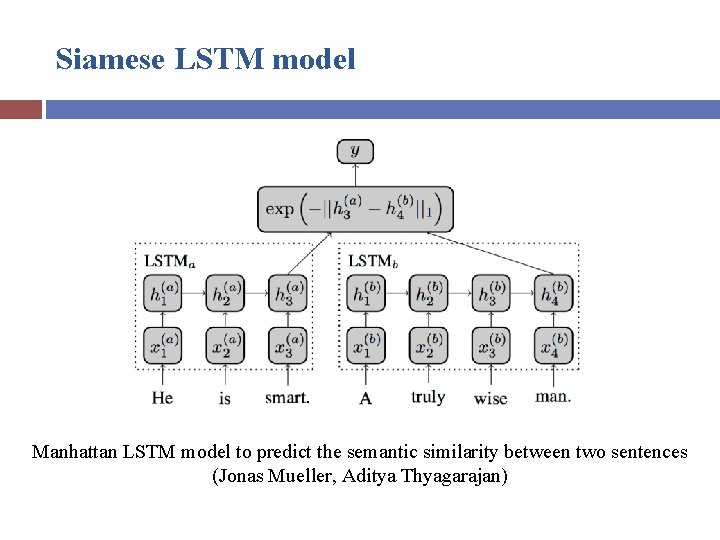
Siamese LSTM model Manhattan LSTM model to predict the semantic similarity between two sentences (Jonas Mueller, Aditya Thyagarajan)
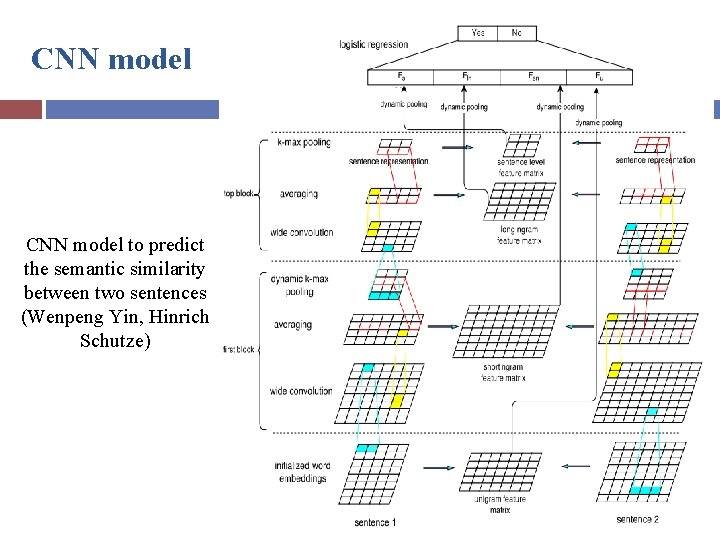
CNN model to predict the semantic similarity between two sentences (Wenpeng Yin, Hinrich Schutze)
Our proposed method Objective: � Find the effective method to identify the paraphrase between English and Vietnamese sentence pairs � Combine the traditional NLP method and the Deep learning method � Use Babel. Net platform
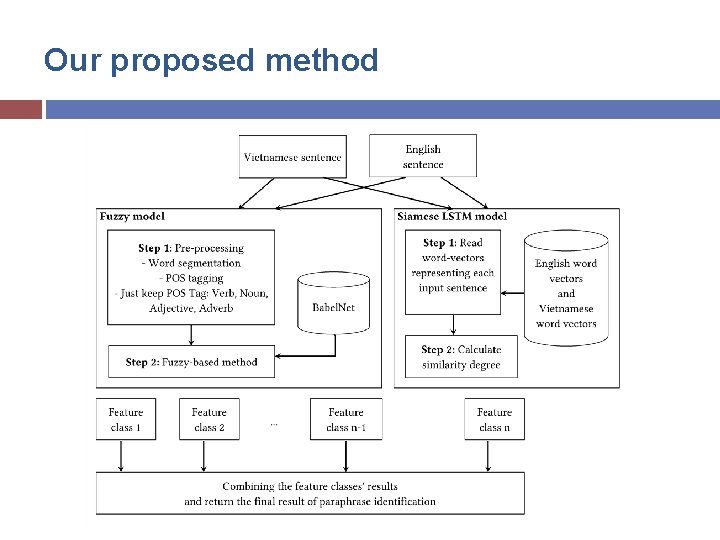
Our proposed method
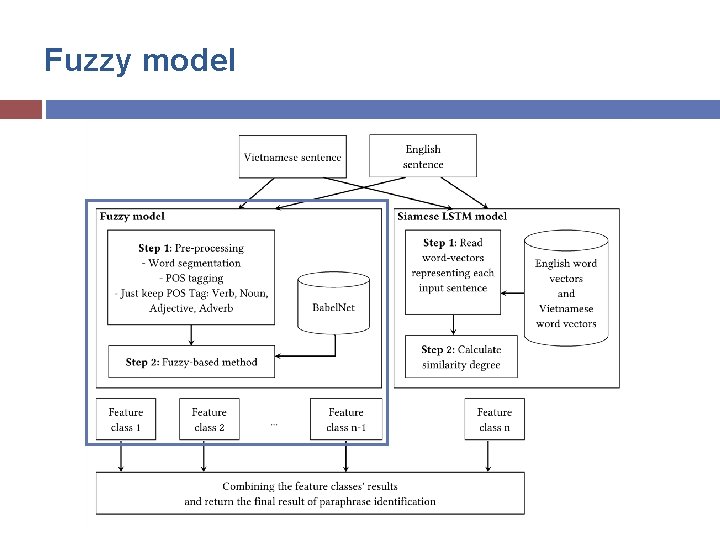
Fuzzy model
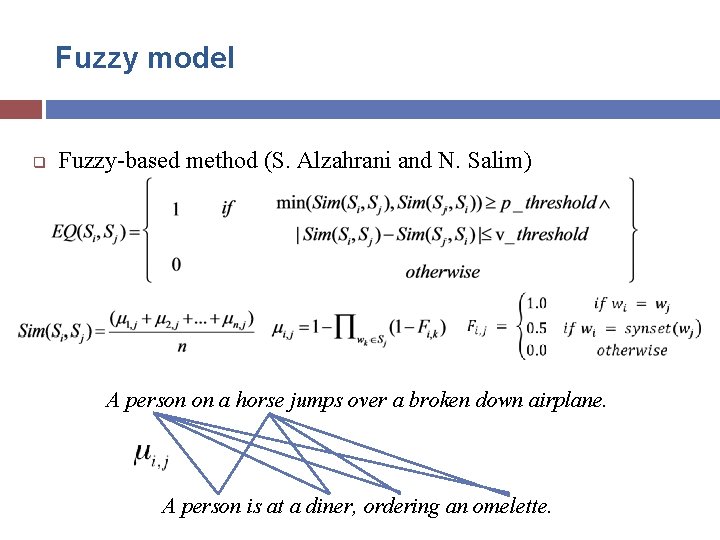
Fuzzy model q Fuzzy-based method (S. Alzahrani and N. Salim) A person on a horse jumps over a broken down airplane. A person is at a diner, ordering an omelette.
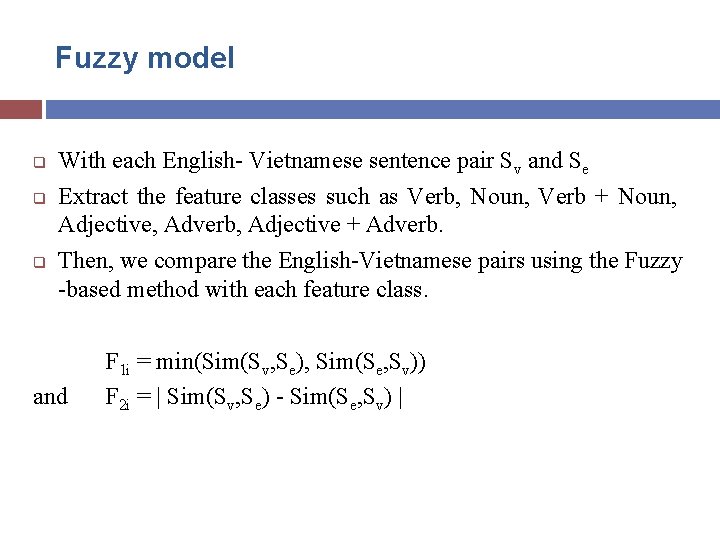
Fuzzy model q q q With each English- Vietnamese sentence pair Sv and Se Extract the feature classes such as Verb, Noun, Verb + Noun, Adjective, Adverb, Adjective + Adverb. Then, we compare the English-Vietnamese pairs using the Fuzzy -based method with each feature class. and F 1 i = min(Sim(Sv, Se), Sim(Se, Sv)) F 2 i = | Sim(Sv, Se) - Sim(Se, Sv) |
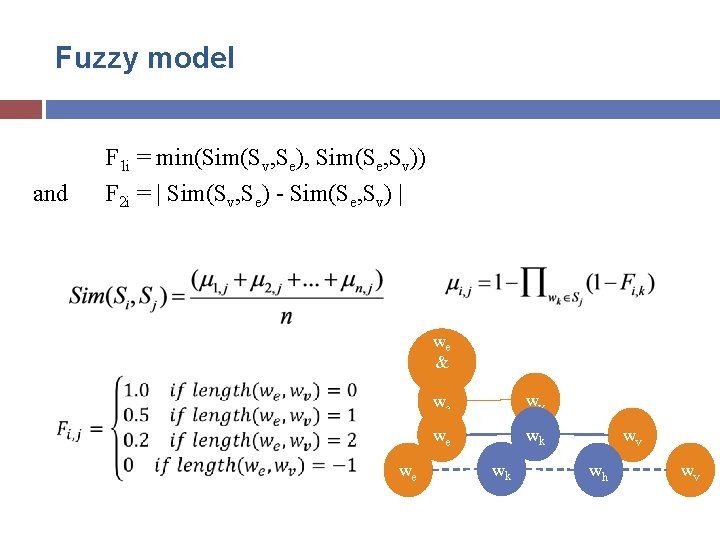
Fuzzy model and F 1 i = min(Sim(Sv, Se), Sim(Se, Sv)) F 2 i = | Sim(Sv, Se) - Sim(Se, Sv) | we we & wv we wk wk wv wh wv
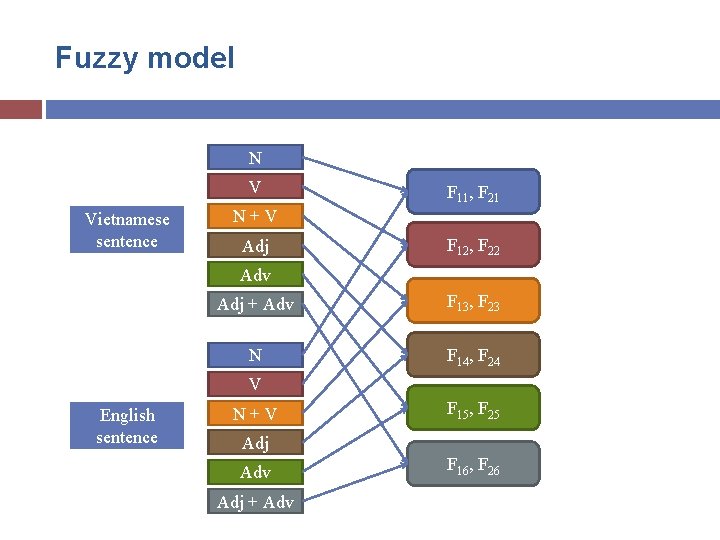
Fuzzy model N V Vietnamese sentence F 11, F 21 N + V Adj F 12, F 22 Adv Adj + Adv F 13, F 23 N F 14, F 24 V English sentence N + V F 15, F 25 Adj Adv Adj + Adv F 16, F 26
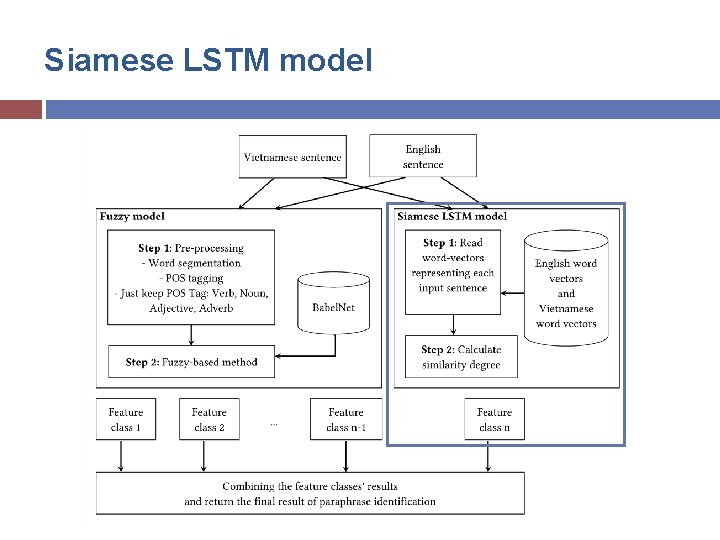
Siamese LSTM model
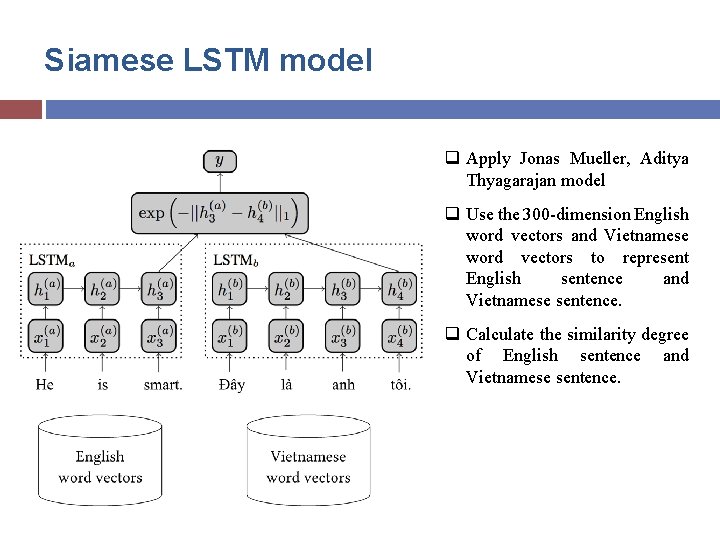
Siamese LSTM model q Apply Jonas Mueller, Aditya Thyagarajan model q Use the 300 -dimension English word vectors and Vietnamese word vectors to represent English sentence and Vietnamese sentence. q Calculate the similarity degree of English sentence and Vietnamese sentence.
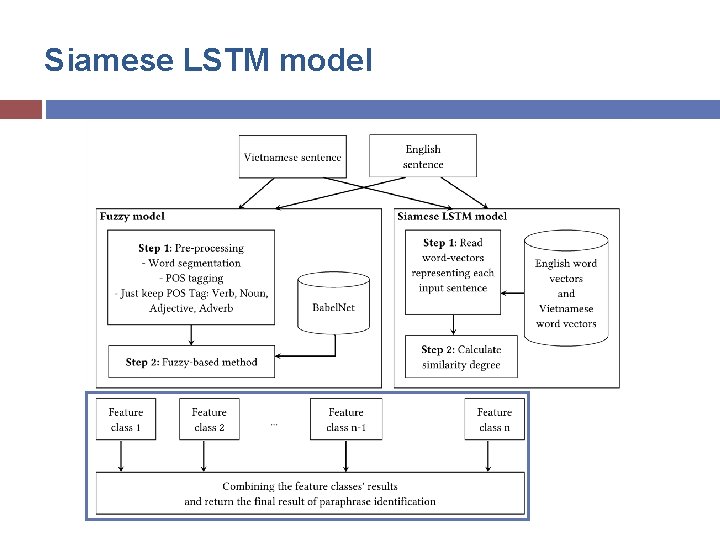
Siamese LSTM model
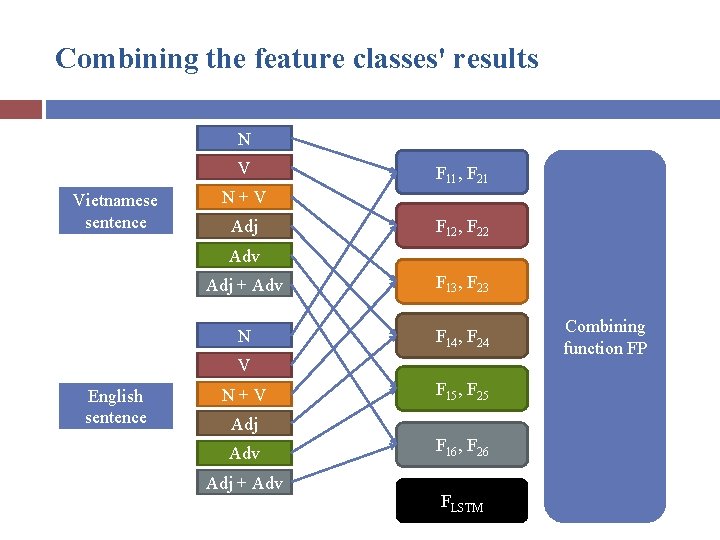
Combining the feature classes' results N V Vietnamese sentence F 11, F 21 N + V Adj F 12, F 22 Adv Adj + Adv F 13, F 23 N F 14, F 24 V English sentence N + V F 15, F 25 Adj Adv Adj + Adv F 16, F 26 FLSTM Combining function FP
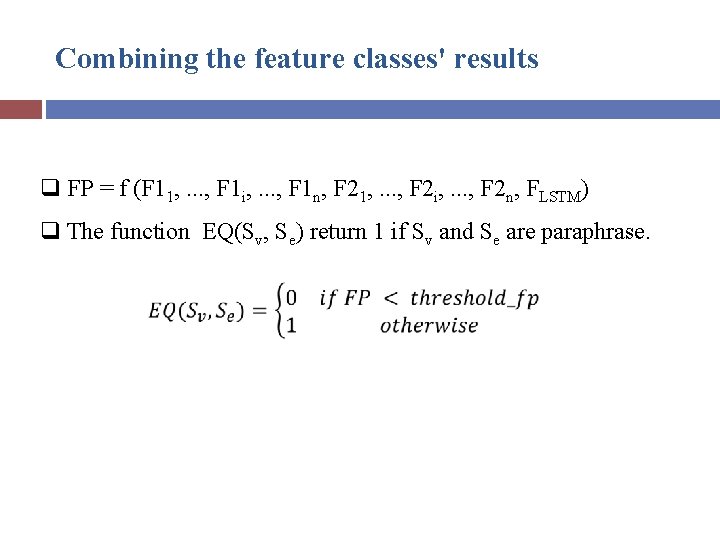
Combining the feature classes' results q FP = f (F 11, . . . , F 1 i, . . . , F 1 n, F 21, . . . , F 2 i, . . . , F 2 n, FLSTM) q The function EQ(Sv, Se) return 1 if Sv and Se are paraphrase.
Experimental results q Data Setup ü ü Use TED bilingual corpus of English-Vietnamese sentence pairs. 3, 000 pairs of English-Vietnamese paraphrase sentences. 3, 000 pairs of English-Vietnamese non-paraphrase sentences. Use 2, 500 paraphrase sentence pairs and 2, 500 non-paraphrase sentence pairs to train the model and use the remaining pairs to evaluate the quality of the model.
Experimental results q Training ü Combine F 1 i, F 2 i, FLSTM and paraphrase label ü Use some algorithms in the Weka tool such as Gaussian Processes, Linear Regression, Random Forest, Multilayer Perceptron to get the formula to determine whether the English-Vietnamese sentence pair is paraphrase.
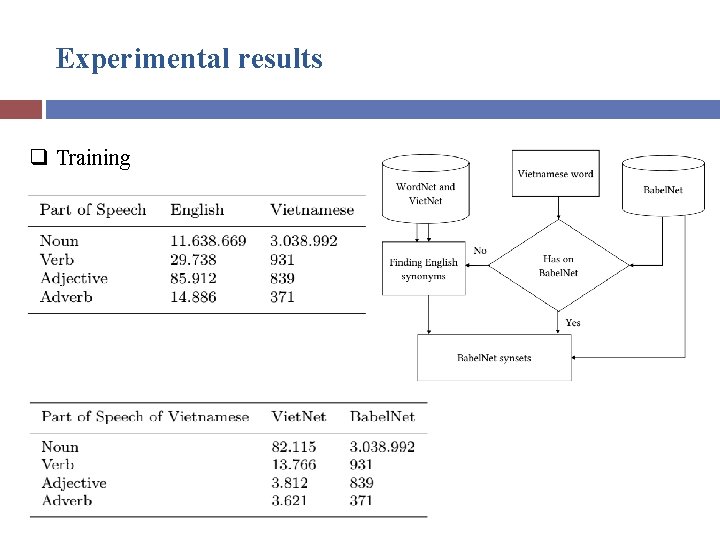
Experimental results q Training
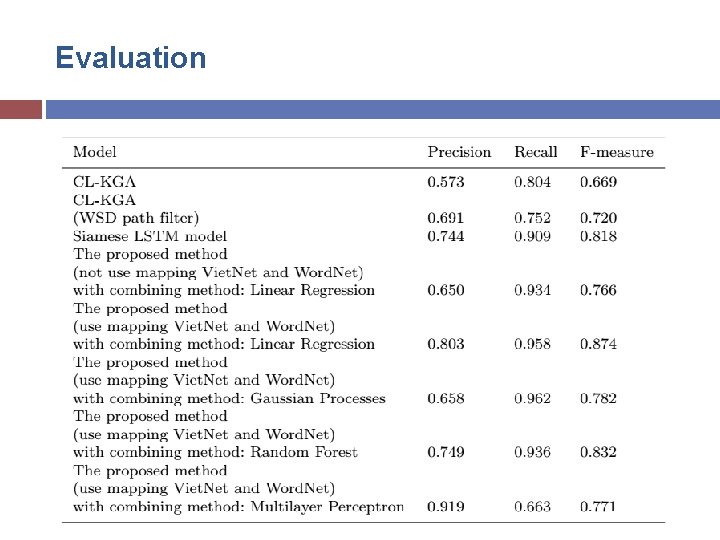
Evaluation
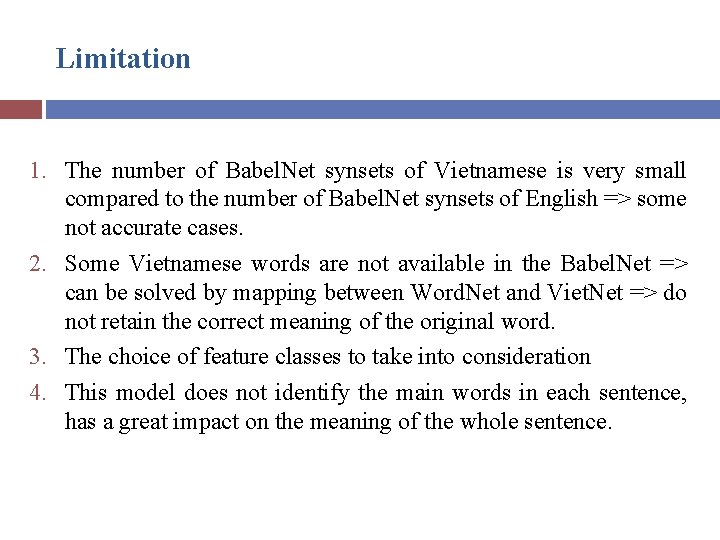
Limitation 1. The number of Babel. Net synsets of Vietnamese is very small compared to the number of Babel. Net synsets of English => some not accurate cases. 2. Some Vietnamese words are not available in the Babel. Net => can be solved by mapping between Word. Net and Viet. Net => do not retain the correct meaning of the original word. 3. The choice of feature classes to take into consideration 4. This model does not identify the main words in each sentence, has a great impact on the meaning of the whole sentence.
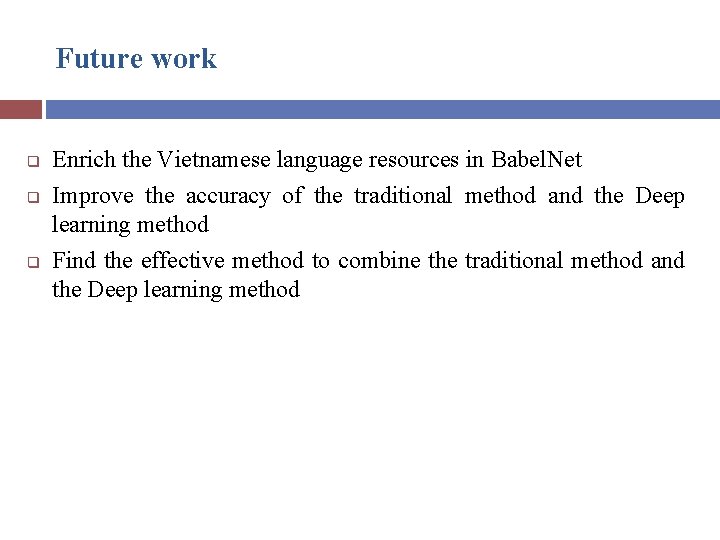
Future work q q q Enrich the Vietnamese language resources in Babel. Net Improve the accuracy of the traditional method and the Deep learning method Find the effective method to combine the traditional method and the Deep learning method
Summary Paraphrase identification is a very important task in natural language processing We propose an English- Vietnamese Cross-Language Paraphrase Identification using Hybrid Method. The results show that the model has achieved encouraging results with F-measure 87. 4%.
Thanks for listening!
- Slides: 31