
ENEL 515 AMDK 5 Processor From AMD 1996

- Slides: 32
ENEL 515 AMD-K 5 Processor From AMD 1996 Publication #18522 Revision E 12/7/2020
Compare 1978 and 1996 CISC processors l Want to compare Motorola 68332 CISC Processor (based on 68000 era 1978/81) with a AMD K 5 CISC Processor (era 1996 CISC) l Look at common features present between AMD K 5 CISC and 21 K DSP l Comment on paper “Microprocessors outperform DSP 2: 1 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
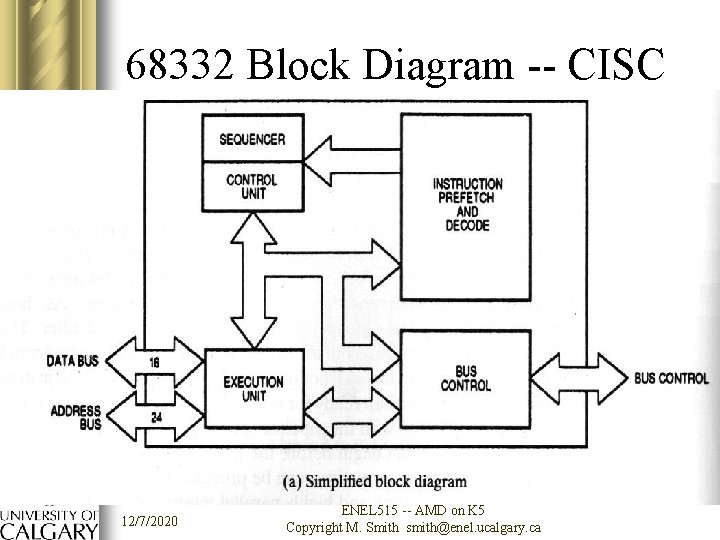
68332 Block Diagram -- CISC 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
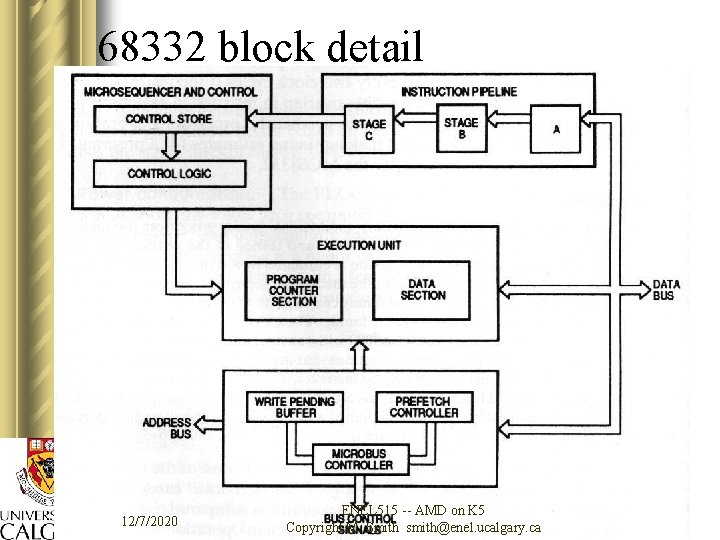
68332 block detail 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
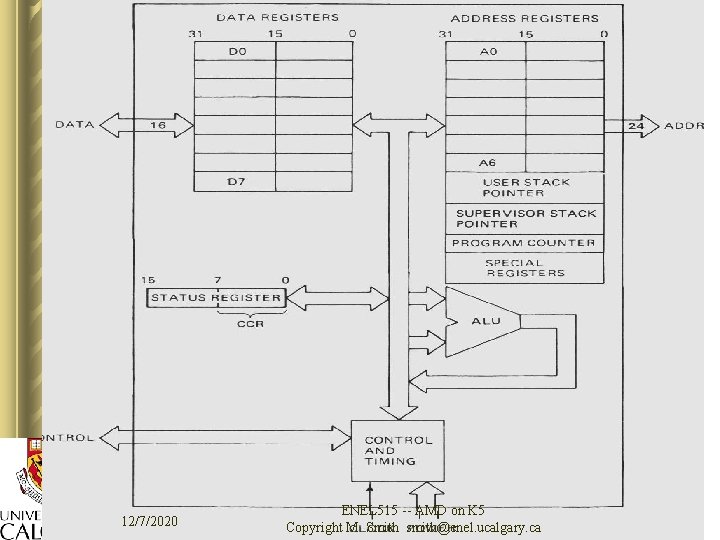
68 K registers and ALU 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
Problems with CISC compatability l X 86 CISC architecture -- dominant standard over many generation l Backward compatibility involves inherent limitations of X 86 CISC – variable length instructions – few general registers – complex addressing mode l Could make same comments to 68 K CISC 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
K 5 overcomes backwards X 86 compatibility problems l Superscalar RISC core l instruction predecoding l improved cache l branch prediction l speculative execution l out of order execution l register renaming 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
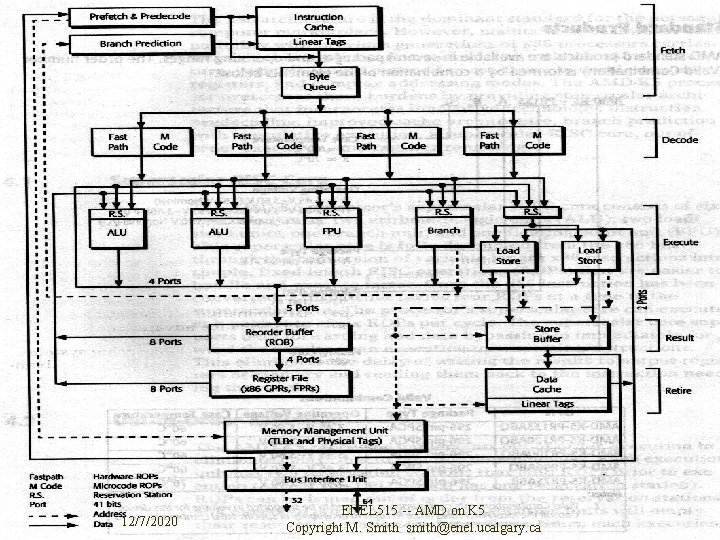
12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
64 bit data bus interface l 64 bit data bus l cache/burst oriented line refill for both instruction cache and data cache l Cache refills as five clock cycles per cache line -- (cache line -- 4 instructions? ) 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
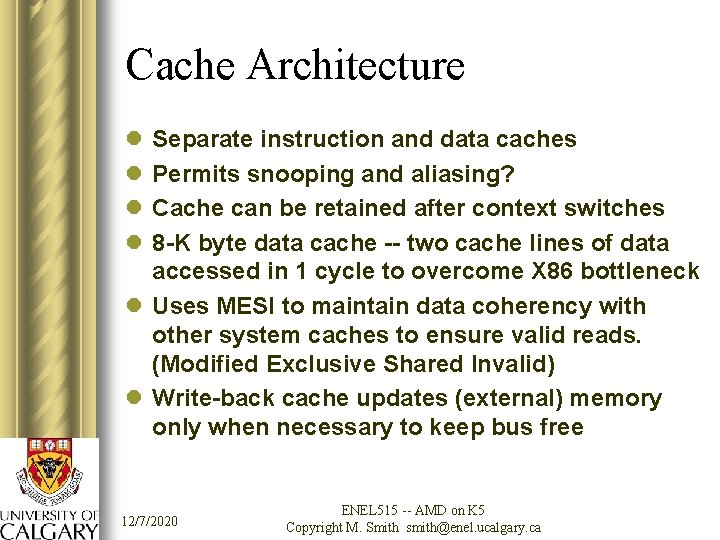
Cache Architecture l l Separate instruction and data caches Permits snooping and aliasing? Cache can be retained after context switches 8 -K byte data cache -- two cache lines of data accessed in 1 cycle to overcome X 86 bottleneck l Uses MESI to maintain data coherency with other system caches to ensure valid reads. (Modified Exclusive Shared Invalid) l Write-back cache updates (external) memory only when necessary to keep bus free 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
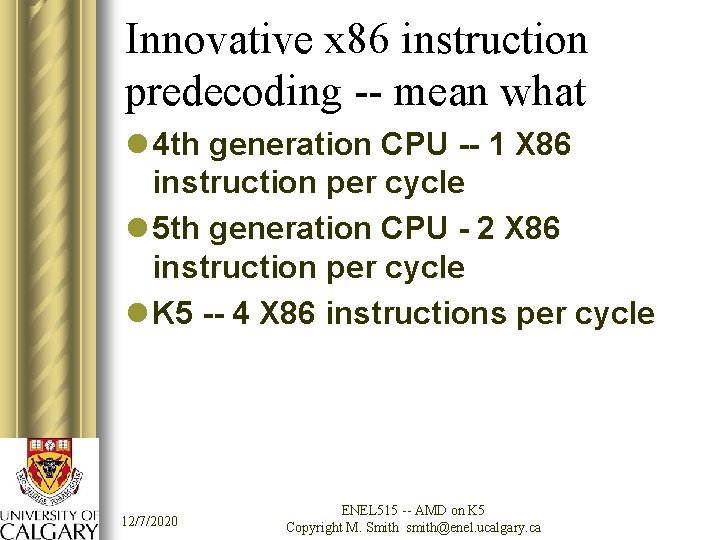
Innovative x 86 instruction predecoding -- mean what l 4 th generation CPU -- 1 X 86 instruction per cycle l 5 th generation CPU - 2 X 86 instruction per cycle l K 5 -- 4 X 86 instructions per cycle 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
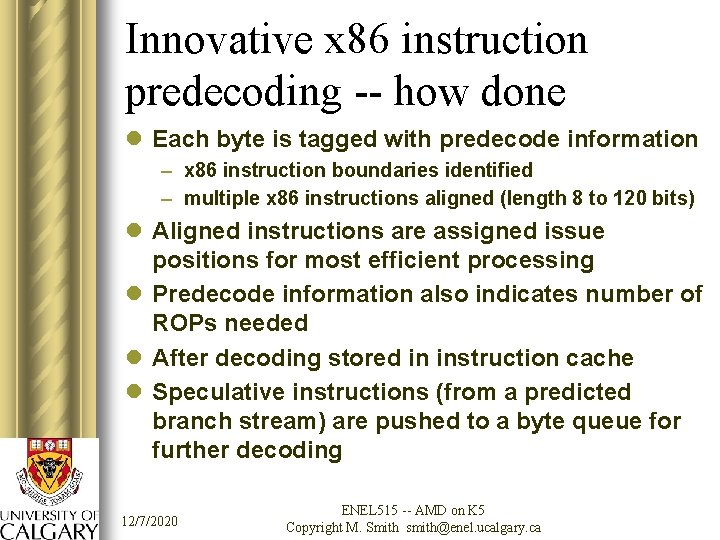
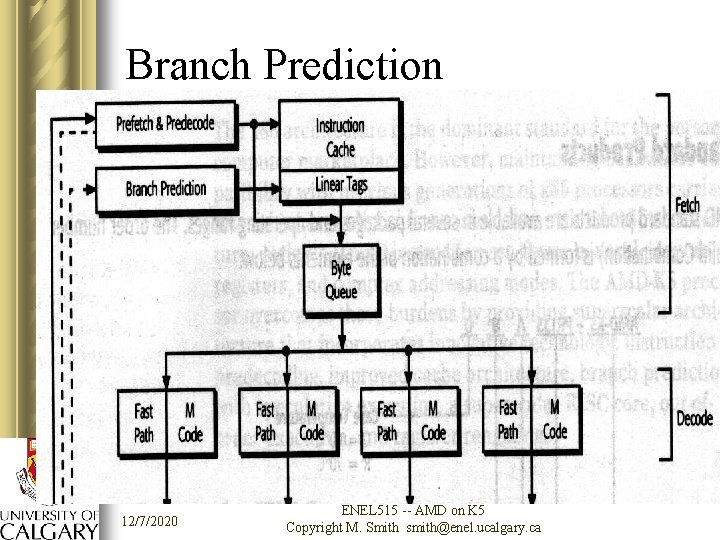
Innovative x 86 instruction predecoding -- how done l Each byte is tagged with predecode information – x 86 instruction boundaries identified – multiple x 86 instructions aligned (length 8 to 120 bits) l Aligned instructions are assigned issue positions for most efficient processing l Predecode information also indicates number of ROPs needed l After decoding stored in instruction cache l Speculative instructions (from a predicted branch stream) are pushed to a byte queue for further decoding 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
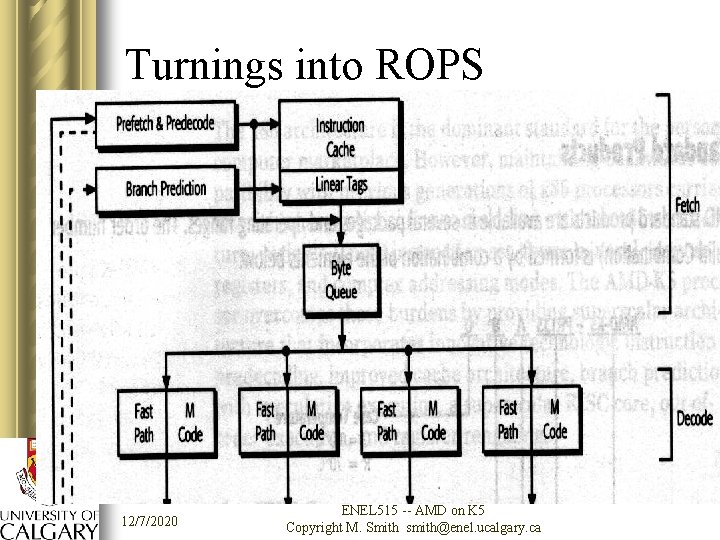
Turnings into ROPS 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
Unique x 86 instruction conversion and decoding l 32 bytes of precoded X 86 instructions forwarded to decoder l Decoder converts complex x 86 to ROPS -- fixed length easy to process l Simultaneous operands for ROP fetched from register files or re-order buffer l X 86 instructions are scanned and allocated to a decode position. Number of ROPS to X 86 is known during predecoding -- saves time -- why? 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
Stage II l If X 86 instruction requires less than 4 ROPS after conversion then goes “fast path” to any of 4 decode positions l Very complex X 86 instructions are transferred to microcode ROM for conversion l After decoding, ROPS send to reservation stations at the 6 execution units. l At execution units, ROPS may be executed out of order -- faster than compiler optimizations l ROPs wait in reservation stations for operands from register file, data cache or result of other ops 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
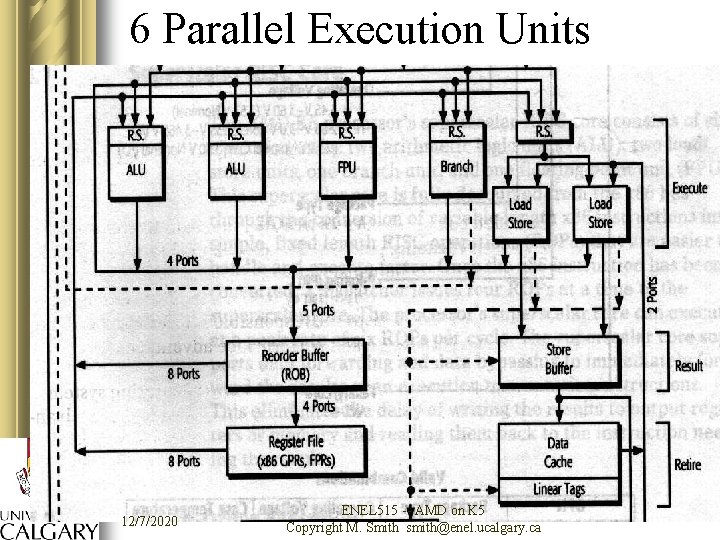
K 5 Superscalar RISC core l Six execution units – – two ALU (integer) two load/store units branch unit floating point FPU l Conversions of variable length X 86 to simple fixed length RISC operations (ROPs) l Dispatch four ROPs at a time to superscalar core l Execution rate -- peak at 6 ROPS per cycle l Register forwarding and data bypassing allows results to be used immediately in next ROP -- no delay of results to destination register and then out again 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
6 Parallel Execution Units 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
Out of order execution l Eliminated delays due to pipeline dependencies l Each execution unit has 2 reservations stations for ROP l Instructions can be issued in any order from reservation stations l Execution unit act independently -- some work if others stall l 16 -entry reorder buffer keeps track of original instruction sequence 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
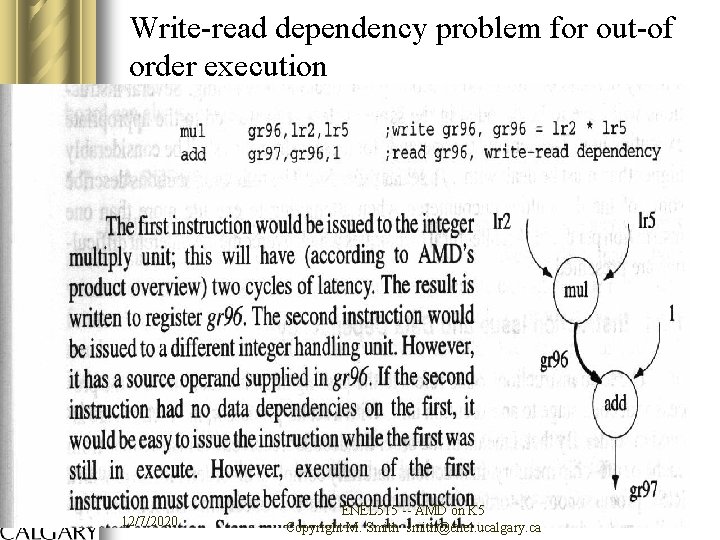
Write-read dependency problem for out-of order execution 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
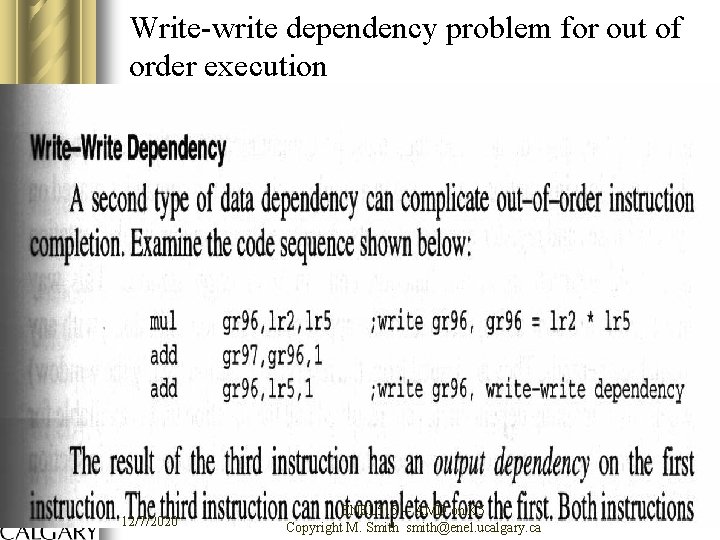
Write-write dependency problem for out of order execution 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
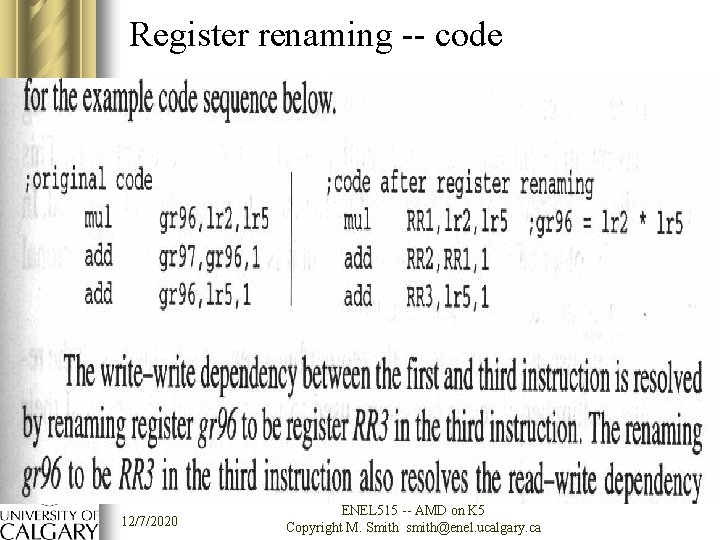
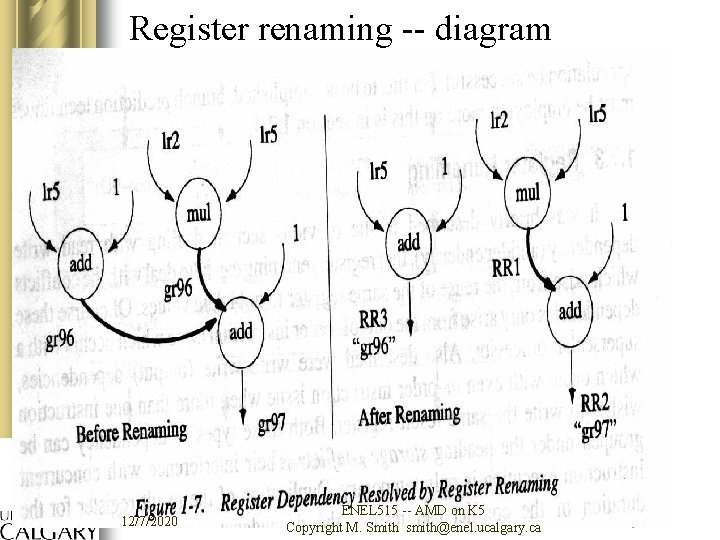
Register renaming l Original X 86 architecture has only 8 general purpose registers – Increases register reuse (load and stores to memory) and register dependencies l Register re-use overcome with multiple load/store execution units and dual-ported data cache l Register renaming overcomes register dependencies -- multiple logical registers for each physical register allow execution units to use the same physical register names simultaneously 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
Register renaming -- code 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
Register renaming -- diagram 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
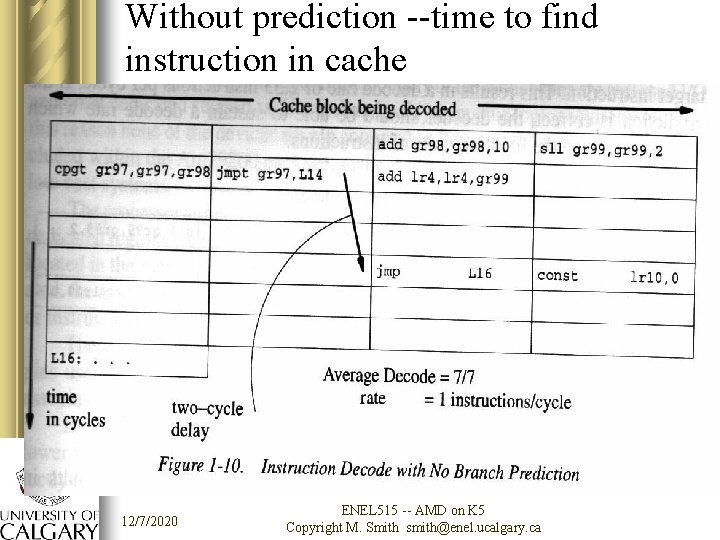
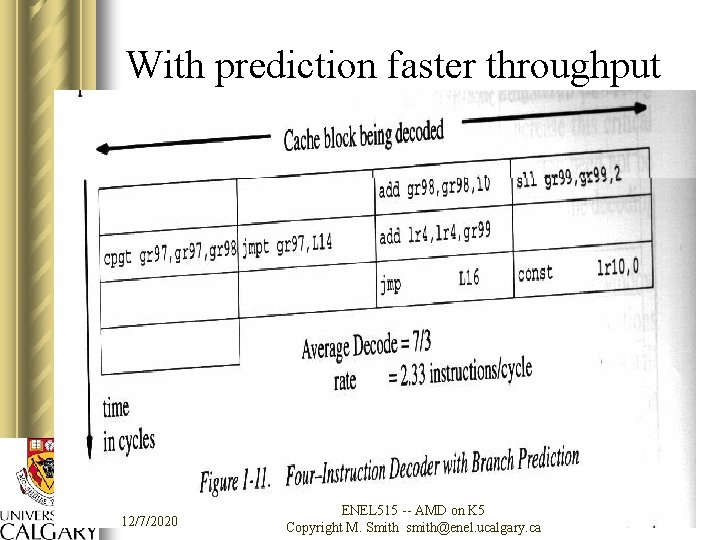
Branch Prediction l Branches in X 86 programs every 7 instructions on average l Processor predicts which branch to take l Prediction done dynamically 75% accuracy, 1024 branch targets are cached l If invalid prediction then minimal 3 cycle mispredict penalty l Dynamic branch prediction enables instructions to be fed to execution core and eliminated pipeline bubbles (stalls? ) 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
Branch Prediction 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
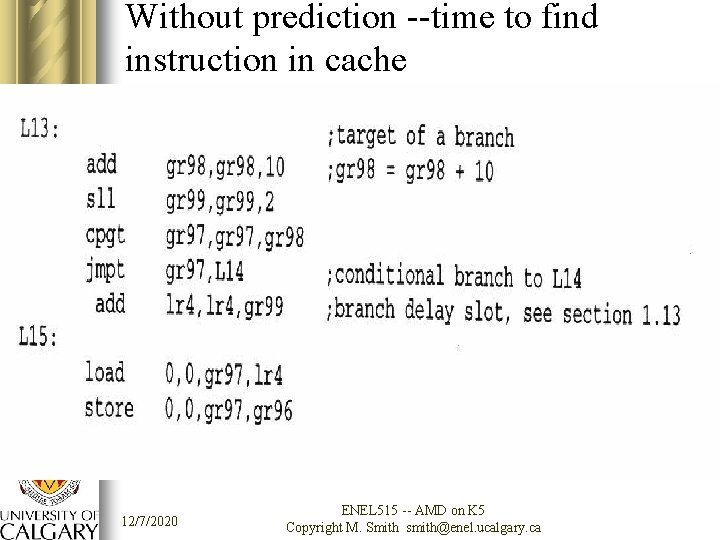
Without prediction --time to find instruction in cache 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
Without prediction --time to find instruction in cache 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
With prediction faster throughput 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
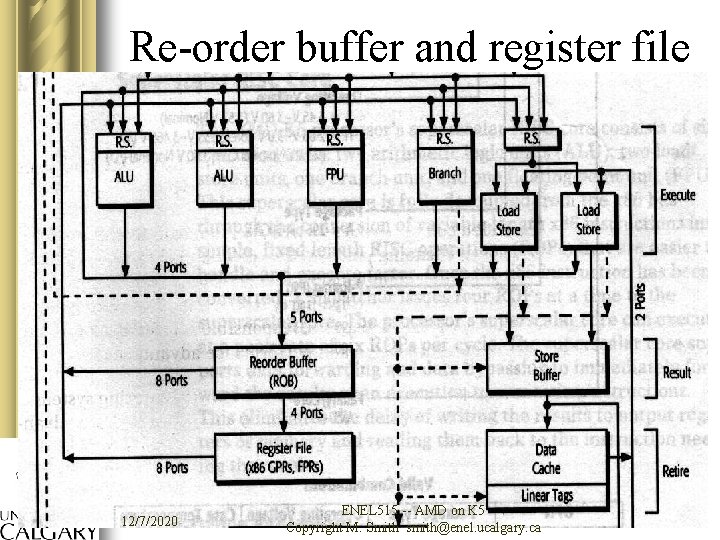
Re-order buffer and register file 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
Reorder buffer l Reorder buffer -- key to speculative out of order execution (issue and completion) l Reorder buffer used to rename registers, provide forwarding of requested intermediate results, recover from mispredictions l Reorder buffer keeps track of original instruction sequence and ensures that results are retired in correct order with results going to register file l If branch is mis-predicted then results of instructions are invalidated in re-order buffer before having affect on x 86 registers or memory 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
Register file l X 86 architecture has limited number of general purpose registers l Fewer registers means frequeent reuse of registers and reduction in performance. -- uses register renaming to avoid this problems l Movement between registers and memory is unavoidable with x 86 instruction set. K 5 -CPU has a single cycle load from data cache. l Also multi-ported register file, renaming in the reorder buffer -- near optimal speculative performance 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca
Quote from AMD l The right combination l Compatibility with performance 12/7/2020 ENEL 515 -- AMD on K 5 Copyright M. Smith smith@enel. ucalgary. ca