
CS 4527 Artificial Intelligence Bayes Nets Sampling Instructor
CS 4/527: Artificial Intelligence Bayes’ Nets: Sampling Instructor: Jared Saia--- University of New Mexico [These slides were created by Dan Klein, Pieter Abbeel, and Anca. http: //ai. berkeley. edu. ]
Bayes’ Net Representation o A directed, acyclic graph, one node per random variable o A conditional probability table (CPT) for each node o A collection of distributions over X, one for each combination of parents’ values
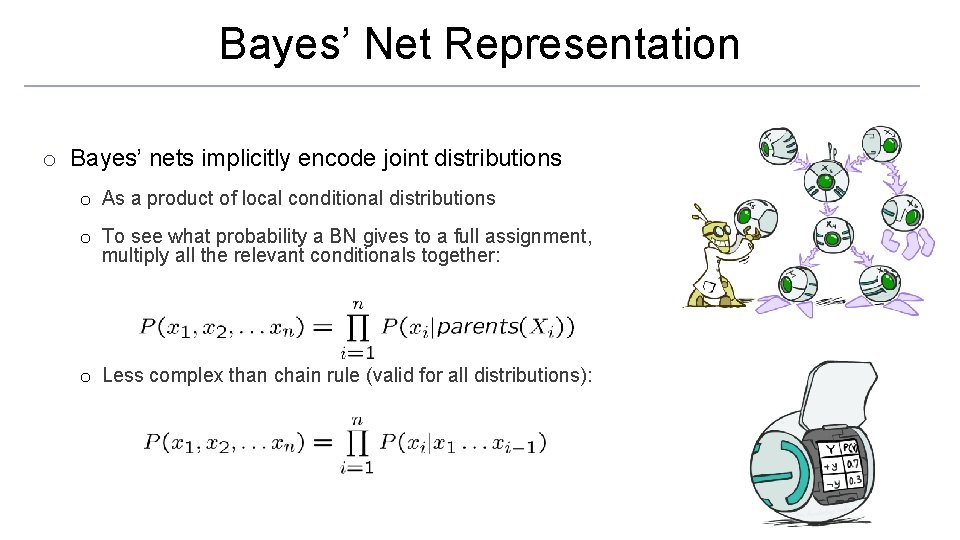
Bayes’ Net Representation o Bayes’ nets implicitly encode joint distributions o As a product of local conditional distributions o To see what probability a BN gives to a full assignment, multiply all the relevant conditionals together: o Less complex than chain rule (valid for all distributions):
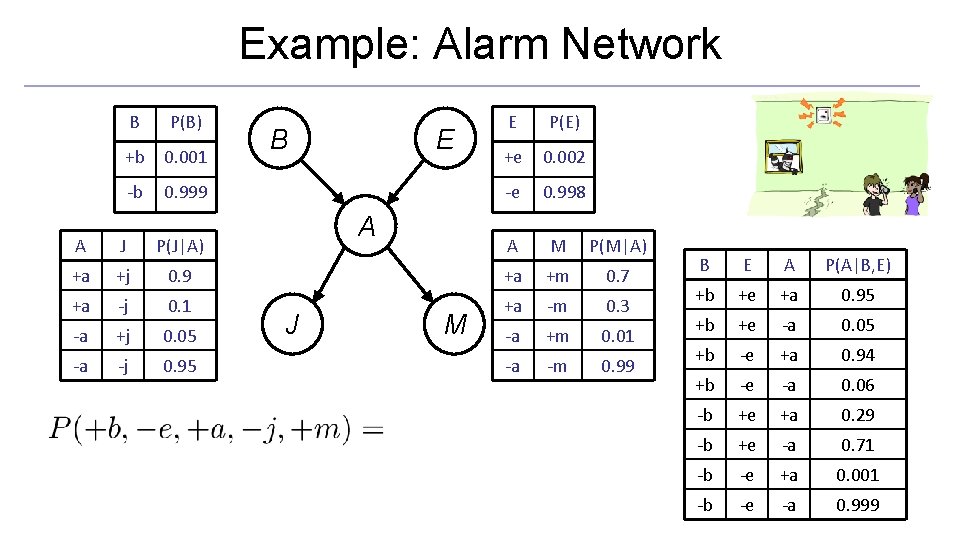
Example: Alarm Network B P(B) +b 0. 001 -b 0. 999 A J P(J|A) +a +j +a B E A E P(E) +e 0. 002 -e 0. 998 A M P(M|A) 0. 9 +a +m 0. 7 -j 0. 1 +a -m 0. 3 -a +j 0. 05 -a +m 0. 01 -a -j 0. 95 -a -m 0. 99 J M B E A P(A|B, E) +b +e +a 0. 95 +b +e -a 0. 05 +b -e +a 0. 94 +b -e -a 0. 06 -b +e +a 0. 29 -b +e -a 0. 71 -b -e +a 0. 001 -b -e -a 0. 999
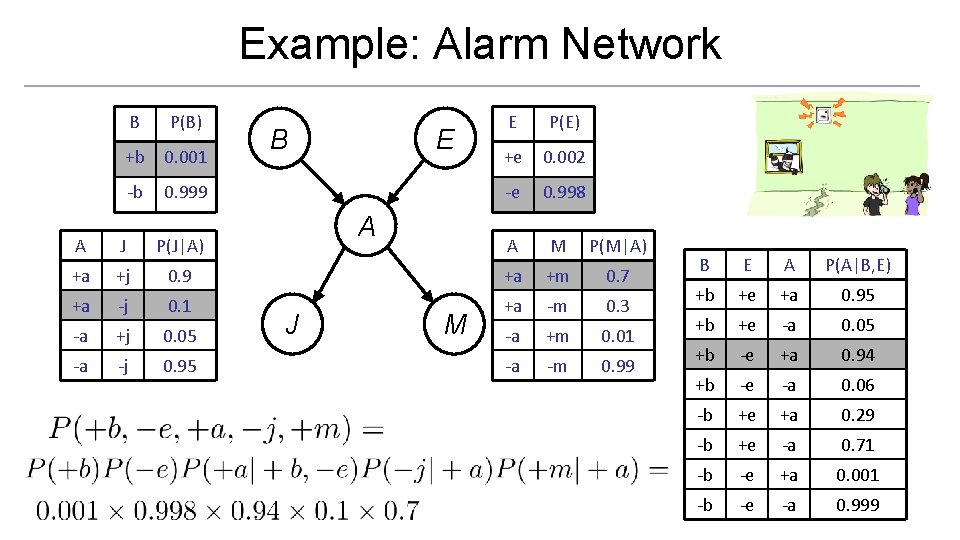
Example: Alarm Network B P(B) +b 0. 001 -b 0. 999 A J P(J|A) +a +j +a B E A E P(E) +e 0. 002 -e 0. 998 A M P(M|A) 0. 9 +a +m 0. 7 -j 0. 1 +a -m 0. 3 -a +j 0. 05 -a +m 0. 01 -a -j 0. 95 -a -m 0. 99 J M B E A P(A|B, E) +b +e +a 0. 95 +b +e -a 0. 05 +b -e +a 0. 94 +b -e -a 0. 06 -b +e +a 0. 29 -b +e -a 0. 71 -b -e +a 0. 001 -b -e -a 0. 999
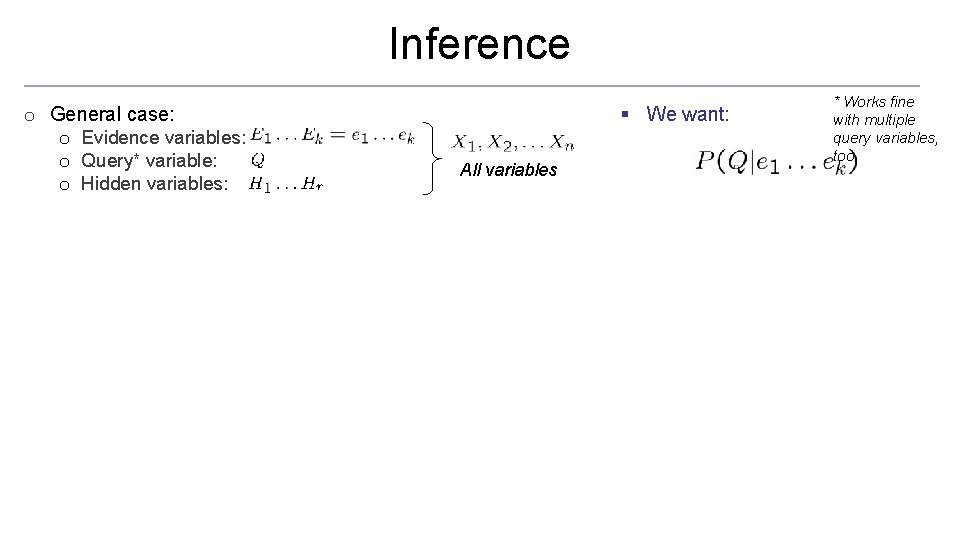
Inference o General case: o Evidence variables: o Query* variable: o Hidden variables: § We want: All variables * Works fine with multiple query variables, too
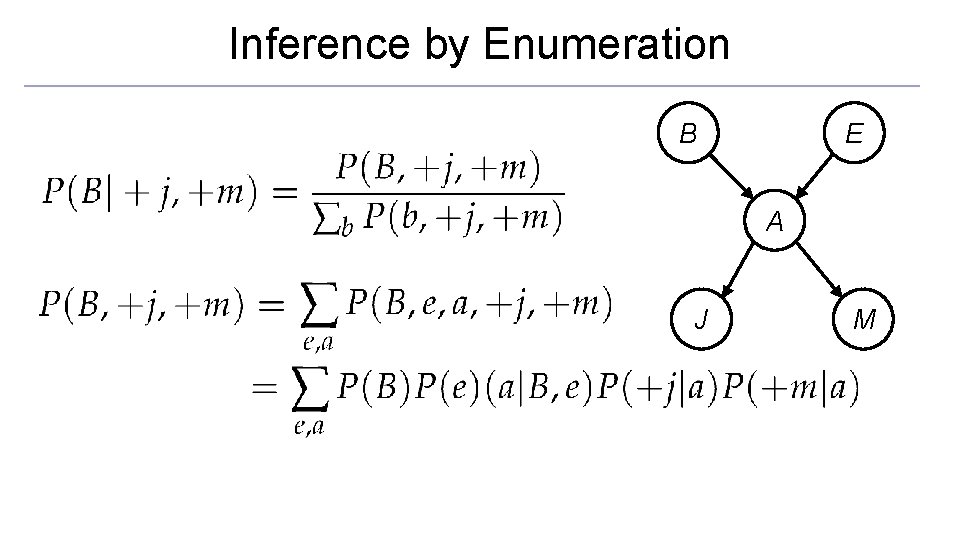
Inference by Enumeration B E A J M

Inference by Enumeration B E A J M
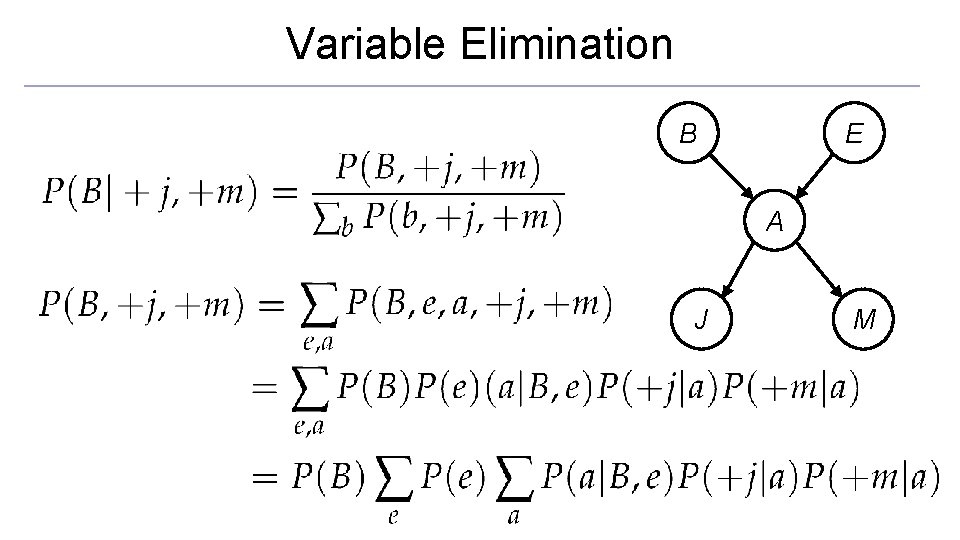
Variable Elimination B E A J M
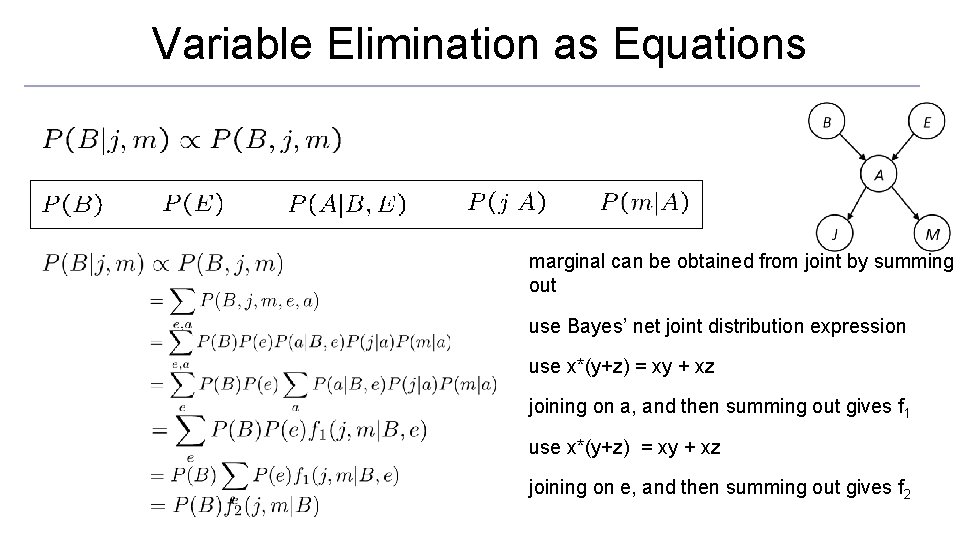
Variable Elimination as Equations marginal can be obtained from joint by summing out use Bayes’ net joint distribution expression use x*(y+z) = xy + xz joining on a, and then summing out gives f 1 use x*(y+z) = xy + xz joining on e, and then summing out gives f 2
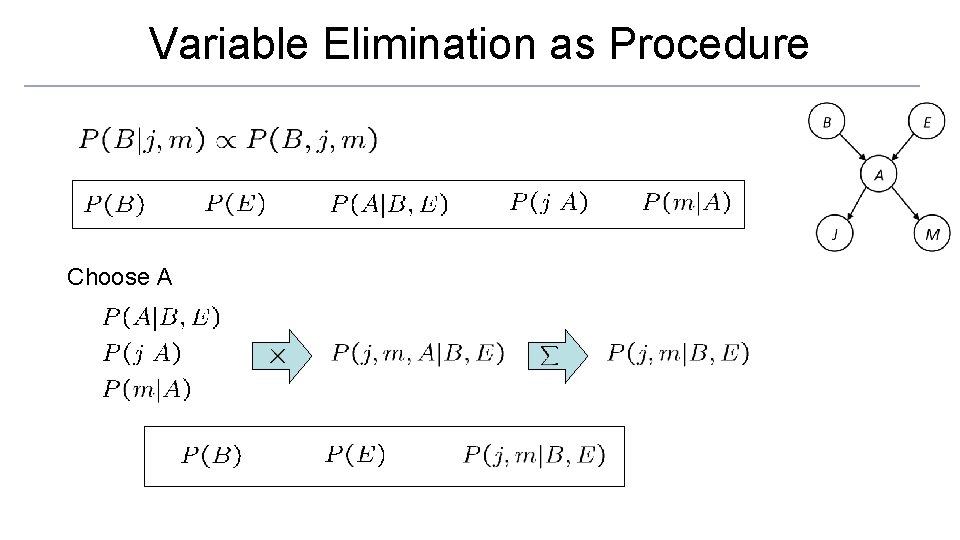
Variable Elimination as Procedure Choose A
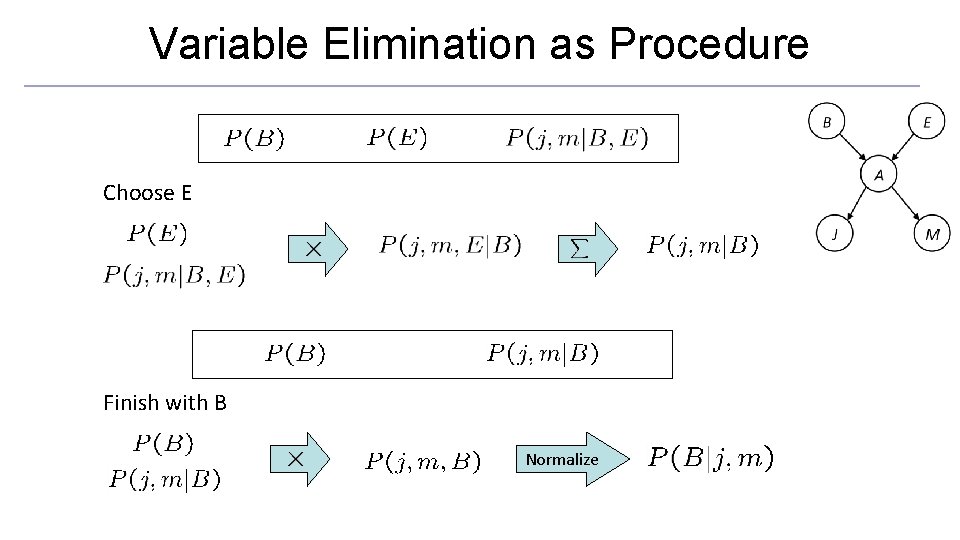
Variable Elimination as Procedure Choose E Finish with B Normalize
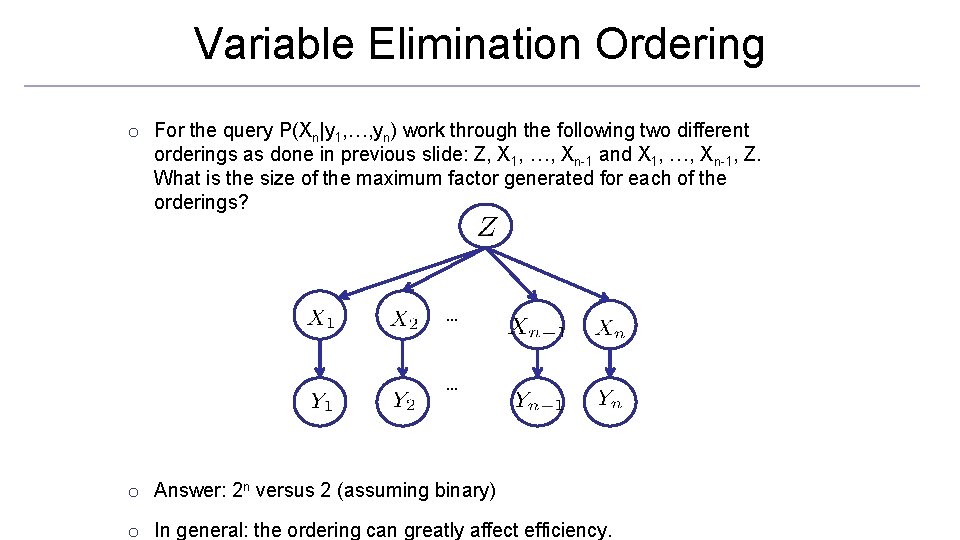
Variable Elimination Ordering o For the query P(Xn|y 1, …, yn) work through the following two different orderings as done in previous slide: Z, X 1, …, Xn-1 and X 1, …, Xn-1, Z. What is the size of the maximum factor generated for each of the orderings? … … o Answer: 2 n versus 2 (assuming binary) o In general: the ordering can greatly affect efficiency.
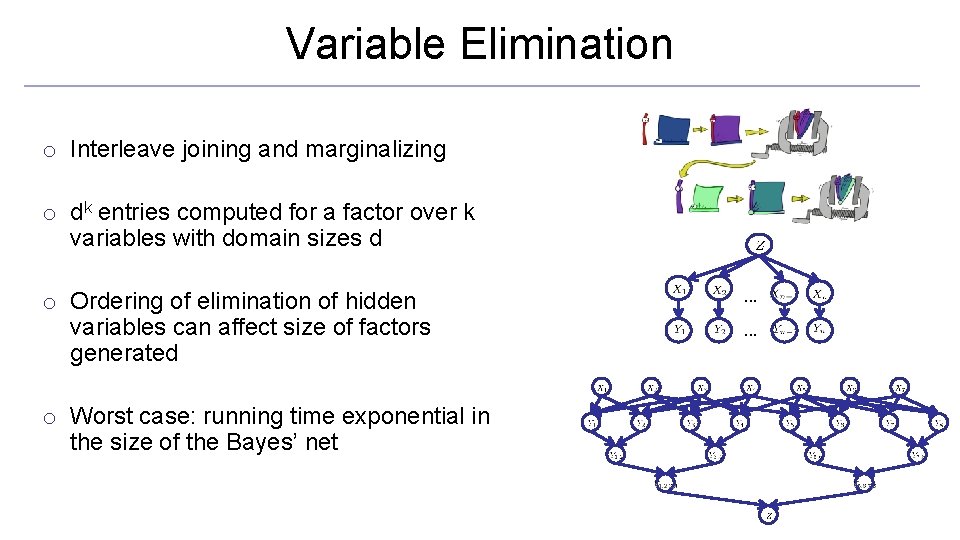
Variable Elimination o Interleave joining and marginalizing o dk entries computed for a factor over k variables with domain sizes d o Ordering of elimination of hidden variables can affect size of factors generated o Worst case: running time exponential in the size of the Bayes’ net … …
Approximate Inference: Sampling
Sampling o Basic idea o Draw N samples from a sampling distribution S o Compute an approximate posterior probability o Show this converges to the true probability P § Why sample? § Inference: getting a sample is faster than computing the right answer (e. g. with variable elimination)
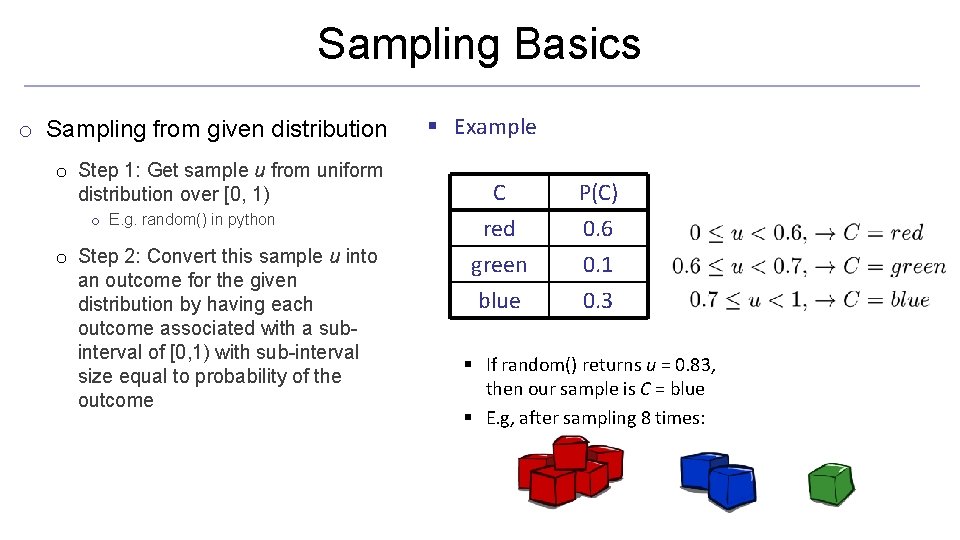
Sampling Basics o Sampling from given distribution o Step 1: Get sample u from uniform distribution over [0, 1) o E. g. random() in python o Step 2: Convert this sample u into an outcome for the given distribution by having each outcome associated with a subinterval of [0, 1) with sub-interval size equal to probability of the outcome § Example C red green blue P(C) 0. 6 0. 1 0. 3 § If random() returns u = 0. 83, then our sample is C = blue § E. g, after sampling 8 times:
Sampling in Bayes’ Nets o Prior Sampling o Rejection Sampling o Likelihood Weighting o Gibbs Sampling
Prior Sampling
Prior Sampling o Ignore evidence. Sample from the joint probability. o Do inference by counting the right samples.
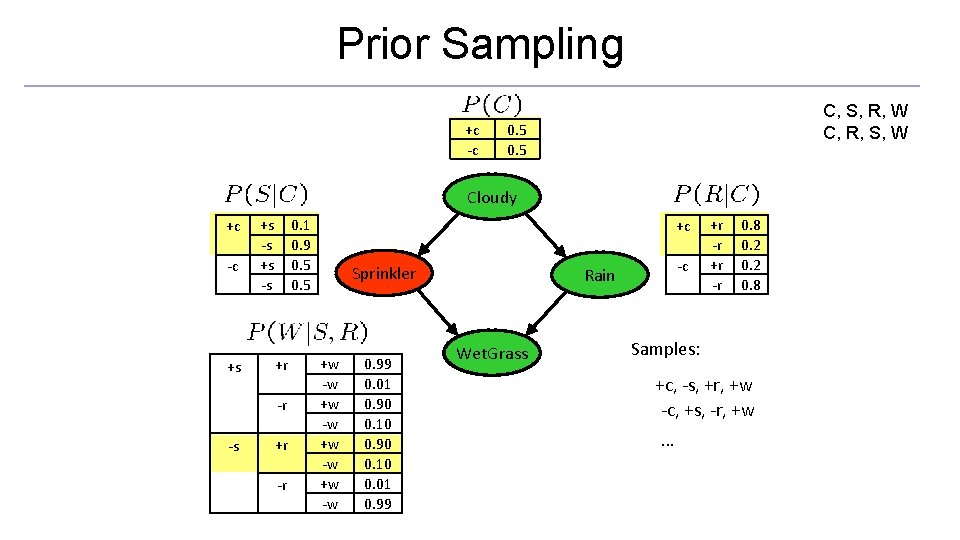
Prior Sampling +c -c C, S, R, W C, R, S, W 0. 5 Cloudy +c -c +s +s -s 0. 1 0. 9 0. 5 +r -r -s +r -r +c Sprinkler +w -w 0. 99 0. 01 0. 90 0. 10 0. 01 0. 99 -c Rain Wet. Grass +r -r 0. 8 0. 2 0. 8 Samples: +c, -s, +r, +w -c, +s, -r, +w …
Prior Sampling o For i=1, 2, …, n o Sample xi from P(Xi | Parents(Xi)) o Return (x 1, x 2, …, xn)
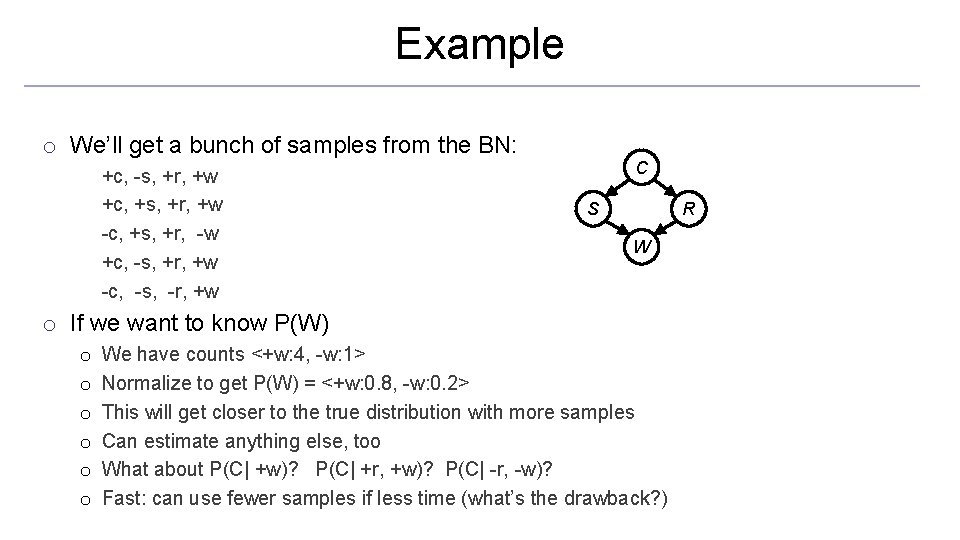
Example o We’ll get a bunch of samples from the BN: +c, -s, +r, +w +c, +s, +r, +w -c, +s, +r, -w +c, -s, +r, +w -c, -s, -r, +w C S R W o If we want to know P(W) o o o We have counts <+w: 4, -w: 1> Normalize to get P(W) = <+w: 0. 8, -w: 0. 2> This will get closer to the true distribution with more samples Can estimate anything else, too What about P(C| +w)? P(C| +r, +w)? P(C| -r, -w)? Fast: can use fewer samples if less time (what’s the drawback? )
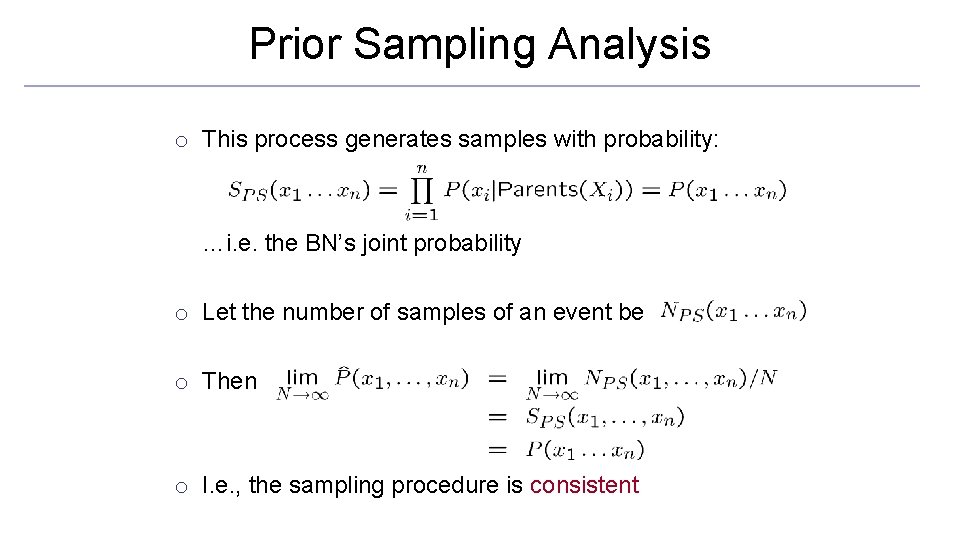
Prior Sampling Analysis o This process generates samples with probability: …i. e. the BN’s joint probability o Let the number of samples of an event be o Then o I. e. , the sampling procedure is consistent
Rejection Sampling
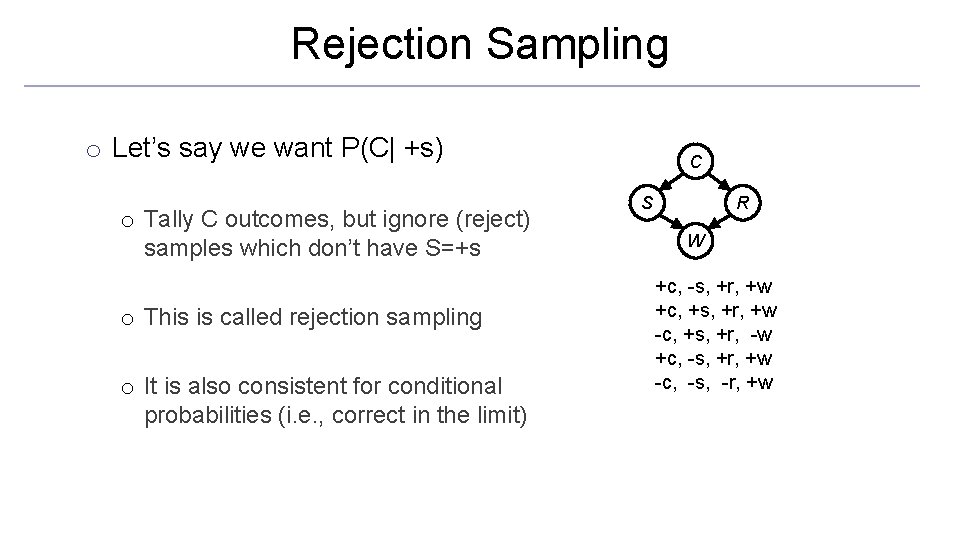
Rejection Sampling o Let’s say we want P(C| +s) o Tally C outcomes, but ignore (reject) samples which don’t have S=+s o This is called rejection sampling o It is also consistent for conditional probabilities (i. e. , correct in the limit) C S R W +c, -s, +r, +w +c, +s, +r, +w -c, +s, +r, -w +c, -s, +r, +w -c, -s, -r, +w
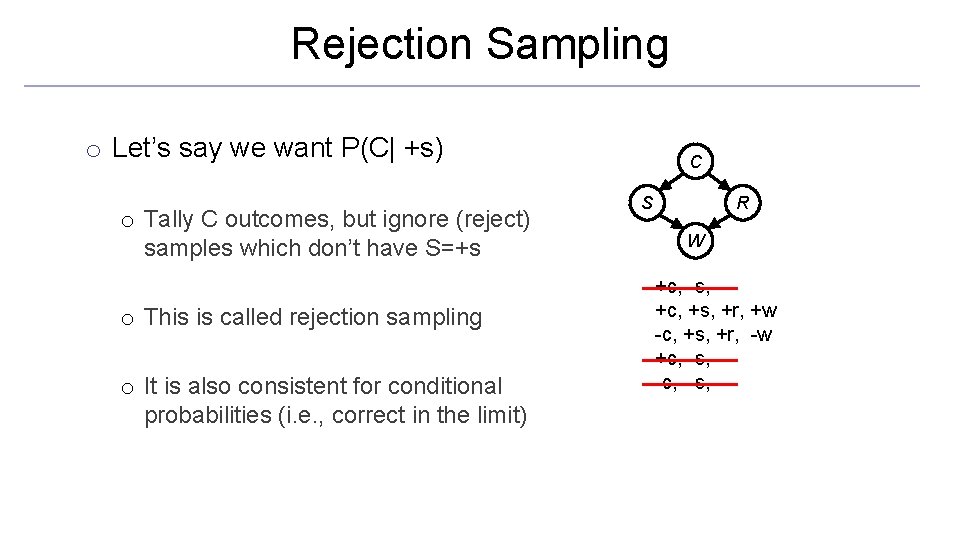
Rejection Sampling o Let’s say we want P(C| +s) o Tally C outcomes, but ignore (reject) samples which don’t have S=+s o This is called rejection sampling o It is also consistent for conditional probabilities (i. e. , correct in the limit) C S R W +c, -s, +c, +s, +r, +w -c, +s, +r, -w +c, -s, -c, -s,
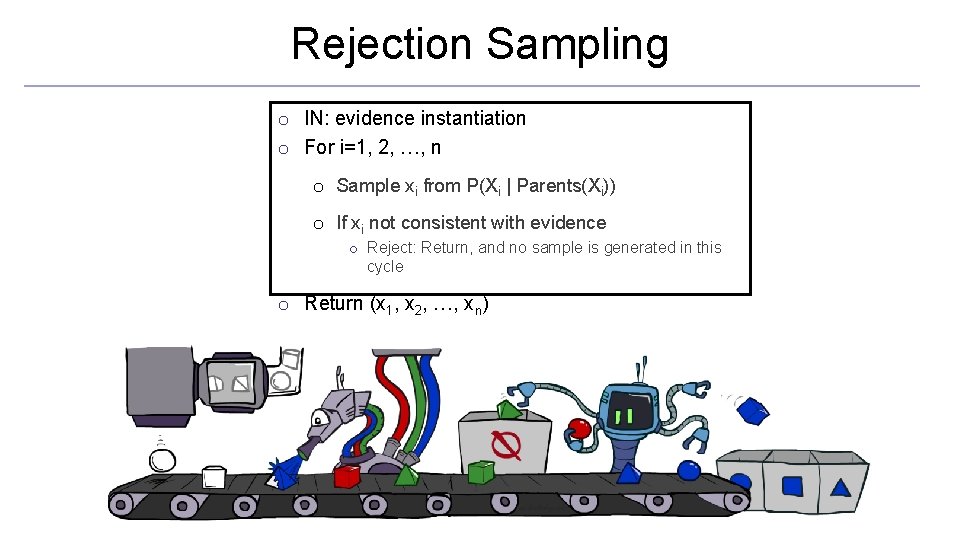
Rejection Sampling o IN: evidence instantiation o For i=1, 2, …, n o Sample xi from P(Xi | Parents(Xi)) o If xi not consistent with evidence o Reject: Return, and no sample is generated in this cycle o Return (x 1, x 2, …, xn)
Likelihood Weighting
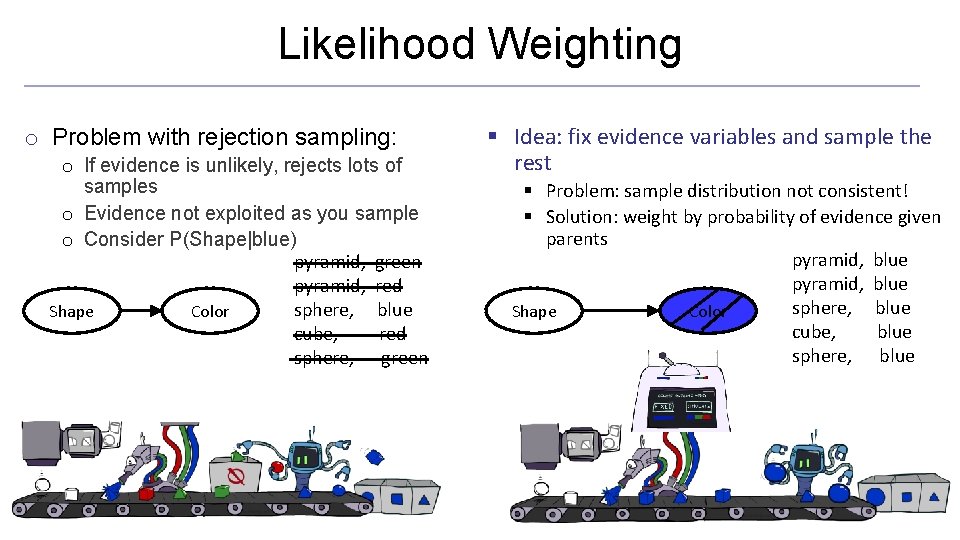
Likelihood Weighting o Problem with rejection sampling: o If evidence is unlikely, rejects lots of samples o Evidence not exploited as you sample o Consider P(Shape|blue) pyramid, green pyramid, red sphere, blue Shape Color cube, red sphere, green § Idea: fix evidence variables and sample the rest § Problem: sample distribution not consistent! § Solution: weight by probability of evidence given parents pyramid, blue sphere, blue Shape Color cube, blue sphere, blue
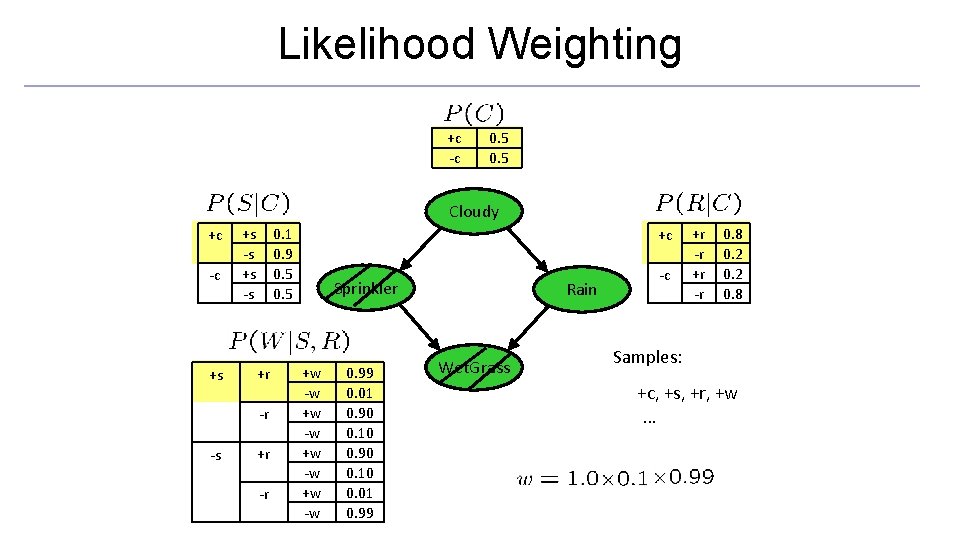
Likelihood Weighting +c -c 0. 5 Cloudy +c -c +s +s -s 0. 1 0. 9 0. 5 +r -r -s +r -r +c Sprinkler +w -w 0. 99 0. 01 0. 90 0. 10 0. 01 0. 99 Rain Wet. Grass -c +r -r 0. 8 0. 2 0. 8 Samples: +c, +s, +r, +w …
Likelihood Weighting o IN: evidence instantiation o w = 1. 0 o for i=1, 2, …, n o if Xi is an evidence variable o Xi = observation xi for Xi o Set w = w * P(xi | Parents(Xi)) o else o Sample xi from P(Xi | Parents(Xi)) o return (x 1, x 2, …, xn), w
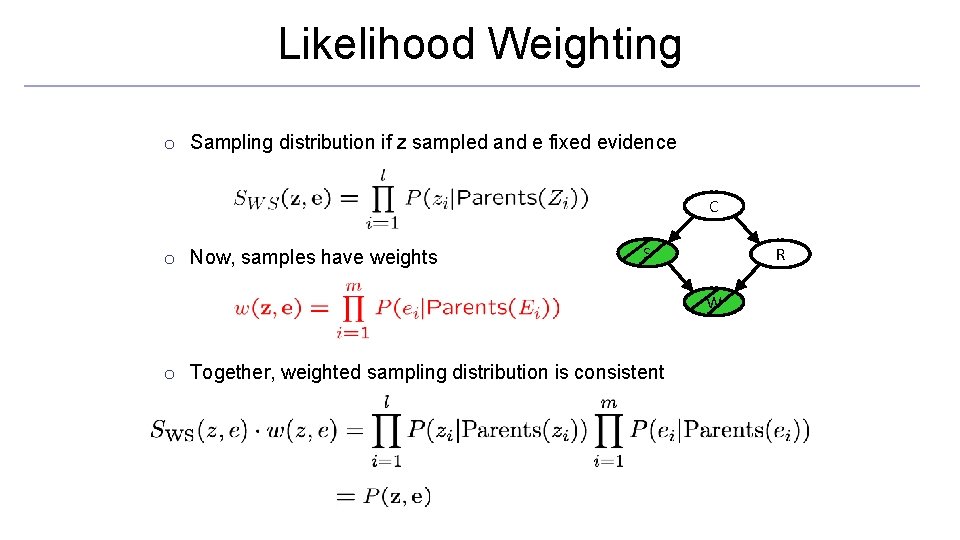
Likelihood Weighting o Sampling distribution if z sampled and e fixed evidence Cloudy C o Now, samples have weights S R W o Together, weighted sampling distribution is consistent

Estimating Probabilities o If we want to know P(R|+s, +w): o same as before, we have samples for +r and –r o instead of just counting, take their weights into account!
Likelihood Weighting o Likelihood weighting is good o We have taken evidence into account as we generate the sample o E. g. here, W’s value will get picked based on the evidence values of S, R o More of our samples will reflect the state of the world suggested by the evidence § Likelihood weighting doesn’t solve all our problems § Evidence influences the choice of downstream variables, but not upstream ones (C isn’t more likely to get a value matching the evidence) § We would like to consider evidence when we sample every variable Gibbs sampling
Gibbs Sampling
Gibbs Sampling o Procedure: keep track of a full instantiation x 1, x 2, …, xn. Start with an arbitrary instantiation consistent with the evidence. Sample one variable at a time, conditioned on all the rest, but keep evidence fixed. Keep repeating this for a long time. o Property: in the limit of repeating this infinitely many times the resulting sample is coming from the correct distribution o Rationale: both upstream and downstream variables condition on evidence. o In contrast: likelihood weighting only conditions on upstream evidence, and hence weights obtained in likelihood weighting can sometimes be very small. Sum of weights over all samples is indicative of how many “effective” samples were obtained, so want high weight.

Gibbs Sampling Example: P( S | +r) o Step 1: Fix evidence o R = +r § Step 2: Initialize other variables C S C § Randomly +r S +r W W o Steps 3: Repeat o Choose a non-evidence variable X o Resample X from P( X | all other variables) C S C +r W S C +r W S +r W
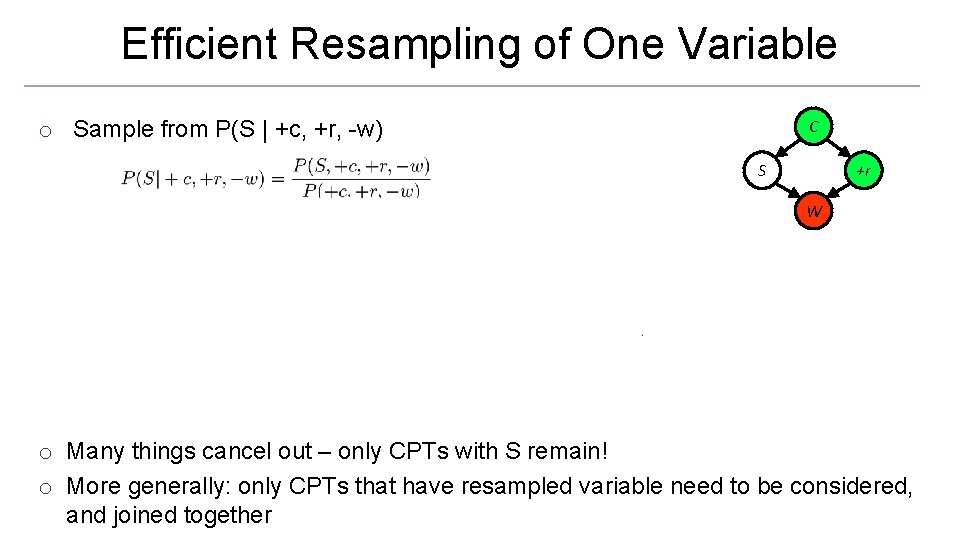
Efficient Resampling of One Variable o Sample from P(S | +c, +r, -w) C S +r W o Many things cancel out – only CPTs with S remain! o More generally: only CPTs that have resampled variable need to be considered, and joined together
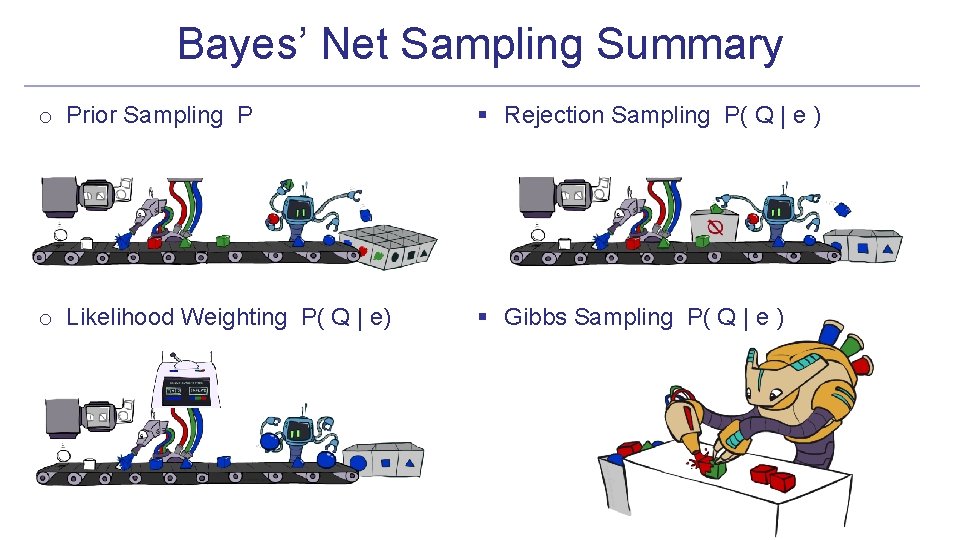
Bayes’ Net Sampling Summary o Prior Sampling P § Rejection Sampling P( Q | e ) o Likelihood Weighting P( Q | e) § Gibbs Sampling P( Q | e )
Further Reading on Gibbs Sampling* o Gibbs sampling produces sample from the query distribution P( Q | e ) in limit of re-sampling infinitely often o Gibbs sampling is a special case of more general methods called Markov chain Monte Carlo (MCMC) methods o Metropolis-Hastings is one of the more famous MCMC methods (in fact, Gibbs sampling is a special case of Metropolis-Hastings) o You may read about Monte Carlo methods – they’re just sampling
- Slides: 41