
Compiling ApplicationSpecific Hardware Mihai Budiu Seth Copen Goldstein
Compiling Application-Specific Hardware Mihai Budiu Seth Copen Goldstein Carnegie Mellon University
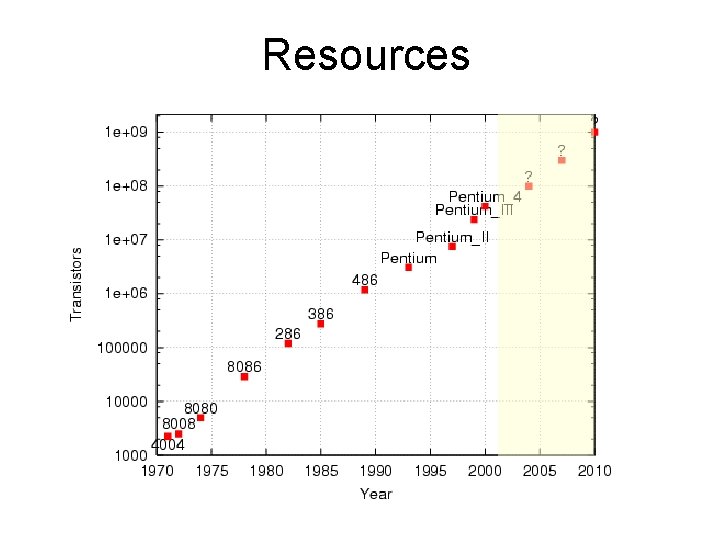
Resources
Problems • • Complexity Power Global Signals Limited issue window => limited ILP We propose a scalable architecture
Outline • Introduction • ASH: Application Specific Hardware • Compiling for ASH • Conclusions
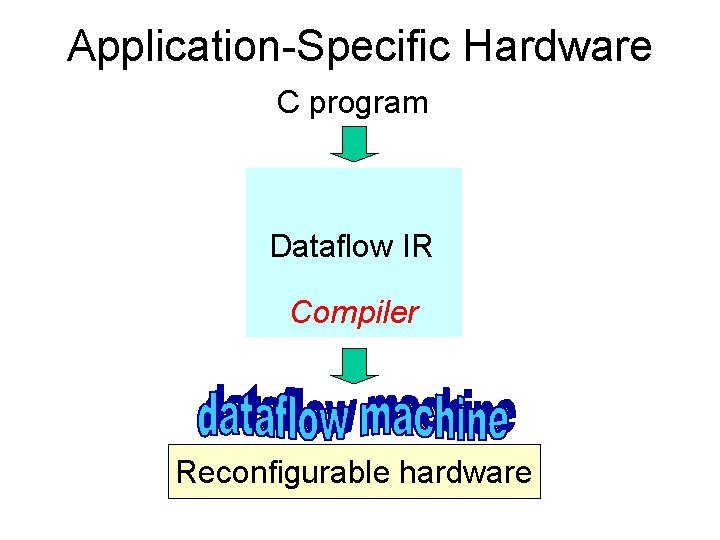
Application-Specific Hardware C program Dataflow IR Compiler Reconfigurable hardware
Our Solution General: applicable to today’s software - programming languages - applications Automatic: compiler-driven Scalable: - run-time: with clock, hardware - compile-time: with program size Parallelism: exploit application parallelism
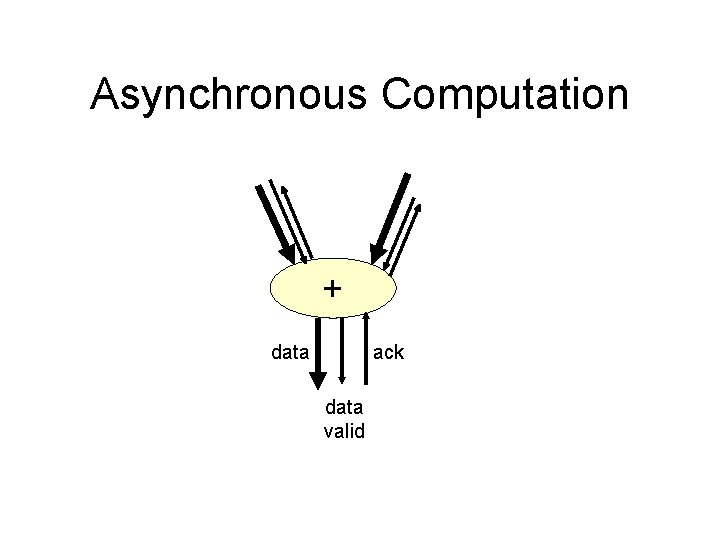
Asynchronous Computation + data ack data valid
New • Entire C applications • Dynamically scheduled circuits • Custom dataflow machines - application-specific - direct execution (no interpretation) - spatial computation
Outline • Scalability • Application Specific Hardware • CASH: Compiling in ASH • Conclusions
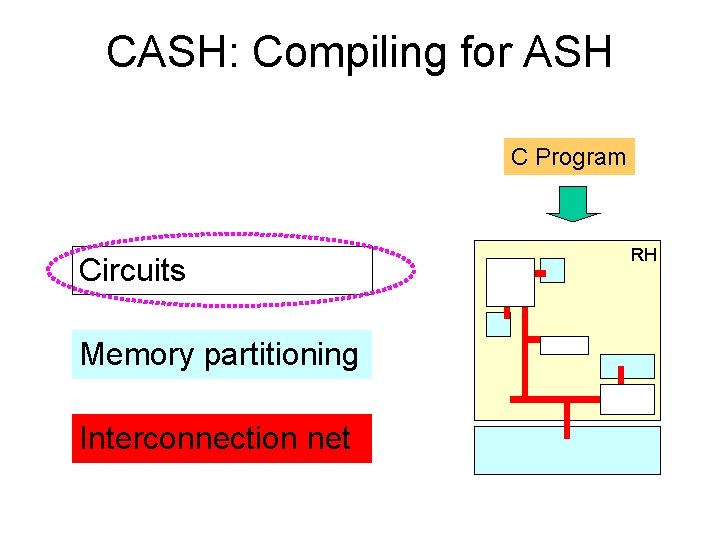
CASH: Compiling for ASH C Program Circuits Memory partitioning Interconnection net RH
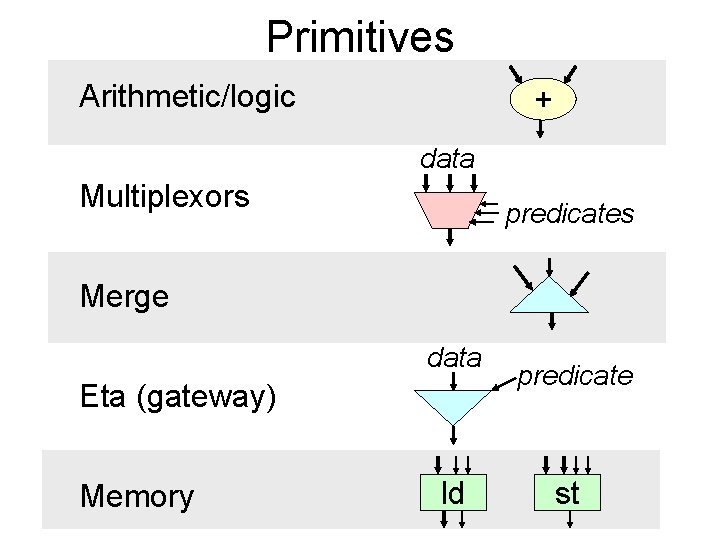
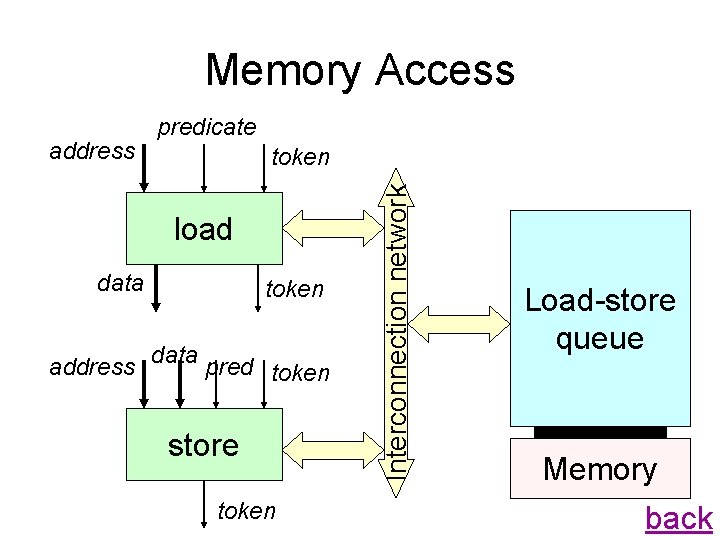
Primitives Arithmetic/logic + data Multiplexors predicates Merge data Eta (gateway) Memory ld predicate st
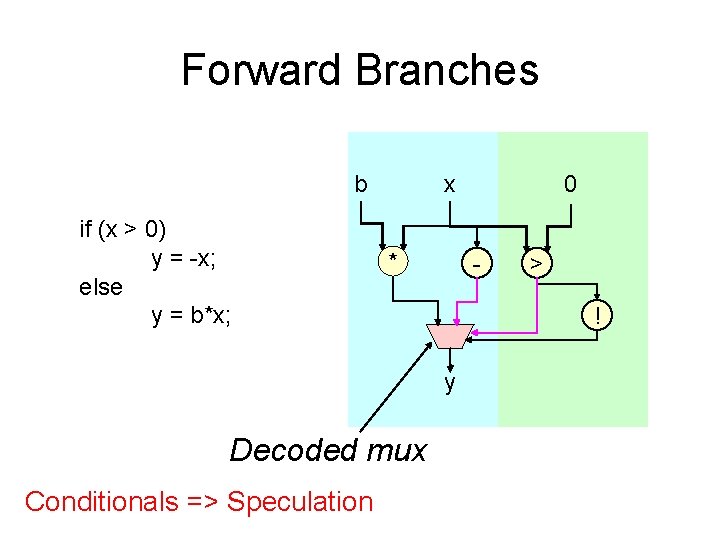
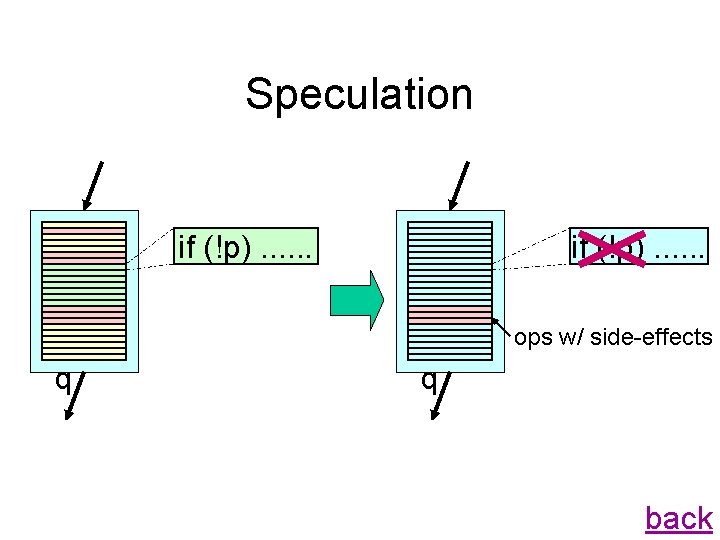
Forward Branches b if (x > 0) y = -x; else y = b*x; x * - Conditionals => Speculation > ! y Decoded mux 0
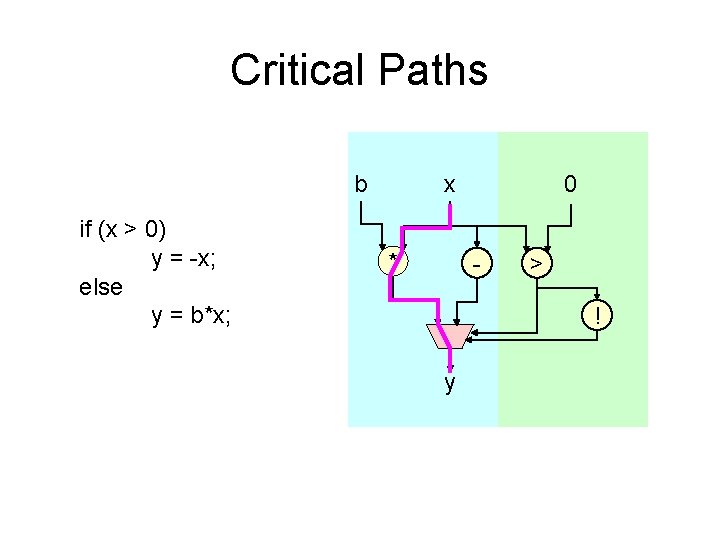
Critical Paths b if (x > 0) y = -x; else y = b*x; x * 0 - > ! y
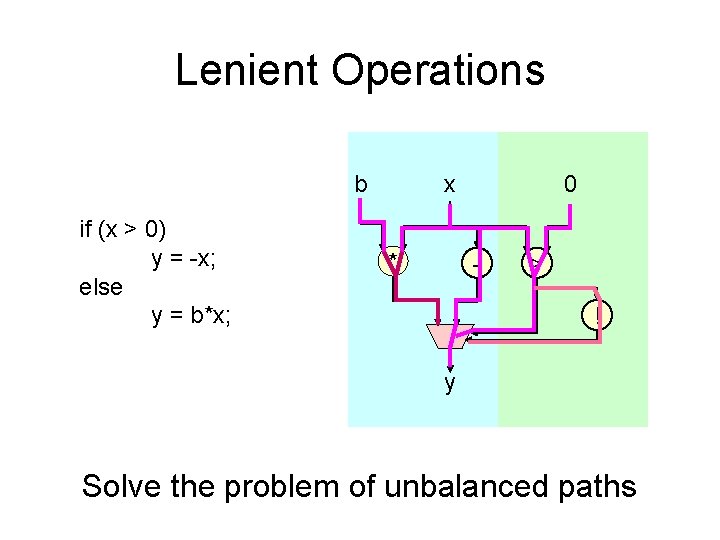
Lenient Operations b if (x > 0) y = -x; else y = b*x; x * 0 - > ! y Solve the problem of unbalanced paths
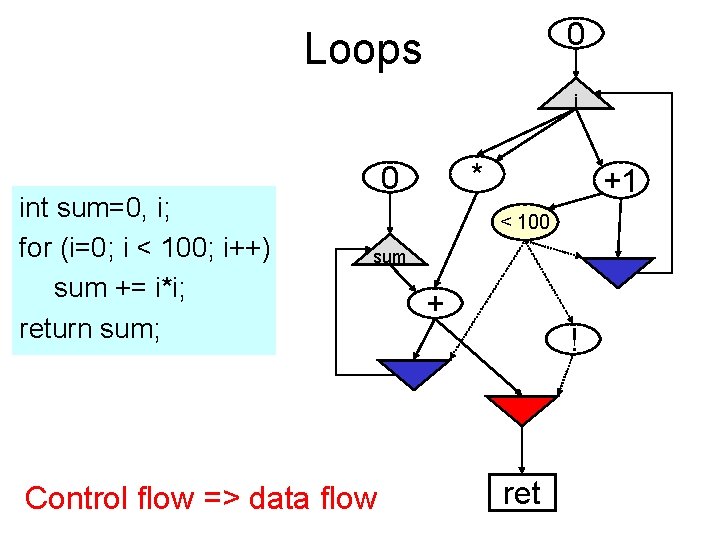
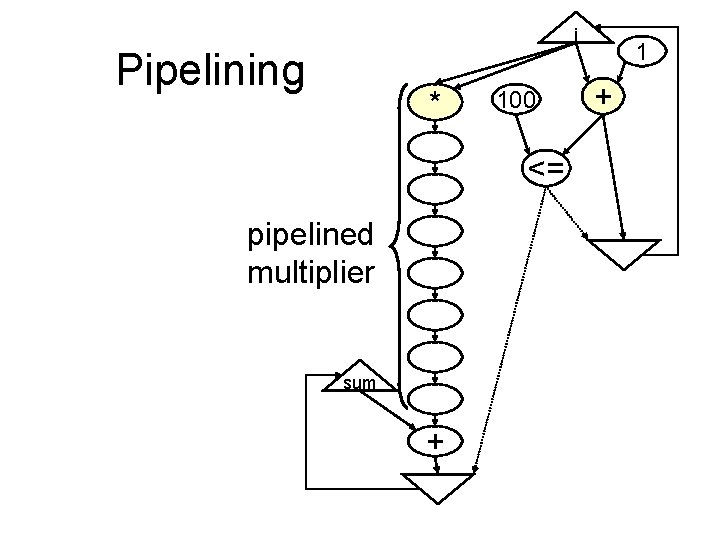
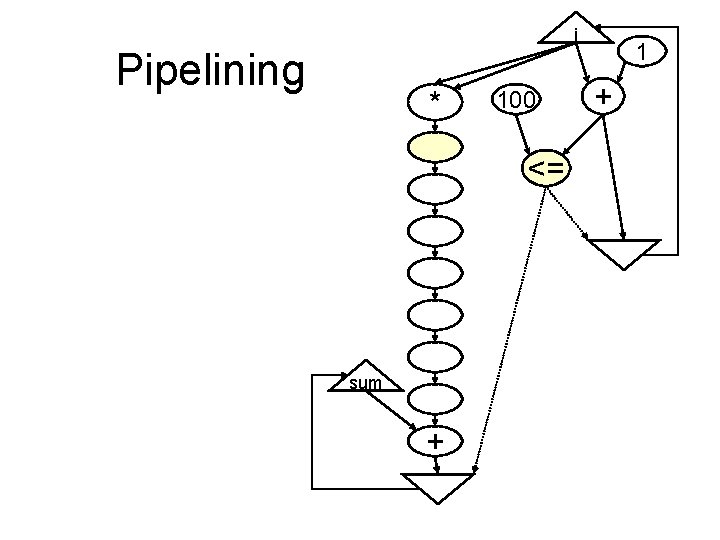
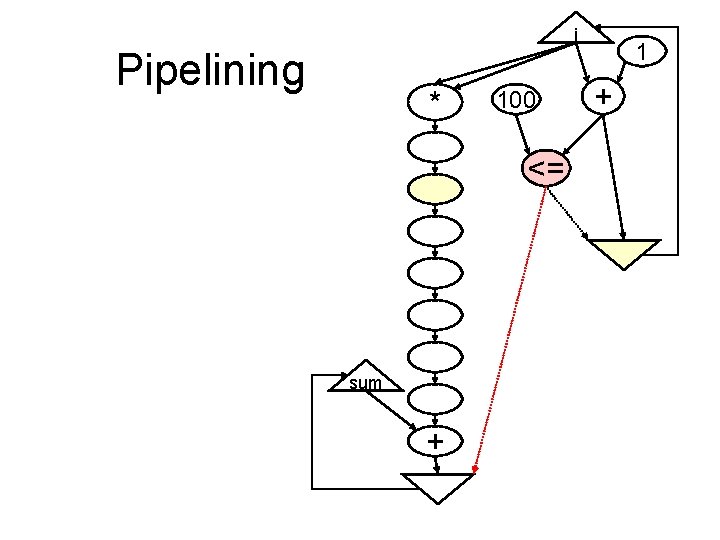
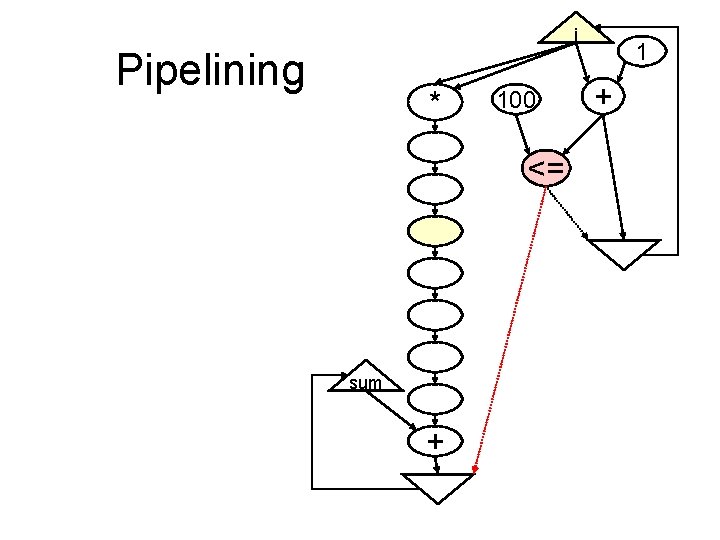
0 Loops i int sum=0, i; for (i=0; i < 100; i++) sum += i*i; return sum; * 0 +1 < 100 sum Control flow => data flow + ! ret
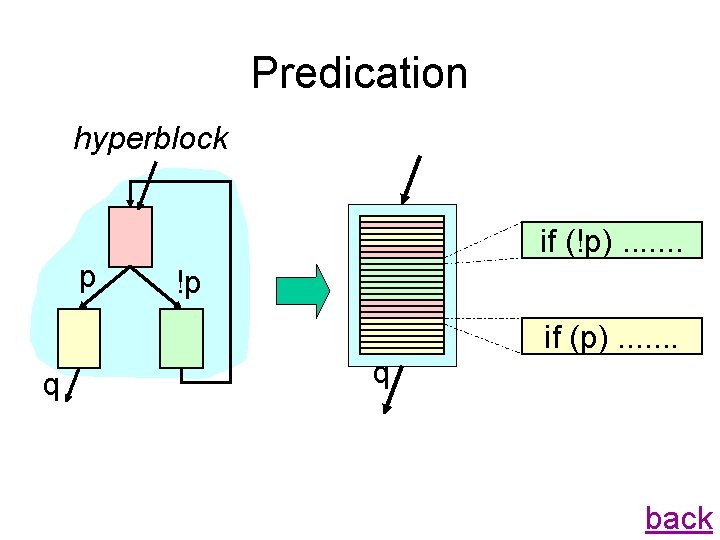
Compilation • Translate C to dataflow machines • Optimizations software-, hardware-, dataflow-specific • Expose parallelism – predication – speculation – localized synchronization – pipelining
i Pipelining * 100 <= pipelined multiplier sum + 1 +
i Pipelining * 100 <= sum + 1 +
i Pipelining * 100 <= sum + 1 +
i Pipelining * 100 <= sum + 1 +
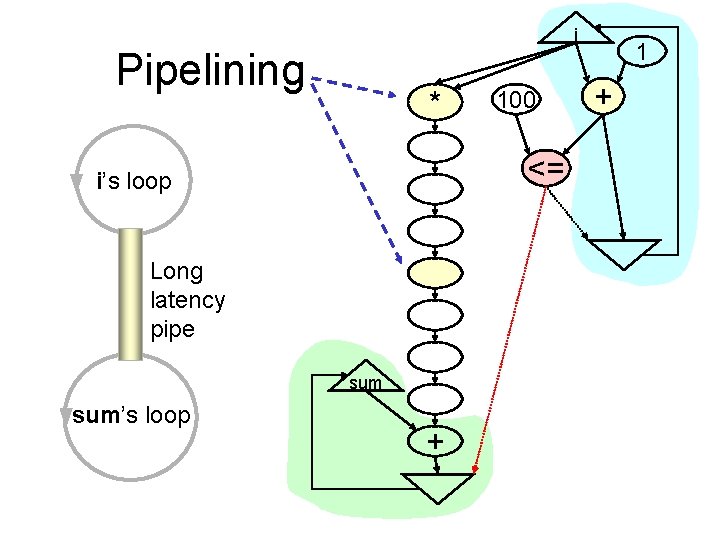
i Pipelining * <= i’s loop Long latency pipe sum’s loop 100 + 1 +
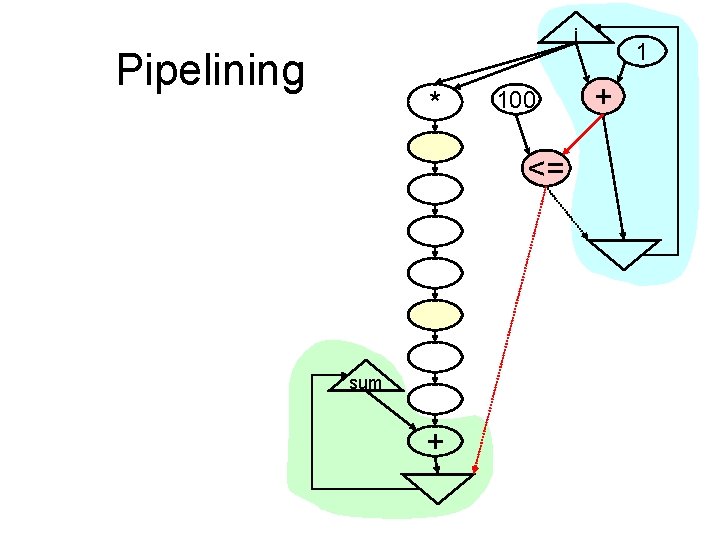
i Pipelining * 100 <= sum + 1 +
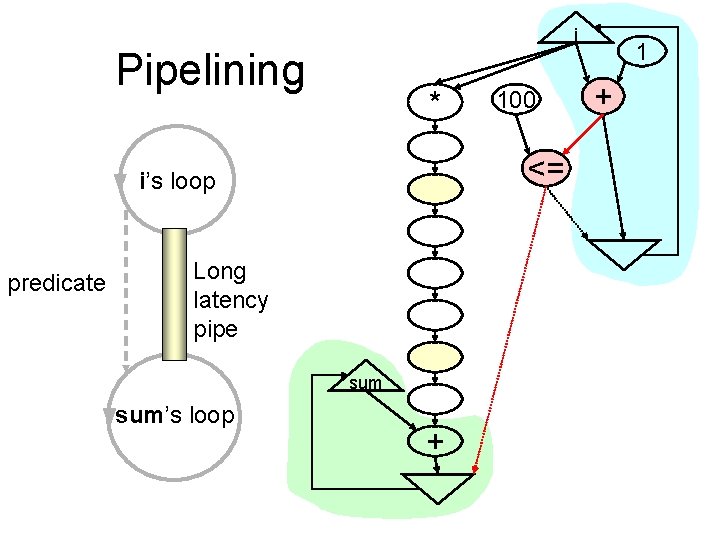
i Pipelining * <= i’s loop predicate Long latency pipe sum’s loop 100 + 1 +
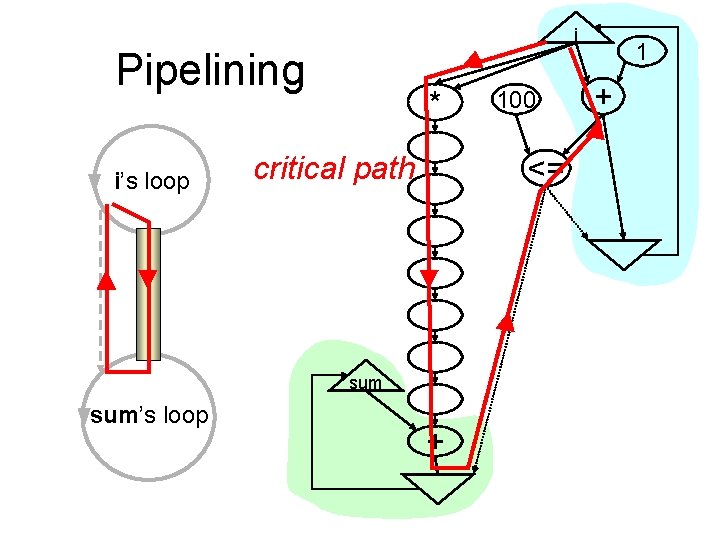
i Pipelining i’s loop * critical path <= Predicate ack edge is on the critical path. sum’s loop 100 + 1 +
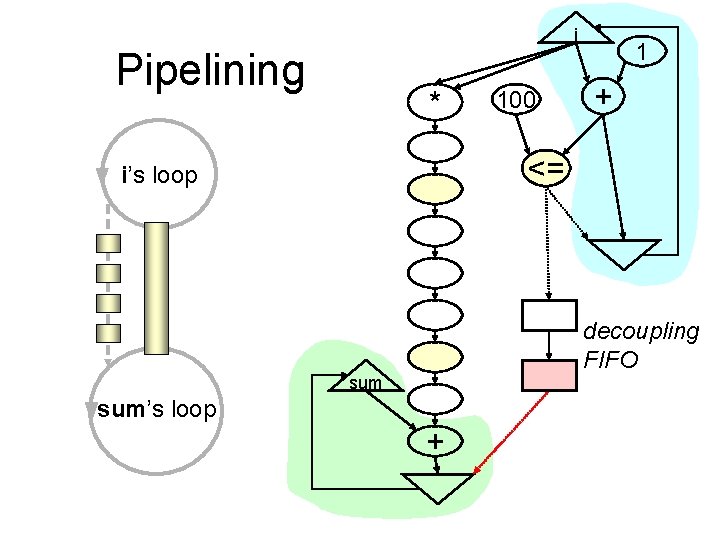
i Pipelining * 100 1 + <= i’s loop decoupling FIFO sum’s loop +
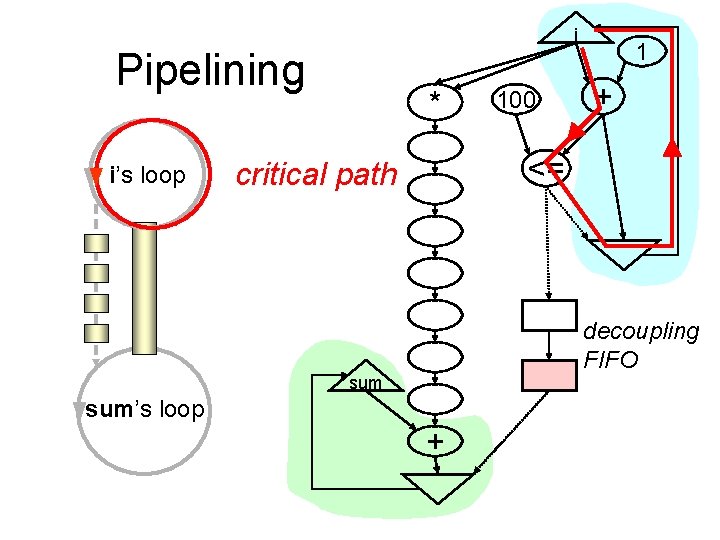
i Pipelining i’s loop * 100 1 + <= critical path decoupling FIFO sum’s loop +
ASH Features • What you code is what you get – no hidden control logic – lean hardware (no CAM, multi-ported files, etc. ) – no global signals • Compiler has complete control • Dynamic scheduling => latency tolerant • Natural ILP and loop pipelining
Conclusions • ASH: compiler-synthesized hardware from HLL • Exposes program parallelism • Dataflow techniques applied to hardware • ASH promises to scale with: – circuit speed – transistors – program size
Backup slides • Hyperblocks • Predication • Speculation • Memory access • Procedure calls • Recursive calls • Resources • Performance
Hyperblocks Procedure back
Predication hyperblock p q if (!p). . . . !p q if (p). . . . back
Speculation if (!p). . . ops w/ side-effects q q back
Memory Access token load data token address data pred token store token Interconnection network address predicate Load-store queue Memory back
args call P Interconnection network Procedure calls Extract args result caller ret Procedure P back
Recursion save live values recursive call restore live values stack hyperblock back
Resources • Estimated Spec. INT 95 and Mediabench • Average < 100 bit-operations/line of code • Routing resources harder to estimate • Detailed data in paper back
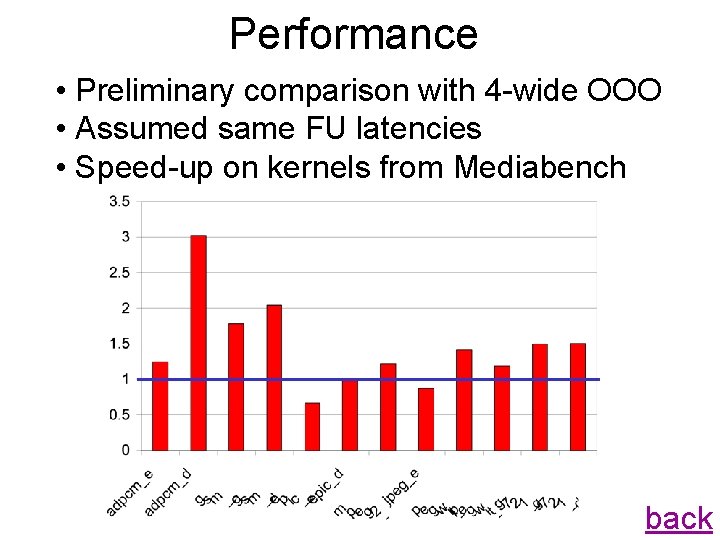
Performance • Preliminary comparison with 4 -wide OOO • Assumed same FU latencies • Speed-up on kernels from Mediabench back
- Slides: 37