
COMP 541 Pipelined MIPS Montek Singh Nov 16
- Slides: 47
COMP 541 Pipelined MIPS Montek Singh Nov 16, 2015 1
Topics ã Today’s topic: Pipelining l Can think of it as: Ø A way to parallelize, or Ø A way to make better utilization of the hardware. l Goal: Try to use all hardware every clock cycle ã Reading l Section 7. 5 of textbook 2
Parallelism ã Two types of parallelism: l Spatial parallelism Ø duplicate hardware performs multiple tasks at once l Temporal parallelism Ø task is broken into multiple stages – each stage operating on different parts of distinct instructions Ø also called pipelining – example: an assembly line
Parallelism Definitions ã Some definitions: l Token: A group of inputs processed together to produce a group of outputs Ø a “bundle” l Latency: Time for one token to pass from start to end l Throughput: The number of tokens that can be processed per unit time ã Parallelism increases throughput l Often sacrificing latency
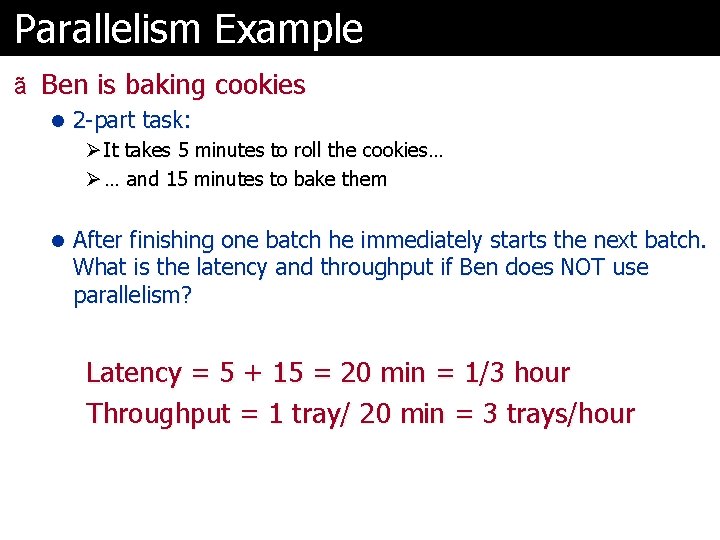
Parallelism Example ã Ben is baking cookies l 2 -part task: Ø It takes 5 minutes to roll the cookies… Ø … and 15 minutes to bake them l After finishing one batch he immediately starts the next batch. What is the latency and throughput if Ben does NOT use parallelism? Latency = 5 + 15 = 20 min = 1/3 hour Throughput = 1 tray/ 20 min = 3 trays/hour
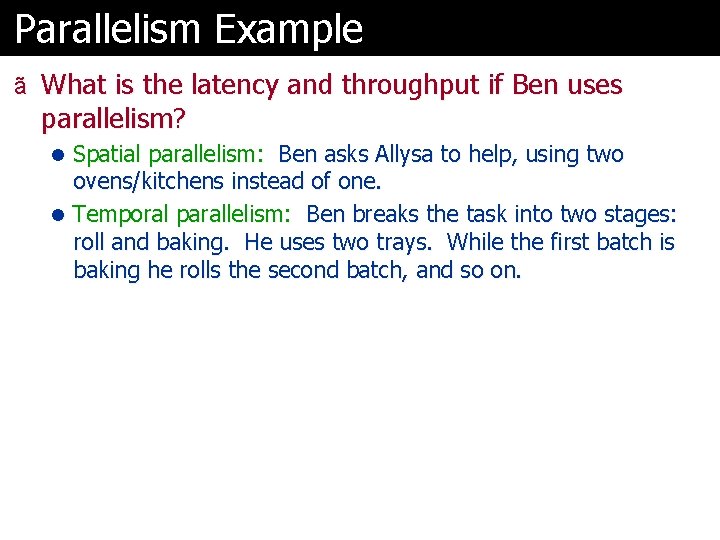
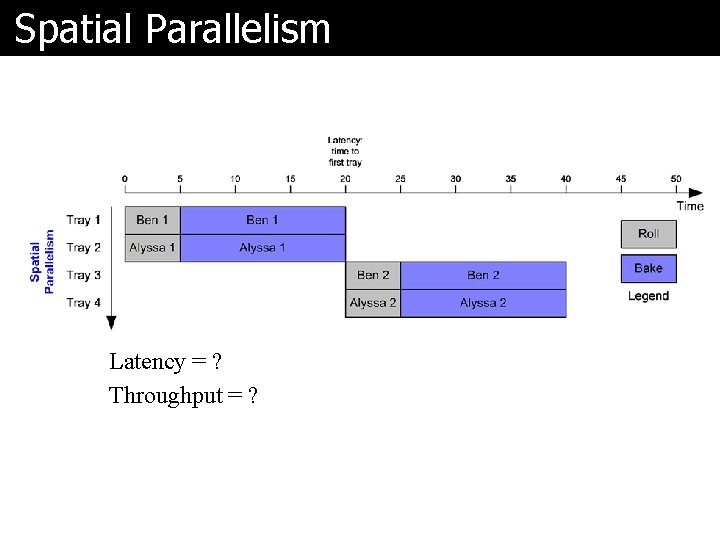
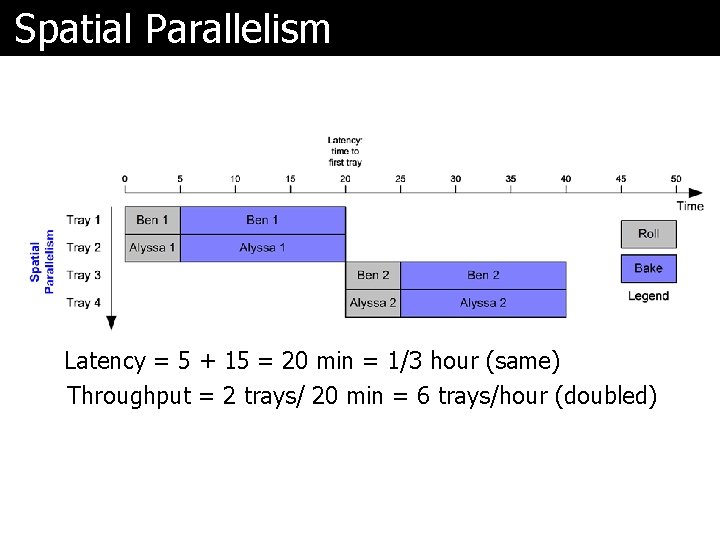
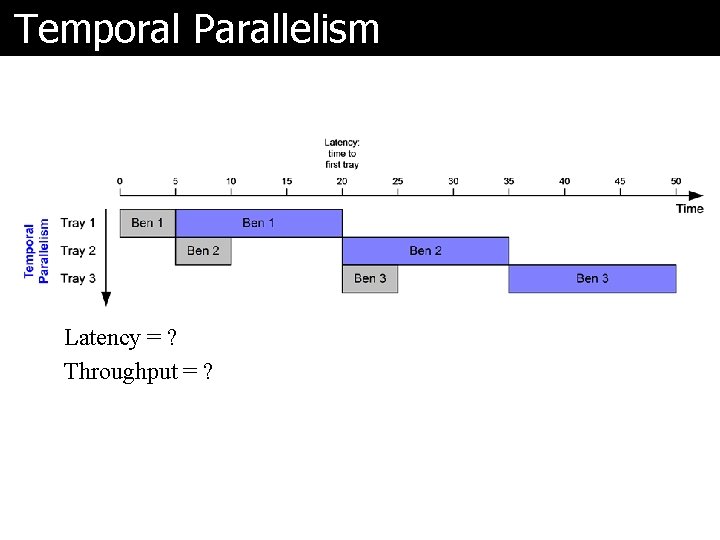
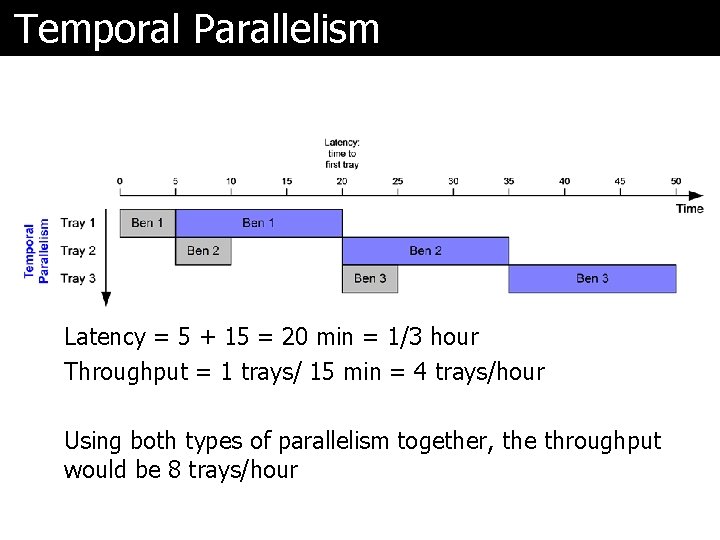
Parallelism Example ã What is the latency and throughput if Ben uses parallelism? l Spatial parallelism: Ben asks Allysa to help, using two ovens/kitchens instead of one. l Temporal parallelism: Ben breaks the task into two stages: roll and baking. He uses two trays. While the first batch is baking he rolls the second batch, and so on.
Spatial Parallelism Latency = ? Throughput = ?
Spatial Parallelism Latency = 5 + 15 = 20 min = 1/3 hour (same) Throughput = 2 trays/ 20 min = 6 trays/hour (doubled)
Temporal Parallelism Latency = ? Throughput = ?
Temporal Parallelism Latency = 5 + 15 = 20 min = 1/3 hour Throughput = 1 trays/ 15 min = 4 trays/hour Using both types of parallelism together, the throughput would be 8 trays/hour
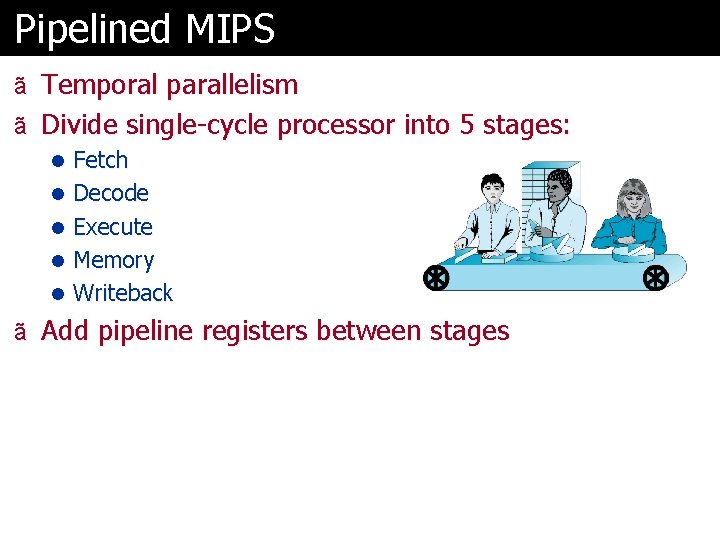
Pipelined MIPS ã Temporal parallelism ã Divide single-cycle processor into 5 stages: l Fetch l Decode l Execute l Memory l Writeback ã Add pipeline registers between stages
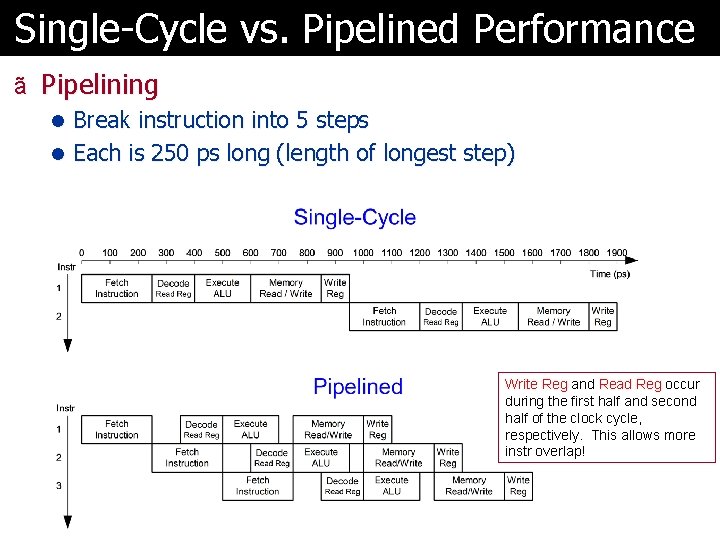
Single-Cycle vs. Pipelined Performance ã Pipelining l Break instruction into 5 steps l Each is 250 ps long (length of longest step) Write Reg and Read Reg occur during the first half and second half of the clock cycle, respectively. This allows more instr overlap!
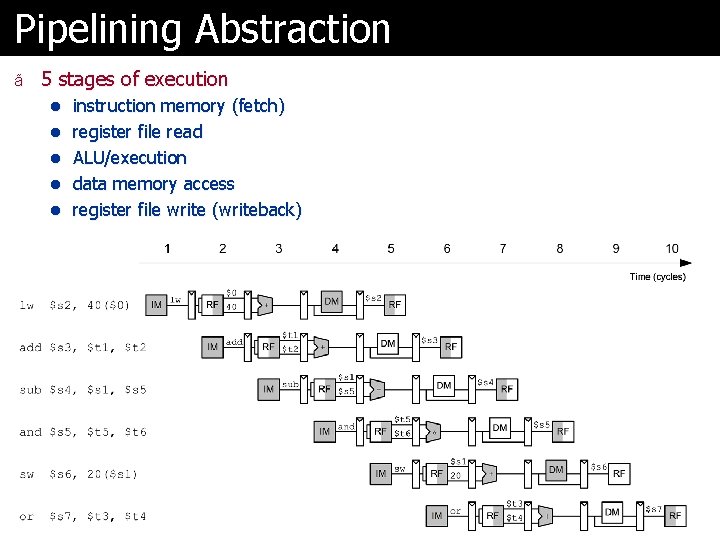
Pipelining Abstraction ã 5 stages of execution l instruction memory (fetch) l register file read l ALU/execution l data memory access l register file write (writeback)
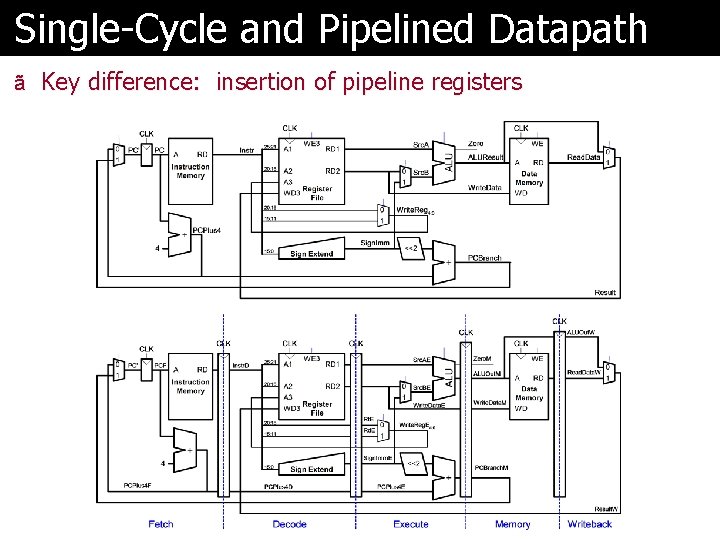
Single-Cycle and Pipelined Datapath ã Key difference: insertion of pipeline registers
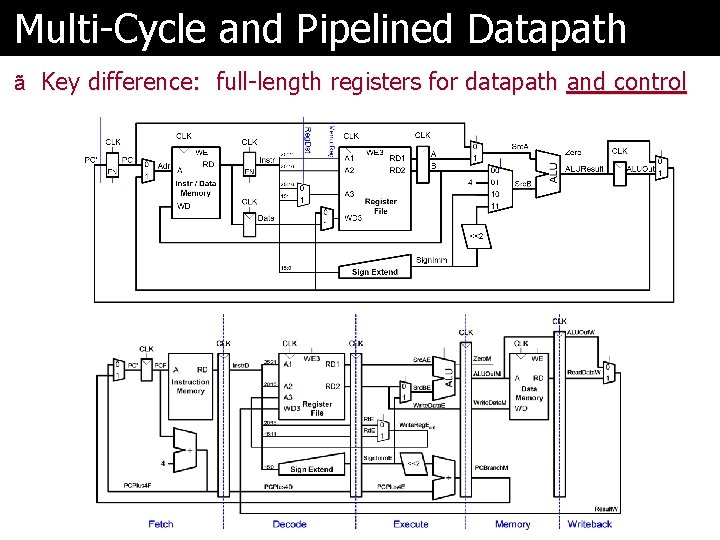
Multi-Cycle and Pipelined Datapath ã Key difference: full-length registers for datapath and control
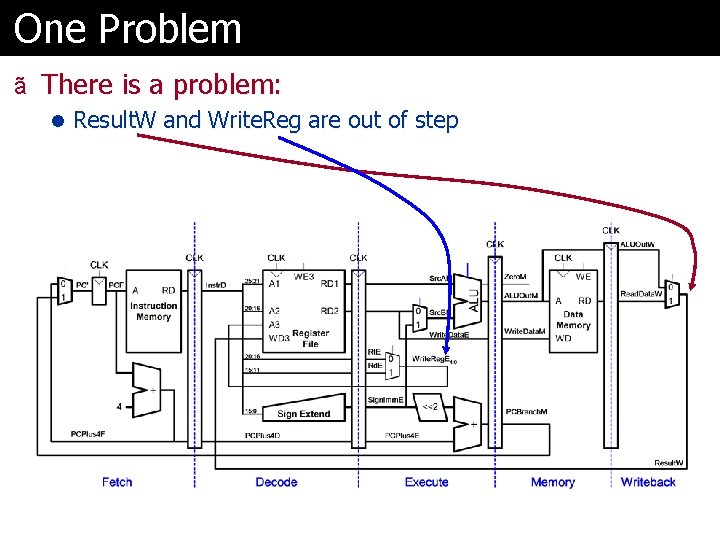
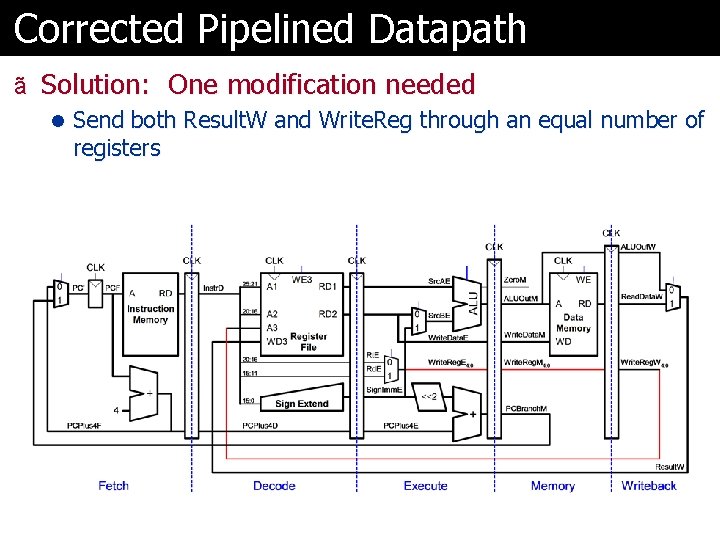
One Problem ã There is a problem: l Result. W and Write. Reg are out of step
Corrected Pipelined Datapath ã Solution: One modification needed l Send both Result. W and Write. Reg through an equal number of registers
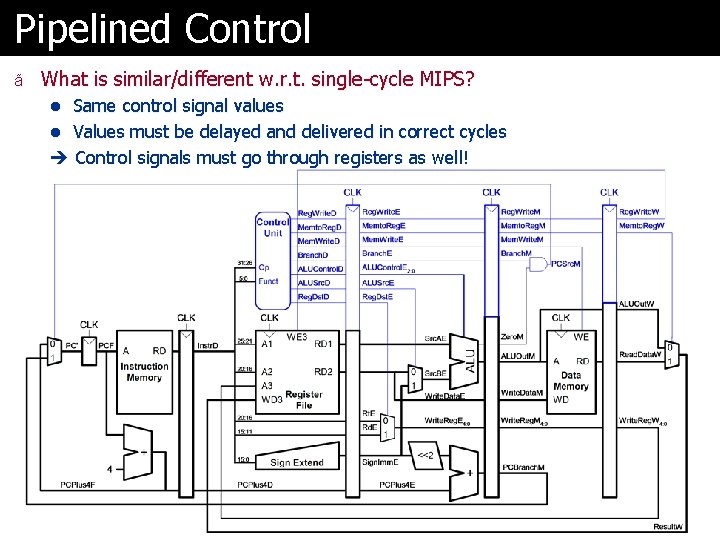
Pipelined Control ã What is similar/different w. r. t. single-cycle MIPS? l Same control signal values l Values must be delayed and delivered in correct cycles Control signals must go through registers as well!
Pipelining Challenges ã “Hazards” l when an instruction depends on results from previous instruction that has not yet completed l 2 types of hazards: Ø Data hazard: register value not written back to register file yet – an instruction produces a result needed by next instruction – new value will be stored during write-back stage – new value needed by next instr during register read following too close behind! Ø Control hazard: don’t know which is next instruction – – – next PC not decided yet cause by conditional branches cannot fetch next instr if current branch is not yet decided
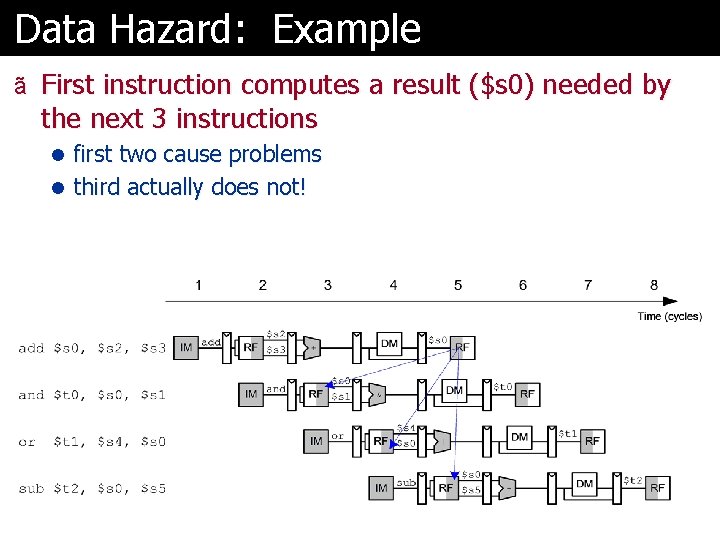
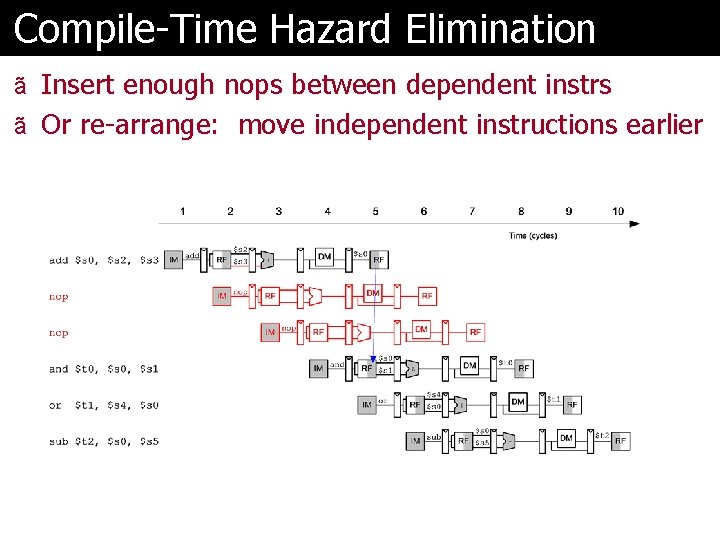
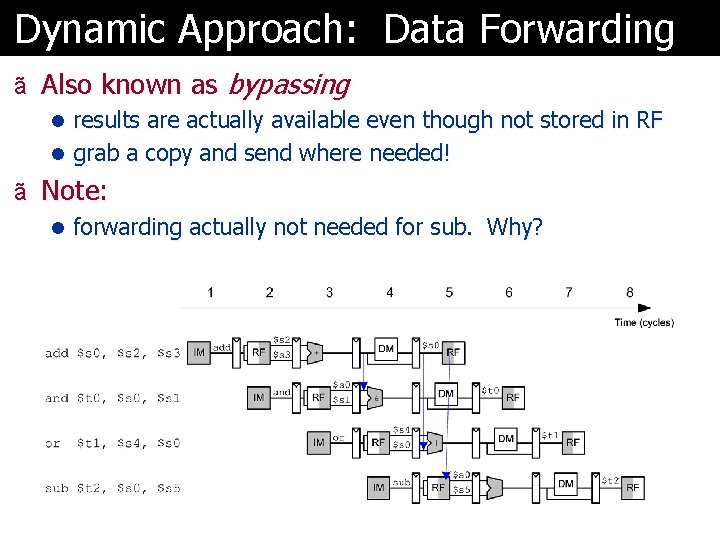
Data Hazard: Example ã First instruction computes a result ($s 0) needed by the next 3 instructions l first two cause problems l third actually does not!
Handling Data Hazards ã Static/compiler approaches: l Insert nop’s (no operations) in code at compile time l Rearrange code at compile time ã Dynamic/runtime approaches: l Forward data at run time l Stall the processor at run time
Compile-Time Hazard Elimination ã Insert enough nops between dependent instrs ã Or re-arrange: move independent instructions earlier
Dynamic Approach: Data Forwarding ã Also known as bypassing l results are actually available even though not stored in RF l grab a copy and send where needed! ã Note: l forwarding actually not needed for sub. Why?
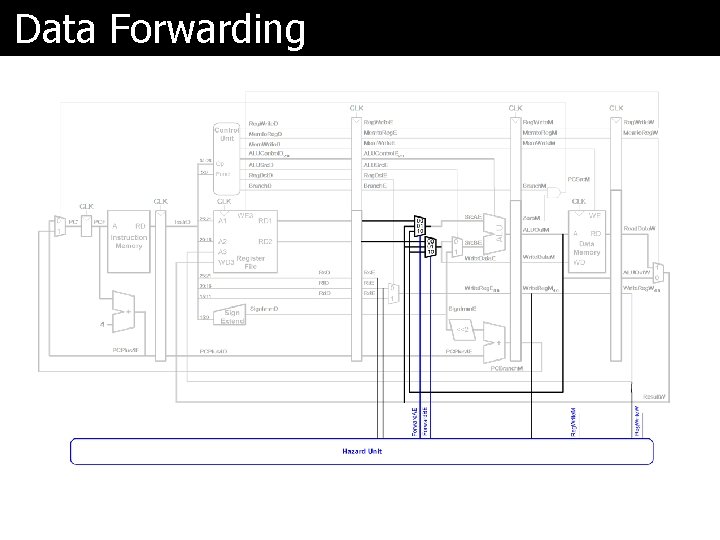
Data Forwarding
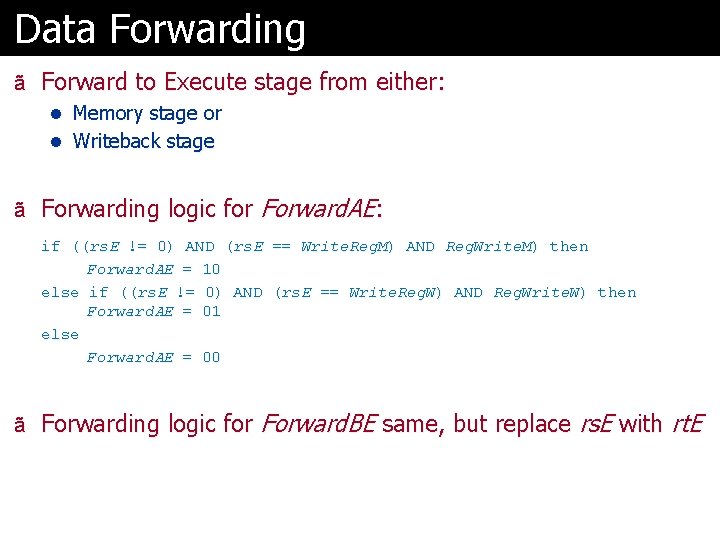
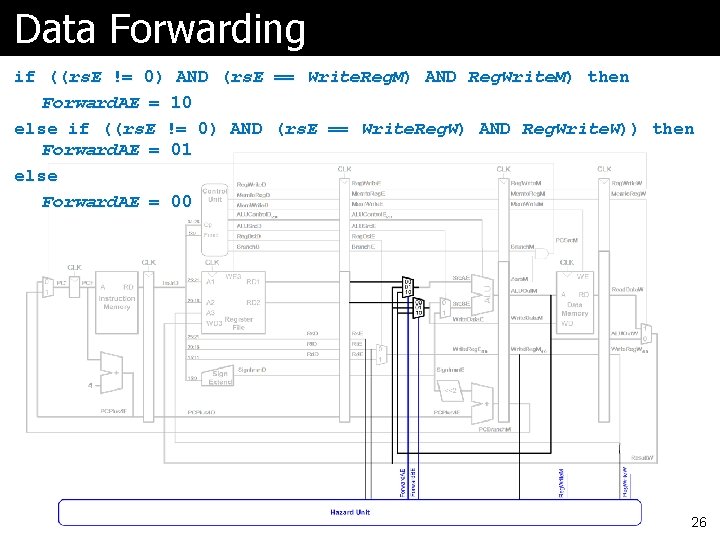
Data Forwarding ã Forward to Execute stage from either: l Memory stage or l Writeback stage ã Forwarding logic for Forward. AE: if ((rs. E != 0) AND (rs. E == Write. Reg. M) AND Reg. Write. M) then Forward. AE = 10 else if ((rs. E != 0) AND (rs. E == Write. Reg. W) AND Reg. Write. W) then Forward. AE = 01 else Forward. AE = 00 ã Forwarding logic for Forward. BE same, but replace rs. E with rt. E
Data Forwarding if ((rs. E != 0) AND (rs. E == Write. Reg. M) AND Reg. Write. M) then Forward. AE = 10 else if ((rs. E != 0) AND (rs. E == Write. Reg. W) AND Reg. Write. W)) then Forward. AE = 01 else Forward. AE = 00 26
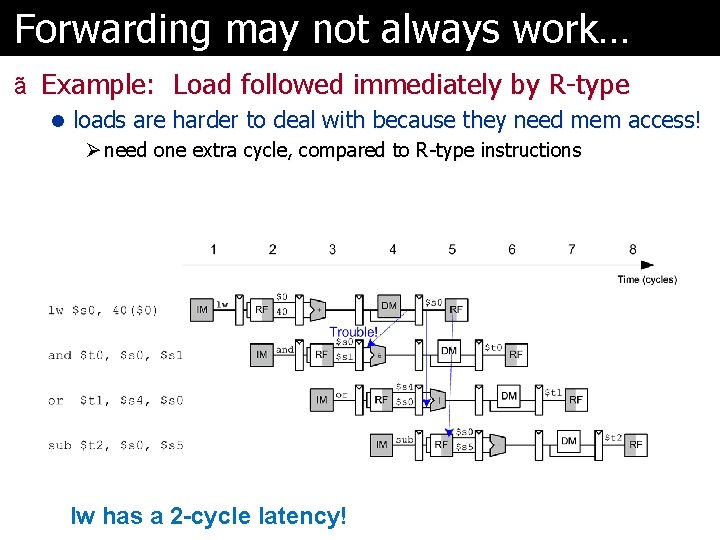
Forwarding may not always work… ã Example: Load followed immediately by R-type l loads are harder to deal with because they need mem access! Ø need one extra cycle, compared to R-type instructions lw has a 2 -cycle latency!
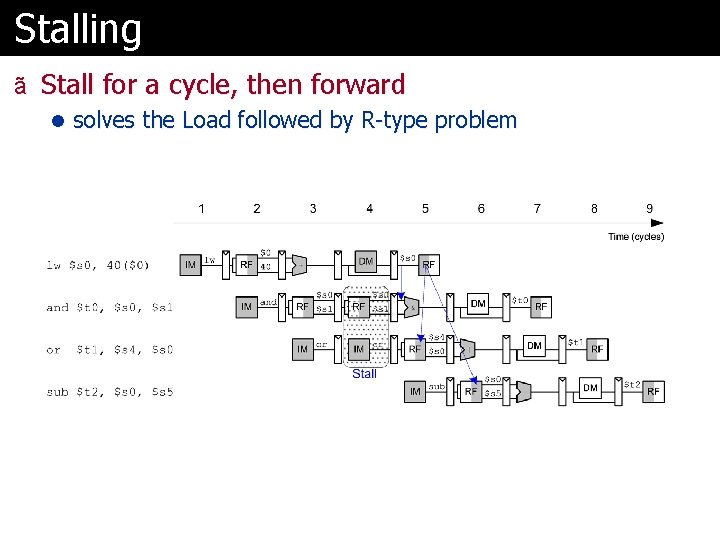
Stalling ã Stall for a cycle, then forward l solves the Load followed by R-type problem
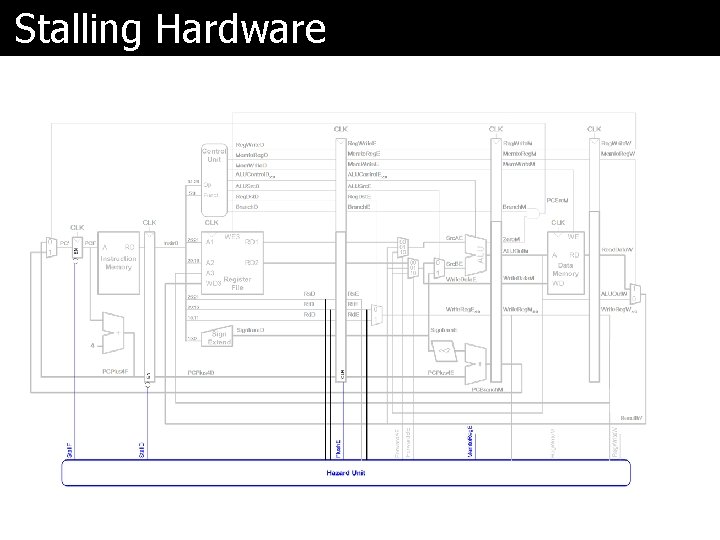
Stalling Hardware
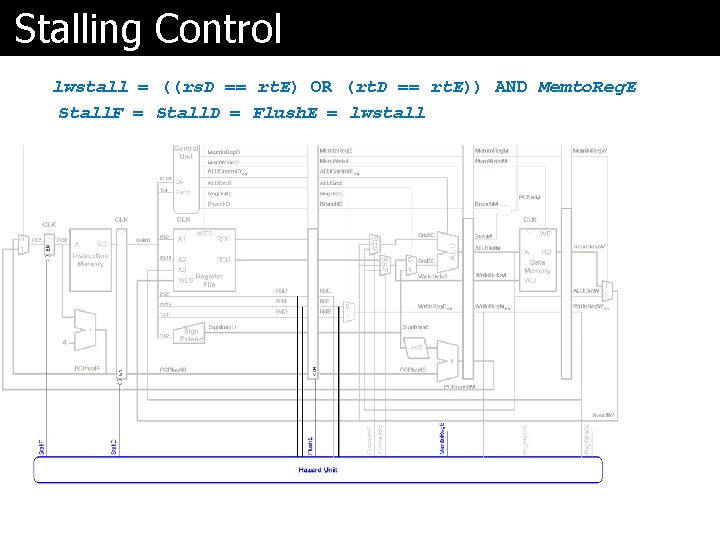
Stalling Control lwstall = ((rs. D == rt. E) OR (rt. D == rt. E)) AND Memto. Reg. E Stall. F = Stall. D = Flush. E = lwstall
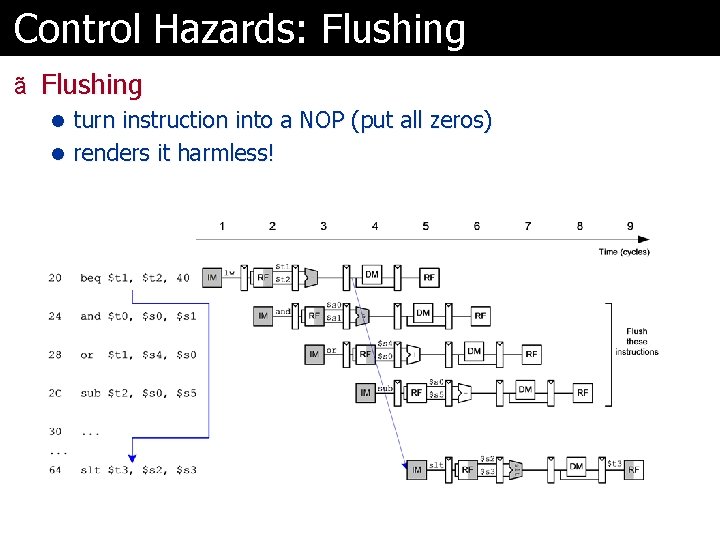
Control Hazards ã beq: l branch is not determined until the fourth stage of the pipeline l Instructions after the branch are fetched before branch occurs l These instructions must be flushed if the branch is taken
Effect & Solutions ã Could always stall when branch decoded l Expensive: 3 cycles lost per branch! ã Could predict banch outcome, and flush if wrong l Branch misprediction penalty Ø Instructions flushed when branch is taken Ø May be reduced by determining branch earlier
Control Hazards: Flushing ã Flushing l turn instruction into a NOP (put all zeros) l renders it harmless!
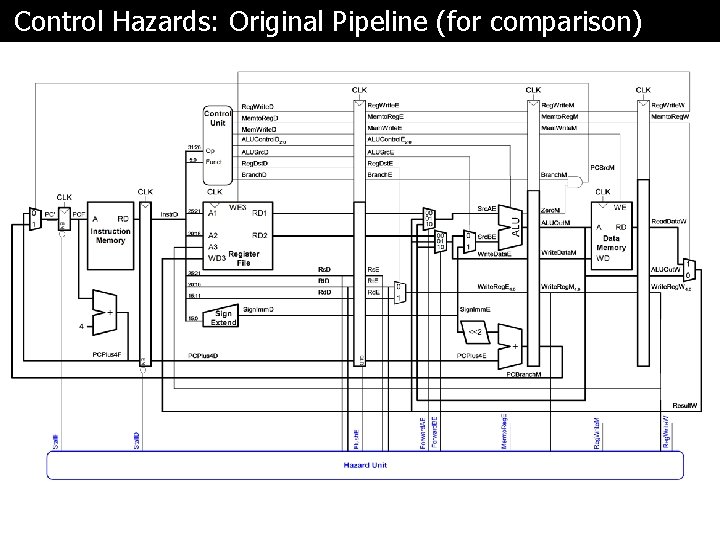
Control Hazards: Original Pipeline (for comparison)
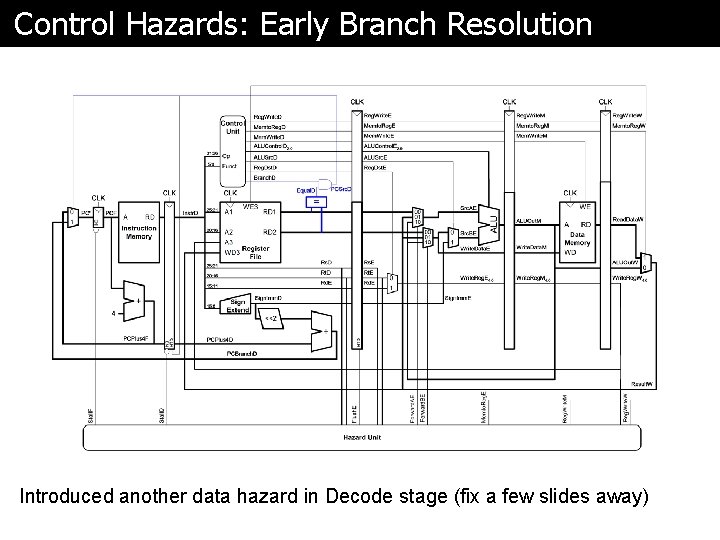
Control Hazards: Early Branch Resolution Introduced another data hazard in Decode stage (fix a few slides away)
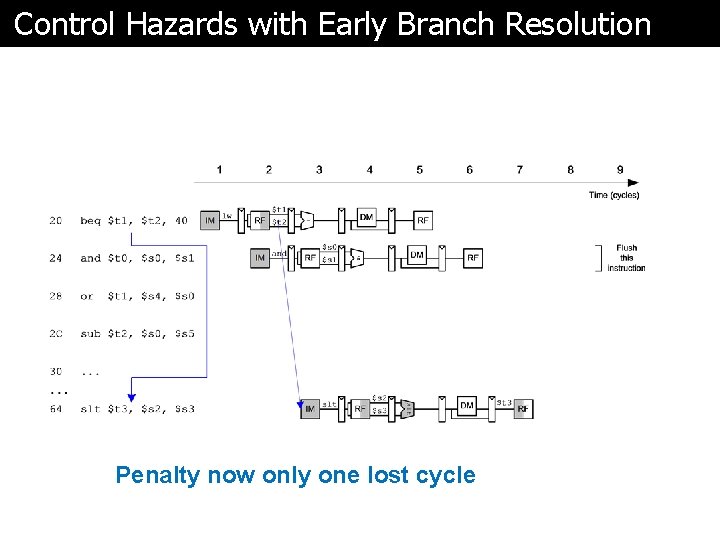
Control Hazards with Early Branch Resolution Penalty now only one lost cycle
Aside: Delayed Branch ã MIPS always executes instruction following a branch l So branch delayed ã This allows us to avoid killing inst. l Compilers move instruction that has no conflict w/ branch into delay slot 37
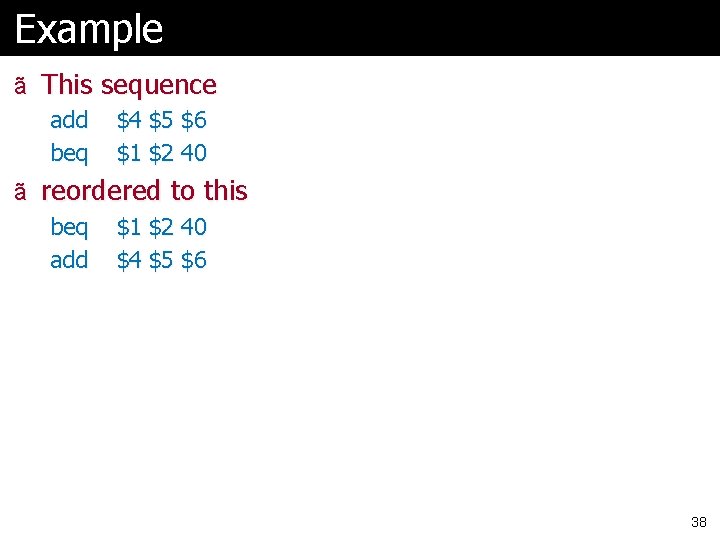
Example ã This sequence add beq $4 $5 $6 $1 $2 40 ã reordered to this beq add $1 $2 40 $4 $5 $6 38
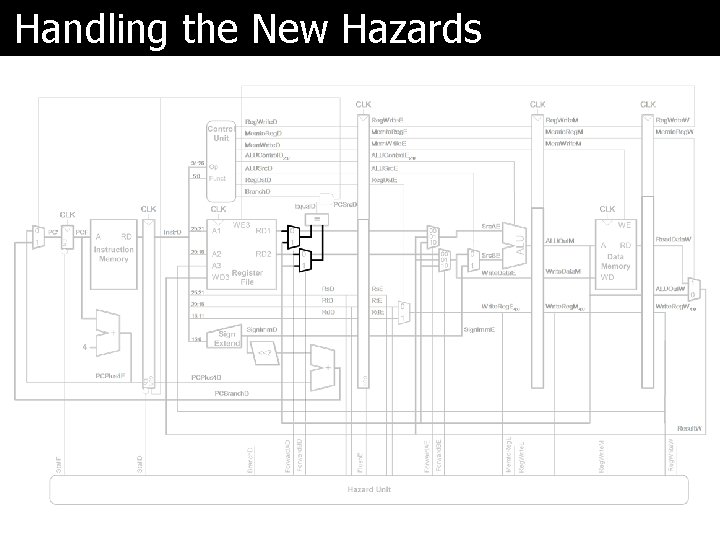
Handling the New Hazards
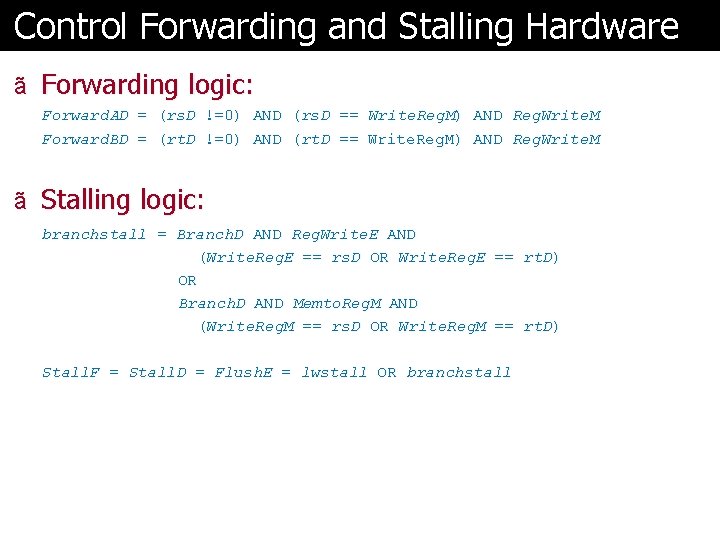
Control Forwarding and Stalling Hardware ã Forwarding logic: Forward. AD Forward. BD = = (rs. D (rt. D !=0) AND (rs. D (rt. D == == Write. Reg. M) AND Reg. Write. M ã Stalling logic: branchstall = Branch. D AND Reg. Write. E AND (Write. Reg. E == rs. D OR Write. Reg. E == rt. D) OR Branch. D AND Memto. Reg. M AND (Write. Reg. M == rs. D OR Write. Reg. M == rt. D) Stall. F = Stall. D = Flush. E = lwstall OR branchstall
Branch Prediction ã Especially important if branch penalty > 1 cycle ã Guess whether branch will be taken l Backward branches are usually taken (loops) l Perhaps consider history of whether branch was previously taken to improve the guess ã Good prediction reduces the fraction of branches requiring a flush
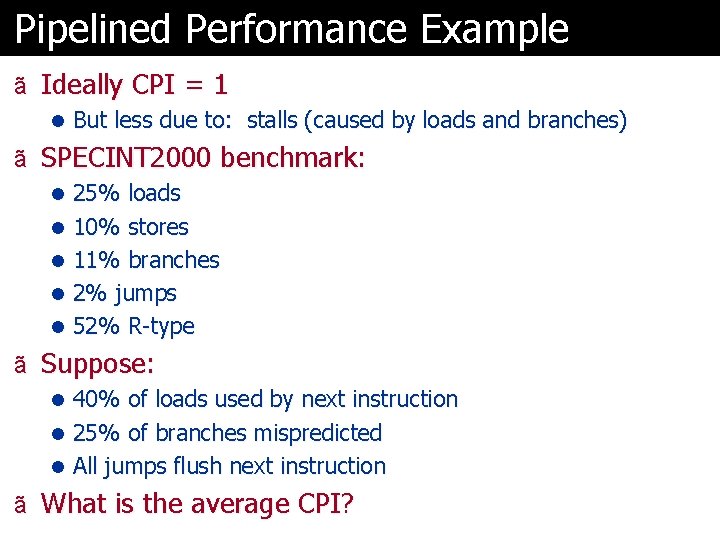
Pipelined Performance Example ã Ideally CPI = 1 l But less due to: stalls (caused by loads and branches) ã SPECINT 2000 benchmark: l 25% loads l 10% stores l 11% branches l 2% jumps l 52% R-type ã Suppose: l 40% of loads used by next instruction l 25% of branches mispredicted l All jumps flush next instruction ã What is the average CPI?
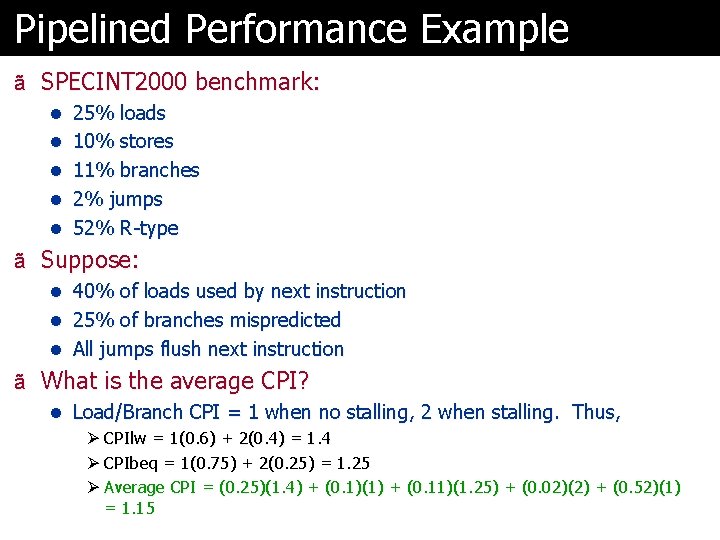
Pipelined Performance Example ã SPECINT 2000 benchmark: l 25% loads l 10% stores l 11% branches l 2% jumps l 52% R-type ã Suppose: l 40% of loads used by next instruction l 25% of branches mispredicted l All jumps flush next instruction ã What is the average CPI? l Load/Branch CPI = 1 when no stalling, 2 when stalling. Thus, Ø CPIlw = 1(0. 6) + 2(0. 4) = 1. 4 Ø CPIbeq = 1(0. 75) + 2(0. 25) = 1. 25 Ø Average CPI = (0. 25)(1. 4) + (0. 1)(1) + (0. 11)(1. 25) + (0. 02)(2) + (0. 52)(1) = 1. 15
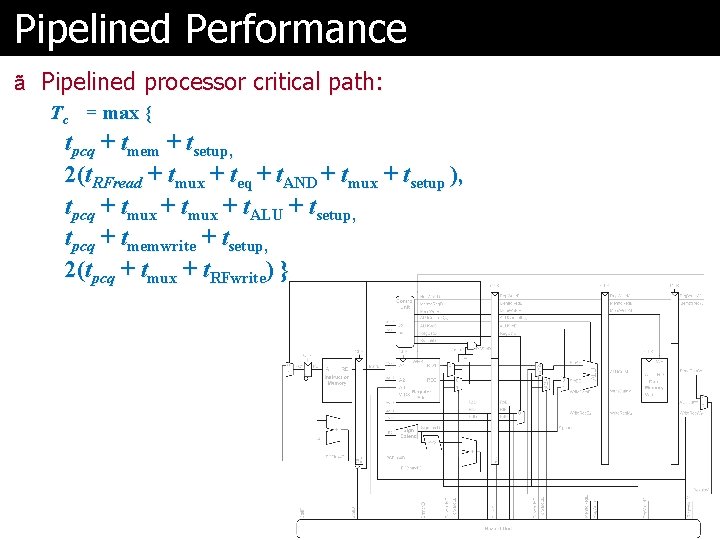
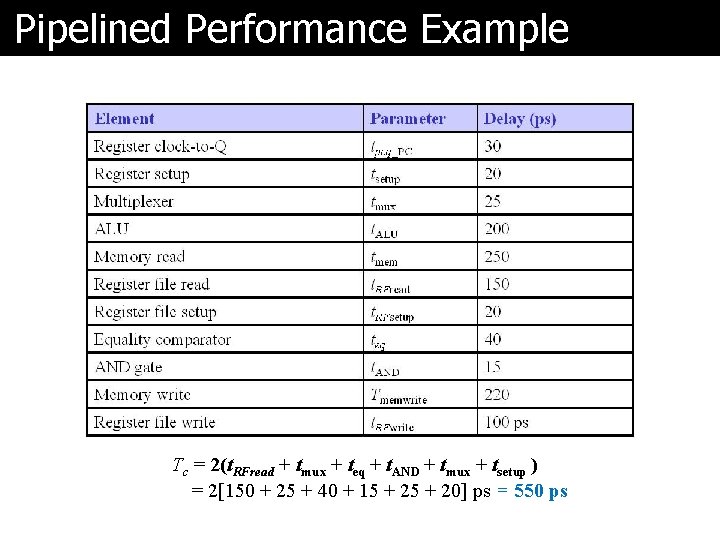
Pipelined Performance ã Pipelined processor critical path: Tc = max { tpcq + tmem + tsetup, 2(t. RFread + tmux + teq + t. AND + tmux + tsetup ), tpcq + tmux + t. ALU + tsetup, tpcq + tmemwrite + tsetup, 2(tpcq + tmux + t. RFwrite) }
Pipelined Performance Example Tc = 2(t. RFread + tmux + teq + t. AND + tmux + tsetup ) = 2[150 + 25 + 40 + 15 + 20] ps = 550 ps
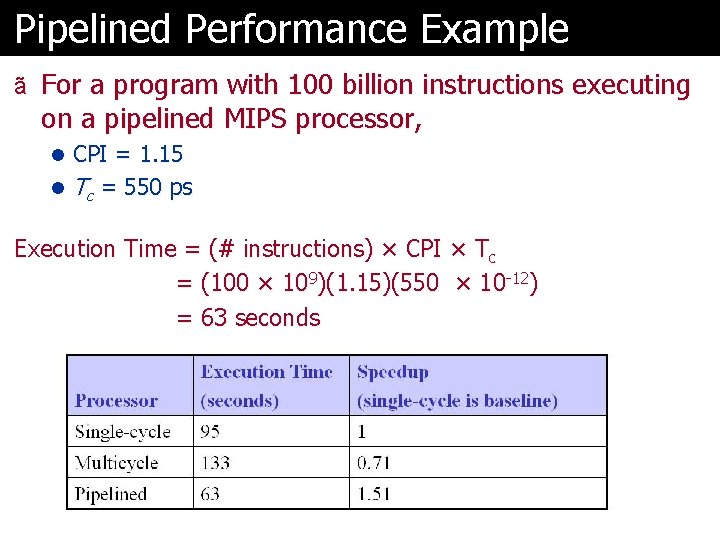
Pipelined Performance Example ã For a program with 100 billion instructions executing on a pipelined MIPS processor, l CPI = 1. 15 l Tc = 550 ps Execution Time = (# instructions) × CPI × Tc = (100 × 109)(1. 15)(550 × 10 -12) = 63 seconds
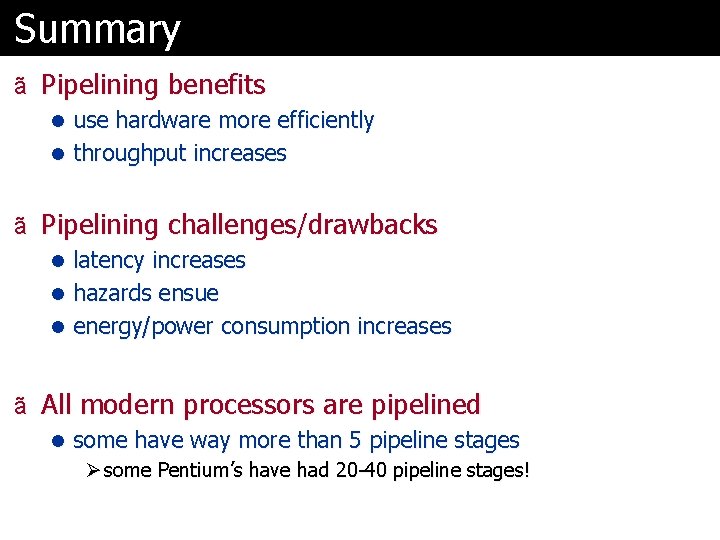
Summary ã Pipelining benefits l use hardware more efficiently l throughput increases ã Pipelining challenges/drawbacks l latency increases l hazards ensue l energy/power consumption increases ã All modern processors are pipelined l some have way more than 5 pipeline stages Ø some Pentium’s have had 20 -40 pipeline stages!