
Chapter 4 The Processor n CPU performance factors
- Slides: 134
Chapter 4 The Processor
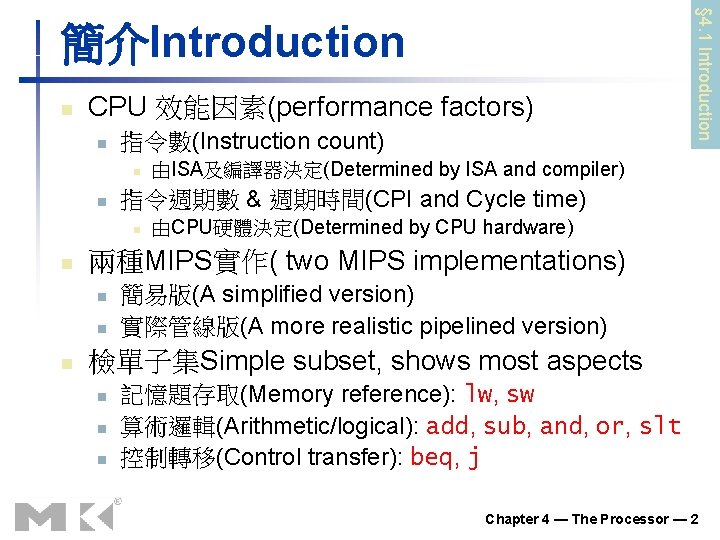
n CPU 效能因素(performance factors) n 指令數(Instruction count) n n 由CPU硬體決定(Determined by CPU hardware) 兩種MIPS實作( two MIPS implementations) n n n 由ISA及編譯器決定(Determined by ISA and compiler) 指令週期數 & 週期時間(CPI and Cycle time) n n § 4. 1 Introduction 簡介Introduction 簡易版(A simplified version) 實際管線版(A more realistic pipelined version) 檢單子集Simple subset, shows most aspects n n n 記憶題存取(Memory reference): lw, sw 算術邏輯(Arithmetic/logical): add, sub, and, or, slt 控制轉移(Control transfer): beq, j Chapter 4 — The Processor — 2
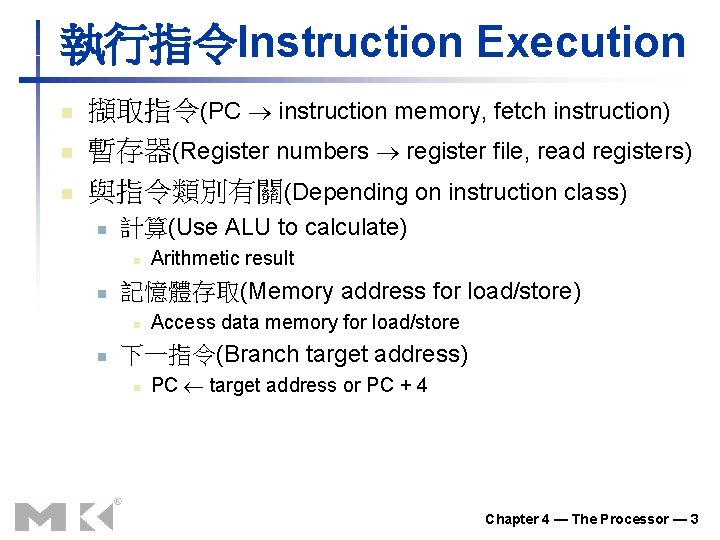
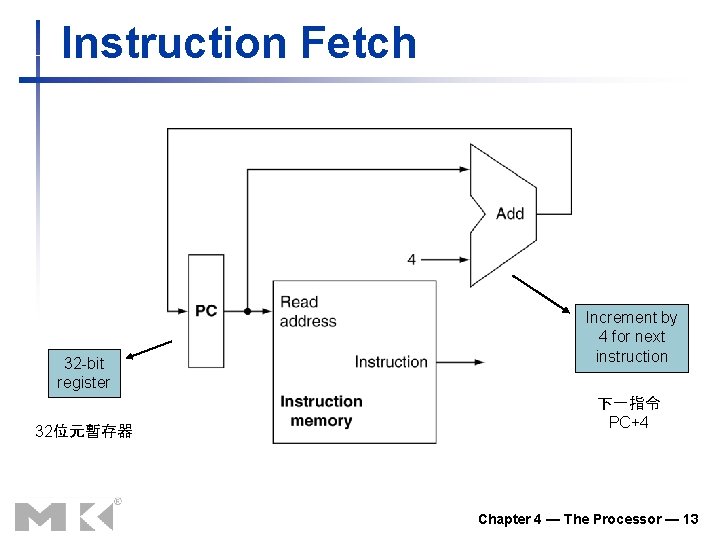
執行指令Instruction Execution n 擷取指令(PC instruction memory, fetch instruction) 暫存器(Register numbers register file, read registers) 與指令類別有關(Depending on instruction class) n 計算(Use ALU to calculate) n n 記憶體存取(Memory address for load/store) n n Arithmetic result Access data memory for load/store 下一指令(Branch target address) n PC target address or PC + 4 Chapter 4 — The Processor — 3
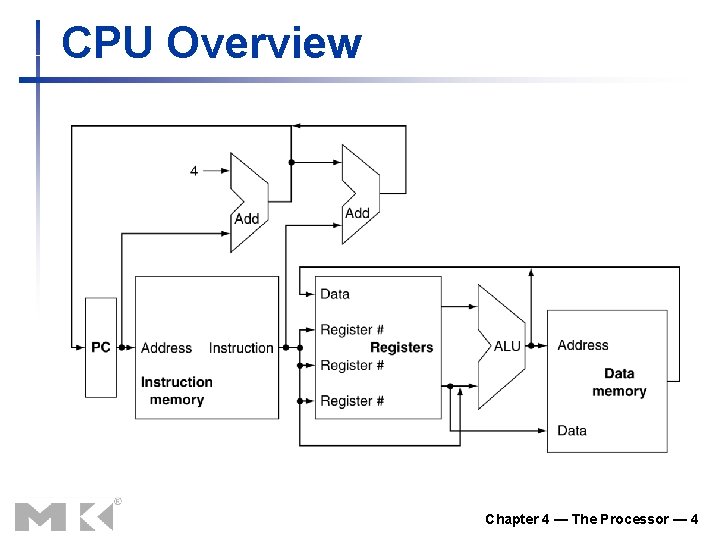
CPU Overview Chapter 4 — The Processor — 4
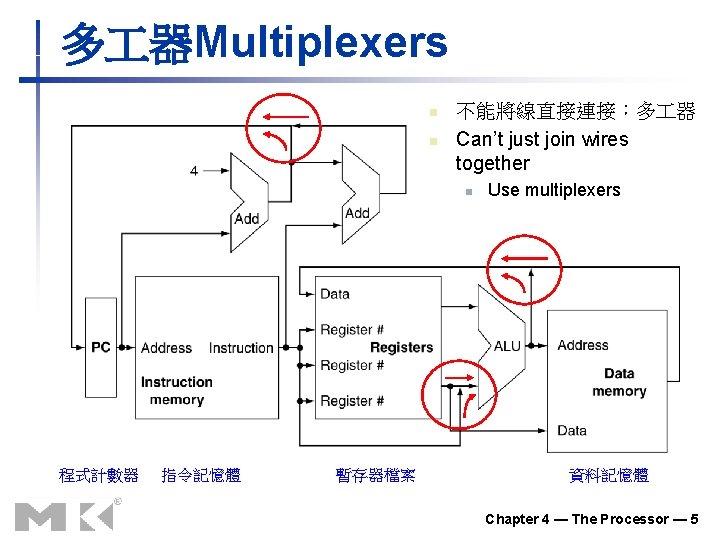
多 器Multiplexers n n 不能將線直接連接:多 器 Can’t just join wires together n 程式計數器 指令記憶體 暫存器檔案 Use multiplexers 資料記憶體 Chapter 4 — The Processor — 5
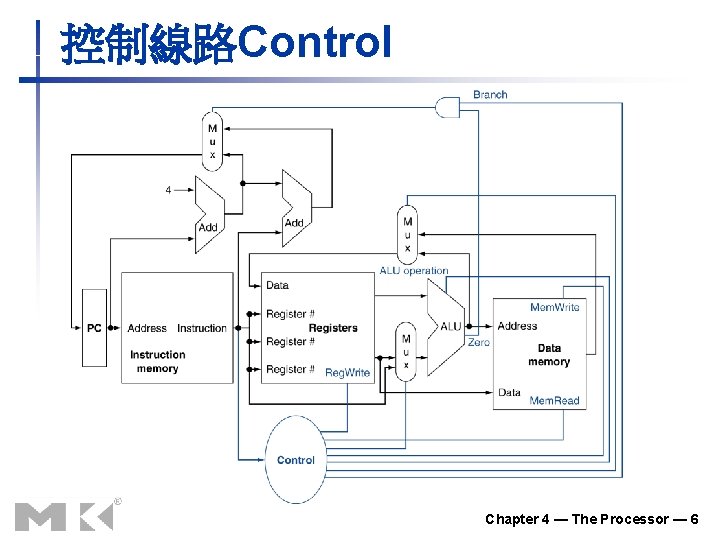
控制線路Control Chapter 4 — The Processor — 6
n 二元資訊Information encoded in binary n n 組合邏輯Combinational element n n n Low voltage = 0, High voltage = 1 One wire per bit Multi-bit data encoded on multi-wire buses § 4. 2 Logic Design Conventions 邏輯設計Logic Design Basics 資料運算Operate on data 輸出入函數關係Output is a function of input 序向邏輯State (sequential) elements n Store information Chapter 4 — The Processor — 7
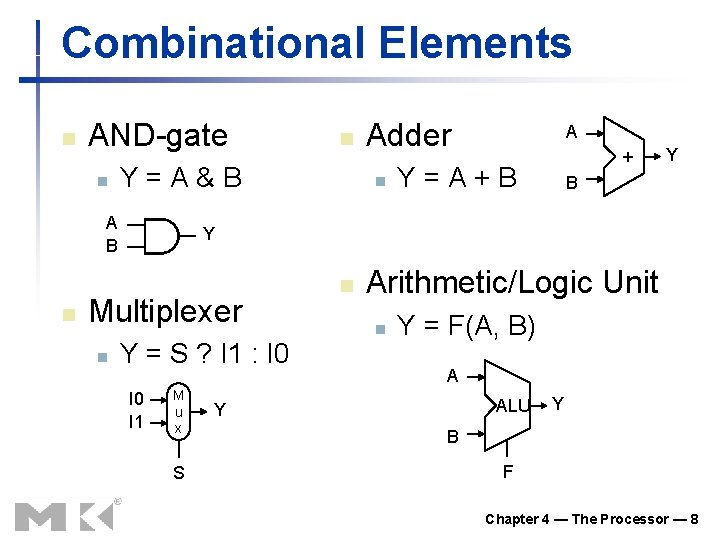
Combinational Elements n AND-gate n Y=A&B A B n Adder n A + Y=A+B Y Multiplexer n n Y = S ? I 1 : I 0 I 1 M u x S n Arithmetic/Logic Unit n Y = F(A, B) A ALU Y Y B F Chapter 4 — The Processor — 8
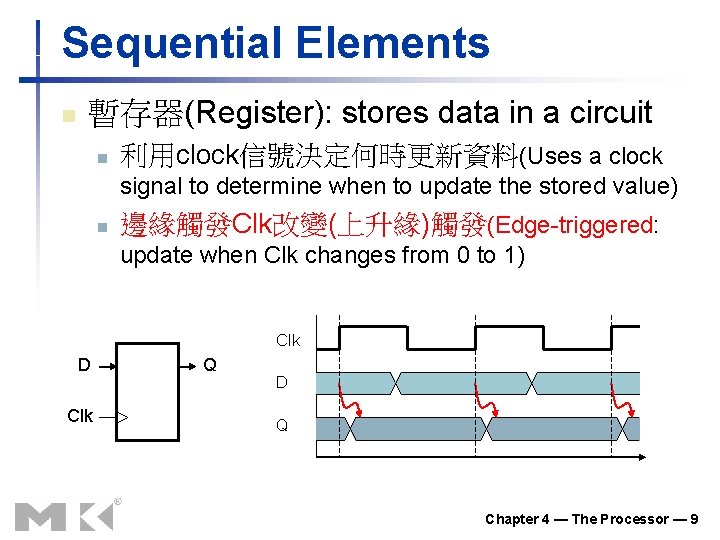
Sequential Elements n 暫存器(Register): stores data in a circuit n 利用clock信號決定何時更新資料(Uses a clock signal to determine when to update the stored value) n 邊緣觸發Clk改變(上升緣)觸發(Edge-triggered: update when Clk changes from 0 to 1) Clk D Clk Q D Q Chapter 4 — The Processor — 9
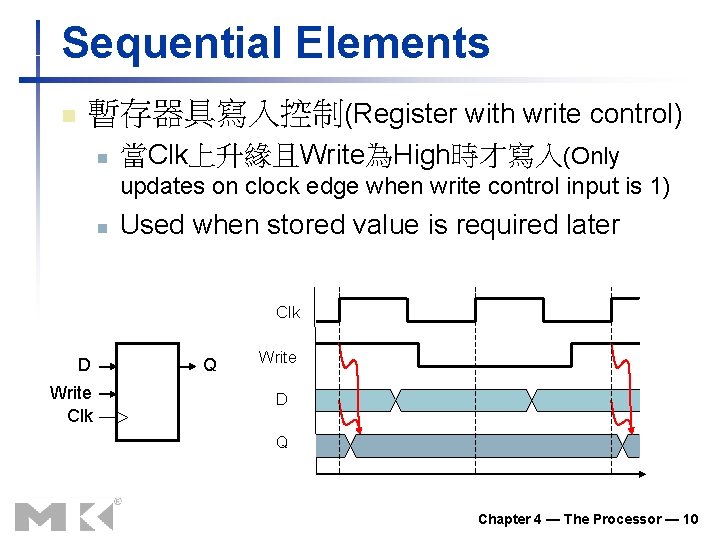
Sequential Elements n 暫存器具寫入控制(Register with write control) n 當Clk上升緣且Write為High時才寫入(Only updates on clock edge when write control input is 1) n Used when stored value is required later Clk D Write Clk Q Write D Q Chapter 4 — The Processor — 10
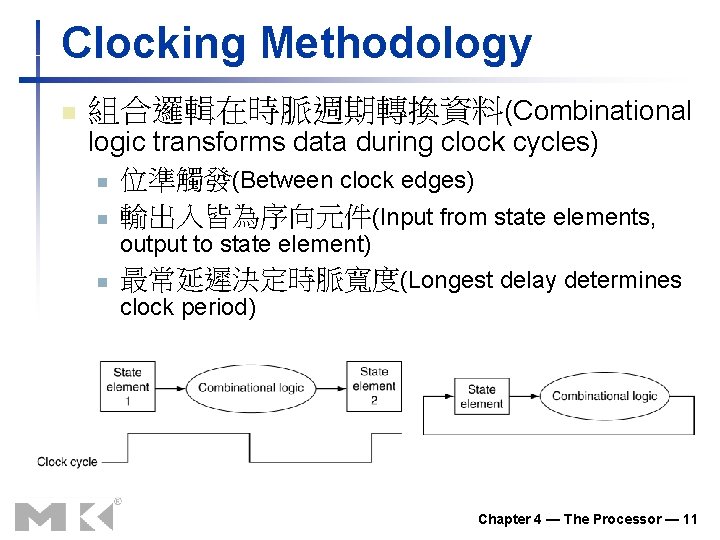
Clocking Methodology n 組合邏輯在時脈週期轉換資料(Combinational logic transforms data during clock cycles) n 位準觸發(Between clock edges) n 輸出入皆為序向元件(Input from state elements, output to state element) n 最常延遲決定時脈寬度(Longest delay determines clock period) Chapter 4 — The Processor — 11
n 資料路徑(Datapath) n CPU中處理資料及位址之元件(Elements that process data and addresses in the CPU) n n § 4. 3 Building a Datapath 建立資料路徑Building a Datapath 暫存器、ALU、多 器(Registers, ALUs, mux’s, memories, …) 建構MIPS資料路徑(Build a MIPS datapath incrementally) n Refining the overview design Chapter 4 — The Processor — 12
Instruction Fetch 32 -bit register 32位元暫存器 Increment by 4 for next instruction 下一指令 PC+4 Chapter 4 — The Processor — 13
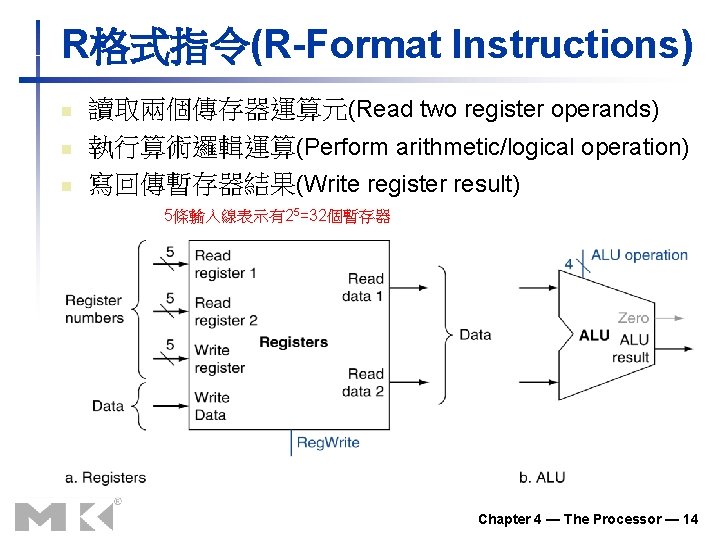
R格式指令(R-Format Instructions) n n n 讀取兩個傳存器運算元(Read two register operands) 執行算術邏輯運算(Perform arithmetic/logical operation) 寫回傳暫存器結果(Write register result) 5條輸入線表示有25=32個暫存器 Chapter 4 — The Processor — 14
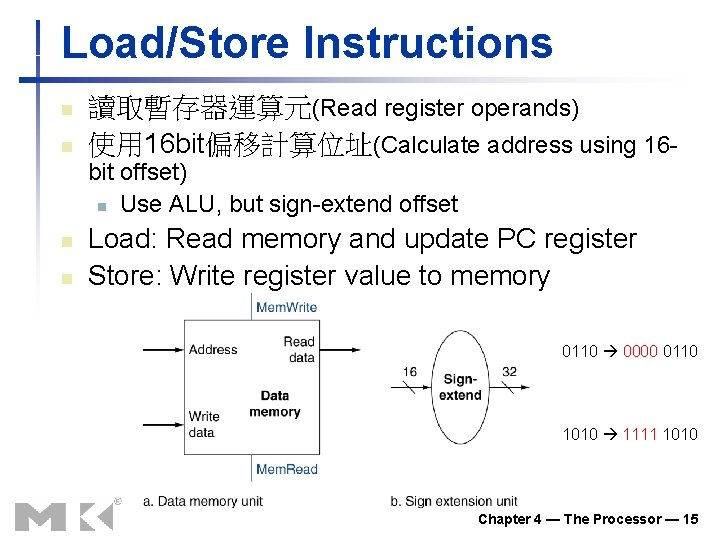
Load/Store Instructions n n 讀取暫存器運算元(Read register operands) 使用 16 bit偏移計算位址(Calculate address using 16 bit offset) n Use ALU, but sign-extend offset n n Load: Read memory and update PC register Store: Write register value to memory 0110 0000 0110 1010 1111 1010 Chapter 4 — The Processor — 15
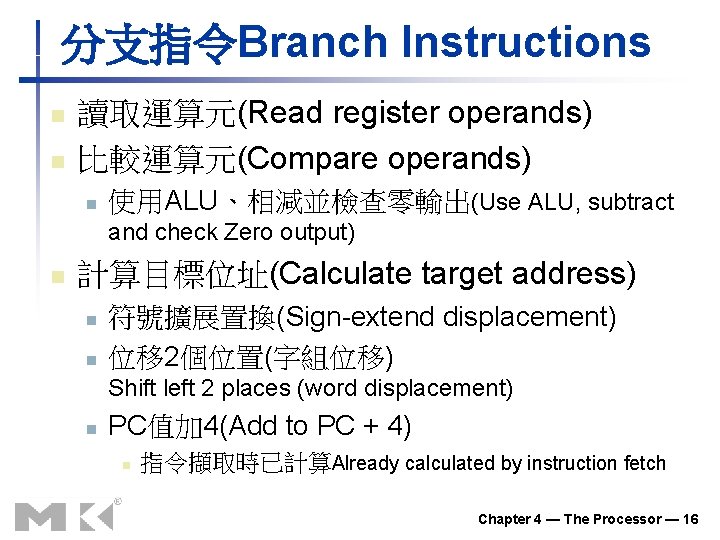
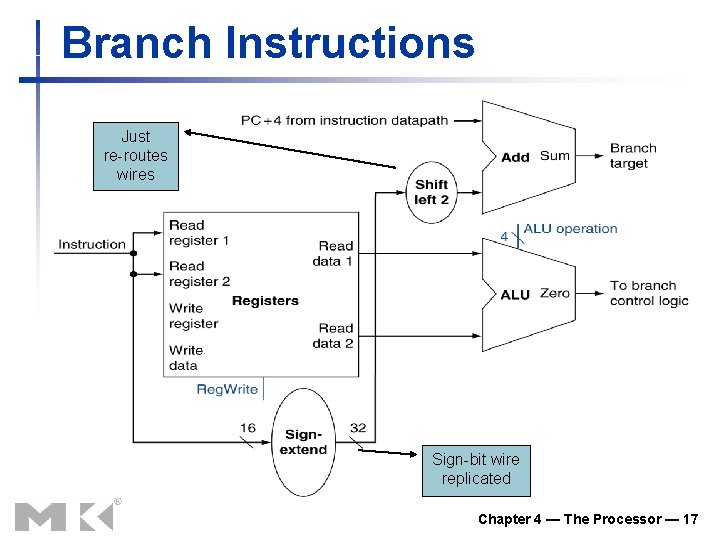
分支指令Branch Instructions n n 讀取運算元(Read register operands) 比較運算元(Compare operands) n 使用ALU、相減並檢查零輸出(Use ALU, subtract and check Zero output) n 計算目標位址(Calculate target address) n n 符號擴展置換(Sign-extend displacement) 位移 2個位置(字組位移) Shift left 2 places (word displacement) n PC值加 4(Add to PC + 4) n 指令擷取時已計算Already calculated by instruction fetch Chapter 4 — The Processor — 16
Branch Instructions Just re-routes wires Sign-bit wire replicated Chapter 4 — The Processor — 17
Composing the Elements n 將指令的資料路徑切在一個時脈週期內 (First-cut data path does an instruction in one clock cycle) n 任一資歷路徑元件只能值一次行一個功能 (Each datapath element can only do one function at a time) n n 將指令與資料記憶體分開 (separate instruction and data memories) 使用多 器選擇不同指令的資料來源 (Use multiplexers where alternate data sources are used for different instructions) Chapter 4 — The Processor — 18
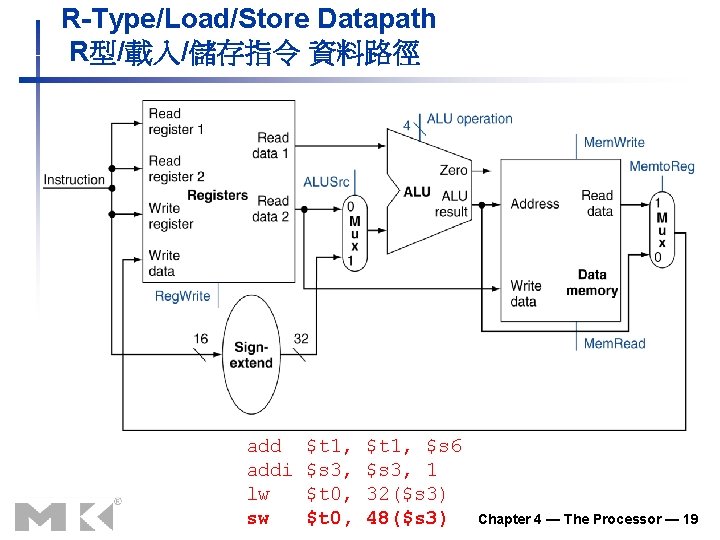
R-Type/Load/Store Datapath R型/載入/儲存指令 資料路徑 addi lw sw $t 1, $s 3, $t 0, $t 1, $s 6 $s 3, 1 32($s 3) 48($s 3) Chapter 4 — The Processor — 19
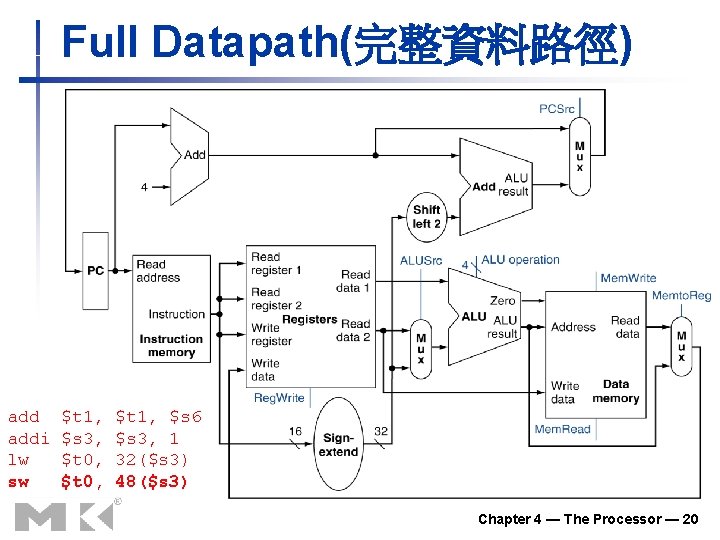
Full Datapath(完整資料路徑) addi lw sw $t 1, $s 3, $t 0, $t 1, $s 6 $s 3, 1 32($s 3) 48($s 3) Chapter 4 — The Processor — 20
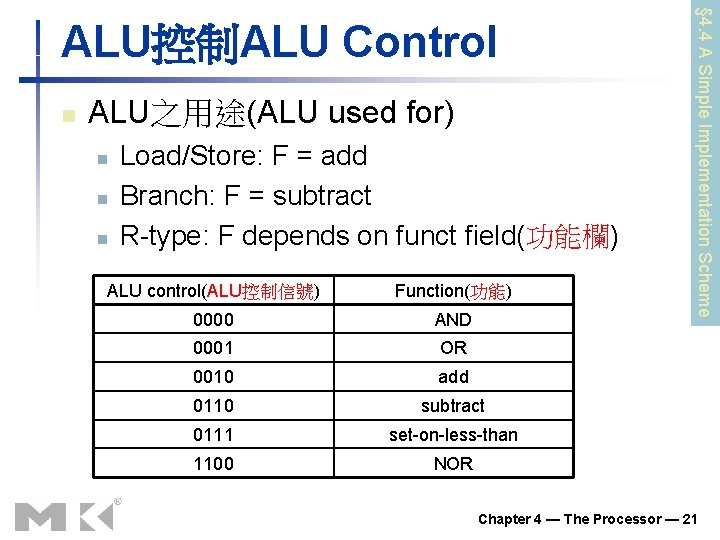
n ALU之用途(ALU used for) n n n Load/Store: F = add Branch: F = subtract R-type: F depends on funct field(功能欄) ALU control(ALU控制信號) Function(功能) 0000 AND 0001 OR 0010 add 0110 subtract 0111 set-on-less-than 1100 NOR § 4. 4 A Simple Implementation Scheme ALU控制ALU Control Chapter 4 — The Processor — 21
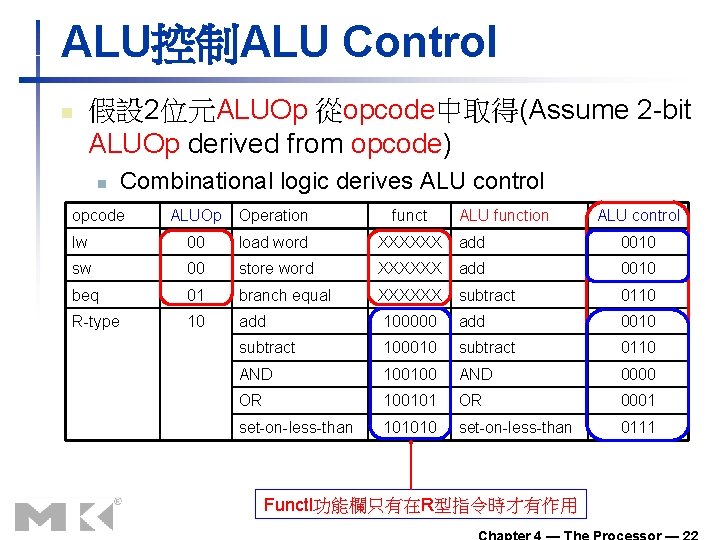
ALU控制ALU Control n 假設 2位元ALUOp 從opcode中取得(Assume 2 -bit ALUOp derived from opcode) n Combinational logic derives ALU control opcode ALUOp Operation funct ALU function lw 00 load word XXXXXX add 0010 sw 00 store word XXXXXX add 0010 beq 01 branch equal XXXXXX subtract 0110 R-type 10 add 100000 add 0010 subtract 100010 subtract 0110 AND 100100 AND 0000 OR 100101 OR 0001 set-on-less-than 101010 set-on-less-than 0111 Functl功能欄只有在R型指令時才有作用 ALU control
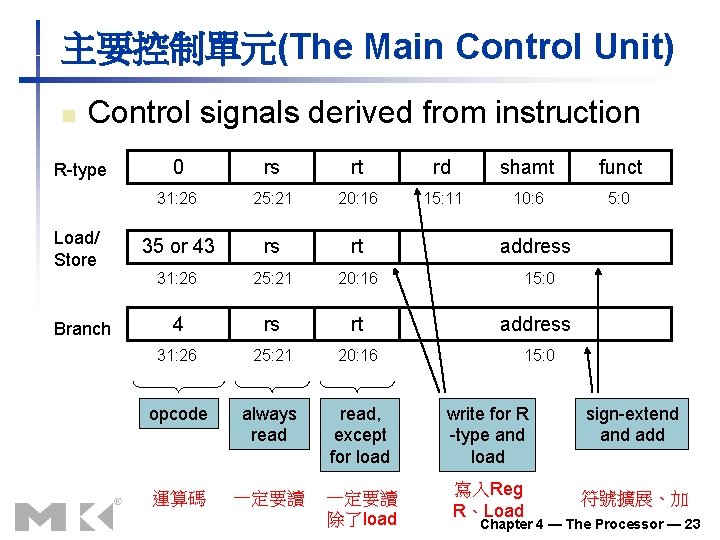
主要控制單元(The Main Control Unit) n Control signals derived from instruction R-type Load/ Store Branch 0 rs rt rd shamt funct 31: 26 25: 21 20: 16 15: 11 10: 6 5: 0 35 or 43 rs rt address 31: 26 25: 21 20: 16 15: 0 4 rs rt address 31: 26 25: 21 20: 16 15: 0 opcode always read, except for load write for R -type and load sign-extend add 運算碼 一定要讀 除了load 寫入Reg R、Load 符號擴展、加 Chapter 4 — The Processor — 23
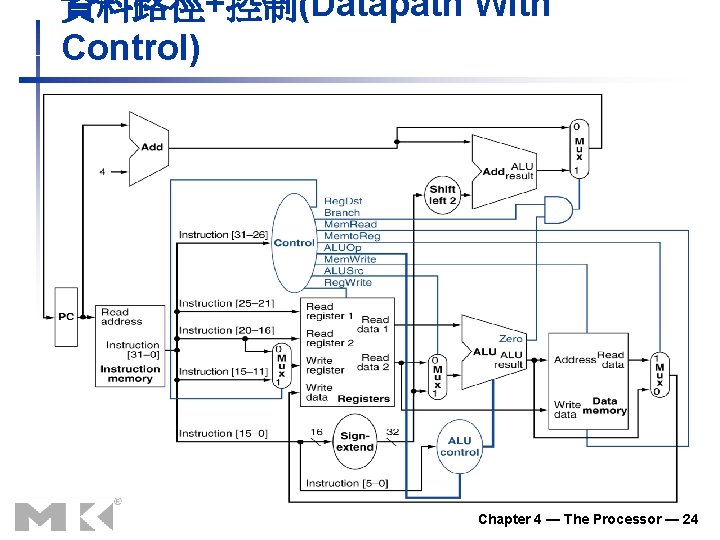
資料路徑+控制(Datapath With Control) Chapter 4 — The Processor — 24
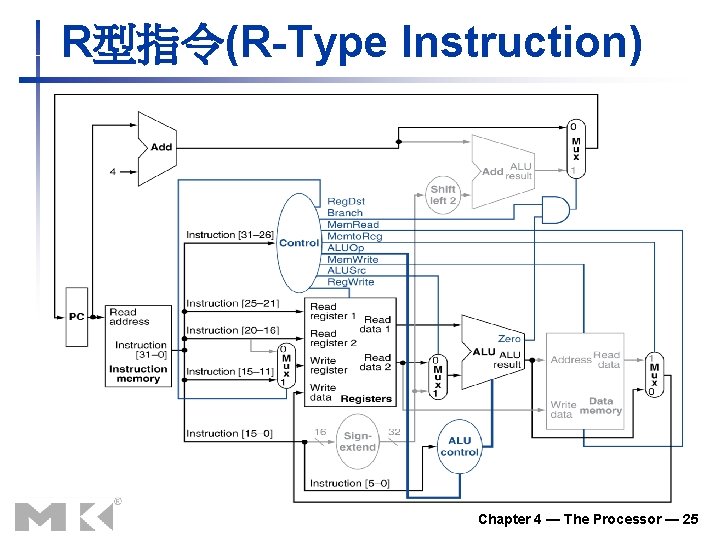
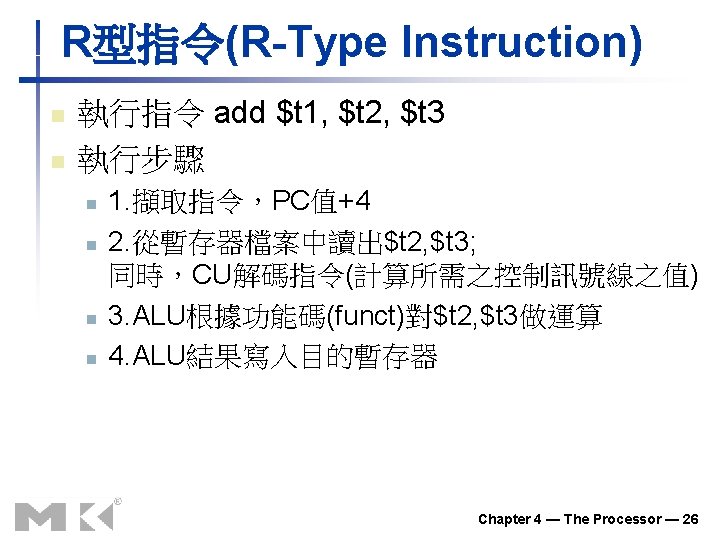
R型指令(R-Type Instruction) Chapter 4 — The Processor — 25
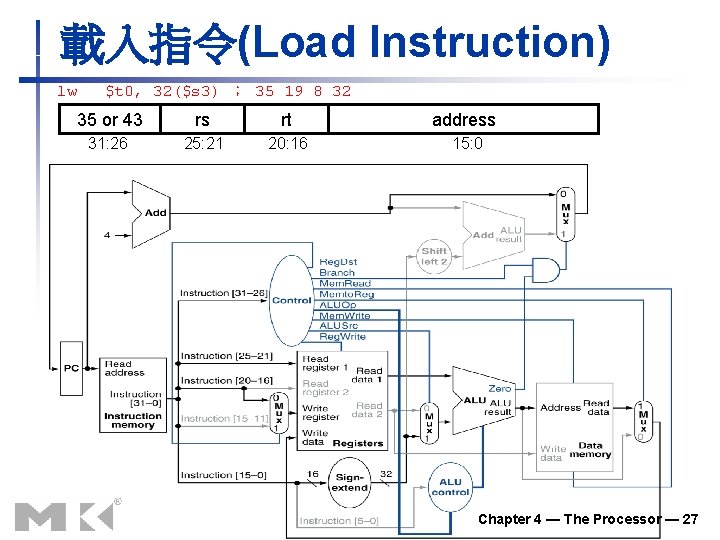
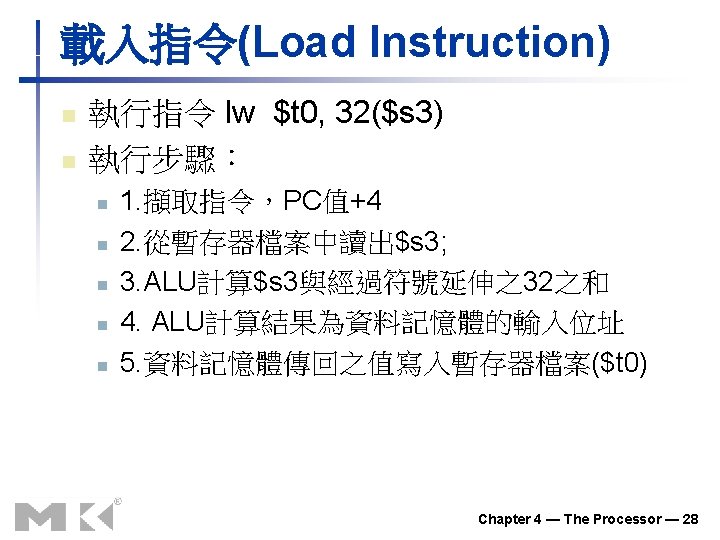
載入指令(Load Instruction) lw $t 0, 32($s 3) ; 35 19 8 32 35 or 43 rs rt address 31: 26 25: 21 20: 16 15: 0 Chapter 4 — The Processor — 27
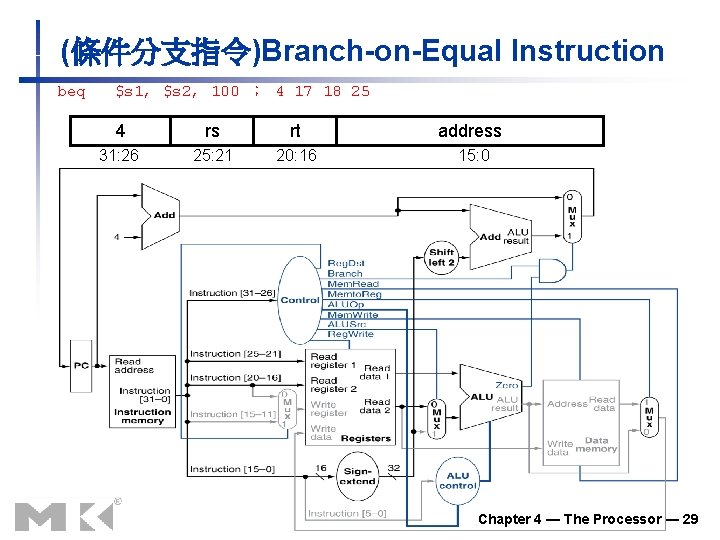
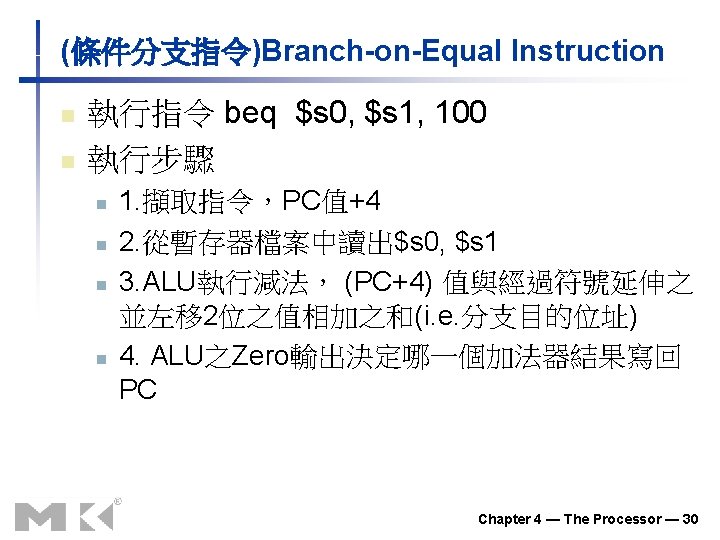
(條件分支指令)Branch-on-Equal Instruction beq $s 1, $s 2, 100 ; 4 17 18 25 4 rs rt address 31: 26 25: 21 20: 16 15: 0 Chapter 4 — The Processor — 29
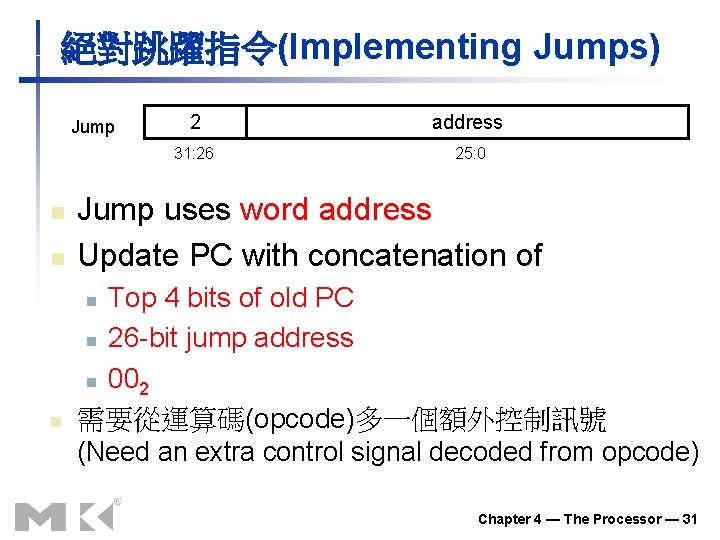
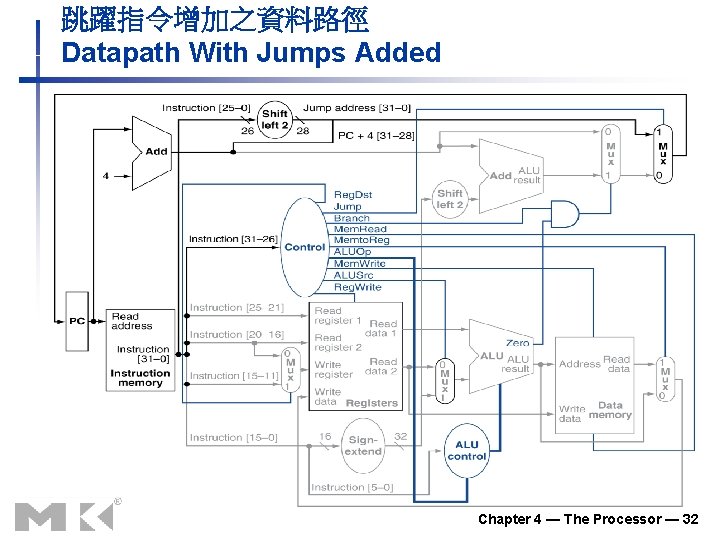
絕對跳躍指令(Implementing Jumps) Jump n n 2 address 31: 26 25: 0 Jump uses word address Update PC with concatenation of Top 4 bits of old PC n 26 -bit jump address n 002 需要從運算碼(opcode)多一個額外控制訊號 (Need an extra control signal decoded from opcode) n n Chapter 4 — The Processor — 31
跳躍指令增加之資料路徑 Datapath With Jumps Added Chapter 4 — The Processor — 32
效能議題Performance Issues n Longest delay determines clock period n n 關鍵路徑:Load指令(Critical path: load instruction) 指令記憶體 暫存器檔案 ALU 資料記憶體 傳存器檔案 (Instruction memory register file ALU data memory register file) n 對不同指令沒有彈性可以改變週期 (Not feasible to vary period for different instructions) n 違反設計原則Violates design principle n n 讓一般情況加快(Making the common case fast) 利用管線處理來增進效能 (We will improve performance by pipelining) Chapter 4 — The Processor — 33
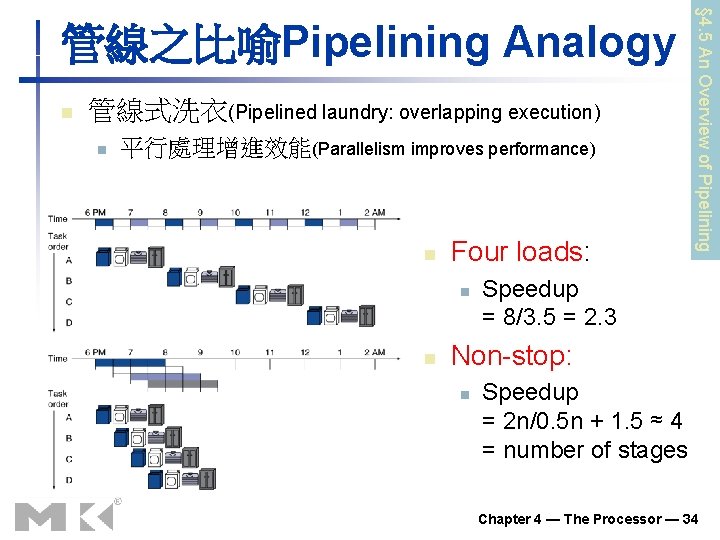
n 管線式洗衣(Pipelined laundry: overlapping execution) n 平行處理增進效能(Parallelism improves performance) n Four loads: n n § 4. 5 An Overview of Pipelining 管線之比喻Pipelining Analogy Speedup = 8/3. 5 = 2. 3 Non-stop: n Speedup = 2 n/0. 5 n + 1. 5 ≈ 4 = number of stages Chapter 4 — The Processor — 34
MIPS管線處理(MIPS Pipeline) 管線處理(pipelining)之定義 n n n 將指令區分成數個步驟,分別由不同的功能單元同時加以執行, 以增進整體程式之效能 管線處理五個步驟(Five stages, one step per stage) 1. IF: Instruction Fetch(擷取指令) 從記憶體擷取指令(Instruction fetch from memory) 2. ID: Instruction Decode(指令解碼) 解碼指令並讀取暫存器(Instruction decode & register read) 3. EX: Execution(執行指令) 執行運算或計算位址(Execute operation or calculate address) 4. MEM: Memory Access(記憶體存取) 存取記憶體運算元(Access memory operand) 5. WB: Write Back(寫回) 將結果寫回至暫存器(Write result back to register) Chapter 4 — The Processor — 35
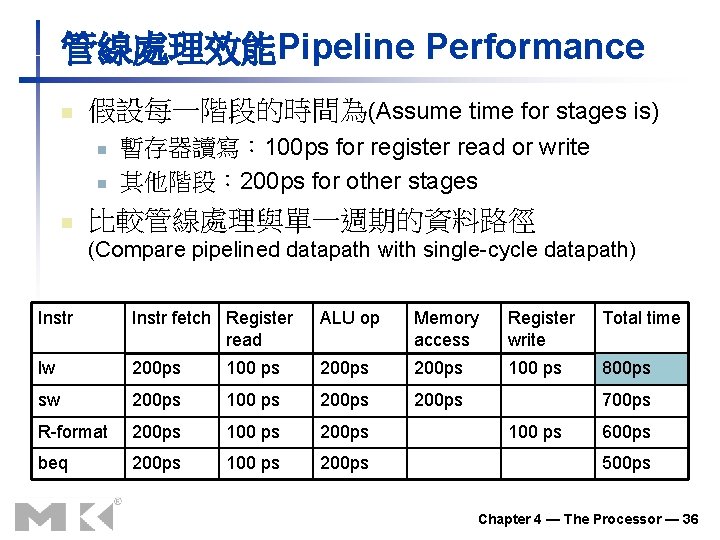
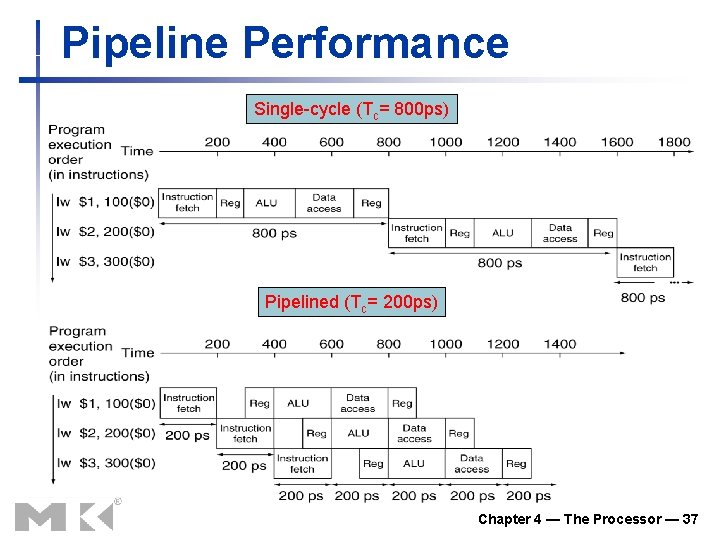
管線處理效能Pipeline Performance n 假設每一階段的時間為(Assume time for stages is) n n n 暫存器讀寫: 100 ps for register read or write 其他階段: 200 ps for other stages 比較管線處理與單一週期的資料路徑 (Compare pipelined datapath with single-cycle datapath) Instr fetch Register read ALU op Memory access Register write Total time lw 200 ps 100 ps 800 ps sw 200 ps 100 ps 200 ps R-format 200 ps 100 ps 200 ps beq 200 ps 100 ps 200 ps 700 ps 100 ps 600 ps 500 ps Chapter 4 — The Processor — 36
Pipeline Performance Single-cycle (Tc= 800 ps) Pipelined (Tc= 200 ps) Chapter 4 — The Processor — 37
管線處理加速Pipeline Speedup n 所有階段都一致If all stages are balanced n 每一階段時間都相同(i. e. , all take the same time) n Time between instructionspipelined = Time between instructionsnonpipelined Number of stages n 若階段不一致,加速值較少If not balanced, speedup is less n 管線處理的「加速』源自增加處理量(產量) Speedup due to increased throughput n 延遲時間(latency每一指令的時間)沒有減少 Latency (time for each instruction) does not decrease Chapter 4 — The Processor — 38
Pipelining and ISA Design n MIPS ISA專為管線化處理所設計 (MIPS ISA designed for pipelining) n 所有指令皆為 32位元(All instructions are 32 -bits) n 較容易在一個週期內擷取並解碼 (Easier to fetch and decode in one cycle) n n c. f. x 86: 1 - to 17 -byte instructions 少量且規則的指令格式(Few and regular instruction formats) n 能在一個步驟內解碼並讀取暫存器 (Can decode and read registers in one step) n 載入與儲存定址(Load/store addressing) n n 能在第 3階段計算位址,在第 4階段存犬記憶體 (Can calculate address in 3 rd stage, access memory in 4 th stage) 記憶體運算元對齊(Alignment of memory operands) n 記憶體存取只需一個週期 (Memory access takes only one cycle) Chapter 4 — The Processor — 39
危障Hazards n 下一週期的起始位址不是下一指令 Situations that prevent starting the next instruction in the next cycle n 危障種類Hazard types n 結構危障(Structure hazards) n n 所需資源忙碌中(A required resource is busy) 資料危障(Data hazard) n 等待前一指令完成資料讀寫 Need to wait for previous instruction to complete its data read/write n 控制危障(Control hazard) n 依前一指令結果決定控制動作 Deciding on control action depends on previous instruction Chapter 4 — The Processor — 40
結構危障Structure Hazards n n 使用資源衝突Conflict for use of a resource MIPS中只有一個記憶體In MIPS pipeline with a single memory n Load/store 需要做資料存取Load/store requires data access n 該週期的指令擷取必須延遲(stall),需管線泡泡 Instruction fetch would have to stall for that cycle Would cause a pipeline “bubble” n 管線式資料路徑需要獨立的指令/資料記憶體 n n 或獨立的指令/資料快取(記憶體) Hence, pipelined datapaths require separate instruction/data memories Or separate instruction/data caches Chapter 4 — The Processor — 41
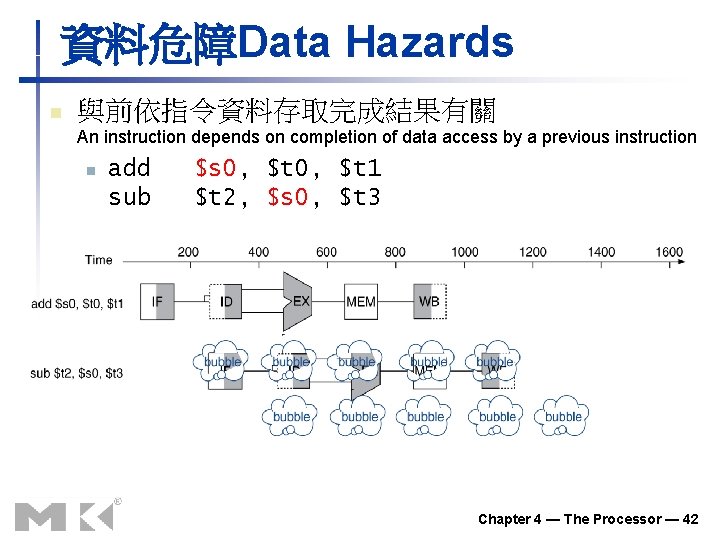
資料危障Data Hazards n 與前依指令資料存取完成結果有關 An instruction depends on completion of data access by a previous instruction n add sub $s 0, $t 1 $t 2, $s 0, $t 3 Chapter 4 — The Processor — 42
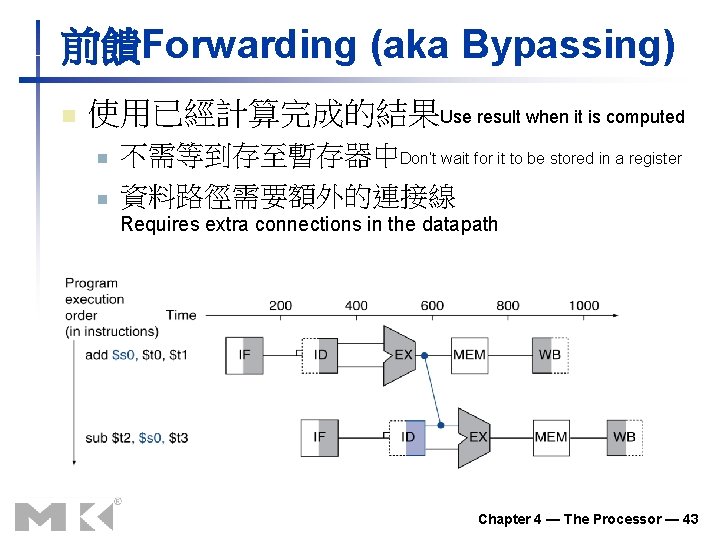
前饋Forwarding (aka Bypassing) n 使用已經計算完成的結果Use result when it is computed n n 不需等到存至暫存器中Don’t wait for it to be stored in a register 資料路徑需要額外的連接線 Requires extra connections in the datapath Chapter 4 — The Processor — 43
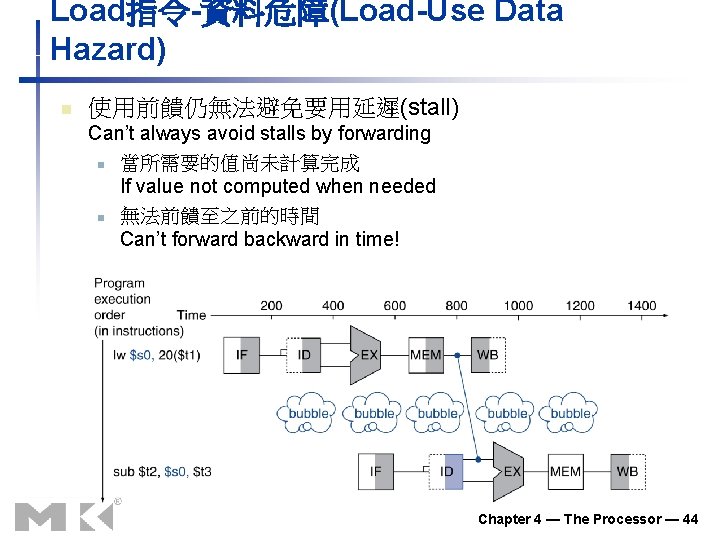
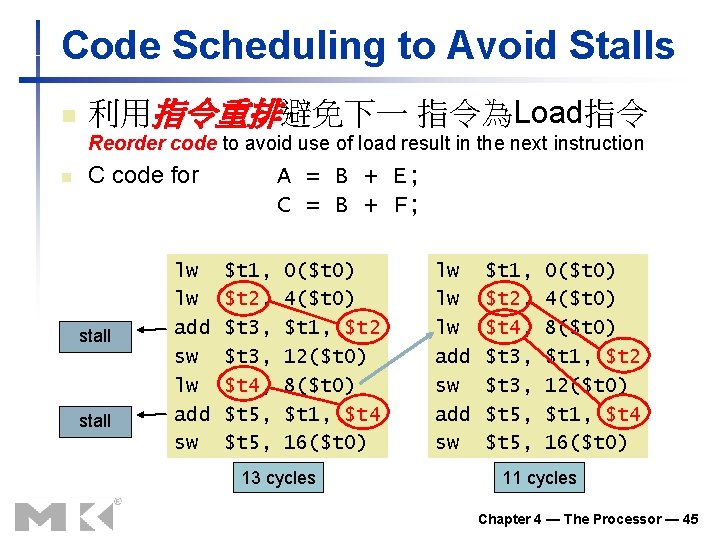
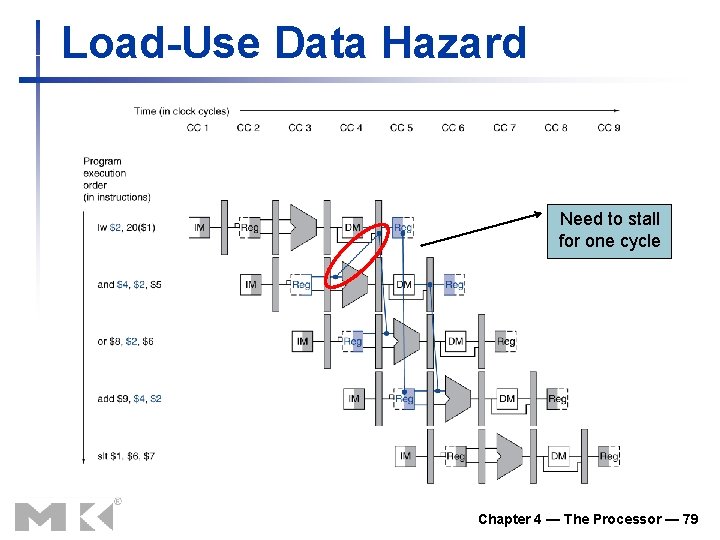
Load指令-資料危障(Load-Use Data Hazard) n 使用前饋仍無法避免要用延遲(stall) Can’t always avoid stalls by forwarding n 當所需要的值尚未計算完成 If value not computed when needed n 無法前饋至之前的時間 Can’t forward backward in time! Chapter 4 — The Processor — 44
Code Scheduling to Avoid Stalls n 利用指令重排避免下一 指令為Load指令 Reorder code to avoid use of load result in the next instruction n C code for stall lw lw add sw A = B + E; C = B + F; $t 1, $t 2, $t 3, $t 4, $t 5, 0($t 0) 4($t 0) $t 1, $t 2 12($t 0) 8($t 0) $t 1, $t 4 16($t 0) 13 cycles lw lw lw add sw $t 1, $t 2, $t 4, $t 3, $t 5, 0($t 0) 4($t 0) 8($t 0) $t 1, $t 2 12($t 0) $t 1, $t 4 16($t 0) 11 cycles Chapter 4 — The Processor — 45
控制危障Control Hazards n 分支決定控制流程Branch determines flow of control n 擷取下一指令取決於分支結果 Fetching next instruction depends on branch outcome n 管線處理不能永遠擷取正確的下一個指令 Pipeline can’t always fetch correct instruction n 仍在分支指令的ID階段 Still working on ID stage of branch n MIPS的管線處理中In MIPS pipeline n 需要在管線中比較暫存器與提早計算目標位址 Need to compare registers and compute target early in the pipeline n 在ID階段增加硬體來處理 Add hardware to do it in ID stage Chapter 4 — The Processor — 46
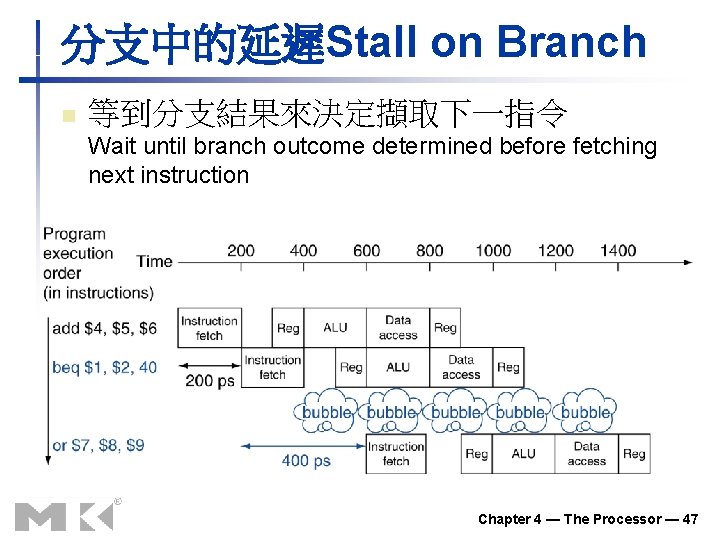
分支中的延遲Stall on Branch n 等到分支結果來決定擷取下一指令 Wait until branch outcome determined before fetching next instruction Chapter 4 — The Processor — 47
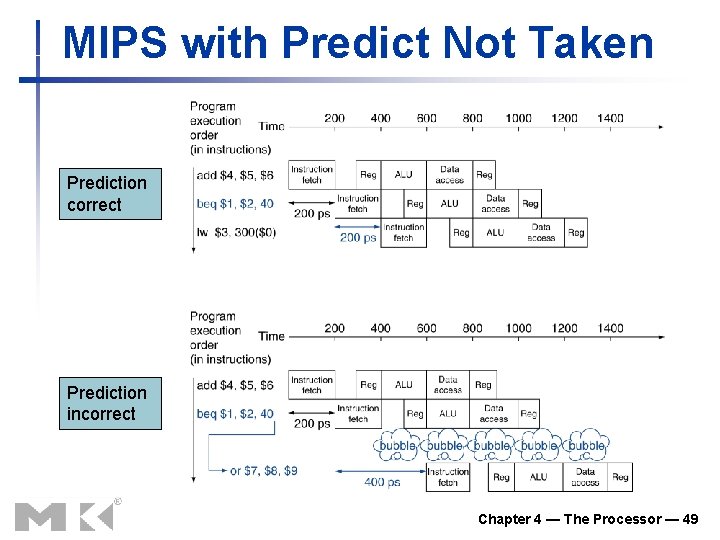
分支預測Branch Prediction n 較長的管線無法完全提早決定分之結果 Longer pipelines can’t readily determine branch outcome early n 延遲時間變得無法接受 Stall penalty becomes unacceptable n 分支預測結果Predict outcome of branch n n 預測錯誤只有造成延遲Only stall if prediction is wrong MIPS管線處理中In MIPS pipeline n n 可以預測分支未發生Can predict branches not taken 分支後的擷取指令沒有延遲 Fetch instruction after branch, with no delay Chapter 4 — The Processor — 48
MIPS with Predict Not Taken Prediction correct Prediction incorrect Chapter 4 — The Processor — 49
More-Realistic Branch Prediction n 靜態分支預測Static branch prediction n n 基於典型分支行為Based on typical branch behavior 範例:迴圈與if指令Example: loop and if-statement branches n n n 預測反向分支會發生Predict backward branches taken 預測前向分支不會發生Predict forward branches not taken 動態分支預測Dynamic branch prediction n 硬體測量實際分支行為Hardware measures actual branch behavior n 例如:記錄每一分支最近結果的歷史 e. g. , record recent history of each branch n 假設未來行為會持續趨勢 Assume future behavior will continue the trend n 當猜錯時,使用重新擷取時延遲stall、並更新歷史紀錄 When wrong, stall while re-fetching, and update history Chapter 4 — The Processor — 50
管線處理總結Pipeline Summary The BIG Picture n 管線處理增加效能是利用增加指令處理量 Pipelining improves performance by increasing instruction throughput n n n 危障Subject to hazards n n 同時執行多個指令Executes multiple instructions in parallel 每一指令有相同延遲時間Each instruction has the same latency 結構、資料、控制Structure, data, control 指令集設計影響實現管線處理的複雜度 Instruction set design affects complexity of pipeline implementation Chapter 4 — The Processor — 51
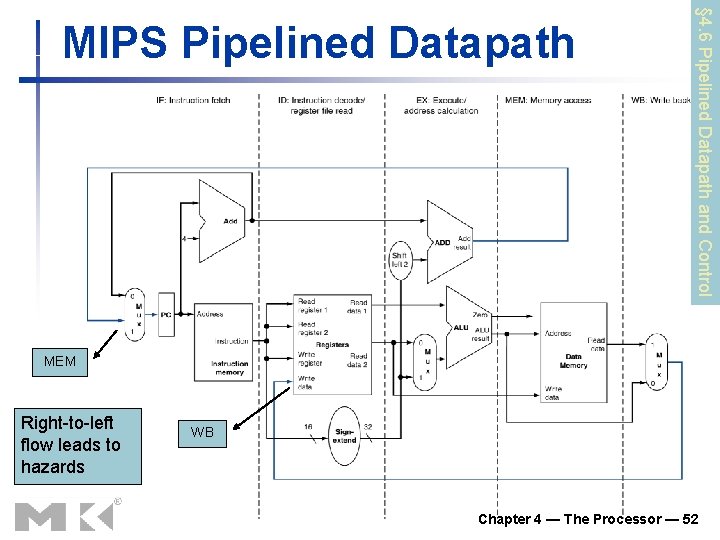
§ 4. 6 Pipelined Datapath and Control MIPS Pipelined Datapath MEM Right-to-left flow leads to hazards WB Chapter 4 — The Processor — 52
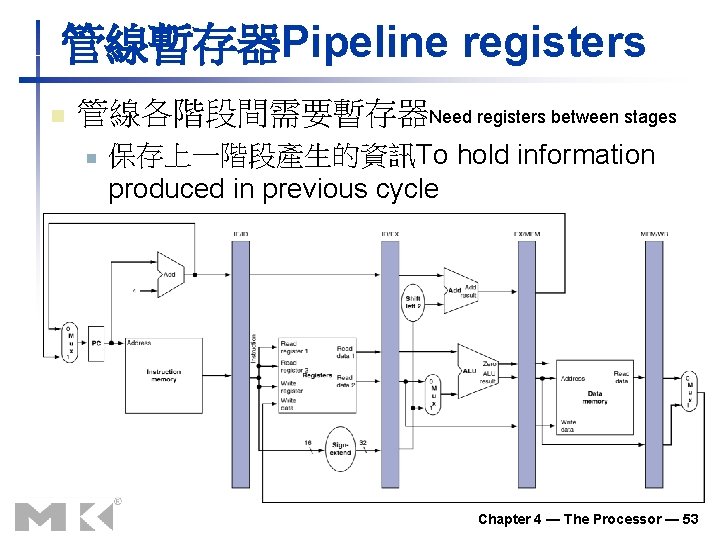
管線暫存器Pipeline registers n 管線各階段間需要暫存器Need registers between stages n 保存上一階段產生的資訊To hold information produced in previous cycle Chapter 4 — The Processor — 53
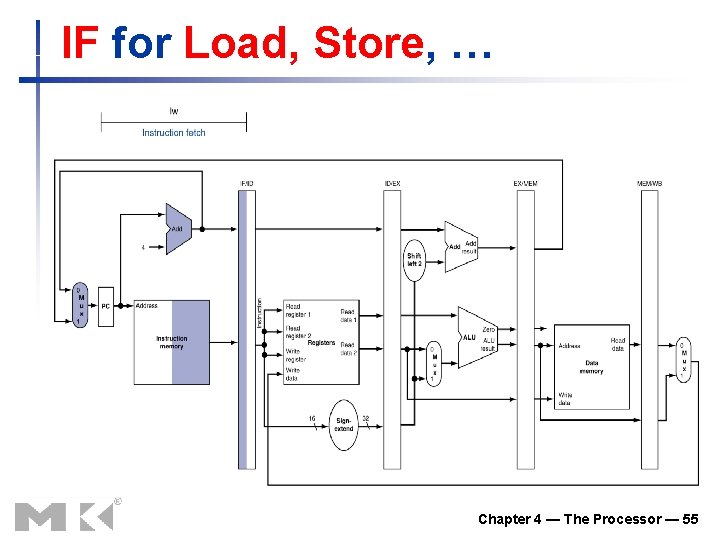
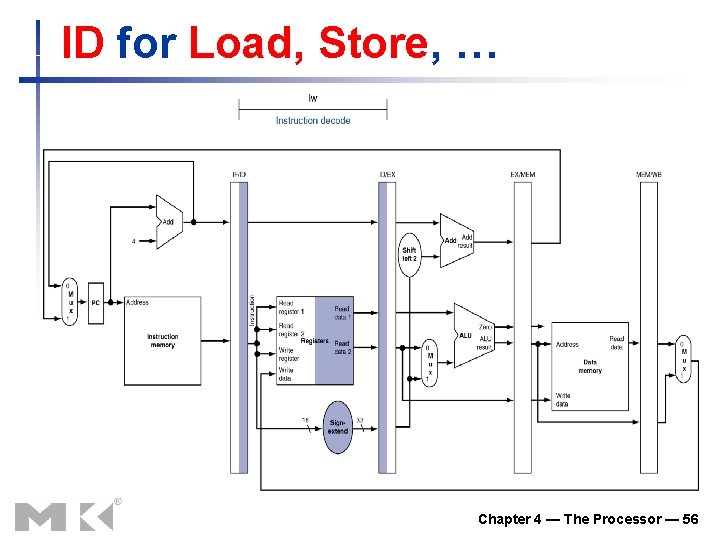
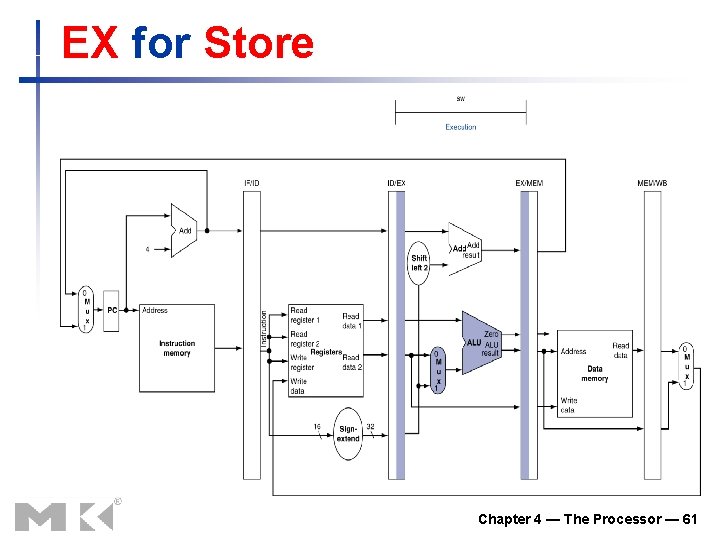
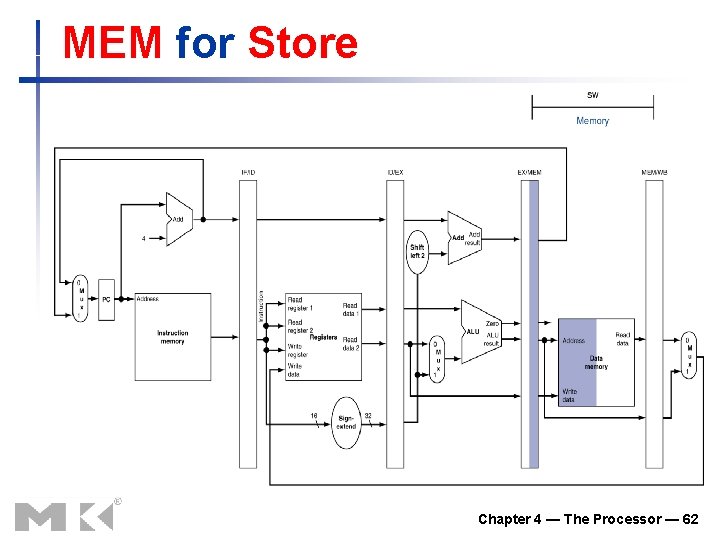
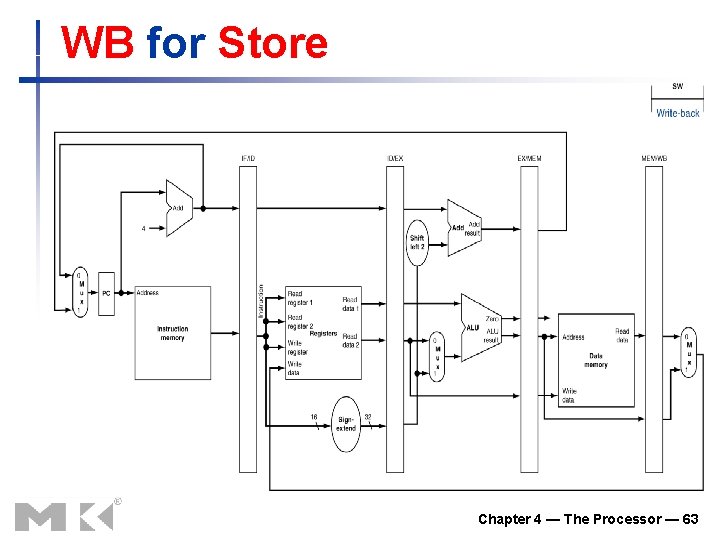
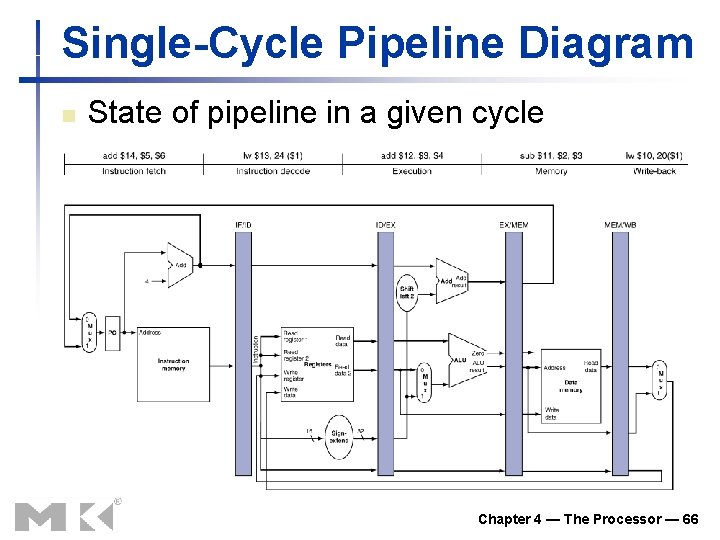
Pipeline Operation n 管線化資料路徑「逐一週期」的流程 Cycle-by-cycle flow of instructions through the pipelined datapath n “Single-clock-cycle” pipeline diagram n n n c. f. “multi-clock-cycle” diagram n n Shows pipeline usage in a single cycle Highlight resources used Graph of operation over time We’ll look at “single-clock-cycle” diagrams for load & store Chapter 4 — The Processor — 54
IF for Load, Store, … Chapter 4 — The Processor — 55
ID for Load, Store, … Chapter 4 — The Processor — 56
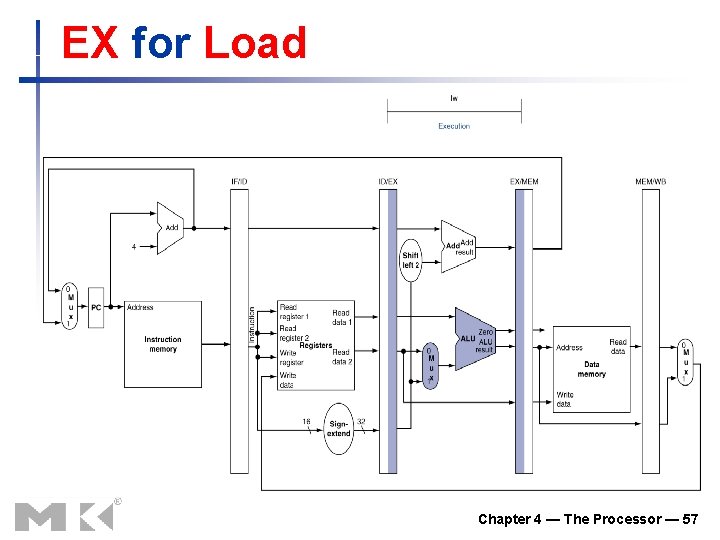
EX for Load Chapter 4 — The Processor — 57
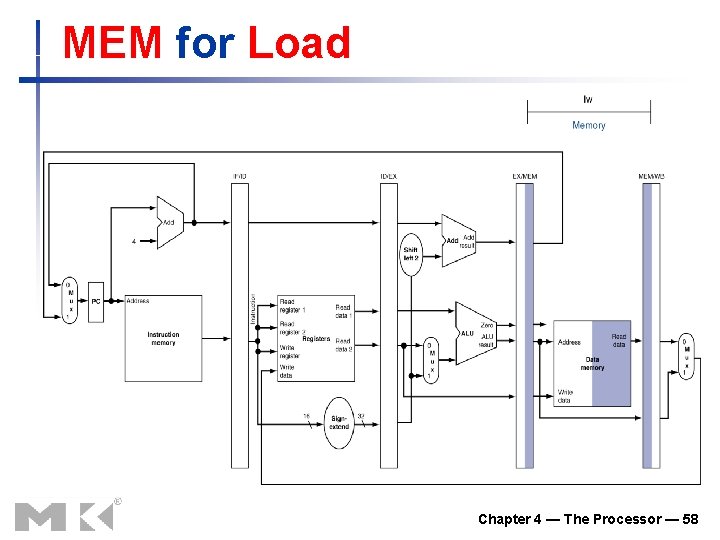
MEM for Load Chapter 4 — The Processor — 58
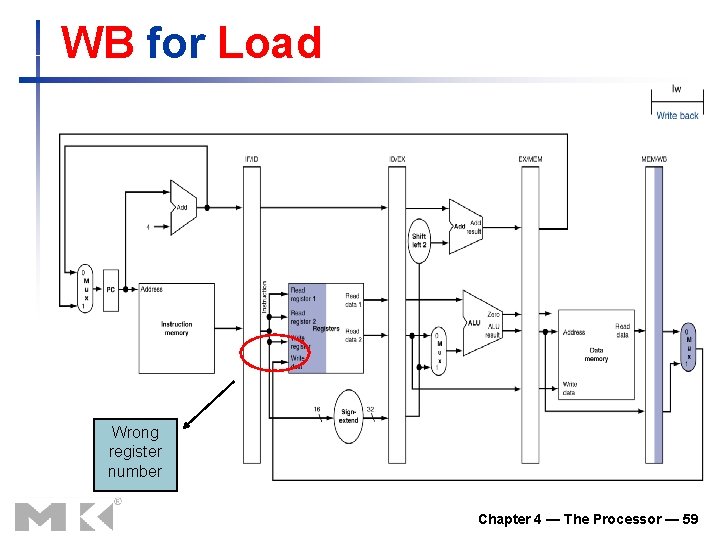
WB for Load Wrong register number Chapter 4 — The Processor — 59
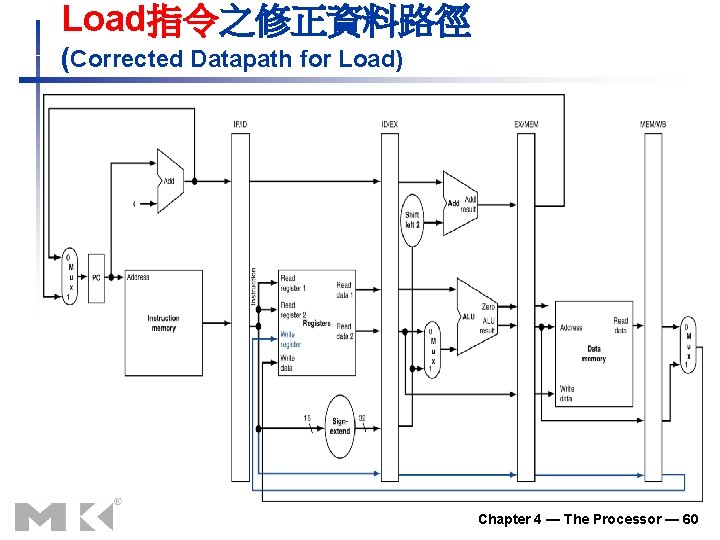
Load指令之修正資料路徑 (Corrected Datapath for Load) Chapter 4 — The Processor — 60
EX for Store Chapter 4 — The Processor — 61
MEM for Store Chapter 4 — The Processor — 62
WB for Store Chapter 4 — The Processor — 63
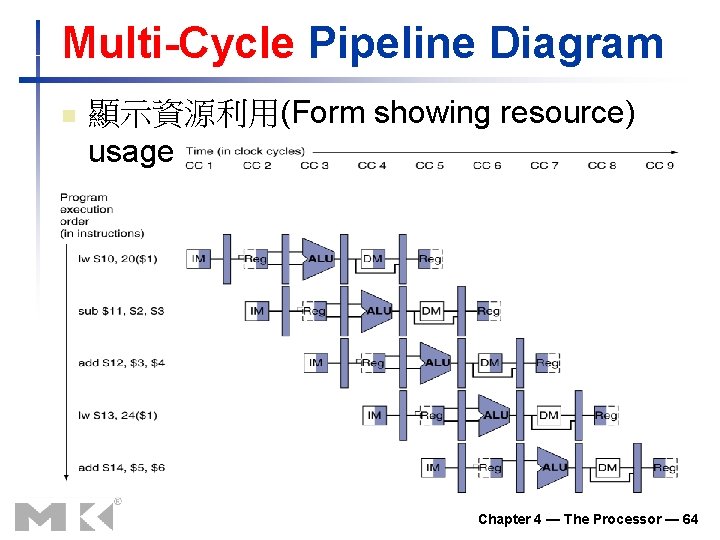
Multi-Cycle Pipeline Diagram n 顯示資源利用(Form showing resource) usage Chapter 4 — The Processor — 64
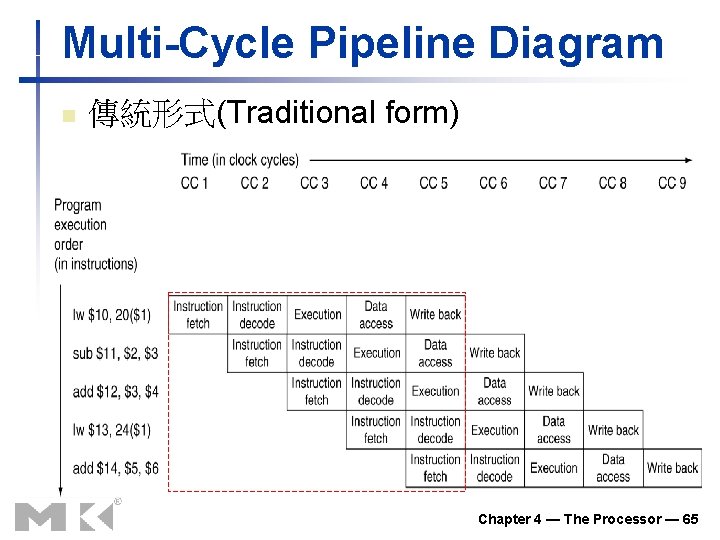
Multi-Cycle Pipeline Diagram n 傳統形式(Traditional form) Chapter 4 — The Processor — 65
Single-Cycle Pipeline Diagram n State of pipeline in a given cycle Chapter 4 — The Processor — 66
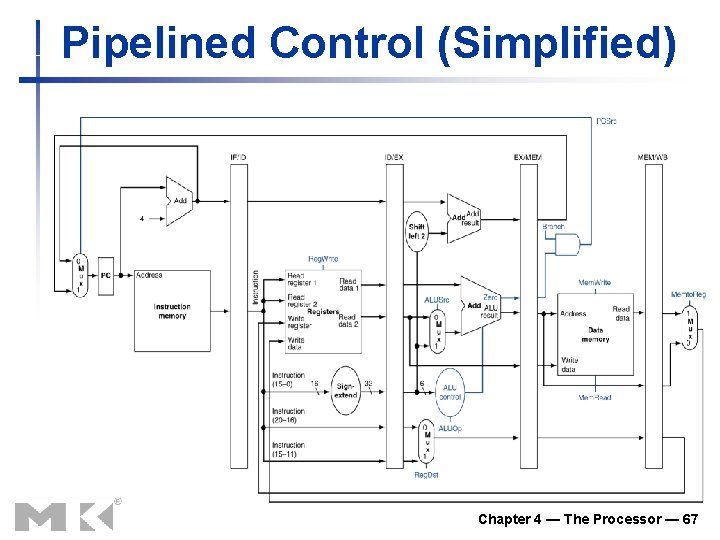
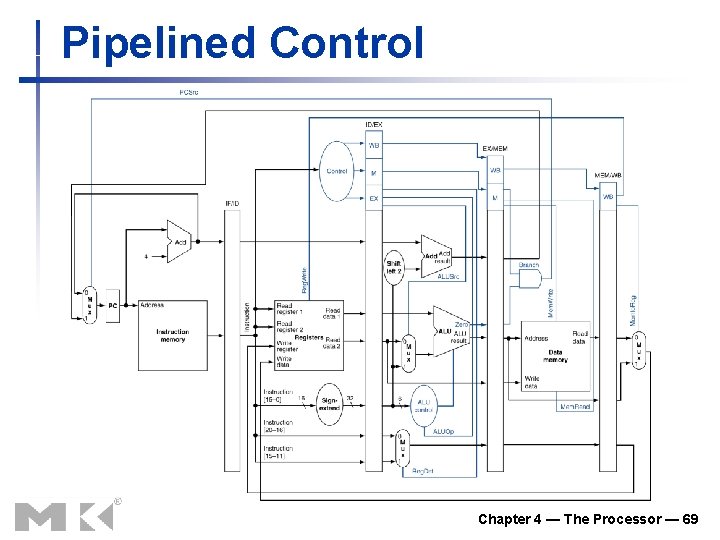
Pipelined Control (Simplified) Chapter 4 — The Processor — 67
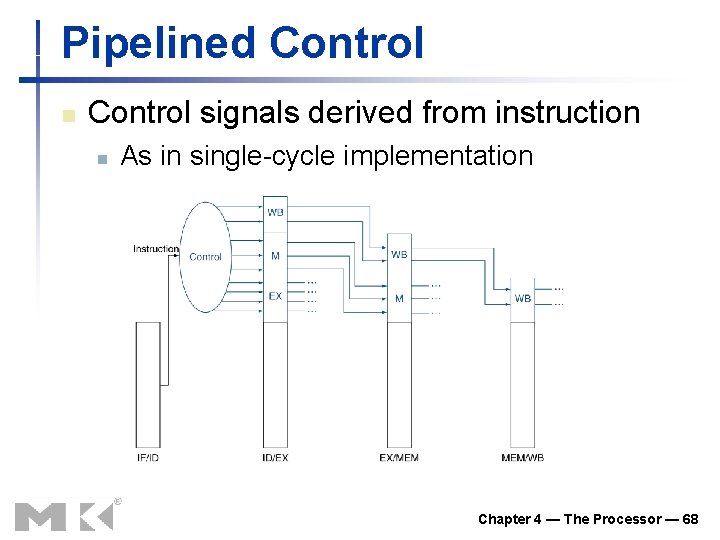
Pipelined Control n Control signals derived from instruction n As in single-cycle implementation Chapter 4 — The Processor — 68
Pipelined Control Chapter 4 — The Processor — 69
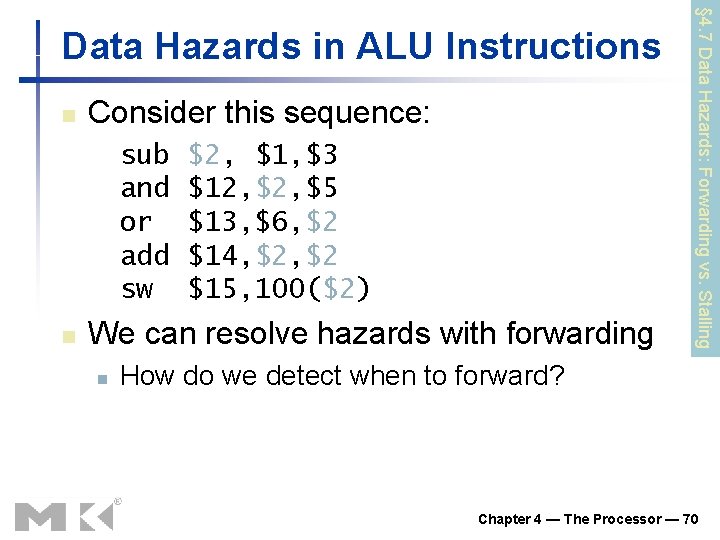
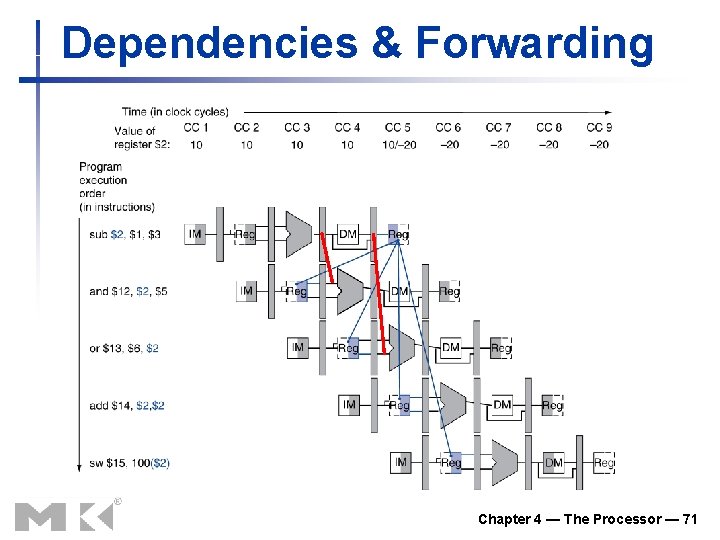
n Consider this sequence: sub and or add sw n $2, $1, $3 $12, $5 $13, $6, $2 $14, $2 $15, 100($2) We can resolve hazards with forwarding n § 4. 7 Data Hazards: Forwarding vs. Stalling Data Hazards in ALU Instructions How do we detect when to forward? Chapter 4 — The Processor — 70
Dependencies & Forwarding Chapter 4 — The Processor — 71
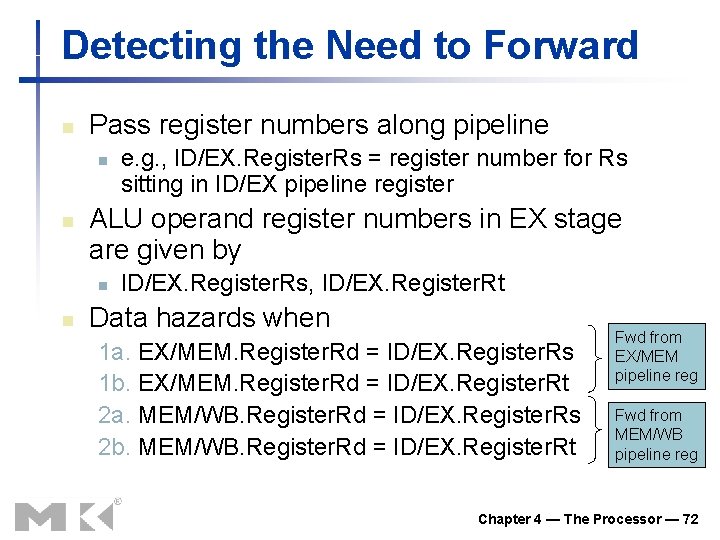
Detecting the Need to Forward n Pass register numbers along pipeline n n ALU operand register numbers in EX stage are given by n n e. g. , ID/EX. Register. Rs = register number for Rs sitting in ID/EX pipeline register ID/EX. Register. Rs, ID/EX. Register. Rt Data hazards when 1 a. EX/MEM. Register. Rd = ID/EX. Register. Rs 1 b. EX/MEM. Register. Rd = ID/EX. Register. Rt 2 a. MEM/WB. Register. Rd = ID/EX. Register. Rs 2 b. MEM/WB. Register. Rd = ID/EX. Register. Rt Fwd from EX/MEM pipeline reg Fwd from MEM/WB pipeline reg Chapter 4 — The Processor — 72
Detecting the Need to Forward n But only if forwarding instruction will write to a register! n n EX/MEM. Reg. Write, MEM/WB. Reg. Write And only if Rd for that instruction is not $zero n EX/MEM. Register. Rd ≠ 0, MEM/WB. Register. Rd ≠ 0 Chapter 4 — The Processor — 73
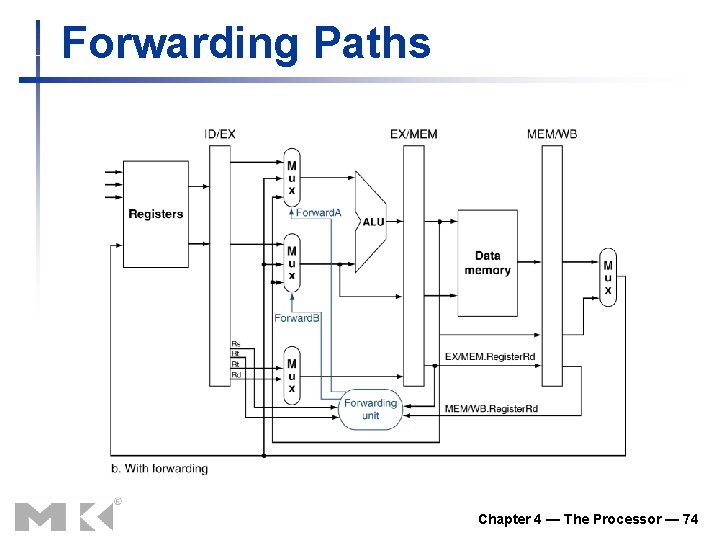
Forwarding Paths Chapter 4 — The Processor — 74
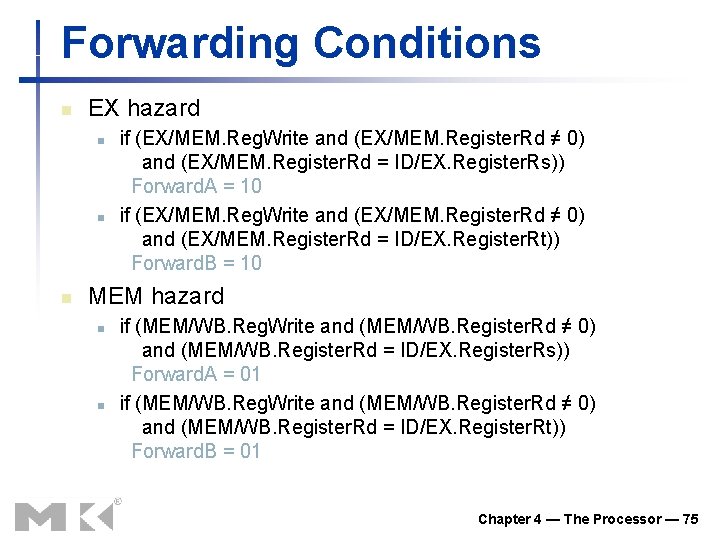
Forwarding Conditions n EX hazard n n n if (EX/MEM. Reg. Write and (EX/MEM. Register. Rd ≠ 0) and (EX/MEM. Register. Rd = ID/EX. Register. Rs)) Forward. A = 10 if (EX/MEM. Reg. Write and (EX/MEM. Register. Rd ≠ 0) and (EX/MEM. Register. Rd = ID/EX. Register. Rt)) Forward. B = 10 MEM hazard n n if (MEM/WB. Reg. Write and (MEM/WB. Register. Rd ≠ 0) and (MEM/WB. Register. Rd = ID/EX. Register. Rs)) Forward. A = 01 if (MEM/WB. Reg. Write and (MEM/WB. Register. Rd ≠ 0) and (MEM/WB. Register. Rd = ID/EX. Register. Rt)) Forward. B = 01 Chapter 4 — The Processor — 75
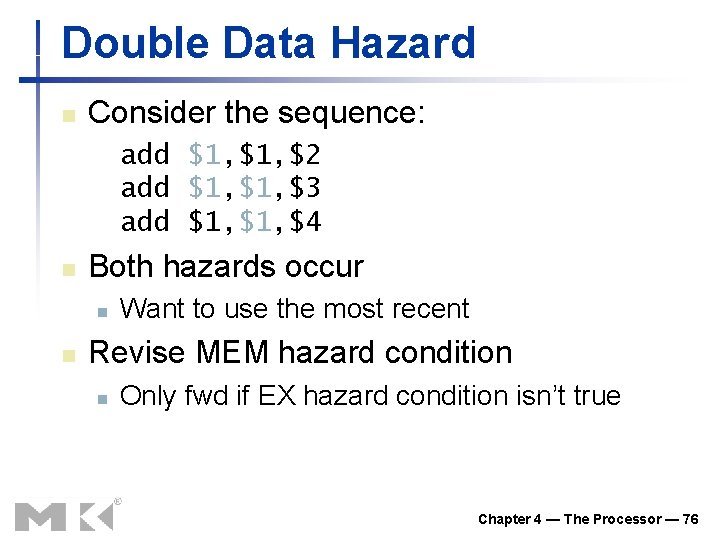
Double Data Hazard n Consider the sequence: add $1, $2 add $1, $3 add $1, $4 n Both hazards occur n n Want to use the most recent Revise MEM hazard condition n Only fwd if EX hazard condition isn’t true Chapter 4 — The Processor — 76
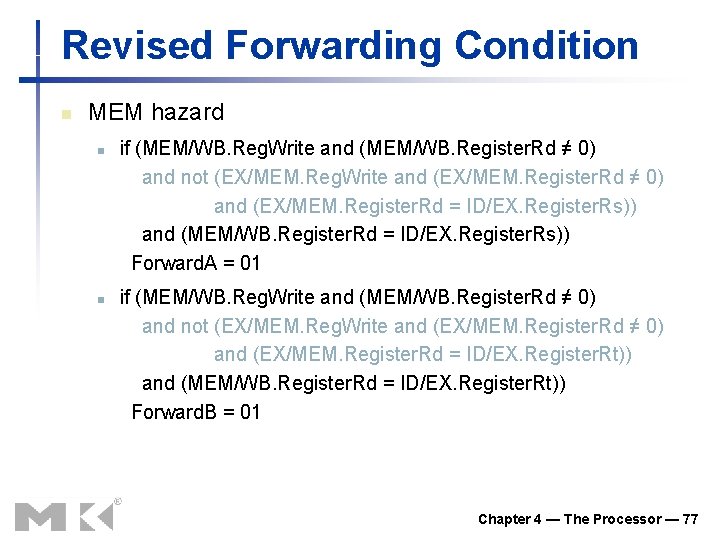
Revised Forwarding Condition n MEM hazard n n if (MEM/WB. Reg. Write and (MEM/WB. Register. Rd ≠ 0) and not (EX/MEM. Reg. Write and (EX/MEM. Register. Rd ≠ 0) and (EX/MEM. Register. Rd = ID/EX. Register. Rs)) and (MEM/WB. Register. Rd = ID/EX. Register. Rs)) Forward. A = 01 if (MEM/WB. Reg. Write and (MEM/WB. Register. Rd ≠ 0) and not (EX/MEM. Reg. Write and (EX/MEM. Register. Rd ≠ 0) and (EX/MEM. Register. Rd = ID/EX. Register. Rt)) and (MEM/WB. Register. Rd = ID/EX. Register. Rt)) Forward. B = 01 Chapter 4 — The Processor — 77
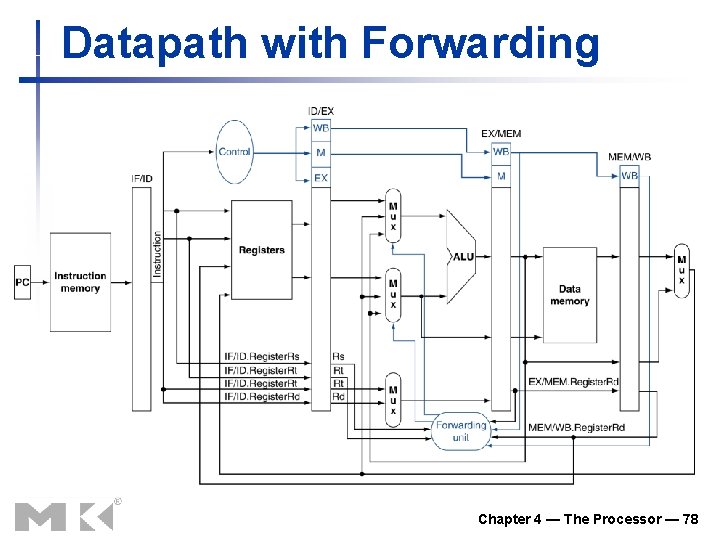
Datapath with Forwarding Chapter 4 — The Processor — 78
Load-Use Data Hazard Need to stall for one cycle Chapter 4 — The Processor — 79
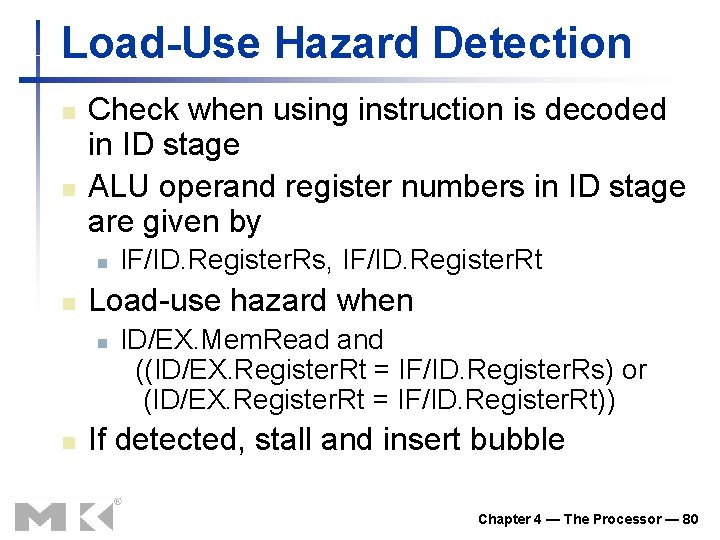
Load-Use Hazard Detection n n Check when using instruction is decoded in ID stage ALU operand register numbers in ID stage are given by n n Load-use hazard when n n IF/ID. Register. Rs, IF/ID. Register. Rt ID/EX. Mem. Read and ((ID/EX. Register. Rt = IF/ID. Register. Rs) or (ID/EX. Register. Rt = IF/ID. Register. Rt)) If detected, stall and insert bubble Chapter 4 — The Processor — 80
How to Stall the Pipeline n Force control values in ID/EX register to 0 n n EX, MEM and WB do nop (no-operation) Prevent update of PC and IF/ID register n n n Using instruction is decoded again Following instruction is fetched again 1 -cycle stall allows MEM to read data for lw n Can subsequently forward to EX stage Chapter 4 — The Processor — 81
Stall/Bubble in the Pipeline Stall inserted here Chapter 4 — The Processor — 82
Stall/Bubble in the Pipeline Or, more accurately… Chapter 4 — The Processor — 83
Datapath with Hazard Detection Chapter 4 — The Processor — 84
Stalls and Performance The BIG Picture n Stalls reduce performance n n But are required to get correct results Compiler can arrange code to avoid hazards and stalls n Requires knowledge of the pipeline structure Chapter 4 — The Processor — 85
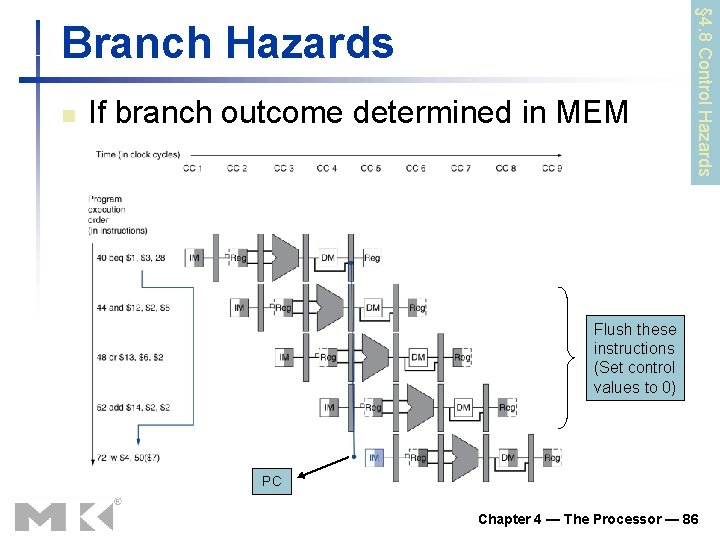
n If branch outcome determined in MEM § 4. 8 Control Hazards Branch Hazards Flush these instructions (Set control values to 0) PC Chapter 4 — The Processor — 86
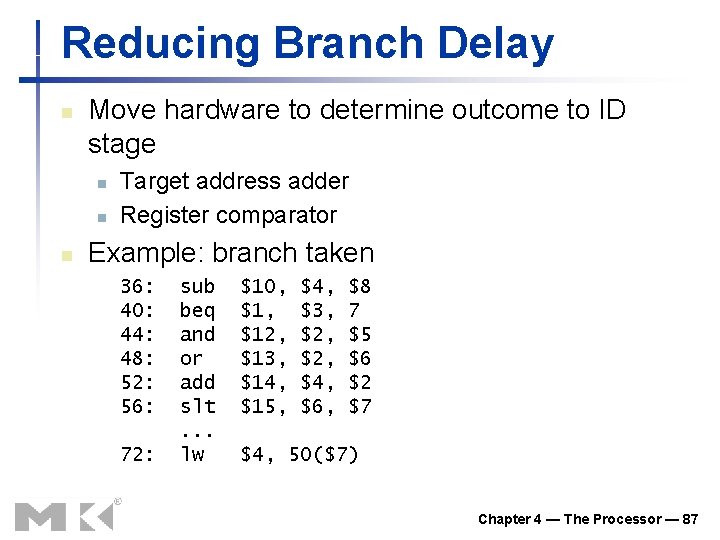
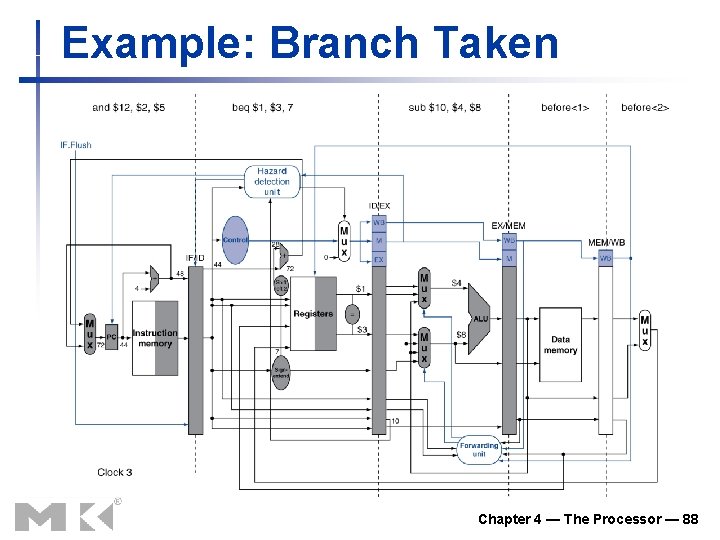
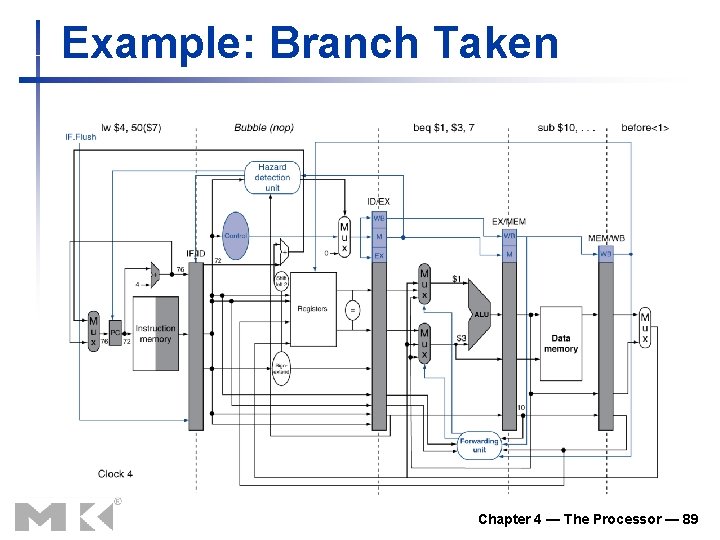
Reducing Branch Delay n Move hardware to determine outcome to ID stage n n n Target address adder Register comparator Example: branch taken 36: 40: 44: 48: 52: 56: 72: sub beq and or add slt. . . lw $10, $12, $13, $14, $15, $4, $3, $2, $4, $6, $8 7 $5 $6 $2 $7 $4, 50($7) Chapter 4 — The Processor — 87
Example: Branch Taken Chapter 4 — The Processor — 88
Example: Branch Taken Chapter 4 — The Processor — 89
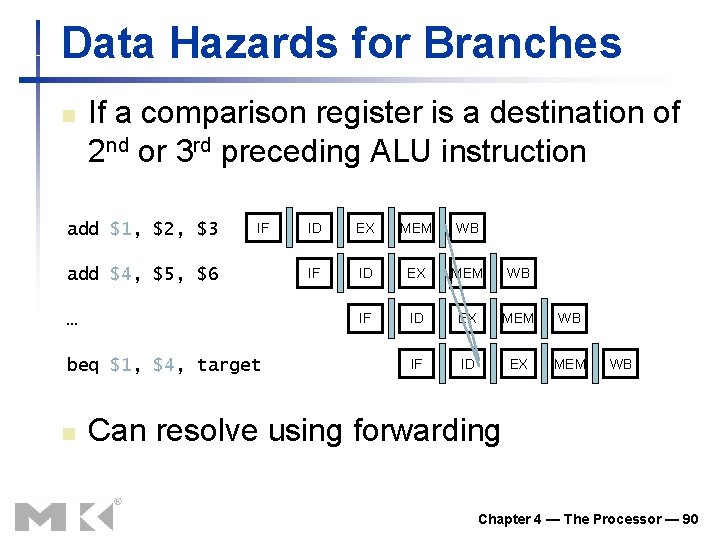
Data Hazards for Branches n If a comparison register is a destination of 2 nd or 3 rd preceding ALU instruction add $1, $2, $3 IF add $4, $5, $6 … beq $1, $4, target n ID EX MEM WB IF ID EX MEM WB Can resolve using forwarding Chapter 4 — The Processor — 90
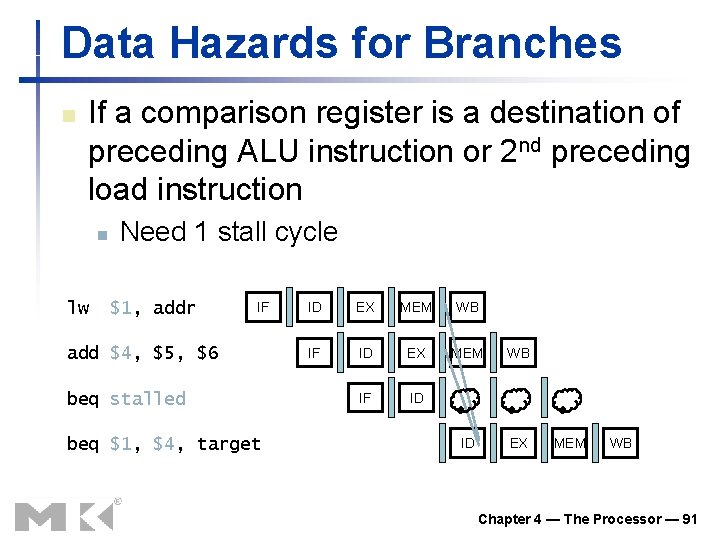
Data Hazards for Branches n If a comparison register is a destination of preceding ALU instruction or 2 nd preceding load instruction n lw Need 1 stall cycle $1, addr IF add $4, $5, $6 beq stalled beq $1, $4, target ID EX MEM WB IF ID ID EX MEM WB Chapter 4 — The Processor — 91
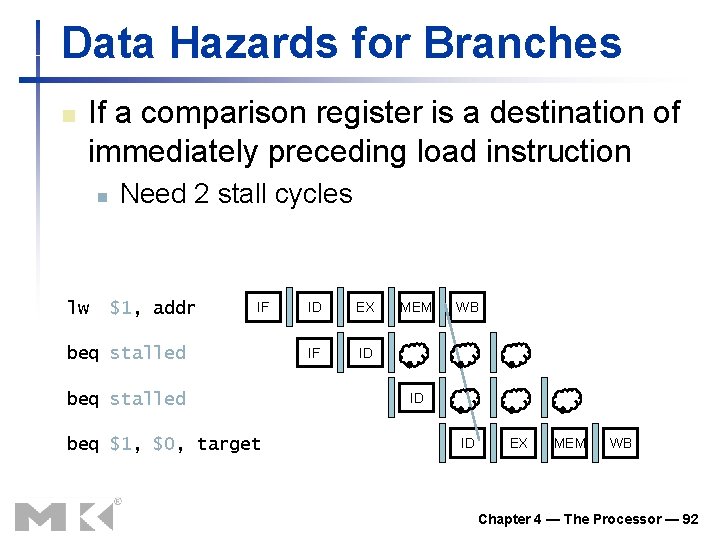
Data Hazards for Branches n If a comparison register is a destination of immediately preceding load instruction n lw Need 2 stall cycles $1, addr IF beq stalled beq $1, $0, target ID EX IF ID MEM WB ID ID EX MEM WB Chapter 4 — The Processor — 92
Dynamic Branch Prediction n n In deeper and superscalar pipelines, branch penalty is more significant Use dynamic prediction n n Branch prediction buffer (aka branch history table) Indexed by recent branch instruction addresses Stores outcome (taken/not taken) To execute a branch n n n Check table, expect the same outcome Start fetching from fall-through or target If wrong, flush pipeline and flip prediction Chapter 4 — The Processor — 93
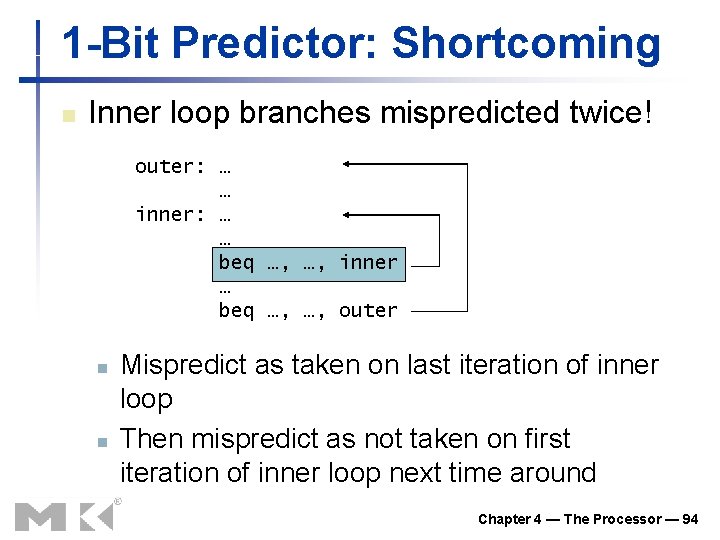
1 -Bit Predictor: Shortcoming n Inner loop branches mispredicted twice! outer: … … inner: … … beq …, …, inner … beq …, …, outer n n Mispredict as taken on last iteration of inner loop Then mispredict as not taken on first iteration of inner loop next time around Chapter 4 — The Processor — 94
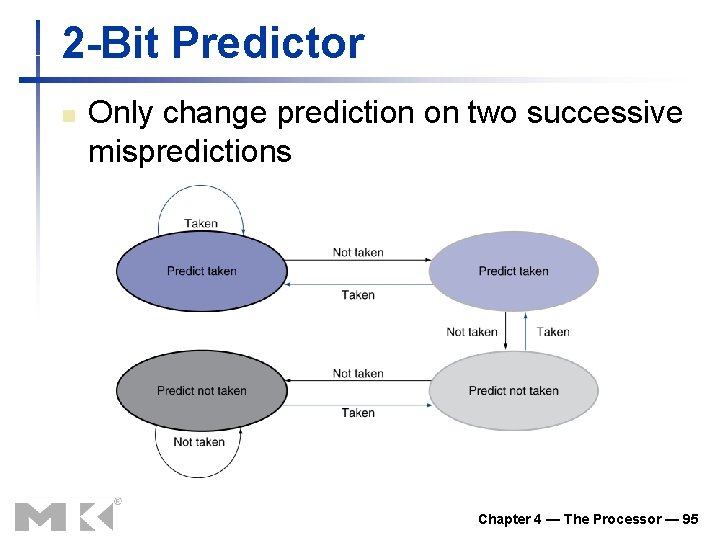
2 -Bit Predictor n Only change prediction on two successive mispredictions Chapter 4 — The Processor — 95
Calculating the Branch Target n Even with predictor, still need to calculate the target address n n 1 -cycle penalty for a taken branch Branch target buffer n n Cache of target addresses Indexed by PC when instruction fetched n If hit and instruction is branch predicted taken, can fetch target immediately Chapter 4 — The Processor — 96
n “Unexpected” events requiring change in flow of control n n Different ISAs use the terms differently Exception n Arises within the CPU n n e. g. , undefined opcode, overflow, syscall, … Interrupt n n § 4. 9 Exceptions and Interrupts From an external I/O controller Dealing with them without sacrificing performance is hard Chapter 4 — The Processor — 97
Handling Exceptions n n In MIPS, exceptions managed by a System Control Coprocessor (CP 0) Save PC of offending (or interrupted) instruction n n In MIPS: Exception Program Counter (EPC) Save indication of the problem n n In MIPS: Cause register We’ll assume 1 -bit n n 0 for undefined opcode, 1 for overflow Jump to handler at 8000 00180 Chapter 4 — The Processor — 98
An Alternate Mechanism n Vectored Interrupts n n Example: n n Handler address determined by the cause Undefined opcode: Overflow: …: C 0000 C 000 0020 C 000 0040 Instructions either n n Deal with the interrupt, or Jump to real handler Chapter 4 — The Processor — 99
Handler Actions n n n Read cause, and transfer to relevant handler Determine action required If restartable n n n Take corrective action use EPC to return to program Otherwise n n Terminate program Report error using EPC, cause, … Chapter 4 — The Processor — 100
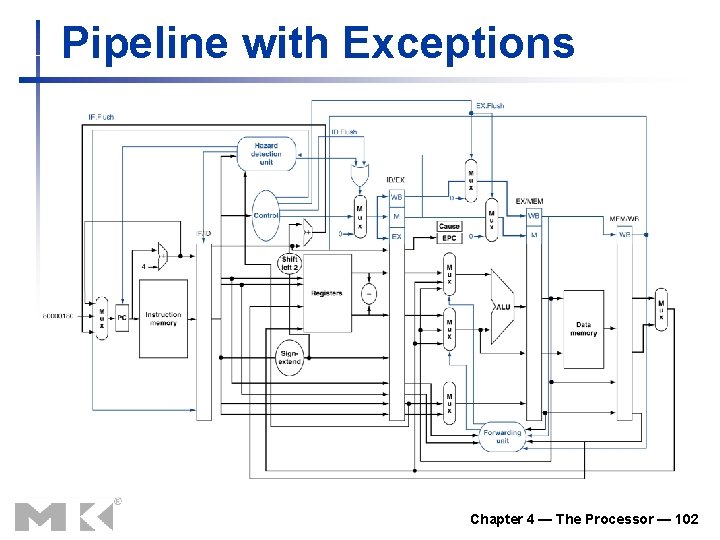
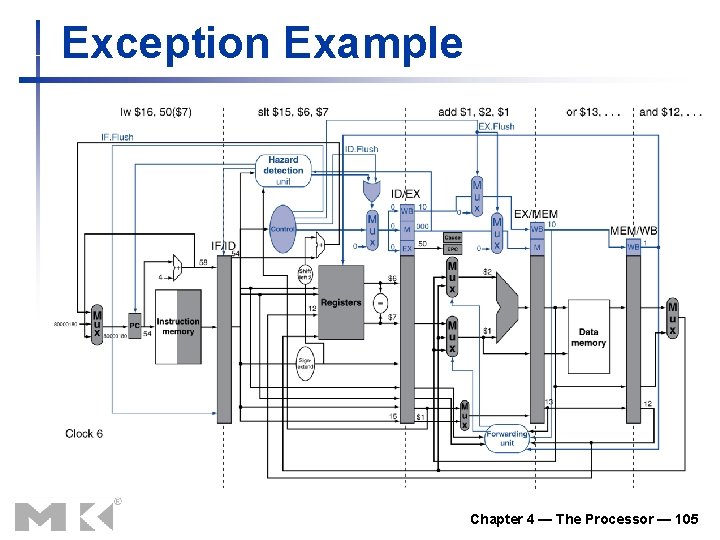
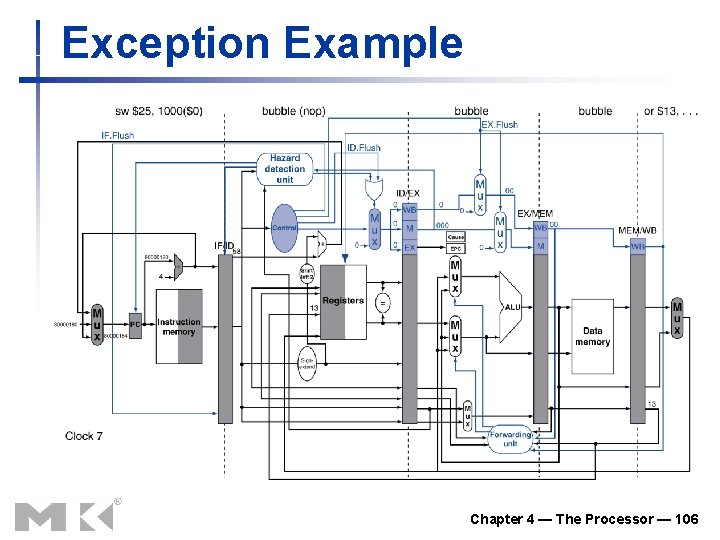
Exceptions in a Pipeline n n Another form of control hazard Consider overflow on add in EX stage add $1, $2, $1 n Prevent $1 from being clobbered n Complete previous instructions n Flush add and subsequent instructions n Set Cause and EPC register values n Transfer control to handler n Similar to mispredicted branch n Use much of the same hardware Chapter 4 — The Processor — 101
Pipeline with Exceptions Chapter 4 — The Processor — 102
Exception Properties n Restartable exceptions n n Pipeline can flush the instruction Handler executes, then returns to the instruction n n Refetched and executed from scratch PC saved in EPC register n n Identifies causing instruction Actually PC + 4 is saved n Handler must adjust Chapter 4 — The Processor — 103
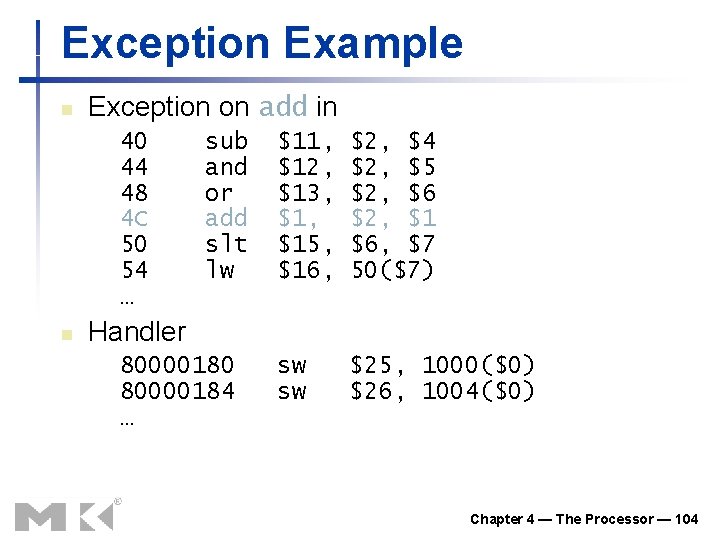
Exception Example n Exception on add in 40 44 48 4 C 50 54 … n sub and or add slt lw $11, $12, $13, $15, $16, $2, $4 $2, $5 $2, $6 $2, $1 $6, $7 50($7) sw sw $25, 1000($0) $26, 1004($0) Handler 80000180 80000184 … Chapter 4 — The Processor — 104
Exception Example Chapter 4 — The Processor — 105
Exception Example Chapter 4 — The Processor — 106
Multiple Exceptions n Pipelining overlaps multiple instructions n n Simple approach: deal with exception from earliest instruction n Could have multiple exceptions at once Flush subsequent instructions “Precise” exceptions In complex pipelines n n n Multiple instructions issued per cycle Out-of-order completion Maintaining precise exceptions is difficult! Chapter 4 — The Processor — 107
Imprecise Exceptions n Just stop pipeline and save state n n Including exception cause(s) Let the handler work out n n Which instruction(s) had exceptions Which to complete or flush n n n May require “manual” completion Simplifies hardware, but more complex handler software Not feasible for complex multiple-issue out-of-order pipelines Chapter 4 — The Processor — 108
n n Pipelining: executing multiple instructions in parallel To increase ILP n Deeper pipeline n n Less work per stage shorter clock cycle Multiple issue n n Replicate pipeline stages multiple pipelines Start multiple instructions per clock cycle CPI < 1, so use Instructions Per Cycle (IPC) E. g. , 4 GHz 4 -way multiple-issue n n 16 BIPS, peak CPI = 0. 25, peak IPC = 4 But dependencies reduce this in practice § 4. 10 Parallelism and Advanced Instruction Level Parallelism Instruction-Level Parallelism (ILP) Chapter 4 — The Processor — 109
Multiple Issue n Static multiple issue n n Compiler groups instructions to be issued together Packages them into “issue slots” Compiler detects and avoids hazards Dynamic multiple issue n n n CPU examines instruction stream and chooses instructions to issue each cycle Compiler can help by reordering instructions CPU resolves hazards using advanced techniques at runtime Chapter 4 — The Processor — 110
Speculation n “Guess” what to do with an instruction n n Start operation as soon as possible Check whether guess was right n n If so, complete the operation If not, roll-back and do the right thing Common to static and dynamic multiple issue Examples n Speculate on branch outcome n n Roll back if path taken is different Speculate on load n Roll back if location is updated Chapter 4 — The Processor — 111
Compiler/Hardware Speculation n Compiler can reorder instructions n n n e. g. , move load before branch Can include “fix-up” instructions to recover from incorrect guess Hardware can look ahead for instructions to execute n n Buffer results until it determines they are actually needed Flush buffers on incorrect speculation Chapter 4 — The Processor — 112
Speculation and Exceptions n What if exception occurs on a speculatively executed instruction? n n Static speculation n n e. g. , speculative load before null-pointer check Can add ISA support for deferring exceptions Dynamic speculation n Can buffer exceptions until instruction completion (which may not occur) Chapter 4 — The Processor — 113
Static Multiple Issue n Compiler groups instructions into “issue packets” n n n Group of instructions that can be issued on a single cycle Determined by pipeline resources required Think of an issue packet as a very long instruction n n Specifies multiple concurrent operations Very Long Instruction Word (VLIW) Chapter 4 — The Processor — 114
Scheduling Static Multiple Issue n Compiler must remove some/all hazards n n n Reorder instructions into issue packets No dependencies with a packet Possibly some dependencies between packets n n Varies between ISAs; compiler must know! Pad with nop if necessary Chapter 4 — The Processor — 115
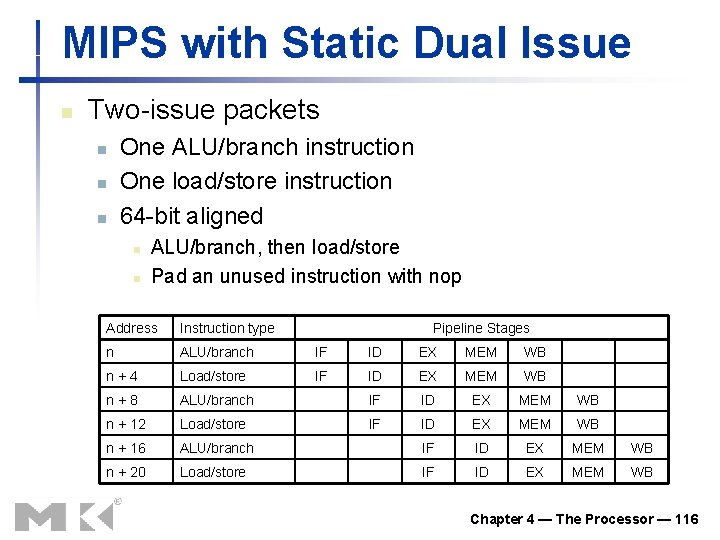
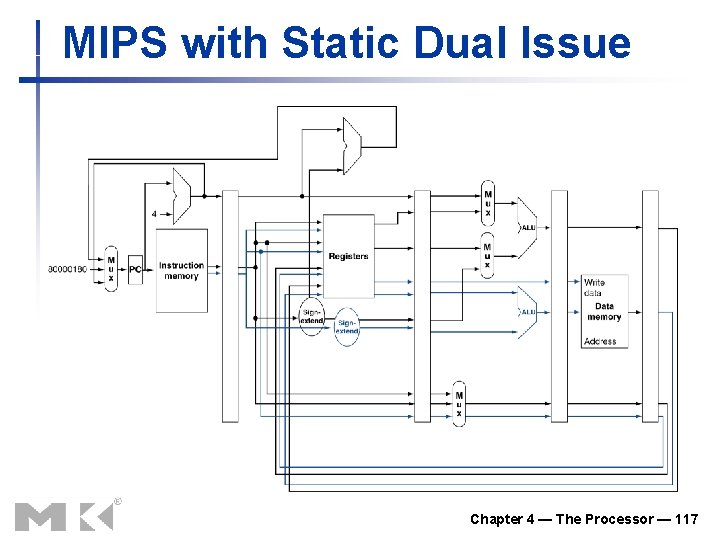
MIPS with Static Dual Issue n Two-issue packets n n n One ALU/branch instruction One load/store instruction 64 -bit aligned n n ALU/branch, then load/store Pad an unused instruction with nop Address Instruction type Pipeline Stages n ALU/branch IF ID EX MEM WB n+4 Load/store IF ID EX MEM WB n+8 ALU/branch IF ID EX MEM WB n + 12 Load/store IF ID EX MEM WB n + 16 ALU/branch IF ID EX MEM WB n + 20 Load/store IF ID EX MEM WB Chapter 4 — The Processor — 116
MIPS with Static Dual Issue Chapter 4 — The Processor — 117
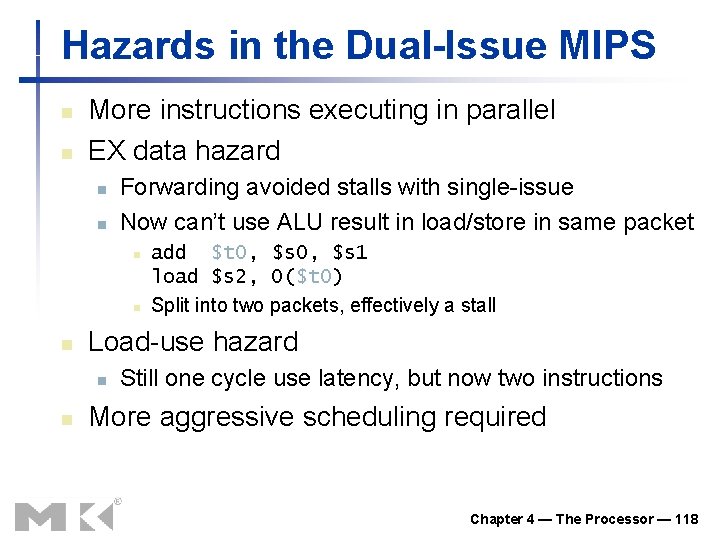
Hazards in the Dual-Issue MIPS n n More instructions executing in parallel EX data hazard n n Forwarding avoided stalls with single-issue Now can’t use ALU result in load/store in same packet n n n Load-use hazard n n add $t 0, $s 1 load $s 2, 0($t 0) Split into two packets, effectively a stall Still one cycle use latency, but now two instructions More aggressive scheduling required Chapter 4 — The Processor — 118
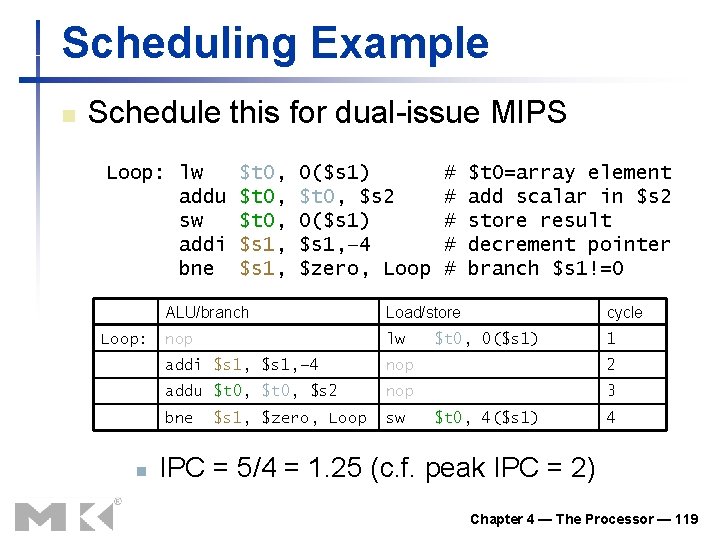
Scheduling Example n Schedule this for dual-issue MIPS Loop: lw addu sw addi bne Loop: n $t 0, $s 1, 0($s 1) $t 0, $s 2 0($s 1) $s 1, – 4 $zero, Loop # # # $t 0=array element add scalar in $s 2 store result decrement pointer branch $s 1!=0 ALU/branch Load/store cycle nop lw 1 addi $s 1, – 4 nop 2 addu $t 0, $s 2 nop 3 bne sw $s 1, $zero, Loop $t 0, 0($s 1) $t 0, 4($s 1) 4 IPC = 5/4 = 1. 25 (c. f. peak IPC = 2) Chapter 4 — The Processor — 119
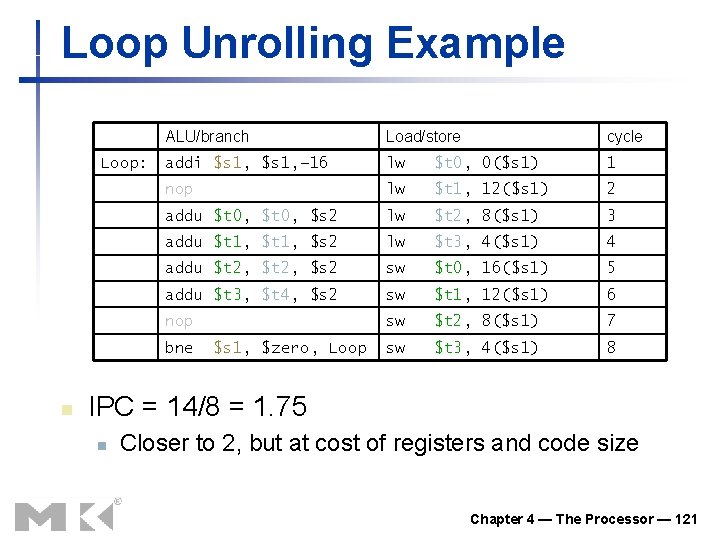
Loop Unrolling n Replicate loop body to expose more parallelism n n Reduces loop-control overhead Use different registers per replication n n Called “register renaming” Avoid loop-carried “anti-dependencies” n n Store followed by a load of the same register Aka “name dependence” n Reuse of a register name Chapter 4 — The Processor — 120
Loop Unrolling Example Loop: ALU/branch Load/store cycle addi $s 1, – 16 lw $t 0, 0($s 1) 1 nop lw $t 1, 12($s 1) 2 addu $t 0, $s 2 lw $t 2, 8($s 1) 3 addu $t 1, $s 2 lw $t 3, 4($s 1) 4 addu $t 2, $s 2 sw $t 0, 16($s 1) 5 addu $t 3, $t 4, $s 2 sw $t 1, 12($s 1) 6 nop sw $t 2, 8($s 1) 7 sw $t 3, 4($s 1) 8 bne n $s 1, $zero, Loop IPC = 14/8 = 1. 75 n Closer to 2, but at cost of registers and code size Chapter 4 — The Processor — 121
Dynamic Multiple Issue n n “Superscalar” processors CPU decides whether to issue 0, 1, 2, … each cycle n n Avoiding structural and data hazards Avoids the need for compiler scheduling n n Though it may still help Code semantics ensured by the CPU Chapter 4 — The Processor — 122
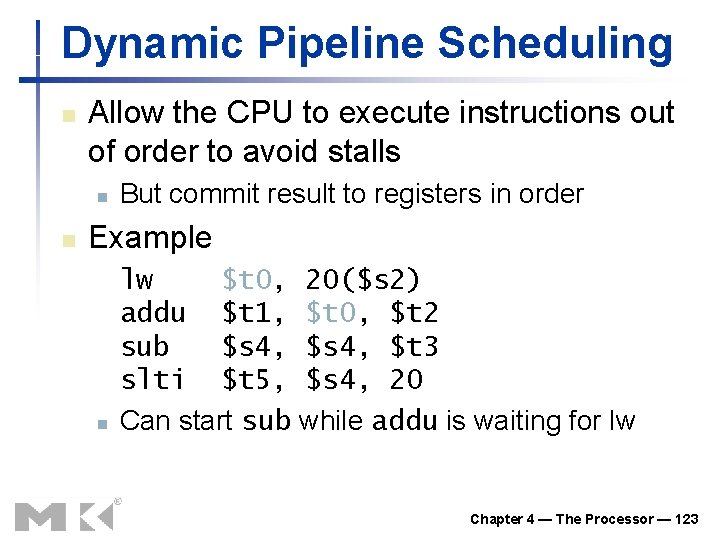
Dynamic Pipeline Scheduling n Allow the CPU to execute instructions out of order to avoid stalls n n But commit result to registers in order Example n lw $t 0, 20($s 2) addu $t 1, $t 0, $t 2 sub $s 4, $t 3 slti $t 5, $s 4, 20 Can start sub while addu is waiting for lw Chapter 4 — The Processor — 123
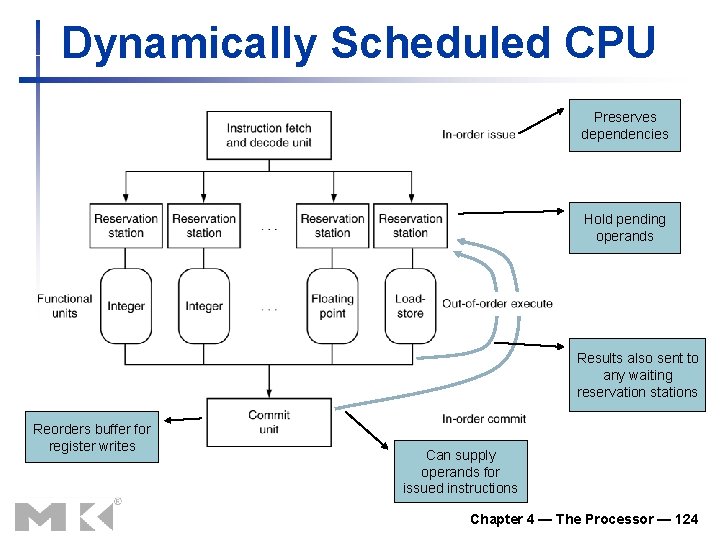
Dynamically Scheduled CPU Preserves dependencies Hold pending operands Results also sent to any waiting reservation stations Reorders buffer for register writes Can supply operands for issued instructions Chapter 4 — The Processor — 124
Register Renaming n n Reservation stations and reorder buffer effectively provide register renaming On instruction issue to reservation station n If operand is available in register file or reorder buffer n n n Copied to reservation station No longer required in the register; can be overwritten If operand is not yet available n n It will be provided to the reservation station by a function unit Register update may not be required Chapter 4 — The Processor — 125
Speculation n Predict branch and continue issuing n n Don’t commit until branch outcome determined Load speculation n Avoid load and cache miss delay n n n Predict the effective address Predict loaded value Load before completing outstanding stores Bypass stored values to load unit Don’t commit load until speculation cleared Chapter 4 — The Processor — 126
Why Do Dynamic Scheduling? n n Why not just let the compiler schedule code? Not all stalls are predicable n n Can’t always schedule around branches n n e. g. , cache misses Branch outcome is dynamically determined Different implementations of an ISA have different latencies and hazards Chapter 4 — The Processor — 127
Does Multiple Issue Work? The BIG Picture n n n Yes, but not as much as we’d like Programs have real dependencies that limit ILP Some dependencies are hard to eliminate n n Some parallelism is hard to expose n n Limited window size during instruction issue Memory delays and limited bandwidth n n e. g. , pointer aliasing Hard to keep pipelines full Speculation can help if done well Chapter 4 — The Processor — 128
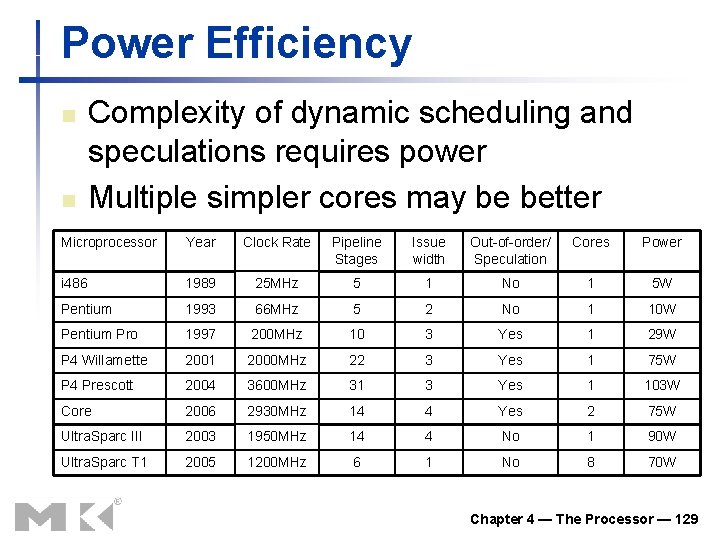
Power Efficiency n n Complexity of dynamic scheduling and speculations requires power Multiple simpler cores may be better Microprocessor Year Clock Rate Pipeline Stages Issue width Out-of-order/ Speculation Cores Power i 486 1989 25 MHz 5 1 No 1 5 W Pentium 1993 66 MHz 5 2 No 1 10 W Pentium Pro 1997 200 MHz 10 3 Yes 1 29 W P 4 Willamette 2001 2000 MHz 22 3 Yes 1 75 W P 4 Prescott 2004 3600 MHz 31 3 Yes 1 103 W Core 2006 2930 MHz 14 4 Yes 2 75 W Ultra. Sparc III 2003 1950 MHz 14 4 No 1 90 W Ultra. Sparc T 1 2005 1200 MHz 6 1 No 8 70 W Chapter 4 — The Processor — 129
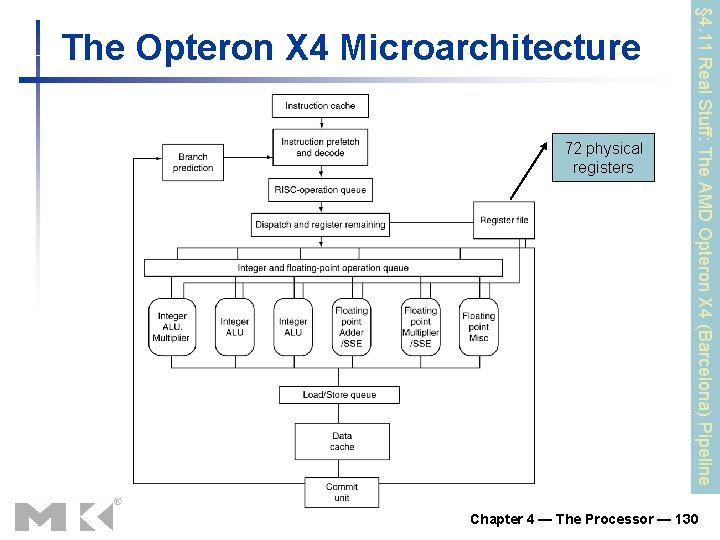
72 physical registers § 4. 11 Real Stuff: The AMD Opteron X 4 (Barcelona) Pipeline The Opteron X 4 Microarchitecture Chapter 4 — The Processor — 130
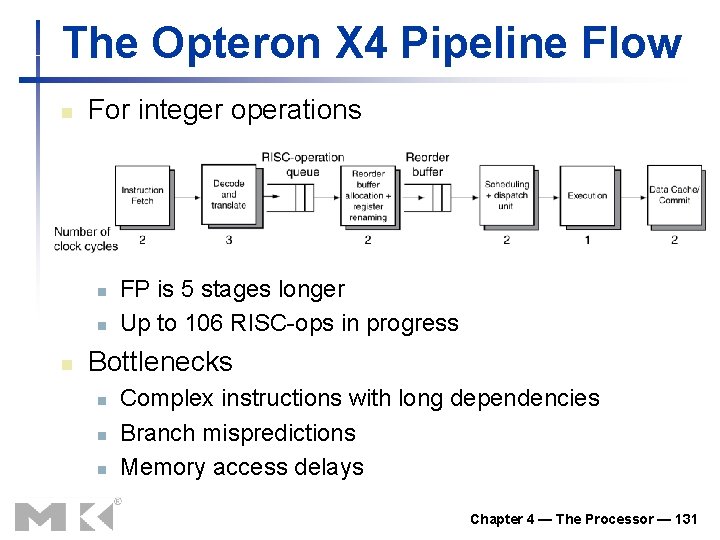
The Opteron X 4 Pipeline Flow n For integer operations n n n FP is 5 stages longer Up to 106 RISC-ops in progress Bottlenecks n n n Complex instructions with long dependencies Branch mispredictions Memory access delays Chapter 4 — The Processor — 131
§ 4. 13 Fallacies and Pitfalls Fallacies n Pipelining is easy (!) n n The basic idea is easy The devil is in the details n n e. g. , detecting data hazards Pipelining is independent of technology n n n So why haven’t we always done pipelining? More transistors make more advanced techniques feasible Pipeline-related ISA design needs to take account of technology trends n e. g. , predicated instructions Chapter 4 — The Processor — 132
Pitfalls n Poor ISA design can make pipelining harder n e. g. , complex instruction sets (VAX, IA-32) n n n e. g. , complex addressing modes n n Significant overhead to make pipelining work IA-32 micro-op approach Register update side effects, memory indirection e. g. , delayed branches n Advanced pipelines have long delay slots Chapter 4 — The Processor — 133
n n n ISA influences design of datapath and control Datapath and control influence design of ISA Pipelining improves instruction throughput using parallelism n n § 4. 14 Concluding Remarks More instructions completed per second Latency for each instruction not reduced Hazards: structural, data, control Multiple issue and dynamic scheduling (ILP) n n Dependencies limit achievable parallelism Complexity leads to the power wall Chapter 4 — The Processor — 134