
Bringing Continuous Delivery to Big Data Applications Reza
Bringing Continuous Delivery to Big Data Applications Reza Yousefzadeh YOW Data Sydney May 2019
Agenda Seek Data Platform Architecture Continuous Delivery Test Driven Development Spark Deep Dive
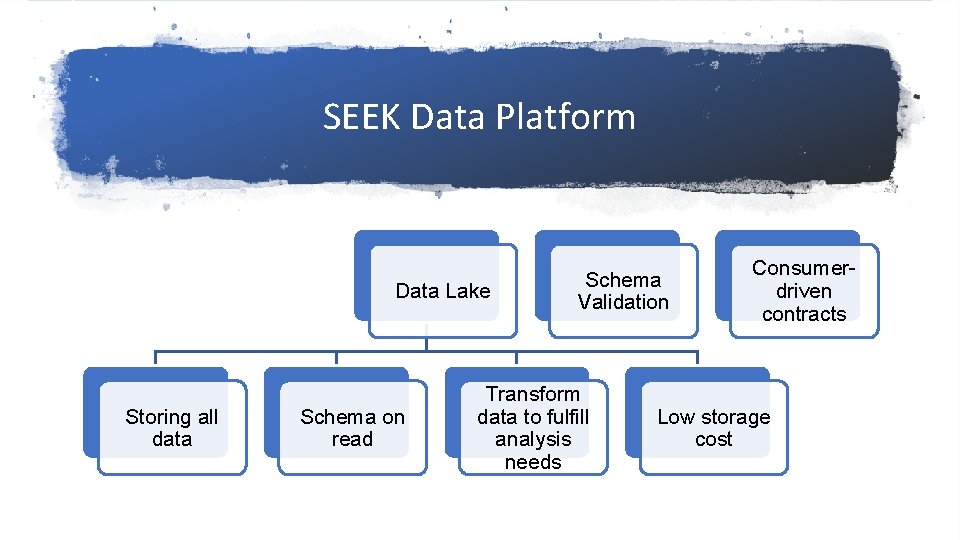
SEEK Data Platform Data Lake Storing all data Schema on read Schema Validation Transform data to fulfill analysis needs Consumerdriven contracts Low storage cost
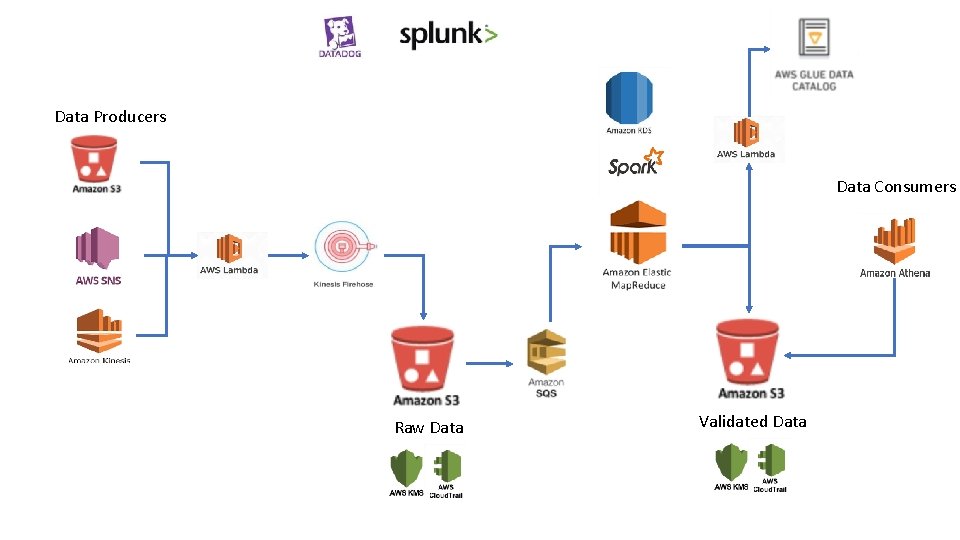
Data Producers Data Consumers Raw Data Validated Data
Easier to Microservices Architecture • • Build Test Deploy Maintain Flexibility in Using Technologies Scalable Loosely Coupled
Enabling Self Service Create and update data sets Create consumer-driven contracts Use Docker to test before sending Pull Request for access to data
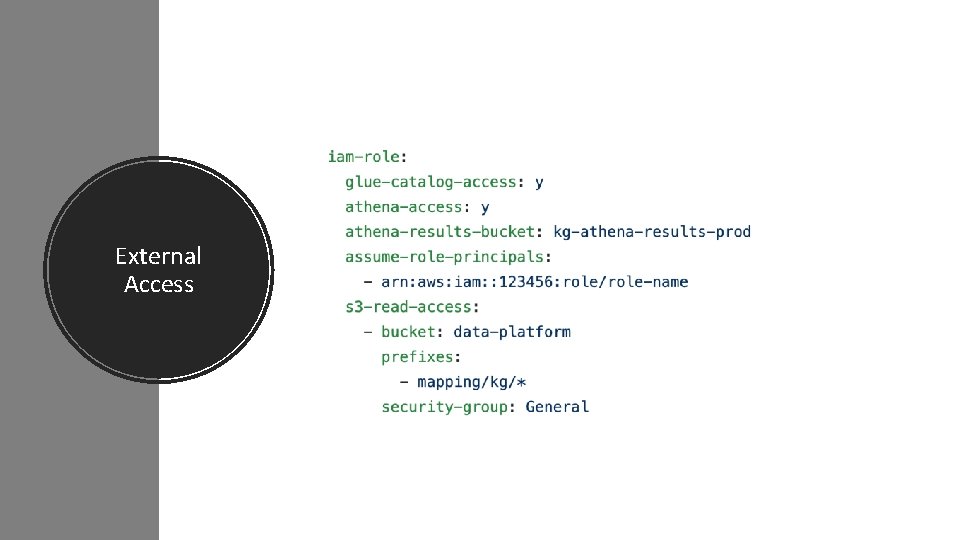
External Access
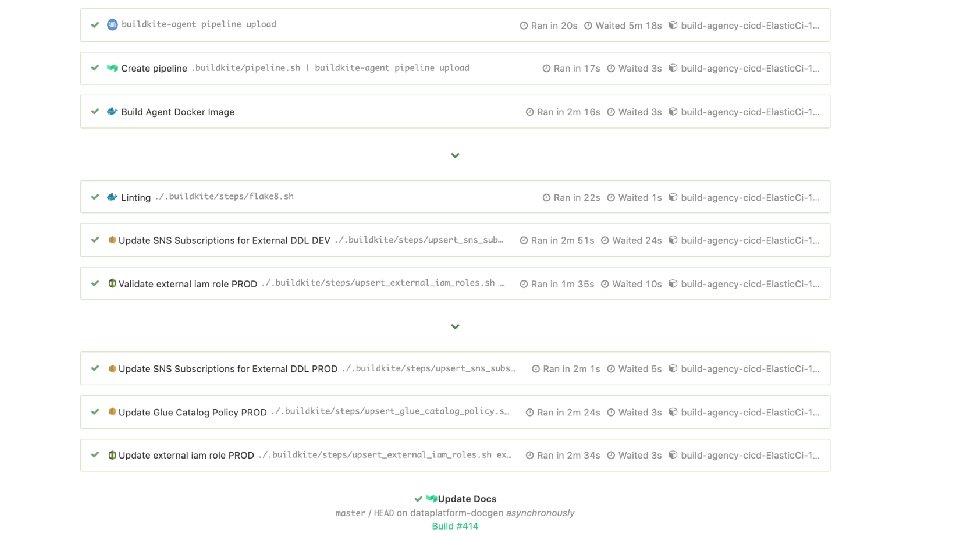
103 contributors on Git. Hub < 1 minute to deploy changes to lambda functions 15 minutes to deploy changes to Spark > 40 deployments per day
Continuous Delivery If it hurts, do it more frequently, and bring the pain forward.
You build it, you run it Dev. Ops Culture Autonomous Teams Infrastructure as Code Continuous Delivery
Build quality in Continuous Delivery Principles Work in small batches Computers perform repetitive tasks; people solve problems Relentlessly pursue continuous improvement Everyone is responsible
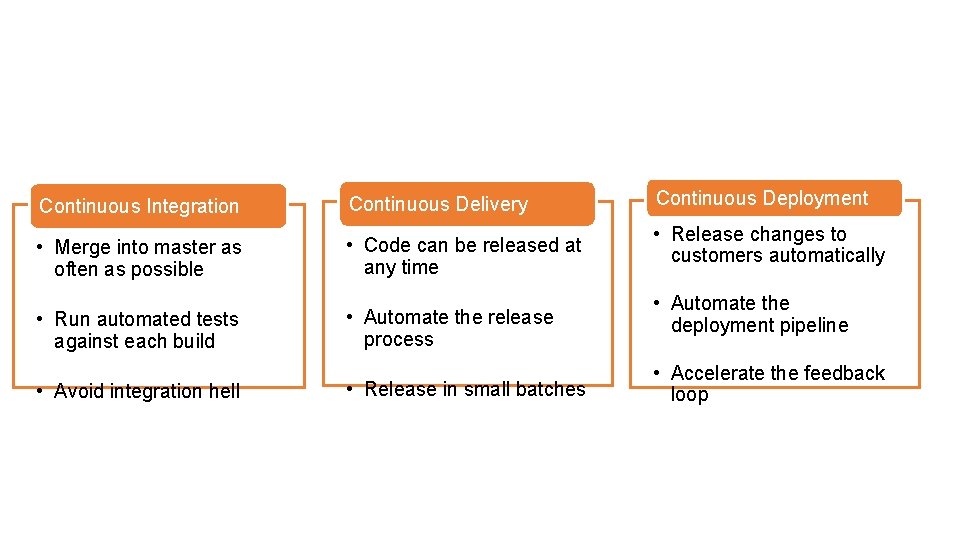
Continuous Integration Microservices Architecture • Merge into master as often as possible • Run automated tests against each build • Avoid integration hell Continuous Delivery • Code can be released at any time • Automate the release process • Release in small batches Continuous Deployment • Release changes to customers automatically • Automate the deployment pipeline • Accelerate the feedback loop
Deployment Pipeline – Lambda Functions Git Commit - Run Unit Tests Deploy to Production
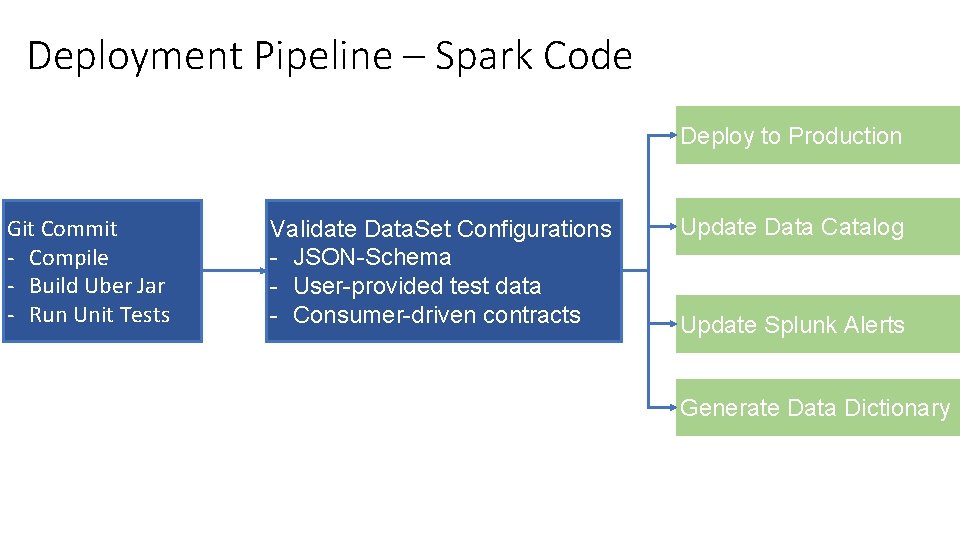
Deployment Pipeline – Spark Code Deploy to Production Git Commit - Compile - Build Uber Jar - Run Unit Tests Validate Data. Set Configurations - JSON-Schema - User-provided test data - Consumer-driven contracts Update Data Catalog Update Splunk Alerts Generate Data Dictionary
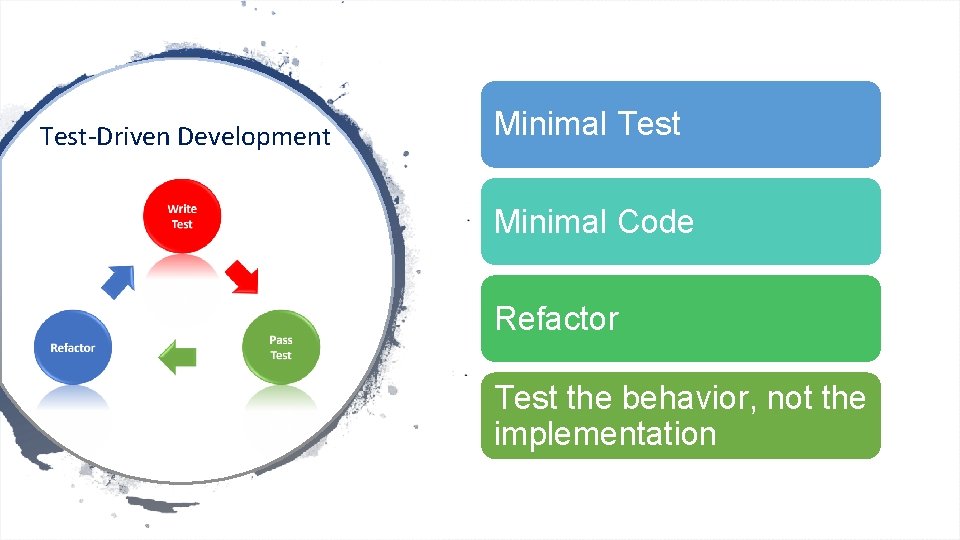
Test-Driven Development Minimal Test Minimal Code Refactor Test the behavior, not the implementation
Spreading TDD Promote Pair Programming Run a Code Retreat • Full day event, 4 -6 exercises • Conway’s Game of Life • Delete code at the end of each round • Change partners at each round • New restriction at each round
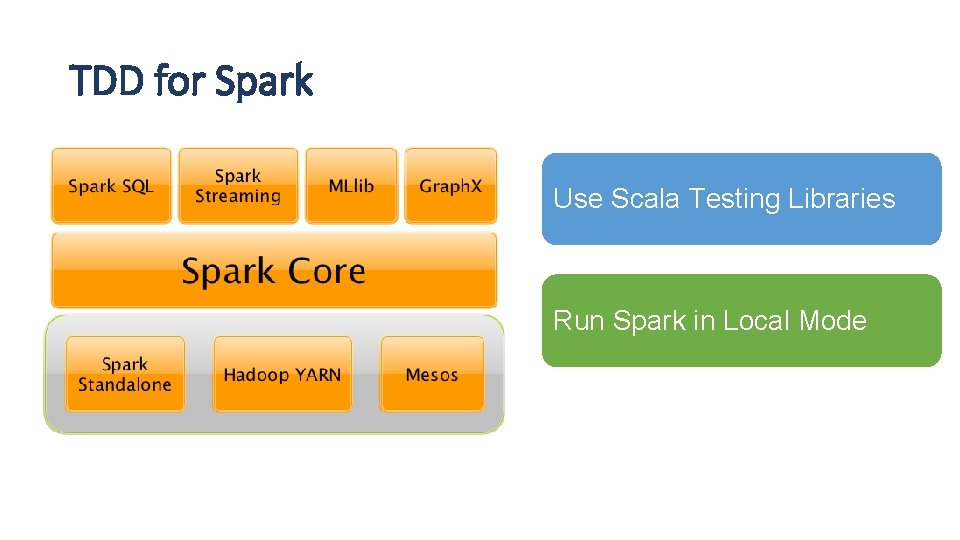
TDD for Spark Use Scala Testing Libraries Run Spark in Local Mode
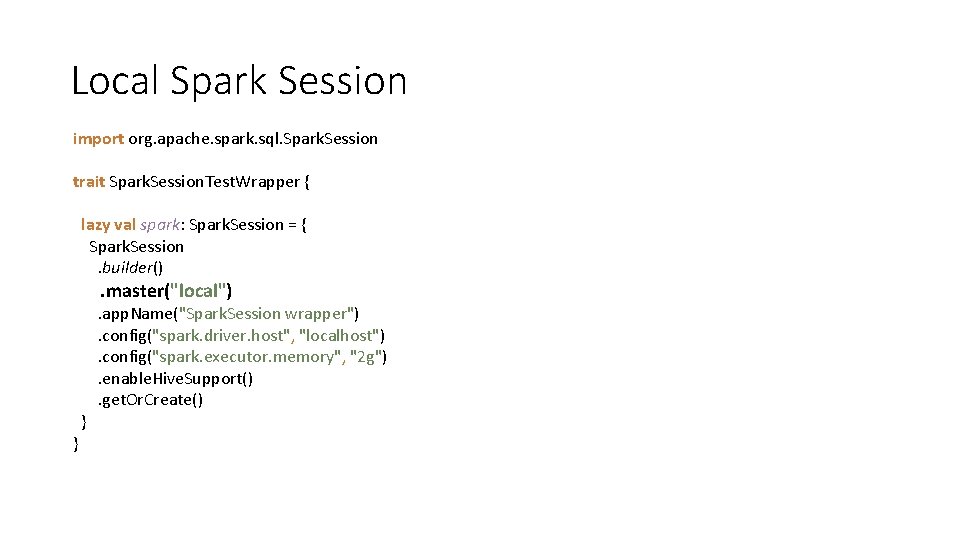
Local Spark Session import org. apache. spark. sql. Spark. Session trait Spark. Session. Test. Wrapper { lazy val spark: Spark. Session = { Spark. Session. builder() . master("local") } } . app. Name("Spark. Session wrapper"). config("spark. driver. host", "localhost"). config("spark. executor. memory", "2 g"). enable. Hive. Support(). get. Or. Create()
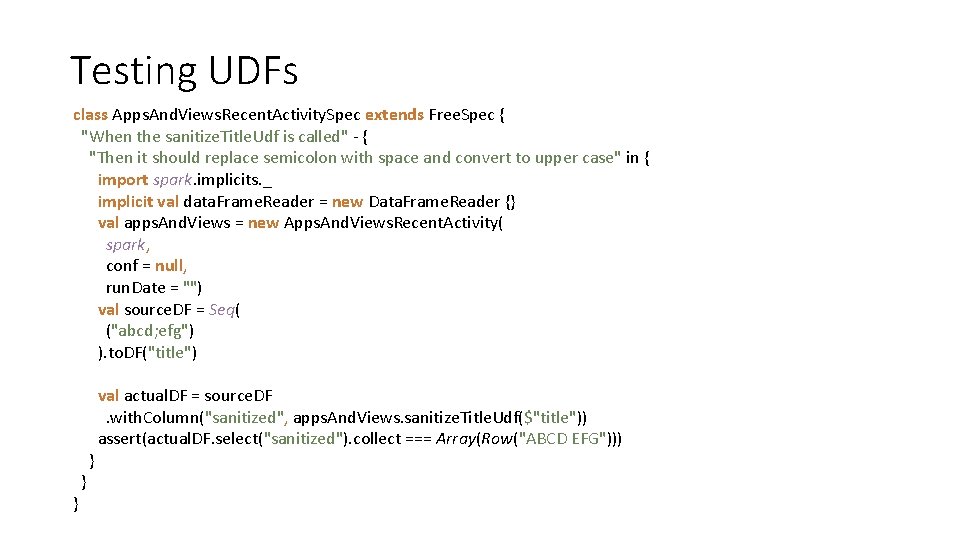
Testing UDFs class Apps. And. Views. Recent. Activity. Spec extends Free. Spec { "When the sanitize. Title. Udf is called" - { "Then it should replace semicolon with space and convert to upper case" in { import spark. implicits. _ implicit val data. Frame. Reader = new Data. Frame. Reader {} val apps. And. Views = new Apps. And. Views. Recent. Activity( spark, conf = null, run. Date = "") val source. DF = Seq( ("abcd; efg") ). to. DF("title") } } } val actual. DF = source. DF. with. Column("sanitized", apps. And. Views. sanitize. Title. Udf($"title")) assert(actual. DF. select("sanitized"). collect === Array(Row("ABCD EFG")))
Testing Spark Queries Create Sample Input File Mocking Data. Frames • • • Case Class for each data type Test. Data. Factory Mock spark. read Compile-time checks More readable code
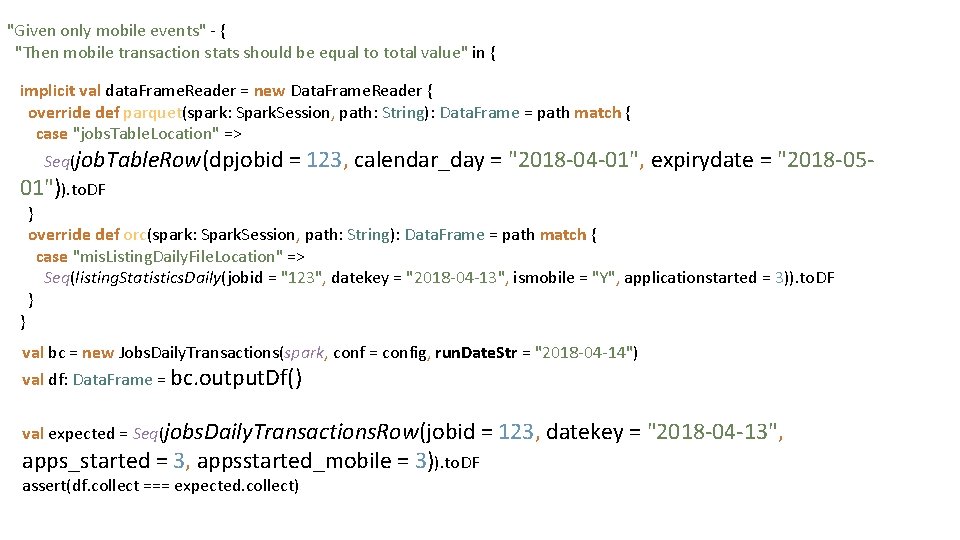
"Given only mobile events" - { "Then mobile transaction stats should be equal to total value" in { implicit val data. Frame. Reader = new Data. Frame. Reader { override def parquet(spark: Spark. Session, path: String): Data. Frame = path match { case "jobs. Table. Location" => Seq(job. Table. Row(dpjobid 01")). to. DF } = 123, calendar_day = "2018 -04 -01", expirydate = "2018 -05 - } override def orc(spark: Spark. Session, path: String): Data. Frame = path match { case "mis. Listing. Daily. File. Location" => Seq(listing. Statistics. Daily(jobid = "123", datekey = "2018 -04 -13", ismobile = "Y", applicationstarted = 3)). to. DF } val bc = new Jobs. Daily. Transactions(spark, conf = config, run. Date. Str = "2018 -04 -14") val df: Data. Frame = bc. output. Df() val expected = Seq(jobs. Daily. Transactions. Row(jobid apps_started = 3, appsstarted_mobile = 3)). to. DF assert(df. collect === expected. collect) = 123, datekey = "2018 -04 -13",
Integration Test: Golden Data A snapshot of source data Store the expected output Make queries deterministic Pass run-date to queries
Learnings Test Monitoring & Alerting Single Responsibility Principle Idempotence Automate! No Click-Ops Short Deployment Times
Thank You
- Slides: 25