
BL 542 Parallel Computing 1 Chapter 1 Parallel
BİL 542 Parallel Computing 1
Chapter 1 Parallel Programming 2
Why Use Parallel Computing? n n n Main Reasons: Save time and/or money: In theory, throwing more resources at a task will shorten its time to completion, with potential cost savings. Parallel clusters can be built from cheap, commodity components. Solve larger problems: Many problems are so large and/or complex that it is impractical or impossible to solve them on a single computer, especially given limited computer memory. For example: ¨ Web search engines/databases processing millions of transactions per second 3
Demand for Computational Speed n n n Continual demand for greater computational speed from a computer system than is currently possible Areas requiring great computational speed include numerical modeling and simulation of scientific and engineering problems. Computations must be completed within a “reasonable” time period. 4
Grand Challenge Problems One that cannot be solved in a reasonable amount of time with today’s computers. Obviously, an execution time of 10 years is always unreasonable. Examples ¨ ¨ ¨ ¨ Databases, data mining Oil exploration Web search engines, web based business services Medical imaging and diagnosis Pharmaceutical design Management of national and multi-national corporations Financial and economic modeling Advanced graphics and virtual reality, particularly in the entertainment industry Networked video and multi-media technologies Collaborative work environments Modeling large DNA structures Global weather forecasting Modeling motion of astronomical bodies. 5
Weather Forecasting n Atmosphere modeled by dividing it into 3 dimensional cells. n Calculations of each cell repeated many times to model passage of time. 6
Global Weather Forecasting Example n Suppose whole global atmosphere divided into cells of size 1 mile to a height of 10 miles (10 cells high) - about 5 108 cells. n Suppose each calculation requires 200 floating point operations. In one time step, 1011 floating point operations necessary. n To forecast the weather over 7 days using 1 -minute intervals, a computer operating at 1 Gflops (109 floating point operations/s) takes 106 seconds or over 10 days. n To perform calculation in 5 minutes requires computer operating at 3. 4 Tflops (3. 4 1012 floating point operations/sec). 7
Modeling Motion of Astronomical Bodies n Each body attracted to each other body by gravitational forces. Movement of each body predicted by calculating total force on each body. n With N bodies, N - 1 forces to calculate for each body, or approx. N 2 calculations. (N log 2 N for an efficient approx. algorithm. ) n After determining new positions of bodies, calculations repeated. 8
Modeling Motion of Astronomical Bodies n A galaxy might have, say, 1011 stars. n Even if each calculation done in 1 ms (extremely optimistic figure), it takes 109 years for one iteration using N 2 algorithm and almost a year for one iteration using an efficient N log 2 N approximate algorithm. 9
Astrophysical N-body simulation by Scott Linssen (undergraduate 10 UNC-Charlotte student).
Parallel Computing n Using more than one computer, or a computer with more than one processor, to solve a problem. Motives n n Usually faster computation - very simple idea - that n computers operating simultaneously can achieve the result n times faster - it will not be n times faster for various reasons. Other motives include: fault tolerance, larger amount of memory available, . . . 11
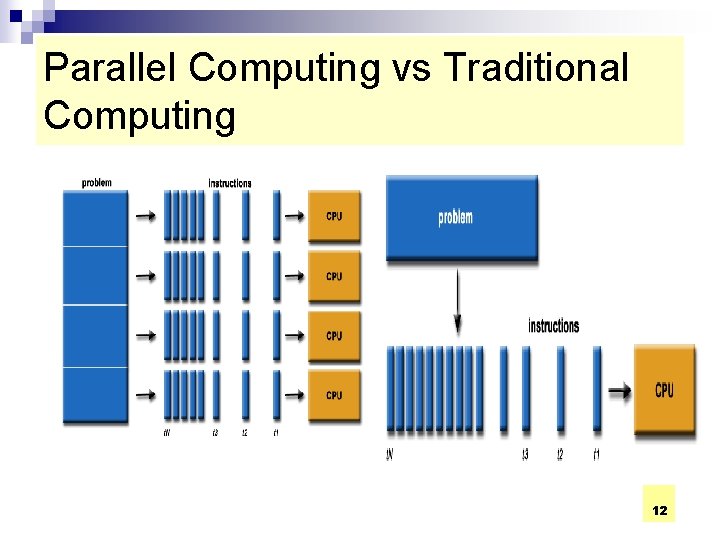
Parallel Computing vs Traditional Computing 12
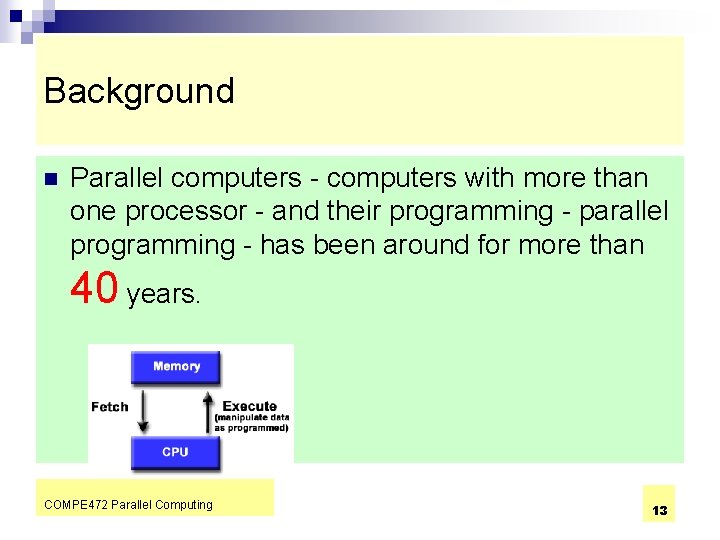
Background n Parallel computers - computers with more than one processor - and their programming - parallel programming - has been around for more than 40 years. COMPE 472 Parallel Computing 13
Gill writes in 1958: “. . . There is therefore nothing new in the idea of parallel programming, but its application to computers. The author cannot believe that there will be any insuperable difficulty in extending it to computers. It is not to be expected that the necessary programming techniques will be worked out overnight. Much experimenting remains to be done. After all, the techniques that are commonly used in programming today were only won at the cost of considerable toil several years ago. In fact the advent of parallel programming may do something to revive the pioneering spirit in programming which seems at the present to be degenerating into a rather dull and routine occupation. . . ” Gill, S. (1958), “Parallel Programming, ” The Computer Journal, vol. 1, April, pp. 2 -10. COMPE 472 Parallel Computing 14
COMPE 472 Parallel Computing 15
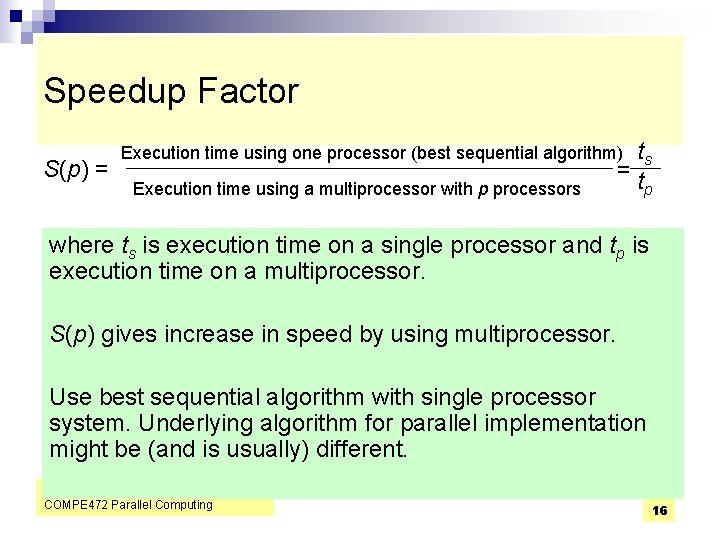
Speedup Factor S(p) = ts =t p Execution time using one processor (best sequential algorithm) Execution time using a multiprocessor with p processors where ts is execution time on a single processor and tp is execution time on a multiprocessor. S(p) gives increase in speed by using multiprocessor. Use best sequential algorithm with single processor system. Underlying algorithm for parallel implementation might be (and is usually) different. COMPE 472 Parallel Computing 16
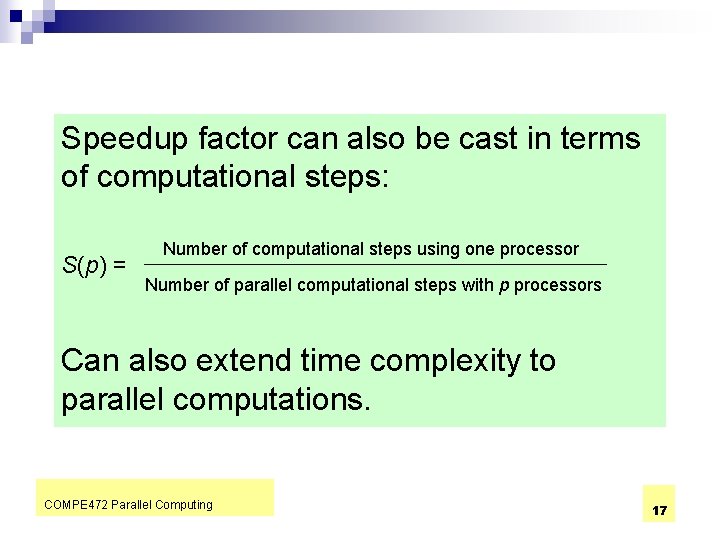
Speedup factor can also be cast in terms of computational steps: S(p) = Number of computational steps using one processor Number of parallel computational steps with p processors Can also extend time complexity to parallel computations. COMPE 472 Parallel Computing 17
Maximum Speedup Maximum speedup is usually p with p processors (linear speedup). Possible to get superlinear speedup (greater than p) but usually a specific reason such as: n Extra memory in multiprocessor system n Nondeterministic algorithm COMPE 472 Parallel Computing 18
Maximum Speedup n Factors limiting speedup ¨ Communication time ¨ Extra computations in the parallel algorithm (reevaluation of constants locally) ¨ Idle time of some processors COMPE 472 Parallel Computing 19
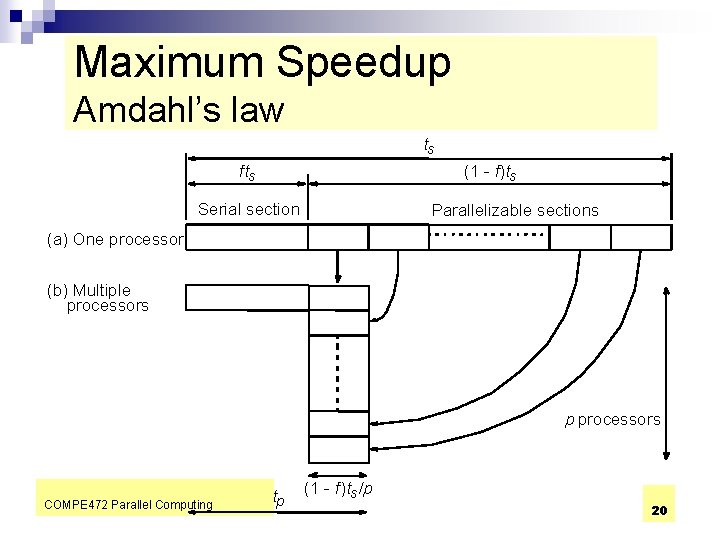
Maximum Speedup Amdahl’s law ts fts (1 - f)ts Serial section Parallelizable sections (a) One processor (b) Multiple processors p processors COMPE 472 Parallel Computing tp (1 - f)ts /p 20
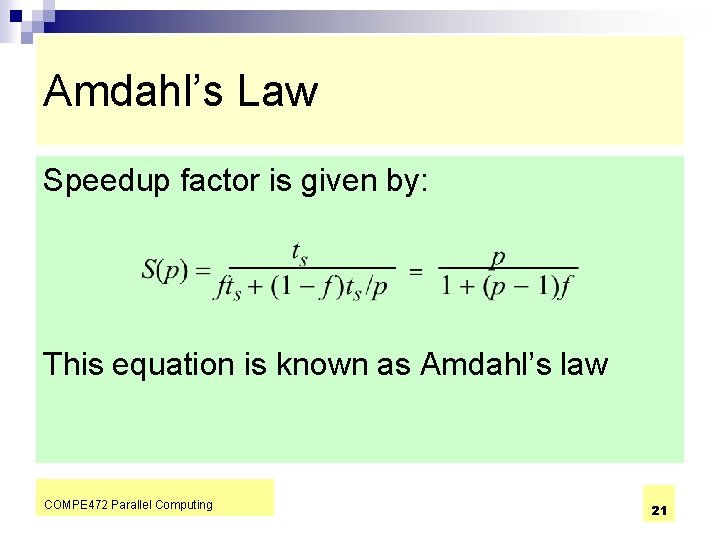
Amdahl’s Law Speedup factor is given by: This equation is known as Amdahl’s law COMPE 472 Parallel Computing 21
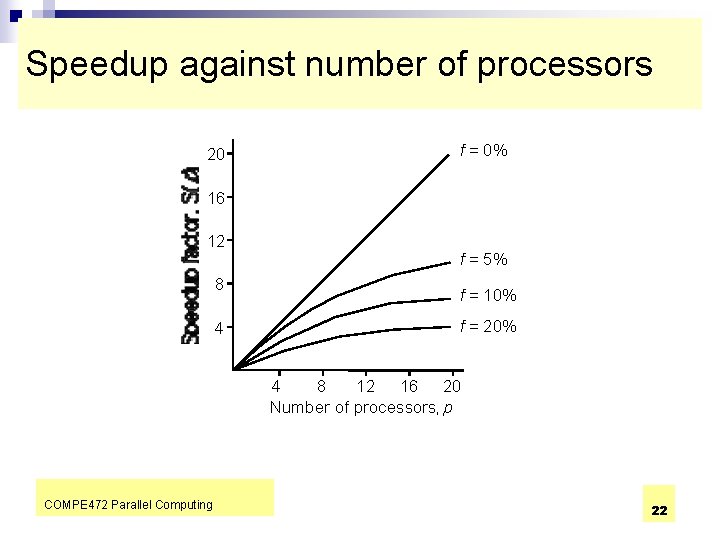
Speedup against number of processors 20 f = 0% 16 12 8 4 f = 5% f = 10% f = 20% 4 8 12 16 20 Number of processors, p COMPE 472 Parallel Computing 22
Amdahl’s law Even with infinite number of processors, maximum speedup is limited to 1/f. Example With only 5% of computation being serial, maximum speedup is 20, irrespective of number of processors. COMPE 472 Parallel Computing 23
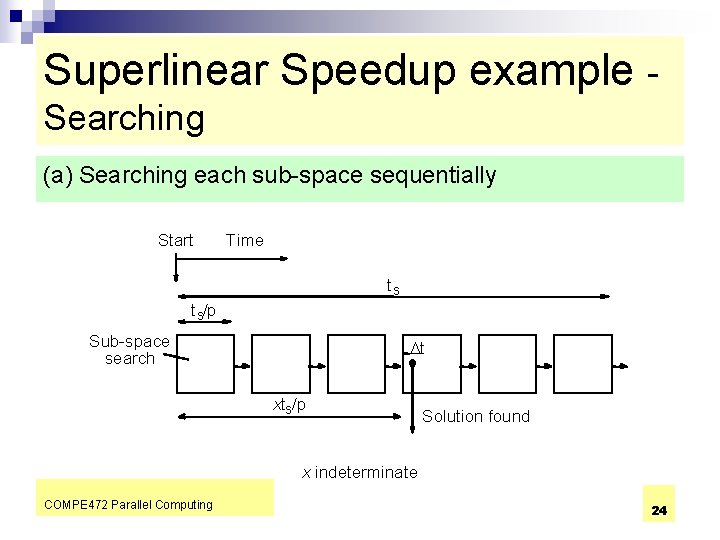
Superlinear Speedup example - Searching (a) Searching each sub-space sequentially Start Time ts t s/p Sub-space search Dt xts/p Solution found x indeterminate COMPE 472 Parallel Computing 24
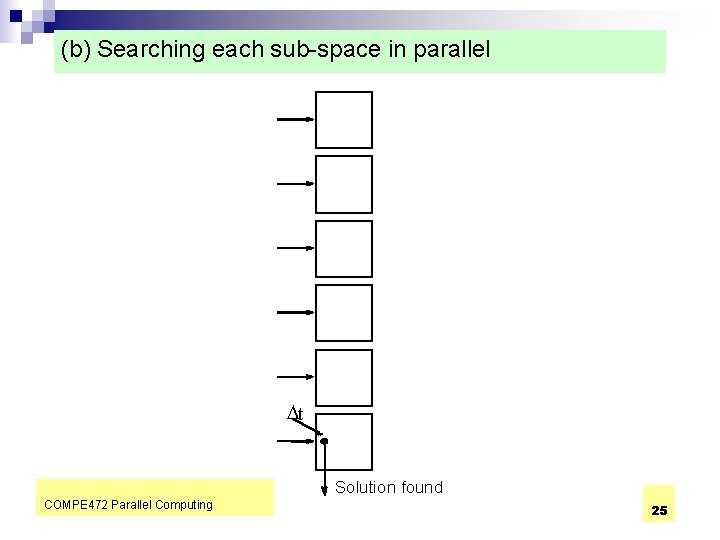
(b) Searching each sub-space in parallel Dt Solution found COMPE 472 Parallel Computing 25
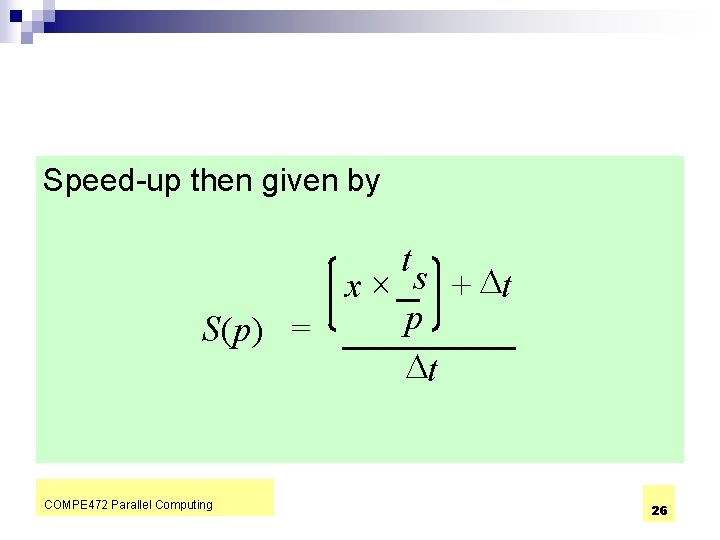
Speed-up then given by x S(p) = COMPE 472 Parallel Computing ts p Dt + Dt 26
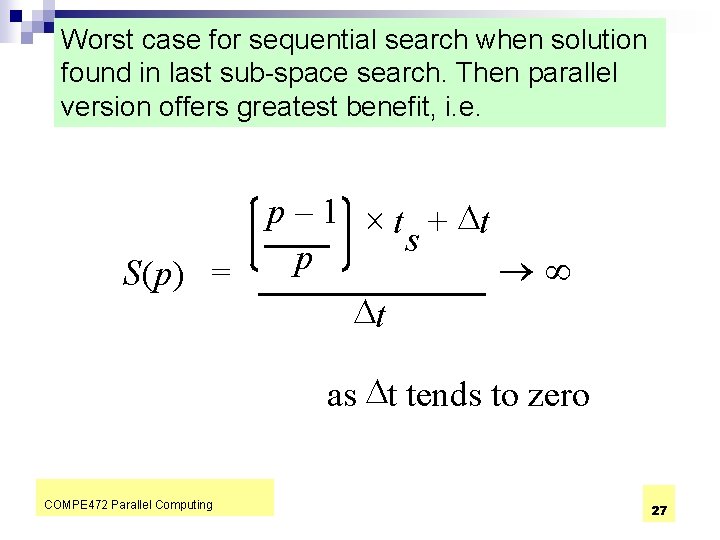
Worst case for sequential search when solution found in last sub-space search. Then parallel version offers greatest benefit, i. e. p – 1 t + Dt s p ®¥ S(p) = Dt as Dt tends to zero COMPE 472 Parallel Computing 27
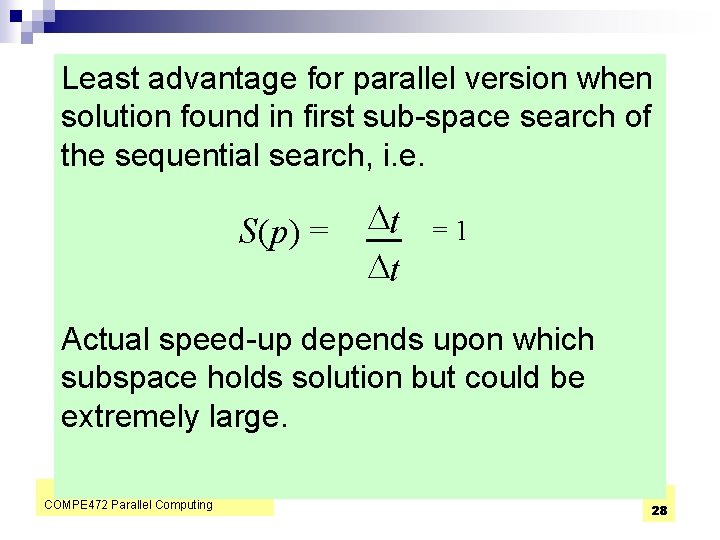
Least advantage for parallel version when solution found in first sub-space search of the sequential search, i. e. S(p) = Dt Dt = 1 Actual speed-up depends upon which subspace holds solution but could be extremely large. COMPE 472 Parallel Computing 28
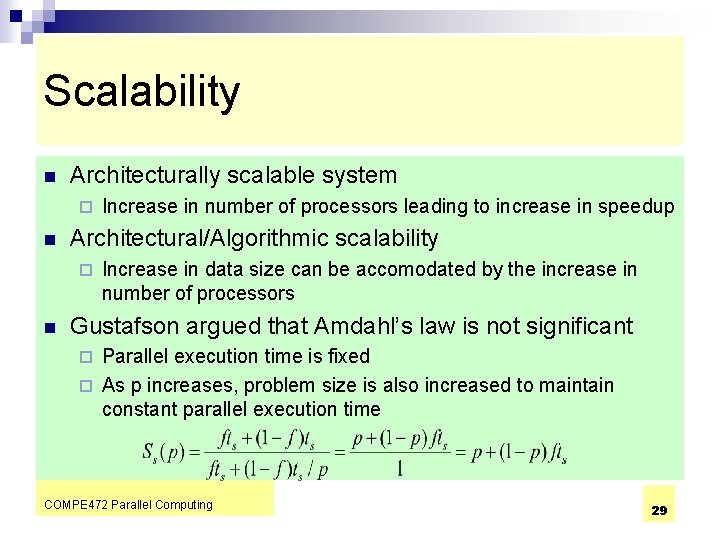
Scalability n Architecturally scalable system ¨ n Architectural/Algorithmic scalability ¨ n Increase in number of processors leading to increase in speedup Increase in data size can be accomodated by the increase in number of processors Gustafson argued that Amdahl’s law is not significant Parallel execution time is fixed ¨ As p increases, problem size is also increased to maintain constant parallel execution time ¨ COMPE 472 Parallel Computing 29

Message-Passing Computations n In a message passing environment, computation time consists of two parts: n The ratio below can be used as a metric: COMPE 472 Parallel Computing 30
Types of Parallel Computers Two principal types: n Shared memory multiprocessor n Distributed memory multicomputer COMPE 472 Parallel Computing 31
Shared Memory Multiprocessor COMPE 472 Parallel Computing 32
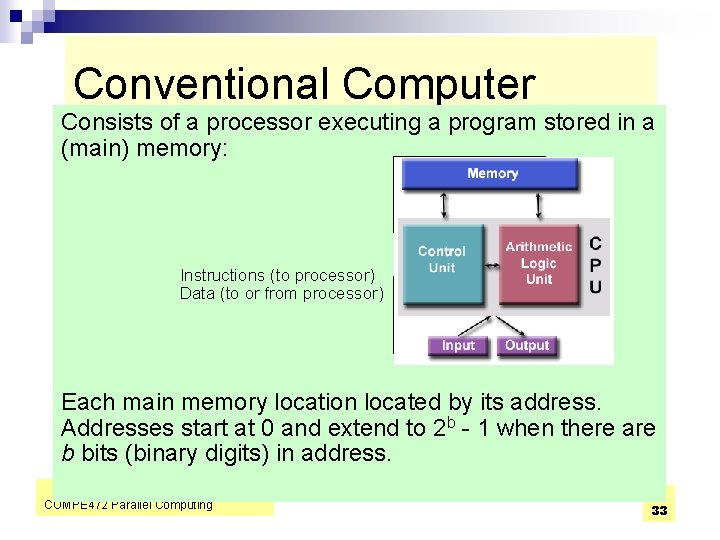
Conventional Computer Consists of a processor executing a program stored in a (main) memory: Main memory Instructions (to processor) Data (to or from processor) Processor Each main memory location located by its address. Addresses start at 0 and extend to 2 b - 1 when there are b bits (binary digits) in address. COMPE 472 Parallel Computing 33
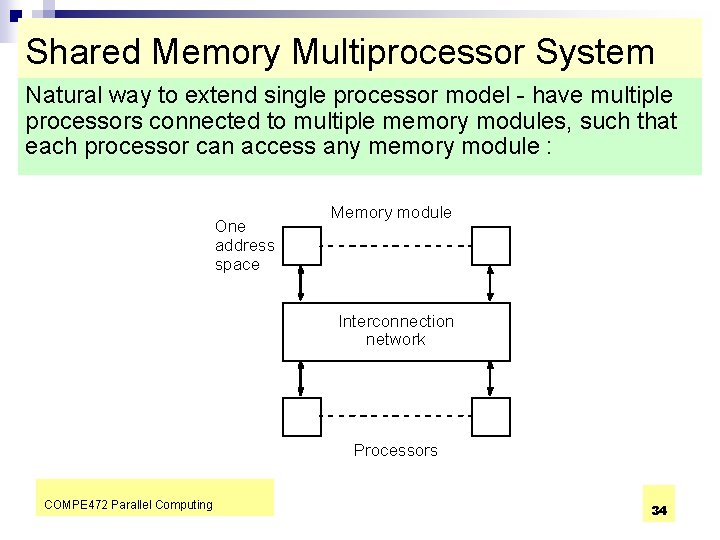
Shared Memory Multiprocessor System Natural way to extend single processor model - have multiple processors connected to multiple memory modules, such that each processor can access any memory module : One address space Memory module Interconnection network Processors COMPE 472 Parallel Computing 34
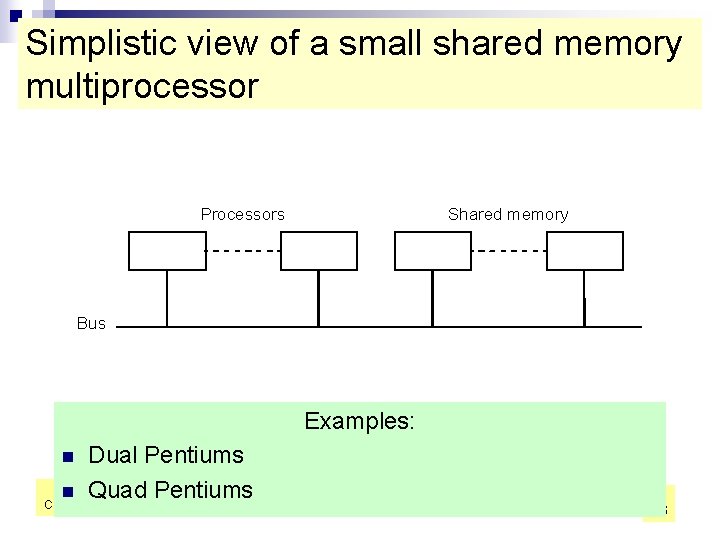
Simplistic view of a small shared memory multiprocessor Processors Shared memory Bus Examples: Dual Pentiums n Quad Pentiums COMPE 472 Parallel Computing n 35
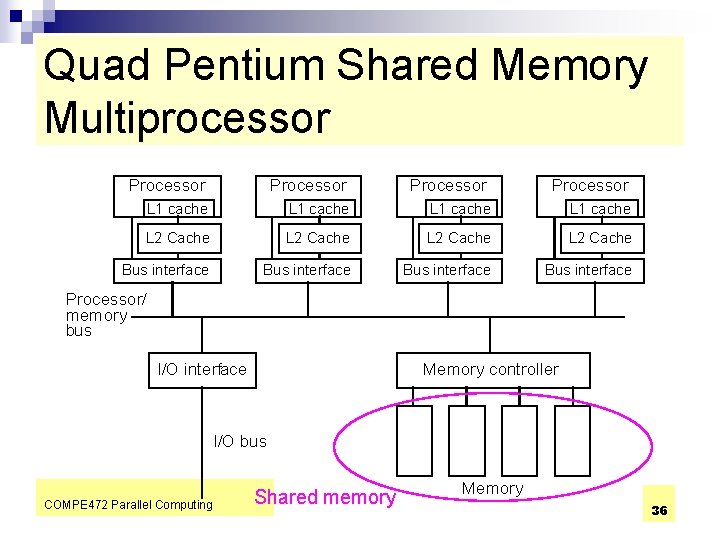
Quad Pentium Shared Memory Multiprocessor Processor L 1 cache L 2 Cache Bus interface Processor/ memory bus I/O interface Memory controller I/O bus COMPE 472 Parallel Computing Shared memory Memory 36

Programming Shared Memory Multiprocessors n Threads - programmer decomposes program into individual parallel sequences, (threads), each being able to access variables declared outside threads. Example Pthreads n Sequential programming language with preprocessor compiler directives to declare shared variables and specify parallelism. Example Open. MP - industry standard - needs Open. MP compiler COMPE 472 Parallel Computing 37
n Sequential programming language with added syntax to declare shared variables and specify parallelism. Example UPC (Unified Parallel C) - needs a UPC compiler. n Parallel programming language with syntax to express parallelism - compiler creates executable code for each processor (not now common) n Sequential programming language and ask parallelizing compiler to convert it into parallel executable code. - also not now common COMPE 472 Parallel Computing 38
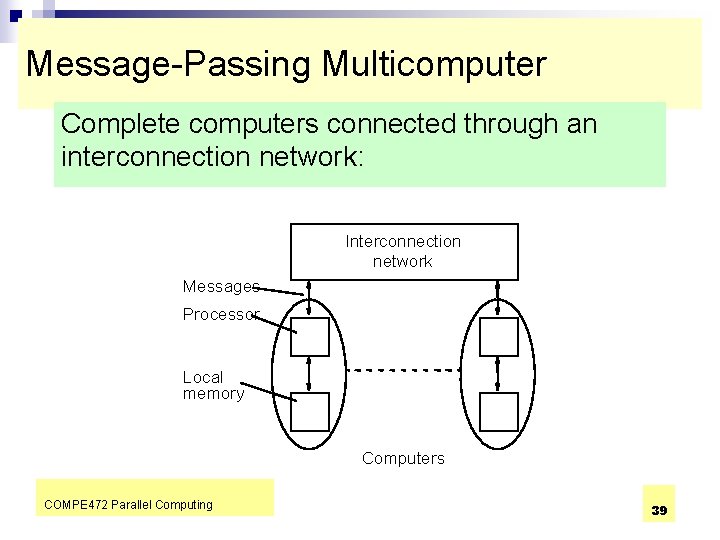
Message-Passing Multicomputer Complete computers connected through an interconnection network: Interconnection network Messages Processor Local memory Computers COMPE 472 Parallel Computing 39
Interconnection Networks n n Limited and exhaustive interconnections 2 - and 3 -dimensional meshes Hypercube (not now common) Using Switches: ¨ Crossbar ¨ Trees ¨ Multistage interconnection networks n Peer-to-peer c(c-1)/2 links with c processors COMPE 472 Parallel Computing 40
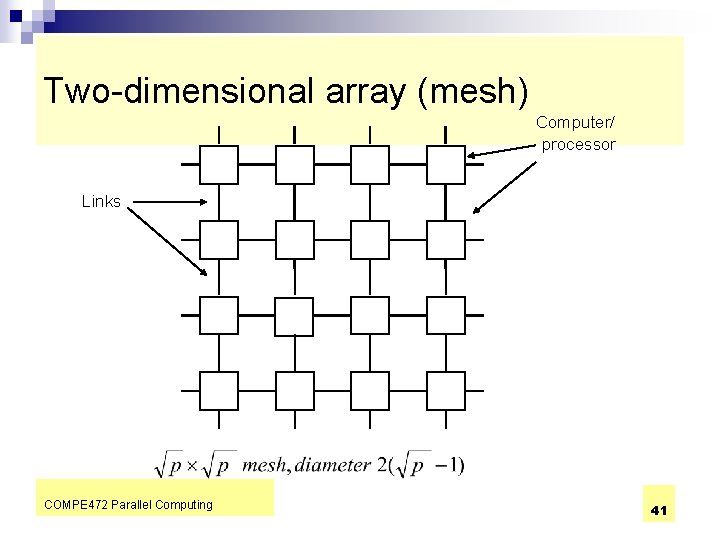
Two-dimensional array (mesh) Computer/ processor Links COMPE 472 Parallel Computing 41
Three-dimensional hypercube n In a d-dim hypercube, each node connects to one node in each dimension. Above a 3 -d hypercube is shown. Each node is assigned a 3 bit address. Address difference between nodes is only 1 bit. Diameter is log 2 p COMPE 472 Parallel Computing 42
Four-dimensional hypercube Hypercubes popular in 1980’s - not now COMPE 472 Parallel Computing 43
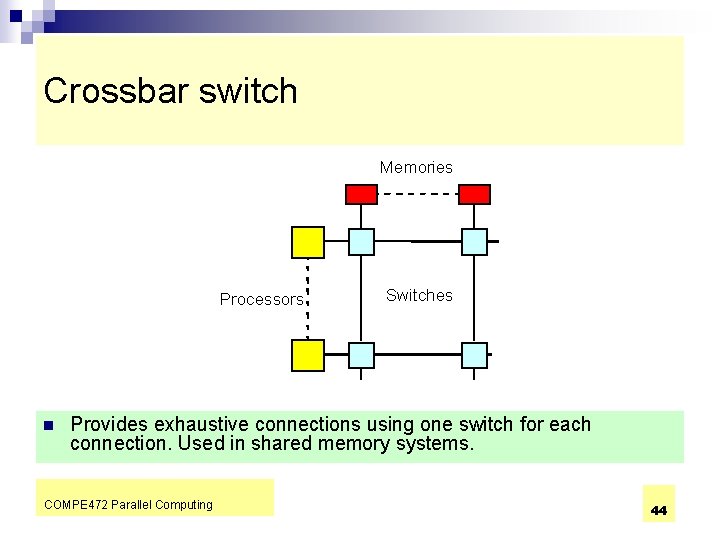
Crossbar switch Memories Processors n Switches Provides exhaustive connections using one switch for each connection. Used in shared memory systems. COMPE 472 Parallel Computing 44
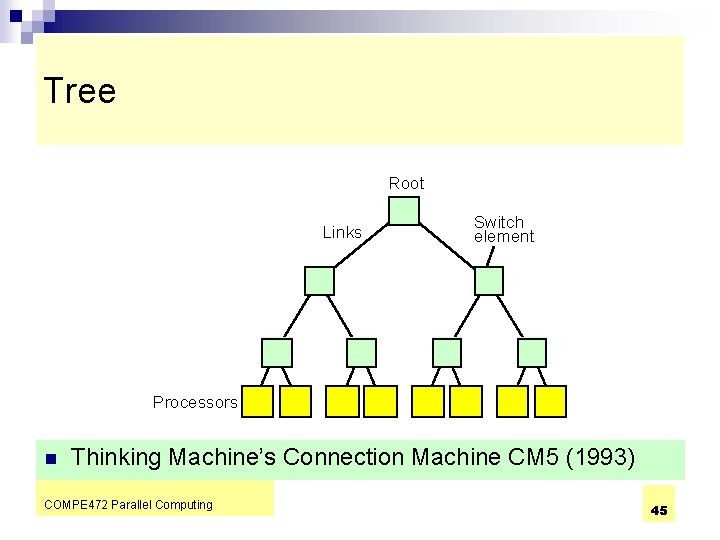
Tree Root Links Switch element Processors n Thinking Machine’s Connection Machine CM 5 (1993) COMPE 472 Parallel Computing 45
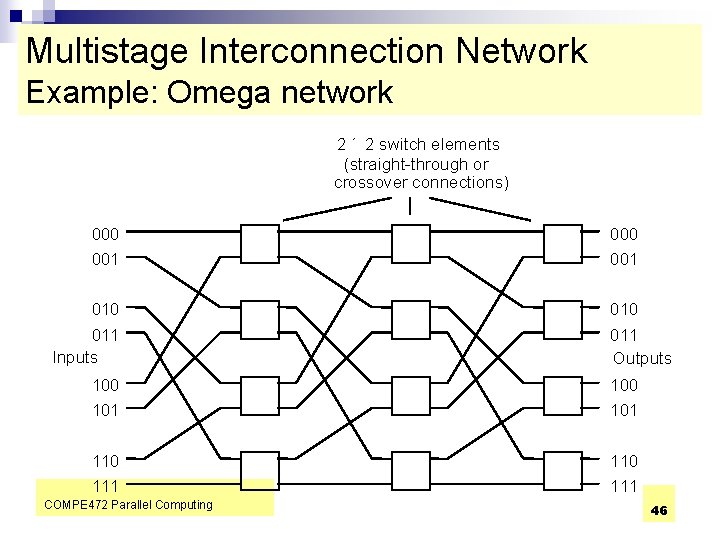
Multistage Interconnection Network Example: Omega network 2 ´ 2 switch elements (straight-through or crossover connections) 000 001 010 011 Inputs 000 001 010 011 Outputs 100 101 110 111 COMPE 472 Parallel Computing 46
Communication Methods n Circuit switching ¨ Establish the path ¨ Maintain/Reserve links for message passing ¨ Simple telephone system is an example ¨ Used in early multicomputers (INTEL IPSC-2) n Packet switching ¨ Divide message into “packets” ¨ Packet = Source/Dest addresses + Data ¨ Packet max size is known ¨ Mail system is an example COMPE 472 Parallel Computing 47
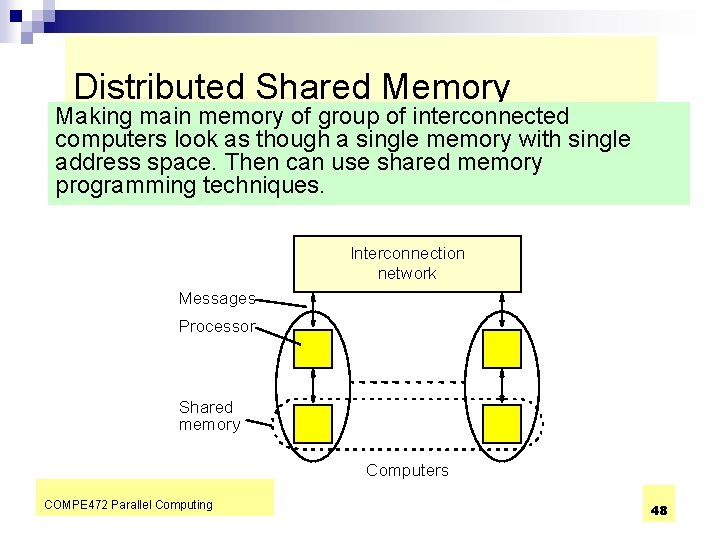
Distributed Shared Memory Making main memory of group of interconnected computers look as though a single memory with single address space. Then can use shared memory programming techniques. Interconnection network Messages Processor Shared memory Computers COMPE 472 Parallel Computing 48
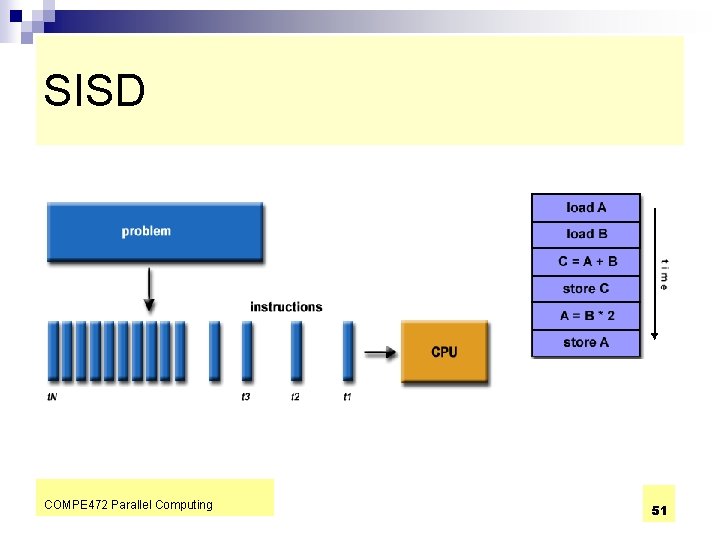
Flynn’s Classifications Flynn (1966) created a classification for computers based upon instruction streams and data streams: ¨ Single instruction stream-single data stream (SISD) computer Single processor computer - single stream of instructions generated from program. Instructions operate upon a single stream of data items. COMPE 472 Parallel Computing 49
Single Instruction, Single Data (SISD): • • • A serial (non-parallel) computer Single instruction: only one instruction stream is being acted on by the CPU during any one clock cycle Single data: only one data stream is being used as input during any one clock cycle Deterministic execution This is the oldest and until recently, the most prevalent form of computer Examples: most PCs, single CPU workstations and mainframes COMPE 472 Parallel Computing 50
SISD COMPE 472 Parallel Computing 51
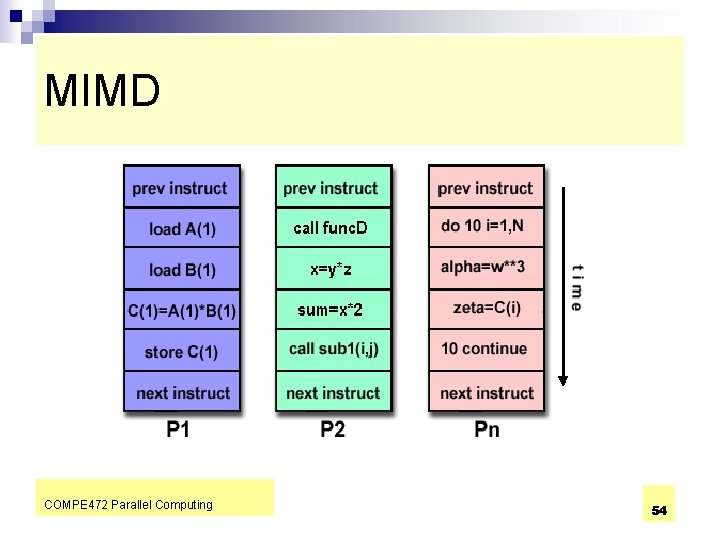
Multiple Instruction Stream-Multiple Data Stream (MIMD) Computer General-purpose multiprocessor system - each processor has a separate program and one instruction stream is generated from each program for each processor. Each instruction operates upon different data. Both the shared memory and the message-passing multiprocessors so far described are in the MIMD classification. COMPE 472 Parallel Computing 52
MIMD Multiple Instruction, Multiple Data (MIMD): n Currently, the most common type of parallel computer. Most modern computers fall into this category. n Multiple Instruction: every processor may be executing a different instruction stream n Multiple Data: every processor may be working with a different data stream n Execution can be synchronous or asynchronous, deterministic or non-deterministic n Examples: most current supercomputers, networked parallel computer "grids" and multi-processor SMP computers - including some types of PCs. COMPE 472 Parallel Computing 53
MIMD COMPE 472 Parallel Computing 54
Single Instruction Stream-Multiple Data Stream (SIMD) Computer n A specially designed computer - a single instruction stream from a single program, but multiple data streams exist. Instructions from program broadcast to more than one processor. Each processor executes same instruction in synchronism, but using different data. n Developed because a number of important applications that mostly operate upon arrays of data. COMPE 472 Parallel Computing 55
SIMD Single Instruction, Multiple Data (SIMD): n A type of parallel computer n Single instruction: All processing units execute the same instruction at any given clock cycle n Multiple data: Each processing unit can operate on a different data element n This type of machine typically has an instruction dispatcher, a very highbandwidth internal network, and a very large array of very small-capacity instruction units. n Best suited for specialized problems characterized by a high degree of regularity, such as image processing. n Synchronous (lockstep) and deterministic execution n Two varieties: Processor Arrays and Vector Pipelines n Examples: ¨ n Processor Arrays: Connection Machine CM-2, Maspar MP-1, MP-2 Vector Pipelines: IBM 9000, Cray C 90, Fujitsu VP, NEC SX-2, Hitachi S 820 COMPE 472 Parallel Computing 56
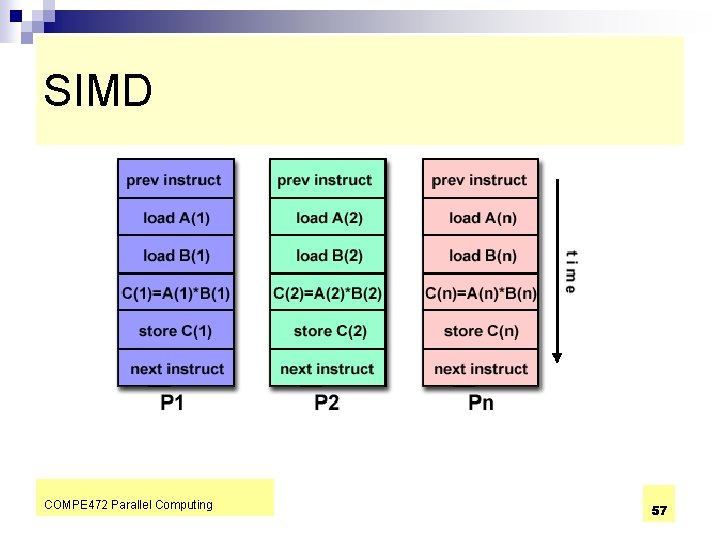
SIMD COMPE 472 Parallel Computing 57
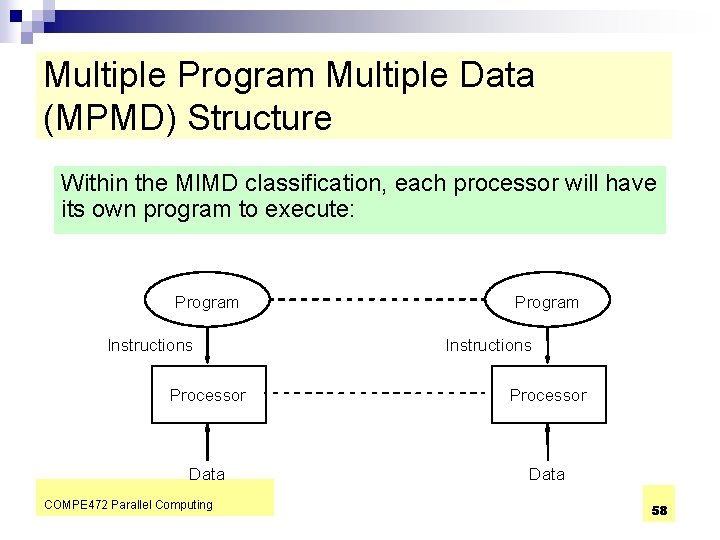
Multiple Program Multiple Data (MPMD) Structure Within the MIMD classification, each processor will have its own program to execute: Program Instructions Processor Data COMPE 472 Parallel Computing 58
Single Program Multiple Data (SPMD) Structure Single source program written and each processor executes its personal copy of this program, although independently and not in synchronism. Source program can be constructed so that parts of the program are executed by certain computers and not others depending upon the identity of the computer. COMPE 472 Parallel Computing 59
Networked Computers as a Computing Platform n A network of computers became a very attractive alternative to expensive supercomputers and parallel computer systems for high-performance computing in early 1990’s. n Several early projects. Notable: ¨ ¨ Berkeley NOW (network of workstations) project. NASA Beowulf project. COMPE 472 Parallel Computing 60
Key advantages: n Very high performance workstations and PCs readily available at low cost. n The latest processors can easily be incorporated into the system as they become available. n Existing software can be used or modified. COMPE 472 Parallel Computing 61
Software Tools for Clusters n Based upon Message Passing Parallel Programming: n Parallel Virtual Machine (PVM) - developed in late 1980’s. Became very popular. n Message-Passing Interface (MPI) - standard defined in 1990 s. n Both provide a set of user-level libraries for message passing. Use with regular programming languages (C, C++, . . . ). COMPE 472 Parallel Computing 62
Beowulf Clusters* n A group of interconnected “commodity” computers achieving high performance with low cost. n Typically using commodity interconnects - high speed Ethernet, and Linux OS. * Beowulf comes from name given by NASA Goddard Space Flight Center cluster project. COMPE 472 Parallel Computing 63

Cluster Interconnects n n Originally fast Ethernet on low cost clusters Gigabit Ethernet - easy upgrade path More Specialized/Higher Performance n n n Myrinet - 2. 4 Gbits/sec - disadvantage: single vendor c. Lan SCI (Scalable Coherent Interface) QNet Infiniband - may be important as infininband interfaces may be integrated on next generation PCs COMPE 472 Parallel Computing 64

Dedicated cluster with a master node Dedicated Cluster User Compute nodes Master node Up link Switch COMPE 472 Parallel Computing 2 nd Ethernet interface External network 65
- Slides: 65