
ATLAS CMS Online Clouds exploit the Experiments online
- Slides: 24
ATLAS & CMS Online Clouds ü exploit the Experiments’ online farms for offline activities during the LS 1 & beyond Olivier Chaze (CERN-PH-CMD) & Alessandro Di Girolamo (CERN IT-SDC-OL) IT-SDC: Support for Distributed Computing
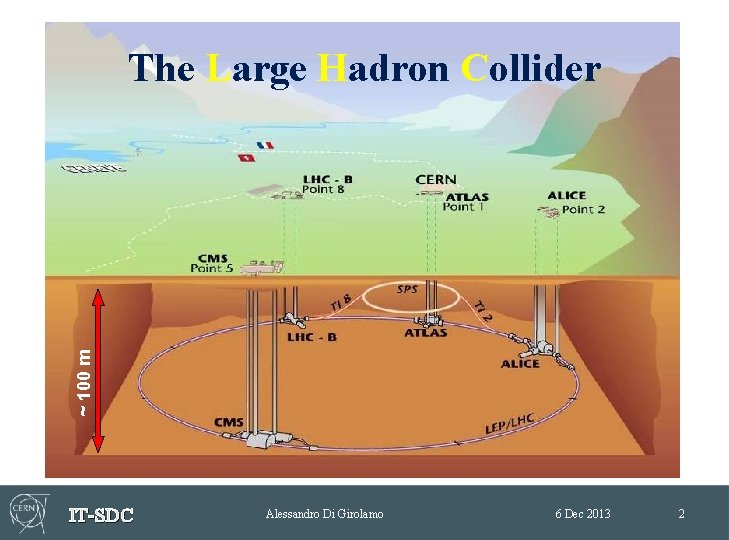
~ 100 m The Large Hadron Collider IT-SDC Alessandro Di Girolamo 6 Dec 2013 2
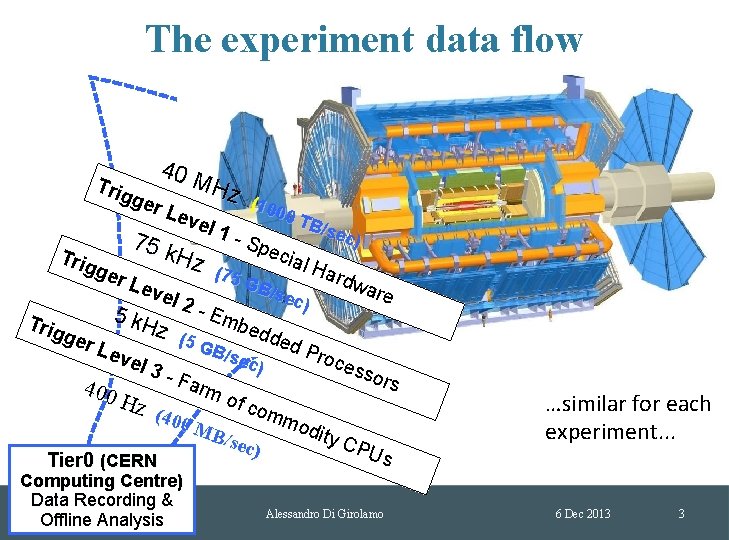
The experiment data flow 40 M Trig Hz ger Lev el 1 75 k Trig Hz ger L (100 0 TB /sec - Sp ) ecia l Ha (75 rdw GB eve are /sec l 2) E 5 k. H mbe z dde ger (5 G d. P Lev B/s roce ec) el 3 sso - Fa rs rm 400 of c Hz omm (40 0 Trig Tier 0 (CERN Computing Centre) Data Recording & IT-SDC Offline Analysis MB /sec ) odit y. C PUs Alessandro Di Girolamo …similar for each experiment. . . 6 Dec 2013 3
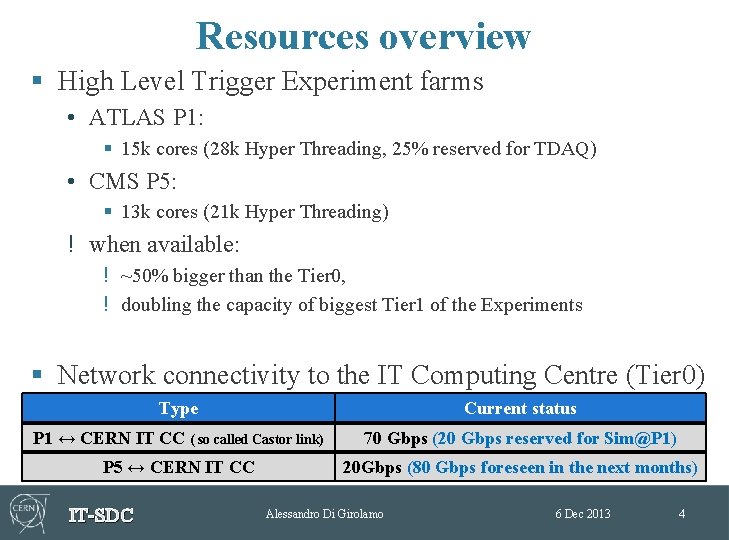
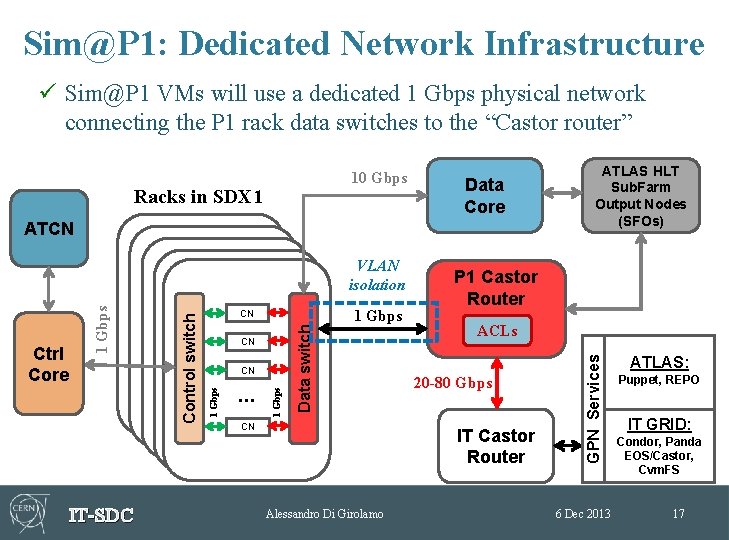
Resources overview § High Level Trigger Experiment farms • ATLAS P 1: § 15 k cores (28 k Hyper Threading, 25% reserved for TDAQ) • CMS P 5: § 13 k cores (21 k Hyper Threading) ! when available: ! ~50% bigger than the Tier 0, ! doubling the capacity of biggest Tier 1 of the Experiments § Network connectivity to the IT Computing Centre (Tier 0) Type Current status P 1 ↔ CERN IT CC ( so called Castor link) 70 Gbps (20 Gbps reserved for Sim@P 1) P 5 ↔ CERN IT CC 20 Gbps (80 Gbps foreseen in the next months) IT-SDC Alessandro Di Girolamo 6 Dec 2013 4
Why § Experiments always resource hungry: • ATLAS + CMS: more than 250 k jobs running in parallel § … exploit all the available resources! IT-SDC Alessandro Di Girolamo 6 Dec 2013 5
Teamwork § Experts from the Trigger & Data Acquisition teams of the Experiments § Experts from other institutes • BNL RACF, Imperial College … § Experts of WLCG (Worldwide LHC Computing Grid) IT-SDC Alessandro Di Girolamo 6 Dec 2013 6
Why Cloud? § Cloud as an overlay infrastructure • provides necessary management of VM resources • support & control of physical hosts remain with TDAQ • delegate Grid support § easy to quickly switch from HLT ↔ Grid • during LS 1: periodic full-scale test of TDAQ sw upgrade • can be used in the future also during short LHC stop § Open. Stack: common solution, big community! • CMS, ATLAS, BNL, CERN IT…. • sharing experiences • …and support if needed IT-SDC Alessandro Di Girolamo 6 Dec 2013 7
Open. Stack § Glance: VM base image storage and management • Central image repository (and distribution) for Nova § Nova: Central operations controller for hypervisors and VMs • CLI tools, VM scheduler, Compute node client § Network in multi-host mode for CMS § Horizon/ High level control tools • Web. UI for Openstack infrastructure/project/VM control (limited use) § Rabbit. MQ Ø ATLAS: Open. Stack version currently used: Folsom Ø CMS: Open. Stack version currently used: Grizzly IT-SDC Alessandro Di Girolamo 6 Dec 2013 8
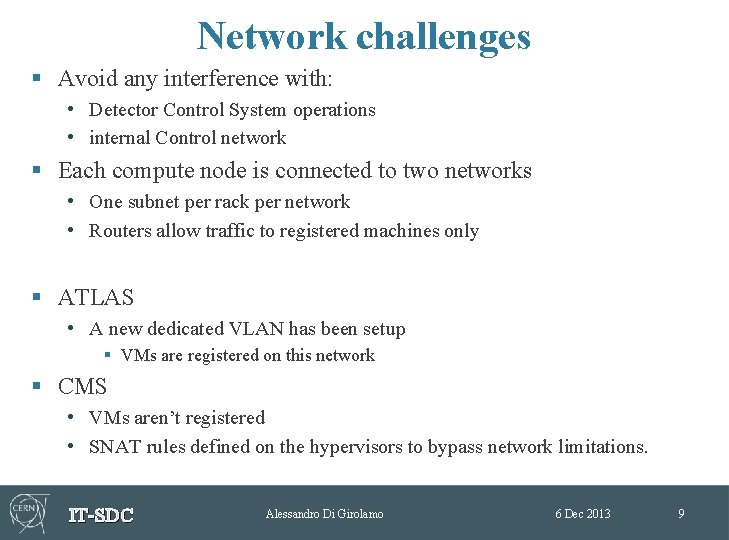
Network challenges § Avoid any interference with: • Detector Control System operations • internal Control network § Each compute node is connected to two networks • One subnet per rack per network • Routers allow traffic to registered machines only § ATLAS • A new dedicated VLAN has been setup § VMs are registered on this network § CMS • VMs aren’t registered • SNAT rules defined on the hypervisors to bypass network limitations. IT-SDC Alessandro Di Girolamo 6 Dec 2013 9
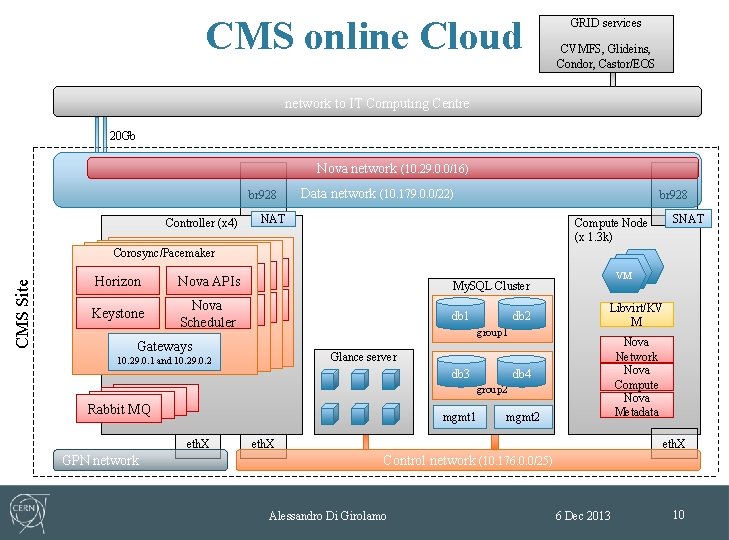
CMS online Cloud GRID services CVMFS, Glideins, Condor, Castor/EOS network to IT Computing Centre 20 Gb Nova network (10. 29. 0. 0/16) br 928 Data network (10. 179. 0. 0/22) br 928 NAT Controller (x 4) CMS Site Corosync/Pacemaker Dashboard apiapiapi Horizon Nova APIs conductor Keystone Nova conductor Keystone Scheduler db 1 db 2 Libvirt/KV M db 4 Nova Network Nova Compute Nova Metadata group 1 Glance server 10. 29. 0. 1 and 10. 29. 0. 2 db 3 group 2 NAT NAT Rabbit MQ mgmt 1 eth. X GPN network VMVM VM My. SQL Cluster Gateways SNAT Compute Node (x 1. 3 k) mgmt 2 eth. X Control network (10. 176. 0. 0/25) Alessandro Di Girolamo 6 Dec 2013 10
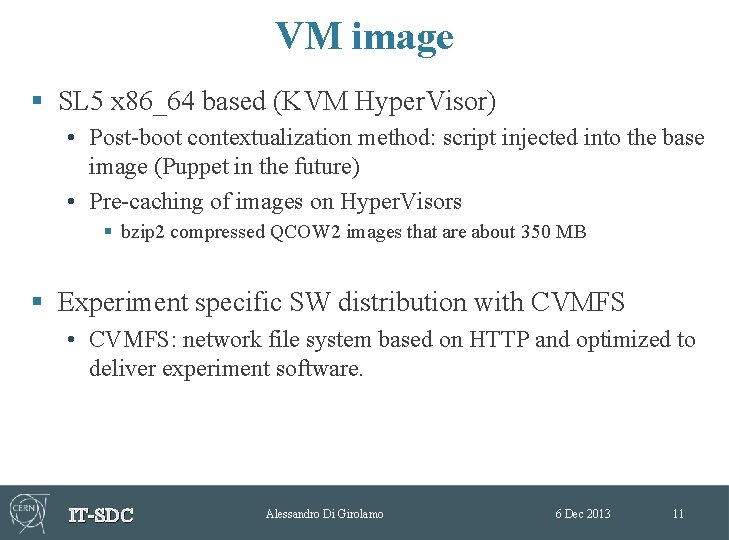
VM image § SL 5 x 86_64 based (KVM Hyper. Visor) • Post-boot contextualization method: script injected into the base image (Puppet in the future) • Pre-caching of images on Hyper. Visors § bzip 2 compressed QCOW 2 images that are about 350 MB § Experiment specific SW distribution with CVMFS • CVMFS: network file system based on HTTP and optimized to deliver experiment software. IT-SDC Alessandro Di Girolamo 6 Dec 2013 11
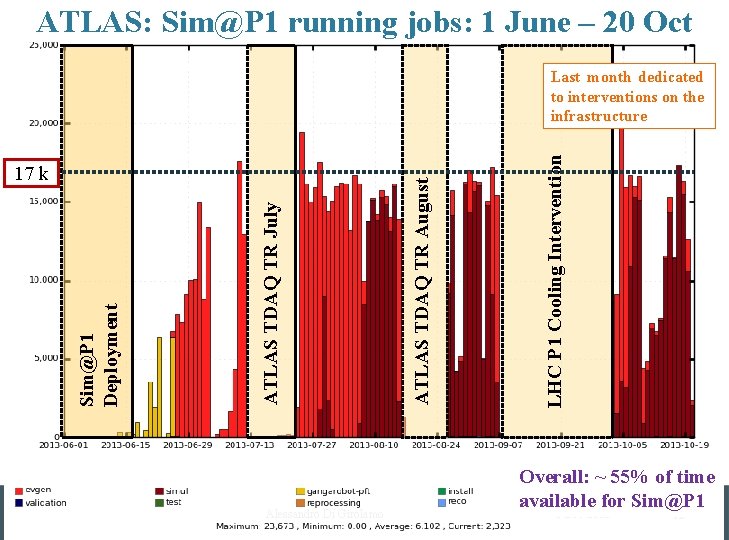
ATLAS: Sim@P 1 running jobs: 1 June – 20 Oct IT-SDC Alessandro Di Girolamo LHC P 1 Cooling Intervention ATLAS TDAQ TR July Sim@P 1 Deployment 17 k ATLAS TDAQ TR August Last month dedicated to interventions on the infrastructure Overall: ~ 55% of time available for Sim@P 1 6 Dec 2013 12
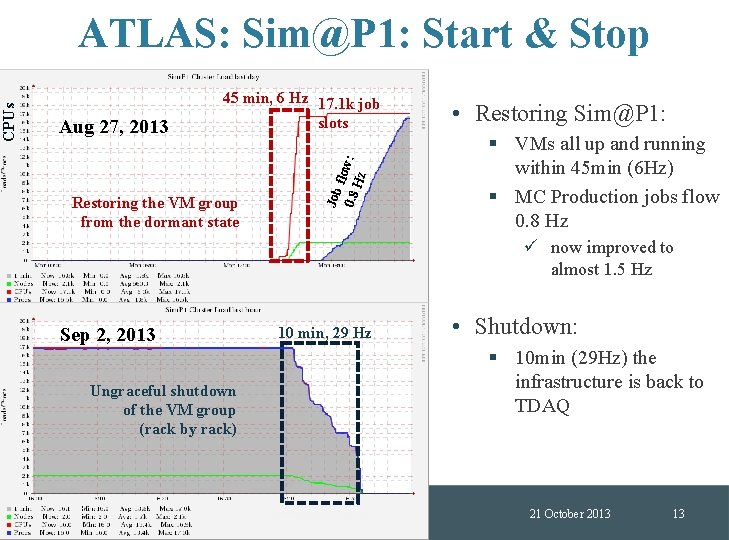
Aug 27, 2013 45 min, 6 Hz 17. 1 k job slots Restoring the VM group from the dormant state Job fl 0. 8 ow: Hz CPUs ATLAS: Sim@P 1: Start & Stop • Restoring Sim@P 1: § VMs all up and running within 45 min (6 Hz) § MC Production jobs flow 0. 8 Hz ü now improved to almost 1. 5 Hz Sep 2, 2013 10 min, 29 Hz § 10 min (29 Hz) the infrastructure is back to TDAQ Ungraceful shutdown of the VM group (rack by rack) 13 IT-SDC • Shutdown: 6 Dec 2013 Alessandro Di Girolamo 21 October 2013 13
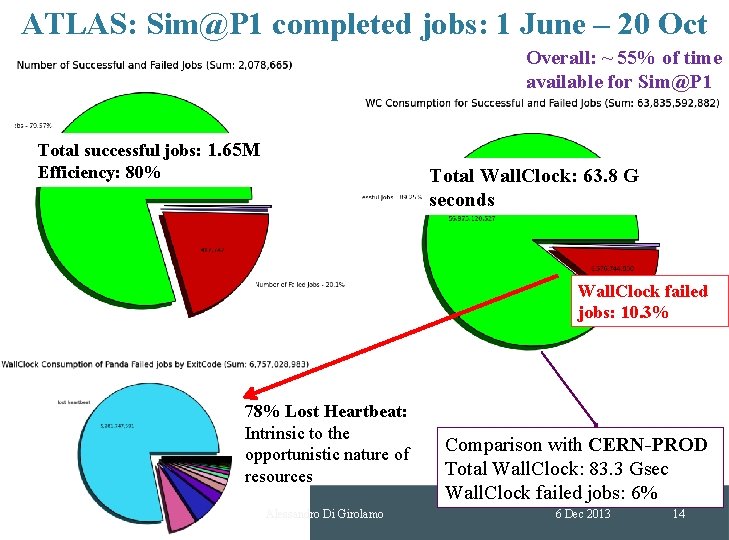
ATLAS: Sim@P 1 completed jobs: 1 June – 20 Oct Overall: ~ 55% of time available for Sim@P 1 Total successful jobs: 1. 65 M Efficiency: 80% Total Wall. Clock: 63. 8 G seconds Wall. Clock failed jobs: 10. 3% 78% Lost Heartbeat: Intrinsic to the opportunistic nature of resources IT-SDC Alessandro Di Girolamo Comparison with CERN-PROD Total Wall. Clock: 83. 3 Gsec Wall. Clock failed jobs: 6% 6 Dec 2013 14
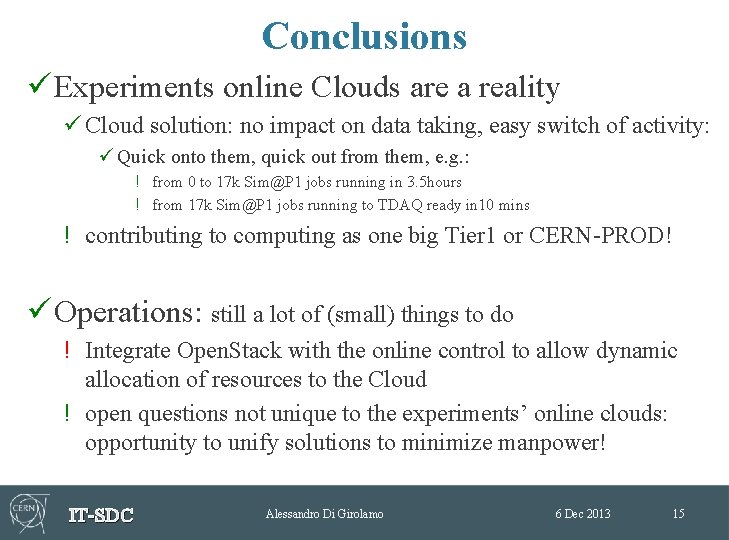
Conclusions ü Experiments online Clouds are a reality ü Cloud solution: no impact on data taking, easy switch of activity: ü Quick onto them, quick out from them, e. g. : ! from 0 to 17 k Sim@P 1 jobs running in 3. 5 hours ! from 17 k Sim@P 1 jobs running to TDAQ ready in 10 mins ! contributing to computing as one big Tier 1 or CERN-PROD! ü Operations: still a lot of (small) things to do ! Integrate Open. Stack with the online control to allow dynamic allocation of resources to the Cloud ! open questions not unique to the experiments’ online clouds: opportunity to unify solutions to minimize manpower! IT-SDC Alessandro Di Girolamo 6 Dec 2013 15
Back. Up IT-SDC Alessandro Di Girolamo 6 Dec 2013 16
Sim@P 1: Dedicated Network Infrastructure ü Sim@P 1 VMs will use a dedicated 1 Gbps physical network connecting the P 1 rack data switches to the “Castor router” Racks in SDX 1 Data Core ATCN IT-SDC 1 Gbps CN . . . 1 Gbps CN Data switch CN 1 Gbps Control switch Ctrl Core 1 Gbps VLAN isolation CN P 1 Castor Router ACLs 20 -80 Gbps IT Castor Router Alessandro Di Girolamo ATLAS HLT Sub. Farm Output Nodes (SFOs) GPN Services 10 Gbps 6 Dec 2013 ATLAS: Puppet, REPO IT GRID: Condor, Panda EOS/Castor, Cvm. FS 17
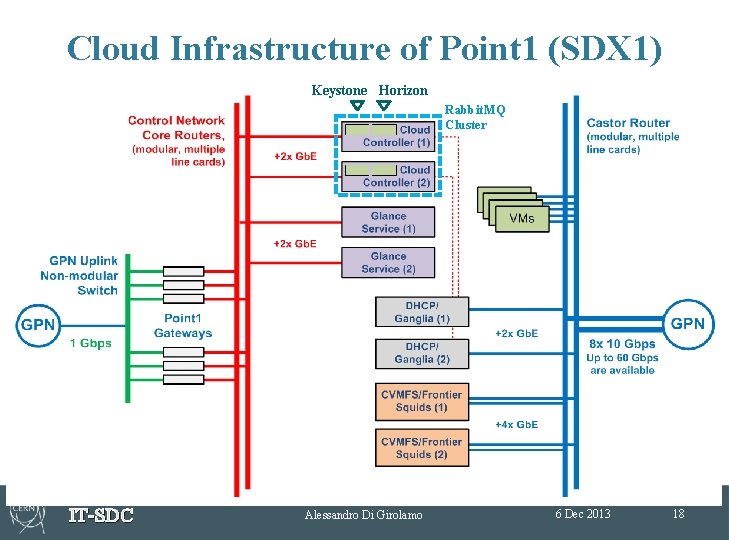
Cloud Infrastructure of Point 1 (SDX 1) Keystone Horizon Rabbit. MQ Cluster IT-SDC Alessandro Di Girolamo 6 Dec 2013 18
Keystone (2012. 2. 4) Slide from Alex Zaytsev (BNL RACF) § No issues with stability/performance observed of any scale § Initial configuration of tenant / users / services / endpoints might deserve some higher level automation • Some automatic configuration scripts were already available in 2013 Q 1 from the third parties, but we found that using the Keystone CLI directly is more convenient & transparent § Simple replication of the keystone Mys. QL DB works fine for maintaining redundant Keystone instances IT-SDC Alessandro Di Girolamo 6 Dec 2013 19
Nova (2012. 2. 4) § Once bug fix needed to be applied Slide from Alex Zaytsev (BNL RACF) • Back port from Grizzly release: “Handle compute node records with no timestamp”: https: //github. com/openstack/nova/commit/fad 69 df 25 ffcea 2 a 44 cbf 3 ef 636 a 68863 a 2 d 64 d 9 § The prefix for the VMs’ MAC addresses had to be changed in order to match the range pre-allocated for Sim@P 1 project • No configuration option for this, direct patch to Python code was needed § Configuring the server environment for Nova Controller supporting more than 1 k hypervisors / 1 k of VMs requires rising the default limits for maximum number of open files per several system users • Not documented / handled automatically by Openstack recommended configuration procedures, but pretty straightforward to figure out § Rabbit. MQ cluster consisting of minimum two nodes was required in order to scale beyond 1 k hypervisors per single Nova Controller • Rabbit. MQ configuration procedure / stability is version sensitive • We had to try several version (currently v 3. 1. 3 -1) before achieving a stable cluster configuration § Overall: stable long term operations with only one Cloud controller (plus one hot spare backup instance) for the entire Point 1 IT-SDC Alessandro Di Girolamo 6 Dec 2013 20
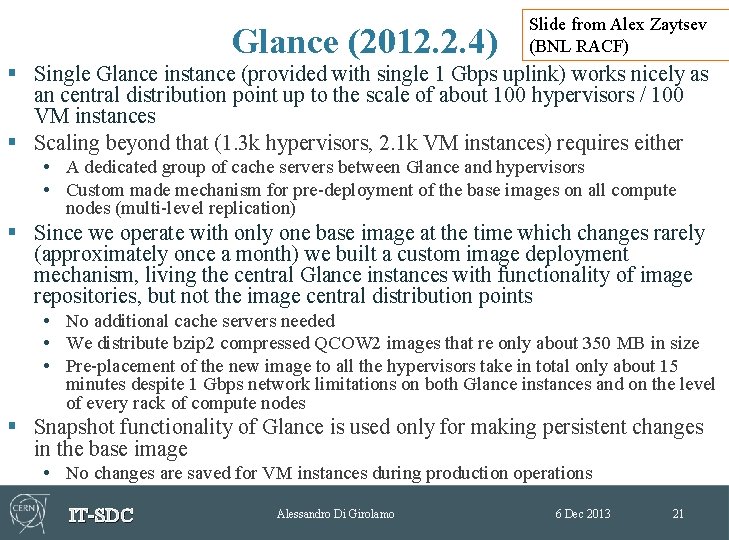
Glance (2012. 2. 4) Slide from Alex Zaytsev (BNL RACF) § Single Glance instance (provided with single 1 Gbps uplink) works nicely as an central distribution point up to the scale of about 100 hypervisors / 100 VM instances § Scaling beyond that (1. 3 k hypervisors, 2. 1 k VM instances) requires either • A dedicated group of cache servers between Glance and hypervisors • Custom made mechanism for pre-deployment of the base images on all compute nodes (multi-level replication) § Since we operate with only one base image at the time which changes rarely (approximately once a month) we built a custom image deployment mechanism, living the central Glance instances with functionality of image repositories, but not the image central distribution points • No additional cache servers needed • We distribute bzip 2 compressed QCOW 2 images that re only about 350 MB in size • Pre-placement of the new image to all the hypervisors take in total only about 15 minutes despite 1 Gbps network limitations on both Glance instances and on the level of every rack of compute nodes § Snapshot functionality of Glance is used only for making persistent changes in the base image • No changes are saved for VM instances during production operations IT-SDC Alessandro Di Girolamo 6 Dec 2013 21
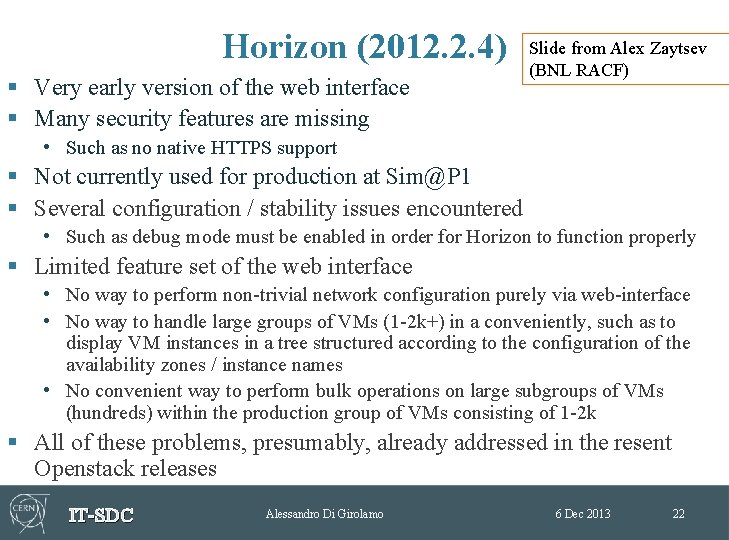
Horizon (2012. 2. 4) § Very early version of the web interface § Many security features are missing Slide from Alex Zaytsev (BNL RACF) • Such as no native HTTPS support § Not currently used for production at Sim@P 1 § Several configuration / stability issues encountered • Such as debug mode must be enabled in order for Horizon to function properly § Limited feature set of the web interface • No way to perform non-trivial network configuration purely via web-interface • No way to handle large groups of VMs (1 -2 k+) in a conveniently, such as to display VM instances in a tree structured according to the configuration of the availability zones / instance names • No convenient way to perform bulk operations on large subgroups of VMs (hundreds) within the production group of VMs consisting of 1 -2 k § All of these problems, presumably, already addressed in the resent Openstack releases IT-SDC Alessandro Di Girolamo 6 Dec 2013 22
… § … • . . • … • . . ! … IT-SDC Alessandro Di Girolamo 6 Dec 2013 23
… § … • . . • … • . . ! … IT-SDC Alessandro Di Girolamo 6 Dec 2013 24