
An ANN approach to identify malicious URLs ECE
- Slides: 8
An ANN approach to identify malicious URLs ECE 539 – Final Project Jayneel Gandhi
Motivation • Prevent users from visiting malicious webpage • Lot of effort into reducing internet crimes • Try to learn which URL is malicious from different sources • Stop users from accessing such website in future
Data Set (1) • Developed by Sys. Net group at University of California at San Diego • Posted at UCI Machine Learning Repository http: //archive. ics. uci. edu/ml/datasets/URL+R eputation
Data Set (2) • Feature Space is made up of: – Lexical Features • Hostname • Primary Domain • Path Tokens – Host Based Features • WHOIS info • IP prefix • Geographical • Feature Vector (sparse): 3, 231, 961 • Number of instances: 2, 396, 130 HUGE data set !!! Takes long time to run … in the range of 20 -30 days
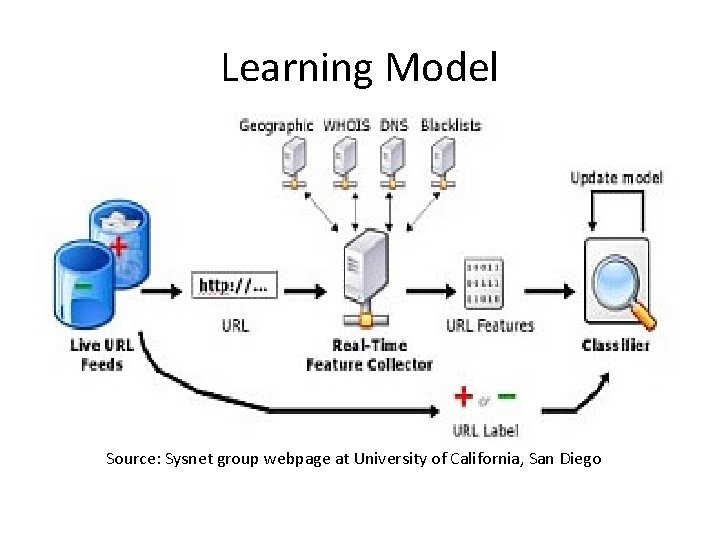
Learning Model Source: Sysnet group webpage at University of California, San Diego
Experiments (1) • Data set organized as URLs visited over the period of 121 days (Day 0 -Day 120) • Each day has roughly 15, 000 -40, 000 URLs visited • I will only be running experiments on Day 0 consisting of 16000 URLs
Experiment (2) • Experiment 1 – Use single perceptron model • Online learning possible • Has history of all the URLs visited is preserved • Experiment 2 – Use Support Vector Machine (SVM) • Online learning not possible • Can only learn based on certain past history • Losses certain history with time
THANK YOU…