
10302020 Dan Han Eleni Stroulia University of Alberta
10/30/2020 Dan Han, Eleni Stroulia University of Alberta A 3 -Dimensional Data Model for Large Time-Series Dataset Analysis in HBase MESOCA 2012 1
Outline Background and Motivation Related Work A 3 -Dimensional Data Model in HBase Case Study and Experiment Results Discussion Conclusions and Future Work 10/30/2020 » » » MESOCA 2012 2
Migrating Applications To the Cloud » Cloud is an attractive computing platform ˃ Elasticity, Excellent Scalability, High Availability, Low operating cost » Applications are moving to the cloud ˃ Social networking, online shopping, monitoring system ˃ Time-Series data: grows monotonously over time ˃ Analysis of large scale time-series data 10/30/2020 + May lead to new knowledge + May lead to Improvements of existing services » Success adoption of this movement paradigm requires a new model of storage MESOCA 2012 3
Migrating RDBMS Content To No. SQL » From RDBMS to No. SQL storage systems ˃ Enable the storage of big data, in order of row key ˃ Scale horizontally across storage nodes easily ˃ Not much data-organization support » Migration challenges 10/30/2020 ˃ Few experiences and principles to follow ˃ Steep learning curve for programming ˃ Much experimentation is required before deployment + Much time is spent in designing the data schema + The “wrong” schema may lead to inefficient, high-latency queries MESOCA 2012 4
We need Design Patterns for HBase Schemas » Our objective is to develop a systematic method for ˃ ˃ Guiding data organization in No. SQL databases, given the types of data stored, the amount of data its usage patterns » We start our investigation with HBase 10/30/2020 ˃ A No. SQL database offering, built on top of Hadoop ˃ Parallel Distributed Computation + Map. Reduce Framework + Coprocessor Framework MESOCA 2012 5
Related Work » Talks in HBase. Con 2012, held in May ˃ Data schema and Coprocessor are two main topics ˃ Experience from 30 enterprises, such as Facebook, Yapmap, e. Bay, Adobe » Organizing time-series data into period-specific “buckets” 10/30/2020 ˃ Open. TSDB: a distributed scalable time series database, written on top of HBase ˃ A data Model in Cassendra, another No. SQL database offering ˃ Applied into our case study MESOCA 2012 6
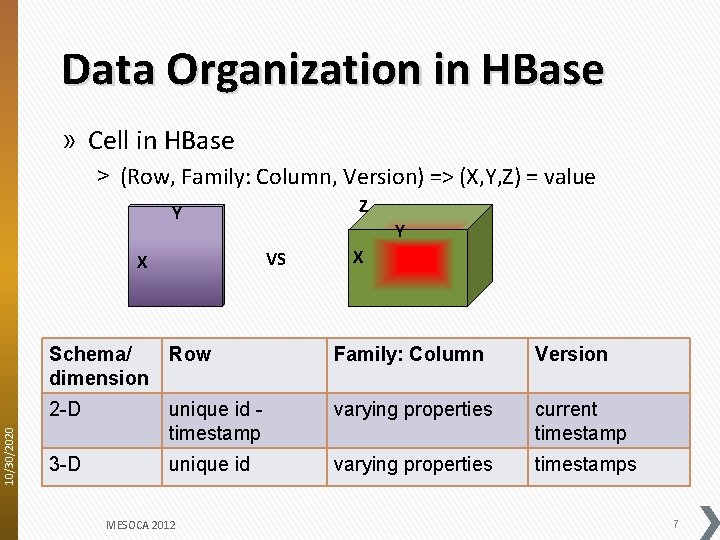
Data Organization in HBase » Cell in HBase ˃ (Row, Family: Column, Version) => (X, Y, Z) = value Z Y VS X 10/30/2020 Y X Schema/ dimension Row Family: Column Version 2 -D unique id timestamp varying properties current timestamp 3 -D unique id varying properties timestamps MESOCA 2012 7
Case study: The Datasets » Cosmology Dataset ˃ ˃ Product of an N-body simulation Three types of particles: dark matter, gas and star Particles evolve over a series of discrete timestamps Each snapshot records the properties of all particles at the time of the snapshot ˃ 9 snapshots, consists of 321, 065, 547 particles 10/30/2020 » Bixi Dataset ˃ Data from a bicycle-renting service in the city of Montreal ˃ Every minute, the statistic information about bike usage a station is collected by the sensor ˃ 96, 842 data points involved MESOCA 2012 8
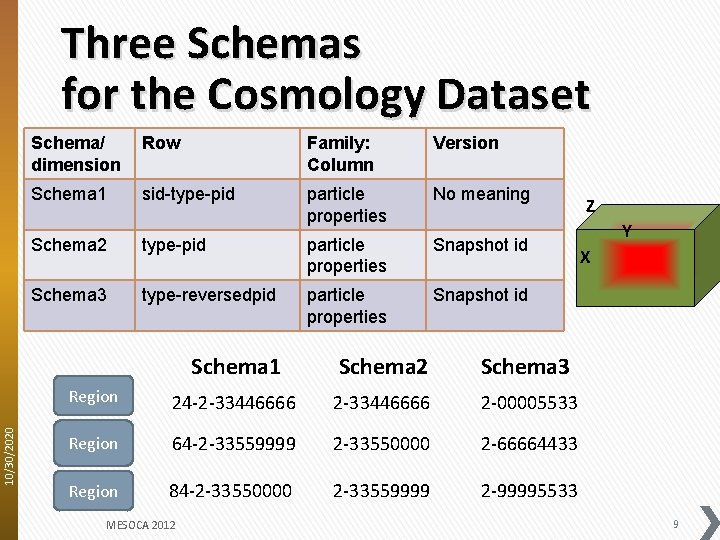
10/30/2020 Three Schemas for the Cosmology Dataset Schema/ dimension Row Family: Column Version Schema 1 sid-type-pid particle properties No meaning Schema 2 type-pid particle properties Snapshot id Schema 3 type-reversedpid particle properties Snapshot id Schema 1 Schema 2 Schema 3 Region 24 -2 -33446666 2 -00005533 Region 64 -2 -33559999 2 -33550000 2 -66664433 Region 84 -2 -33550000 2 -33559999 2 -99995533 MESOCA 2012 Z Y X 9
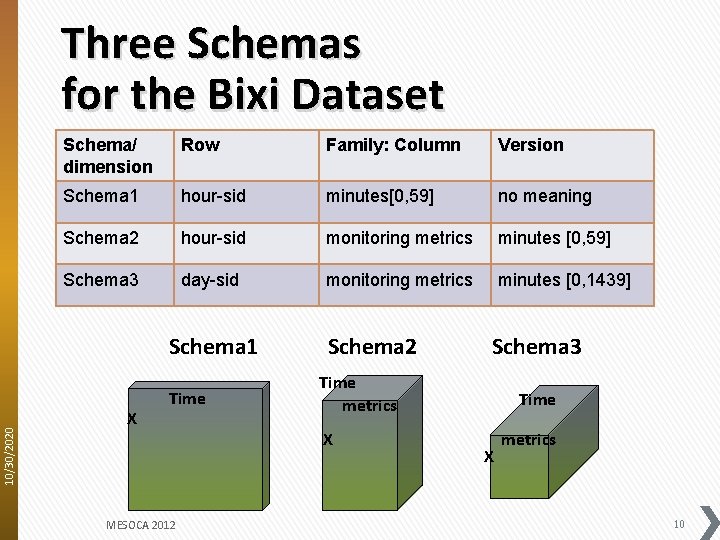
Three Schemas for the Bixi Dataset Schema/ dimension Row Family: Column Version Schema 1 hour-sid minutes[0, 59] no meaning Schema 2 hour-sid monitoring metrics minutes [0, 59] Schema 3 day-sid monitoring metrics minutes [0, 1439] 10/30/2020 Schema 1 X Time MESOCA 2012 Schema 3 Time metrics X Time X metrics 10
Experiment Results » Experiment Environment ˃ Hadoop 0. 20, HBase 0. 93 -snapshot (Coprocessor support) ˃ A four-node cluster on virtual machines » Quires for each dataset ˃ Three Queries of Cosmology dataset from related research ˃ One query of Bixi dataset from business requirement 10/30/2020 » Query processing Implementation ˃ Native java API ˃ User-Level Coprocessor Implementation MESOCA 2012 11
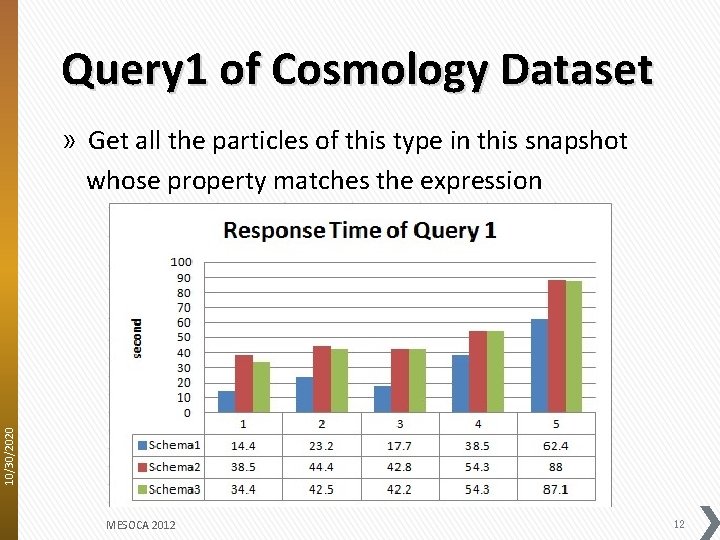
Query 1 of Cosmology Dataset 10/30/2020 » Get all the particles of this type in this snapshot whose property matches the expression MESOCA 2012 12
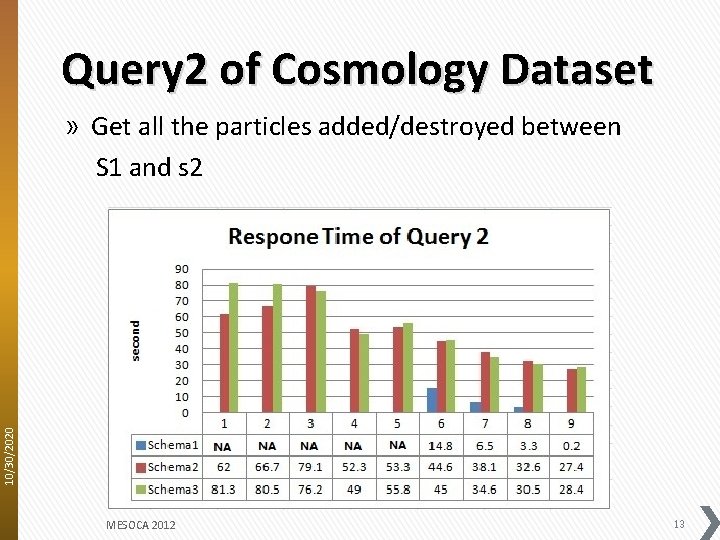
Query 2 of Cosmology Dataset 10/30/2020 » Get all the particles added/destroyed between S 1 and s 2 MESOCA 2012 13
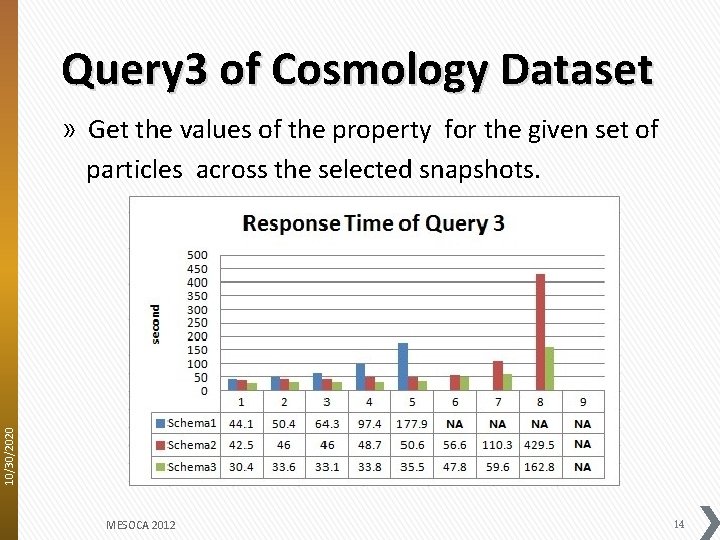
Query 3 of Cosmology Dataset 10/30/2020 » Get the values of the property for the given set of particles across the selected snapshots. MESOCA 2012 14
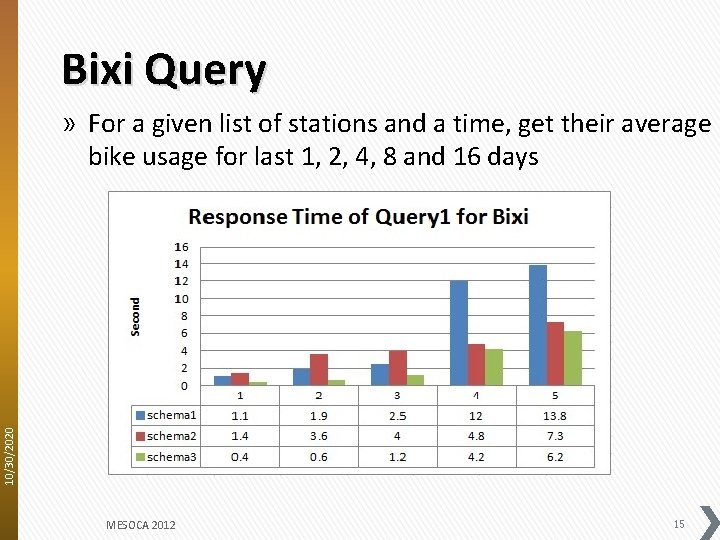
Bixi Query 10/30/2020 » For a given list of stations and a time, get their average bike usage for last 1, 2, 4, 8 and 16 days MESOCA 2012 15
Discussion “Qualitative” versus “Quantitative” Suggestions Dynamic Data versus Static Data Historical Dataset versus Real-Time Datasets Supported versus Non-Supported Datasets 10/30/2020 » » MESOCA 2012 16
Conclusion » A 3 -dimensional data model ˃ Improved performance can be got from the data schema that use the version dimension of HBase » Fit in “write-once, read-many” system 10/30/2020 ˃ Monitoring system ˃ Sensor-based system ˃ Version-based analysis MESOCA 2012 17
Future Work » More Evaluation of this data model ˃ scalability, elasticity, and utilization » How to design data model for other datasets 10/30/2020 ˃ Spatial dataset ˃ Graphic dataset MESOCA 2012 18
Questions? 10/30/2020 Thank you MESOCA 2012 19
- Slides: 19